Hunspell splits a compound left to right and checks the rest of the word as a slice that starts at some position. To try a simplified join in that slice, the code writes out the long form in a new array that starts with the whole word, then reads the next part from position 0 instead of from where the slice starts.
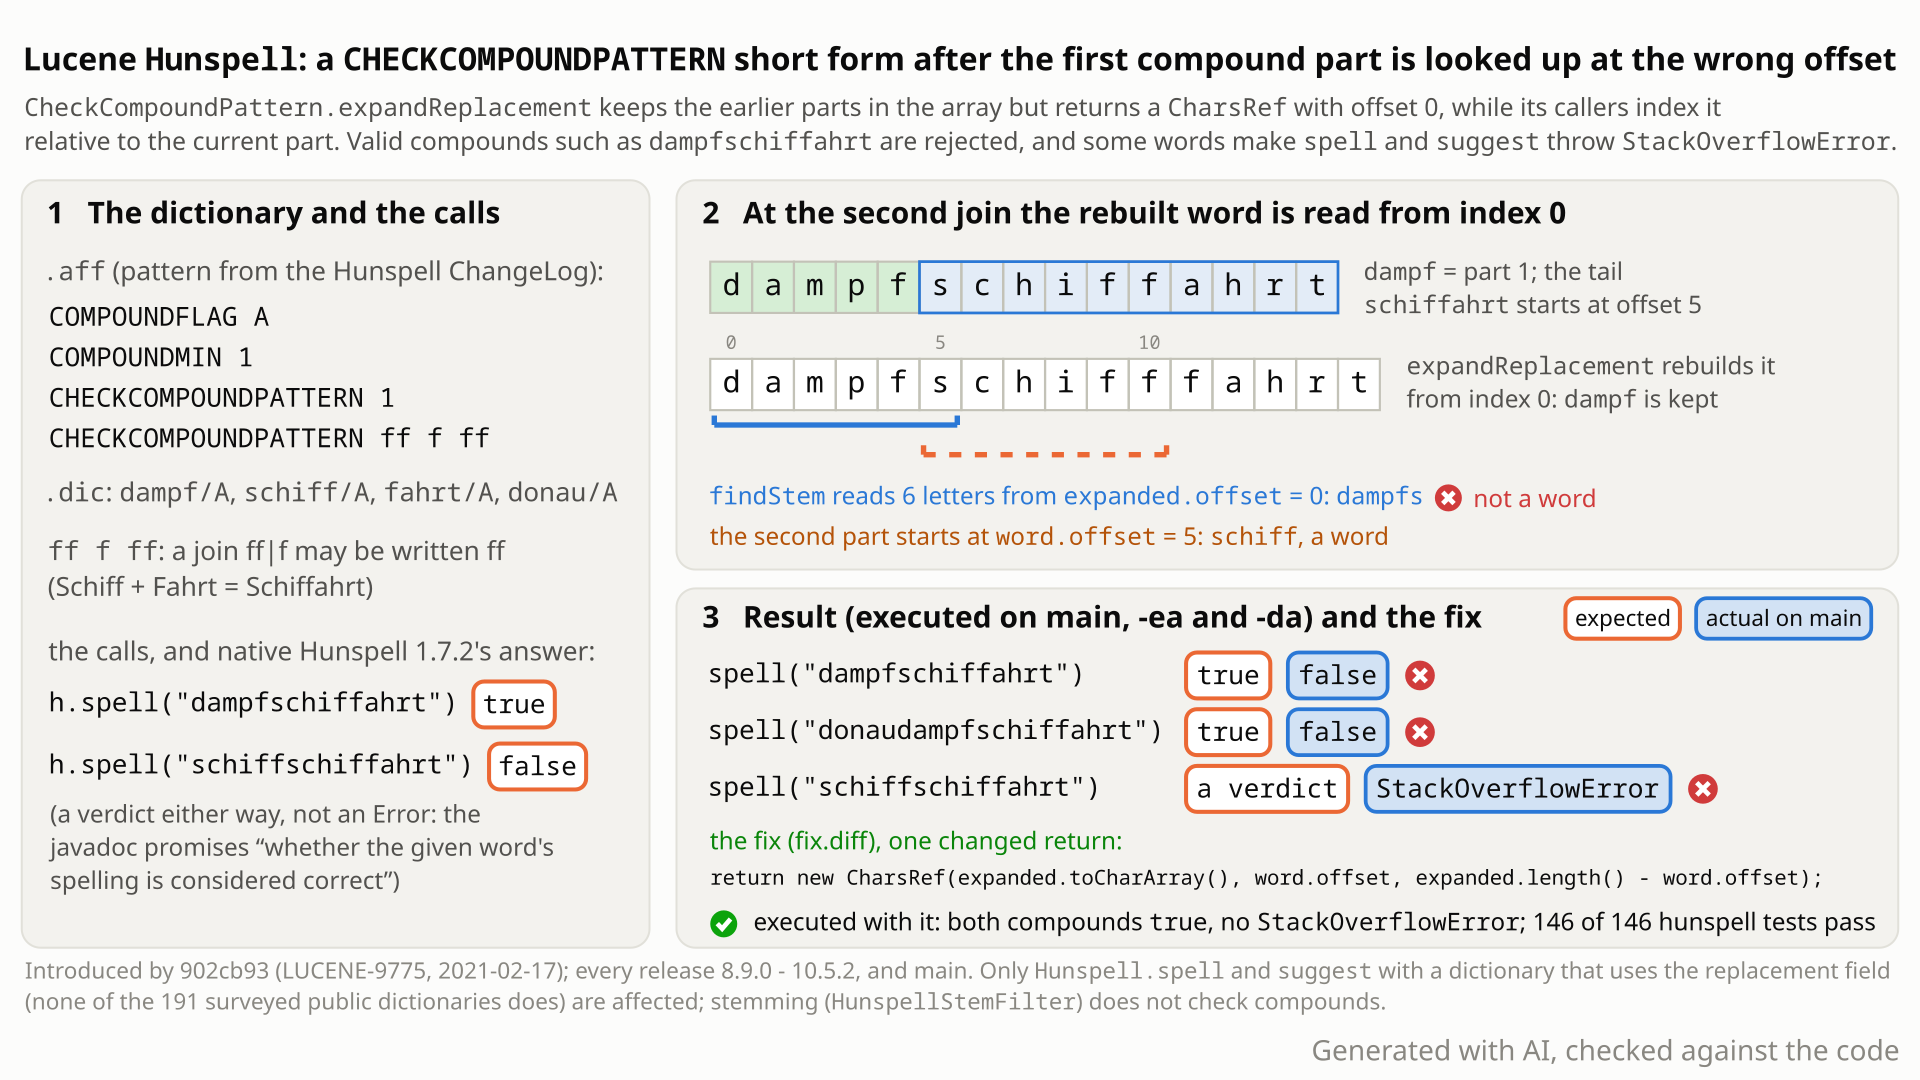
dampfschiffahrt split as dampf + schiff|fahrt, and which letters the code reads for the part after the first join. Select the still to open it at full size. Generated with AI, checked against the code.- Load a dictionary with
CHECKCOMPOUNDPATTERN ff f ff, the Hunspell ChangeLog's own example: a writtenffat a compound join stands forff|f, as in pre-reform German Schiffahrt = Schiff + Fahrt. Words: dampf, schiff, fahrt, donau.spell("schiffahrt")returns true. - Put a part in front:
spell("dampfschiffahrt"), dampf + schiff|fahrt. You expect true, as native Hunspell 1.3.2 and 1.7.2 return. You get false, with no error;donaudampfschiffahrttoo. spell("schiffschiffahrt")returns no verdict at all: it throwsStackOverflowError, and so doessuggest. Native Hunspell just answers "misspelled".- Why: to try the simplified join in the rest
schiffahrt, which starts at position 5, the code writes out the long formdampfschifffahrtbut reads the next part from position 0:dampfsinstead ofschiff. Inschiffschiffahrtit readsschiff, the first part, again, and the rest grows by one letter at every level. - Only the opt-in spell-checker is hit, and only with dictionaries that use this replacement field (none of 191 surveyed public ones does). Stemming, indexing and search are unaffected. Every release from 8.9.0 to 10.6.0 (10.6.0 by reading).
Only applications that call the opt-in spell-checker (Hunspell.spell, suggest) with a dictionary that uses the replacement field of CHECKCOMPOUNDPATTERN (simplified joins, as in pre-reform German). None of 191 surveyed public dictionaries does. Then valid compounds whose simplified join comes after the first part are reported as misspelled, and some words throw StackOverflowError. Stemming, indexing and search are unaffected.
Mechanism, terms and numbers761 words
CHECKCOMPOUNDPATTERN endchars beginchars replacement lets a Hunspell dictionary accept a simplified spelling at a compound join: with ff f ff, a written ff stands for ff|f, as in pre-reform German Schiffahrt (Schiff + Fahrt). Lucene's Hunspell.spell splits a compound left to right and works on the rest of the word as a slice of the same array. To try a simplified join in that slice, CheckCompoundPattern.expandReplacement writes the long form into a new array that starts with the whole word (kept so the FORCEUCASE check can see the first letter) but returns it with offset 0, while its callers count positions from the start of the slice. At the first join the two agree; at a later join the next part is read from the start of the whole word. So dampfschiffahrt and donaudampfschiffahrt are rejected (native Hunspell accepts both), and schiffschiffahrt, or the 3-letter auu with CHECKCOMPOUNDPATTERN u u u, makes spell() and suggest() throw StackOverflowError. Only the opt-in spell-checker is affected, with dictionaries that use the replacement field, in every release from 8.9.0 to 10.6.0 (10.6.0 by reading); the fix is one changed return in one method.
- Compound checking: when a word is not in the dictionary,
Hunspell.spelltries to split it into dictionary words that may be compounded (here, words with theCOMPOUNDFLAG). It finds a first part, then splits the rest the same way, recursively, so a word can have any number of parts (COMPOUNDWORDMAXdefaults to unlimited). - Simplified join (
CHECKCOMPOUNDPATTERN endchars beginchars replacement, hunspell(5): "The optional replacement parameter allows simplified compound form"): withff f ff, the two lettersffwritten at a join stand forff|f, soschiffahrtis read as schiff + fahrt. - The slice: from the second part on, the code works on the rest of the word as a slice of the same array, an offset (where the rest starts) and a length.
- For each position in the current slice,
checkCompoundsalso tries the simplified joins (Hunspell.java:241):expandReplacementwrites the long form,new String(word.chars, 0, word.offset + breakPos) + endChars + beginChars + rest(CheckCompoundPattern.java:96-100). The string starts at position 0 of the whole word, because LUCENE-9775 kept the earlier parts for the FORCEUCASE check, andnew CharsRef(String)gives it offset 0. - The caller looks up the next part as
findStem(expanded.chars, expanded.offset, breakPos, ...)withbreakPos = pos + endLength, a length counted inside the slice (Hunspell.java:255-257);checkCompoundsAfterthen reads or recurses on the rest atoffset + breakPos(:270-275,:284). - At the first join the slice starts at 0 and all is right. At a later join the next part is read from the start of the whole word, and the rest re-includes the earlier parts.
- If those first letters are not a word, that split fails, and for
dampfschiffahrtevery other split fails too, so the valid compound is rejected. If they happen to be one (the first part again) and the pattern matches again, the rest is longer than before; nothing limits the depth by default (compoundMax = Integer.MAX_VALUE,Dictionary.java:152, checked atHunspell.java:214), so the recursion ends inStackOverflowError.
dampfschiffahrt (15 letters, positions 0-14) with the dictionary dampf, schiff, fahrt, donau:
| step | slice (offset, length) | what happens | main | with the fix |
|---|---|---|---|---|
| 1 | dampfschiffahrt (0, 15) | first part dampf; rest schiffahrt (5, 10) | same | same |
| 2 | schiffahrt (5, 10) | ff at position 4 of the slice may be ff|f: long form dampfschifffahrt | next part read as [0, 6) = dampfs: no word | [5, 11) = schiff, then [11, 16) = fahrt |
| 3 | rejected | accepted |
schiffschiffahrt (16 letters): at the second join the long form is schiffschifffahrt (17); the next part is read as [0, 6) = schiff, the first part again, and the rest is [6, 17) = schifffahrt, 11 letters instead of 10. The next level gives schiffffahrt (12), then 13, and so on, one more f each time, until the stack overflows. An executed trace of the lookups shows exactly these letters, on main and with the fix ([6, 12) = schiff, [12, 17) = fahrt: accepted).
The same shape gives a 3-letter overflow: one word au with CHECKCOMPOUNDPATTERN u u u makes spell("auu") find au again at every level. C Hunspell expands the current part in a copy and recurses on its substring (affixmgr.cxx:1641-1646, :2084), so its positions stay relative to the part.
Exposure and likelihood360 words
- Who. Callers of the spell-checker API:
Hunspell.spell,Hunspell.suggest, andSuggester(a public class from 9.5.0), which creates an internal speller (Suggester.java:184-185) and validates candidates with itsspell(:215,:298,:301); before 9.5.0 the same code is reached throughHunspell.spellandsuggest. Executed:spellandsuggestboth throw. - Opt-in twice. The spell-checker is a separate API that no analyzer calls, and the dictionary must use the optional replacement field of
CHECKCOMPOUNDPATTERN. Compounds of three or more parts are the default once compounding is on, sinceCOMPOUNDWORDMAXis unlimited by default. - Real dictionaries. None of 191 public
.afffiles surveyed (LibreOffice and wooorm/dictionaries) uses the replacement field. A dictionary author reported using it to native Hunspell (hunspell/hunspell#950, 2023, a Sanskrit rule). Both documented examples, the ChangeLog'sff f ffand theu/B u/B uof native's Telugu testcheckcompoundpattern4, reach the overflow. - Effect. Valid compounds whose simplified join is not the first join are reported as misspelled, silently. Words in which the expanded letters line up with an earlier part throw
StackOverflowError: anError, socatch (Exception e)does not catch it, and the default suggest time limit (250 ms, return partial result) does not stop it. Each call fails on its own: after the overflows, the sameHunspellinstance answered five checked words like a fresh instance. - Not affected.
HunspellStemFilterusesStemmer.stem, which does not compound (HunspellStemFilter.java:86,:111), andgetRootsreturns no roots for compounds (Hunspell.java:300). Executed: the stem filter returns the triggering words unchanged with all three triggering dictionaries, andgetRoots("schiffschiffahrt")is[]. - Workarounds. A small
COMPOUNDWORDMAXin the dictionary stops the overflow but not the false negatives (withCOMPOUNDWORDMAX 3,barfozaris still rejected); a large one is finite but costly (with 1024,spell("auu")made about a million stem lookups and allocated about 1.5 GB); acheckCanceledhook with a budget can stop the recursion, since it runs on every stem lookup (Hunspell.java:165). - Likelihood: rare. It needs such a dictionary; then ordinary three-part compounds hit the false negative. No scale is needed: one word triggers it.
The test shows that a CHECKCOMPOUNDPATTERN replacement after the first compound part is checked from the start of the word (rule u u u, root au/x), so the recursion never ends.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.hunspell;

import java.io.ByteArrayInputStream;
import java.nio.charset.StandardCharsets;
import java.util.List;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestCompoundPatternReplacementRecursion extends LuceneTestCase {

  public void testReplacementAfterFirstPart() throws Exception {
    String aff = "COMPOUNDFLAG x\nCOMPOUNDMIN 1\nCHECKCOMPOUNDPATTERN 1\nCHECKCOMPOUNDPATTERN u u u\n";
    String dic = "1\nau/x\n";
    Dictionary dictionary =
        new Dictionary(
            new ByteArrayInputStream(aff.getBytes(StandardCharsets.UTF_8)),
            List.of(new ByteArrayInputStream(dic.getBytes(StandardCharsets.UTF_8))),
            false,
            SortingStrategy.inMemory());
    // expected: false ("auu" is no compound of "au"); actual: StackOverflowError
    assertFalse(new Hunspell(dictionary).spell("auu"));
  }
}
# in a copy of this finding's repro folder (repro/LFV-377/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.hunspell.TestCompoundPatternReplacementRecursion
- Expected vs actual
- Expected:
spell("auu")returns false (C Hunspell: misspelled, suggestionau). Actual:StackOverflowError.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.StackOverflowError
       org.apache.lucene.analysis.hunspell.Dictionary.hasFlag(Dictionary.java:1506)
       org.apache.lucene.analysis.hunspell.Hunspell.acceptCase(Hunspell.java:187)
       org.apache.lucene.analysis.hunspell.Hunspell.lambda$findStem$0(Hunspell.java:175)
       org.apache.lucene.analysis.hunspell.Stemmer.doStem(Stemmer.java:245)
       org.apache.lucene.analysis.hunspell.Hunspell.findStem(Hunspell.java:169)
       org.apache.lucene.analysis.hunspell.Hunspell.checkCompoundPatternReplacements(Hunspell.java:257)
       org.apache.lucene.analysis.hunspell.Hunspell.checkCompounds(Hunspell.java:241)
       org.apache.lucene.analysis.hunspell.Hunspell.checkCompoundsAfter(Hunspell.java:285)
       org.apache.lucene.analysis.hunspell.Hunspell.checkCompoundPatternReplacements(Hunspell.java:260)
[...]- hunspell(5): "The optional replacement parameter allows simplified compound form", with no limit on where the join is; native Hunspell accepts
dampfschiffahrtand answers every overflow word. - The feature commit handled later joins; a one-line FORCEUCASE change (LUCENE-9775) broke them, and reverting that line alone restores the old results.
spell()documents a boolean result; nothing documents aStackOverflowErroras expected.
The full argument363 words
- Contract. hunspell(5): "CHECKCOMPOUNDPATTERN endchars[/flag] beginchars[/flag] [replacement] ... The optional replacement parameter allows simplified compound form." No limit on the position or the number of parts, and "COMPOUNDWORDMAX ... (Default is unlimited.)".
Hunspell.spell: "@return whether the given word's spelling is considered correct according to Hunspell rules" (Hunspell.java:71-74): a boolean result; not a formal promise that noErrorescapes, but no limitation or expected failure is documented. The class "can be used in place of native Hunspell for many languages" (:35-36); its examples of unsupported cases ("For example:" Hungarian, non-BMP characters, PHONE,:37-44) do not mention this directive. hunspell(5) warns right after the directive that "COMPOUNDMIN doesn't work correctly with the compound word alternation" (man/hunspell.5:494-495); that does not explain this bug, since every repro usesCOMPOUNDMIN 1. - Tests. Lucene's ported fixtures
checkcompoundpattern2andcheckcompoundpattern3list only two-part simplified forms (fozar,fur,bozan), so no test reaches a later join (TestSpellChecking.java:97-106).TestHunspellRepositoryTestCasesdoes not exclude native'scheckcompoundpattern4(:38-46), so Lucene expects to conform on it; that fixture's own words are two-part and pass (checked with the verifiers' own tests on that dictionary; the repository-wide test needs a Hunspell source checkout and was not run). - History. The feature commit (LUCENE-9717,
d0ae2bd2b9c, 2021-02-03) built the long form relative to the part and handled later joins (barfozar,barfuraccepted,spell("auu")false). Two weeks later LUCENE-9775 (902cb93db22) changed only that expression inexpandReplacementso the FORCEUCASE check could see the word's first letter, and left the offset at 0; the author's review note says "Include all compounds parts from the very beginning for the case check to work later". That commit with only this line reverted is correct again. Nothing in it mentions simplified joins after the first part. - Reference. Native Hunspell 1.3.2 and 1.7.2 accept
barfozar,barfur,barbozan,dampfschiffahrtanddonaudampfschiffahrt, answerauuwith "misspelled, suggestion au", and never crash on the words tried. - Precedents. LUCENE-9729 fixed an earlier offset/length slip in the same class; native Hunspell fixed CHECKCOMPOUNDPATTERN failing in compounds of more than two parts as a bug in 2010 (hunspell/hunspell#126).
The devil's-advocate check130 words
The strongest case: the class promises to replace native Hunspell only for many languages, the ported fixtures show only two-part simplified forms, and native Hunspell is itself position-dependent (it rejects fozarbar and schiffschiffahrt), so behaviour beyond two parts is unspecified.
Why it fails: the manual sets no position or count limit; the original code handled later joins, and the loss came from an unrelated FORCEUCASE change; the javadoc's examples of unsupported cases do not mention this directive; the asserted cases are exactly those where native Hunspell, the manual and the fixed code agree; and nothing documents a StackOverflowError from spell() on a 16-letter, or 3-letter, word as expected. Every reviewer that rated the intended-behaviour case rated it weak; the refute review gave no verdict. Verdict: not intended, a defect.
Recommended A: keep the earlier parts, return the current part's offset (one changed return)
In CheckCompoundPattern.expandReplacement, keep the earlier parts in the long-form array, since the FORCEUCASE check reads the word's first letter, but return it with the current part's offset: new CharsRef(expanded.toCharArray(), word.offset, expanded.length() - word.offset). The repros then pass, the hunspell test package runs 177 tests with 0 failures (164 pass, 13 skipped) with assertions on and off, and lint passes.
-      return new CharsRef(
+      String expanded =
           new String(word.chars, 0, word.offset + breakPos)
               + endChars
               + beginChars
-              + word.subSequence(breakPos + replacement.length(), word.length));
+              + word.subSequence(breakPos + replacement.length(), word.length);
+      // keep the preceding compound parts in the array, but keep positions relative to word.offset
+      return new CharsRef(expanded.toCharArray(), word.offset, expanded.length() - word.offset);
All options and trade-offs4 options · 786 words
One fix was built and run in a scratch worktree at a9779ef3c193; the finder and the independent reproducer produced textually different patches that make the same correction. It keeps what LUCENE-9775 wanted (the array still starts with the whole word) and makes every part-relative reader see the current part at the offset it expects. It does not bound the recursion for every possible pattern (option C). For the regression test, the primary test class covers both symptoms; the 3 fixture lines are smaller but cover only the false negatives.
A: keep the earlier parts, return the current part's offset (one changed return) (validated by the checks) (recommended)
Build the long form as today, then wrap it with word.offset instead of 0.
-      return new CharsRef(
+      String expanded =
           new String(word.chars, 0, word.offset + breakPos)
               + endChars
               + beginChars
-              + word.subSequence(breakPos + replacement.length(), word.length));
+              + word.subSequence(breakPos + replacement.length(), word.length);
+      // keep the preceding compound parts in the array, but keep positions relative to word.offset
+      return new CharsRef(expanded.toCharArray(), word.offset, expanded.length() - word.offset);
Trade-offs
Changes verdicts only for dictionaries that use the replacement field: valid later-join simplified forms are accepted, and the overflow words of these examples return a verdict. Native Hunspell's verdicts depend on the position and the pattern in ways hunspell(5) does not describe: with the checkcompoundpattern2/3 patterns it rejects fozarbar, furbar and bozanbar; with ff f ff it accepts schiffahrtdampf but rejects schiffschiffahrt. The fix accepts all of these words, so it also accepts some words native rejects (furfur, bozanbozan, schiffschiffahrt); stock Lucene already accepts first-join forms native rejects (fozarbar, furbar). It allocates what today's code allocates (new CharsRef(String) also copies the string). Not benchmarked.
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, seed DEADBEEF: stock plus the fixture lines fails 16 of 72 (five repro classes andTestSpellChecking), with assertions on and off; the primary test alone fails 2 of 3 both ways. - With the fix and the fixture lines:
--tests 'org.apache.lucene.analysis.hunspell.*'plus the five repro classes, 51 classes, 177 tests, 0 failures, 13 skipped (TestPerformance10 andTestAllDictionaries1 need external dictionaries or word corpora,TestAllDictionaries1 is@Ignored,TestHunspellRepositoryTestCases1 needs a Hunspell source checkout), so 164 ran and passed, with assertions on and off;TestSpellChecking's forceucase, checkcompoundpattern and simplifiedtriple cases included. :lucene:analysis:common:check -x test(google-java-format, ecj lint, forbidden APIs) passes with the fix, the fixture lines and the primary test.- Earlier, with the fix shadowed on
ea57360912ed: the finder's 3 of 3, the independent reproducer's 7 of 7, the devil's advocate's tests and Lucene's hunspell test classes 146 of 146 pass; the lookup trace readsschiffat the right offset. - Later, by probe on
a9779ef3c193, assertions on and off: a simplified join followed by a regular part (dampfschiffahrtdampf,donaudampfschiffahrtdampf) is false on main and true with the fix, as native Hunspell 1.3.2 and 1.7.2 answer. No test covers a pattern for which the fix does not shrink the tail (option C).
Revert to word.subSequence(0, breakPos) + ... (offset 0 is then right) and pass the whole word's first character, or the original array, to hasForceUCaseProblem separately.
Trade-offs
Same verdicts as A in principle, a larger diff in Hunspell.java. Not run. Reverting the line alone is not enough: for a simplified compound the FORCEUCASE check would read the current part's first letter (Hunspell.java:279, :290).
Stop when the remaining tail is not shorter than the current slice, or cap the depth by the word length.
Trade-offs
Prevents the StackOverflowError but not the false negatives. Not run. Not made redundant by A: after A the tail left after a simplified join is shorter than the slice only when the match position plus the replacement's length exceeds the length of beginchars, and the parser allows any lengths (CheckCompoundPattern.java:29-45). Executed: CHECKCOMPOUNDPATTERN x yx x with COMPOUNDMIN 1 and the words yx, z makes spell("yxz") throw StackOverflowError on main and with A, assertions on and off. The match is at the first join, where the offset is right, so this is a separate, contrived edge; native Hunspell 1.3.2 and 1.7.2 answer "misspelled".
Add a small COMPOUNDWORDMAX to the dictionary, or pass a checkCanceled hook with a budget to the Hunspell constructor.
Trade-offs
Stops the overflow (executed with COMPOUNDWORDMAX 3), not the false negatives. A large value is finite but costly: with 1024, spell("auu") made about a million stem lookups and allocated about 1.5 GB.
Downstream: a spell-checking service that loads such a dictionary and checks words its users type can see single spell or suggest calls fail with StackOverflowError, an Error that catch (Exception e) does not catch; indexing and search through HunspellStemFilter are not affected.
Differential testing: the stock jar's Hunspell.spell was compared with C Hunspell 1.7.2 on words generated from the 131 Hunspell 1.7.2 conformance fixtures. Lucene threw StackOverflowError on 11 generated words of the Telugu checkcompoundpattern4 dictionary; code reading found the offset, and three-part words on Lucene's own fixtures showed the false misspellings.
The method in full156 words
Method: differential testing against another implementation (the hunt counts this as testing, not as checking against an exact reference semantics).
- A generator built word lists from the 131 Hunspell 1.7.2 conformance fixtures: fixture words, every generated form, case variants, edits, two-part and three-part concatenations. A small C driver called
Hunspell_spellper word, and the results were compared with the stock Lucene jar. - On the
checkcompoundpattern4(Telugu sandhi) dictionary, Lucene threwStackOverflowErroron 11 words, such aspErupErupEruandsUrya-pEru; the fixture's own two-part words pass. - Code reading of
expandReplacementand its callers found the offset; a shadow fix confirmed it. Three-part words on Lucene's owncheckcompoundpattern2/3content (barfozar,barfur,barbozan) showed the silent false negatives, and the finder reduced both to a public-API JUnit. - An independent reproducer, two cross-model stages, a devil's advocate (who added the ChangeLog's German example), an adjudication and a credibility audit then checked it (see the checks).
No prior report found (159 query records over Lucene issues, PRs, commits, JIRA, the mailing lists, downstream trackers and the web, 2026-10-26). The only upstream items about this code are its own history, LUCENE-9717 (the feature) and LUCENE-9775 (the change that introduced the bug); no open PR touches the two files.
Searches4 searches
Registry verdict new: no report, issue, PR or discussion of this bug by anyone else was found. Related, not reports: #10814 / lucene-solr#2375 (LUCENE-9775, introduced it; no discussion of the offset or of three or more parts), #10756 / lucene-solr#2280 (LUCENE-9717, the feature; its ported fixtures are two-part), #10768 (LUCENE-9729, an earlier offset fix in the same class), native hunspell/hunspell#126 (2010, an analogous multi-part bug in the C++ prohibition patterns) and hunspell/hunspell#950 (2023, a dictionary author using the replacement field). Gaps: keyword-based searches; private channels are not visible.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; Elasticsearch, OpenSearch, Solr; web | 2026-10-26 | a scripted prior-report search, 37 queries | only the feature's own history |
| dev@, java-user@, issues@, commits@; JIRA (LUCENE) | 2026-10-26 | a scripted prior-report search, 24 queries | only LUCENE-9717, LUCENE-9775, LUCENE-9729 and notification mirrors |
| GitHub (apache/lucene, apache/lucene-solr, native hunspell, downstream) | 2026-10-26 | 94 read-only GraphQL searches, including all 218 apache/lucene items that mention hunspell; 43 items read in full | no report; 17 hits judged, none the same bug |
| Open PRs and fix status | 2026-10-26 | touched files of all 411 open apache/lucene PRs; commit history of both files on main, branch_10x and branch_10_6; local history | only #16422 touches a hunspell file (Dictionary.java); not fixed |
Introduced by LUCENE-9775 (902cb93db22, 2021-02-17), a one-line FORCEUCASE change to the CHECKCOMPOUNDPATTERN code added two weeks earlier; first released in 8.9.0, so no release had the feature without the bug. 11 releases from 8.9.0 to 10.5.2 and main fail; not fixed upstream.
Versions tested11 rows
Introduced by 902cb93db2274a0a1d424fb69fdd6be645887da5 "LUCENE-9775: Hunspell: make FORCEUCASE work when the first compound word is inherently title-case (#2375)" (@donnerpeter, 2021-02-17; lucene-solr#2375; issue #10814). It changed the expandReplacement expression from word.subSequence(0, breakPos) to new String(word.chars, 0, word.offset + breakPos) and left the offset at 0. The feature itself was d0ae2bd2b9c (LUCENE-9717, lucene-solr#2280, 2021-02-03, #10756), correct at that commit. Both reached 8.x in the squashed backport c6b964a11576 (lucene-solr#2499, LUCENE-9687, 2021-05-28), so 8.9.0 was the first release with the feature and with the bug. javap shows the same construction in every cached analysis-common jar from 8.9.0 to 10.5.1, and all 21 9.x and 12 10.x release tags contain 902cb93. No later commit changes the line, and no open PR touches the two files (2026-10-26).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | gradle: the primary test fails 2 of 3; the five repro classes plus TestSpellChecking with 3 fixture lines 16 of 72; assertions on and off |
main ea57360912ed | affected | finder, independent reproducer, cross-model stage, devil's advocate, adjudication, audit and follow-up re-runs: fail with -ea and -da |
| 10.5.2, 9.12.3 | affected | release jars: the finder's JUnit 2 of 3 and the independent reproducer's 6 of 7 fail; the German example fails on 9.12.3 |
| 9.9.0 | affected | release jars: the primary test fails 2 of 3 (it does not compile on 9.8.0, which has no SortingStrategy) |
| 10.3.2, 10.0.0, 9.8.0, 9.4.2, 9.0.0 | affected | main() probe: barfozar and barfur false, StackOverflowError from spell and suggest("auu") |
| 8.11.4, 8.10.1, 8.9.0 | affected | main() probe: the same (8.9.0 and 8.11.4 also the portable repro) |
| 8.8.2 | no API | the probe does not compile: no spell-checking class |
d0ae2bd2b9c (LUCENE-9717) and 2555418 | bisect | barfozar and barfur true, spell("auu") false, suggest returns (shadowed over the 9.0.0 jars) |
902cb93db22 (LUCENE-9775) | bisect | barfozar and barfur false, StackOverflowError from spell and suggest("auu") |
902cb93db22 with the line reverted | bisect | correct again: the one expression is the cause |
fix A on a9779ef3c193 | not affected | hunspell test package: 177 tests, 0 failures (164 pass, 13 skipped), assertions on and off; lint passes |
An independent reproducer, cross-model reviews (a third produced no verdict), a works-as-designed devil's advocate, an adjudication and a credibility audit. Every re-run on main failed with assertions on and off, every run of the repros with the fix passed, and native Hunspell 1.3.2 and 1.7.2 gave the expected verdicts.
Checks and verdicts458 words
Each check ran or read on its own; the registration check re-ran the tests with fresh seeds, and this doc re-ran them through gradle on a9779ef3c193 and traced the lookups.
| Check | Verdict | What it found |
|---|---|---|
| finder (differential testing) | candidate | 11 overflowing words on native's Telugu dictionary; JUnit fails 2 of 3 on main, 10.5.2 and 9.12.3; the portable probe fails on 8.9.0, 8.11.4 and 9.0.0; the fix passes. |
| cross-model review, works-as-designed lens | real, medium | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: root cause agreed, intended argument weak; a separate re-run failed 2 of 3. |
| cross-model review, refute lens | no verdict | It returned no verdict. |
| independent reproducer | real | Own 7-test JUnit in another package fails 6 of 7 on main (-ea, -da), 10.5.2 and 9.12.3; own one-line fix passes 7 of 7 and TestSpellChecking 53 of 53; native Hunspell 1.3.2 and 1.7.2 give the expected verdicts. |
| cross-model stage, root-cause lens | real, medium | Root cause agreed, inputs in contract, intended argument weak; a separate run re-ran the repro on main and 10.5.2 and the 146 hunspell tests, stock and fixed. |
| intended-behaviour devil's advocate | real | Intended argument weak; added the ChangeLog's German example and native's unmodified Telugu dictionary, both overflow; COMPOUNDWORDMAX 3 stops the overflow but not the false negatives. |
| adjudication | confirmed, high | Re-ran the independent JUnit (-ea, -da: 6 of 7 fail; with the fix 7 of 7 pass) and re-checked native Hunspell 1.3.2. |
| security screen | none (strict re-evaluation 2026-10-27) | Only spell and suggest reach it; stemming output unchanged; a request-level Error, and no lasting state change seen in a five-word check after the overflows. |
| credibility audit | keep | Own probe on native's unmodified Telugu dictionary: three-part words overflow on main and 10.5.2, the fixture's own words pass; the German example fails on main -da and passes with the fix. |
| this doc's gradle runs and lookup trace | confirmed | Stock main: the primary test fails 2 of 3, the five repro classes plus the fixture lines 16 of 72, assertions on and off. With the fix: 177 tests, 0 failures, 13 skipped, both modes; lint passes. The trace shows dampfs read instead of schiff. |
| independent fact and diagram checks | claim holds; errors fixed | An independent fact check (re-ran the repro, the fix and native Hunspell), a cross-model fact check by a reviewer from another model family (OpenAI GPT-5.6) and a diagram check all found the bug real. Their text errors (an assertions-mode label, the native position rule, the 9.9.0 release floor, passed vs skipped counts, fix A's termination claim and evidence tags) are fixed here and in the diagrams; a resolution probe added the mixed-join and x yx x cases. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 494 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,421 words
- Registry title
- Hunspell spell-checker: a CHECKCOMPOUNDPATTERN simplified compound form (the optional replacement field) after the first compound part is checked from the start of the whole word, so valid compounds such as dampfschiffahrt (dampf + schiff|fahrt with 'ff f ff') are rejected and some words (schiffschiffahrt, or auu with 'u u u') make spell()/suggest() throw StackOverflowError (expandReplacement returns offset 0 over an array that still holds the earlier parts)
- Area
- analysis / hunspell (Hunspell.spell and suggest compound checking, CHECKCOMPOUNDPATTERN replacements)
- Priority
- Low, rank 463: Hunspell rejects valid simplified compounds and can throw StackOverflowError, but no surveyed public dictionary uses the CHECKCOMPOUNDPATTERN replacement field.
- Impact class
- silent wrong results
- Impact note
- Only applications that call the opt-in Hunspell spell-checker (Hunspell.spell and Hunspell.suggest, and the Suggester that suggest uses) with a dictionary that uses the optional replacement field of CHECKCOMPOUNDPATTERN (simplified compound forms; none of the 191 public .aff files the finder surveyed uses it) are hit: valid compounds of 3 or more parts whose simplified boundary is not the first are reported as misspelled with no error, and words in which the replacement reappears in its own expansion make the call throw StackOverflowError (a 3-letter word with 'CHECKCOMPOUNDPATTERN u u u', words of native Hunspell's unmodified checkcompoundpattern4 fixture, schiffschiffahrt with the ChangeLog's German 'ff f ff' example); stemming, indexing and search (HunspellStemFilter, getRoots) are not affected [exec], no scale is needed, and every release from 8.9.0 to 10.6.0 has it (10.6.0 by reading).
- Summary
- You load a Hunspell dictionary whose CHECKCOMPOUNDPATTERN rule has a replacement, which hunspell(5) documents as 'The optional replacement parameter allows simplified compound form' (for example 'CHECKCOMPOUNDPATTERN ff f ff' from the Hunspell ChangeLog, for pre-reform German Schiffahrt = Schiff + Fahrt), and expect Hunspell.spell to accept the simplified form wherever it occurs in a compound, as native Hunspell 1.3.2 and 1.7.2 do for dampfschiffahrt, donaudampfschiffahrt, barfozar and barfur, and to return true or false for every word. Instead Lucene accepts schiffahrt but rejects dampfschiffahrt and donaudampfschiffahrt (and barfozar, barfur and barbozan on the content of its own checkcompoundpattern2/3 fixtures), and spell()/suggest() throw StackOverflowError for schiffschiffahrt, for 'auu' with the one-word dictionary au and 'CHECKCOMPOUNDPATTERN u u u', and for words of native Hunspell's own checkcompoundpattern4 (Telugu sandhi) fixture. The cause: CheckCompoundPattern.expandReplacement builds the expanded word from the start of the whole word (word.chars[0 .. word.offset + breakPos], which keeps the earlier compound parts for the FORCEUCASE check) but returns it as a CharsRef with offset 0, while its callers index it relative to the current part, so at the second and later boundaries the stem lookup starts at the beginning of the word and the remaining tail never gets shorter.
- Introduced
- 902cb93db2274a0a1d424fb69fdd6be645887da5, LUCENE-9775 'Hunspell: make FORCEUCASE work when the first compound word is inherently title-case' (apache/lucene-solr#2375, by donnerpeter; migrated issue apache/lucene#10814), on lucene-solr master, now part of the apache/lucene main history [read: git show in the history clone changes the one expandReplacement line from word.subSequence(0, breakPos) (relative to word.offset) to new String(word.chars, 0, word.offset + breakPos) and keeps new CharsRef(String), offset 0; git blame at the history head attributes the line to this commit, and later commits to the file (97464ebfcb9 #13049, 942065cc3e7 #13328) do not touch it] [exec: with the hunspell package of each commit shadowed over the 9.0.0 jars, the feature commit d0ae2bd2b9c (LUCENE-9717, lucene-solr#2280, 2021-02-03) and the parent 2555418 are correct, 902cb93 shows the bug, and 902cb93 with only that line reverted is correct]. Reached 8.x through the squashed branch_8x backport c6b964a11576 (lucene-solr#2499, LUCENE-9687; commit id from the ASF git bot comment on LUCENE-9687, not in the local clone; the bad line is in the 8.9.0 bytecode). A regression against the 2021-02-03 feature commit, but no release ever had the feature without the bug (2021-02-17 (main); 2021-05-28 (branch_8x backport))
- First affected version
- 8.9.0 [exec] (the first release with the spell-checking API and CHECKCOMPOUNDPATTERN; 8.8.2 has no Hunspell class and does not compile the repro [exec]); on the main line 9.0.0 [exec]
- Affected versions
- every release that has the feature: 8.9.0 - 8.11.4, 9.0.0 - 9.12.3 and 10.0.0 - 10.6.0 (10.6.0 by reading), and main ea57360912ed. Executed (history probe or version-portable main(), -ea): 8.9.0, 8.10.1, 8.11.4, 9.0.0, 9.4.2, 9.8.0, 9.12.3, 10.0.0, 10.3.2, 10.5.2 and main; the finder's and the independent reproduction's JUnits fail on 9.12.3, 10.5.2 and main (main also -da), the intended-behaviour check's German example on 9.12.3 and main (-ea and -da) [exec]. [read] javap shows the same new String(chars, 0, offset + breakPos) construction in expandReplacement in every cached analysis-common jar from 8.9.0 to 10.5.1, and all 21 9.x and 12 10.x release tags contain 902cb93. Not affected: 8.8.2 and older (no spell-checking API) [exec]. Not fixed upstream: no commit after 902cb93 changes expandReplacement, and no open apache/lucene PR touches CheckCompoundPattern.java or Hunspell.java (2026-10-26). All runs on Linux aarch64 with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by code reading
- Upstream and prior reports
- none found (2026-10-26, read-only, the prior-report record verdict new, 159 query records: two scripted prior-report searches over GitHub issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web; 94 read-only GitHub GraphQL searches, including a listing of all 218 apache/lucene items that mention hunspell; 43 items read in full; the touched files of all 411 open apache/lucene PRs; local git history; 17 hits judged, none the same bug; the finder's and the intended-behaviour check's searches agree). Closest items: #10814 (LUCENE-9775) and lucene-solr#2375, the change that introduced the bug (no discussion of the offset or of compounds of 3 or more parts; the author's review note says the earlier parts are kept for the case check); #10756 (LUCENE-9717, lucene-solr#2280), the feature, whose ported fixtures have only 2-part simplified forms; #10768 (LUCENE-9729), an earlier offset/length fix in the same class (precedent, not this bug); native hunspell/hunspell#126 (2010), an analogous multi-boundary CHECKCOMPOUNDPATTERN bug in the C++ code (prohibition patterns, not the replacement); #16422 (the only open PR touching a hunspell file, Dictionary.java only). Not fixed upstream.
- Lucene commit tested
- main
a9779ef3c193(gradle in a scratch worktree, assertions on and off, stock and with the fix; the module's lint check) and mainea57360912ed(hunt, independent checks, adjudication, audit, follow-up re-runs and a lookup-trace probe; no file of the analysis-common module differs between the two commits); the release jars 8.9.0, 8.10.1, 8.11.4, 9.0.0, 9.4.2, 9.8.0, 9.9.0, 9.12.3, 10.0.0, 10.3.2 and 10.5.2 (8.8.2 has no spell-checking API; the releases in between by bytecode and release tags); the feature commitd0ae2bd2b9c, the introducing commit902cb93db22, its parent and the commit with the line reverted, shadowed over the 9.0.0 jars; native Hunspell 1.3.2 and 1.7.2 as the reference. OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/CheckCompoundPattern.java at ea57360912ed: :94-103 expandReplacement (:97 new String(word.chars, 0, word.offset + breakPos), wrapped in new CharsRef(String), offset 0)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java at ea57360912ed: :34-47 class javadoc (replacement for native Hunspell 'for many languages'; unsupported: Hungarian, non-BMP, PHONE), :71-74 (spell javadoc 'whether the given word's spelling is considered correct according to Hunspell rules'), :213-247 checkCompounds (:214 the compoundMax bound, :215-218 the FORCEUCASE offset-0 guard), :249-267 checkCompoundPatternReplacements (:257 findStem(expanded.chars, expanded.offset, breakPos, ...)), :269-286 checkCompoundsAfter (:284 recursion on new CharsRef(word.chars, breakOffset, remainingLength)), :574-597 suggest (default 250 ms limit, RETURN_PARTIAL_RESULT from the default constructor :55-57)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:152 (compoundMin = 3, compoundMax = Integer.MAX_VALUE)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/checkcompoundpattern2.aff, .dic, .good (fozar, fur, barfoo), checkcompoundpattern3.* (all simplified forms 2-part); TestHunspellRepositoryTestCases.java:38 EXPECTED_FAILURES (checkcompoundpattern4 not excluded)
- The finding in 30 seconds
a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/CheckCompoundPattern.java:94-103a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:100, 150-161, 213-247, 249-267, 269-286a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:152, 439
- Who is affected
a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Suggester.java:184-185, 215, 298, 301; HunspellStemFilter.java:86, 111; Hunspell.java:165, 300, 574-597
- Why it looks unintended
a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:35-46, 71-74a Lucene main checkout lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestSpellChecking.java:97-106; TestHunspellRepositoryTestCases.java:38-46, 57-59; checkcompoundpattern2.good, checkcompoundpattern3.good
- Suggested fix
a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:279, 288-292; a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/CharsRef.java:60-64
- TestCompoundPatternReplacementRecursion.java (JUnit test):
repro/LFV-377/src/org/apache/lucene/analysis/hunspell/TestCompoundPatternReplacementRecursion.java(38 lines)
A picture of the worked example, made in parallel with this doc; the alt text describes the example.
assets/LFV-377/bug.png(494 KB)