SimpleNaiveBayesDocumentClassifier (module lucene/classification) classifies a whole Document. For every class it adds, per value of each configured text field, a log prior plus the value's log-likelihood averaged over its tokens, then normalises the class scores into probabilities that sum to 1.
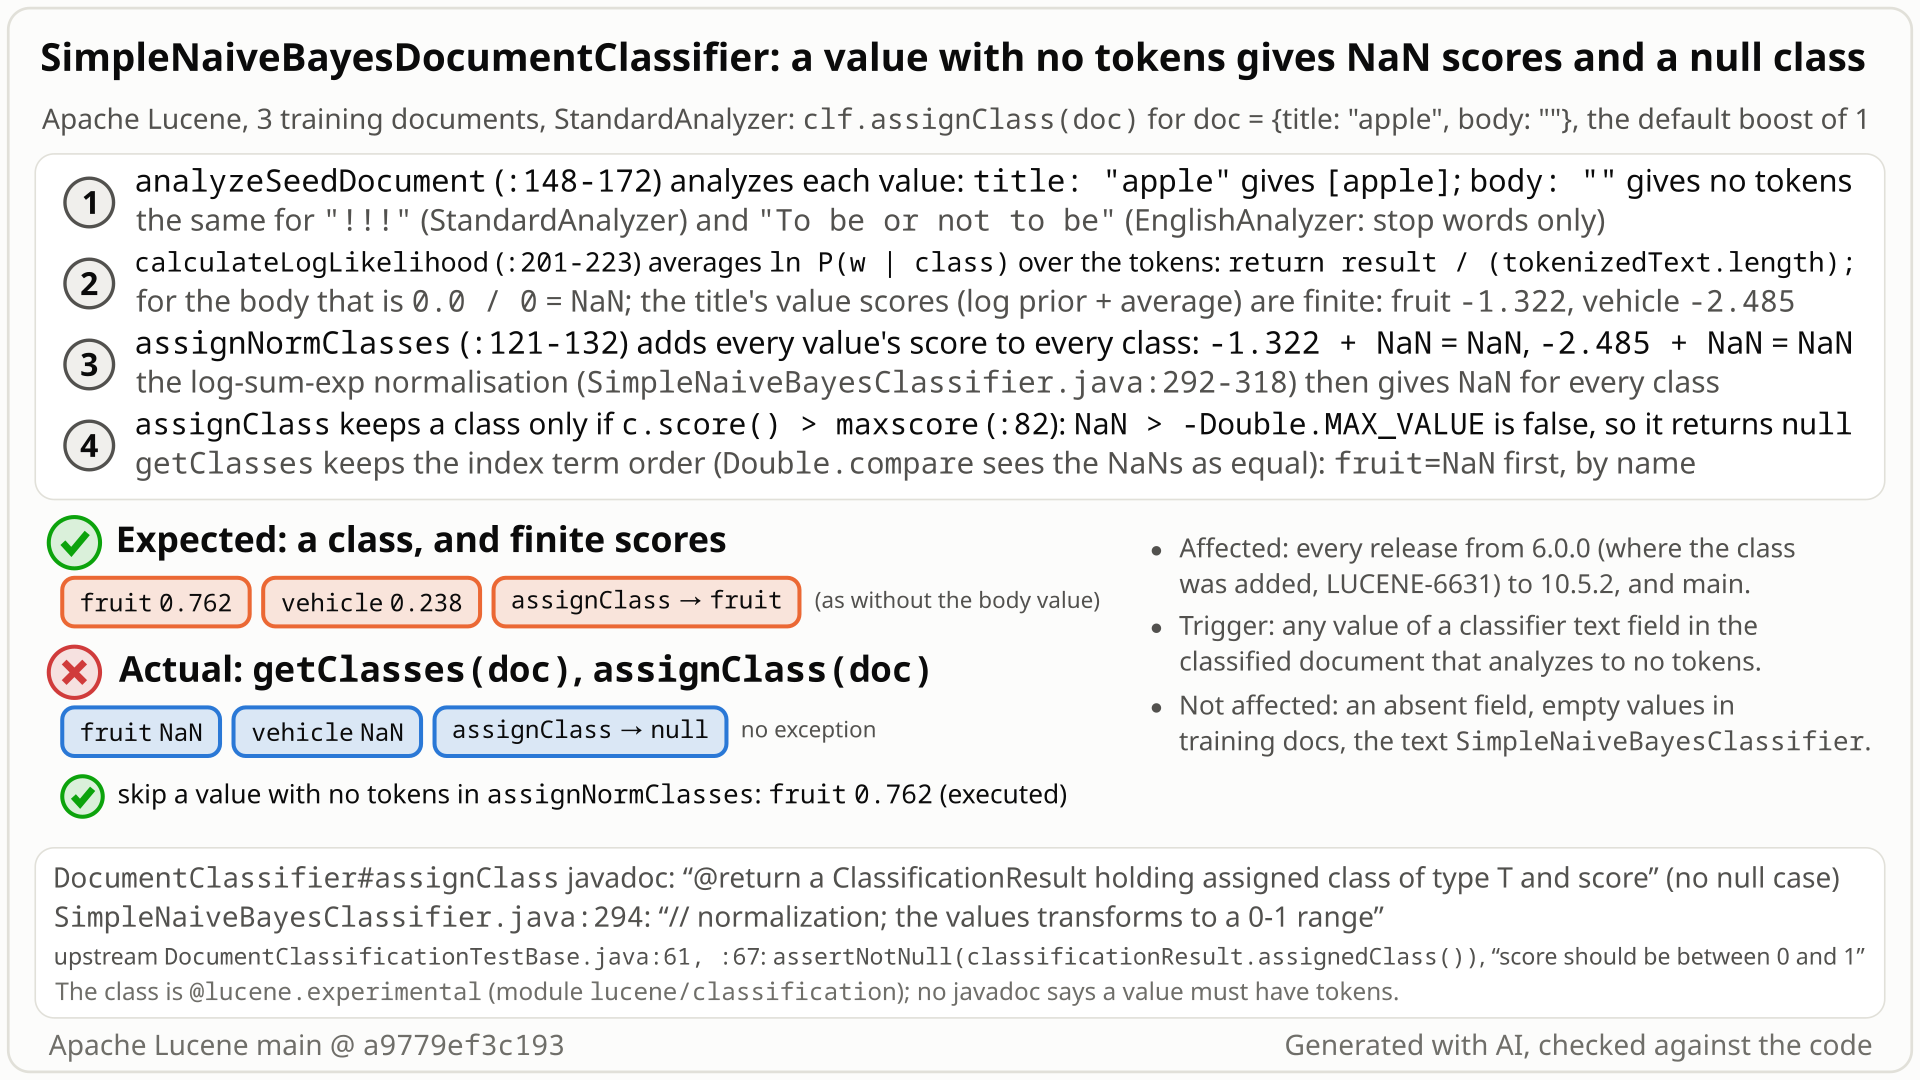
assignClass returns null, where fruit 0.762 is expected. Select the still to open it at full size. Generated with AI, checked against the code.- Train
SimpleNaiveBayesDocumentClassifieron three documents with text fieldstitleandbody(stockEnglishAnalyzer): apple / "sweet fruit" is fruit, pear / "green fruit" is fruit, car / "four wheels" is vehicle. Classify title "apple": fruit 0.762, vehicle 0.238. - Add a body that carries no words:
"","To be or not to be"(all stop words) or"!!!". You expect fruit again, with probabilities that sum to 1. - You get fruit = NaN and vehicle = NaN, and
assignClassreturns null. No exception, with assertions on or off; one empty body value next to five "sweet fruit" values does the same. - Why: each value adds its log prior plus the sum of log P(word | class) divided by its token count, here 0.0 / 0 = NaN. It is added to every class, the normalisation spreads it, and
NaN > maxis never true. getClasses(doc, 1)then returns the first class name in term order: title "car" alone gives vehicle 0.556, but with an empty body it gives fruit (NaN). Skipping values with no tokens fixes it.
Users of the opt-in, @lucene.experimental lucene/classification module who classify documents with SimpleNaiveBayesDocumentClassifier. One value in any configured text field that analyzes to no tokens is enough: an empty value, stop words only, or punctuation only. No setting or scale is needed; empty values in training documents do not trigger it.
Mechanism, terms and numbers692 words
SimpleNaiveBayesDocumentClassifier scores each class by adding, for every value of every configured text field of the input Document, a log prior plus the value's log-likelihood, which is the sum of log P(w|c) over the value's tokens divided by the number of tokens. A value with no tokens, such as an empty TextField or one that the analyzer reduces to nothing (stop words only, punctuation only), gives 0.0 / 0 = NaN. That NaN is added to every class, the log-sum-exp normalisation turns every probability into NaN, assignClass returns null because NaN > maxscore is never true, and getClasses lists the classes in index term order. On three training documents, title "apple" gives fruit 0.762, and the same title with an empty, stop-word-only or punctuation-only body gives NaN for both classes and no class. It is silent, with assertions on or off, needs no setting, and the division is in all 83 release tags checked from 6.0.0 to 10.5.2 and in main; skipping values with no tokens fixes it.
- Document classifier:
new SimpleNaiveBayesDocumentClassifier(reader, query, classFieldName, field2analyzer, textFieldNames...)learns from the labelled documents of an index (the class is a term ofclassFieldName) and classifies an unseenDocument:assignClass(doc)returns the best class with its score,getClasses(doc)all classes sorted by score. - Per-value score: the input document's values are analyzed with the field's analyzer (
SimpleNaiveBayesDocumentClassifier.java:148-172). For every class and every value, the class score gainslog prior + log-likelihood * boost(:121-131). - Log-likelihood: the sum of
log P(w|c)over the value's tokens, divided by the number of tokens (:201-223). The original comment explains the division: "this is normalized because if not, long text fields will always be more important than short fields" (commit71cea88773e, 2015). - Normalisation: a log-sum-exp turns the class scores into probabilities, "the values transforms to a 0-1 range" (
SimpleNaiveBayesClassifier.java:292-318, comment at:294).
- An empty value, or one whose tokens are all removed by the analyzer, gives a token array of length 0 (an absent field gives an empty list, so the scoring loop never runs for it).
calculateLogLikelihoodthen skips its loop and returnsresult / (tokenizedText.length)withresult = 0.0and length 0 (:222):0.0 / 0 = NaN.assignNormClassesaddsprior + NaN * boost = NaNto every class (:124-130).- The normalisation takes the top score as
smaxand sumsexp(score - smax): one NaN input makes every output NaN. assignClasskeeps a result only ifc.score() > maxscore, starting from-Double.MAX_VALUE(:80-87); with NaN this is never true, so it returnsnull.getClassessorts withDouble.compare(ClassificationResult.java:31-33), which treats all NaN values as equal, so the list stays in class-term order andgetClasses(doc, n)returns the first n class names (SimpleNaiveBayesDocumentClassifier.java:98-103).
Index: {apple, "sweet fruit", fruit}, {pear, "green fruit", fruit}, {car, "four wheels", vehicle}, EnglishAnalyzer (it stems apple to appl). Title field: 3 postings over 3 documents, so 1.0 unique term per document.
| class | word probability of appl | log | log prior | title value | empty body value |
|---|---|---|---|---|---|
| fruit | (1 + 1) / (1.0 x 2 + 3) = 0.4 | -0.916 | log(2/3) = -0.405 | -1.322 | -0.405 + 0.0 / 0 = NaN |
| vehicle | (0 + 1) / (1.0 x 1 + 3) = 0.25 | -1.386 | log(1/3) = -1.099 | -2.485 | -1.099 + 0.0 / 0 = NaN |
Without the body: fruit 0.7619, vehicle 0.2381. With the empty body: both NaN, assignClass = null. Executed cases (stock main):
| input | getClasses | assignClass |
|---|---|---|
| title "apple", no body | fruit 0.7619, vehicle 0.2381 | fruit |
| title "apple", body "sweet" | fruit 0.9014, vehicle 0.0986 | fruit |
title "apple", body "", "To be or not to be" or "!!!" | fruit NaN, vehicle NaN | null |
title "apple", five "sweet fruit" bodies and one "" | fruit NaN, vehicle NaN | null |
| title "car", no body | vehicle 0.5556, fruit 0.4444 | vehicle |
title "car", body "" | fruit NaN, vehicle NaN (getClasses(doc, 1) = fruit) | null |
text SimpleNaiveBayesClassifier, input "" | fruit 0.6667, vehicle 0.3333 | fruit |
KNearestNeighborDocumentClassifier, title "apple", body "" | fruit 0.5639 |
Exposure and likelihood271 words
- Who is exposed. Applications that classify documents with
SimpleNaiveBayesDocumentClassifier("A simplistic Lucene based NaiveBayes classifier",@lucene.experimental). No other Lucene module uses the class. - What triggers it. One value of any configured text field in the document being classified that analyzes to no tokens: an empty description, a title made only of stop words ("To be or not to be" under
EnglishAnalyzer), a value of punctuation or symbols. Three training documents and stock analyzers show it; one such value among many non-empty ones is enough. - What breaks. Every class probability is NaN and
assignClassreturnsnull, so a caller that readsassignClass(doc).assignedClass()throws aNullPointerExceptionlater, and a caller that takesgetClasses(doc, 1)gets the first class name in index term order whatever the document says. Nothing fails inside Lucene, with assertions on or off. - Not affected. Classification after empty values in training documents (they enter only through index statistics; with 50 such training documents in the index a normal document still got finite scores and the right class), later calls on the same instance, the index, and the other classifiers on the same input. A different case, not this bug: if every training value of a configured text field is empty, so the field has no indexed terms, classifying a document with tokens in that field throws a
NullPointerException(getTextTermFreqForClass,:233-236); the fact check reproduced it, and it has not been checked for prior reports. - How likely. Such values are ordinary in real data and trigger it every time, but the module has few users, and no report of it was found since 6.0.0 (2016).
The test shows that SimpleNaiveBayesDocumentClassifier returns no class when one field value of the document has no tokens ({title: 'apple', body: ''}): the value's log-likelihood is 0.0 / 0 = NaN, which makes every class score NaN.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.classification.document;

import java.util.List;
import java.util.Map;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.classification.ClassificationResult;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestSimpleNaiveBayesDocumentClassifierEmptyField extends LuceneTestCase {

  public void testEmptyFieldValue() throws Exception {
    Analyzer analyzer = new StandardAnalyzer();
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
        w.addDocument(
            List.of(
                new TextField("title", "apple", Field.Store.NO),
                new TextField("body", "sweet fruit", Field.Store.NO),
                new StringField("cls", "fruit", Field.Store.NO)));
        w.addDocument(
            List.of(
                new TextField("title", "car", Field.Store.NO),
                new TextField("body", "four wheels", Field.Store.NO),
                new StringField("cls", "vehicle", Field.Store.NO)));
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        SimpleNaiveBayesDocumentClassifier classifier =
            new SimpleNaiveBayesDocumentClassifier(
                reader, null, "cls", Map.of("title", analyzer, "body", analyzer), "title", "body");
        Document doc = new Document();
        doc.add(new TextField("title", "apple", Field.Store.NO));
        doc.add(new TextField("body", "", Field.Store.NO));
        ClassificationResult<BytesRef> result = classifier.assignClass(doc);
        // expected a class with a finite score; actual null, because every class score is NaN
        assertTrue(
            "expected a class with a finite score; assignClass: "
                + result
                + ", getClasses: "
                + classifier.getClasses(doc),
            result != null && Double.isFinite(result.score()));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-380/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/classification/build/libs/lucene-classification-$V.jar
CP=$CP:$LUCENE/lucene/grouping/build/libs/lucene-grouping-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.classification.document.TestSimpleNaiveBayesDocumentClassifierEmptyField
- Expected vs actual
- Expected a non-null class with a finite score; actual
assignClassreturns null andgetClassesgives fruit=NaN and vehicle=NaN, with-eaand-da.
More files, environment, full output53 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected a class with a finite score; assignClass: null, getClasses: [ClassificationResult[assignedClass=[66 72 75 69 74], score=NaN], ClassificationResult[assignedClass=[76 65 68 69 63 6c 65], score=NaN]]
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
org.apache.lucene.classification.document.TestSimpleNaiveBayesDocumentClassifierEmptyField.testEmptyFieldValue(TestSimpleNaiveBayesDocumentClassifierEmptyField.java:62)assignClassreturns "a ClassificationResult holding assigned class ... and score", with no null case; scores are normalised "to a 0-1 range".- The upstream test base asserts a non-null class and a score in [0, 1]; nothing requires values to have tokens.
- On the same input the field-absent path, the text classifier and the k-NN document classifier stay finite.
The full argument239 words
- Interface contract.
DocumentClassifier.assignClass: "Assign a class (with score) to the given Document", returning "a ClassificationResult holding assigned class of type T and score" (DocumentClassifier.java:31-40). OnlygetClassesmentionsnull, "if the classifier can't make lists" (:48-49,:62-63). The contract is implied, not explicit: no javadoc promises a finite score, and the implementation already returnsnullwhen the index has no class terms at all. - Range. "normalization; the values transforms to a 0-1 range" (
SimpleNaiveBayesClassifier.java:156,:294). NaN is not in that range. - The comment above the division describes a sum,
log(P(d|c)) = log(P(w1|c))+...+log(P(wn|c))(SimpleNaiveBayesDocumentClassifier.java:221), which is 0 for no tokens, not NaN. - Tests.
DocumentClassificationTestBase.checkCorrectDocumentClassificationasserts a non-null class (:61) and0 <= score <= 1(:67);ClassificationTestBaseasserts a non-null result (:93, a line added on purpose by LUCENE-7981, #9030, 2017) and a non-null class (:95, older). No test uses an empty or stop-word-only value, and both fixes keep the whole module suite green. - History. The division is deliberate length normalisation from the commit that created the class (LUCENE-6631,
71cea88773e, 2015); the zero-length case was never handled. LUCENE-5698 (552c367c5d2, 2019) only inlined it. The issue's description and 21 comments do not mention empty values. - Legal input. No javadoc says field values must produce tokens;
TextFieldandIndexWriteraccept empty values, and stock analyzers remove stop words and punctuation.
The devil's-advocate check214 words
The strongest "intended" case (built by an intended-behaviour checker; a cross-model reviewer rated it weak): the class is @lucene.experimental and "simplistic", the division is deliberate length normalisation, and an average over zero tokens is undefined, so a caller who passes empty values gets what they asked for.
Why it fails: no javadoc, test, CHANGES or MIGRATE entry, issue or list thread states a "values must have tokens" precondition, and such values are legal input; one empty value cancels the evidence of every other field and value, and assignClass returns no class where its javadoc describes a result holding a class and a score; every sibling path (field absent, the text SimpleNaiveBayesClassifier, KNearestNeighborDocumentClassifier) returns a finite score and a class on the same input; @lucene.experimental allows API changes, not results outside the documented range. The independent reproduction, the cross-model review and the intended-behaviour check rated the bug real and the adjudication confirmed it with high confidence; the refute-lens cross-model review gave only a procedural "not real" at low confidence (it could not run Java) while agreeing with the root cause. Not settled: whether an empty value should count like an absent one (fix A), keep its prior (fix B) or be rejected with an exception; a maintainer could reasonably choose any of these.
Recommended Skip a value with no tokens (fix A)
Skip a field value that has no tokens in assignNormClasses (3 added lines), so it counts like an absent value: the repro then gives fruit 0.7619, the no-body result. The new test, the closest suites, the whole lucene/classification suite (assertions on and off) and check -x test pass with it.
           for (String[] fieldTokensArray : tokensArrays) {
+            if (fieldTokensArray.length == 0) {
+              continue; // no tokens, no evidence: treat the value as absent
+            }
             fieldScore +=
                 calculateLogPrior(term, docsWithClassSize)
All options and trade-offs3 options · 653 words
Two fixes were built and validated in a scratch worktree of a9779ef3c193. Ask upstream only for finite scores and a class; that an empty value scores like an absent one is fix A's design choice, not a documented promise. Other defensible choices, not built: reject a value with no tokens with an exception, document a precondition, or guard the normalisation against NaN.
In assignNormClasses (SimpleNaiveBayesDocumentClassifier.java:124), continue when the value's token array is empty; an empty value then adds neither the prior nor a likelihood, exactly like an absent field. The hunt's own fix is the same change.
           for (String[] fieldTokensArray : tokensArrays) {
+            if (fieldTokensArray.length == 0) {
+              continue; // no tokens, no evidence: treat the value as absent
+            }
             fieldScore +=
                 calculateLogPrior(term, docsWithClassSize)
Trade-offs
- An empty, stop-word-only or punctuation-only body gives the no-body result: fruit 0.7619 for title "apple", vehicle 0.5556 for title "car".
- A document whose every value is empty gets uniform scores (0.5 / 0.5,
assignClass= the first class), which is what a document with no fields at all already gets today; the textSimpleNaiveBayesClassifierreturns the prior (0.6667) for empty input instead.
What the checks validated
- Gradle, JDK 25: the new test fails 3 of 4 on stock with assertions on and off; with the fix, the new test plus
TestSimpleNaiveBayesDocumentClassifier,TestSimpleNaiveBayesClassifierandTestKNearestNeighborDocumentClassifierpass (4 suites, 15 tests); the whole:lucene:classification:testpasses with assertions on and off (13 suites, 47 tests, 1 skipped, 0 failures each);:lucene:classification:check -x testpasses. - Standalone runner with the fix shadowed: the new test 4 of 4 (
-ea,-da), the finder's test 2 of 2, the independent reproducer's test 6 of 6. - Earlier, on
ea57360912ed: the 42 upstream classification tests and the security probe (poisoned documents get the no-body result).
At the division (SimpleNaiveBayesDocumentClassifier.java:222), return 0 when the value has no tokens: the empty sum the comment above it describes.
     // log(P(d|c)) = log(P(w1|c))+...+log(P(wn|c))
+    if (tokenizedText.length == 0) {
+      return 0; // empty sum; dividing by the length would give 0.0 / 0 = NaN
+    }
     return result / (tokenizedText.length);
Trade-offs
- Scores become finite, but the empty value still adds its class prior once more (the per-value prior at
:125-126), which pulls the result towards the larger class: title "apple" plus an empty body gives fruit 0.8649 instead of 0.7619, and title "car" plus an empty body gives fruit 0.6154 while "car" alone gives vehicle 0.5556. So an empty value can still change the class. - The smallest change at the division; the adjudication noted upstream may prefer it if they see the per-value prior as intended (the audit lists both fixes as acceptable). With equal class priors it gives the same scores as fix A (arithmetic: the extra prior cancels in the normalisation; no run compared the two).
What the checks validated
- Gradle, JDK 25: the same four suites (15 tests) and the whole
:lucene:classification:testwith assertions on and off (13 suites, 47 tests, 1 skipped, 0 failures each);check -x testpasses; standalone: the new test 4 of 4, the finder's 2 of 2, the independent reproducer's 6 of 6.
Drop field values that analyze to no tokens before classifying (run the field's analyzer, or at least skip empty strings), or treat NaN scores and a null from assignClass as "unclassified" instead of taking the first entry of getClasses. Lucene itself stores nothing wrong (the classifier only reads the index), so the index needs no repair; an application that stored the returned class (for example through Solr's update processor) may need to reclassify the affected documents.
Trade-offs
Needs one extra analysis pass per value, or a NaN check in the caller.
Solr's opt-in classification update processor with algorithm=bayes uses this classifier and writes the returned class names into incoming documents that do not already carry the class field (the default algorithm is k-NN), so there a document with one zero-token field value would get the first class name in term order (code reading only).
An AI finder listed every division and logarithm in the naive-Bayes classifiers' raw scores and asked an SMT solver (Z3) which of them can produce NaN: the token-count division with zero tokens can, for every class. A bounded check of the real normalisation showed that one NaN spoils every class, and a public-API JUnit confirmed it on the stock jar.
The method in full174 words
Method: semi-formal (an SMT inventory plus a bounded check of the real code), then a JUnit test. A hunt unit (classification), 2026-10-26, main ea57360912ed.
- The finder wrote a Z3 4.12.2 model (floating-point arithmetic with an uninterpreted
log) of every division and log site in the classifiers' raw scores. Site S4,result / tokenizedText.lengthwith length 0, was satisfiable (a NaN field score for every class); with length >= 1 it was proved finite. The site was read in the code while building the inventory, so this was a guided rather than a blind find. - 21 of 21 Z3 and cvc5 lemmas characterised
normClassificationResults, and a bounded check of the real method over 1,082,400 special-value vectors (0 failures) showed that an output is NaN exactly when an input is NaN or +Inf, or every input is -Inf: one NaN poisons every class. - A public-API JUnit on the stock jar then witnessed it (fruit = NaN for an empty and a stop-word-only body), with assertions on and off, on main, 10.5.2 and 9.12.3.
No prior report found (searched 2026-10-26, refreshed 2026-10-27): 84 logged queries over GitHub issues, PRs and commits, JIRA, the Lucene and Solr mailing lists, downstream projects and the web; of the 408 open PRs only #16847 changes the class (int to long, keeping the division). Nearest: an NPE in the same class (LUCENE-7950, fixed in 7.1.0).
Searches6 searches
All 27 assessed hits are a different bug. The nearest items are listed in the last row.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, the old lucene-solr repository, apache/solr, Elasticsearch, OpenSearch, all of GitHub) | 2026-10-26 | the scripted prior-report search (16 issue and PR, 3 commit and 2 downstream queries) plus 16 manual searches: class names, "classification NaN", "classifier null", the module:classification label (68 items), open classification PRs | no report; #8999 (LUCENE-7950) and #9030 (LUCENE-7981) are the nearest |
| Open PRs | 2026-10-26 | 2026-10-26: the changed files of the 170 older or unlabelled of the 410 open apache/lucene PRs, and the path-based module:classification label for the other 240; 2026-10-27: the changed files of all 408 then-open PRs | #16847 edits calculateLogLikelihood (int to long) and keeps the division; #12295 and #681 touch other module files |
| JIRA and mailing lists | 2026-10-26 | all 47 LUCENE modules/classification titles; LUCENE and SOLR text searches; comments of 16 related issues; dev@, java-user@, issues@, commits@ and the Solr user and dev lists (37 CI-failure mails scanned) | no report; the solr-user@ empty-string thread is about the class field, not an input field |
| History, CHANGES and the web | 2026-10-26 | git log -S'tokenizedText.length', lucene/CHANGES.txt, web searches, the class author's design post | on main's history only the introducing commit (an all-branches search also lists branch-housekeeping commits); no CHANGES entry about empty values or NaN |
| Refresh (GitHub, read-only) | 2026-10-27 | SimpleNaiveBayesDocumentClassifier, "naive bayes NaN" and calculateLogLikelihood in apache/lucene issues and PRs; upstream main f7bcc0abd816 | no new item: calculateLogLikelihood returns only #7494 (LUCENE-6435, a different bug already assessed); line 222 unchanged |
| Nearest items (read) | 2026-10-26 | #8999 / LUCENE-7950, #9030 / LUCENE-7981, #9158 / LUCENE-8110, #5992 / LUCENE-4927, #7689 / LUCENE-6631, lucene-solr#544 / LUCENE-5698 | different defects (NPE without class field, getClasses bound, text-classifier underflow), a test-only non-null assertion, and the commits that added and inlined the division |
Present since the class was added by LUCENE-6631 (71cea88773e, 2015), so since 6.0.0; LUCENE-5698 (552c367c5d2, 2019) only inlined the division. Executed on 10 releases from 6.0.0 to 10.5.2 and on main: all fail. Not fixed upstream (main f7bcc0abd816, 2026-10-27).
Versions tested5 rows
Introduced by LUCENE-6631 (#7689), commit 71cea88773e (2015-10-20, "added document classification api and impls"; svn era, no pull request), which created the class with double normScore = result / (tokenizedText.length); // this is normalized because if not, long text fields will always be more important than short fields. LUCENE-5698 (552c367c5d2, 2019-01-18, first in 9.0.0) inlined it and dropped the comment. The division is in all 83 release tags of the history clone that contain the file.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test: 3 of 4 fail (gradle and the standalone runner, assertions on and off): fruit NaN, vehicle NaN, assignClass null |
| 10.5.2, 9.12.3 | affected | this doc's test: 3 of 4 fail, the same messages (assertions on and off; 9.12.3 with assertions off in the fact check's run) |
| 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 10.0.0 | release sweep | the finder's test fails 2 of 2 on each (6.0.0 also with assertions off); the independent reproducer's test fails 3 of 6 on 8.11.4 (its own run) and on 6.0.0 (the version-history runs's run) |
| 5.5.0, 5.5.5 | no API | the class does not exist (compile error) |
upstream main f7bcc0abd816 (2026-10-27) | code reading | line 222 still divides by the token count |
An independent reproducer (3 of 6 fail, controls pass), a devil's advocate, an adjudication (confirmed, high), an audit and cross-model reviews (OpenAI GPT-5.6, reading only) agree on the root cause; one review's "not real" was procedural. This doc's gradle runs reproduced it on main a9779ef3c193 and validated both fixes, and fact checks re-ran them.
Checks and verdicts447 words
Every executed check reproduced the same symptom (NaN for every class, assignClass null) and the same root cause at line 222.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | SMT inventory flagged the zero-token division; the JUnit test fails 2 of 2 on main with assertions on and off, on 10.5.2 and on 9.12.3, and passes with fix A. |
| cross-model review, refute lens | not real (low, procedural) | OpenAI GPT-5.6, reading only: it could not run Java, so the review voted not real on procedure only; it agreed with the root cause, called the inputs legal and the intended case weak. A separate re-run of the finder's test failed 2 of 2. |
| independent reproducer | real | Own 6-test class with other data and equal priors: 3 of 6 fail on main (assertions on and off), 10.5.2, 9.12.3 and 8.11.4 (and on 6.0.0 in the version-history runs's run of this test); 60 of 60 failures in 20 iterations; the 3 controls pass; 6 of 6 with fix A. |
| cross-model review, intended lens | real (medium) | OpenAI GPT-5.6, reading only; intended argument weak. The step re-ran the finder's test on main (assertions on and off) and a probe: body "sweet" fruit 0.901, body "" NaN and null. |
| devil's advocate | real (high) | Stock EnglishAnalyzer with the body "To be or not to be": NaN and null on main (assertions on and off) and 10.5.2; field-absent, k-NN document and text-classifier controls finite. No precondition anywhere. |
| adjudication | confirmed (high) | Re-ran the independent reproduction with a new seed (3 of 6 fail, assertions on and off) and the finder's test (2 of 2). |
| audit | keep | Re-ran both tests with assertions off; its own plain main() probe with the stock StandardAnalyzer gives NaN and null for an empty and a punctuation-only body, controls finite. |
| this doc | reproduced | New 4-test class through gradle and the standalone runner on main a9779ef3c193, 10.5.2 and 9.12.3; fixes A and B validated; found that fix B can flip the class ("car" plus an empty body gives fruit 0.615). |
| fact check | reproduced; 7 wording errors fixed | Separate AI tool. Re-ran the gradle command (assertions on and off), the standalone runner on main, 10.5.2 and 9.12.3 (assertions on and off), both fixes through the whole module suite and check -x test, and two probes: every number reproduced. Its 7 wording and attribution errors are fixed. |
| cross-model fact check | real; errors fixed | OpenAI GPT-5.6, reading only, over generated references (history, blame, tags, open PRs, Solr sources, run records): the core bug is real and well demonstrated; its 9 factual errors, 4 overclaims and 7 missing caveats are resolved. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 605 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,145 words
- Registry title
- SimpleNaiveBayesDocumentClassifier returns NaN for every class and null from assignClass when the document has a field value with no tokens (empty, stop words only or punctuation only), because each value's log-likelihood is divided by its token count (released since 6.0.0)
- Area
- classification / document classifiers (SimpleNaiveBayesDocumentClassifier.assignClass and getClasses)
- Priority
- Medium, rank 187: The same experimental classifier silently returns NaN scores and a null class whenever one field value analyzes to no tokens, which is ordinary data but needs an empty value, so it follows the two broader classification rows.
- Impact class
- silent wrong results
- Impact note
- Applications that use the opt-in, @lucene.experimental lucene/classification module and classify documents with SimpleNaiveBayesDocumentClassifier are hit whenever one of the classifier's text fields in the document being classified has a value that analyzes to no tokens (an empty TextField value, or a stop-word-only or punctuation-only value under stock analyzers such as EnglishAnalyzer or StandardAnalyzer): with no error, every class score is NaN, assignClass returns null and getClasses(doc, n) returns classes in index term order, whatever the other fields say; no setting or scale is needed, every release from 6.0.0 to 10.5.2 is affected, and empty values in training documents do not trigger it.
- Summary
- You train SimpleNaiveBayesDocumentClassifier on the fields title and body and classify the document {title: 'apple', body: ''} (or a body such as 'the of and' that the analyzer reduces to stop words), expecting a class with a finite score, as the DocumentClassifier.assignClass javadoc and the '0-1 range' normalisation comment imply and as the same document without the body value gets (fruit). Instead getClasses returns fruit=NaN and vehicle=NaN, and assignClass returns null. calculateLogLikelihood returns result / tokenizedText.length, which is 0.0 / 0 = NaN for a value with no tokens; assignNormClasses adds that NaN to every class, and neither the log-sum-exp normalisation nor the 'score > maxscore' test in assignClass can recover from it.
- Introduced
- 71cea88773e8fe1086d0f2d7829b17b9c23bcc63 'LUCENE-6631 - added document classification api and impls' (svn trunk r1709522; committed by GitHub tteofili from a JIRA patch by alessandrobenedetti; migrated issue apache/lucene#7689; no pull request) [read: git log --follow creates the file here, git log -S'tokenizedText.length' finds only this commit; exec: 5.5.0 and 5.5.5 lack the class, 6.0.0 fails]. git blame on main :222 points to 552c367c5d2 (LUCENE-5698, 2019-01-18, apache/lucene-solr#544), which only inlined the division and dropped its comment (behaviour unchanged). (2015-10-20)
- First affected version
- 6.0.0 [exec] (tagged 2016-04-07, the first release with the class: CHANGES 6.0.0 'LUCENE-6631: Lucene Document classification'; 5.5.0 and 5.5.5 lack the API [exec: compile error on the missing class])
- Affected versions
- Every release from 6.0.0 to 10.5.2 and main ea57360912ed; not fixed upstream (upstream main cf398bfb142c, 2026-10-26, still divides at line 222). [exec] the finder's JUnit fails 2 of 2 on 6.0.0 (-ea and -da), 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da), with API-spelling variants for older releases; the independent reproduction's JUnit fails 3 of 6 (controls pass) on main (-ea and -da), 10.5.2, 9.12.3, 8.11.4 and 6.0.0. [read] the division is present in all 83 release tags of the history clone that contain the file (6.0.0 to 10.5.2; 8.8.2-8.11.3 are not tagged there, 8.11.4 was executed).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3
- Upstream and prior reports
- none found (2026-10-26, read-only, the prior-report record verdict new: 84 logged queries: a scripted prior-report search (16 GitHub issue and PR, 3 commit, 2 downstream, 20 mailing-list queries over dev@, java-user@, issues@ and commits@, 4 JIRA and 6 web queries), 16 more GitHub searches (apache/lucene, apache/solr, Elasticsearch and OpenSearch, all of GitHub), 6 JIRA REST searches plus a read of the related classification issues and their comments, lists.apache.org searches of solr-user@, users@solr, dev@solr, java-user@ and dev@lucene (37 CI-failure mail bodies scanned), web searches, the full git history and CHANGES, and the changed files of all 410 open apache/lucene PRs; plus the finder's and the intended-behaviour check's scripted prior-report searches); no hit is the same bug. Nearest: #8999 / LUCENE-7950 (NPE in the same class when no document has the class field, fixed in 7.1.0, different cause), #9030 / LUCENE-7981 (a test-only assertion that classifiers return a non-null result: contract evidence), #9158 / LUCENE-8110 (getClasses(doc, max) bound), #5992 / LUCENE-4927 (underflow in the text classifier, fixed by log likelihood), #7689 / LUCENE-6631 (the introducing issue; no discussion of empty values). Open PR #16847 edits calculateLogLikelihood (int to long) but keeps the division, so a fix touches the same lines. Not fixed upstream (main cf398bfb142c, 2026-10-26, line 222 unchanged).
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27; itslucene/classificationsources are identical to the hunt'sea57360912ed) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 release jar (assertions on and off) and the 9.12.3 release jar (assertions on; the fact check also ran it with assertions off). The version-history runs ran the finder's test on 10 releases from 6.0.0 to 10.5.2 and on main, and showed that 5.5.0 and 5.5.5 lack the class. Fixes A and B were validated in the scratch worktree: the new test, the closest suites, the wholelucene/classificationsuite with assertions on and off, and:lucene:classification:check -x test. An independent fact check re-ran the main, 10.5.2 and 9.12.3 runs and both fix validations, with the same results.
- Finding record
lucene/classification/src/java/org/apache/lucene/classification/document/SimpleNaiveBayesDocumentClassifier.java:77-88 (assignClass, 'c.score() > maxscore'), :121-131 (assignNormClasses), :148-172 (analyzeSeedDocument), :201-223 (calculateLogLikelihood, :222 'return result / (tokenizedText.length);')lucene/classification/src/java/org/apache/lucene/classification/SimpleNaiveBayesClassifier.java:156 and :294 ('the values transforms to a 0-1 range'), :292-318 (normClassificationResults)lucene/classification/src/java/org/apache/lucene/classification/document/DocumentClassifier.java:31-40 (assignClass javadoc: 'holding assigned class ... and score'); lucene/classification/src/java/org/apache/lucene/classification/ClassificationResult.java:31-32 (compareTo by Double.compare); lucene/classification/src/test/org/apache/lucene/classification/document/DocumentClassificationTestBase.java:61, :67 (non-null class, score in [0, 1])
- The finding in 30 seconds
lucene/classification/src/java/org/apache/lucene/classification/document/SimpleNaiveBayesDocumentClassifier.java:44-49, 77-103, 105-136 (110-118, 121-131), 148-172, 181-191, 201-223 (221, 222)lucene/classification/src/java/org/apache/lucene/classification/SimpleNaiveBayesClassifier.java:156, 292-318 (294)lucene/classification/src/java/org/apache/lucene/classification/ClassificationResult.java:27-33
- Who is affected
lucene/classification/src/java/org/apache/lucene/classification/document/SimpleNaiveBayesDocumentClassifier.java:44-49, 148-172
- Why it looks unintended
lucene/classification/src/java/org/apache/lucene/classification/document/DocumentClassifier.java:31-40, 48-49, 62-63lucene/classification/src/java/org/apache/lucene/classification/SimpleNaiveBayesClassifier.java:156, 294lucene/classification/src/java/org/apache/lucene/classification/document/SimpleNaiveBayesDocumentClassifier.java:44-49, 221-222lucene/classification/src/test/org/apache/lucene/classification/document/DocumentClassificationTestBase.java:58-69 (61, 67)
- Suggested fix
lucene/classification/src/java/org/apache/lucene/classification/document/SimpleNaiveBayesDocumentClassifier.java:121-131, 221-222
- TestSimpleNaiveBayesDocumentClassifierEmptyField.java (JUnit test):
repro/LFV-380/src/org/apache/lucene/classification/document/TestSimpleNaiveBayesDocumentClassifierEmptyField.java(71 lines)
A light summary card (the PNG), made in parallel with this text from an executed probe trace on main a9779ef3c193 (assertions on and off, and with the fix as a control). The diagram uses StandardAnalyzer and the repro EnglishAnalyzer; the title "apple" gives the same numbers with both.
assets/LFV-380/bug.png(605 KB)