The union and drill-down-advance loops of DrillSidewaysScorer keep their chunk end in an int. Above 2,147,481,600 documents the exit test nextChunkStart >= maxDoc can never become true, because the step wraps negative first.
DrillSideways.searchreturns the hits of a drill-down query plus, for each drilled dimension, the facet counts as if that dimension were not drilled ("sideways"). Without an executor it does this in one pass, with a bulk scorer namedDrillSidewaysScorer.- Unless the base query is about 10 times cheaper than the drill-downs, that scorer walks the doc IDs in fixed chunks of 2,048: it gathers each chunk's matches, collects them, then moves the chunk end on by 2,048.
- It stops after the chunk whose end is at or past the segment's
maxDoc.
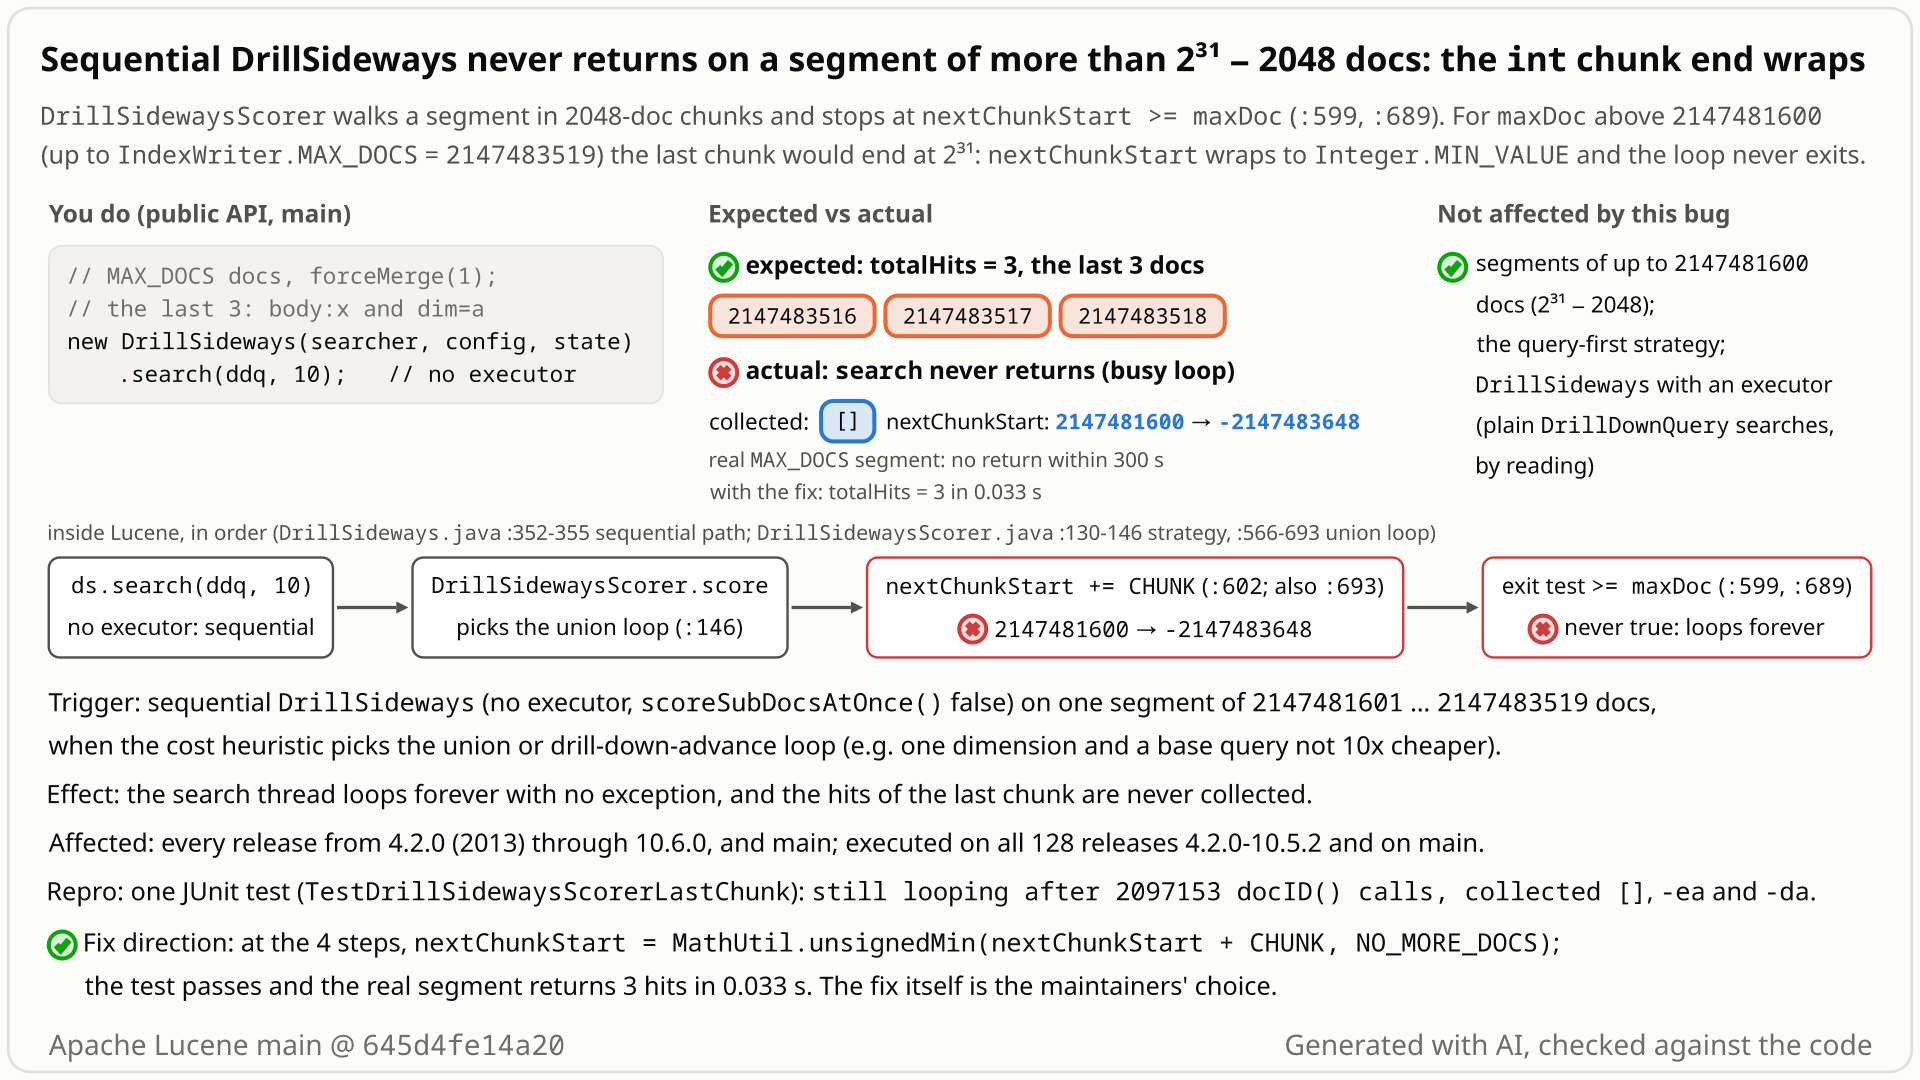
maxDoc = 2,147,483,519; the next step overflows to -2,147,483,648, so the exit test never fires and the last 1,919 doc IDs, with the 3 hits, are never collected. Select the still to open it at full size. Generated with AI, checked against the code.- Index
IndexWriter.MAX_DOCS= 2,147,483,519 documents with the default config andforceMerge(1)them into one segment; Lucene allows this, and its own@Monstertest does the same. The last 3 documents havebody:xand the facetdim=a. - Run a
DrillSidewayssearch without an executor (the default): aDrillDownQueryonbody:xwithadd("dim", "a"), top 10. You expect the 3 hits, as with 2,147,481,600 documents, where the same search returns in 0.029 s. - Instead it never returns (stopped after 300 s; with the fix it returns the 3 hits in 0.033 s). The scorer walks the segment in chunks of 2,048 doc IDs and stops once the chunk end, an
int, reaches the segment size: 2,048, 4,096, ..., 2,147,481,600. - 2,147,481,600 is the largest multiple of 2,048 an
intcan hold, and it is still below 2,147,483,519. Adding 2,048 overflows to -2,147,483,648, so the counter cycles forever without reaching the size, and the last 1,919 doc IDs, where the 3 hits are, are never collected.
Only applications that run DrillSideways without an executor (the default) on an index with one segment of more than 2,147,481,600 documents: within 1,918 documents of Lucene's hard limit, for example an index at the limit force-merged to one segment. There each search that takes the union or drill-down-advance loop hangs a search thread. Smaller segments are safe.
Mechanism, terms and numbers746 words
DrillSidewaysScorer, the bulk scorer behind a DrillSideways search without an executor, walks a segment in chunks of CHUNK = 2048 doc IDs in its union and drill-down-advance strategies. The chunk end is an int nextChunkStart = CHUNK; after each chunk the loop exits when nextChunkStart >= maxDoc and otherwise does nextChunkStart += CHUNK. The largest multiple of 2,048 an int can hold is 2,147,481,600 (2^31 - 2048). On a segment with maxDoc from 2,147,481,601 to IndexWriter.MAX_DOCS = 2,147,483,519 (1,919 legal sizes) the exit test fails there and the next step overflows to Integer.MIN_VALUE; no later value ever reaches maxDoc, so the search never returns, keeps a thread busy, and never collects the hits from doc 2,147,481,600 up. Through the public API on a real force-merged segment of MAX_DOCS documents the stock search did not return within 300 s, while the fixed build returned its 3 hits in 0.033 s and a segment of 2,147,481,600 documents returned them in 0.029 s. It needs the default sequential mode (scoreSubDocsAtOnce() false) and the union or drill-down-advance strategy, which a pure browse (no base query) takes unless its drill-down clauses together cost more than 10 x maxDoc; the query-first strategy and the concurrent (executor) mode do not use the loop. Every release from 4.2.0 (2013) through 10.6.0, and main, is affected; saturating the step with MathUtil.unsignedMin(nextChunkStart + CHUNK, NO_MORE_DOCS), the helper #14750 added to core to simplify its window-end overflow guards, fixes it.
DrillSidewaysScorer.java on main 645d4fe14a20: CHUNK = 2048 (:60); int nextChunkStart = CHUNK in doDrillDownAdvanceScoring (:353) and doUnionScoring (:566). Each round gathers the matches with while (docID < nextChunkStart), so nextChunkStart is the exclusive end of the current chunk. The exit test and the step, union strategy (:598-603, :689-693; the drill-down-advance copy is :475-480, :535-539):
      if (filledCount == 0) {          // no match in this chunk
        if (nextChunkStart >= maxDoc) {
          break;
        }
        nextChunkStart += CHUNK;
        continue;
      }
      ...                              // score and collect this chunk's matches
      if (nextChunkStart >= maxDoc) {
        break;
      }
nextChunkStart += CHUNK; // 2,147,481,600 + 2,048 wraps to -2,147,483,648maxDoc | chunk ends tried | outcome |
|---|---|---|
| 2,147,481,600 (2^31 - 2048) | 2,048, 4,096, ..., 2,147,481,600 | 2,147,481,600 >= maxDoc: exits |
| 2,147,481,601 ... 2,147,483,519 (1,919 sizes) | ..., 2,147,481,600, -2,147,483,648, ..., 0, ..., 2,147,481,600, ... | never >= maxDoc: spins forever |
After the wrap every value is a multiple of 2,048 in int, so at most 2,147,481,600, which is below maxDoc: the exit is unreachable, and no doc ID from 2,147,481,600 up is ever below the chunk end, so those hits are never collected. Both facts were proved with Z3 and cross-checked with cvc5. The counter runs through all 2^21 multiples of 2,048 and starts over. With all hits early in the segment, they are collected first, and then score() still never returns.
Each round only reads the iterators' current docID() and does cheap bookkeeping (in union baseIterator.docID(), :574). It calls no nextDoc or advance, no collector and no reader method, checks no interrupt flag and allocates nothing (the 2,048-slot arrays are allocated before the loop), so by reading it keeps one core busy and never ends (what was measured: the real-segment search had not returned after 300 s).
score() picks a strategy by cost (:130-147): query-first, which has no chunk loop, if scoreSubDocsAtOnce or baseQueryCost < drillDownCost / 10; else drill-down-advance if there are at least 2 dimensions and the second-cheapest (the dimensions are sorted by cost, DrillSidewaysQuery.java:182) costs less than a tenth of the base query; else union. A pure browse (no base query) uses MatchAllDocsQuery (DrillSideways.java:459), whose cost is maxDoc, so it takes query-first only if its drill-down clauses together cost more than 10 x maxDoc. In the real-segment run the base query and the dimension each match 3 documents, so union ran (the stack shows doUnionScoring).
DrillSideways.search without an executor (executor == null, DrillSideways.java:352-355; every constructor but the 5-argument one passes null) calls searchSequentially, which builds a DrillSidewaysQuery with scoreSubDocsAtOnce() (default false, :248-250) and runs searcher.search(dsq, ...) (:467); its weight's bulkScorer() returns a DrillSidewaysScorer (DrillSidewaysQuery.java:192-194). The concurrent mode runs plain DrillDownQuery searches instead (DrillSideways.java:483-508) and never builds this scorer (by reading, not executed).
Exposure and likelihood348 words
- Who. Applications that use
DrillSidewayswithout an executor (the default; the concurrent mode is opt-in) on an index that has one segment of more than 2,147,481,600 documents. The whole index is capped atIndexWriter.MAX_DOCS= 2,147,483,519, so that is an index within 1,918 documents of the hard limit with almost all of it in one segment, for example an index at the limit afterforceMerge(1), which is what Lucene's own@MonstertestTest2BDocsbuilds and then reads. - Settings. Default codec,
IndexWriterConfig, searcher and DrillSideways mode;DrillSidewaysitself is an opt-in facet-module API marked@lucene.experimental. - Effect. On such a segment a sequential drill-sideways search that takes the union or drill-down-advance strategy never returns, wherever its matches are, and keeps one search thread busy, unless a collector ends collection early by throwing
CollectionTerminatedExceptionbefore the loop wraps; the defaultDrillSidewayscollector includes the drill-downFacetsCollector, which never does that, so this takes a custom subclass. By reading, Lucene throws nothing and logs nothing. No Lucene time limit applies, but not because of this bug: sequential DrillSideways already rejectsIndexSearcher#setTimeout(its scorer only accepts the full doc-ID range; open issue #12032). Repeated requests can occupy every search thread (an inference, not executed). By reading, the loop allocates nothing (memory was not measured), and the index is not touched. - Not affected. Segments of up to 2,147,481,600 documents, the query-first strategy, and the concurrent (executor) mode.
- Likelihood: contrived. Almost no deployment has a single segment of 2.1 billion documents; one that does would see its faceted browsing hang outright rather than fail now and then.
- Mitigations until fixed (by reading, not executed): keep segments at or below 2,147,481,600 documents (for example, do not
forceMerge(1)an index at the limit); or subclassDrillSidewaysand returntruefromscoreSubDocsAtOnce(), which forces the query-first strategy at "some performance loss". The concurrent mode does not build this scorer, but it was not run at this scale and is not a verified workaround: by reading, its plain drill-down searches go through core scorers whose own behaviour at this size was not checked here.
One JUnit test in the facet package (it calls the package-private scorer, as Lucene's own TestDrillSideways does). A FilterLeafReader reports maxDoc() = IndexWriter.MAX_DOCS over a 1-document index; the base query and one dimension match the last 3 doc IDs. The base iterator fails the test after twice the chunks a terminating run needs, instead of hanging.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.facet;

import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.FilterLeafReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.LeafReader;
import org.apache.lucene.search.ConstantScoreScorer;
import org.apache.lucene.search.DocIdSetIterator;
import org.apache.lucene.search.FilterDocIdSetIterator;
import org.apache.lucene.search.LeafCollector;
import org.apache.lucene.search.Scorable;
import org.apache.lucene.search.ScoreMode;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestDrillSidewaysScorerLastChunk extends LuceneTestCase {

  private static LeafCollector recorder(List<Integer> docs) {
    return new LeafCollector() {
      @Override
      public void setScorer(Scorable scorer) {}

      @Override
      public void collect(int doc) {
        docs.add(doc);
      }
    };
  }

  public void testUnionScoringLastChunk() throws Exception {
    int maxDoc = IndexWriter.MAX_DOCS;
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        w.addDocument(new Document());
      }
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        // DrillSidewaysScorer reads only maxDoc() from the segment
        LeafReader segment =
            new FilterLeafReader(r.leaves().get(0).reader()) {
              @Override
              public int maxDoc() {
                return maxDoc;
              }

              @Override
              public CacheHelper getCoreCacheHelper() {
                return null;
              }

              @Override
              public CacheHelper getReaderCacheHelper() {
                return null;
              }
            };
        List<Integer> hits = new ArrayList<>();
        long chunks = maxDoc / 2048 + 1;
        DocIdSetIterator base =
            new FilterDocIdSetIterator(DocIdSetIterator.range(maxDoc - 3, maxDoc)) {
              long calls;

              @Override
              public int docID() {
                if (++calls > 2 * chunks) {
                  throw new AssertionError(
                      "expected score() to return the last 3 docs after "
                          + chunks
                          + " chunks; actual: still looping after "
                          + calls
                          + " docID() calls, collected "
                          + hits);
                }
                return in.docID();
              }
            };
        DrillSidewaysScorer.DocsAndCost dim =
            new DrillSidewaysScorer.DocsAndCost(
                new ConstantScoreScorer(
                    1f, ScoreMode.COMPLETE, DocIdSetIterator.range(maxDoc - 3, maxDoc)),
                recorder(new ArrayList<>()));
        new DrillSidewaysScorer(
                segment.getContext(),
                new ConstantScoreScorer(1f, ScoreMode.COMPLETE, base),
                new DrillSidewaysScorer.DocsAndCost[] {dim},
                false)
            .score(recorder(hits), null, 0, DocIdSetIterator.NO_MORE_DOCS);
        assertEquals(List.of(maxDoc - 3, maxDoc - 2, maxDoc - 1), hits);
      }
    }
  }
}
cd $LUCENE && ./gradlew :lucene:facet:test --tests org.apache.lucene.facet.TestDrillSidewaysScorerLastChunk -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
score()returns and collects the last 3 doc IDs, 2,147,483,516 to 2,147,483,518.- Observed
AssertionError: expected score() to return the last 3 docs after 1048576 chunks; actual: still looping after 2097153 docID() calls, collected [], thrown by the test's base iterator (docID(), test line 85) whenDrillSidewaysScorer.doUnionScoringcalls it at line 574, with assertions on and off.
More files, environment, full output458 words
One test class, one method. It sits in org.apache.lucene.facet because it calls the package-private DrillSidewaysScorer and DrillSidewaysScorer.DocsAndCost constructors, as upstream TestDrillSideways#testCollectionTerminated does; everything else is public API. A real segment of more than 2^31 - 2048 documents takes minutes to build, so the test wraps a 1-document index in a FilterLeafReader whose maxDoc() is IndexWriter.MAX_DOCS; the scorer reads nothing else from the reader. With equal costs and one dimension, score() takes the union strategy.
The loop calls the base iterator's docID() once per 2,048-doc chunk, so the iterator throws after twice the 1,048,576 chunks a terminating run needs: the endless loop becomes a failure after about 1.5 s. No threads, no sleeps, no random input. Pass -Ptests.asserts explicitly, because Lucene's build picks it at random from the seed; the result is the same both ways.
Regression test: this same test. It passes the facet module's format, ECJ and forbidden-apis checks unchanged, fails on stock main and passes with the fix. It covers the union strategy; the two drill-down-advance sites get the same one-line change.
At real scale (public API only, not the repro): default IndexWriterConfig, 2,147,483,519 documents, all empty except the last 3 (StringField("body", "x"), SortedSetDocValuesFacetField("dim", "a")), forceMerge(1) (one segment; index directory 31 MB; built in 380 s), then new DrillSideways(searcher, config, state).search(ddq, 10) on an IndexSearcher without an executor. Stock: no return within 300 s, the thread in doUnionScoring; fixed: totalHits=3 in 0.033 s; the same index with 2,147,481,600 documents: totalHits=3 in 0.029 s on the stock build.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; 10.6.0: fails; with the fix: passes |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the arithmetic is plain int) |
cp $REPRO/TestDrillSidewaysScorerLastChunk.java $LUCENE/lucene/facet/src/test/org/apache/lucene/facet/
cd $LUCENE && ./gradlew :lucene:facet:test --tests org.apache.lucene.facet.TestDrillSidewaysScorerLastChunk -Ptests.seed=DEADBEEF -Ptests.asserts=true
# same failure with -Ptests.asserts=false; 17 s and 22 s in the recorded runs (with --no-daemon --offline, on a built worktree)
# gradle, main 645d4fe14a20, seed DEADBEEF, -Ptests.asserts=true (identical with false)
TestDrillSidewaysScorerLastChunk > testUnionScoringLastChunk FAILED
    java.lang.AssertionError: expected score() to return the last 3 docs after 1048576 chunks; actual: still looping after 2097153 docID() calls, collected []
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:668D39A3329707FE]:0)
        at org.apache.lucene.facet.TestDrillSidewaysScorerLastChunk$3.docID(TestDrillSidewaysScorerLastChunk.java:85)
        at org.apache.lucene.facet.DrillSidewaysScorer.doUnionScoring(DrillSidewaysScorer.java:574)
        at org.apache.lucene.facet.DrillSidewaysScorer.score(DrillSidewaysScorer.java:146)
        at org.apache.lucene.facet.TestDrillSidewaysScorerLastChunk.testUnionScoringLastChunk(TestDrillSidewaysScorerLastChunk.java:106)
1 test completed, 1 failed

# release 10.6.0: the same message, at DrillSidewaysScorer.java:579 (10.x line numbering)

# real segment, public API (main ea57360912ed, identical DrillSidewaysScorer.java)
# N = 2,147,483,519 (MAX_DOCS), stock
leaves=1 maxDoc=2147483519
search did NOT return within 300 s; search thread stack:
    at org.apache.lucene.facet.DrillSidewaysScorer.doUnionScoring(DrillSidewaysScorer.java:603)
    at org.apache.lucene.facet.DrillSidewaysScorer.score(DrillSidewaysScorer.java:146)
    at org.apache.lucene.search.IndexSearcher.searchLeaf(IndexSearcher.java:852)
    ...
    at org.apache.lucene.facet.DrillSideways.searchSequentially(DrillSideways.java:467)
    at org.apache.lucene.facet.DrillSideways.search(DrillSideways.java:355)
# same index, fixed DrillSidewaysScorer
search returned after 0.033 s: totalHits=3 docs=[doc=2147483516 ..., doc=2147483517 ..., doc=2147483518 ...]
# N = 2,147,481,600 (2^31 - 2048), stock
search returned after 0.029 s: totalHits=3 docs=[doc=2147481597 ..., doc=2147481598 ..., doc=2147481599 ...]IndexWriter.MAX_DOCS(2,147,483,519) is the only documented size limit; Lucene's@MonstertestTest2BDocsforce-merges that many documents into one segment and reads it.BulkScorer.scoremust collect the matches in its range and return; this one never returns.- The core scorers #14750 touched guard the same window-end arithmetic (
longcaps, nowMathUtil.unsignedMin); this loop has no guard.
The full argument282 words
- The only documented limit is
MAX_DOCS. It is the "Hard limit on the maximum number of documents that may be added to the index" (IndexWriter.java:201-208); LUCENE-5843 added it so that going past it throws "instead of silently creating an unusable index" (CHANGES.txt). No javadoc ofDrillSideways,DrillDownQuery,DrillSidewaysQuery, the facet package,MIGRATE.mdorCHANGES.txtsets a lower per-segment limit. - Lucene's own tests use such a segment.
Test2BDocs(@Monster) force-mergesMAX_DOCSdocuments into one segment and walks its postings.TestIndexWriterMaxDocs.testExactlyAtTrueLimit(@Monster) indexesMAX_DOCSdocuments, asserts that searches returntotalHits == MAX_DOCSand force-merges them into one segment (committed only when the writer closes, after its last search). - The
BulkScorercontract.score"Collects matching documents in a range and return[s] an estimation of the next matching document" (BulkScorer.java:31-32); this one never returns and never collects the last chunk. - Core guards the same kind of arithmetic. The core bulk scorers and iterators that #14750 (jpountz, merged 2025-06-03, first released in 10.3.0) touched already guarded their window-end arithmetic with
longcaps such as(int) Math.min(max, (long) windowMin + WINDOW_SIZE); #14750 replaced them withMathUtil#unsignedMin, added because dividing the doc-ID space into windows "is prone to integer overflows if the size of the window is greater thanInteger.MAX_VALUE - windowStart". It simplified guards that were already overflow-safe and was not a bug fix. Today 11 core classes use the helper; no facet class does, andDrillSidewaysScorer's chunk loop has no guard of either kind. - Nothing covers the boundary. The facet tests have no test near 2^31 documents, and the LUCENE-4748 discussion mentions
CHUNKonly for its up-front array cost.
The devil's-advocate check172 words
The strongest case for "not a bug" (the devil's-advocate verifier and a reviewer from another model family, OpenAI GPT-5.6): DrillSideways is @lucene.experimental, the scorer is package-private, the scale is absurd (one segment of 2.1 billion documents), and workarounds exist (scoreSubDocsAtOnce(), smaller segments, possibly the concurrent mode); a custom collector that ends collection early also avoids the hang. A committer could say nobody runs drill sideways there, and that other facet code may have its own int limits at this scale (not checked).
Why it fails: @lucene.experimental is about API stability, not permission to hang; the package-private scorer is what the public default DrillSideways.search builds; the size is legal by Lucene's own documentation and tests, so "absurd" argues for low priority, not for intent; early termination needs a non-default collector setup; and core guards the same kind of window-end arithmetic in the scorers #14750 touched (long caps, simplified to MathUtil.unsignedMin), which this loop lacks. The cross-model reviewer rated the intended-behaviour case weak. A defect, small and low priority.
Recommended Saturate the chunk step at NO_MORE_DOCS with MathUtil.unsignedMin
At the 4 chunk steps, replace nextChunkStart += CHUNK with nextChunkStart = MathUtil.unsignedMin(nextChunkStart + CHUNK, DocIdSetIterator.NO_MORE_DOCS), the helper core's bulk scorers use for the same kind of window-end overflow. The step then ends the last chunk at NO_MORE_DOCS and the loop exits. With it the repro and the whole facet module test suite pass, with assertions on and off.
import org.apache.lucene.util.MathUtil;
...
// at each of the 4 chunk steps, instead of: nextChunkStart += CHUNK;
nextChunkStart = MathUtil.unsignedMin(nextChunkStart + CHUNK, DocIdSetIterator.NO_MORE_DOCS);
All options and trade-offs4 options · 627 words
One fix was built and validated through gradle in a scratch worktree of 645d4fe14a20; a long-arithmetic form of the same cap was validated by an independent reproducer; making the counter a long alone was run and does not work.
Saturate the chunk step at NO_MORE_DOCS with MathUtil.unsignedMin (validated by the checks) (recommended)
The 4 steps (DrillSidewaysScorer.java:479, :539, :602, :693) plus one import, +7/-4 lines after google-java-format (the two 8-space-indented sites wrap onto a second line).
import org.apache.lucene.util.MathUtil;
...
// at each of the 4 chunk steps, instead of: nextChunkStart += CHUNK;
nextChunkStart = MathUtil.unsignedMin(nextChunkStart + CHUNK, DocIdSetIterator.NO_MORE_DOCS);
Trade-offs
- Every chunk end below 2,147,481,600 is unchanged. At 2,147,481,600 the sum wraps to
Integer.MIN_VALUE, which is unsigned-greater thanNO_MORE_DOCS(2^31 - 1), so the step yieldsNO_MORE_DOCS: the last chunk ends there, itsdocID < NO_MORE_DOCStest still stops at an exhausted iterator, and the next exit test fires. Z3 proves the step is then exactly +2,048 orNO_MORE_DOCSand that every document of the last chunk is below it. - Cost: one unsigned compare per 2,048-doc chunk; the per-document loops are unchanged.
- The same helper and pattern as the core bulk scorers since #14750 (for example
DisjunctionMaxBulkScorer,ConstantScoreBulkScorer).
What the checks validated
- Scratch worktree of
645d4fe14a20, gradle, OpenJDK 25.0.3, seed DEADBEEF. Stock: the repro fails with assertions on and off. - With the fix: the whole
:lucene:facet:test(39 upstream suites plus the repro, includingTestDrillSideways,TestParallelDrillSidewaysandTestDrillDownQuery) runs 307 tests, 0 failures, with assertions on (7 skipped) and off (8 skipped);checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMainandforbiddenApisTestof:lucene:facetpass. - A 4-test JUnit covering both strategies at
MAX_DOCSplus two controls at 2^31 - 2048 fails 2 of 4 on stock and passes 4 of 4 with the fixed file, with assertions on and off. On the realMAX_DOCSsegment the same cap returned the 3 hits in 0.033 s. Other modules' tests were not run.
nextChunkStart = (int) Math.min((long) nextChunkStart + CHUNK, DocIdSetIterator.NO_MORE_DOCS); at the 4 steps.
Trade-offs
Equivalent behaviour; the recommended form reuses the helper core already uses.
What the checks validated
By the independent reproducer and the adjudication on main ea57360912ed (identical file): its public-API JUnit, 6 tests over both strategies and the smallest affected size, passes 6 of 6; not re-run here.
Declaring long nextChunkStart = CHUNK; at the two sites stops the wrap, but the repro still fails (run with assertions on), now with AssertionError: slot=1916 docID=2147483516 in doUnionScoring (line 588).
Trade-offs
By reading: the last chunk then ends at 2^31, so docID < nextChunkStart also holds for NO_MORE_DOCS (2^31 - 1), and the loop takes NO_MORE_DOCS as a match and calls nextDoc() on the exhausted iterator. The cap at NO_MORE_DOCS is the part that matters.
What the checks validated
Run on 645d4fe14a20 with the repro runner, assertions on only: fails as above. With assertions off it was not run; by reading, the outcome then depends on what the exhausted iterator's nextDoc() returns.
Override DrillSideways#scoreSubDocsAtOnce() to return true (query-first strategy, no chunk loop, "some performance loss"), or keep segments at or below 2,147,481,600 documents. The concurrent mode (an ExecutorService in the constructor) does not build this scorer, but it is not a verified workaround at this scale.
Trade-offs
By reading only, not executed. The first changes performance characteristics; the second limits merging of an index near the hard limit. The concurrent mode was not run at this scale, and its plain drill-down searches go through core scorers whose behaviour at this size was not checked here.
A read-only code search found no use of DrillSideways in Elasticsearch, OpenSearch or Solr, so exposure is limited to applications that embed the facet module directly.
A hunt for integer overflows near Lucene's size limits scanned the bytecode for a constant added to an int that then feeds a comparison, and flagged the +2048 steps in DrillSidewaysScorer. A JUnit on the stock jars failed first; SMT proofs (Z3, cross-checked with cvc5) then showed the loop cannot exit above 2^31 - 2048 documents, and a run on a real segment confirmed it.
The method in full243 words
Method: semi-formal (a bytecode inventory, then a failing JUnit, then SMT obligations and a run on a real segment).
- Inventory. An abstract interpreter over the bytecode (JDK 25
java.lang.classfile) listed everyintaddition of a constant of 64 or more whose result flows into anintcomparison. One row wasiinc 2048intoIF_ICMPGEinDrillSidewaysScorer.doUnionScoringanddoDrillDownAdvanceScoring. - Witness. A JUnit on the stock jars (the package-private scorer over a reader that reports
maxDoc = MAX_DOCS) failed on main with assertions on and off (later also on 10.5.2 and 9.12.3). - Obligations, then a run at scale. Z3 bit-vector obligations, cross-checked with cvc5, with
maxDoc <= IndexWriter.MAX_DOCSas the precondition: a counterexample for the wrap whose smallestmaxDocis 2^31 - 2047 (DS1); no overflow formaxDoc <= 2^31 - 2048(DS1b); for larger legalmaxDocno reachable chunk end is>= maxDoc(DS2) and no document of the last chunk is ever below one (DS3); and the saturating fix steps by exactly 2,048 or reachesNO_MORE_DOCS, covering the last chunk (DS4, DS4b). A public-API run on a real force-mergedMAX_DOCSsegment then did not return within 300 s, while the fixed build returned in 0.033 s. - Then an independent reproducer, reviews by a model from another family (OpenAI GPT-5.6; the refute-lens one was never obtained, the intended-lens one was reading-only), a devil's-advocate verifier, an adjudication, a follow-up (history and prior reports), a credibility audit and a repro-minimization step followed.
No matching public report found in the documented searches (2026-10-26: scripted prior-report search runs over GitHub, the JIRA archive, the mailing lists, downstream trackers and the web, 40 GitHub searches, the files of all 411 open PRs; refreshed 2026-10-31); private reports cannot be searched. Related: #14750 added the MathUtil.unsignedMin helper that the fix uses.
Searches2 searches
Verdict new: in the documented searches, no issue, PR, commit, JIRA entry, list thread, advisory or downstream issue describes the nextChunkStart wrap, a drill-sideways hang near 2^31 documents, or a fix (the searches cannot rule out private reports). Related, not reports: #14750 (added MathUtil.unsignedMin to simplify existing window-overflow guards in core; the helper the fix uses); #12032 (open: IndexSearcher#setTimeout cannot be used with sequential DrillSideways); #16847 (open draft, long global doc IDs: only swaps the maxDoc accessor in this file); #16952 (open, 2026-10-30: changes only the argument check in score()); #16855/#16856 (another bulk scorer's bound); #12211/#12212 (a two-phase bug in the same scorer).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive; Lucene.NET, Solr, Elasticsearch, OpenSearch), JIRA, dev@/java-user@/issues@/commits@ lists, advisories, web | 2026-10-26 | two scripted prior-report search runs (16 GitHub, 3 commit, 2 downstream, 20 list, 4 JIRA, 12 web queries each; 158 and 374 hits), the earlier runs of the finder and a verifier, 40 GitHub GraphQL searches (nextChunkStart, doUnionScoring, overflow, hang, MAX_DOCS), 6 commit-message searches, the changed files of all 411 open PRs, list full-text searches (545 mails), the GitHub advisory database, 15 web queries; 22 items read in full | no report; related: #14750, #12032, #16847, #12211/#12212 |
| GitHub (apache/lucene) | 2026-10-31 | issue/PR searches for DrillSidewaysScorer, nextChunkStart and symptom phrases updated since 2026-10-26; the changed files of every PR updated since then; commit search; the file's blob on main, branch_11x, branch_10_6 and 10.6.0 | no report; #16952 (open) touches the file but not the loop; the file is unchanged on main |
Introduced with the class by LUCENE-4748 (2c30b69f82e, 2013-02-26) and first released in 4.2.0. All 128 releases from 4.2.0 to 10.5.2, 10.6.0 and main were run and all fail; 4.1.0 has no DrillSideways. Never fixed, not a regression.
Versions tested7 rows
Introduced by 2c30b69f82e56b101863d07a31aceded4e421cd3 (trunk) and its branch_4x twin e01492bbee41b0e65b893370bc99d78118cc6035 (the commit the 4.x releases contain), both 2013-02-26, "LUCENE-4748: add DrillSideways utility class to facets module" (GitHub issue #5813; mikemccand). It added the scorer with CHUNK = 2048, int nextChunkStart = CHUNK and the exit-then-step pattern at two sites in each method. git blame -w -M -C -C -C assigns today's exit tests and steps to it; LUCENE-5339 (2013) moved the loop verbatim; no other commit changed these lines. Subversion era, no PR.
Since 4.9.1 (LUCENE-5843, IndexWriter.MAX_DOCS) the trigger window is the 1,919 sizes above 2^31 - 2048; before that, IndexWriter enforced no document limit. #14750 (10.3.0) replaced core's existing long-arithmetic window caps with MathUtil.unsignedMin and did not touch the facet module.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20; 10.6.0 | affected | minimal test: score() still looping after 2,097,153 docID() calls, nothing collected, with assertions on and off |
main ea57360912ed (identical file), real segment | public API | 2,147,483,519 documents: no return within 300 s; fixed: 3 hits in 0.033 s; 2,147,481,600 documents: 3 hits in 0.029 s |
| 10.0.0-10.5.2 (12 releases) | affected | both strategies spin, nothing collected; 10.5.2 also with assertions off |
| 4.2.1-9.12.3 (115 releases) | affected | the same test ported across 13 API eras: both strategies spin, controls at 2^31 - 2048 pass |
| 4.2.0 | first release | both strategies spin; with the 4 steps saturated the test passes |
| 4.1.0 | not affected | no DrillSideways class (the test does not compile) |
upstream main 2f424fd428da, branch_11x, branch_10_6 | read | main and branch_11x: the same file as 645d4fe14a20; branch_10_6: the same file as 10.6.0 |
The finder, an independent reproducer, a devil's-advocate verifier, an adjudication, a credibility audit, the repro-minimization step and this doc each reproduced it. A cross-model review (OpenAI GPT-5.6) was never obtained; the other, reading only, rated the bug real.
Checks and verdicts313 words
Every executed check ran on stock builds. No cross-model reviewer executed Java for this bug; separate runs re-ran the repro.
| Check | Verdict | What it found |
|---|---|---|
| Finder (bytecode inventory, Z3/cvc5 obligations) | candidate | 4-test JUnit: 2 fail on main (assertions on and off), 10.5.2 and 9.12.3; the fix passes 4/4. Real MAX_DOCS segment: no return in 300 s, fixed 0.033 s, control 0.029 s. |
| Cross-model review, refute lens (OpenAI GPT-5.6) | not obtained | No attempt returned a verdict: an availability failure, not a refutation. |
| Independent reproducer | real | Own public-API JUnit through DrillSideways.search: 4 of 6 fail on main (assertions on and off), 10.5.2 and 9.12.3: union at MAX_DOCS, the smallest affected size losing its one last-chunk document, hits at the start collected and then no return, drill-down-advance; controls pass; its long-cap fix passes 6/6. |
| Cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (high) | The intended-behaviour case is weak; root cause and fix agree. A separate re-run fails 2 of 4 and passes 4/4 with the fix. |
| Devil's-advocate verifier | real | Built and rejected the intended-behaviour case; int-wrap check over a full period: 1,919 affected sizes; re-runs fail on main, 10.5.2 and 9.12.3. |
| Adjudication | confirmed (high) | Re-ran the reproducer's JUnit on main: 4 of 6 fail, controls pass; with its fix 6/6. |
| Follow-up and credibility audit | history and prior art; rated lower | 128 releases run, all affected; 4.1.0 has no API; prior art new; the audit's re-run fails both ways; rated lower because DrillSideways is opt-in and experimental. |
| Repro minimization (2026-10-29) | verified | The one-test repro fails on 645d4fe14a20 with assertions on and off; the fix passes. |
| This doc (2026-10-31) | reproduced, fix validated | Gradle on 645d4fe14a20: the repro fails both ways; with the fix the facet module's 307 tests and lint pass. Release 10.6.0 fails; the long-counter-only variant still fails. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 516 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,449 words
- Registry title
- Sequential DrillSideways never returns on a segment of more than 2^31 - 2048 documents: DrillSidewaysScorer's int chunk start wraps to Integer.MIN_VALUE, so its union and drill-down-advance loops never exit (released since 4.2.0)
- Area
- facet / DrillSideways (sequential DrillSidewaysScorer, union and drill-down-advance strategies)
- Priority
- Low, rank 969: In the facet module, sequential DrillSideways hangs forever on a segment within about 1,900 docs of MAX_DOCS, which needs the same 2^31-doc segment as the core BooleanScorer hang LFV-048.
- Impact class
- hang
- Impact note
- Applications that run the default sequential DrillSideways (no executor, scoreSubDocsAtOnce() false) on an index with one segment of more than 2,147,481,600 documents (the top 1,919 legal sizes below IndexWriter.MAX_DOCS, for example an index at the hard limit force-merged to one segment) get a search that never returns and pins a thread at 100% CPU whenever the cost heuristic picks the union or drill-down-advance strategy, which every pure browse request (no base query) does, wherever the matches are; default codec, IndexWriterConfig and searcher, every release since 4.2.0, extreme scale; the query-first strategy and the executor-backed concurrent DrillSideways do not use the chunk loop.
- Summary
- You run a faceted DrillSideways search in the default sequential mode on an index whose single segment holds more than 2,147,481,600 documents, which IndexWriter accepts (MAX_DOCS = 2,147,483,519), and expect it to return its hits as it does on a segment 2,048 documents smaller. Instead DrillSidewaysScorer's union and drill-down-advance loops walk the segment in 2048-document chunks with an int nextChunkStart that wraps from 2^31 - 2048 to Integer.MIN_VALUE before the exit test 'nextChunkStart >= maxDoc' can fire, so the search thread spins forever and the hits of the last chunk are never collected. Through the public API on a real segment of MAX_DOCS documents the stock search did not return within 300 s, while the fixed build returned its 3 hits in 0.033 s.
- Introduced
- 2c30b69f82e56b101863d07a31aceded4e421cd3 (trunk, svn r1449972) and its branch_4x twin e01492bbee41b0e65b893370bc99d78118cc6035 (svn r1449973, the commit the 4.x releases contain): LUCENE-4748 'Add DrillSideways helper class to Lucene facets module' (migrated as GitHub issue #5813), by GitHub mikemccand; SVN era, no PR. It added DrillSidewaysScorer with CHUNK = 2048, 'int nextChunkStart = CHUNK' and, in doDrillDownAdvanceScoring and doUnionScoring, 'if (nextChunkStart >= maxDoc) break;' followed by 'nextChunkStart += CHUNK;' (2 sites per method) [read: git blame -w -M -C -C -C assigns today's lines 476-479, 535-539, 599-602 and 689-693 to 2c30b69f82e; the initialisations (353, 566) and CHUNK (60) blame to the verbatim LUCENE-5339 copy 46e67d8f04b with identical text; git log -G lists no other change to these lines since 2013] [exec: 4.1.0 has no DrillSideways class, 4.2.0 fails, and the 4.2.0 class with the 4 steps saturated passes] (2013-02-26 (both commits; 4.2.0 tagged 2013-03-11))
- First affected version
- 4.2.0 [exec] (4.1.0 and earlier have no DrillSideways API [exec: compile error on 4.1.0]; IndexWriter.MAX_DOCS exists since 4.9.1 (LUCENE-5843), which bounds the trigger window to maxDoc in [2^31 - 2047, 2^31 - 129]; before 4.9.1 IndexWriter enforced no document limit)
- Affected versions
- every release from 4.2.0 to 10.6.0 and main ea57360912ed and 645d4fe14a20 [exec 2026-10-31: the minimal test fails on the 10.6.0 release jars (SHA-1 checked) and on main 645d4fe14a20 with -ea and -da; exec: the version-history runs ran all 128 releases from 4.2.0 to 10.5.2 (including 8.8.2-8.11.4 from SHA-1-verified release jars) with 13 API-glue variants of the same repro, a reader that reports maxDoc = 2^31 - 129 and a docID() budget: 128 of 128 hang on both affected paths with nothing collected, controls at 2^31 - 2048 pass, 4.2.0 and 10.5.2 also with -da; on main the finder's and the independent reproduction's JUnits fail with -ea and -da, 10.5.2 and 9.12.3 fail for the independent reproduction and the intended-behaviour check too, and a public-API run on a real MAX_DOCS segment hangs]; branch_10x (unreleased) and branch_10_6 (10.6.0, released 2026-10-29) hold the same DrillSidewaysScorer blob as 10.0.0-10.5.2, and upstream main (e1c4184cb983 and cf398bfb142c, 2026-10-26) the same blob as ea57360912ed [read, read-only GitHub contents API]. Not checked: x86; the end-to-end run on a real segment was done on main only
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3/cvc5
- Upstream and prior reports
- none found (2026-10-26 by the finder, the verifier and the follow-up; the prior-report record verdict new; all read-only): scripted prior-report searches over GitHub issues and PRs, commit messages, Elasticsearch/OpenSearch/Solr, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web (finder 10 GitHub + 2 commit queries; the intended-behaviour check 16 + 3 + 20 list + 4 JIRA, 164 hits; two follow-up runs, 16 GitHub, 3 commit, 2 downstream, 20 list, 4 JIRA and 12 web queries each, 158 and 374 hits); 40 GitHub GraphQL searches including apache/lucenenet, apache/lucene-solr, apache/solr, elastic/elasticsearch and opensearch-project/OpenSearch ('nextChunkStart': 0 hits in apache/lucene and Lucene.NET); 6 commit-message searches (0 hits each); the changed-file lists of all 411 open apache/lucene PRs; 6 full-text list searches (545 mails screened); the GitHub advisory database (none); 15 web queries; 22 items read in full, none the same bug. Closest, not this bug: #14750 (merged 2025-06-03) added MathUtil#unsignedMin because dividing the doc-ID space into windows 'is prone to integer overflows' and fixed 7 core files, no facet file; #16847 (open draft, long global doc IDs) is the only open PR touching DrillSidewaysScorer.java and only renames the maxDoc accessor; #12032 (open) shows IndexSearcher#setTimeout cannot be used with sequential DrillSideways; #12211/#12212 are a two-phase base-query bug in the same scorer. Not fixed on upstream main e1c4184cb983, branch_10x or branch_10_6. Gaps: private security@ reports are invisible, GitHub search does not index PR diff code (open PRs were checked by changed files), searches cannot prove absence
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails through gradle in a scratch worktree with assertions on and off, and through a standalone runner; with the recommended fix it passes, the whole facet module test suite (40 suites, 307 tests) passes with assertions on and off, and the facet module's format, ECJ and forbidden-apis checks pass. Release 10.6.0 fails the minimal test both ways. The public-API run on a real segment of 2,147,483,519 documents was done on mainea57360912ed, whoseDrillSidewaysScorer.javaandDrillSideways.javaare identical to645d4fe14a20's. All 128 releases from 4.2.0 to 10.5.2 were run with era-specific copies of the test.
- Finding record
lucene/facet/src/java/org/apache/lucene/facet/DrillSidewaysScorer.java:60 (CHUNK = 2048), 95-96 (score() requires max == Integer.MAX_VALUE), 130-147 (strategy choice: query-first if scoreSubDocsAtOnce or baseQueryCost < drillDownCost / 10, else drill-down-advance if numDims > 1 and dims[1] cost < baseQueryCost / 10, else union), 353 and 566 ('int nextChunkStart = CHUNK'), 476-479, 535-539, 599-602, 689-693 (exit test and int step)lucene/facet/src/java/org/apache/lucene/facet/DrillSideways.java:69 (@lucene.experimental), 245-250 (scoreSubDocsAtOnce() default false), 352-355 and 441-467 (sequential search path), 483-508 (concurrent path runs plain DrillDownQuery searches); DrillSidewaysQuery.java:192-194 (the Weight returns a DrillSidewaysScorer)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:200-208 (MAX_DOCS = Integer.MAX_VALUE - 128, hard limit); lucene/core/src/test/org/apache/lucene/index/TestIndexWriterMaxDocs.java:46-89 (@Monster testExactlyAtTrueLimit: forceMerge(1) of MAX_DOCS docs, then searched)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/facet/src/java/org/apache/lucene/facet/DrillSidewaysScorer.java:60, 130-147, 338, 353, 369, 475-480, 535-539, 550, 566, 574, 579, 598-603, 689-693a Lucene main checkout (645d4fe14a20) lucene/facet/src/java/org/apache/lucene/facet/DrillSideways.java:89-131 (constructors), 248-250, 352-355, 459, 463-467, 483-508; lucene/facet/src/java/org/apache/lucene/facet/DrillSidewaysQuery.java:192-194a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/ConstantScoreScorerSupplier.java:31-33 (match-all cost = maxDoc); lucene/core/src/java/org/apache/lucene/search/MatchAllDocsQuery.java:48
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:201-208; lucene/core/src/test/org/apache/lucene/index/Test2BDocs.java:64-73, 90-123a Lucene main checkout (645d4fe14a20) lucene/facet/src/java/org/apache/lucene/facet/DrillSideways.java:69 (@lucene.experimental), 243-250 (scoreSubDocsAtOnce javadoc), 483-508; lucene/facet/src/java/org/apache/lucene/facet/DrillDownQuery.java:45a Lucene main checkout (645d4fe14a20) lucene/facet/src/java/org/apache/lucene/facet/DrillSidewaysScorer.java:95-96; lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:846-847; lucene/core/src/java/org/apache/lucene/search/TimeLimitingBulkScorer.java:36, 70-86; lucene/facet/src/test/org/apache/lucene/facet/TestDrillSideways.java:145-146a Lucene main checkout (645d4fe14a20) lucene/facet/src/java/org/apache/lucene/facet/DrillSidewaysScorer.java:148-153 (CollectionTerminatedException passes through score()); lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:853-855 (caught per leaf); lucene/facet/src/java/org/apache/lucene/facet/DrillSideways.java:330-336 (the main collector includes the drill-down FacetsCollector)upstream apache/lucene#12032 (open; read-only)
- Minimal repro
a Lucene main checkout (645d4fe14a20) lucene/facet/src/test/org/apache/lucene/facet/TestDrillSideways.java:258, 309-313 (testCollectionTerminated drives the scorer directly)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:201-208; lucene/CHANGES.txt:12045-12049 (LUCENE-5843)a Lucene main checkout (645d4fe14a20) lucene/core/src/test/org/apache/lucene/index/Test2BDocs.java:64-73 (index MAX_DOCS, forceMerge(1), close), 90-123 (postings walk); lucene/core/src/test/org/apache/lucene/index/TestIndexWriterMaxDocs.java:61 (commit), 65-80 (searches), 85 (forceMerge), 88 (close)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/BulkScorer.java:31-32; lucene/core/src/java/org/apache/lucene/util/MathUtil.java:196-199
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/util/MathUtil.java:196-199; lucene/core/src/java/org/apache/lucene/search/DisjunctionMaxBulkScorer.java:90; lucene/core/src/java/org/apache/lucene/search/ConstantScoreBulkScorer.java:131-132; lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:70-81 (range restarts at minDoc after NO_MORE_DOCS)a Lucene main checkout (645d4fe14a20) lucene/facet/src/java/org/apache/lucene/facet/DrillSideways.java:243-250 (scoreSubDocsAtOnce javadoc)
- Diagrams
a Lucene main checkout (645d4fe14a20) lucene/facet/src/java/org/apache/lucene/facet/DrillSidewaysScorer.java:60, 353, 566, 598-603, 689-693
- TestDrillSidewaysScorerLastChunk.java (one test class):
repro/LFV-383/src/org/apache/lucene/facet/TestDrillSidewaysScorerLastChunk.java(111 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the executed runs.
assets/LFV-383/bug.png(516 KB)