A label stays in the class field's term dictionary when the training query excludes all its documents, or when they are all deleted and no merge has dropped the term. BM25NBClassifier still scores it, as if it had probability 1.
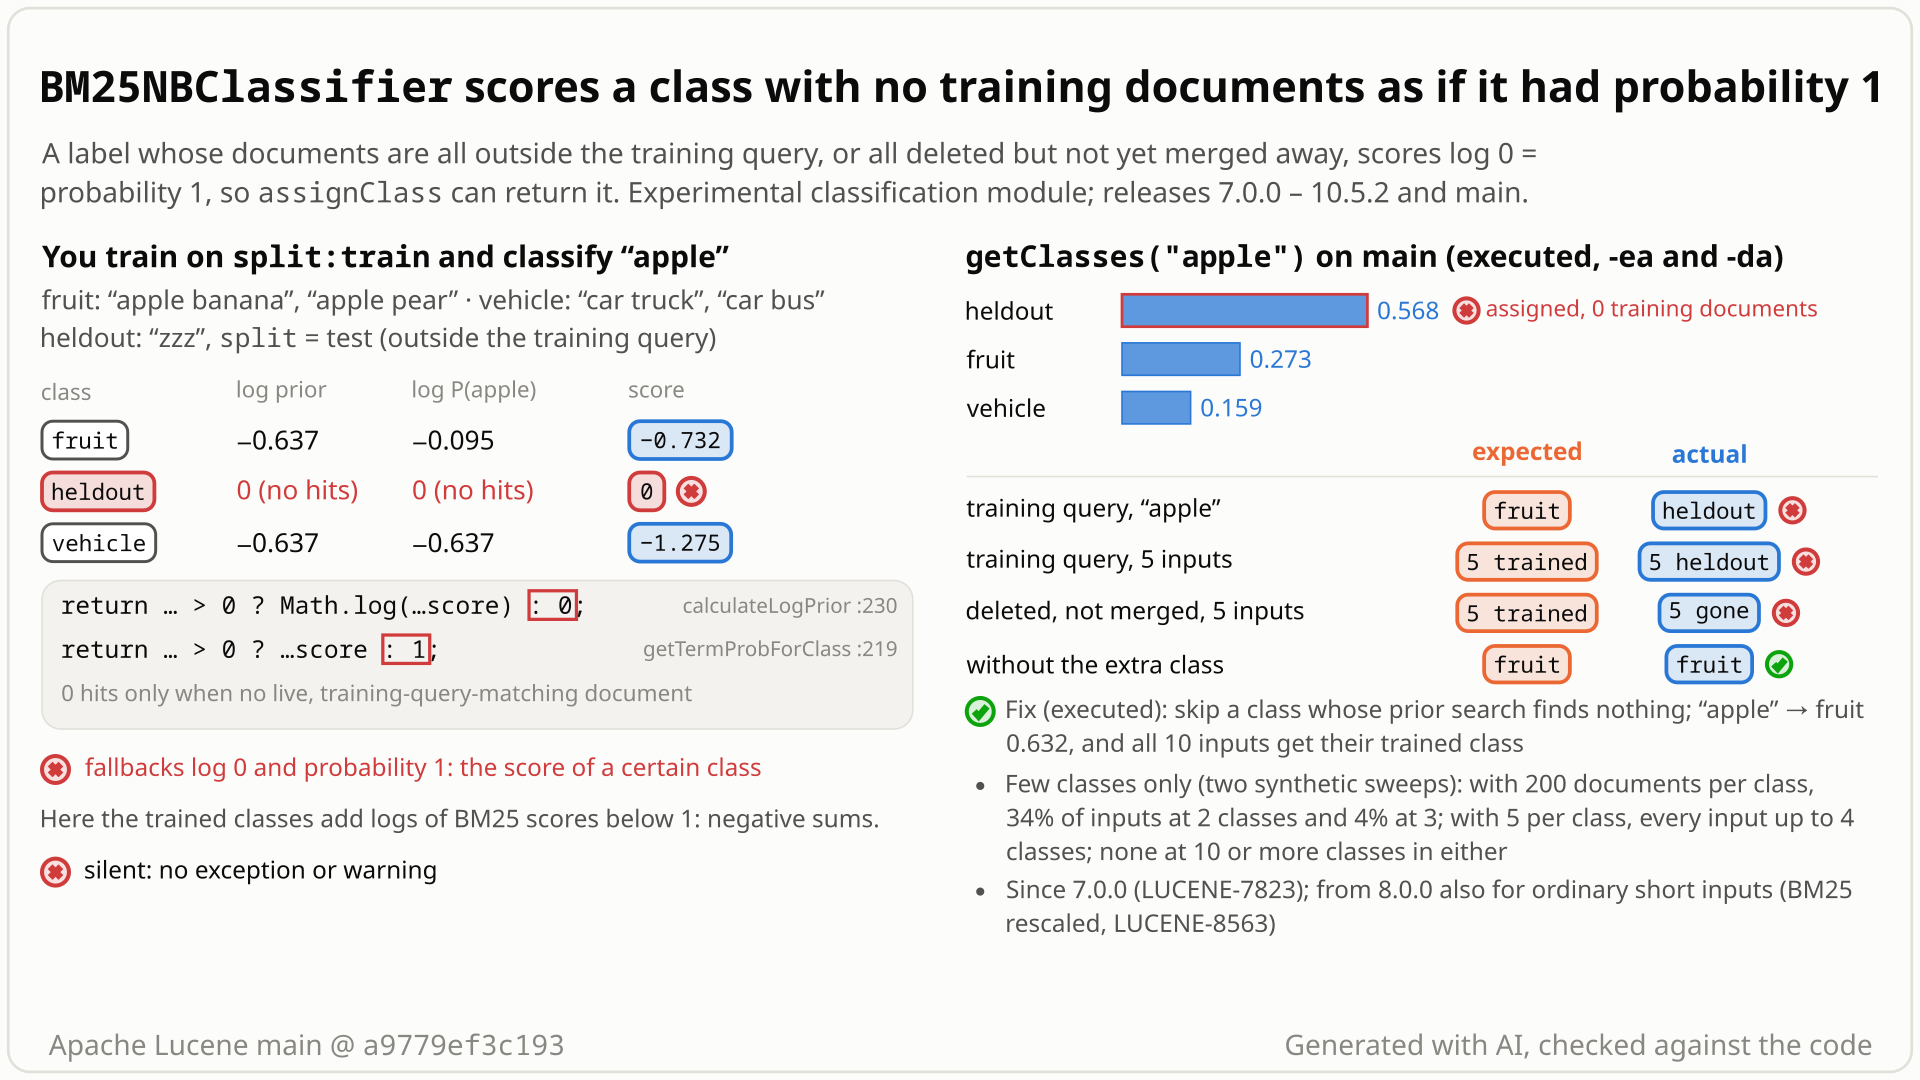
- Index "apple banana" and "apple pear" (label fruit) and "car truck" and "car bus" (label vehicle), all with
split:train, plus one document "zzz" with label heldout andsplit:test. - Classify "apple" with
BM25NBClassifierand the training querysplit:train. heldout has no training document, so you expect fruit, which is the answer without the heldout document (fruit 0.651, vehicle 0.349). - You get heldout (heldout 0.568, fruit 0.273, vehicle 0.159), and so do all 5 inputs tried. No error. Deleting a label's only document has the same effect until a merge drops its term: "apple" goes to gone (0.681).
- Why: a label scores log prior plus a log likelihood per word, each from the top BM25 score of a search that requires the label. heldout's searches find nothing, so the code falls back to prior 1 and probability 1: total 0. Here the trained labels add logs of scores below 1: fruit -0.73, vehicle -1.27.
- It needs few labels: in a 200-documents-per-label sweep the untrained label won 34% of inputs with 2 labels, 4% with 3 and none with 5 or more; with 5 documents per label it won every input up to 4 labels, and no sweep shows it with 10 or more. Skipping labels without a training document fixes it.
Users of the opt-in, experimental classification module running BM25NBClassifier while a label has no live training document: a train/test split in one index, or a retired label deleted but not yet merged. Default settings suffice. The wrong top answer needs few labels: up to 3 at 200 documents per label, up to 8 at 5; none with 10 or more.
Mechanism, terms and numbers553 words
BM25NBClassifier makes every term of the class field a candidate label, including a label whose documents are all outside the documented training query or all deleted but not yet merged away. It scores each label as a log prior plus one log likelihood per input word, each the log of the top BM25 score of a search in which the label term is a MUST clause. For a label with no live, training-query-matching document both searches find nothing, and the code falls back to log prior 0 and word probability 1: the label scores exactly 0, the score of a label with probability 1. Trained labels add logs of BM25 scores, which are negative when those scores are below 1, so with few labels the untrained one comes first: on five documents assignClass("apple") returns heldout (0.568) instead of fruit. No error is raised. Every release checked from 7.0.0 to 10.5.2 and main has the code, with ordinary short inputs from 8.0.0; skipping labels whose prior search finds nothing fixes it.
- Label: a term of the class field, for example
fruit.BM25NBClassifiertakes every term of that field as a candidate (MultiTerms.getTerms,BM25NBClassifier.java:124). - Training query: the constructor's
query, documented as "a Query to eventually filter the docs used for training the classifier" (:72-73). Both searches below add it as aMUSTclause. - Score of a label: log prior + the sum of log likelihoods of the input words (
:134).- Prior: the top BM25 score of
label MUST+training query MUST(:222-231). - Likelihood of a word: the top BM25 score of
label MUST+word SHOULD+training query MUST(:205-220). The word is optional, so a trained label always has a hit.
- Prior: the top BM25 score of
- Result: the scores are turned into probabilities with a softmax, best first (
:147-173);assignClassreturns the first (:96).
- When a search finds nothing, the code falls back to log prior
0(:230) and word probability1, so log likelihood 0 (:219). - Because the label term is
MUSTin both searches, only a label with no live, training-query-matching document ever reaches these fallbacks. It scores exactly 0, the score of a label with probability 1. - A trained label scores the sum of 1 + t logs of BM25 scores for t input words. A single BM25 term score on a
StringFieldlabel is idf / 2.2 with the default k1 = 1.2, which is below 1 unless the label covers fewer than about 11% of the documents. So with few, large labels the trained totals are negative and the untrained label wins.
| label | prior: top score, log | "apple": top score, log | total | probability |
|---|---|---|---|---|
| fruit | 0.5287, -0.637 | 0.9093, -0.095 | -0.732 | 0.273 |
| vehicle | 0.5287, -0.637 | 0.5287 (no vehicle document has "apple"), -0.637 | -1.275 | 0.159 |
| heldout | no hit: 0 | no hit: log 1 = 0 | 0 | 0.568 |
A BM25 score can exceed 1: in "apple pear", "pear" scores 1.1314 (log +0.124) for fruit, yet fruit's total is -0.609 and heldout still wins (0.591). Deleted variant, no training query: fruit -1.172, vehicle -1.843, gone 0, so gone 0.681. After forceMergeDeletes() the term gone is dropped and "apple" is fruit (0.667).
Exposure and likelihood366 words
- Who is exposed. Applications that classify with
BM25NBClassifier(@lucene.experimental) when a label is in the class field but has no live, training-query-matching document: one index holding a train/test split in which some label occurs only in test documents, or a retired label whose documents were all deleted and whose segment has not been merged yet. Both use public API and default settings. - How often. It depends on the number of labels and on the corpus. Every input tried in the two small repro corpora (5 of 5 here, 6 of 6 in an independent sports/cooking corpus). In a synthetic sweep with K balanced labels of 200 documents per label and one deleted extra label: 34% of inputs at K = 2 (accuracy 0.90 to 0.64), 4% at K = 3, 0% at K = 5, 10 and 20 (the same 34% and 4% with the extra label outside the training query). In a second sweep with 5 documents per label and the extra label outside the training query: every input at K = 2, 3 and 4, 2 of 8 at K = 6, 2 of 10 at K = 8, none at K = 10, 15 and 20. So no sweep shows a wrong top answer with 10 or more labels; where the untrained label does not win, it still gets a non-zero share in
getClasses. - The input matters. Each extra input word adds a negative log to every trained label and 0 to the untrained one: in the 200-documents sweep, appending 5 unknown words to each input raised the share sent to the untrained label from 34% to 98% at K = 2 and from 4% to 49.3% at K = 3 (still 0% at K = 5 and 10).
- Silent. No exception, with assertions on or off; the answer is a real label from the index with a plausible probability.
- Not affected. Indexes where every label has at least one live training document.
- Downstream. No known caller: Solr's classification update processor builds only the k-NN and simple naive Bayes document classifiers, and a read-only code search found no occurrence of
BM25NBClassifieron the default branches of Solr, Elasticsearch and OpenSearch.
The test shows that BM25NBClassifier built with the training query split:train assigns a class whose only document that query excludes (TestBM25NBUntrainedClass#testClassExcludedByTrainingQueryIsNotAssigned, 3 documents).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.classification;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestBM25NBUntrainedClass extends LuceneTestCase {

  public void testClassExcludedByTrainingQueryIsNotAssigned() throws Exception {
    Analyzer analyzer = new StandardAnalyzer();
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
        String[][] docs = {
          {"apple", "fruit", "train"}, {"car", "vehicle", "train"}, {"zzz", "heldout", "test"}
        };
        for (String[] d : docs) {
          Document doc = new Document();
          doc.add(new TextField("text", d[0], Field.Store.NO));
          doc.add(new StringField("cls", d[1], Field.Store.NO));
          doc.add(new StringField("split", d[2], Field.Store.NO));
          w.addDocument(doc);
        }
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        TermQuery trainingDocs = new TermQuery(new Term("split", "train"));
        BM25NBClassifier classifier =
            new BM25NBClassifier(reader, analyzer, trainingDocs, "cls", "text");
        // Expected: "fruit"; actual: "heldout", whose only document the training query excludes.
        assertEquals("fruit", classifier.assignClass("apple").assignedClass().utf8ToString());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-388/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/classification/build/libs/lucene-classification-$V.jar
CP=$CP:$LUCENE/lucene/grouping/build/libs/lucene-grouping-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.classification.TestBM25NBUntrainedClass
- Expected vs actual
- Expected: assignClass("apple") returns "fruit". Actual: "heldout" (its zero-hit fallbacks give it log prior 0 and log-likelihood 0, the score of a probability-1 class); fails with -ea and -da.
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[frui]t> but was:<[heldou]t>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.classification.TestBM25NBUntrainedClass.testClassExcludedByTrainingQueryIsNotAssigned(TestBM25NBUntrainedClass.java:56)- The class "approximates naive bayes": there a label with no training documents has prior 0; here it gets prior 1.
- The training query is documented to filter "the docs used for training the classifier"; the label it excludes becomes the answer.
- Only zero-evidence labels reach the fallbacks, which score them as certain; no test or comment covers this.
The full argument215 words
- Contract. Class javadoc: "A classifier approximating naive bayes classifier by using pure queries on BM25" (
BM25NBClassifier.java:43). Constructor javadoc: "a Query to eventually filter the docs used for training the classifier, or null if all the indexed docs should be used" (:72-73). Package javadoc: "Uses already seen data (the indexed documents) to classify an input". - Design intent. The introducing issue #8874 (LUCENE-7823): "uses BM25 scoring as a probability measure of both prior and likelihood". The issue that added the training query, #6348 (LUCENE-5284): "It's sometimes useful to use only a certain subset of the whole index to train the classifier with".
- Tests.
TestBM25NBClassifier.testBasicUsageWithQueryfilters withtext:not, which matches a document of both sample labels, and the test base force-merges its indexes, so no test has a label without training documents. - History. Both fallbacks date from the introducing commit (2017); later commits only adapted APIs, and no commit message or comment explains the values.
- Metamorphic check. Two readers with the same live, training-query-matching documents give different answers depending on whether the deleted label's term is still in the dictionary:
forceMergeDeletes()turns gone back into fruit. The merge also changes the BM25 statistics, but on the unmerged reader fix A already answers fruit (0.662), so the term, not the statistics, flips the answer.
The devil's-advocate check240 words
The strongest "intended" case (cross-model reviews rated it moderate): the class is @lucene.experimental and only approximates naive Bayes with uncalibrated BM25 scores; the fallbacks 1 and log 1 = 0 guard against log 0 = -Infinity, which would make the normalisation NaN when no label has a hit; the private javadoc of assignClassNormalizedList promises "one for each existing class" (:117); and the module's train/test workflow, DatasetSplitter, writes a separate training index, whose term dictionary holds only the labels that reached it (LUCENE-7196 aimed at class coverage, although a label with a single document can still land entirely in the test or cross-validation index, DatasetSplitter.java:153-160).
Why it fails: the guard explains why some value was needed, not why that value is log 0 = log 1, the score of a label with probability 1, which outranks every trained label whose summed logs are negative. A label with any training document never reaches the fallbacks, so they are not a neutral value for weak evidence but the value given only to zero evidence. The training query is documented for training on a subset of one index, and nothing tells the caller to avoid a subset that lacks a label. @lucene.experimental allows API changes, not an answer that contradicts the javadoc. Verdict: not intended, a defect. The deleted-documents variant is the one a maintainer is most likely to push back on (term dictionaries keep deleted terms until a merge).
Recommended Skip labels without a training document and handle the shorter list (fix A)
Make calculateLogPrior return -Infinity when no training document has the label and skip such labels; return null from assignClass when no label is left, and clamp max in getClasses(text, max). The new test passes, and the whole classification suite passes with assertions on and off.
        double logPrior = calculateLogPrior(term);  // now -Infinity when no hit
        if (logPrior == Double.NEGATIVE_INFINITY) {
          continue;  // no training document has this class: prior 0
        }
        assignedClasses.add(
            new ClassificationResult<>(
                term.bytes(), logPrior + calculateLogLikelihood(tokenizedText, term)));
  // assignClass:
    return assignedClasses.isEmpty() ? null : assignedClasses.get(0);
  // getClasses(text, max):
    return assignedClasses.subList(0, Math.min(max, assignedClasses.size()));
All options and trade-offs3 options · 924 words
Two fixes were built and validated; a third is a design alternative. Labels with training documents keep exactly their old raw scores under fixes A and B.
Workaround until a fix ships. Deleted labels: IndexWriter.forceMergeDeletes() (or any merge that rewrites the segment) drops the term, and after reopening "apple" is fruit again; nothing is stored wrong, so no reindex is needed. Training splits: classify on an index that holds only the training documents, for example DatasetSplitter's output.
Either way, add tests like the repro's (both variants and the control), plus the empty-training-set case and getClasses(text, max) for the chosen fix.
Skip labels without a training document and handle the shorter list (fix A) (validated by the checks) (recommended)
+14/-6 lines in BM25NBClassifier.java: the prior fallback becomes Double.NEGATIVE_INFINITY (:230); assignClassNormalizedList skips a label whose prior is -Infinity, which also saves its t likelihood searches (its prior search still runs: that search finds the label has no training document); assignClass returns null when no label is left (:96); getClasses(text, max) clamps max to the list size (:110); the private javadoc says "one for each class that has at least one live document matching the training query".
        double logPrior = calculateLogPrior(term);  // now -Infinity when no hit
        if (logPrior == Double.NEGATIVE_INFINITY) {
          continue;  // no training document has this class: prior 0
        }
        assignedClasses.add(
            new ClassificationResult<>(
                term.bytes(), logPrior + calculateLogLikelihood(tokenizedText, term)));
  // assignClass:
    return assignedClasses.isEmpty() ? null : assignedClasses.get(0);
  // getClasses(text, max):
    return assignedClasses.subList(0, Math.min(max, assignedClasses.size()));
Trade-offs
- Why the two extra changes. Skipping can leave the list empty or shorter than the number of label terms. When the training query matches no labelled document, stock code returns an arbitrary label (every label scores 0: fruit, heldout, vehicle 0.333 each), and the hunt's first skip-only sketch threw
IndexOutOfBoundsExceptionat:96. Fix A returnsnulland an empty list, asSimpleNaiveBayesClassifier.assignClass(:102-113) andKNearestNeighborClassifier.classifyFromTopDocs(:126-138) already do when they have no class;ConfusionMatrixGeneratorskips a null result (:109), but if every result is null its average time istime / counterwith counter 0, so NaN or Infinity (:149). getClasses(text, max)with amaxbetween the number of trained labels and the number of label terms would otherwise throw at:110where it worked before. The clamp also changes the open #9158 / LUCENE-8110 behaviour (amaxlarger than the list throws) for this class only, asKNearestNeighborDocumentClassifieralready clamps (:112). Mention #9158: the same clamp was committed for this and four other classifiers (af41d02eae6, 2017-12-28) and reverted the same day (152d223b323) after a reviewer asked for a test, so add one.nullfromassignClassis not in its javadoc (Classifier.java:30-37does not mention null; thegetClassesjavadoc says it may return null,:43-44,:55-56); it appears only in the empty-training-set case, where the stock answer was arbitrary. The: 1fallback at:219becomes unreachable.
What the checks validated
- Scratch worktree of
a9779ef3c193, gradle, JDK 25: the new test fails 2 of 3 on stock with assertions on and off; with the fix, the whole:lucene:classification:testpasses with assertions on and off (13 suites, 46 tests including the new test's 3,TestBM25NBClassifierandTestConfusionMatrixGenerator, 1 skipped, 0 failures each);:lucene:classification:check -x test(google-java-format, ecj lint, forbidden APIs) passes. - Standalone runner with the fix shadowed: the new test 3 of 3 with
-eaand-da; the finder's test 2 of 2; the independent reproducer's test 3 of 3; the probe: 0 of 5 inputs to the untrained label in both variants ("apple": fruit 0.632, vehicle 0.368),getClasses("apple", 3)returns the 2 trained labels, and the empty training set givesnulland an empty list.
The :230 change of fix A alone, one expression (the independent reproducer's root-cause probe was the same change). An untrained label scores -Infinity and gets probability 0 but stays in the list, so getClasses(text, max) is unchanged: "apple" gives fruit 0.632, vehicle 0.368, heldout 0.000.
-    return topDocs.totalHits.value() > 0 ? Math.log(topDocs.scoreDocs[0].score) : 0;
+    return topDocs.totalHits.value() > 0
+        ? Math.log(topDocs.scoreDocs[0].score)
+        : Double.NEGATIVE_INFINITY;
Trade-offs
When no label has a training document, every score is -Infinity and the normalisation computes exp(-Infinity - (-Infinity)) = NaN: getClasses returns fruit NaN, heldout NaN, vehicle NaN, and assignClass returns fruit with score NaN. Untrained labels still cost 1 + t searches each and stay listed. A maintainer may pair it with an explicit case for "every score is -Infinity" in the normalisation.
What the checks validated
The new test 3 of 3 with the fix shadowed; the whole :lucene:classification:test with assertions on in the scratch worktree (13 suites, 46 tests, 1 skipped, 0 failures); the probe shows the NaN case above.
Use the label's share of the training documents as prior, for example log(count(label AND query) / count(labelled documents AND query)). That is -Infinity for a label without training documents as long as some labelled document matches the query; when none does it is log(0/0) = NaN, so the empty training set needs its own handling (and count(query) alone would also count unlabelled matches).
Trade-offs
Changes every label's score, also on indexes without the bug, and would also address the broader bias towards rare labels that one reviewer reported (not confirmed as a separate bug); it needs an accuracy check, for example with Test20NewsgroupsClassification, and a maintainer's view.
No downstream product is known to call BM25NBClassifier (Solr's classification update processor builds only the k-NN and simple naive Bayes document classifiers), but an application that retires a label by deleting its documents, or keeps a test split in the training index, can still get that label back as the answer.
Code reading, not a formal result. While listing every log and division site in the classifiers' scores for an SMT check (Z3), a hunting AI tool noticed the two zero-hit fallbacks; the SMT check of that site passed and did not flag the bug. A public-API JUnit then reproduced it on the stock jars.
The method in full143 words
- The hunt unit for
lucene/classificationbuilt an SMT inventory (Z3 4.12.2) of every division and log in the classifiers' raw scores. ForBM25NBClassifier.java:219and:230the obligation was that the log of a positive, finite BM25 score is finite; it was proved, and it does not cover the fallback branch. - Reading those lines, the finder saw that a search with no hit returns probability 1 and log prior 0, and that the label term is
MUSTin both searches, so only a label with no live training document gets there. A JUnit on the stock jars confirmed it with the training-query and the deleted-documents variant. - An independent reviewer from another model family (OpenAI GPT-5.6) made the finder narrow the claim ("assigned for every input" holds only while the trained labels' BM25 scores stay below 1). Independent verifiers, an adjudication and an audit followed.
No prior report found (2026-10-26): 231 read-only queries over GitHub issues, PRs and commits, downstream repositories, six mailing lists, JIRA and the web, plus all 47 classification issues and the changed files of all 410 open PRs. Nearest: the introducing issue #8874 and the open #9158 (getClasses(text, max)).
Searches4 searches
27 hits were assessed and none is the same bug; the finder's and verifiers' own searches agree. Nearest items: #8874 / LUCENE-7823 (the introducing issue and its design-intent quote), #8723 / LUCENE-7672 (open: CachingNaiveBayesClassifier omits the log prior), #6529 / LUCENE-5466 (training query ignored in SimpleNaiveBayesClassifier's class count), #8251 / LUCENE-7196 (DatasetSplitter class coverage, before BM25NB existed), #9158 / LUCENE-8110 (open: getClasses(text, max) IndexOutOfBoundsException, relevant to the fix) and #9609 / LUCENE-8563 (the BM25 rescale that amplified the symptom; it never mentions classification). No open PR touches BM25NBClassifier.java. A sibling bug of this hunt about scored training queries in the k-NN and perceptron classifiers notes that BM25NB also scores its training query; that is a different defect.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, the old lucene-solr repository, all of GitHub) | 2026-10-26 | the scripted prior-report search (36 issue and PR, 6 commit queries: class and method names, "BM25NB", "bm25 naive bayes", "untrained class", "training query", "deleted documents", "log prior", "wrong class") and 38 manual issue and PR plus 5 commit searches; review comments of the 5 PRs that changed the file read directly | only #8874, the introducing issue; history items |
| Classification module items and open PRs | 2026-10-26 | body and comments of all 47 module:classification issues; the module's 21 PRs listed, with review and conversation comments read for the PRs that changed the file; changed files of all 410 open PRs | no report; no open PR touches the file |
| Mailing lists and JIRA | 2026-10-26 | 104 list queries over dev@, java-user@, issues@, commits@, general@ and solr-user@; 16 JIRA queries including the classification component (47 issues) and 3 cross-project queries | commit mails, the LUCENE-7823 digest and unrelated threads |
| Downstream and web | 2026-10-26 | 5 downstream queries (apache/solr, Elasticsearch, OpenSearch); 12 web searches (1 throttled) | nothing; Solr's classification integration does not use this class |
Introduced with the class in 7.0.0 (89905001831, LUCENE-7823, 2017). The 8.0.0 BM25 rescale (LUCENE-8563) made it fire for ordinary short inputs; on 7.x only inputs with unknown words show it. All 65 release tags checked from 7.0.0 to 10.5.2 and main have the code; not fixed upstream.
Versions tested6 rows
Introduced by 89905001831 "LUCENE-7823 - added bm25 nb classifier" (@tteofili, 2017-05-11, committed directly to master, no pull request; issue #8874), which wrote the label enumeration and both fallbacks; its parent has no BM25NBClassifier.java. First release 7.0.0, released 2017-09-20 (tagged 2017-09-18; CHANGES: "LUCENE-7823: Pure query based naive bayes classifier using BM25 scores"). Later commits only adapted APIs. Amplifier, not cause: LUCENE-8563 (cf016f8987e8, 2018-11-14, 8.0.0) removed the (k1 + 1) factor from BM25, so every trained label's total fell by (1 + t) x ln 2.2 for t input words while the untrained label stays at 0 (28 of 28 pairs, 7.7.3 vs 8.0.0, to 6 decimals). Upstream main cf398bfb142c (2026-10-26) still has the file byte-identical. All 65 release tags of the history clone from 7.0.0 to 10.5.2 contain the enumeration and both fallbacks; 8.8.2 to 8.11.3 are not in the clone (8.11.4 was executed). The 7.x and 8.x jars ran on JDK 25, newer than they support; only sun.misc.Unsafe warnings appeared and every control passed.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test: 2 of 3 fail (gradle and the standalone runner, assertions on and off): heldout 0.568, gone 0.681 |
| 10.5.2, 9.12.3 | affected | this doc's test: 2 of 3 fail with assertions on, the same numbers (9.x accessor copy) |
8.0.0, 8.11.4, 9.0.0, 10.0.0, main ea57360912ed | history harness | 5 ordinary inputs x 2 variants: 10 of 10 assigned to the untrained label; 2 unknown-word inputs x 2: 4 of 4 |
| 7.0.0, 7.7.3 | unknown-word inputs only | ordinary inputs pass (0 of 10, the untrained label still gets p > 0); unknown-word inputs fail 2 of 4 (deleted variant) |
| 6.5.1, 6.6.0, 6.6.6 | not affected | the class does not exist (compile error) |
fix A / fix B on a9779ef3c193 | not affected | 3 of 3 pass; 0 of 5 inputs to the untrained label |
An independent reproducer, a devil's advocate, an adjudication, an audit and an independent reviewer from another model family (OpenAI GPT-5.6) agree on the root cause; a second review by it, unable to run Java, said not real on procedure only. This doc's gradle runs reproduced it on main a9779ef3c193 and validated two fixes.
Checks and verdicts359 words
The hunt and its checks ran on main ea57360912ed; lucene/classification is identical at a9779ef3c193, where this doc re-ran everything it states.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | JUnit fails 2 of 2 on main with assertions on and off, on 10.5.2 and on 9.12.3; passes with the skip-only fix sketch, and the upstream classification tests pass with it. |
| cross-model review, refute lens | not real (low), procedural | Could not run Java; agreed with the root cause, called the inputs legal and rated the intended case moderate. Its point that "assigned for every input" overstated the claim was accepted. A separate re-run failed 2 of 2. |
| independent reproducer | real | Own 3-test class with other data and the default merge policy: 2 of 3 fail on main, 10.5.2 and 9.12.3 (6 of 6 inputs); the control passes; a one-expression -Infinity prior makes all 3 pass; reach sweep (200 documents per label) 34% / 4% / 0%. |
| cross-model review, intended lens | real (medium), intended argument moderate | Reading only; a separate run re-ran the repro at two seeds (fail). Its probe (5 documents per label) gave the untrained label every input up to 4 labels, 2 inputs at 6 and 8 labels and none from 10. From its runs the adjudication also recorded a broader bias towards rare labels, not confirmed as a separate bug. |
| devil's advocate | real (high for the training query, medium-high for deletes) | Built the intended case and rejected it; ran 8.0.0, 7.7.3 and 7.0.0 and traced the 8.0 jump to LUCENE-8563; found that the skip-only fix throws on an empty training set. |
| adjudication | confirmed (high) | Re-ran the reproducer's test (2 of 3 fail, assertions on and off), the finder's (2 of 2 fail) and the root-cause probe (3 of 3 pass). |
| audit | keep | Re-ran the finder's test with a new seed: 2 of 2 fail with assertions on and off. |
| this doc | reproduced; two fixes validated | New 3-test class through gradle and the standalone runner on main a9779ef3c193, 10.5.2 and 9.12.3; the number probe; fixes A and B in a scratch worktree. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 447 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,373 words
- Registry title
- BM25NBClassifier scores a class that has no live, training-query-matching document as if it had probability 1 (log prior 0 and log-likelihood 0), so with few classes it outranks the trained classes and is assigned although it has no training data (released since 7.0.0)
- Area
- classification / BM25NBClassifier (assignClass and getClasses)
- Priority
- Low, rank 342: In the experimental, little-used BM25NB classifier, and only with few classes and a label that has no live training documents.
- Impact class
- silent wrong results
- Impact note
- Applications that use the opt-in, @lucene.experimental lucene/classification module and classify text with BM25NBClassifier are hit when a label that is still in the class field's term dictionary has no live document matching the training query, either because the documented training query excludes all its documents (for example a train/test split field in one index) or because all its documents were deleted and their segment has not been merged away: with no error, that label gets the score of a probability-1 class and assignClass returns it whenever the trained classes' BM25 scores stay below 1, which in the executed runs meant every input tried in the small two-class repro corpora (5 of 5 and 6 of 6), 34% of inputs with 2 classes and 4% with 3 classes on a synthetic 200-documents-per-class corpus, and no input with 5 or more classes (where the label still gets a non-zero share in getClasses); no non-default setting or scale is needed, and every release from 7.0.0 to 10.5.2 is affected (with ordinary short inputs from 8.0.0 on).
- Summary
- You index four training documents labelled fruit ('apple banana', 'apple pear') or vehicle ('car truck', 'car bus') plus one document labelled heldout that your training query split:train excludes, build BM25NBClassifier with that query and classify 'apple', expecting fruit, which is what the classifier answers when the heldout document is absent. Instead assignClass returns heldout (getClasses: heldout 0.568, fruit 0.273, vehicle 0.159), and the same happens with no training query when every document of a label is deleted but its segment is not yet merged ('apple' -> gone 0.681). BM25NBClassifier makes every term of the class field a candidate class (MultiTerms.getTerms), and for a class with no live, query-matching document both of its searches find no hit, so calculateLogPrior falls back to 0 and getTermProbForClass to 1 (log 0): the class scores exactly 0, while each trained class sums log(top BM25 score) over the prior and every input token, which is negative whenever those scores are below 1.
- Introduced
- 89905001831de12dd8cb18647d3d54944899ccdf 'LUCENE-7823 - added bm25 nb classifier' (by GitHub tteofili; issue apache/lucene#8874; committed directly to master, no pull request) wrote the class enumeration and both zero-hit fallbacks [read: git log -L, git blame -w -M -C and git log -S in the full-history clone; the parent 89905001831^ has no BM25NBClassifier.java; exec: 6.5.1, 6.6.0 and 6.6.6 lack the class]. Later commits on these lines only adapted APIs (fd9164801e7 LUCENE-7875, 331ccf39106 LUCENE-8405, 9ca053712af LUCENE-8430, f0fd51c4d5c #13762). Amplifier, not cause: cf016f8987e8 (LUCENE-8563, apache/lucene#9609, in 8.0.0) removed the (k1+1) factor from BM25, which lowered every trained class's log score by exactly (1+t)*ln(2.2) for t input tokens while the untrained class stays at 0 [exec: 28 of 28 pairs, 7.7.3 vs 8.0.0, to 6 decimals], so the wrong top-1 answer fires for ordinary short inputs from 8.0.0 on. (2017-05-11 (89905001831); amplified 2018-11-14 (cf016f8987e8, LUCENE-8563))
- First affected version
- 7.0.0 [exec] (tagged 2017-09-18, the first release with the class; CHANGES 7.0.0 'LUCENE-7823: Pure query based naive bayes classifier using BM25 scores'; 6.5.1, 6.6.0 and 6.6.6 lack the API [exec: compile error]). On 7.0.0 and 7.7.3 the wrong top-1 answer shows only for inputs with words absent from the class documents (deleted variant, 2 of 4) while ordinary short inputs pass with the untrained class at p > 0; from 8.0.0 ordinary short inputs fail too [exec]
- Affected versions
- Every release from 7.0.0 to 10.5.2 and main ea57360912ed; not fixed upstream (upstream main cf398bfb142c, 2026-10-26: BM25NBClassifier.java byte-identical to the tested file, fallbacks still at :219 and :230). [exec] follow-up history harness (5 ordinary inputs and 2 unknown-word inputs, each with the training-query and the deleted variant; control index checked first): 7.0.0 and 7.7.3 ordinary inputs pass (0 of 10 assigned; the untrained class gets p > 0 in 10 of 10), unknown-word inputs fail (2 of 4); 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main fail (10 of 10 and 4 of 4). The finder's JUnit fails 2 of 2 on main (-ea and -da), 10.5.2 and 9.12.3 (9.x accessor variant repro/src-9x); the independent reproduction's JUnit fails 2 of 3 (its control passes) on main (-ea and -da), 10.5.2 and 9.12.3; the intended-behaviour check's portable main() fails on main (-ea and -da) and 8.0.0. Not affected: 6.x and earlier (class absent). [read] 8.8.2-8.11.3 are not tagged in the history clone; 8.11.4 was executed.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, read-only, the prior-report record verdict new: 231 logged queries, 0 errors: scripted prior-report searches with 36 GitHub issue and PR, 6 commit, 5 downstream, 104 mailing-list (dev@, java-user@, issues@, commits@, general@, solr-user@), 16 JIRA and 6 web queries; 38 manual GitHub issue and PR searches and 5 commit searches (apache/lucene, apache/solr, Elasticsearch, OpenSearch and all of GitHub); 3 cross-project JIRA queries; 6 more web searches (1 throttled); the body and comments of all 47 module:classification issues and the 21 module PRs; the changed files of all 410 open apache/lucene PRs; the git history); 27 hits assessed, none the same bug. Nearest: #8874 / LUCENE-7823 (the introducing issue; its design intent 'uses BM25 scoring as a probability measure of both prior and likelihood'), #8723 / LUCENE-7672 (open: CachingNaiveBayesClassifier omits the log prior; different class and fix site), #6529 / LUCENE-5466 (training query ignored in SimpleNaiveBayesClassifier's class count; different class), #8251 / LUCENE-7196 (DatasetSplitter class coverage; predates BM25NB), #9158 / LUCENE-8110 (open: getClasses(text, max) IndexOutOfBoundsException; constrains the fix design), #9609 / LUCENE-8563 (the BM25 (k1+1) removal that amplified the symptom; does not mention classification). No open PR touches BM25NBClassifier.java. Not fixed upstream (main cf398bfb142c, 2026-10-26, file unchanged).
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 9.12.3 release jars (assertions on). The hunt and its verifiers ran on mainea57360912ed, whoselucene/classificationis identical. The version-history runs ran releases from 6.5.1 to 10.5.2. Fixes A and B were validated in the scratch worktree: the new test and the wholelucene/classificationsuite (fix A with assertions on and off, plus:lucene:classification:check -x test).
- Finding record
lucene/classification/src/java/org/apache/lucene/classification/BM25NBClassifier.java:42-46 (class javadoc 'A classifier approximating naive bayes classifier by using pure queries on BM25', @lucene.experimental), :72-73 (query javadoc 'a Query to eventually filter the docs used for training the classifier'), :95-97 (assignClass = first of the normalised list), :107-111 (getClasses(text, max) subList), :113-139 (assignClassNormalizedList, :124 MultiTerms.getTerms), :147-173 (normClassificationResults), :197-203 (calculateLogLikelihood), :205-220 (getTermProbForClass: class term MUST, words SHOULD, query MUST; :219 fallback 1), :222-231 (calculateLogPrior: class term MUST, query MUST; :230 fallback 0)
- The finding in 30 seconds
lucene/classification/src/java/org/apache/lucene/classification/BM25NBClassifier.java:43, :72-73, :96, :124-136, :147-173, :197-203, :205-220, :222-231 (read at a9779ef3c193)lucene/core/src/java/org/apache/lucene/search/similarities/BM25Similarity.java:140 (idf), :267 (doScore), :328 (the tf formula in the explanation)
- Who is affected
lucene/classification/src/java/org/apache/lucene/classification/BM25NBClassifier.java:45 (@lucene.experimental)
- Why it looks unintended
lucene/classification/src/java/org/apache/lucene/classification/BM25NBClassifier.java:43, :45, :72-73, :117 (read at a9779ef3c193)lucene/classification/src/java/org/apache/lucene/classification/package-info.java:19lucene/classification/src/test/org/apache/lucene/classification/TestBM25NBClassifier.java (testBasicUsageWithQuery); ClassificationTestBase.java:190, :210 ('not' in a politics and a technology document), :232, :260 (forceMerge)lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:140-163 (a one-document class can go to test or cross-validation)
- Suggested fix
lucene/classification/src/java/org/apache/lucene/classification/SimpleNaiveBayesClassifier.java:102-113; KNearestNeighborClassifier.java:126-138; utils/ConfusionMatrixGenerator.java:109; document/KNearestNeighborDocumentClassifier.java:112; Classifier.java:30-59lucene/classification/src/java/org/apache/lucene/classification/utils/ConfusionMatrixGenerator.java:81-83, :149 (time / counter)
- TestBM25NBUntrainedClass.java (JUnit test):
repro/LFV-388/src/org/apache/lucene/classification/TestBM25NBUntrainedClass.java(60 lines)
assets/LFV-388/bug.png(447 KB)