A fuzzy kNN classification query weights its terms with an idf that turns negative on an index full of unmerged deletes, and then throws instead of matching.
- A deleted document stays in its segment, only marked as deleted, until a merge rewrites that segment.
numDocs()counts the live documents,maxDoc()every document still in a segment, anddocFreq(term)the documents containing the term, deleted ones included: its javadoc says it "does not take into account deleted documents that have not yet been merged away". NearestFuzzyQuery(classification module) expands each input term into fuzzy variants (one edit away) and gives each a boost of edit-similarity² × idf.KNearestFuzzyClassifierruns it to find the k most similar training documents and lets them vote on the class.
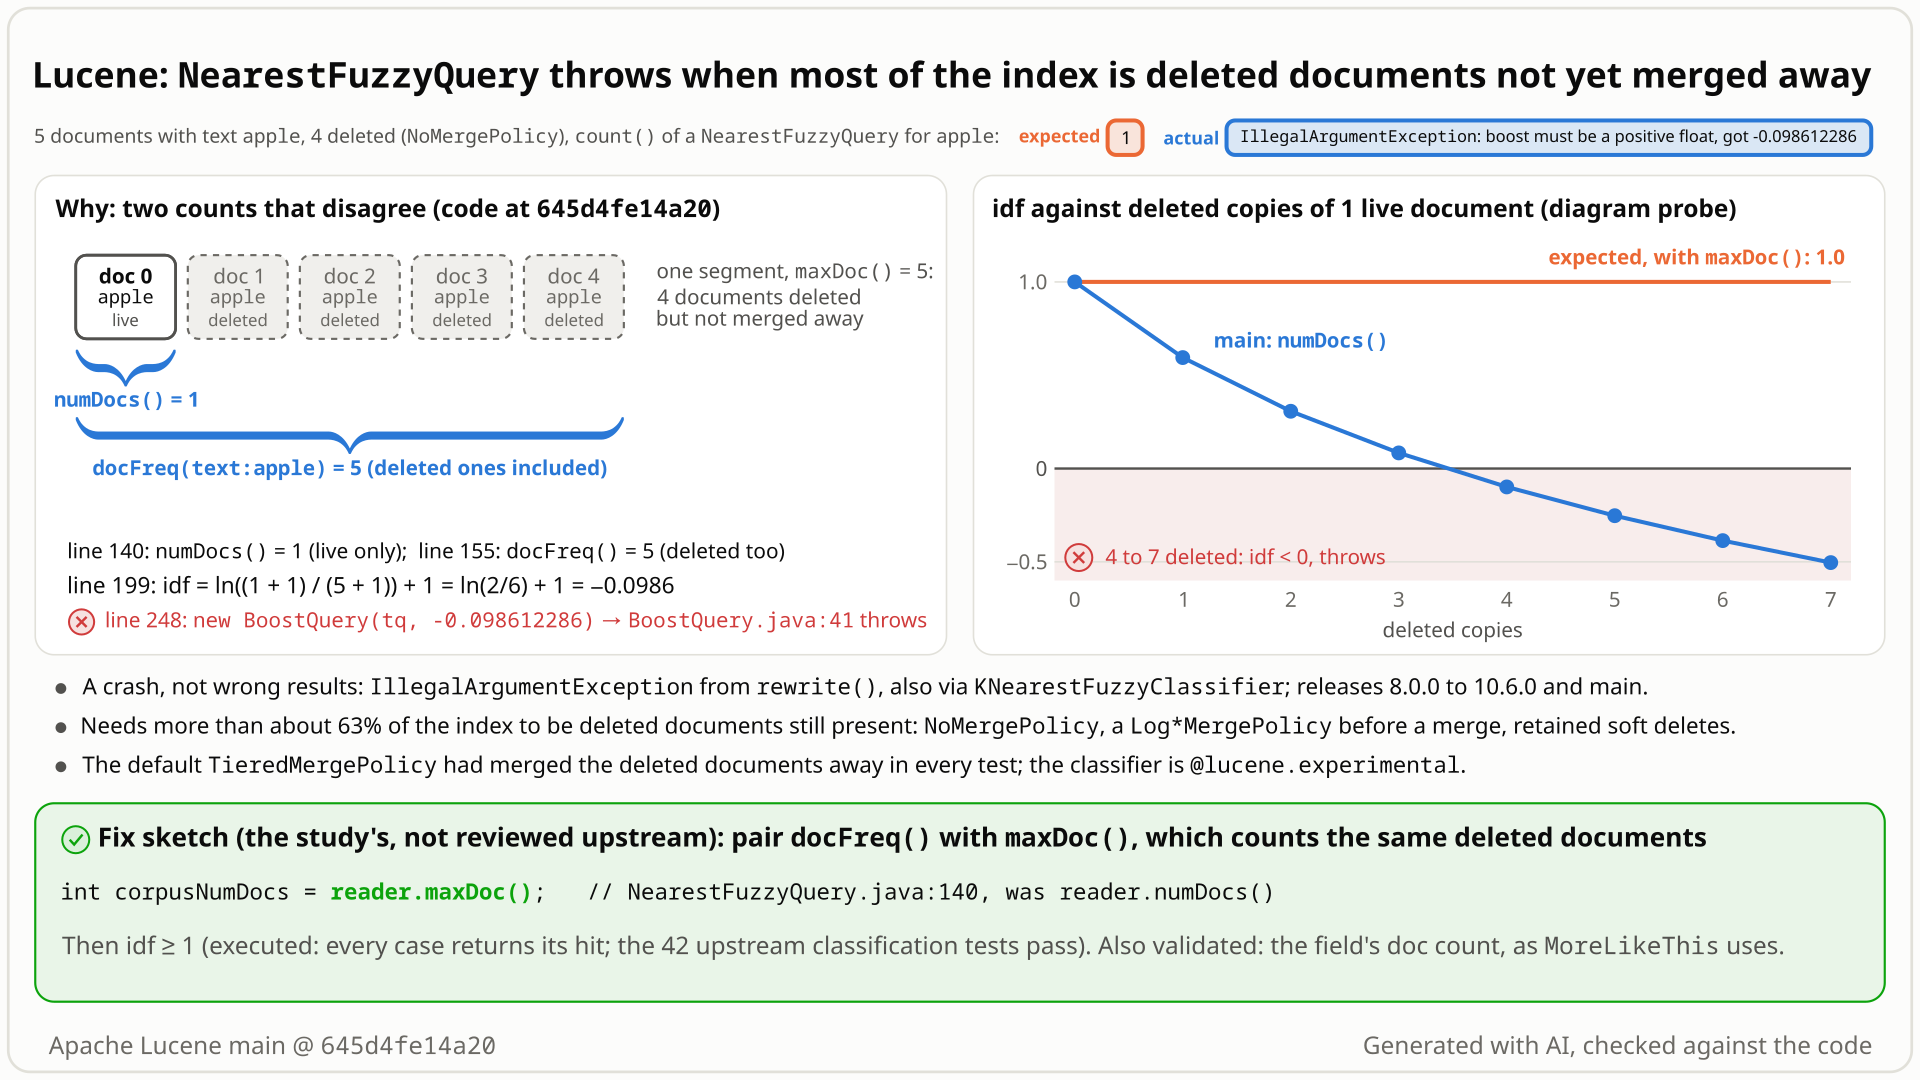
numDocs() = 1 but docFreq = 5, so the idf is ln(2/6) + 1 < 0 and BoostQuery throws; with maxDoc() the idf is 1. Select the still to open it at full size. Generated with AI, checked against the code.- Index 5 documents whose
textis "apple" and delete 4 before a merge reclaims them (the repro usesNoMergePolicy; a stockLogDocMergePolicybefore a merge or soft-delete retention give the same counts). The reader reportsnumDocs()= 1 butdocFreq(text:apple)= 5: docFreq still counts deleted documents, as documented. - Count the hits of a
NearestFuzzyQueryfor "apple", or callKNearestFuzzyClassifier.assignClass("apple"). You expect 1 hit, the live document, and its class. - Instead the query's rewrite throws
IllegalArgumentException: boost must be a positive float, got -0.098612286, with assertions on and off. - Why: the term weight is idf = ln((numDocs + 1) / (docFreq + 1)) + 1 = ln(2/6) + 1 = −0.0986, and
BoostQueryrejects a negative boost. WithmaxDoc()= 5 in place ofnumDocs(): ln(6/6) + 1 = 1. - It takes docFreq + 1 > e × (numDocs + 1): with 3 deleted copies (docFreq 4) the idf is still +0.084 and the query works. So more than about 63% of the index must be deleted but not merged away; the default
TieredMergePolicyhad reclaimed the deletes in every tested shape.
Users of the opt-in classification module's KNearestFuzzyClassifier (@lucene.experimental) or NearestFuzzyQuery, on an index where over about 63% of documents are deleted but not merged: a stock Log*MergePolicy before a merge, soft-delete retention of often-updated documents, NoMergePolicy. Requests whose kept fuzzy variants include an affected term throw; others work. The default merge policy reclaimed the deletes in every tested shape.
Mechanism, terms and numbers745 words
NearestFuzzyQuery, the query behind KNearestFuzzyClassifier in the classification module, weights each term with idf = ln((numDocs + 1) / (docFreq + 1)) + 1, taking numDocs from reader.numDocs() (live documents only) and docFreq from reader.docFreq(), which still counts deleted documents that are not merged away yet. When the deleted copies push docFreq + 1 above e × (numDocs + 1), the idf is negative, and new BoostQuery(termQuery, negativeScore) in rewrite() throws IllegalArgumentException: boost must be a positive float (since 8.0.0, when LUCENE-7996 made BoostQuery reject negative boosts; 7.x silently returned negative scores). The smallest case with a live document is 5 documents with "apple", 4 deleted: numDocs 1, docFreq 5, idf −0.0986 (with retained soft deletes and no live document, 2 documents already throw). It needs more than about 63% of all documents deleted but still present: reached with the stock Log*MergePolicy before a merge, soft-delete retention (even after forceMerge(1)) and NoMergePolicy, not with the default TieredMergePolicy in any tested shape. Using reader.maxDoc() keeps idf ≥ 1; the highlighter had the same mismatch: LUCENE-1355 clamped docFreq, then LUCENE-4289 switched to maxDoc().
KNearestFuzzyClassifier.assignClassandgetClasses(KNearestFuzzyClassifier.java:105-133) callknnSearch(:135-148), which adds oneNearestFuzzyQueryfor the input text (addTermsonce per text field) as aMUSTclause, next to aMUSTWildcardQueryon the class field and the optional filter query, and callsindexSearcher.search(bq.build(), k)(:147). Those clauses do not help:rewritetakes its statistics from the whole reader.NearestFuzzyQuery.rewrite(NearestFuzzyQuery.java:217-264) collects the terms on the searcher's whole reader (:219,:223). The privateaddTermsreadsint corpusNumDocs = reader.numDocs();(:140), then per analyzed termint df = reader.docFreq(startTerm);(:155); when the term itself is absent,dfis the average docFreq of its variants (:173-178), which counts deleted documents too.- Each variant's score is
(editBoost * editBoost) * idf(df, corpusNumDocs)(:187), withidf = (float) (Math.log((docCount + 1) / (double) (docFreq + 1)) + 1.0)(:198-200). The squared factor is never negative (it can be 0 for an edit of a one-character term, and 0 × a negative idf is −0.0, whichBoostQueryrejects too), so a variant's boost is rejected exactly when the idf is negative: docFreq + 1 > e × (numDocs + 1). rewritewraps each variant asnew BoostQuery(tq, st.score)(:248,:256), andBoostQuery's constructor throwsIllegalArgumentException("boost must be a positive float, got " + boost)for a negative boost (BoostQuery.java:38-44). It is a plain check, not an assertion.numDocs()counts live documents (IndexReader.java:292-298),docFreqalso counts deleted ones (IndexReader.java:401-408), and docFreq ≤maxDoc(). So withmaxDoc()at:140the idf is always ≥ 1.
- The minimal repro: 5 documents with "apple", 4 deleted under
NoMergePolicy, an NRT reader: numDocs 1, maxDoc 5, docFreq 5;count(NearestFuzzyQuery("apple"))throwsboost must be a positive float, got -0.098612286= ln(2/6) + 1, with-eaand-da, on main and on the 10.6.0 jars. - Sweep, 1 live document plus d deleted copies: d = 0, 1, 2, 3 give idf 1.0, 0.595, 0.307, 0.084 and 1 hit; d = 4 to 8 throw exactly the predicted idf: -0.0986, -0.253, -0.386, -0.504, -0.609.
- The same failure, executed on main and 10.6.0:
KNearestFuzzyClassifier.assignClass("apple"); the misspelled input "appel" (-0.0631 = 0.8² × -0.0986, through the variant average); a commit-point reader instead of an NRT reader; one document soft-updated 4 times whileSoftDeletesRetentionMergePolicykeeps the old versions, thenforceMerge(1);LogDocMergePolicyat its defaults. - Not affected: no deletions; 3 of 4 deleted; the default
IndexWriterConfig, which had already dropped the deletes when the reader opened (maxDoc 1). - Threshold in general: since docFreq ≤ maxDoc, it needs maxDoc + 1 > e × (numDocs + 1), more than about 1 − 1/e = 63% of the reader's documents deleted but present (80% with 1 live document). Then an input term whose df (its docFreq, or for an absent term its variants' average, deleted copies included) exceeds e × (numDocs + 1) − 1 makes
rewritethrow if one of its variants is kept. For long input that is necessary, not sufficient: the query keeps only the 300 highest-scoring variants overall (MAX_NUM_TERMS,:58), so enough positive-scored variants can push the negative ones out; the one-term repro always keeps its variant. Inputs without such a term still work.
Exposure and likelihood332 words
- Who is hit. Applications that use
KNearestFuzzyClassifier(@lucene.experimental) orNearestFuzzyQuery(public, not tagged experimental) from the opt-in classification module, on an index or reader where more than about 63% of the documents are deleted but still present. A request throws when a kept fuzzy variant comes from a term above the threshold (in long input, positive-scored variants can push it out of the 300 kept); others work. - Default vs opt-in. The default
IndexWriterConfig(TieredMergePolicy) dropped the deletes in every test, including a probe with up to 1,000 added-then-deleted documents; itsdeletesPctAllowed, "the maximum percentage of doc id space taken by deleted docs", is 20% by default and at most 50% (TieredMergePolicy.java:120-124), both under the 63% needed, but it is a target for merge selection, not a guarantee, and heavy churn on large segments was not tested. The state does arise with supported setups: the stockLogByteSizeMergePolicyorLogDocMergePolicybefore a merge;SoftDeletesRetentionMergePolicy(itself@lucene.experimental), whose "main purpose ... is to implement retention policies for document modification to vanish in the index" (SoftDeletesRetentionMergePolicy.java:40-44;forceMerge(1)keeps the retained versions);NoMergePolicy; or a reader view that hides documents through live docs (no deletions at all; a custom wrapper, an informational run). - Scale. No scale needed: 5 documents. The failure is immediate and loud; nothing wrong is returned and nothing is written. It lasts as long as the index state does.
- Likelihood: rare. No downstream caller of these classes was found: Solr's classification processor uses
KNearestNeighborDocumentClassifierandSimpleNaiveBayesDocumentClassifier, and code search of Solr, Elasticsearch and OpenSearch finds neither class. No public report was found in the documented searches, although the exception has existed since 8.0.0 (2019). - Workaround. Reclaim the deletes before classifying (a merge that drops them removes the trigger), or catch
IllegalArgumentExceptionand treat the input as unclassified. Under soft-delete retention a merge keeps the retained versions (evenforceMerge(1)), so there the retention query or the retained data has to change first.
One JUnit class for lucene/classification/src/test/org/apache/lucene/classification/utils/, one method, public API only: 5 documents with "apple", 4 deleted under NoMergePolicy, an NRT reader, then count of a NearestFuzzyQuery for "apple". It calls no random(), and it failed the same way under every recorded seed of Lucene's randomized test framework, with assertions on and off; it is also the suggested regression test.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.classification.utils;

import java.util.List;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.NoMergePolicy;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestNearestFuzzyQueryDeletedDocs extends LuceneTestCase {

  public void testDeletedDocsNotMergedAway() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE))) {
      for (int i = 0; i < 5; i++) {
        w.addDocument(
            List.of(
                new StringField("id", i == 0 ? "live" : "deleted", Field.Store.NO),
                new TextField("text", "apple", Field.Store.NO)));
      }
      w.deleteDocuments(new Term("id", "deleted"));
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        NearestFuzzyQuery query = new NearestFuzzyQuery(new StandardAnalyzer());
        query.addTerms("apple", "text");
        try {
          assertEquals(1, new IndexSearcher(reader).count(query));
        } catch (IllegalArgumentException e) {
          fail(
              "expected: 1 hit (numDocs=" + reader.numDocs() + ", docFreq(apple)="
                  + reader.docFreq(new Term("text", "apple")) + "); actual: " + e.getMessage());
        }
      }
    }
  }
}
cp $REPRO/TestNearestFuzzyQueryDeletedDocs.java $LUCENE/lucene/classification/src/test/org/apache/lucene/classification/utils/
cd $LUCENE && ./gradlew --no-daemon :lucene:classification:test --tests org.apache.lucene.classification.utils.TestNearestFuzzyQueryDeletedDocs -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same failure)
- Expected
- 1 hit: the one live document containing "apple".
- Observed
IllegalArgumentException: boost must be a positive float, got -0.098612286fromBoostQuery.<init>inNearestFuzzyQuery.rewrite, with assertions on and off.
More files, environment, full output173 words
The test catches only the IllegalArgumentException and turns it into a failure that states expected vs actual, including numDocs and docFreq. NoMergePolicy is just the simplest way to keep the deletes: a stock LogDocMergePolicy before a merge or one document soft-updated 4 times under SoftDeletesRetentionMergePolicy (even after forceMerge(1)) reach the same counts and fail the same way, and so does KNearestFuzzyClassifier.assignClass("apple") on the same documents with a class field added. Formatting: google-java-format reflows the fail(...) message. The test could equally be a method of the existing TestKNearestFuzzyClassifier.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also the 10.6.0 release; the exception exists since 8.0.0 |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
TestNearestFuzzyQueryDeletedDocs > testDeletedDocsNotMergedAway FAILED
    java.lang.AssertionError: expected: 1 hit (numDocs=1, docFreq(apple)=5); actual: boost must be a positive float, got -0.098612286
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:643F8D37CED96DDE]:0)
        at junit@4.13.2/org.junit.Assert.fail(Assert.java:89)
        at org.apache.lucene.classification.utils.TestNearestFuzzyQueryDeletedDocs.testDeletedDocsNotMergedAway(TestNearestFuzzyQueryDeletedDocs.java:53)

1 test completed, 1 failed

# the same with -Ptests.asserts=false and on the 10.6.0 release jars; the exception is thrown at
#   BoostQuery.<init>(BoostQuery.java:41) <- NearestFuzzyQuery.rewrite(NearestFuzzyQuery.java:248) (:245 on 10.6.0)
# with the recommended fix the test passesdocFreqcounts deleted documents (IndexReader.java:402-404); core similarities pair it with a count of the same documents for exactly this reason (TFIDFSimilarity.java:360-363), and so doesMoreLikeThis.MIGRATE.md(LUCENE-7996): a query's score formula "may never produce negative scores".- The same numDocs-against-docFreq idf bug was fixed twice in the highlighter (LUCENE-1355 clamped docFreq; LUCENE-4289 then switched
numDocs()tomaxDoc()).
The full argument344 words
- The two counts come from different populations, and Lucene documents it.
IndexReader.docFreq: "This method does not take into account deleted documents that have not yet been merged away" (IndexReader.java:402-404).TFIDFSimilarity.idfExplain:FieldStats#docCount()"is used instead of IndexReader#numDocs() because also TermStats#docFreq() is used, and when the latter is inaccurate, so is FieldStats#docCount(), and in the same direction" (TFIDFSimilarity.java:360-363).MoreLikeThistakes its idf corpus size fromir.getDocCount(fieldName)(MoreLikeThis.java:634). - Queries must not produce negative scores.
MIGRATE.md:1368-1375, "Scorer must produce positive scores (LUCENE-7996)": "If you have custom query implementations, you should make sure their score formula may never produce negative scores. As a side-effect of this change, negative boosts are now rejected". - Fixed as a bug before, in the highlighter. LUCENE-1355 (#2432, 2008): "An index with a few documents and many deletes can report a lower total docs than docFreq for a term - total docs will account for deletes while docFreq will not - this causes the idf to be negative" (fixed by clamping docFreq). LUCENE-4289 (#5357, 2012): "highlighter uses numDocs instead of maxDoc" (fixed by
reader.numDocs()toreader.maxDoc(), which also removed the clamp).QueryTermExtractor.java:74andWeightedSpanTermExtractor.java:549usereader.maxDoc()today.NearestFuzzyQuery(2017) copied the older pairing from the sandboxFuzzyLikeThisQuery. - No precondition anywhere. No javadoc in the classification module restricts the classifier or the query to merged or deletion-free indexes, and
Classifier.assignClasspromises to "Assign a class (with score) to the given text String" (Classifier.java:31). The shared test base starts fromdeleteAll()(ClassificationTestBase.java:243, which keeps no deleted documents), then only adds documents, commits and callsforceMerge(1)(:231-232,:259-260), so the case was never exercised. - History. The LUCENE-7838 discussion (#8889) is about removing a sandbox dependency and never mentions idf or deletes; the LUCENE-7996 commit did not touch the classification module, so nothing shows its new rule was checked against this formula. Before
NearestFuzzyQuery, the first form ofKNearestFuzzyClassifier(bd9e32d3583, 2017-05-18) used the sandboxFuzzyLikeThisQuerywith the same pairing; no release shipped it (7.0.0 already hasNearestFuzzyQuery).
The devil's-advocate check210 words
The strongest case for "works as designed": the classifier is @lucene.experimental; the docFreq skew is documented behaviour; the formula was carried over from FuzzyLikeThisQuery; the trigger needs more than 63% of the index deleted, which the default merge policy avoided in every test; and BoostQuery rejects negative boosts on purpose. A maintainer could also prefer a clamp, or reject a change of ranking on indexes with deletes.
Why it fails: the tag's text, "This API is experimental and might change in incompatible ways in the next release", warns about API changes, not about exceptions on valid indexes, and NearestFuzzyQuery is not tagged; the documented docFreq skew is exactly why numDocs is the wrong partner (core similarities and MoreLikeThis avoid it, and the highlighter was fixed for it twice); the commit made a trimmed copy, and neither it nor its discussion mentions idf or deletes, so nothing shows the mismatch was chosen; rarity lowers the impact but does not make supported merge policies illegal; and the BoostQuery check is correct: the defect is the formula that feeds it a negative number, which MIGRATE.md forbids. The earlier cross-model reviews rated the intended-behaviour case weak, the fact check's cross-model reviewer moderate, without doubting the bug. Verdict: not intended; a small bug.
Recommended A: use reader.maxDoc()
Take the corpus size from reader.maxDoc() instead of reader.numDocs() at NearestFuzzyQuery.java:140 (one line). docFreq ≤ maxDoc, so the idf stays ≥ 1; indexes without deletions score exactly as before. With it the repro and the classification module's tests (44 tests: the repro and 43 upstream, 1 @Monster skipped) pass in gradle, with assertions on and off.
// docFreq also counts deleted documents that are not merged away yet, so take the corpus
// size from the same population: then docFreq <= corpusNumDocs and idf stays >= 1
int corpusNumDocs = reader.maxDoc(); // was: reader.numDocs()
All options and trade-offs3 options · 496 words
Options A and B were applied in a scratch worktree of 645d4fe14a20 and run with gradle (the worktree was removed after the runs); option C was not built. Any fix changes the idf, and so the order of neighbours, on indexes with deletes. The sandbox FuzzyLikeThisQuery has the same numDocs() line (FuzzyLikeThisQuery.java:204, read, not executed), and open draft PR #16847 edits the same lines (int to long) without touching this bug, so a fix PR may need a rebase.
One line at NearestFuzzyQuery.java:140; the comment is optional. The same change LUCENE-4289 made in the highlighter.
// docFreq also counts deleted documents that are not merged away yet, so take the corpus
// size from the same population: then docFreq <= corpusNumDocs and idf stays >= 1
int corpusNumDocs = reader.maxDoc(); // was: reader.numDocs()
Trade-offs
- docFreq ≤ maxDoc, so idf = ln((maxDoc + 1) / (docFreq + 1)) + 1 ≥ 1, for the variant-average fallback too. On an index without deletions
numDocs() == maxDoc(), so nothing changes there. - On an index with deletions the idf values, and so the neighbours' order, change, in line with core scoring statistics, which also count deleted documents.
What the checks validated
- Gradle, stock
645d4fe14a20: the repro fails with assertions on and off. - Gradle with the fix (seed DEADBEEF): the repro and every test of the classification module, 44 tests (the repro plus 43 upstream, including
TestKNearestFuzzyClassifier3), 1 skipped (Test20NewsgroupsClassification,@Monster), 0 failures, with assertions on and off.checkGoogleJavaFormataccepts the change. - Earlier hunt checks: the finder's, a verifier's, the adjudication's and the minimization's shadowed fix checks pass, and all 7 checks of the tiebreak program pass with it on main.
int corpusNumDocs = terms.getDocCount(); (terms is the field's Terms from MultiTerms.getTerms(reader, field) at NearestFuzzyQuery.java:133: the leaf's own Terms for one segment, a MultiTerms for several), as TFIDFSimilarity and MoreLikeThis do.
int corpusNumDocs = terms.getDocCount(); // was: reader.numDocs()Trade-offs
- A term's docFreq in the field is at most the number of documents with the field (both count deleted documents), so the idf stays ≥ 1.
- Also changes the idf on deletion-free indexes whenever the field is sparse (docCount < maxDoc), so it moves more rankings than A.
What the checks validated
Same scratch worktree, gradle, seed DEADBEEF, assertions on: the repro and the classification module, 44 tests, 1 skipped, 0 failures, with the codecs those runs drew. MoreLikeThis keeps a fallback to numDocs() for getDocCount() == -1 (MoreLikeThis.java:635-637) that B lacks; at 645d4fe14a20 the Terms.getDocCount() javadoc documents no -1 case (Terms.java:117-121).
The LUCENE-1355 style: df = Math.min(df, corpusNumDocs) before computing the idf.
Trade-offs
Never negative, but it keeps mixing the two populations for every term below the clamp; LUCENE-4289 later replaced exactly this clamp with maxDoc() in the highlighter.
No downstream caller of these classes was found; an application that exposes KNearestFuzzyClassifier over an index that keeps deletes would see requests with common terms fail, and can catch the IllegalArgumentException until a fix ships.
AI tools fuzzed every classifier in the module with Jazzer (coverage-guided) against simple invariants, on small random training sets with deletions. After 184,134 runs one input threw this exception; the thrown value, ln(2/7) + 1, pointed to docFreq 6 against 1 live document, and a public-API JUnit confirmed it on the stock jar.
The method in full135 words
Method: non-formal baseline (coverage-guided fuzzing).
- The hunt unit for the classification module ran Jazzer 0.30.0 on a property harness that builds random small training sets (with deletions under
NoMergePolicy) and checks invariants for every classifier: 2 runs of 20 minutes, 427,743 executions. Its one finding, after 184,134 runs, wasIllegalArgumentException: boost must be a positive float, got -0.25276297fromNearestFuzzyQuery.rewriteviaKNearestFuzzyClassifier.getClasses. The seeded random driver (10,000 cases) had not hit it. - The value ln(2/7) + 1 gave away docFreq 6 against numDocs 1, and the finder wrote a public-API JUnit on the stock jar. Independent verifiers then reproduced it with their own tests and other triggers, found the exact threshold (docFreq 5 for 1 live document) and that the exception dates from 8.0.0; the case was later reduced to the one-method test.
No prior report found (2026-10-26, 125 logged queries): GitHub issues and PRs incl. the JIRA archive, four mailing lists, downstream projects, the web and the changed files of every open PR; re-checked 2026-10-30. Nearest: #10608 (same message, different cause) and the highlighter fixes LUCENE-1355 and LUCENE-4289 (same defect class, other code).
Searches4 searches
No report of this bug was found, and upstream main, branch_11x and branch_10_6 still have the line. #10608 / LUCENE-9568 (open) shares the exception text, but there a negative FuzzyTermsEnum edit boost reaches a highlighting rewrite; NearestFuzzyQuery squares that factor, so it cannot cause this. LUCENE-1355 (#2432), LUCENE-4289 (#5357) and the MoreLikeThis changes LUCENE-8333 / LUCENE-8984 fixed the same kind of count mismatch in other code: precedent, not reports. Open draft PR #16847 edits the same lines without touching the bug.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs, commits (apache/lucene incl. the migrated JIRA archive; downstream repositories) | 2026-10-26 | an automated pass (18 issue/PR, 3 commit, 3 downstream queries) plus 25 manual searches: both class names, the exception text, negative idf, numDocs/maxDoc idf, FuzzyLikeThis, downstream projects (Elasticsearch, OpenSearch, Solr, Lucene.NET) | no report; closest #10608 (same message, different cause), #8889 (introduced the class), #9044 (the positive-score rule) |
| Mailing lists, JIRA, web | 2026-10-26 | 32 automated and 9 manual list queries over dev@, java-user@, issues@ and commits@; 8 automated and 13 manual JIRA queries (LUCENE and SOLR, all 47 classification issues); 12 web queries | nothing about this bug; one Stack Overflow page on the #10608 highlighter case could be read by title only |
| Open PRs and upstream history | 2026-10-26 | module labels for PRs since 2025-02 and the changed-file lists of the 163 older open PRs; git log -S on the full history | only draft PR #16847 touches the file (int to long, keeps numDocs()); no fix |
| Re-check for this page | 2026-10-30 | the line on upstream main, branch_11x and branch_10_6; GitHub searches for both class names, the exception text and negative idf with deletes | unchanged; only #8889 and #10608 come up |
Introduced by LUCENE-7838 (92e460389dc9, 2017, first released in 7.0.0), which copied the numDocs/docFreq pairing from the sandbox FuzzyLikeThisQuery. It throws since 8.0.0, when LUCENE-7996 (a8a63464e7da) made BoostQuery reject negative boosts; 7.x returns negative scores silently. 8.0.0 to 10.6.0 and main are affected (7 releases and main run).
Versions tested10 rows
92e460389dc9 "LUCENE-7838 - removed dep from sandbox, created a minimal FLT version specific for knn classification" (tteofili, 2017-06-29, committed directly, issue #8889; CHANGES 7.0.0 New Features) wrote every defective line; git blame attributes NearestFuzzyQuery.java:140, :155, :187 and :248 to it; :199 and :255-256 show the later reformat 7f8b7ffbcad (LUCENE-9570, same expressions). Before it, bd9e32d3583 (2017-05-18, same issue) had built KNearestFuzzyClassifier on the sandbox FuzzyLikeThisQuery with the same pairing; no release shipped that form. a8a63464e7da "LUCENE-7996: Queries are now required to produce positive scores." (jpountz, 2017-12-06, #9044; CHANGES 8.0.0) added the BoostQuery check; that change is correct and turned the wrong idf into an exception. Swapping only that check confirms the boundary: added to 7.7.3, 7.7.3 throws the same value; removed from 8.0.0, the test passes with assertions off and a negative hit score.
The 10.6.0 row and the gradle runs on main use the minimal test; the older rows use the finder's tests (1 live and 5 deleted copies, thrown value -0.25276297 = ln(2/7) + 1). All on OpenJDK 25.0.3, Linux aarch64; release jars SHA-1 checked against Maven Central. The releases not run have the same lines and the check (read at every tag, not executed).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 (unreleased 11.0) | affected | throws, -ea and -da (gradle and standalone) |
main ea57360912ed, a9779ef3c193 | affected | throws (ea57360912ed with -ea and -da) |
| 10.6.0 | affected | throws, -ea and -da (minimal test and the 7-check program) |
| 10.5.2 | affected | throws, -ea and -da |
| 10.0.0, 9.0.0 | affected | throws |
| 9.12.3, 8.11.4 | affected | throws, -ea and -da |
| 8.0.0 | affected | throws, -ea and -da (first release with the BoostQuery check) |
| 7.0.0, 7.7.3 | silent | no exception: negative boost -0.25276297 and negative hit score -0.3893675 (same root cause) |
| 7.7.3 + only the LUCENE-7996 check; 8.0.0 − only that check | swap | 7.7.3 then throws the same value; 8.0.0 then passes with -da and a negative score |
| 6.6.6 | n/a | does not compile: neither class exists |
The finder, an independent reproducer, a devil's advocate, an adjudication, a credibility audit, a tiebreak check, this page's gradle runs and its fact check all reproduce it. Cross-model reviews (OpenAI GPT-5.6) could not execute the repro: some said real; the others said not real on procedure alone, agreeing with the root cause.
Checks and verdicts512 words
Every executing check ran on the stock jars and voted real. The "not real" verdicts are procedural: those reviews could not execute (one ran read-only, the other could run no command) and they needed an executed repro of their own; both agreed with the root cause, called the inputs legal and rated the intended-behaviour case weak.
| Check | Verdict | What it found |
|---|---|---|
| Finder (finder) | candidate | Jazzer finding (1 in 427,743 runs); public-API JUnit fails 2 of 2 on main (-ea, -da), 20 of 20 iterated, 10.5.2 and 9.12.3; the maxDoc fix passes it, with 42 upstream classification tests. |
| Cross-model review, refute lens (OpenAI GPT-5.6, 2026-10-26) | not real, low (procedural) | Read-only, could run nothing; root cause agreed, inputs in contract, intended-behaviour case weak; a separate re-run fails 2 of 2. |
| Independent reproducer | real | Own 4-test JUnit (update sweep, soft-delete retention + forceMerge(1), classifier, control): 3 of 4 fail on main (-ea, -da), 10.5.2 and 9.12.3; thrown values equal the predicted idf; corrected the version (exception since 8.0.0) and the threshold (docFreq 5). |
| Cross-model review, intended lens (OpenAI GPT-5.6) | real, medium; intended case weak | Read-only review; separate controls fail 2 of 5 as predicted and pass 5 of 5 with the fix. |
| Intended-behaviour devil's advocate | real | Own JUnit with LogByteSizeMergePolicy and LogDocMergePolicy at their defaults fails on main (-ea, -da) and 10.5.2; the default TieredMergePolicy did not reach it; found LUCENE-1355 and LUCENE-4289. |
| Adjudication | confirmed, high; severity Low | Re-ran the independent reproduction's test with a new seed: 3 of 4 fail with -ea and -da, 4 of 4 pass with the fix. |
| Credibility audit | keep | Re-ran the finder's test with -da and a new seed: 2 of 2 fail. |
| Second cross-model refute review (OpenAI GPT-5.6, 2026-10-30) | not real, medium (procedural) | It could run no command, so it ran nothing; root cause agreed, inputs in contract, intended case weak. A separate re-run of the minimal test fails 1 of 1 with -ea and -da. |
| Tiebreak check (2026-10-30) | reproduced | The minimal test fails on main and 10.6.0 (-ea, -da); a stand-alone 7-check program (query, classifier, misspelled input, commit-point reader, soft-delete retention + forceMerge(1), LogDocMergePolicy) fails 7 of 7 with 3 controls passing on both; everything passes with the fix. |
| This page's runs | reproduced; fixes A and B validated | Gradle on 645d4fe14a20: the minimal test fails with -ea and -da; with fix A it passes with the whole classification module (-ea and -da), with fix B likewise (-ea). |
| Fact check of this page (2026-10-30) | real, no blocking error | The page's exact gradle command fails the same way (-ea, -da); fix A with the whole classification module, new seed, -da: 44 tests, 1 skipped, 0 failures; the minimal test fails on main and 10.6.0 and passes with fix A or B; precision fixes applied. |
| Cross-model fact check (OpenAI GPT-5.6, read-only, 2026-10-30) | real; intended case moderate | Read the code and the recorded runs, executed no Java; confirmed the root cause, the numbers and the history, and asked for wording corrections, applied here. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 404 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,500 words
- Registry title
- NearestFuzzyQuery (used by KNearestFuzzyClassifier) computes idf from reader.numDocs() (live documents) and reader.docFreq() (which still counts deleted documents), so when deleted documents that are not yet merged away make up most of the index the idf is negative and rewrite throws 'boost must be a positive float' (released since 8.0.0)
- Area
- classification / NearestFuzzyQuery (KNearestFuzzyClassifier)
- Priority
- Low, rank 630: The experimental KNearestFuzzyClassifier/NearestFuzzyQuery throws IllegalArgumentException only when more than about 63% of the index is unmerged deleted documents (non-default merge setups), so it sits with the other niche queries that throw instead of answering.
- Impact class
- crash
- Impact note
- Applications that use the opt-in lucene/classification module's KNearestFuzzyClassifier (@lucene.experimental) or NearestFuzzyQuery directly are hit when more than about 63% (1 - 1/e) of the whole index is deleted documents that are still present and the input has a term whose docFreq, counting deleted copies, exceeds e*(numDocs+1) - 1: every such request throws IllegalArgumentException instead of returning hits or a class. That index state was reached with NoMergePolicy, the stock LogByteSizeMergePolicy and LogDocMergePolicy before a merge, SoftDeletesRetentionMergePolicy (even after forceMerge(1)) and a reader view that hides documents through live docs, but never with the default TieredMergePolicy in any test. No scale is needed (6 documents suffice), and every release from 8.0.0 to 10.6.0 is affected (10.6.0 executed on its release jars).
- Summary
- You index 6 documents containing 'apple' (class fruit), delete 5 of them under NoMergePolicy (or soft-delete them and keep them with SoftDeletesRetentionMergePolicy), and then search NearestFuzzyQuery('apple') or call KNearestFuzzyClassifier.assignClass('apple'), expecting the one live document and the class fruit. Instead both throw IllegalArgumentException 'boost must be a positive float, got -0.25276297'. NearestFuzzyQuery computes idf = ln((numDocs+1)/(docFreq+1)) + 1 from reader.numDocs(), which counts only live documents, and reader.docFreq(), which still counts the 5 deleted copies, so idf = ln(2/7) + 1 < 0, and since LUCENE-7996 (8.0.0) BoostQuery rejects the resulting negative boost.
- Introduced
- 92e460389dc9b0af83c445cb029e3a51799a37dc 'LUCENE-7838 - removed dep from sandbox, created a minimal FLT version specific for knn classification' (by GitHub tteofili; issue apache/lucene#8889; committed directly to master, no pull request) created NearestFuzzyQuery and wrote every defective line: corpusNumDocs = reader.numDocs() (:140 on main), df = reader.docFreq(startTerm) (:155), score = edit^2 * idf(df, corpusNumDocs) (:187), the idf formula (:198-199; line 199 later reformatted by 7f8b7ffbcad, LUCENE-9570, same expression) and new BoostQuery(tq, st.score) (:248, :256) [read: git blame on main; the pairing was copied from the sandbox FuzzyLikeThisQuery, where it dates from 87768c51c632, 2006]. The exception comes from a later, correct change, not from the defect: a8a63464e7da63b3dbc884634fd0e00b3f0c140b 'LUCENE-7996: Queries are now required to produce positive scores' (by GitHub jpountz; apache/lucene#9044) added the BoostQuery positive-boost check [exec: adding only that 3-line check to 7.7.3's BoostQuery makes 7.7.3 throw the same exception and value; removing only it from 8.0.0 makes the test pass under -da with a negative hit score] (2017-06-29 (92e460389dc9, the defect); 2017-12-06 (a8a63464e7da, LUCENE-7996, which turns it into an exception))
- First affected version
- 8.0.0 [exec] for the IllegalArgumentException (the first release with the LUCENE-7996 BoostQuery check). The defective idf is in every release since 7.0.0, the first release with NearestFuzzyQuery and KNearestFuzzyClassifier (6.6.6: API absent, compile error [exec]); on 7.0.0 and 7.7.3 [exec] the same input silently gives a negative boost (-0.25276297) and a negative hit score (-0.3893675) instead of throwing
- Affected versions
- Exception: every release from 8.0.0 to 10.6.0 and main ea57360912ed (10.6.0 [exec] on its release jars, -ea and -da, in the bug doc's re-check). [exec] the follow-up history matrix (same seed, same thrown value -0.25276297): 8.0.0 (-ea and -da), 8.11.4 (-ea and -da), 9.0.0, 9.12.3 (-ea and -da), 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da) fail; the finder's JUnit fails 2 of 2 on main (-ea and -da), 10.5.2 and 9.12.3 (9.x accessor variant repro/src-9x); the independent reproduction's JUnit fails 3 of 4 (its control passes) on main (-ea and -da), 10.5.2 and 9.12.3; the intended-behaviour check's LogByteSizeMergePolicy/LogDocMergePolicy JUnit fails 2 of 2 on main (-ea and -da) and 10.5.2. [read] The NearestFuzzyQuery lines are identical at every release tag from 7.0.0 to 10.5.2 apart from the 9.0.0 reformat, and BoostQuery has the check at every tag from 8.0.0; 8.8.2-8.11.3 are not tagged in the history clone (bracketed by the 8.0.0 and 8.11.4 runs). Same root cause, different symptom: 7.0.0-7.7.3 return a negative boost and score without an exception [exec 7.0.0, 7.7.3]. Not affected: 6.x and earlier (API absent). Not fixed upstream: the file's last upstream change is a7704f5242d (2025-06-18) and upstream main still has the numDocs line (the intended-behaviour check, the prior-report record, 2026-10-26)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its “not real” is procedural), an adjudication that ruled it real, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal baseline: fuzzing/PBT
- Upstream and prior reports
- none found (2026-10-26, read-only, the prior-report record verdict new: 125 logged queries, 0 errors: scripted prior-report searches with 18 GitHub issue and PR, 3 commit, 3 downstream, 32 mailing-list (dev@, java-user@, issues@, commits@), 8 JIRA-archive and 6 web queries; 25 manual GitHub searches, 13 manual JIRA (LUCENE and SOLR), 9 manual list, 6 manual web and 2 git queries; every open apache/lucene PR checked for changes to NearestFuzzyQuery.java or FuzzyLikeThisQuery.java (path labels for PRs since 2025-02, changed-file lists for the 163 older open PRs); the finder's and the intended-behaviour check's earlier searches agree); 23 hits assessed, none the same bug. Nearest: #10608 / LUCENE-9568 (open: the same exception text from a negative FuzzyTermsEnum edit boost in highlighting; different code, and in NearestFuzzyQuery that factor is squared), open PR #16847 (long global doc ids: edits NearestFuzzyQuery.java:140, :155, :198 from int to long but keeps reader.numDocs(); neither fixes nor mentions the bug, and a fix would touch the same lines), #8889 / LUCENE-7838 (the introducing issue; no mention of deletes or idf), #9044 / LUCENE-7996 (the positive-score rule); same defect class fixed only in other code: #2432 / LUCENE-1355 and #5357 / LUCENE-4289 (highlighter idf negative with deletes, fixed there by numDocs -> maxDoc), LUCENE-8333 and LUCENE-8984 (MoreLikeThis maxDoc / docCount). Not fixed upstream (file last changed 2025-06-18).
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28; main716d6f216f52, branch_11x603af8703753and branch_10_67e5aec4370e0as fetched on 2026-10-29, and live upstream mainf6e64aa0db37on 2026-10-30, have the same line): the minimal repro with gradle in a scratch worktree, stock with assertions on and off, and with fix A (assertions on and off) and fix B together with every test of the classification module (the worktree was removed after the runs); a standalone runner on main645d4fe14a20,a9779ef3c193andea57360912edand on the published jars of 10.6.0, 10.5.2, 10.0.0, 9.12.3, 9.0.0, 8.11.4, 8.0.0, 7.7.3, 7.0.0 and 6.6.6; the independent tests of the finder, verifiers, an adjudication, a credibility audit and a tiebreak check. JDK OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/classification/src/java/org/apache/lucene/classification/utils/NearestFuzzyQuery.java:48 (class javadoc 'Simplification of FuzzyLikeThisQuery, to be used in the context of KNN classification'), :140 (corpusNumDocs = reader.numDocs()), :155 (df = reader.docFreq(startTerm)), :157-161 (int totalVariantDocFreqs), :187 (score = edit^2 * idf), :198-200 (idf = log((docCount+1)/(docFreq+1)) + 1), :248 and :256 (new BoostQuery(tq, st.score))lucene/classification/src/java/org/apache/lucene/classification/KNearestFuzzyClassifier.java:46-48 (javadoc 'based on NearestFuzzyQuery', @lucene.experimental), :137-147 (knnSearch builds and searches the NearestFuzzyQuery)lucene/core/src/java/org/apache/lucene/search/BoostQuery.java:39-42 (negative or non-finite boost -> IllegalArgumentException 'boost must be a positive float')lucene/core/src/java/org/apache/lucene/index/IndexReader.java:401-408 (docFreq 'does not take into account deleted documents that have not yet been merged away')lucene/sandbox/src/java/org/apache/lucene/sandbox/queries/FuzzyLikeThisQuery.java:204 (same corpusNumDocs = reader.numDocs() line; sandbox, out of scope, not executed)
- The finding in 30 seconds
lucene/classification/src/java/org/apache/lucene/classification/utils/NearestFuzzyQuery.java:48 (at 645d4fe14a20) (class javadoc), :58 (MAX_NUM_TERMS = 300), :140 (numDocs), :155 (docFreq), :173-178 (variant average), :187 (score), :198-200 (idf), :217-264 (rewrite; BoostQuery at :248, :256)lucene/classification/src/java/org/apache/lucene/classification/KNearestFuzzyClassifier.java:45-50 (at 645d4fe14a20) (javadoc, @lucene.experimental), :105-133 (assignClass, getClasses), :135-148 (knnSearch)lucene/core/src/java/org/apache/lucene/search/BoostQuery.java:38-44; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/IndexReader.java:292-305 (numDocs, maxDoc), :401-408 (docFreq javadoc)lucene/core/src/java/org/apache/lucene/search/FuzzyTermsEnum.java:250-257 (edit boost 1 - ed/minTermLength); BoostQuery.java:40 (Float.compare(boost, 0f) < 0 also rejects -0.0)
- Who is affected
lucene/core/src/java/org/apache/lucene/index/SoftDeletesRetentionMergePolicy.java:40-44 (at 645d4fe14a20) (purpose; @lucene.experimental); lucene/core/src/java/org/apache/lucene/index/TieredMergePolicy.java:82, :120-124, :138-141 (deletesPctAllowed: default 20, at most 50)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/IndexReader.java:401-408; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/similarities/TFIDFSimilarity.java:350-370; lucene/queries/src/java/org/apache/lucene/queries/mlt/MoreLikeThis.java:634-660lucene/MIGRATE.md:1368-1375 (at 645d4fe14a20)lucene/highlighter/src/java/org/apache/lucene/search/highlight/QueryTermExtractor.java:74; (at 645d4fe14a20) WeightedSpanTermExtractor.java:549lucene/classification/src/java/org/apache/lucene/classification/Classifier.java:31; (at 645d4fe14a20) lucene/classification/src/test/org/apache/lucene/classification/ClassificationTestBase.java:231-232, :243, :259-260Lucene main 645d4fe14a20 build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/RenderJavadocPlugin.java:502 (the @lucene.experimental tag text)
- Suggested fix
lucene/sandbox/src/java/org/apache/lucene/sandbox/queries/FuzzyLikeThisQuery.java:204 (at 645d4fe14a20)lucene/queries/src/java/org/apache/lucene/queries/mlt/MoreLikeThis.java:634-637; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/Terms.java:117-121; lucene/core/src/java/org/apache/lucene/index/MultiTerms.java:68-93
- History
lucene/CHANGES.txt:6636 (at 645d4fe14a20) (LUCENE-7996), :8020 (LUCENE-7838)
- TestNearestFuzzyQueryDeletedDocs.java (JUnit for Lucene's build):
repro/LFV-393/src/org/apache/lucene/classification/utils/TestNearestFuzzyQueryDeletedDocs.java(60 lines)
Made in parallel with this page: a summary card (PNG)(what the user does, the two counts, the idf inside rewrite(), the arithmetic, the threshold, where it happens on main and 10.6.0, and a fix sketch), built from facts checked against the code, the minimal repro and executed probe output.
assets/LFV-393/bug.png(404 KB)