BooleanPerceptronClassifier gives each term of the text field a weight, starting at its total term frequency, and keeps the weights in an FST that assignClass sums per token. An FST must be built from its keys in sorted byte order.
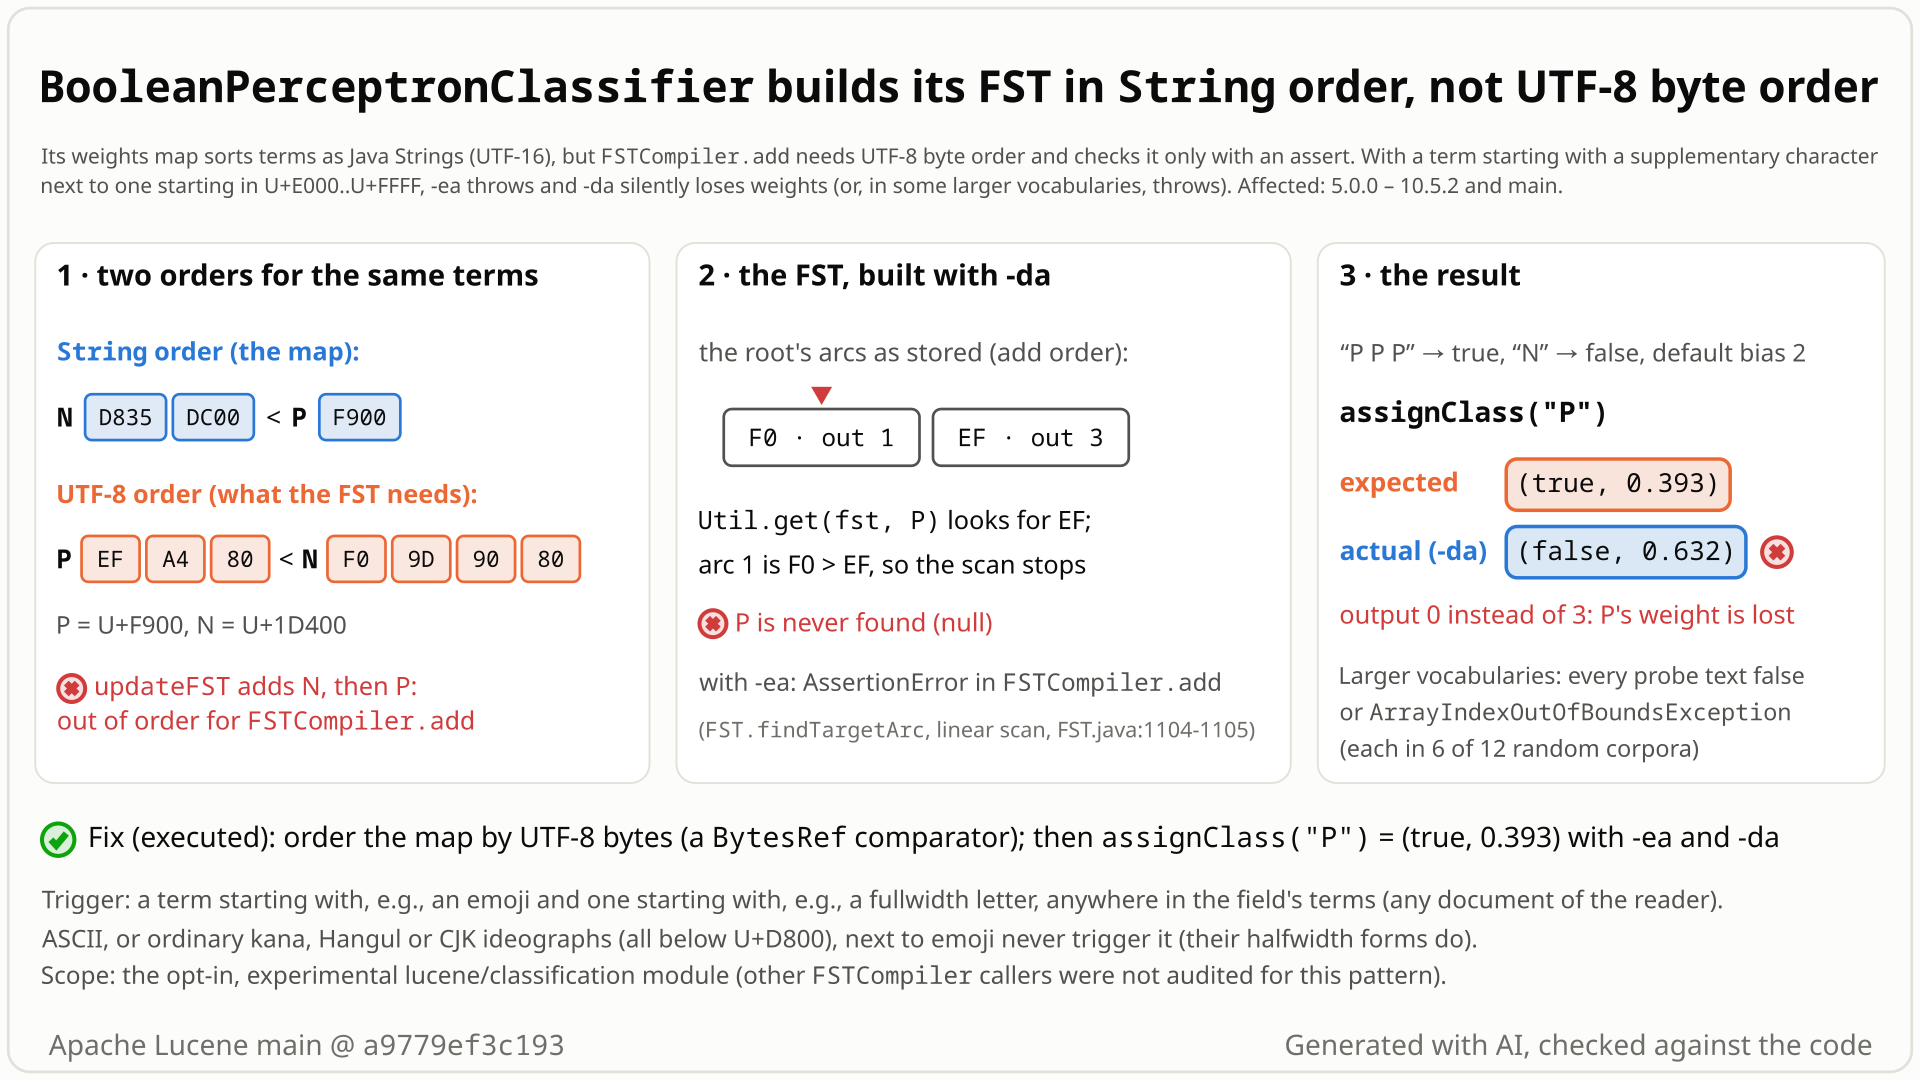
- Index "P P P" labelled true and "N" labelled false, with P = "sale" ("sale" in fullwidth letters) and N = "🎉". Train
BooleanPerceptronClassifierwith the default bias, the average term frequency: (3 + 1) / 2 = 2. - You expect
assignClass("sale")= (true, 0.393): its weight is its term frequency, 3, and 3 >= 2. Plain "sale"/"party", or katakana "セール" next to "🎉", give exactly that. - Inside, the classifier sorts the words as Java Strings: "🎉" (UTF-16
D83C DF89) comes before "sale" (FF53 ...). The FST needs UTF-8 byte order, where "sale" (EF BD 93 ...) comes before "🎉" (F0 9F 8E 89). It gets them the wrong way round. - With assertions off you get (false, 0.632), and no error: the FST no longer finds "sale", so its weight counts as 0. With assertions on, the constructor throws
AssertionError: inputs are added out of order. - One such document anywhere in the index is enough, even unlabelled. In 12 synthetic random 300-document indexes with one added, 6 then classified every probe text false and 6 failed training with
ArrayIndexOutOfBoundsException.
Direct users of the experimental BooleanPerceptronClassifier whose text field mixes the two groups: a word starting with an emoji (or another character above U+FFFF) and a word starting with a fullwidth or halfwidth form, compatibility ideograph, ligature, private-use character or U+FFFD. No setting is needed; one document anywhere in the index suffices.
Mechanism, terms and numbers987 words
BooleanPerceptronClassifier (the experimental lucene/classification module) keeps one weight per indexed term in an FST. It stages the weights in a ConcurrentSkipListMap<String, Double>, whose order is Java String order (UTF-16 code units), and adds the keys' UTF-8 bytes to a BYTE1 FSTCompiler in that order. FSTCompiler.add requires byte order and checks it only with an assert. The two orders disagree exactly when two terms first differ at a character where one is supplementary (most emoji, CJK Extension B, mathematical letters) and the other is in U+E000..U+FFFF (fullwidth and halfwidth forms, CJK compatibility ideographs, presentation forms and ligatures, private use, U+FFFD). Then the public constructor throws AssertionError with assertions on; with assertions off it silently builds an FST from out-of-order input whose affected weights read back as missing. Trained on "sale sale sale" -> true and "🎉" -> false with the default bias 2, assignClass("sale") returns (false, 0.632) instead of (true, 0.393). In larger term sets one such document, labelled or not, made every tested probe text classify false or made training throw ArrayIndexOutOfBoundsException. Every release checked from 5.0.0 to 10.5.2, and main, is affected. An index vocabulary of only ASCII, or of emoji next to ordinary CJK, kana or Hangul, cannot trigger it. Keying the map by the terms' bytes (BytesRef) fixes it; the repro and the whole classification test suite pass with that change.
BooleanPerceptronClassifier(lucene/classification,@lucene.experimental): a perceptron that assignstrueorfalseto a text. Its javadoc: the weights "are calculated using TermsEnum#totalTermFreq ... and then a corresponding FST is used for class assignment" (BooleanPerceptronClassifier.java:50-56).assignClass(text)sums the FST weights of the text's tokens and answersoutput >= bias, with score1 - exp(-|bias - output| / bias)(:222-240). The default bias is the average total term frequency (:99-105).- FST and
FSTCompiler: Lucene's compact sorted map from byte strings to outputs.FSTCompiler.addmust receive each key "sorted after the previous one according to IntsRef#compareTo" (FSTCompiler.java:840-847), which for a BYTE1 FST of UTF-8 terms is unsigned byte order. The order is checked only by anassert(:854-855). - UTF-16 vs UTF-8 order: Java's
String.compareTocompares UTF-16 code units. A supplementary character is a surrogate pairD800-DBFF DC00-DFFF, which sorts belowE000-FFFF. In UTF-8 a supplementary character starts with byteF0-F4and a character in U+E000..U+FFFF withEE-EF, so byte order puts them the other way round. Below U+D800 the two orders agree.
- The constructor reads every term of the text field over the whole reader from a
TermsEnum(:90,:119-123), which yields them in UTF-8 byte order. - It decodes each with
utf8ToString()intoSortedMap<String, Double> weights = new ConcurrentSkipListMap<>()(:117, "TODO : remove this map as soon as we have a writable FST"), which re-sorts them in UTF-16 order. updateFSTiterates the map, re-encodes each key withcopyCharsand callsfstCompiler.addon a BYTE1 compiler in map order (:208-220), after the initial fill (:124) and after misclassified training documents (:203-205).- With assertions on,
FSTCompiler.addthrowsAssertionError: inputs are added out of orderfrom the public constructor. With assertions off, the FST is built anyway. In the two-document case the root keeps its two arcs as a plain list in the orderF0,EF; a list lookup gives up at the first label larger than the one it seeks (FST.java:1093-1107), so "sale" (EF ...) reads back as missing. With "sale" labelled true, training misclassifies its document andupdateWeightswrites 0 for it (:200); with the labels swapped, both training documents already get their labelled class, no update happens, and only the score of "sale" is wrong. - In larger term sets, nodes stored with fixed-length arcs take their label range from the first and last label (
FSTCompiler.java:540) and their presence bits from label differences (:798, checked only by asserts at:797and:808-810), so a node can be read misaligned: every weight in it unreadable, orArrayIndexOutOfBoundsException. This explanation was checked for one root shape (14 of 14 cases); deeper nodes and other layouts were not mapped. - A Z3 model of both orders (strings of up to 2 Unicode scalars) confirms they disagree exactly when, at the first differing character, one is supplementary and the other in U+E000..U+FFFF (6 of 6 checks as expected).
The numbers (training set "P P P" -> true, "N" -> false; default bias 2; expected (true, 0.393) for P and (false, 0.393) for N)
| P / N | assertions on | assertions off |
|---|---|---|
| "sale" / "party" | as expected | as expected |
| "セール" (katakana, below U+D800) / "🎉" | as expected | as expected |
| "sale" (fullwidth) / "🎉" | AssertionError ... lastInput=[f0 9f 8e 89] vs input=[ef bd 93 ...] | P = (false, 0.632) |
| "🎉" / "sale" | the same AssertionError | N = (false, 0.632): class right, score wrong |
One document can switch the model off (assertions off). A dense ASCII training set of 8 labelled documents plus one unlabelled document "😀 a": all 8 probe texts classify false with output 0 ("apple bonus cash" is true, output 6, when that document is "一 丁" instead). The same when the document is deleted before training and not yet merged away, because the FST keys come from the term dictionary. Over 12 random 300-document corpora plus one such document: 6 throw ArrayIndexOutOfBoundsException during training (where a message is recorded: Index -1 out of bounds for length 32768), and in the other 6 every probe text gets output 0. With the fix none of this happens. These corpora are synthetic (300 labelled documents from a 400-word vocabulary of ASCII letters and digits, plus one fixed unlabelled trigger document): they show that the damage depends on the layout of the whole term set, not how often it happens in natural-language indexes.
Exposure and likelihood355 words
- Who is exposed. Applications that train
BooleanPerceptronClassifier(opt-inlucene/classificationmodule,@lucene.experimental). Nothing in Lucene constructs the class outside its tests, and no major downstream product is known to use it (Solr's classification update processor offers only k-NN and naive Bayes). - Default vs opt-in. Inside the module no non-default setting is needed: the public constructor with batchSize 1 and the default bias, a whitespace analyzer, two documents. The stock
StandardAnalyzerkeeps the trigger characters (an independent check ran it with halfwidth katakana "セール" and fullwidth "sale" next to "🎉"). Width folding removes only some trigger forms:CJKWidthFilterfolds fullwidth ASCII (U+FF01..U+FF5E) and halfwidth katakana (U+FF65..U+FF9F) only; NFKC also folds ligatures such as U+FB01, compatibility ideographs such as U+F900 and halfwidth Hangul, but leaves private-use characters and U+FFFD unchanged. Neither was run as a classifier test, and other analyzers were not tested. - What text hits it. Informal or mixed-script text: an emoji word next to a word starting with a fullwidth Latin letter or halfwidth katakana (common in Japanese text), a CJK compatibility ideograph, a ligature from PDF extraction (such as U+FB01 "fi") or U+FFFD. An ASCII-only vocabulary never triggers it, and neither does emoji next to ordinary CJK ideographs, kana or Hangul (all below U+D800). Once a trigger pair is in the index, though, ASCII texts can lose their weights too.
- Who triggers it. Any document in the reader: labelled or not, and a deleted one until a merge drops its terms. The training query and the class-field clause do not restrict the FST's terms; they select the documents used for updates and, as scoring clauses, may also reorder them (the separate LFV-684). Text passed to
assignClasscannot trigger it. - Silent in production. With assertions off there is no error: weights are lost, in some term sets all of them. With assertions on (how Lucene's own tests run), the public constructor throws an internal
AssertionError. - Deterministic. Every training run on such an index is affected, again on every retraining while the terms stay in the index.
- How likely. Plausible but quiet: nobody has reported it since 5.0.0 (2015), which fits a small user base.
The test shows that BooleanPerceptronClassifier adds its weights to the FST in Java String (UTF-16) order, not the UTF-8 byte order FSTCompiler requires, when one term starts with U+F900 and another with U+1D400 (corpus 'P P P' -> true, 'N' -> false).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.classification;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.StringField;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestBooleanPerceptronUtf8Order extends LuceneTestCase {

  public void testHighBmpAndSupplementaryTerms() throws Exception {
    String p = "\uF900";
    String n = new String(Character.toChars(0x1D400));
    FieldType ft = new FieldType(TextField.TYPE_STORED);
    ft.setStoreTermVectors(true);
    try (Directory dir = new ByteBuffersDirectory();
        Analyzer analyzer = new StandardAnalyzer()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
        String[][] docs = {{p + " " + p + " " + p, "true"}, {n, "false"}};
        for (String[] d : docs) {
          Document doc = new Document();
          doc.add(new Field("text", d[0], ft));
          doc.add(new StringField("cls", d[1], Field.Store.YES));
          w.addDocument(doc);
        }
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        BooleanPerceptronClassifier classifier =
            new BooleanPerceptronClassifier(reader, analyzer, null, 1, null, "cls", "text");
        // expected true, as with ASCII terms; actual: FSTCompiler AssertionError (-ea), false (-da)
        assertEquals(Boolean.TRUE, classifier.assignClass(p).assignedClass());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-395/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/classification/build/libs/lucene-classification-$V.jar
CP=$CP:$LUCENE/lucene/grouping/build/libs/lucene-grouping-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.classification.TestBooleanPerceptronUtf8Order
- Expected vs actual
- Expected assignClass(U+F900) = true, as with ASCII terms; actual: with
-eathe constructor throwsAssertionError: inputs are added out of order lastInput=[f0 9d 90 80] vs input=[ef a4 80], with-daexpected:<true> but was:<false>.
More files, environment, full output44 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: inputs are added out of order lastInput=[f0 9d 90 80] vs input=[ef a4 80]
       org.apache.lucene.util.fst.FSTCompiler.add(FSTCompiler.java:855)
       org.apache.lucene.classification.BooleanPerceptronClassifier.updateFST(BooleanPerceptronClassifier.java:216)
       org.apache.lucene.classification.BooleanPerceptronClassifier.<init>(BooleanPerceptronClassifier.java:124)
org.apache.lucene.classification.TestBooleanPerceptronUtf8Order.testHighBmpAndSupplementaryTerms(TestBooleanPerceptronUtf8Order.java:53)FSTCompiler.addrequires its keys in sorted byte order; the classifier's own private code breaks that precondition.- Lucene's FST package docs warn that sorting keys with
String.compareTo"is not correct and can lead to exceptions while building the FST". SynonymMapalready sorts its FST keys by code point for exactly this case, and nothing limits the classifier to ASCII.
The full argument218 words
- The callee's contract.
FSTCompiler.add: "The provided input must be sorted after the previous one according to IntsRef#compareTo" (FSTCompiler.java:840-847). The caller that breaks it is the classifier's own privateupdateFST, fed from its own private map; the user passes an ordinary index. - Lucene documents this exact pitfall.
util/fst/package-info.java:38-40: keys "must be provided to Builder in Unicode code point (UTF8 or UTF32) sorted order. Note that sorting by Java's String.compareTo, which is UTF16 sorted order, is not correct and can lead to exceptions while building the FST". The warning came from #10095 / LUCENE-9053 (2019), where a user's own code hit the same assertion. - Lucene's own practice.
SynonymMap.Builder.compareCodePoints: "Compares by Unicode code point, which matches the UTF-8 byte order the FST requires" (SynonymMap.java:196-197, used at:261), withTestSynonymMap.testSupplementaryCharsSortAfterHighBMPfor exactly this boundary (#16834). - The class's own documentation describes the weights and the FST lookup (
BooleanPerceptronClassifier.java:50-56). No javadoc, package doc, CHANGES or MIGRATE entry limits the text to ASCII or to characters below U+D800. - Why the tests never caught it. Every perceptron test uses ASCII text: a fixed English sample and
TestUtil.randomSimpleString(a..z) (ClassificationTestBase.java:146,:254-267). - History. The String-ordered map is in the class's first commit (2013,
TreeMap<String,Double>); the LUCENE-4818 discussion never mentions character order or Unicode.
The devil's-advocate check224 words
The strongest "works as designed" case (a refute-lens review by another model family rated it moderate; the independent reproducer, an intended-lens review and the devil's advocate rated it weak or rejected it): the class is @lucene.experimental and promises no accuracy; FSTCompiler puts the sorted-input duty on its caller; all upstream perceptron tests are ASCII; the map is a self-described temporary hack ("TODO : remove this map ..."); and "renaming tokens must not change the class", the first oracle used, is not a documented contract.
Why it fails: experimental status allows API changes, not a constructor that throws an internal assertion or drops weights it was given for ordinary indexed Unicode. The caller that owns the precondition is this class. The repro's expected values follow from the documented weighting and the code's own formulas, not from renaming, and the controls show the same corpus gives them when the two orders agree. ASCII-only tests are a coverage gap, not a statement of intent. Eleven years without a report fits a small user base, not a design choice; width folding is an analyzer option the class never asks for, and it does not fold every trigger; LUCENE-9053 was resolved Invalid because the out-of-order caller there was the user's own code, while here it is Lucene's own class. Verdict: a defect (adjudication: confirmed, high; every executed check: real).
Recommended Key the weights by the terms' bytes (BytesRef)
Key the weights map by the terms' UTF-8 bytes (SortedMap<BytesRef, Double>) instead of Strings, so the FST gets its keys in the order it needs, with no decoding or re-encoding (+8/-12 lines). The repro, the whole classification test suite (47 tests, assertions on and off) and the module's format and lint checks pass.
    // TODO : remove this map as soon as we have a writable FST
    // keyed by the terms' UTF-8 bytes: BytesRef order is the input order FSTCompiler requires
    SortedMap<BytesRef, Double> weights = new ConcurrentSkipListMap<>();
    ...
      weights.put(BytesRef.deepCopyOf(textTerm), (double) termsEnum.totalTermFreq());
    ...
    for (Map.Entry<BytesRef, Double> entry : weights.entrySet()) {
      fstCompiler.add(Util.toIntsRef(entry.getKey(), scratchInts), entry.getValue().longValue());
    }
All options and trade-offs4 options · 655 words
Two fixes were run, the recommended one through gradle. A one-line alternative orders the existing String map by UTF-8 bytes. Separately, FSTCompiler.add could check its input order for real instead of only with an assert; that is a core-wide change with its own cost question. Workaround until a fix ships: fold width in the text field's analyzer. CJKWidthFilter folds only fullwidth ASCII (U+FF01..U+FF5E) and halfwidth katakana (U+FF65..U+FF9F); NFKC also folds ligatures (U+FB01), compatibility ideographs (U+F900) and halfwidth Hangul. Private-use characters and U+FFFD stay under both, so neither removes every trigger (not run as a classifier test).
The map becomes SortedMap<BytesRef, Double>, filled with BytesRef.deepCopyOf(term) in the constructor and in updateWeights; updateFST adds Util.toIntsRef(entry.getKey(), scratchInts) directly; BytesRefBuilder, utf8ToString() and copyChars go. +8/-12 in BooleanPerceptronClassifier.java.
    // TODO : remove this map as soon as we have a writable FST
    // keyed by the terms' UTF-8 bytes: BytesRef order is the input order FSTCompiler requires
    SortedMap<BytesRef, Double> weights = new ConcurrentSkipListMap<>();
    ...
      weights.put(BytesRef.deepCopyOf(textTerm), (double) termsEnum.totalTermFreq());
    ...
    for (Map.Entry<BytesRef, Double> entry : weights.entrySet()) {
      fstCompiler.add(Util.toIntsRef(entry.getKey(), scratchInts), entry.getValue().longValue());
    }
Trade-offs
BytesRef.compareTois unsigned byte order, which is the order of the BYTE1 labels, so the order is right by construction; no allocation per comparison.- Unchanged behaviour on text that is not affected today (ASCII, or every character below U+D800): the orders agree there and the keys are the same bytes.
- Cost: a
BytesRefdeep copy wherever the code builds aStringtoday: once per dictionary term in the constructor, and once per term of each misclassified training document inupdateWeights; not benchmarked. - It edits the same
updateWeightslines as the fix for the sibling batchSize bug (LFV-680); the two are compatible in intent, but neither diff applies on top of the other, so combining them needs a small manual merge (not run).
What the checks validated
- Scratch worktree of main
a9779ef3c193with the diff applied, gradle: the new test passes 4 of 4, and the whole:lucene:classification:testpasses with assertions on and off (13 suites, 47 tests including the new 4, 0 failures, 1@Monstertest skipped). :lucene:classification:check -x testpasses (checkGoogleJavaFormat,ecjLintMain,ecjLintTestandforbiddenApisMainran;forbiddenApisTestwas up to date from the stock run, where it ran and passed on the same test sources).- Standalone runner with the fixed class shadowed: this doc's test (on and off), the independent reproducer's test (4 of 4, on and off) and the follow-up probe (unlabelled and deleted documents: trigger equals control; 12 random corpora: 0 throw, 0 changed) pass.
The finder's change: new ConcurrentSkipListMap<>((a, b) -> new BytesRef(a).compareTo(new BytesRef(b))). +3/-1.
    SortedMap<String, Double> weights =
        new ConcurrentSkipListMap<>((a, b) -> new BytesRef(a).compareTo(new BytesRef(b)));
Trade-offs
Smallest diff. It encodes both Strings into new byte arrays on every comparison (about V log V encodings to fill a map of V terms); cost not measured.
What the checks validated
This doc's test with the class shadowed: 4 of 4 pass, on and off. Earlier: every verifier's test and the 42 upstream classification tests pass with it.
Compare by code point, as SynonymMap.Builder.compareCodePoints does; code point order equals UTF-8 byte order.
Trade-offs
No allocation, but that helper is package-private in analysis-common, which lucene/classification's main code does not depend on (only its tests do), so its 16 lines would be copied. Not run.
Replace the assert with a check that throws, so this silent corruption, and any other caller's, becomes an exception.
Trade-offs
Core-wide; changes a hot path for every FST build, and Lucene asks that robustness changes not slow hot paths. Cost not measured; other FSTCompiler callers were not audited for this pattern. Not a fix for this class on its own. Not run.
An application that uses this classifier as a spam, abuse or routing filter on user text could have the filter silently switched off by one such document, but that depends on its own use of this experimental API.
While reading the classifier to model its scoring for an SMT solver, an AI tool saw a String-sorted map feeding the FST. A Z3 model of UTF-16 versus UTF-8 order then pinned the exact trigger, and a public-API JUnit test reproduced it; other AI tools then reproduced, reviewed and judged it independently.
The method in full144 words
Method: non-formal (the hunt's tier for finds made by reading code; a model characterised the trigger afterwards). A hunt unit (classification), 2026-10-26, stock main jars.
- The unit's primary method was transcribing the classifiers' score pipelines into an SMT model. While reading
BooleanPerceptronClassifierfor it, the finder noticed theString-keyed sorted map feeding a BYTE1FSTCompiler. - A Z3 QF_BV model of UTF-16 versus UTF-8 lexicographic order over strings of up to 2 Unicode scalars then characterised the trigger: a satisfiable witness that the orders differ, two unsatisfiable implications showing they differ exactly when, at the first differing scalar, one is supplementary and the other in U+E000..U+FFFF, and three vacuity probes (6 of 6 as expected).
- A public-API JUnit test reproduced it on the stock jars of main, 10.5.2 and 9.12.3, and the finder's fix made it pass along with the upstream classification tests.
No prior report found (2026-10-26): 90 tool queries plus manual searches of GitHub, all 47 JIRA classification issues, the mailing lists and the web. Closest: LUCENE-9053 (#10095), where a user's own code hit the same FST assertion with String-sorted keys; it led to today's FST package warning and never mentions the classifier.
Searches4 searches
No issue, PR, commit, JIRA entry, list thread, downstream issue or web page reports that BooleanPerceptronClassifier (or anything in lucene/classification) builds its FST in String order, or an assertion failure, lost weight or wrong class from it on non-ASCII text. Not fixed: upstream main on 2026-10-27 (f7bcc0abd816) and branch_10x have the same file as a9779ef3c193, last changed by 942065cc3e7 (2024-09-10, a record conversion); no open PR touches it.
Closest items, none a report of this bug: #10095 / LUCENE-9053 (2019, resolved Invalid): a user's own code fed String-sorted keys (a supplementary math letter before U+FB01/U+FB02 ligature words) to the FST builder and hit the same assertion; it led to the package-info warning (2020) and never mentions the classifier or Lucene's own FST callers. If "the same pitfall anywhere" counted as a prior report, this is the item that would make the bug known; under the hunt's rule (same root cause and fix site) it is related, not the same bug. #16834 (merged 2026-10-13) moved the UTF-16-as-UTF-8 comparator into SynonymMap.Builder.compareCodePoints and does not touch the classifier. #12416 (open): the same assertion text from an unsorted dictionary in the KNN demo. #5883 (LUCENE-4818, origin of the code), #6761 (LUCENE-5699, score normalization) and #7911 (LUCENE-6853, the only other bug report on this classifier): nothing on term order or non-ASCII text.
Gaps: GitHub's search rate limit was reached (one manual query re-run after a back-off); one web page could not be fetched; downstream coverage is issue and PR text only; private security reports are invisible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene; cross-repository) | 2026-10-26 | scripted prior-report search: 34 issue/PR, 6 commit and 4 downstream queries; manual: open PRs by class name and module path, open FSTCompiler PRs and their files, the commits API for both files | no report; 19 hits assessed in total, none the same bug |
| JIRA archive | 2026-10-26 | 8 tool queries; all 47 issues of component modules/classification (the perceptron ones read in full); the error phrase, "UTF16 sorted order", String.compareTo + FST | LUCENE-9053 (related, a user's own code); nothing on the classifier |
| Mailing lists | 2026-10-26 | 32 tool queries over dev@, java-user@, issues@ and commits@; manual perceptron and error-phrase queries | only JIRA notifications and commits for known issues; the error phrase matches only LUCENE-9053 and #12416 |
| Web and downstream | 2026-10-26 | 6 web queries; issue and PR text of three downstream projects | the general Java pitfall only (the LUCENE-9053 strings); 0 downstream hits |
Present since the class was added (LUCENE-4818, 2013, 05940e34ab8) and first released in 5.0.0. A history test fails on every release run, 5.0.0 to 10.5.2, and on main; 4.10.4 and earlier lack the class. Not fixed upstream.
Versions tested7 rows
Introduced by 05940e34ab8 (trunk, 2013-09-03, @tteofili, svn r1519590, "LUCNE-4818 - added boolean perceptron classifier"; issue LUCENE-4818, now #5883; no pull request). The first version already keyed the weights in a TreeMap<String,Double> and added their copyChars UTF-8 encodings in that order to a BYTE1 FST Builder whose order check was an assert. It reached a release through the branch_5x backport 55594bad9b0 (LUCENE-5944, 2014-09-18): first release 5.0.0 (2015-02-19). The JIRA fix version of LUCENE-4818 says 6.0, but the 5.0.0 jar contains the class.
Later changes. 4641ee4c5d2 (LUCENE-5699, 2014, "normalized score for boolean perceptron classifier"): as far as the map goes, it only swapped TreeMap for ConcurrentSkipListMap, with the same String order; the same commit introduced today's score formula 1 - exp(-|threshold - output| / threshold), which gives the repro's 0.393 and 0.632. So it did not introduce the bug. The assertions-off symptom changed: 5.x throws NullPointerException in updateWeights (training aborts); 8b2e0d937d5 (LUCENE-6479, 6.0.0) made a missing weight reset silently to 0; from 7.0.0 (cbad533d7a4, LUCENE-6853, default bias) both trigger cases give a wrong class or score. All 98 release tags of the history clone from 5.0.0 to 8.8.1 and from 9.0.0 to 10.5.2 have the String-keyed map, copyChars and BYTE1; the clone has no tags for 8.8.2 and 8.9.0 to 8.11.3, so those were not read (8.11.4 was executed).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test: 2 of 4 fail (both trigger cases; gradle and the standalone runner, assertions on and off); the finder's repro re-run: still reproduces |
| 10.5.2, 9.12.3 | affected | this doc's test: the same 2 of 4 failures and messages, assertions on and off |
| 7.7.3, 8.11.4 | affected | history test: assertions on, FST assertion; off, P = (false, 0.632) and N's score 0.632 |
| 6.6.6 | one case masked | assertions on, FST assertion; off, the fullwidth-positive case gives a wrong class, while the swapped case happens to match (the lost weight is reset to 0, which training would reach anyway) |
| 5.0.0, 5.5.5 | throws | assertions on, FST assertion in Builder.add; off, NullPointerException in updateWeights, training aborts (the swapped case is masked) |
| 4.10.4 and earlier | no API | the class does not exist (the repro does not compile) |
| main + the fix | not affected | every repro passes; the whole classification test suite and the module's checks pass |
An independent reproducer and a devil's advocate each reproduced it with their own tests, and an adjudication re-ran the reproducer's test at a new seed; reviews by another model family read the code and agreed on the root cause. A fourth audit kept it, and this doc's own test reproduced it through gradle and validated the fix.
Checks and verdicts418 words
Every executed check on main ran on the stock jars with assertions on and off (the recommended fix's gradle runs applied the diff in a scratch worktree; the standalone fix runs shadowed the class). The reviews by the other model family (OpenAI GPT-5.6) could only read code: they could not run their own tests, so separate runs re-ran the finder's repro for them. Those checks ran on main ea57360912ed, whose classification module and FST code are identical to a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API JUnit fails on main (on and off), 10.5.2 and 9.12.3; the fix passes, and so do the 42 upstream classification tests. |
| review, refute lens | not real (low), procedural | Another model family, reading only: its own test could not run, so the review voted not real on procedure only, while it agreed on the root cause, called the inputs legal and rated the intended case moderate. A separate re-run of the repro failed. |
| Independent reproducer | real | Own JUnit with exact expected values fails 2 of 4 on main (on and off, and in 25 random-seed iterations of its 4 tests (100 runs) per mode), 10.5.2, 9.12.3 and 8.11.4; controls pass; the fix passes. |
| Cross-model review, intended lens | real (medium) | Reading only; intended-behaviour argument weak; cites the FST package warning and SynonymMap's comparator. A separate run re-ran the repro on main, 10.5.2 and 9.12.3: fails. |
| Devil's advocate | real (high on mechanism, modest impact) | Built the strongest "works as designed" case and rejected it; own JUnit with StandardAnalyzer fails on main, 10.5.2 and 9.12.3; the CJK-ideograph-plus-emoji control passes; the fix passes. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's test at seed C0FFEE (2 of 4 fail, on and off; controls pass); no duplicate. |
| Follow-up | affected 5.0.0 to main | History test on 7 releases and main; reach probe: one unlabelled or deleted document switches the model off; 12 random corpora: 6 throw, 6 all false; the fix removes every effect. |
| registry re-runs and audit | keep | The independent reproduction's test re-run with new seeds: 2 of 4 fail on and off, passes with the fix; code read confirms the String-ordered map fed to a BYTE1 FSTCompiler. |
| this doc's runs | reproduced, fix validated | The doc's 4-test JUnit fails 2 of 4 through gradle (on and off) and the standalone runner on main, 10.5.2 and 9.12.3; with the recommended fix it, the whole classification test suite and :lucene:classification:check -x test pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 426 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,686 words
- Registry title
- BooleanPerceptronClassifier adds its term weights to its FST in Java String (UTF-16) order instead of the UTF-8 byte order the FST requires, so a text field with a term starting with a supplementary character (such as an emoji) and a term starting with a character in U+E000..U+FFFF (such as a fullwidth letter) makes training throw AssertionError with -ea and, with -da, silently loses term weights (in some term layouts all of them) or throws ArrayIndexOutOfBoundsException (released since 5.0.0)
- Area
- classification / BooleanPerceptronClassifier (weights FST)
- Priority
- Medium, rank 188: The experimental perceptron classifier deterministically loses term weights under -da on mixed-script text such as emoji next to fullwidth forms, released since 5.0.0, but it needs a specific script mix.
- Impact class
- silent wrong results
- Impact note
- Applications that use the opt-in, @lucene.experimental lucene/classification module and train BooleanPerceptronClassifier on an index whose text field holds at least one term starting with a supplementary character (most emoji, CJK Extension B ideographs, mathematical alphanumerics) and one starting with a character in U+E000..U+FFFF (fullwidth or halfwidth forms, CJK compatibility ideographs, ligatures and other presentation forms, private use, U+FFFD) are hit on every training run: with -ea the public constructor throws AssertionError, and with -da (production) the FST is built from out-of-order input, so the affected terms' weights are silently lost and, depending on the byte layout of the whole term set, every weight can become unreadable (every text classified false) or training throws ArrayIndexOutOfBoundsException (each in 6 of 12 random 300-document corpora in the follow-up probe); one such document anywhere in the reader suffices (labelled or not, or deleted but not yet merged away), no non-default setting or scale is needed, and every release from 5.0.0 to 10.5.2 is affected.
- Summary
- You index two documents, 'P P P' labelled true and 'N' labelled false, where P is U+F900 (a CJK compatibility ideograph) and N is U+1D400 (mathematical bold capital A), train BooleanPerceptronClassifier with the default bias (the average term frequency, here 2), and expect assignClass(P) = (true, 0.393), which is what the same corpus gives with ASCII terms or with ordinary CJK ideographs. Instead the constructor throws AssertionError 'inputs are added out of order lastInput=[f0 9d 90 80] vs input=[ef a4 80]' with -ea, and with -da assignClass(P) returns (false, 0.632) because P's weight can no longer be found in the FST. The classifier keeps its weights in a ConcurrentSkipListMap<String, Double>, whose String order (UTF-16 code units) puts U+1D400 (D835 DC00) before U+F900, and adds their UTF-8 encodings in that order to an FSTCompiler that requires UTF-8 byte order (EF before F0) and checks it only with an assert.
- Introduced
- 05940e34ab8c2a961fef8498b39d592f4099e8e2 (trunk, svn r1519590, message 'LUCNE-4818 - added boolean perceptron classifier'; issue LUCENE-4818 'Create a boolean perceptron classifier', migrated as GitHub issue #5883; by GitHub tteofili; svn era, no pull request): the first version of the class already keyed the weights in a TreeMap<String,Double> (String order) and added their copyChars UTF-8 encodings in that order to a BYTE1 FST Builder whose input order is checked only by an assert [read: git log --follow, git blame and git log -S in the full-history clone]. It reached a release through the branch_5x bulk backport 55594bad9b0 (LUCENE-5944, svn r1626055, same pattern) [read]. 4641ee4c5d2 (LUCENE-5699, 2014-11-12) only swapped TreeMap for ConcurrentSkipListMap with the same String order, so the hunt's record's attribution to LUCENE-5699 is wrong [read]. [exec: 4.10.4 has no such class (compile error); 5.0.0 fails] (2013-09-03 (05940e34ab8, trunk); 2014-09-18 (branch_5x backport 55594bad9b0); first release 5.0.0, tagged 2015-02-19)
- First affected version
- 5.0.0 [exec] (the 5.0.0 classification jar contains BooleanPerceptronClassifier and the history test fails there: -ea AssertionError in Builder.add, -da NullPointerException in updateWeights; 4.10.4 and earlier lack the class [exec: compile error 'cannot find symbol']; the JIRA fix version of LUCENE-4818 says 6.0, but the class shipped in 5.0.0)
- Affected versions
- Every release from 5.0.0 to 10.5.2 and main ea57360912ed; not fixed upstream (upstream main cf398bfb142c and branch_10x, 2026-10-26: BooleanPerceptronClassifier.java last changed by 942065cc3e7, 2024-09-10, a record conversion; no open PR touches it). [exec] follow-up history test (corpus 'P P P' -> true, 'N' -> false with P = U+F900 and N = U+1D400 in both roles; oracle = the ASCII control trained in the same run; the low-BMP control U+4E00 + U+1D400 passes everywhere): 5.0.0 and 5.5.5 fail with -ea (AssertionError in Builder.add) and -da (NullPointerException in updateWeights, training aborts; the swapped case is masked); 6.6.6 fails with -ea and -da (wrong class; the swapped case is masked); 7.7.3, 8.11.4, 9.12.3, 10.5.2 and main fail both trigger cases with -ea (AssertionError) and -da (wrong class or score); main with the fix shadowed passes with -ea and -da. The finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's JUnits fail on main (-ea and -da), and the finder's, the independent reproduction's and the intended-behaviour check's on 10.5.2 and 9.12.3 (the independent reproduction also on 8.11.4). [read] all 98 release tags of the history clone from 5.0.0 to 8.8.1 and from 9.0.0 to 10.5.2 have the String-keyed sorted map, copyChars and INPUT_TYPE.BYTE1 in this class; 8.8.2-8.11.x are not tagged in the clone (8.11.4 was executed). Not affected: 4.10.4 and earlier (class absent). All runs used JDK 25; the failing path (Java collection order plus FST construction) does not depend on the JDK.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by Z3
- Upstream and prior reports
- none found (2026-10-26, read-only, the prior-report record verdict new: a scripted prior-report search with 90 queries (34 GitHub issue and PR, 6 commit, 4 downstream, 32 mailing-list over dev@, java-user@, issues@ and commits@, 8 JIRA, 6 web; 784 distinct hits); manual JIRA queries including all 47 issues of component modules/classification (the perceptron ones read in full); manual mailing-list and GitHub searches (open PRs by class name and by module path, open FSTCompiler PRs with their changed files, cross-repository issues, the commits API for both files); 19 hits assessed, none the same bug; the finder's, the independent reproduction's and the intended-behaviour check's searches agree). Closest, not this bug: #10095 / LUCENE-9053 (2019, resolved Invalid): a user's own code fed String-sorted keys to the FST builder and hit the same assertion; it led to the util/fst/package-info.java warning that String.compareTo (UTF-16) order 'is not correct and can lead to exceptions while building the FST' (8147e491ce3, 2020) and never mentions the classifier or Lucene's own FST callers; #12416 (open): the same assertion text from unsorted input in the KNN demo; #16834 (merged 2026-10-13): moved the UTF-16-as-UTF-8 comparator into SynonymMap.Builder.compareCodePoints and does not touch the classifier; #5883 / LUCENE-4818 (origin of the code), #6761 / LUCENE-5699 (TreeMap to ConcurrentSkipListMap) and #7911 / LUCENE-6853 (threshold sensitivity, the only other bug report on this classifier) say nothing on term order or non-ASCII text. Not fixed upstream (main cf398bfb142c and branch_10x: file unchanged since 942065cc3e7, 2024-09-10); no open PR touches the file. Gaps: GitHub search was shared and partly rate-limited (one manual query re-run after back-off), one web page could not be fetched, downstream coverage is issue and PR text only, private security@ reports are invisible.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 9.12.3 release jars (this doc's test). The follow-up's history test ran on 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.12.3, 10.5.2 and mainea57360912ed. The earlier checks ran on mainea57360912ed, whose classification module and FST code are identical toa9779ef3c193; the main refresh re-ran the finder's repro ona9779ef3c193(still reproduces). The fix was validated in the scratch worktree: the new test, the whole:lucene:classification:test(assertions on and off) and:lucene:classification:check -x test.
- Finding record
lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:50-57 (class javadoc: weights from TermsEnum#totalTermFreq, an FST used for class assignment, @lucene.experimental), :65 (private FST field), :90 (MultiTerms.getTerms over the whole reader), :99-105 (default bias = average total term frequency), :116-124 (String-keyed ConcurrentSkipListMap filled from the TermsEnum, then updateFST), :196 (Util.get in updateWeights), :203-205 (updateFST after a batch), :208-220 (updateFST: copyChars, BYTE1 FSTCompiler.add in map order), :230 (Util.get in assignClass)lucene/core/src/java/org/apache/lucene/util/fst/FSTCompiler.java:840-846 (add javadoc: 'must be sorted after the previous one according to IntsRef#compareTo'), :854-855 (assert-only order check)lucene/core/src/java/org/apache/lucene/util/fst/package-info.java:38-40 ('sorting by Java's String.compareTo, which is UTF16 sorted order, is not correct and can lead to exceptions while building the FST')lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymMap.java:196-197, 261 (compareCodePoints 'matches the UTF-8 byte order the FST requires') and src/test/.../synonym/TestSynonymMap.java:46 (testSupplementaryCharsSortAfterHighBMP)
- The finding in 30 seconds
lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:50-57, :90, :99-105, :116-124, :196-205, :208-220, :222-240lucene/core/src/java/org/apache/lucene/util/fst/FSTCompiler.java:540, :601-606, :797, :798, :808-810, :840-847, :854-855; lucene/core/src/java/org/apache/lucene/util/fst/FST.java:1093-1107
- Who is affected
grep -rl BooleanPerceptronClassifier lucene/*/src/java (only the class itself), 2026-10-27lucene/analysis/common/src/java/org/apache/lucene/analysis/cjk/CJKWidthFilter.java:67-75 (folded ranges); NFKC of U+FB01, U+F900, U+FFA1, U+E000, U+FFFD checked with Python unicodedata, 2026-10-27lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:130-140 (scoring MUST clauses; training iterates scoreDocs)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/util/fst/FSTCompiler.java:840-847, :854-855lucene/core/src/java/org/apache/lucene/util/fst/package-info.java:38-40lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymMap.java:196-197, :261; lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/TestSynonymMap.java:46-52lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:50-57, :116lucene/classification/src/test/org/apache/lucene/classification/ClassificationTestBase.java:146, :236-267; TestBooleanPerceptronClassifier.java:37, :52, :68, :82 (grep for literal non-ASCII: only DocumentClassificationTestBase.java, not used by the perceptron; utils/TestDataSplitter.java:70 generates random Unicode for the data splitter, not a classifier)
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymMap.java:196-212SECURITY.md line 46 (robustness changes must not slow hot paths)
- TestBooleanPerceptronUtf8Order.java (JUnit test):
repro/LFV-395/src/org/apache/lucene/classification/TestBooleanPerceptronUtf8Order.java(59 lines)
A summary still, made in parallel with this doc from an executed trace on main a9779ef3c193 (with the fix as control); the PNG is the summary. The diagram uses the independent reproducer's characters (U+F900, U+1D400), the steps use fullwidth "sale" and "🎉"; both pairs are executed and give the same class and score. This caption and alt text follow the summary still as re-rendered after the diagram check (2026-10-27).
assets/LFV-395/bug.png(426 KB)