WeightedSpanTermExtractor rewrites a phrase as new SpanNearQuery(clauses, slop + positionGaps, inorder), a plain int sum (WeightedSpanTermExtractor.java:161-162; MultiPhraseQuery :232). It is exact only while slop is at most Integer.MAX_VALUE minus the holes. Above that it wraps to about Integer.MIN_VALUE, and since a span match must be at most slop wide, none is found.
- A phrase's slop is how far its words may move and still match:
"quick fox"~1matchesquick brown fox. SlopInteger.MAX_VALUEis the usual way to say "any distance"; Lucene's own core tests use it. - A hole is a position with no word. An analyzer that removes stop words keeps their positions, so
"quick the fox"becomesquickat position 0 andfoxat position 2, printed"quick ? fox". - The classic
HighlighterwithQueryScorerdoes not ask the search what matched. It rewrites the phrase as a span query, runs it on the text and marks the words of each match, adding one to the slop per hole so the hole fits.
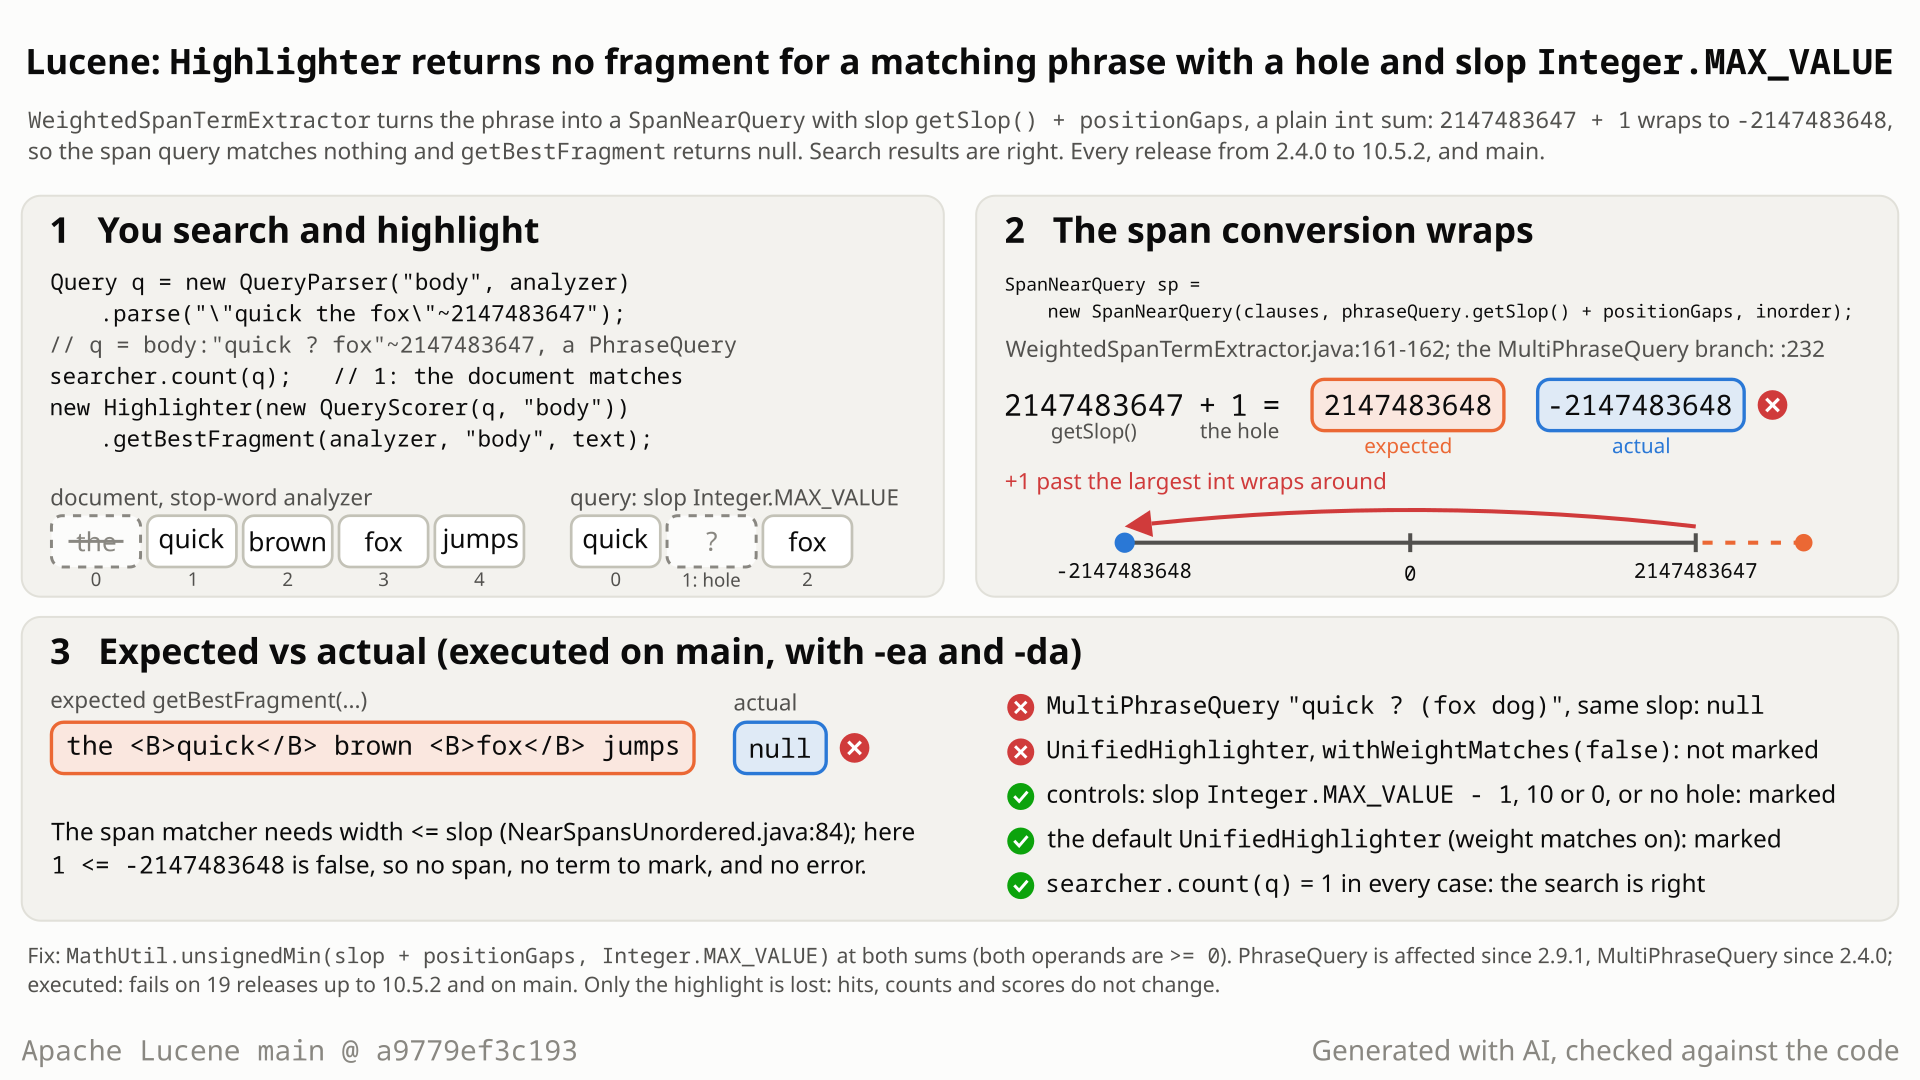
- You index
the quick brown fox jumpswith an analyzer that removes stop words. A user types"quick the fox"~3000000000; the classic QueryParser makes it"quick ? fox"~2147483647(the removed "the" leaves a hole, and the parser caps the huge slop atInteger.MAX_VALUE), and the search finds the document. - You highlight the hit with
HighlighterandQueryScorerand expectthe <B>quick</B> brown <B>fox</B> jumps, which you get with slop 2147483646 or with the same phrase without the hole. - To find the words, the Highlighter rewrites the phrase as a span query with slop + holes = 2147483647 + 1. In
intarithmetic that is -2147483648. - A span match may be at most slop positions wide, so with -2147483648 none qualifies:
getBestFragmentreturnsnull, with no error, assertions on or off. The UnifiedHighlighter with weight matches off returnsthe quick brown fox jumpswith nothing marked.
Applications that highlight with the classic Highlighter and QueryScorer, or with the UnifiedHighlighter with weight matches, multi-term or passage-relevancy handling off and strict phrases on, for a phrase with a hole and slop + holes > Integer.MAX_VALUE. Search hits stay correct; ordinary slops and the default UnifiedHighlighter are fine.
Mechanism, terms and numbers624 words
The classic Highlighter with its span-aware QueryScorer finds the words to mark by rewriting each phrase query as a SpanNearQuery and running it on the document's text. A phrase can have holes, positions with no word, most often a stop word that the analyzer removed; the rewrite widens the slop by one per hole, slop + positionGaps, as a plain int sum. When the slop is Integer.MAX_VALUE, the usual way to say "any distance" and what the classic QueryParser makes of any huge typed ~N, one hole is enough: the sum wraps to -2147483648, the span query matches nothing, and the Highlighter returns null for a document the query matched. MultiPhraseQuery has the same sum, and the UnifiedHighlighter reaches it when weight matches are off while strict phrase highlighting stays on (the default). Search hits, counts and scores are correct; only highlighting is lost, silently. Present since 2.4.0 (2008); a two-line saturating fix passes the whole highlighter test suite.
- Classic Highlighter:
org.apache.lucene.search.highlight.Highlighter. With aQueryScorerit "converts appropriate Querys to SpanQuerys and attempts to score only those terms that participated in generating the 'hit'" (QueryScorer.java:33-37). The conversion isWeightedSpanTermExtractor.extract. - Position hole (
positionGaps): the number of positions between the phrase's first and last term that hold no term:positions[last] - positions[0] - positions.length + 1for aPhraseQuery(WeightedSpanTermExtractor.java:150-156), the empty positions up to the last one for aMultiPhraseQuery(:215-224). - Span slop: a
SpanNearQueryaccepts a match only if its width is at most the slop:matchWidth <= allowedSlop(ordered,NearSpansOrdered.java:67,:89) or(maxEndPosition - start - totalSpanLength) <= allowedSlop(unordered,NearSpansUnordered.java:84). Its constructor stores any slop (SpanNearQuery.java:119-131).
- The PhraseQuery branch builds
new SpanNearQuery(clauses, phraseQuery.getSlop() + positionGaps, inorder)(WeightedSpanTermExtractor.java:161-162); the MultiPhraseQuery branchnew SpanNearQuery(clauses, slop + positionGaps, inorder)(:232). Both are plainintadditions. - For
slop >= 0andpositionGaps >= 0the sum is exact and non-negative whenslop <= Integer.MAX_VALUE - positionGaps(proved with Z3, checked with cvc5), and above that it wraps to aboutInteger.MIN_VALUE(the converse, checked separately with cvc5 and Z3). - A wrap needs a slop of at least 1, so the conversion is not in order and the unordered check decides. For the reproduced phrase the width is
4 - 1 - 2 = 1(one unmatched position, "brown"), and1 <= -2147483648is false, so no span matches, no weighted term is extracted, andgetBestFragmentreturnsnull, its documented value for "no terms found" (Highlighter.java:71,:92). An independent check captured the converted query:spanNear([body:quick, body:fox], -2147483648, false). - The UnifiedHighlighter's
PhraseHelperbuilds an anonymous subclass of the same extractor ("WSTE will convert to an equivalent SpanQuery",PhraseHelper.java:106-109). It is used when weight matches are not applied and strict phrase highlighting is on (UnifiedHighlighter.java:1219-1236: noPhraseHelperwith weight matches,:1221-1223, or with strict phrases off,:1225-1235); it then returns the passage with nothing marked. WithwithHighlightPhrasesStrictly(false)the passage is marked correctly (executed).
| query (one hole unless noted) | slop | classic Highlighter | UnifiedHighlighter, weight matches off |
|---|---|---|---|
"quick ? fox" (control) | 2147483646 | the <B>quick</B> brown <B>fox</B> jumps | the <b>quick</b> brown <b>fox</b> jumps |
"quick fox", no hole (control) | 2147483647 | the <B>quick</B> brown <B>fox</B> jumps | not run |
"quick ? fox", typed ~3000000000 | 2147483647 | null | the quick brown fox jumps |
"quick ? (fox dog)", MultiPhraseQuery | 2147483647 | null | not run |
Main a9779ef3c193, assertions on and off; the same on the 10.5.2 and 10.0.0 jars (assertions on). Two holes fail from slop Integer.MAX_VALUE - 1 (credibility audit). The default UnifiedHighlighter (weight matches on) marks the <b>quick brown fox</b> jumps for the same query.
Exposure and likelihood331 words
- Who is hit. The classic
HighlighterwithQueryScorer, its span-aware scorer, which LUCENE-1685 made the default in 2.9.0. The UnifiedHighlighter when weight matches are not applied and strict phrase highlighting stays on (the default):withWeightMatches(false), and alsowithHandleMultiTermQuery(false)orwithPassageRelevancyOverSpeed(false), because weight matches are applied only when multi-term handling, strict phrases, passage relevancy and weight matches are all on (UnifiedHighlighter.java:518-528; all on by default,:108-111). All three settings were executed on main;withWeightMatches(false)also on 10.5.2 and 10.0.0.withHighlightPhrasesStrictly(false)uses noPhraseHelper(:1225-1235) and highlights correctly (executed). - Which queries. A
PhraseQueryorMultiPhraseQuerywith at least one hole and a slop aboveInteger.MAX_VALUEminus the number of holes (slop + holes > Integer.MAX_VALUE). In practice:- slop
Integer.MAX_VALUEas "any distance": Lucene's core tests use it (TestPhraseQuery.java:339,TestSimpleSearchEquivalence.java:173), a 2004 java-user@ answer recommends"red fox"~2147483647, andQueryParser.setPhraseSlop(Integer.MAX_VALUE)applies it to every phrase (executed); - a huge typed
~N: the classic parser reads it with(int) Float.parseFloat(QueryParserBase.java:802), so any typed slop from 2147483584 up becomesInteger.MAX_VALUE.
- slop
- Where holes come from. Analyzers that remove stop words keep their positions (
EnglishAnalyzer()usesENGLISH_STOP_WORDS_SET; the no-argumentStandardAnalyzerremoves none,StandardAnalyzer.java:51-53), and phrases built with explicit positions. - Effect. Silent and deterministic: a hit with no snippet (
null) or an unmarked passage. One document is enough; no index size or setting matters. Not affected: hits, counts and scores; ordinary slops, even in the millions, on phrases with ordinary position gaps (a phrase built with very far apart explicit positions has a huge gap count, so a small slop could cross the same bound; not run); the default UnifiedHighlighter. - Not assessed. The FastVectorHighlighter, the MatchHighlighter, and UnifiedHighlighter offset sources other than re-analysis of the stored text.
- Why nobody noticed. For one hole the cliff is one value wide (slop 2147483646 works), and nobody has reported it in the 17 years since it reached the default scorer.
The test shows that Highlighter with QueryScorer returns no fragment for a matching PhraseQuery with a position hole and slop Integer.MAX_VALUE, because WeightedSpanTermExtractor's int sum slop + positionGaps wraps negative.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.highlight;

import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.PhraseQuery;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestHighlighterPhraseSlopOverflow extends LuceneTestCase {

  public void testPhraseQuerySlopMaxValue() throws Exception {
    PhraseQuery q =
        new PhraseQuery.Builder()
            .add(new Term("f", "quick"), 0)
            .add(new Term("f", "fox"), 2)
            .setSlop(Integer.MAX_VALUE)
            .build();
    String text = "the quick brown fox jumps";
    String fragment =
        new Highlighter(new QueryScorer(q, "f")).getBestFragment(new StandardAnalyzer(), "f", text);
    // the phrase matches; expected quick and fox marked, actual null (slop + 1 gap wraps negative)
    assertEquals("the <B>quick</B> brown <B>fox</B> jumps", fragment);
  }
}
# in a copy of this finding's repro folder (repro/LFV-397/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/highlighter/build/libs/lucene-highlighter-$V.jar
CP=$CP:$LUCENE/lucene/memory/build/libs/lucene-memory-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.highlight.TestHighlighterPhraseSlopOverflow
- Expected vs actual
- Expected
the <B>quick</B> brown <B>fox</B> jumps; actualnull(expected:<the <B>quick</B> brown <B>fox</B> jumps> but was:<null>), with-eaand-da.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<the <B>quick</B> brown <B>fox</B> jumps> but was:<null>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.highlight.TestHighlighterPhraseSlopOverflow.testPhraseQuerySlopMaxValue(TestHighlighterPhraseSlopOverflow.java:37)PhraseQueryandMultiPhraseQueryaccept any slop of 0 or more; Lucene's core tests use slopInteger.MAX_VALUEas "any distance", and the classic QueryParser produces it from user text.- LUCENE-5503 (5.4.0) fixed the same symptom in this converter as a bug: "a slop that is too low (no highlight)".
- The cliff is arbitrary: slop 2147483646 is highlighted, 2147483647 is not.
The full argument164 words
- The inputs are legal.
PhraseQueryrejects onlyslop < 0(PhraseQuery.java:173-175),MultiPhraseQuery.Builder.setSloponlys < 0(MultiPhraseQuery.java:95-102). ThegetSlopjavadoc defines slop as "the maximum edit distance for a document to match", with no bound (PhraseQuery.java:268-283); so doesQueryParserBase.setPhraseSlop(:205-210). - Precedent in this converter.
CHANGES.txt, 5.4.0 Bug Fixes: "LUCENE-5503: When Highlighter's WeightedSpanTermExtractor converts a PhraseQuery to an equivalent SpanQuery, it would sometimes use a slop that is too low (no highlight) or determine inOrder wrong." (lucene/CHANGES.txt:10042-10045). That commit (c5b49baa592, #6566) wrote today'sgetSlop() + positionGaps; its thread never mentions overflow. - Tests state the goal.
TestHighlighterPhrase.testStopWords("shows the need to sum the increments in WeightedSpanTermExtractor",:273-274) andtestInOrderWithStopWords(:308) assert that a matching phrase with stop-word holes is highlighted. - The terms are found. The query matches the document, and the default UnifiedHighlighter marks the same text; only the converted slop is wrong. The classic Highlighter is not deprecated.
The devil's-advocate check230 words
The strongest case for "intended": slop Integer.MAX_VALUE is a degenerate sentinel; huge slops are known to be costly for highlighting, and in LUCENE-5182 (#6246, the FastVectorHighlighter's run time at high slop) @rmuir suggested "maybe just a Math.min and a default of Integer.MAX_VALUE. Sure its still trappy but at least its an improvement"; QueryScorer only "attempts" to score the terms that produced the hit, and getBestFragment documents null for "no terms found".
Why it fails: that thread is about run time in another highlighter; the Math.min there was a suggested user-configurable cap (not adopted: the committed fix terminates phrase searches early once a maximum phrase window is exceeded), it bounds work, and nothing in it makes dropping highlights intended. Accepting a slop through the public API does not by itself promise a fragment from every highlighter path; the case rests on the combination: nothing documents an upper bound on slop, core tests use Integer.MAX_VALUE as "any distance", Lucene's own parser produces the value, the converter's purpose is an equivalent span query, here the terms are found, nothing gets slower, and the answer flips at an arbitrary point (slop 2147483646 works, 2147483647 does not); LUCENE-5503 treated "converted slop too low, no highlight" as a bug. The independent reproducer, the cross-model review (it rated the intended argument's strength "weak"), the devil's advocate, the adjudication and the audit all concluded it is not intended.
Recommended Saturate slop + positionGaps at Integer.MAX_VALUE (two lines)
Saturate both sums: MathUtil.unsignedMin(slop + positionGaps, Integer.MAX_VALUE) in WeightedSpanTermExtractor. Both operands are 0 or more, so a wrapped sum becomes Integer.MAX_VALUE and every other slop stays as it is. The repro then passes, and so does the whole highlighter test task (727 tests), assertions on and off.
// PhraseQuery branch (WeightedSpanTermExtractor.java:161-162)
// both are >= 0: saturate at Integer.MAX_VALUE instead of wrapping to a negative slop
int slop = MathUtil.unsignedMin(phraseQuery.getSlop() + positionGaps, Integer.MAX_VALUE);
SpanNearQuery sp = new SpanNearQuery(clauses, slop, inorder);

// MultiPhraseQuery branch (:232)
SpanNearQuery sp =
    new SpanNearQuery(
        clauses, MathUtil.unsignedMin(slop + positionGaps, Integer.MAX_VALUE), inorder);
All options and trade-offs4 options · 456 words
One fix was built and validated through gradle; a long-arithmetic variant was checked with the repro runner. The other options are listed for the discussion with maintainers.
Saturate slop + positionGaps at Integer.MAX_VALUE (two lines) (validated by the checks) (recommended)
Both operands are >= 0, so a wrapped sum is negative as a signed int and above Integer.MAX_VALUE as an unsigned one; MathUtil.unsignedMin(sum, Integer.MAX_VALUE) (MathUtil.java:196-199) returns the exact sum when it fits and Integer.MAX_VALUE when it wrapped. Core uses the same idiom (MaxScoreBulkScorer.java:424: MathUtil.unsignedMin(Integer.MAX_VALUE, windowMin + minWindowSize); BitSetDocIdStream.java:34). Z3 proves the result is at least the phrase's own slop and never negative.
// PhraseQuery branch (WeightedSpanTermExtractor.java:161-162)
// both are >= 0: saturate at Integer.MAX_VALUE instead of wrapping to a negative slop
int slop = MathUtil.unsignedMin(phraseQuery.getSlop() + positionGaps, Integer.MAX_VALUE);
SpanNearQuery sp = new SpanNearQuery(clauses, slop, inorder);

// MultiPhraseQuery branch (:232)
SpanNearQuery sp =
    new SpanNearQuery(
        clauses, MathUtil.unsignedMin(slop + positionGaps, Integer.MAX_VALUE), inorder);
Trade-offs
- None found for valid inputs: every sum that fits is unchanged, and a saturated slop means "any distance", which is what such a slop asks for. One unsigned compare per converted phrase.
- A PR could add the paste-ready test (or a shorter one) next to
TestHighlighterPhrase.testStopWords, and apply the same line to sandboxPayloadSpanUtil.java:152, which has the same sum (not run).
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle: the paste-ready test fails 3 of 5 on stock main, assertions on and off, and 30 of 50 with 10 random seeds per method; with the patch the whole:lucene:highlighter:testtask passes, 35 classes, 727 tests, 0 failures, assertions on and off (counting the 5 paste-ready tests), and 50 of 50 with 10 random seeds per method. ecjLintMain,ecjLintTestandcheckGoogleJavaFormatfor the module pass.- The UnifiedHighlighter settings probe passes 4 of 4 with the patch; the hunt's equivalent patch passed every earlier repro and the highlighter, facet and grouping suites plus two core merge-policy test classes (1,097 tests, with five other fixes).
(int) Math.min((long) slop + positionGaps, Integer.MAX_VALUE) at both sites: the same values, and perhaps easier to read.
Trade-offs
Checked only with the repro runner (the paste-ready test passes 5 of 5 with it shadowed on main); the module suite was not run and the sketch is not formatted.
Throw on overflow.
Trade-offs
Turns a missing highlight into an ArithmeticException for a query that searches fine. Not run.
Check slop >= 0 in the constructor.
Trade-offs
Makes the failure loud but does not restore the highlight, and could change behaviour for callers that rely on small negative slops (stored unchecked today; none identified). Not run.
Search servers that pass user-typed ~N through the classic QueryParser to the classic Highlighter, or that turn off the UnifiedHighlighter's weight matches with strict phrases on, inherit the missing highlights.
Semi-formal. A scan of the compiled highlighter code for int additions of two variables passed on as a slop flagged the two sums, and a public-API JUnit on the stock jars failed. Z3 then found a wrapping input, proved the exact safe bound and proved that the saturating fix is never stricter than the phrase (cvc5 agrees).
The method in full148 words
- Signal. A hunt unit on int overflow at scale ran a bytecode inventory of
intarithmetic (a JDK 25java.lang.classfileabstract interpreter flaggingiaddof two non-constant ints passed as an argument). Its rows forWeightedSpanTermExtractor.extractat lines 162 and 232 were reviewed while triaging highlighter parameters that users set to sentinel values. - Witness. A 3-test public-API JUnit (
MemoryIndex, explicit positions) failed 2 of 3 on main with assertions on and off, and on 10.5.2 and 9.12.3; the slopInteger.MAX_VALUE - 1control passed. - Proof obligations. Then Z3 bit-vector checks: WS1 gave a counterexample (the sum wraps negative); WS1s proved the sum is exact and non-negative when
slop <= Integer.MAX_VALUE - positionGaps(the converse, that it wraps above, was checked separately with cvc5 and Z3); WS2 proved thatMathUtil.unsignedMin(slop + positionGaps, Integer.MAX_VALUE)is never below the phrase's slop and never negative. cvc5 agrees on all three.
No prior report found: 164 logged queries over GitHub issues, PRs and commits, the JIRA archive, the mailing lists, downstream trackers and the web, plus the changed files of all 410 open PRs (2026-10-26), and a re-check on 2026-10-28. Nearest: #6566 (LUCENE-5503), which wrote today's line and fixed another "slop too low" cause. Not fixed upstream.
Searches4 searches
No report of this defect was found. The nearest items wrote or touched the formula, or show the same symptom for another cause; none mentions overflow. Upstream main 645d4fe14a20 (2026-10-28) still has both sums, and so does the 10.6 release branch (4ae946e5a9b9, read, not executed).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), JIRA archive (LUCENE, SOLR), mailing lists (dev@, java-user@, issues@, commits@), downstream trackers, web | 2026-10-26 | 164 logged queries by the finder, verifiers and the follow-up (scripted prior-report search runs, manual and GraphQL searches, JQL, list archive queries, code searches for positionGaps), and the file's path history on main, branch_10x, branch_10_6 and branch_9x | only related items: #6566 / LUCENE-5503 (wrote today's PhraseQuery line; another cause), #3078 / LUCENE-2003 and #1869 / LUCENE-794 (introduced the sums), #5568 / LUCENE-4502 (same symptom with slop 0), #8631 / LUCENE-7580 (other slop arithmetic, never merged) |
| Open PRs | 2026-10-26 | the changed-file lists of all 410 open apache/lucene PRs | #12295 and #16851 touch the files but not the sums |
| GitHub issues and PRs (apache/lucene), re-check | 2026-10-28 | WeightedSpanTermExtractor slop, highlighter slop Integer.MAX_VALUE, positionGaps overflow, highlighter phrase slop overflow; upstream file history | 0 results each; the file last changed upstream on 2026-05-14 (#16056, unrelated); both sums unchanged on main |
| Downstream code | 2026-10-26 | code searches in downstream search engines | the same unchecked sum in two downstream CustomUnifiedHighlighter copies (MultiPhrasePrefixQuery); no report; read only |
Present since the converter was written: the MultiPhraseQuery sum in 2.4.0 (2008, LUCENE-794), the PhraseQuery sum in 2.9.1 (2009, LUCENE-2003), rewritten as today's line in 5.4.0 (LUCENE-5503) with the overflow kept. Executed on 19 releases from 2.4.0 to 10.5.2 and on main: all affected; never fixed.
Versions tested8 rows
Introduced in two steps, both before GitHub. 35c7eb36dfb (2008-04-29, LUCENE-794, now #1869, committed by @markharwood from a patch series by @markrmiller) created WeightedSpanTermExtractor with the MultiPhraseQuery sum in today's form, first released in 2.4.0 through the opt-in SpanScorer; LUCENE-1685 made the span-aware scorer the default QueryScorer in 2.9.0. LUCENE-2003 (#3078; 6cd7218a428 on the 2.9 branch, 9609a2cb4db on trunk, 2009-10-23, @markrmiller) added the holes to the PhraseQuery slop as slop += largestInc, first released in 2.9.1 and 3.0.0. LUCENE-5503 (#6566; c5b49baa592, 4c40ad78c94 on branch_5x, 2015-09-13, patch by @tballison, committed by @dsmiley) rewrote it as today's getSlop() + positionGaps, keeping the overflow and moving its threshold. Later commits to the method (LUCENE-1285, LUCENE-7231 and LUCENE-7417, fixes for other cases; LUCENE-9570, a reformat) keep both sums. Commit isolation was executed at each step.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | paste-ready test fails 3 of 5 (gradle and runner, assertions on and off) |
| 10.5.2, 10.0.0 | affected | the same (this doc's test, runner) |
| 9.12.3 | affected | the finder's JUnit fails 2 of 3, assertions on and off |
| 5.4.0 to 9.0.0 | ports | PhraseQuery and MultiPhraseQuery at slop Integer.MAX_VALUE get no highlight; slop Integer.MAX_VALUE - 1 works |
| 2.9.1 to 5.3.2 | ports | the same, and the PhraseQuery already fails at slop Integer.MAX_VALUE - 1 (slop += largestInc) |
| 2.4.0, 2.4.1, 2.9.0 | MultiPhraseQuery only | MultiPhraseQuery at slop Integer.MAX_VALUE gets no highlight; PhraseQuery fine (2.4.x only through the opt-in SpanScorer) |
| 2.3.2 | no code | the converter does not exist |
| main + the fix | not affected | all 5 pass; whole highlighter test task passes (727 tests) |
The finder, an independent reproducer, an intended-behaviour devil's advocate and a credibility audit each ran their own test; the adjudication re-ran the reproducer's test with new seeds; all said real. A reading-only review by another model family (OpenAI GPT-5.6) said real (medium); its refute-lens review gave no verdict. This doc re-ran the repro and the fix through gradle.
Checks and verdicts315 words
Every check except the cross-model review executed code on main (the hunt's checks on ea57360912ed, this doc's on a9779ef3c193).
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | 3-test public-API JUnit: 2 of 3 fail on main (assertions on and off), 10.5.2 and 9.12.3; the slop Integer.MAX_VALUE - 1 control passes; Z3 counterexample and proofs. |
| cross-model review, refute lens (OpenAI GPT-5.6) | no verdict | 5 attempts ended in reviewer-side failures; not a refutation. |
| independent reproducer | real | Own 8-test JUnit with an indexed document and a stop-word analyzer: 5 of 8 fail on main (on and off), 10.5.2 and 9.12.3; captured spanNear(..., -2147483648, false); found the UnifiedHighlighter path; 3 controls pass. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | Works-as-designed argument weak; root cause agreed; separate tests fail on main (Highlighter 1 of 2, UnifiedHighlighter 2 of 4) and pass with the fix. |
| intended-behaviour devil's advocate | real; not intended | Reached it from user query text through the classic QueryParser and setPhraseSlop(Integer.MAX_VALUE): 2 of 3 fail on main, 10.5.2 and 9.12.3; built the strongest intended case and showed why it fails; rated the impact low. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's test with new seeds: 5 of 8 fail, on and off; 8 of 8 pass with the fix. |
| credibility audit | keep | Own 5-test JUnit: 2 of 5 fail (typed slop; two holes at slop Integer.MAX_VALUE - 1), controls pass; 5 of 5 with the fix; committer view: real, easy to accept, low severity. |
| this doc | repro and fix confirmed | Paste-ready test fails 3 of 5 through gradle (on and off; 30 of 50 with random seeds) and the runner (main, 10.5.2, 10.0.0); with the fix the whole highlighter test task passes (727 tests), on and off; a probe found two more UnifiedHighlighter settings that reach the bug. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 497 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,578 words
- Registry title
- Highlighter with the default QueryScorer returns no fragment for a matching PhraseQuery or MultiPhraseQuery that has a position hole (for example a removed stop word) and a slop within the number of holes of Integer.MAX_VALUE: WeightedSpanTermExtractor converts it to a SpanNearQuery with the plain int sum slop + positionGaps, which wraps to about Integer.MIN_VALUE, so the span query matches nothing
- Area
- highlighter / original Highlighter, QueryScorer and WeightedSpanTermExtractor (phrase-to-span conversion)
- Priority
- Low, rank 540: The original Highlighter silently misses highlights only for a slop near Integer.MAX_VALUE plus a position hole, while search results stay correct, so it is a boundary-value, output-only row next to the phrase int-overflow bug LFV-196.
- Impact class
- silent wrong results
- Impact note
- Applications on any release from 2.4.0 through 10.6.0 (10.6.0 by reading) or main that highlight with the original Highlighter and the default QueryScorer (or with the UnifiedHighlighter with weight matches turned off, through PhraseHelper) a PhraseQuery or MultiPhraseQuery whose slop is above Integer.MAX_VALUE minus the phrase's number of position holes, in practice slop Integer.MAX_VALUE used as 'any distance' or a huge user-typed ~N that the classic QueryParser saturates to it, on a phrase with a removed stop word or an explicit gap, get no highlight for a document the query matches (getBestFragment returns null; the UnifiedHighlighter path returns the passage unmarked); search hits, counts and scores are correct, there is no exception with -ea or -da, no index size or setting is needed, ordinary slops are safe, and the default UnifiedHighlighter (weight matches on) is not affected.
- Summary
- You analyse 'the quick brown fox jumps' with a stop-word analyzer, search for the phrase "quick the fox" with slop Integer.MAX_VALUE (for example from the user text "quick the fox"~3000000000, which the classic QueryParser turns into "quick ? fox"~2147483647; the query matches), and highlight the hit with Highlighter and QueryScorer, expecting 'the <B>quick</B> brown <B>fox</B> jumps', which slop Integer.MAX_VALUE - 1 or the same phrase without the hole gives. Instead getBestFragment returns null, with no error: WeightedSpanTermExtractor rewrites the phrase as new SpanNearQuery(clauses, slop + positionGaps, inorder) with a plain int sum, the removed stop word counts as one position gap, the sum wraps to -2147483648, and a span query with that slop accepts no match, so no term is marked. MultiPhraseQuery has the same sum, and the UnifiedHighlighter with weight matches turned off reaches it through PhraseHelper and returns the passage with no highlight.
- Introduced
- 35c7eb36dfb (svn r652164, LUCENE-794 'Commit of LUCENE-794 patch - adding phrase/span query support to highlighter', committed by GitHub markharwood, patch series by GitHub markrmiller; JIRA LUCENE-794 is now apache/lucene#1869; 2008-04-29) created WeightedSpanTermExtractor with the MultiPhraseQuery sum 'slop + positionGaps' already in today's form (main :232); LUCENE-2003 (#3078, 6cd7218a428 on the 2.9 branch and 9609a2cb4db on trunk, 2009-10-23, committed by GitHub markrmiller) added the PhraseQuery sum as 'slop += largestInc'; LUCENE-5503 (#6566, c5b49baa592 on trunk and 4c40ad78c94 on branch_5x, 2015-09-13, patch by GitHub tballison, committed by GitHub dsmiley) rewrote it as today's 'getSlop() + positionGaps' (main :161-162) and kept the overflow, only moving its threshold [read: git log -S/-G and blame in the full-history clone; later commits LUCENE-1285, LUCENE-7231, LUCENE-7417 and LUCENE-9570 only refactor or reformat the lines] [exec: commit isolation: 2.9.0 against 2.9.1 flips only the PhraseQuery cases, 2.9.1 with only the LUCENE-2003 hunk reverted highlights them again, 2.4.0 with the MultiPhraseQuery sum saturated passes, and 5.3.2 against 5.4.0 flips the slop Integer.MAX_VALUE - 1 case as the formula change predicts]. Present since the code was written; not a regression; both changes predate GitHub, so there is no pull request (2008-04-29 (35c7eb36dfb, LUCENE-794: MultiPhraseQuery sum); 2009-10-23 (LUCENE-2003: PhraseQuery sum); 2015-09-13 (LUCENE-5503: today's PhraseQuery formula, overflow kept))
- First affected version
- 2.4.0 [exec] (release 2008-10-08): MultiPhraseQuery only, and only through the opt-in SpanScorer; 2.9.0 [exec]: MultiPhraseQuery through the default QueryScorer (LUCENE-1685 made the span-aware scorer the default); 2.9.1 and 3.0.0 [exec]: PhraseQuery too, the common case. 2.3.2 has no such code [exec: the SpanScorer port does not compile there, and its term-based QueryScorer highlights every case]
- Affected versions
- every release from 2.4.0 through 10.6.0 (10.6.0 by reading) and main ea57360912ed; no version has a fix [exec: fails on 19 releases, 2.4.0, 2.4.1 (SpanScorer), 2.9.0, 2.9.1, 3.0.0, 3.6.2, 4.0.0, 4.10.4, 5.3.2, 5.4.0, 5.5.5, 6.0.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2, and on main; releases before 9.12.3 ran public-API main() ports of the same scenario, 9.12.3, 10.5.2 and main also the canonical JUnit; -da gave the same result as -ea wherever both ran (2.4.0, 2.9.0, 2.9.1, 5.3.2, 5.4.0, 9.12.3, 10.5.2, main); controls pass in every affected run. Threshold by era: 2.9.1 to 5.3.x, slop >= Integer.MAX_VALUE - 1 with one hole (slop += largestInc); 5.4.0 on, slop > Integer.MAX_VALUE - positionGaps] [read: all release tags from 2.4.0 on contain 35c7eb36dfb; both sums are unchanged on upstream main cf398bfb142c, branch_10x and branch_10_6, and no open PR changes them]. The UnifiedHighlighter weight-matches-off path (PhraseHelper subclasses WeightedSpanTermExtractor since 6.3.0, read) was executed on main and 10.5.2 only. 10.6.0 (released 2026-10-29) was read at 4ae946e5a9b, not executed. Every run used JDK 25.0.3
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3/cvc5
- Upstream and prior reports
- none found (2026-10-26 by the finder, the independent reproduction, the intended-behaviour check and the follow-up, all read-only; the prior-report record, verdict new: 164 logged queries over apache/lucene issues and PRs, open and closed (the intended-behaviour check's 12 scripted prior-report search queries, the finder's 3, the follow-up's 2 before GitHub's search rate limit ran out, and 34 GraphQL searches), commits and the file's path history on main, branch_10x, branch_10_6 and branch_9x, the file lists of all 410 open PRs, the LUCENE and SOLR JIRA archive, the dev@, java-user@, issues@ and commits@ lists, 21 GraphQL searches over the Elasticsearch, OpenSearch, Solr and old lucene-solr trackers plus code searches, and the web; 19 hits read, none the same bug and none a partial overlap; the independent reproduction's own searches found only #6566). Context, not reports: #6566 (LUCENE-5503, closed, fixed in 5.4.0) wrote today's PhraseQuery line and fixed another 'slop too low (no highlight)' defect in this converter, caused by the gap formula, and its 7 comments never mention overflow; #3078 (LUCENE-2003) and #1869 (LUCENE-794) introduced the gap-to-slop sums, with no overflow discussion; #5568 (LUCENE-4502, open since 2013) has the same symptom with slop 0, where no overflow is possible; #8631 (LUCENE-7580, Won't Fix) noted that slop Integer.MAX_VALUE overflows distance+1 in its own never-merged span-scoring patch, different code. Not fixed upstream: both sums are unchanged on upstream main cf398bfb142c, branch_10x and branch_10_6; the open PRs #12295 and #16851 touch WeightedSpanTermExtractor.java or PhraseHelper.java but not the sums
- Lucene commit tested
- main
a9779ef3c193(gradle in a scratch worktree, assertions on and off and 10 random seeds per test method, plus the standalone JUnit runner); the 10.5.2 and 10.0.0 release jars (this doc's test); 2.4.0 to 9.12.3 (the history runs, public-APImain()ports before 9.12.3); the fix on main (gradle, the whole highlighter test task, assertions on and off, and the module's lint and format checks). The hunt and its checks ran on mainea57360912ed, whose highlighter, spans, query and parser sources equala9779ef3c193.
- Finding record
lucene/highlighter/src/java/org/apache/lucene/search/highlight/WeightedSpanTermExtractor.java:139-164 (at ea57360912ed) (PhraseQuery branch: positionGaps at :150-156, the sum 'phraseQuery.getSlop() + positionGaps' at :161-162), :187-235 (MultiPhraseQuery branch: positionGaps counts empty positions at :215-224, the sum 'slop + positionGaps' at :232)lucene/queries/src/java/org/apache/lucene/queries/spans/SpanNearQuery.java:119-131 (at ea57360912ed) (the constructor does not check slop); NearSpansOrdered.java:67, :89 and NearSpansUnordered.java:84 (a match needs width <= allowedSlop)lucene/highlighter/src/java/org/apache/lucene/search/highlight/Highlighter.java:71, (at ea57360912ed) :92 (getBestFragment returns null 'if no terms found'); lucene/highlighter/src/java/org/apache/lucene/search/highlight/QueryScorer.java:33-37 (class javadoc: converts appropriate Querys to SpanQuerys)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/PhraseHelper.java:105-109 (at ea57360912ed) (anonymous WeightedSpanTermExtractor subclass; 'WSTE will convert to an equivalent SpanQuery'); lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:110 (DEFAULT_ENABLE_WEIGHT_MATCHES = true), :349 (withWeightMatches)lucene/core/src/java/org/apache/lucene/search/PhraseQuery.java:173-174 (at ea57360912ed) (rejects only slop < 0); lucene/core/src/java/org/apache/lucene/search/MultiPhraseQuery.java:95-99 (setSlop rejects only s < 0); lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:798-809 (handleQuotedTerm: (int) Float.parseFloat saturates a typed slop at :802)lucene/core/src/test/org/apache/lucene/search/TestPhraseQuery.java:339 (at ea57360912ed) and TestSimpleSearchEquivalence.java:173 (slop Integer.MAX_VALUE used as infinity); lucene/highlighter/src/test/org/apache/lucene/search/highlight/TestHighlighterPhrase.java:274, :308 (testStopWords, testInOrderWithStopWords); lucene/CHANGES.txt:10026 (LUCENE-5503 under 5.4.0 Bug Fixes)lucene/core/src/java/org/apache/lucene/analysis/standard/StandardAnalyzer.java:51-53 (at ea57360912ed) (the no-argument constructor uses CharArraySet.EMPTY_SET, so the default StandardAnalyzer leaves no hole)
- The finding in 30 seconds
lucene/highlighter/src/java/org/apache/lucene/search/highlight/WeightedSpanTermExtractor.java:139-164 (at a9779ef3c193) (PhraseQuery branch; positionGaps :150-156; sum :161-162), :187-235 (MultiPhraseQuery branch; positionGaps :215-224; sum :232)lucene/queries/src/java/org/apache/lucene/queries/spans/SpanNearQuery.java:119-131, (at a9779ef3c193) :230-232; NearSpansOrdered.java:67, :89; NearSpansUnordered.java:84lucene/highlighter/src/java/org/apache/lucene/search/highlight/Highlighter.java:71, (at a9779ef3c193) :92; QueryScorer.java:33-37
- Who is affected
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:108-111, (at a9779ef3c193) :349, :518-528lucene/core/src/test/org/apache/lucene/search/TestPhraseQuery.java:339; (at a9779ef3c193) lucene/core/src/test/org/apache/lucene/search/TestSimpleSearchEquivalence.java:173 (at a9779ef3c193)lucene/analysis/common/src/java/org/apache/lucene/analysis/en/EnglishAnalyzer.java:67-69; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/standard/StandardAnalyzer.java:51-53 (at a9779ef3c193)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/PhraseQuery.java:173-175, (at a9779ef3c193) :268-283; lucene/core/src/java/org/apache/lucene/search/MultiPhraseQuery.java:95-102 (at a9779ef3c193)lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:205-210, (at a9779ef3c193) :802lucene/CHANGES.txt:10016 (at a9779ef3c193) (5.4.0 Bug Fixes), :10042-10045 (LUCENE-5503)lucene/highlighter/src/test/org/apache/lucene/search/highlight/TestHighlighterPhrase.java:273-274, (at a9779ef3c193) :308lucene/highlighter/src/java/org/apache/lucene/search/highlight/QueryScorer.java:35-36; (at a9779ef3c193) Highlighter.java:71, :92
- Suggested fix
lucene/core/src/java/org/apache/lucene/util/MathUtil.java:196-199; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/search/MaxScoreBulkScorer.java:424; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/search/BitSetDocIdStream.java:34 (at a9779ef3c193)lucene/sandbox/src/java/org/apache/lucene/payloads/PayloadSpanUtil.java:152 (at a9779ef3c193)
- Prior reports
a Lucene clone: git show origin/branch_10_6 (4ae946e5a9b9):lucene/highlighter/src/java/org/apache/lucene/search/highlight/WeightedSpanTermExtractor.java:163, :233
- TestHighlighterPhraseSlopOverflow.java (JUnit test):
repro/LFV-397/src/org/apache/lucene/search/highlight/TestHighlighterPhraseSlopOverflow.java(39 lines)
Made in parallel with this doc from the code at main a9779ef3c193 and the executed runs; every value drawn should come from the paste-ready test's output and the source at that commit.
assets/LFV-397/bug.png(497 KB)