The escaper's tables lag behind the grammar. Since 9.1 an @ is syntax at every position of a term, but the escaper escapes it only at the first; && and || have always meant AND and OR, but only the words are escaped.
- The flexible
StandardQueryParserfirst turns the text into a tree of query nodes. A term becomes aFieldQueryNodeholding the field and the unescaped text:user\@example.combecomes fielddf, textuser@example.com. - Every node can print itself back as query text with
toQueryString(escaper). A term node printsfield:followed by its text passed through the escaper (only the text when the field isnullor the reserved name_plain). EscapeQuerySyntaxImpl, the escaper for the standard syntax, puts a backslash before whatever the grammar would read as syntax: characters such as(or:anywhere in the term,+,-and@only at its start, and the whole wordsAND,ORandNOT.
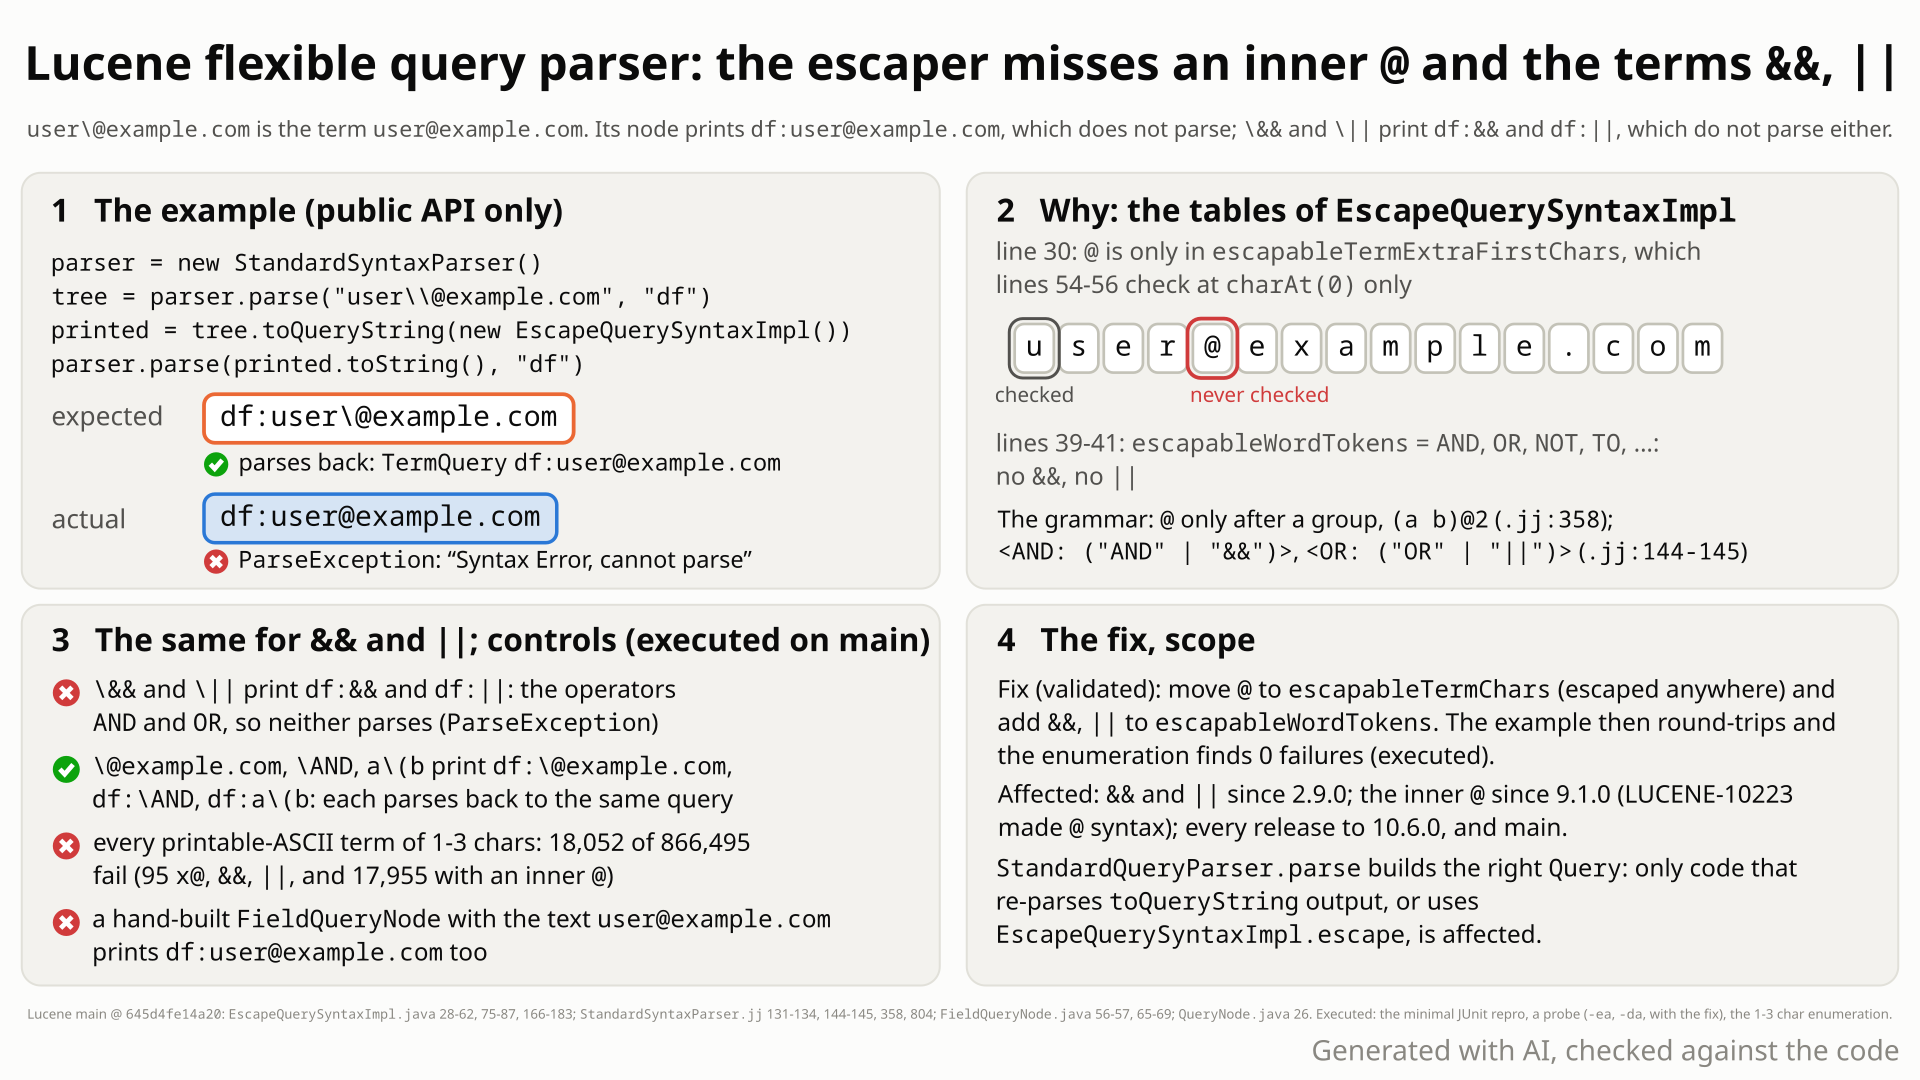
user\@example.com: parse, print with toQueryString, parse again. The printed text loses the backslash before the inner @, so the second parse fails; && fails the same way. Select the still to open it at full size. Generated with AI, checked against the code.- Parse
user\@example.com, an e-mail address written the way the flexible parser requires since 9.1 (an@inside a term must be escaped). The parser builds one term node: fielddf, textuser@example.com. - Print it with
toQueryString(new EscapeQuerySyntaxImpl()), documented to return "a query string understood by the query parser". You expectdf:user\@example.com: the escaper already prints a leading@as\@and the wordANDas\AND. - You get
df:user@example.com, and parsing it again throwsINVALID_SYNTAX_CANNOT_PARSE. The escaper escapes@only at position 0, while the grammar rejects an unescaped@at every position of a term. - The term
&&(typed\&&) prints asdf:&&, which the parser reads as the AND operator: the same syntax error, and||likewise. The escaper's reserved words includeAND,ORandNOT, but not&&or||. - Of all 866,495 printable-ASCII texts of 1 to 3 characters, each built as a term node, 18,052 do not survive the round trip, each with an
@after the first character or exactly&&/||; a three-line change to three of the escaper's tables brings that to 0. TheQuerythatparse()builds is not affected.
Applications that print flexible-parser node trees back to text with toQueryString(new EscapeQuerySyntaxImpl()), or call EscapeQuerySyntaxImpl.escape themselves, and parse that text again: a term with @ after its first character, such as an e-mail address, or the term && or || gives a syntax error. Default settings; parse() results are unaffected.
Mechanism, terms and numbers715 words
QueryNode#toQueryString(EscapeQuerySyntax) is documented to "convert to a query string understood by the query parser", and EscapeQuerySyntaxImpl is the escaper for the standard syntax. Since 9.1 (LUCENE-10223) the standard grammar rejects an unescaped @ anywhere in a term, so an e-mail address has to be written user\@example.com (or quoted); && and || have been the AND and OR operators since the flexible parser's first release, 2.9.0. The escaper was never updated for either: it escapes @ only as a term's first character, and its reserved words are AND, OR, NOT but not && or ||.
So the term nodes the parser builds from user\@example.com, \&& and \|| print as df:user@example.com, df:&& and df:||, and parsing any of them again throws INVALID_SYNTAX_CANNOT_PARSE. Of all 866,495 printable-ASCII texts of length 1 to 3, each built as a term node, exactly 18,052 fail this round trip; with a three-line change to three of the escaper's tables, none do. The Query that StandardQueryParser.parse() builds is not affected: only code that turns node trees back into text, or calls the escaper itself, and then parses that text. The && / || half is in every release from 2.9.0 to 10.6.0, the inner-@ half in every release from 9.1.0, and main has both.
- The parser builds the node. A term token becomes
new FieldQueryNode(field, discardEscapeChar(term.image), ...)(StandardSyntaxParser.jj:804), souser\@example.comgives a node whose text isuser@example.com. - The node prints itself.
FieldQueryNode.toQueryStringreturnsfield + ":" + getTermEscaped(escaper), or only the escaped term whenisDefaultField(field)is true: anullfield, the reserved field name_plain, or a node told to ignore fields (FieldQueryNode.java:64-71,QueryNodeImpl.java:35,:206-211);getTermEscapedcallsescaper.escape(text, Locale.getDefault(), Type.NORMAL)(:55-58).NORMALis documented as "for escaping reserved words (like AND) in terms" (EscapeQuerySyntax.java:27-28). - The escaper.
escape(EscapeQuerySyntaxImpl.java:166-183) handles wildcards and backslashes, thenescapeTerm(:75-87) runsescapeCharandescapeWhiteCharand finally compares the whole term withescapableWordTokens(:83-85).escapeChar(:43-62) escapes each character ofescapableTermChars(:32-34) at every position, but checksescapableTermExtraFirstChars = {"+", "-", "@"}(:30) againstbuffer.charAt(0)only (:53-59).escapableTermCharshas no@, andescapableWordTokens(:39-41) isAND, OR, NOT, TO, WITHIN, SENTENCE, PARAGRAPH, INORDER. - The grammar.
_TERM_START_CHARexcludes@(StandardSyntaxParser.jj:131-133) and_TERM_CHARadds back only-and+(:134). So+and-are legal inside a term, and escaping them only at the start is right, but an unescaped@is legal nowhere in a term: it appears only as the min-should-match marker after a group,( ... )@N(:358). - The operators.
<AND: ("AND" | "&&")>and<OR: ("OR" | "||")>(:144-145) are declared before<TERM>(:161). For exactly&&, the AND and TERM tokens match the same length and the earlier one wins, sodf:&&is a field followed by an operator: a syntax error.&&&anda&&bare longer TERM matches and round-trip.
\@example.com(control,@first) printsdf:\@example.comand parses back.user\@example.comprintsdf:user@example.com: syntax error. With the fix:df:user\@example.com, parses.\&&printsdf:&&: syntax error (read as AND). With the fix:df:\&&, parses.\||printsdf:||: syntax error (read as OR). With the fix:df:\||, parses.- Controls:
\AND,&&&anda&&bprintdf:\AND,df:&&&anddf:a&&band parse back. (UnescapedANDis rejected as input:Syntax Error, cannot parse AND:.)
The same nodes come from the public constructor new FieldQueryNode("f", "user@example.com", 0, 0); hand-built nodes with the texts AND, &&& and a&&b print f:\AND, f:&&& and f:a&&b and parse back. Quoted terms are not affected; they use the STRING escaping path.
Every printable-ASCII text of length 1 to 3 (95 + 95^2 + 95^3 = 866,495) was built directly as a term node (FieldQueryNode), printed and parsed again: 18,052 fail, exactly the 95 two-character texts x@, the texts && and ||, and 17,955 three-character texts with @ after the first character. With the fix, 0 fail. An independent reproducer repeated the enumeration and got the same count.
Exposure and likelihood274 words
- Who is hit. Code that turns node trees into text and parses it again, for example to store, log or forward a rewritten query, or that escapes words with
EscapeQuerySyntaxImpl.escape. The trigger is any term with an inner@(e-mail addresses,user@hosthandles) or a literal&&/||term, from escaped input or from hand-built nodes. - Default vs opt-in. Default parser settings and the stock escaper, the only implementation in Lucene. The round trip itself is an uncommon API pattern;
StandardQueryParser.parse()never re-parses its own output. - What goes wrong. For a term printed with a field prefix (
df:user@example.com,df:&&,df:||) the printed query is refused with a cleanParseException(INVALID_SYNTAX_CANNOT_PARSE): it fails loudly. A bare||printed without a prefix (a node whose field isnullor the reserved name_plain, or a word escaped withEscapeQuerySyntaxImpl.escapeand joined into a query) parses again as the OR operator and can change what the query means. - The three cases differ. An inner
@(e-mail addresses, handles) is the realistic one and fails since 9.1; a literal&&or||term is unusual; only||has a shown change of meaning, and only in text printed without a field prefix. - Inside Lucene escaped output only feeds exception messages (
QueryTreeBuilder.java:161,BooleanQueryNodeBuilder.java:72,MatchAllDocsQueryNodeBuilder.java:42,MatchNoDocsQueryNodeBuilder.java:42,AllowLeadingWildcardProcessor.java:74), which then show the term unescaped.IntervalQueryNode.toString()also callstoQueryString(new EscapeQuerySyntaxImpl())(IntervalQueryNode.java:52-55), but itstoQueryStringignores the escaper (:47-50). - Scale and reach. One term is enough, deterministic. No public report since 9.1.0 (2022) for
@or since 2.9.0 (2009) for&&/||.
One JUnit class in lucene/queryparser, public API only: parse the escaped input, print it with toQueryString(new EscapeQuerySyntaxImpl()), assert the escaped text, parse it again. Two methods, one per half: user\@example.com (since 9.1.0) and \&& (since 2.9.0). No index; deterministic; fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queryparser.flexible.standard.parser;

import org.apache.lucene.tests.util.LuceneTestCase;

// toQueryString must print a query string the parser accepts; the unescaped output fails to parse
public class TestEscapeQuerySyntaxRoundTrip extends LuceneTestCase {

  private static void assertRoundTrip(String query, String expected) throws Exception {
    StandardSyntaxParser parser = new StandardSyntaxParser();
    String printed = parser.parse(query, "df").toQueryString(new EscapeQuerySyntaxImpl()).toString();
    assertEquals(expected, printed);
    parser.parse(printed, "df");
  }

  public void testAtSignInsideTerm() throws Exception {
    assertRoundTrip("user\\@example.com", "df:user\\@example.com");
  }

  public void testAndAndTerm() throws Exception {
    assertRoundTrip("\\&&", "df:\\&&");
  }
}
cd $LUCENE   # an apache/lucene checkout at 645d4fe14a20 (or any commit with the same EscapeQuerySyntaxImpl.java)
mkdir -p lucene/queryparser/src/test/org/apache/lucene/queryparser/flexible/standard/parser
cp $REPRO/TestEscapeQuerySyntaxRoundTrip.java lucene/queryparser/src/test/org/apache/lucene/queryparser/flexible/standard/parser/
./gradlew :lucene:queryparser:test --tests org.apache.lucene.queryparser.flexible.standard.parser.TestEscapeQuerySyntaxRoundTrip -Ptests.seed=DEADBEEF
# assertions off fails the same way: add -Ptests.asserts=false
- Expected
toQueryStringprintsdf:user\@example.comanddf:\&&, and both strings parse back to the same term.- Observed
- It prints
df:user@example.comanddf:&&(2 of 2 tests fail); parsing either throwsINVALID_SYNTAX_CANNOT_PARSE, on main, 10.6.0 and 10.5.2.
More files, environment, full output244 words
Two methods because the bug has two independent halves with different table entries and version ranges; || shares the && table entry and fix line and is left out. The class sits in the parser package, as an upstream test would, but uses no package-private member. It is also the suggested regression test.
Its printed line is one line over the google-java-format limit; ./gradlew :lucene:queryparser:tidy wraps it, nothing else changes, and :lucene:queryparser:check -x test then passes.
The test asserts the escaped text first, then parses it, the same "expected format, then parse" shape as TestAbstractRangeQueryNode. A maintainer who prefers a different parseable form, such as quoting, may want the assertion relaxed to parse-back only; the failure on stock code is the same.
On 9.0.0 and older the first assertion of testAtSignInsideTerm also fails, although df:user@example.com still parses there, because no release has ever escaped an inner @. The 9.1.0 boundary rests on the parse-back runs in the version history.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): affected; also the 10.6.0 and 10.5.2 release jars with this test |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux, aarch64 |
TestEscapeQuerySyntaxRoundTrip > testAtSignInsideTerm FAILED
    org.junit.ComparisonFailure: expected:<df:user[\]@example.com> but was:<df:user[]@example.com>
        at org.apache.lucene.queryparser.flexible.standard.parser.TestEscapeQuerySyntaxRoundTrip.assertRoundTrip(TestEscapeQuerySyntaxRoundTrip.java:27)
        at org.apache.lucene.queryparser.flexible.standard.parser.TestEscapeQuerySyntaxRoundTrip.testAtSignInsideTerm(TestEscapeQuerySyntaxRoundTrip.java:32)

TestEscapeQuerySyntaxRoundTrip > testAndAndTerm FAILED
    org.junit.ComparisonFailure: expected:<df:[\]&&> but was:<df:[]&&>
        at org.apache.lucene.queryparser.flexible.standard.parser.TestEscapeQuerySyntaxRoundTrip.assertRoundTrip(TestEscapeQuerySyntaxRoundTrip.java:27)
        at org.apache.lucene.queryparser.flexible.standard.parser.TestEscapeQuerySyntaxRoundTrip.testAndAndTerm(TestEscapeQuerySyntaxRoundTrip.java:36)

:lucene:queryparser:test (FAILURE): 2 tests, 2  failures

# re-parsing the unescaped strings (mechanism check on the same commit):
INVALID_SYNTAX_CANNOT_PARSE: Syntax Error, cannot parse df:user@example.com:
INVALID_SYNTAX_CANNOT_PARSE: Syntax Error, cannot parse df:&&:
INVALID_SYNTAX_CANNOT_PARSE: Syntax Error, cannot parse df:||:- The javadoc says so:
toQueryStringreturns "a query string understood by the query parser". - Since 9.1 an inner
@must be escaped,am\@zing, or quoted (Dawid Weiss on #11800); when/became syntax in 2012, the escaper gained/in the same commit. QueryParserUtil.escapeescapes&and|, and #7865 fixed unparseable range-node output as a bug in 11.0.0.
The full argument308 words
- The documentation says the output parses. "convert to a query string understood by the query parser" (
QueryNode.java:26); "A query node tree can also generate a query string that can be parsed back by the original text parser, at this point only the standard lucene syntax is supported" (core/nodes/package-info.java:42-43);NORMALescapes "reserved words (like AND) in terms" (EscapeQuerySyntax.java:27-28). These describe the intended behaviour rather than state a formal round-trip guarantee, but the output here is a syntax error. - The inner
@must be escaped by design. On #11800 (2022) Robert Muir called the 9.1@parse failure "not a bug", an intended grammar change, and Dawid Weiss wrote "You can escape the at character":am\@zing. So the escaped form is the intended syntax, and the escaper should produce it. Neither mentionstoQueryString. - The escaper was kept in step with the grammar once before. LUCENE-3981 (
167b296353d, 2012) excluded/from term characters and added/toescapableTermCharsin the same commit. LUCENE-10223 (f725b27e12a, #429) added@to the exclusions and did not touchEscapeQuerySyntaxImpl. So the@half is a missed follow-up in the escaper; the grammar change itself was intended (#11800). - The escaper already escapes the word forms (
ANDprints\AND), and the package's other escaper,QueryParserUtil.escape, escapes&and|(QueryParserUtil.java:172-174), asserted since LUCENE-881 (TestQPHelper.java:923-925). - Precedent.
CHANGES.txt:296-298, Lucene 11.0.0 Bug Fixes: "GITHUB#7865 AbstractRangeQueryNode#toQueryString(EscapeQuerySyntax) now returns a string which can be parsed back into the original node";TestAbstractRangeQueryNodeasserts the "query string should have expected format and parse into a valid query" (:44-47). - Nothing documents the gap. No javadoc, test, CHANGES or MIGRATE entry says these terms may print unparseable;
MIGRATE.md:1116-1122mentions only "the@character after parentheses". No upstream test pins the escaper's current output.
The devil's-advocate check196 words
The strongest case for "intended" (weak, as every verifier rated it; a later reading-only fact check by another model family rated it moderate): "There has never been a guarantee that going back and forth between a parsed query and its string representation is idempotent" (Erick Erickson, java-user, March 2017, about range nodes), and open #8667 questions toQueryString's design; toQueryString also reads like a display serializer (it takes the escaper as a parameter, and in-tree callers use it for messages).
Why it fails: both quotes are about output that differs from the input, not output that does not parse, and the javadoc describes the output as parseable. In the same 2017 thread Michael McCandless replied "Why don't we fix this in Lucene?", and that line of work ended in the #7865 Bug Fixes entry. A second argument, letting the grammar accept @ inside terms again, reverses the decision on #11800 and leaves && / || unfixed; the escaper fix is the consistent one. One range-node fix (#7865) does not make a general round-trip guarantee, so the claim easiest to accept is the narrow one: FieldQueryNode's term printing is out of step with the current grammar.
Recommended Update three of the escaper's tables
In EscapeQuerySyntaxImpl, move @ from the first-character list to the every-position list, and add && and || to the reserved words (+3/-3, one file). The repro passes with assertions on and off, and so does the whole queryparser test task (535 tests, 1 skipped). Only values with an inner @ or exactly && / || print differently.
-  private static final String[] escapableTermExtraFirstChars = {"+", "-", "@"};
+  private static final String[] escapableTermExtraFirstChars = {"+", "-"};
   private static final String[] escapableTermChars = {
-    "\"", "<", ">", "=", "!", "(", ")", "^", "[", "{", ":", "]", "}", "~", "/"
+    "\"", "<", ">", "=", "!", "(", ")", "^", "[", "{", ":", "]", "}", "~", "/", "@"
   };
   private static final String[] escapableWordTokens = {
-    "AND", "OR", "NOT", "TO", "WITHIN", "SENTENCE", "PARAGRAPH", "INORDER"
+    "AND", "OR", "NOT", "TO", "WITHIN", "SENTENCE", "PARAGRAPH", "INORDER", "&&", "||"
   };
All options and trade-offs3 options · 525 words
One fix was built and checked through gradle in a scratch worktree of 645d4fe14a20; the alternatives come from the verifiers and were not run.
Escape @ at every position, as LUCENE-3981 did for / (a leading @ still prints \@), and treat a term that is exactly && or || like AND: a leading backslash. &&& and a&&b stay as they are. Could add a CHANGES entry under Bug Fixes.
-  private static final String[] escapableTermExtraFirstChars = {"+", "-", "@"};
+  private static final String[] escapableTermExtraFirstChars = {"+", "-"};
   private static final String[] escapableTermChars = {
-    "\"", "<", ">", "=", "!", "(", ")", "^", "[", "{", ":", "]", "}", "~", "/"
+    "\"", "<", ">", "=", "!", "(", ")", "^", "[", "{", ":", "]", "}", "~", "/", "@"
   };
   private static final String[] escapableWordTokens = {
-    "AND", "OR", "NOT", "TO", "WITHIN", "SENTENCE", "PARAGRAPH", "INORDER"
+    "AND", "OR", "NOT", "TO", "WITHIN", "SENTENCE", "PARAGRAPH", "INORDER", "&&", "||"
   };
Trade-offs
- Only the printed text of a value with an inner
@or exactly&&/||changes. For a term with a field prefix that text did not parse before and now does. A bare||printed without a prefix (anullor_plainfield, orescape()on a single word) was read as OR and now stays a term. Range bounds also go through the escaper, and inside brackets@,&&and||already parse:[a@b TO c]and[&& TO zz]now printdf:[a\@b TO c]anddf:[\&& TO zz]and parse back to the same range query (executed). With the fix the study's exhaustive length 1-3 round trip has 0 failures, and its security enumeration gives the intended term query for all 866,495 texts. - Exception messages that print nodes now show the escaped text. No upstream test pins the old output.
- Open PR #16853 edits
escapeIgnoringCasein the same file; its diff does not touch these tables.
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20, seed DEADBEEF: stock, the repro fails 2 of 2 with assertions on and off; with the fix it passes 2 of 2 with assertions on and off. - With the fix:
TestQPHelper,TestStandardQPandTestAbstractRangeQueryNode86 tests, 1 skipped (an existing@Ignore), 0 failures; the whole:lucene:queryparser:test535 tests, 1 skipped, 0 failures;:lucene:queryparser:check -x testpasses with the tidied repro test in place. - Earlier, on the standalone runner: the repro, a parse-back-only test including a
Query-level check (5 of 5), the exhaustive length 1-3 check (0 failures) and the security probe.
Add & and | to escapableTermChars, as QueryParserUtil.escape does.
Trade-offs
A simpler rule, consistent with the other helper, but it also changes the output of terms that round-trip today (a&&b would print a\&\&b). Not run.
Add @ to _TERM_CHAR in StandardSyntaxParser.jj.
Trade-offs
Reverses the intended 9.1 change (#11800), needs the JavaCC parser regenerated, and does nothing for && / ||. Not recommended; not run as a fix.
Not a Lucene security issue; downstream, a word that is exactly || and printed without a field prefix (escaped alone with EscapeQuerySyntaxImpl.escape and joined into a query string, or a node whose field is null or the reserved name _plain) is read as the OR operator, which can make a neighbouring clause without + optional.
A bounded-exhaustive round-trip check of the stock jar: every printable-ASCII text of 1 to 3 characters (866,495) was printed as a term node with toQueryString and parsed again. Exactly 18,052 failed, each with an inner @ or exactly && / ||, and 0 with the fix; a public-API JUnit then witnessed it.
The method in full199 words
Method: semi-formal, translation validation of the stock main jar (a hunt unit, the flexible, simple and XML query parsers).
- Mode
escape: every printable-ASCII text of length 1 to 3 built directly as a term node (FieldQueryNode), printed withtoQueryString(new EscapeQuerySyntaxImpl())and parsed again (the log counts 866,497 checks: two extra texts with non-ASCII whitespace). 18,052ParseExceptions: the 95 textsx@,&&,||and 17,955 three-character texts with@after the first character; 0 with the fix. - Mode
syntax: every query string of length up to 5 over a 20-symbol alphabet (3,368,420 strings) was parsed; the 163,434 that parse were printed and parsed again. 1,806 failures fall in the inner-@class and 266 in the&&/||class; 264 more combine an inner@with an escaped field name, a separate bug. - A first draft blamed the grammar (an unescaped
@inside a term stopped parsing in 9.1). It was withdrawn after reading #11800, where maintainers called that change intended; the surviving defect is the escaper. - An AI tool then wrote the public-API JUnit test; an independent reproducer repeated the enumeration with its own code and got the same 18,052.
No prior report: 321 query records on 2026-10-31 (GitHub issues and PRs, the changed files of all 410 open PRs, commits, downstream trackers, mailing lists, JIRA, web), repeating a 281-query search of 2026-10-26. Closest: open PR #16892, which changes only QueryParserUtil.escape and says this escaper already escapes @.
Searches4 searches
Verdict new; none of the hits is this bug.
- Open PR #16892 (by others, 2026-10-22) adds
=,<,>and@toQueryParserUtil.escapeand saysEscapeQuerySyntaxImpl"already escapes all four", which for@holds only at the first character; it never mentions&&or||. Its claim about this class is exactly the gap. - Open PR #16853 (same author) fixes escape positions after length-changing lower-casing; it does not change the tables.
- #11800 (closed 2022): the intended grammar change, the premise of the
@half. - LUCENE-881 / #1956 (fixed 2007): the same
|/&gap in the classic escaper; #7283 (open): classic escaper and word operators. - #8667 (open,
toQueryStringdesign); #7865 / PR #14697 (fixed for 11.0.0, the range-node precedent); #9618, #9744, PR #12973, #11259 / PR #429 (same class, other defects, a cleanup, the grammar change).
Gaps: GitHub and JIRA search drop @, && and || as punctuation (searched by words instead); only the first 50 results of two broad queries were read; private reports to the security list are not visible. Someone else opened two PRs on these files in October 2026.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, migrated JIRA issues included) | 2026-10-31 | four scripted prior-report search runs (the @ half, the && / || half, round-trip wording, 16 manual phrasings) and 50 manual REST searches, including date-bounded ones | no report; closest #16892, #16853, #11800 |
| Open PRs and commit history | 2026-10-31 | gh pr list searches; the changed-file lists of all 410 open PRs; commit searches; upstream histories of EscapeQuerySyntaxImpl.java, StandardSyntaxParser.jj and QueryParserUtil.java; git log -S/-G over the full history | no PR or commit changes the escape tables; the escaper last changed on 2026-04-01 (a refactor) |
| Downstream and all of GitHub | 2026-10-31 | EscapeQuerySyntaxImpl in Elasticsearch, OpenSearch, Solr, Lucene.NET and across GitHub | only mirrors and an unrelated escaping PR |
| Mailing lists, JIRA archive, web | 2026-10-31 | dev@, java-user@, issues@, commits@ (tool and 18 manual queries); 9 manual JQL searches incl. LUCENE-881; 9 web searches | LUCENE-881 and older round-trip threads on range nodes; no report |
&& / || since the flexible parser's first release, 2.9.0 (LUCENE-1567, 2009); the inner @ since 9.1.0, when LUCENE-10223 (#429, 2021) made @ syntax in the grammar but not in the escaper. Executed on all 148 releases from 2.9.0 to 10.6.0 and on main; none is fixed.
Versions tested5 rows
&& / ||: introduced by LUCENE-1567 "New flexible QueryParser framework" (343992fcbb4, Michael Busch, 2009-08-03, svn era, no PR). Its grammar already had && and || as AND and OR, while the escaper listed only the words.
Inner @: introduced by LUCENE-10223 "interval support in standard syntax parser" (PR #429, issue #11259, Dawid Weiss, merged 2021-11-11; main f725b27e12a, branch_9x ff9ee28c603). It added @ to the term-character exclusions for the new ( ... )@N syntax and left the escaper's first-character-only @ rule, which dates from 2009: a missed follow-up in the escaper, while the grammar change itself was intended (#11800). A commit-level check pins it: the 9.1.0 jars with the generated parser of ff9ee28c603 fail the inner-@ case; with the parser of its parent 238cd5fd0c3 they pass.
In the whole history the escape tables changed only once, when LUCENE-3981 (2012) added /.
| Version or commit | Verdict | Result |
|---|---|---|
| 2.9.0 to 9.0.0 (115 releases) | && / || only | parse-back probe: && and || fail, the inner @ passes (it is still a term character), the leading-@ control passes |
| 9.1.0 jars + parser of 238cd5fd0c3 / of ff9ee28c603 | commit check | the parent's parser passes the inner-@ case; the commit's parser fails it |
| 9.1.0 to 10.6.0 (33 releases) | both halves | inner @, && and || fail; the minimal test fails 2 of 2 on 9.1.0, 10.5.2 and 10.6.0 |
| main 645d4fe14a20 | affected | fails through gradle and the standalone runner, assertions on and off; passes with the fix |
| upstream main 2f424fd428da (2026-10-30), branch_10_6 | by reading | the same three escape tables |
An independent reproducer, an intended-behaviour devil's advocate and an adjudication each ran their own tests and rated it real (adjudication: high confidence). Reviews by another model family (OpenAI GPT-5.6) could only read code: one real, one a procedural "not real". A 2026-10-31 re-run, a tie-breaker and a gradle check of the fix followed.
Checks and verdicts318 words
No verifier found the intended-behaviour argument stronger than weak. No executed cross-model review exists: the GPT reviews were reading-only.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit) | candidate | Exhaustive round trip (18,052 failures, 0 with the fix), then a public-API JUnit: 3 of 4 fail, the leading-@ control passes. |
| Cross-model review, refute lens (OpenAI GPT-5.6) | not real (low, procedural) | Reading only, it could not run Java; it agreed with the root cause, found the inputs in contract and rated the intended argument weak. A separate re-run failed 3 of 4. |
| Cross-model review, intended lens (OpenAI GPT-5.6) | real (medium) | Reading only; intended argument weak, root cause agreed, inputs in contract. |
| Independent reproducer | real | Own 10-test class: 6 of 10 fail on main, 10.5.2 and 9.12.3, all 4 controls pass; own enumeration matches 18,052; own fix 10 of 10. |
| Intended-behaviour devil's advocate | real | 30 of 33 assorted constructs round-trip; only \&&, \|| and x\@y fail. No test, javadoc, CHANGES or MIGRATE entry intends it. |
| Adjudication | confirmed (high) | The independent reproduction's test fails 6 of 10 with assertions on and off, controls pass; 10 of 10 with the fix. |
| 2026-10-31 reproducer and tie-breaker | real | The minimal test fails on main 645d4fe14a20, 10.6.0 and 10.5.2; an own parse-back-only test fails 4 of 5 and passes 5 of 5 with the fix. |
| This doc's gradle runs | fix validated | Repro fails stock, passes with the fix (assertions on and off); 535 queryparser tests and the module check pass with the fix. |
| Fact checks of this doc and the brief | corrections applied | An independent fact check re-ran the repro, the gradle command and its own probes (bug, repro, fix and classification hold; five wording and scope errors, now fixed); a reading-only fact check by another model family found further overclaims, now fixed; the diagram check passed. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 536 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,531 words
- Registry title
- Flexible query parser: EscapeQuerySyntaxImpl does not escape '@' after the first character of a term or a term that is exactly && or ||, so QueryNode#toQueryString output for such terms does not parse
- Area
- queryparser / flexible parser term escaping (EscapeQuerySyntaxImpl, as used by QueryNode#toQueryString)
- Priority
- Low, rank 893: The flexible parser's escaper utility breaks its round-trip contract for an inner '@' or a bare && or ||, while the parse-to-Query path is unaffected.
- Impact class
- minor
- Impact note
- A round-trip (contract) defect in a utility method, with no effect on the Query that StandardQueryParser.parse builds: applications that turn flexible-parser node trees (parsed from escaped input such as 'user\@example.com', or built by hand) back into text with toQueryString(new EscapeQuerySyntaxImpl()), or that call EscapeQuerySyntaxImpl.escape themselves, and then parse that text get a syntax error for any term with '@' after its first character (an e-mail address, for example) or a term that is exactly && or ||; inside Lucene the output only feeds exception messages; default parser configuration, any scale, every release since 2.9.0 for && / || and since 9.1.0 for '@'.
- Summary
- Since 9.1 the standard flexible parser reads an '@' anywhere in a term as syntax (it must be escaped, as in user\@example.com), and && and || are its AND and OR operators, so QueryNode#toQueryString, documented to return 'a query string understood by the query parser', has to escape them. Its escaper EscapeQuerySyntaxImpl escapes '@' only when it is the first character of a term and lists AND, OR and NOT but not && or || as reserved words, so the node for 'user\@example.com' prints 'df:user@example.com' and the nodes for '\&&' and '\||' print 'df:&&' and 'df:||'. Parsing any of these strings again throws INVALID_SYNTAX_CANNOT_PARSE; with a small fix to the escaper's tables every printable-ASCII term of length 1-3 round-trips.
- Introduced
- Two parts with one fix site. '@' part: f725b27e12a9 on main and its branch_9x backport ff9ee28c6035 (LUCENE-10223, GitHub #11259, PR #429 by dweiss, merged 2021-11-11): it excluded '@' from every term character in StandardSyntaxParser.jj (for the new '(...)@N' min-should-match syntax) but did not change EscapeQuerySyntaxImpl, whose first-character-only '@' rule (escapableTermExtraFirstChars) dates from 343992fcbb4b [exec: commit-level check, 9.1.0 jars with the generated parser of the parent 238cd5fd0c3 pass the inner-'@' test, with the parser of ff9ee28c6035 they fail it; read: git log -G on _TERM_START_CHAR between 9.0.0 and 9.1.0 returns only ff9ee28c6035, and EscapeQuerySyntaxImpl is identical in 9.0.0 and 9.1.0]. && / || part: 343992fcbb4b31249f07354014723f18d0508d8a (LUCENE-1567 'New flexible QueryParser framework', GitHub #2641, SVN r800191; SVN era, no PR): its grammar already defined <AND: "AND" | "&&"> and <OR: "OR" | "||"> while escapableWordTokens listed only the word forms [read: git log -S'"&&"' finds no commit that ever adds && or || to the escaper; exec: 2.9.0 fails]. (2009-08-03 (&& / || part, 343992fcbb4b); 2021-11-11 ('@' part, PR #429 merged))
- First affected version
- 2.9.0 [exec] for the && / || part (the first release with the flexible query parser; no earlier release has EscapeQuerySyntaxImpl); 9.1.0 [exec] for the '@' part (9.0.0 [exec] is the last release without it; 10.0.0 is the first main-line release that contains f725b27e12a9)
- Affected versions
- && / || part: every release from 2.9.0 to 10.6.0 and main ea57360912ed; '@' part: 9.1.0 to 9.12.3, 10.0.0 to 10.6.0 and main [exec on 10.6.0: the minimal test fails 2 of 2 on the release jars with -ea, 2026-10-31]; no fixed release, and upstream main cf398bfb142c (2026-10-26) has the same escape tables. [exec] the finder's JUnit (4 tests) fails 3 of 4 on main (-ea and -da), 10.5.2, 10.0.0, 9.12.3 and 9.1.0 and 2 of 4 (only && and ||, inner '@' passes) on 9.0.0, 8.11.4 and 4.0.0 (the pre-9.1 runs with only the test-framework imports changed, 4.0.0 under JUnitCore); a main() probe with the same inputs fails only && and || on 2.9.0 and 3.6.2; the independent reproduction's JUnit fails 6 of 10 on main (-ea and -da), 10.5.2 and 9.12.3, and the independent reproduction's main() probe fails only && and || on 9.0.0, 8.11.2 and 4.0.0. [read] source sweep of every release tag in the history clone; the 8.9.0 to 8.11.3 tags are missing there and are inferred from 8.8.1 (source) and 8.11.4 (executed). Not executed: x86 and each release's own JDK (all runs JDK 25.0.3 aarch64; the code path is pure string handling).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an adjudication that ruled it real, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record, verdict new): no issue, PR, commit, JIRA ticket, mailing-list thread or downstream report says that EscapeQuerySyntaxImpl escapes '@' only as the first character of a term or leaves a term that is exactly && or || unescaped; upstream main cf398bfb142c (2026-10-26) has the same escape tables. Related, not this bug: open PR #16892 (GitHub soma0212, opened 2026-10-22, no reviews) adds '=', '<', '>' and '@' to the separate helper QueryParserUtil.escape and states that EscapeQuerySyntaxImpl 'already escapes all four', which for '@' holds only at the first character, so it asserts the opposite of this bug and changes different code; open PR #16853 (same author) fixes a different EscapeQuerySyntaxImpl defect (escape positions after length-changing lower-casing, as in #9618 / #9744) and does not touch the escape tables; closed #11800 (2022) is the premise: maintainers said that since 9.1 (LUCENE-10223) an inner '@' must be escaped ('am\@zing') or quoted, and nobody mentioned EscapeQuerySyntaxImpl or toQueryString; LUCENE-881 (GitHub #1956, fixed 2007) is the same defect class in the classic QueryParser.escape (| and &), and open #7283 (LUCENE-6221) is about that escaper and the word operators; #7865 / PR #14697 (range-node toQueryString, fixed for 11.0.0) is the precedent that unparseable toQueryString output is fixed as a bug; #8667 (open, toQueryString design); #11259 / PR #429 (the grammar change; neither discusses the escaper); java-user threads of 2009 and 2017 on range round trips. Searched: a scripted prior-report search (the finder's run and runs A-E over GitHub issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA and web), 28 manual GitHub GraphQL searches, JIRA REST, lists.apache.org, 11 manual web searches and git log over the full history (281 queries). Gaps: GitHub search drops '@', '&&' and '||' as punctuation (those halves were searched by words such as 'at sign', 'email' and 'reserved words'), one Q&A page could not be read, and private reports to security@lucene.apache.org are not visible. Timing: the same person opened two PRs on these files within ten days.
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28): the two-method test through gradle in a scratch worktree, assertions on and off, stock and with the fix, plus the closest suites, the wholelucene/queryparsertest task and:lucene:queryparser:check -x testwith the fix; the 10.6.0 and 10.5.2 release jars on the standalone runner; a parse-back probe on all 148 releases from 2.9.0 to 10.6.0. The escaper, the grammar and the node classes are the same blobs at the study's mainea57360912edand on upstream main2f424fd428da(2026-10-30).
- Finding record
lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/parser/EscapeQuerySyntaxImpl.java:25 (at ea57360912ed) (class javadoc 'for the standard lucene syntax'), :30 (escapableTermExtraFirstChars {+, -, @}), :32-34 (escapableTermChars, no '@'), :39-41 (escapableWordTokens, no && or ||), :43-62 (escapeChar: '@' only at index 0), :75-87 (escapeTerm: word tokens matched against the whole term)lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/parser/StandardSyntaxParser.jj:131-134 (at ea57360912ed) (_TERM_START_CHAR excludes '@'; _TERM_CHAR adds back only '-' and '+'), :144-145 (<AND: "AND" | "&&">, <OR: "OR" | "||">)lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/QueryNode.java:26 (at ea57360912ed) ('convert to a query string understood by the query parser'); lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/package-info.java:42-43 ('can be parsed back by the original text parser'); lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/parser/EscapeQuerySyntax.java:27 ('NORMAL for escaping reserved words (like AND) in terms'); lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/FieldQueryNode.java:55-71 (getTermEscaped uses Type.NORMAL; toQueryString prints field + ':' + escaped term)lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/QueryParserUtil.java:174 (at ea57360912ed) (escape escapes '|' and '&') and lucene/queryparser/src/test/org/apache/lucene/queryparser/flexible/standard/TestQPHelper.java:923-925 (LUCENE-881 asserts)
- The finding in 30 seconds
lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/parser/StandardSyntaxParser.jj:131-134, (at 645d4fe14a20) :144-145, :161, :358, :804lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/FieldQueryNode.java:55-58, (at 645d4fe14a20) :64-71; core/parser/EscapeQuerySyntax.java:27-28lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/parser/EscapeQuerySyntaxImpl.java:25, (at 645d4fe14a20) :30, :32-34, :39-41, :43-62, :75-87, :166-183lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/QueryNodeImpl.java:35, (at 645d4fe14a20) :206-211 (isDefaultField)
- Who is affected
lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/builders/QueryTreeBuilder.java:161; (at 645d4fe14a20) standard/builders/BooleanQueryNodeBuilder.java:72; standard/builders/MatchAllDocsQueryNodeBuilder.java:42; standard/builders/MatchNoDocsQueryNodeBuilder.java:42; standard/processors/AllowLeadingWildcardProcessor.java:74; standard/nodes/IntervalQueryNode.java:47-55
- Why it looks unintended
lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/QueryNode.java:26; (at 645d4fe14a20) core/nodes/package-info.java:42-43; core/parser/EscapeQuerySyntax.java:27-28; standard/parser/EscapeQuerySyntaxImpl.java:25lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/QueryParserUtil.java:172-174; (at 645d4fe14a20) lucene/queryparser/src/test/org/apache/lucene/queryparser/flexible/standard/TestQPHelper.java:923-925 (at 645d4fe14a20)lucene/CHANGES.txt:296-298; (at 645d4fe14a20) lucene/MIGRATE.md:1116-1122; lucene/queryparser/src/test/org/apache/lucene/queryparser/flexible/standard/nodes/TestAbstractRangeQueryNode.java:44-47 (at 645d4fe14a20)GitHub apache/lucene#11800 comments by rmuir and dweiss (read-only API, 2026-10-31)
- Prior reports
GitHub apache/lucene PR #16892 body (read-only API, 2026-10-31)
- Diagrams
lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/parser/EscapeQuerySyntaxImpl.java:30, (at 645d4fe14a20) :53-59; standard/parser/StandardSyntaxParser.jj:131-134, :144-145
- TestEscapeQuerySyntaxRoundTrip.java (2 tests):
repro/LFV-398/src/org/apache/lucene/queryparser/flexible/standard/parser/TestEscapeQuerySyntaxRoundTrip.java(38 lines)
A picture of the round trip, parse, print and parse again, and of the escaper rule that drops the backslash, made in parallel with this doc from the code at 645d4fe14a20; the PNG is the summary still.
assets/LFV-398/bug.png(536 KB)