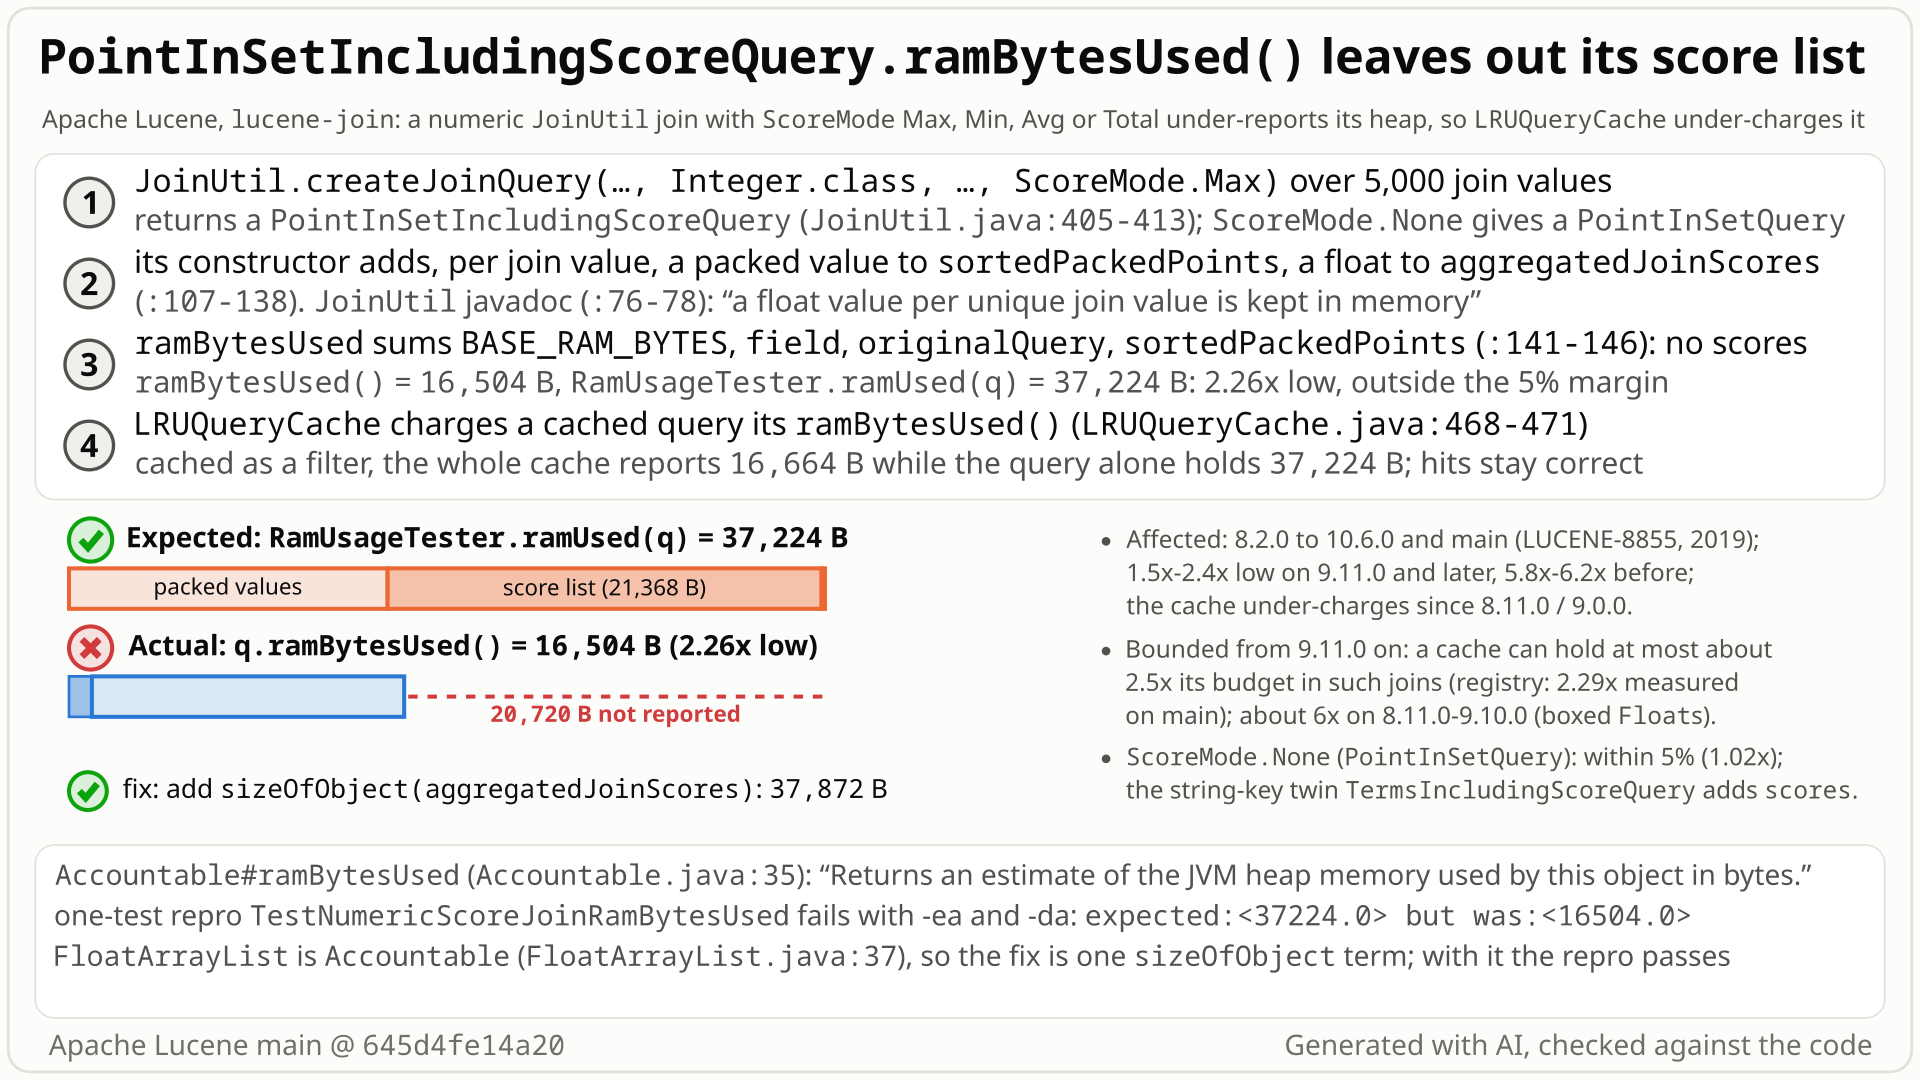
The scoring numeric join keeps two lists of the same length, the packed join values and their scores, but ramBytesUsed() adds up only the first.
- Numeric query-time join.
JoinUtil.createJoinQuery(...)with a numeric type runs the from query, collects the unique values of the from field, and returns a query matching documents whose to field holds one of them. WithScoreModeMax, Min, Avg or Total it also keeps one score per value; withScoreMode.Noneit keeps none. ramBytesUsed(). Queries that implementAccountablereport an estimate of the heap they hold.- Query cache.
LRUQueryCachecaches filters and charges each cached query itsramBytesUsed()against itsmaxRamBytesUsedbudget.
- Build a numeric join over 5,000 join values:
JoinUtil.createJoinQuery("from", false, "to", Integer.class, new MatchAllDocsQuery(), searcher, ScoreMode.Max). The query keeps the 5,000 values packed and, next to them, one float score per value. - You expect
ramBytesUsed()to cover both. TheScoreMode.Nonejoin of the same values reports 15,528 bytes, so the Max join should report at least 15,528 + 5,000 × 4 = 35,528. It really holds 37,224 bytes. - Instead it reports 16,504 bytes, only 976 more than the None join. The constructor adds up the base object, the field, the from query and the packed values (15,376 bytes) and never adds the 21,368-byte score list.
- A query cache charges this number for each cached query object, next to a small per-entry cost and the cached doc ids. Cached as a filter over 100,000 join values, the join costs the cache 304,408 bytes in all, while the query object alone holds 710,632. Cached and uncached hits are the same.
- The gap is about 4 to 4.5 bytes per join value: on 9.11.0 and later 1.5x to 2.4x depending on the keys, and the omission alone never makes it more than about 2.5x; on 8.2.0 to 9.10.0, with boxed
Floats, about 6x. Min, Avg and Total behave the same;ScoreMode.Noneand string-key joins are counted correctly.
Applications that build a numeric JoinUtil join with ScoreMode Max, Min, Avg or Total and read its ramBytesUsed(), or run it as a cached filter (MUST_NOT, ConstantScoreQuery, count). The default query cache (on in 10.x, off on main) charges this number since 8.11.0. Bounded overshoot: at most about 2.5 times the budget from 9.11.0 on, about 6 times on 8.11.0-9.10.0.
Mechanism, terms and numbers509 words
JoinUtil.createJoinQuery(fromField, multipleValuesPerDocument, toField, numericType, fromQuery, fromSearcher, scoreMode) with ScoreMode Max, Min, Avg or Total returns a package-private PointInSetIncludingScoreQuery. It keeps the join values as packed points and one float score per value in aggregatedJoinScores, as JoinUtil's javadoc says ("a float value per unique join value is kept in memory"). Its ramBytesUsed() adds the base object, the field name, the from query and the packed points, but not the score list.
With 5,000 join values it reports 16,504 bytes, only 976 more than the ScoreMode.None join of the same values (15,528), while it holds 37,224; the missing list alone is 21,368 bytes. LRUQueryCache charges this number for the query object of each cached join, so a cache holding such joins as filters holds more heap than its budget: from 9.11.0 on at most about 2.5 times, on 8.11.0 to 9.10.0 about 6 times. The string-key twin TermsIncludingScoreQuery counts its scores; both sums were written in the same commit (LUCENE-8855, first released in 8.2.0). The fix is one more term in the sum.
- Which class you get. The numeric overload (
JoinUtil.java:142-150) returnsnew PointInSetIncludingScoreQuery(...)whenscoreMode != ScoreMode.None(:155,:405-413), else aPointInSetQuery(:414-420). - What it keeps. The constructor appends each value to a
PrefixCodedTerms.Builderand its score to a newFloatArrayList(PointInSetIncludingScoreQuery.java:107-137;:134the value,:135the score). Both are final fields (:76,:81). Every search reads the list again (MergePointVisitor,:259), so it lives as long as the query, also while the query is a cache key. - What it reports. The constructor then caches
BASE_RAM_BYTES + sizeOfObject(field) + sizeOfObject(originalQuery, QUERY_DEFAULT_RAM_BYTES_USED) + sizeOfObject(sortedPackedPoints)(:141-146), whichramBytesUsed()returns (:380-383).aggregatedJoinScoresis not in the sum. - Counting it would be O(1).
FloatArrayListisAccountable(FloatArrayList.java:37,ramBytesUsed()at:388-390), andRamUsageEstimator.sizeOfObjectreturnsramBytesUsed()for anyAccountable(RamUsageEstimator.java:413). - Who consumes the number.
LRUQueryCachecharges each distinct cached queryRamUsageEstimator.sizeOf(query, 32)(LRUQueryCache.java:465-471,:994), which isramBytesUsed()for anAccountablequery (RamUsageEstimator.java:378-381). The weight is always cacheable (PointInSetIncludingScoreQuery.java:235-236), andUsageTrackingQueryCachingPolicycaches the class after 2 uses as a costly point query (UsageTrackingQueryCachingPolicy.java:33-53,:122-124). - No score-free path.
TermsIncludingScoreQueryswitches to aTermsQuerywhen scores are not needed (TermsIncludingScoreQuery.java:132-139); this class always returns its own weight (PointInSetIncludingScoreQuery.java:156-160), so a scoring numeric join used as a filter stays this object, with its list.
| part | counted by ramBytesUsed() | held |
|---|---|---|
| base object, field, from query | 1,128 | 168 |
packed join values (sortedPackedPoints) | 15,376 | 15,688 |
score list (aggregatedJoinScores, 5,000 floats in a float[5332]) | 0 | 21,368 |
| total | 16,504 | 37,224 |
With the fix the score list is counted too: 37,872 reported for 37,224 held (the 1.7% excess comes mostly from the 1,024-byte default estimate for the MatchAllDocsQuery from query, which holds 16 bytes, partly offset by the packed values being counted 312 bytes low).
Exposure and likelihood398 words
- Who is hit. Applications using the numeric
JoinUtiloverload (Integer, Long, Float or Double keys) with a scoringScoreMode, when they readramBytesUsed()or run the join where scores are not needed on a searcher with a query cache, often enough to be cached. The defaultLRUQueryCache(maxSize, maxRamBytesUsed)caches only segments of at least 10,000 documents that also hold more than half the average segment's documents (LRUQueryCache.java:251-253,:277-295).ScoreMode.Nonejoins and string-key joins are counted correctly. - Default vs opt-in. The wrong number appears for every scoring numeric join. The
IndexSearcherdefault cache is on in the 8.x, 9.x and 10.x lines and chargesramBytesUsed()since 8.11.0 (10.6.0:LRUQueryCache(1000, min(32 MB, max heap / 20))); on main it is off by default (GITHUB#14187,IndexSearcher.java:82-84), so there it needs an application-installed cache.JoinUtilis@lucene.experimental. - Scale. For large lists about 4 to 4.5 omitted bytes per join value (a float plus up to 1/8 growth slack; 21,368 bytes for 5,000 values, 4.27 per value). The under-count depends on how compactly the keys prefix-code: 2.26x for 5,000 sequential Integer keys, 2.43x for 20,000, 1.89x for 20,000 random Integer keys, 1.49x for 20,000 random Long keys. In 8.2.0 to 9.10.0 the list held boxed
Floats and the gap was larger (5.8x for the 5,000-value join on 9.10.0). - Fixed bound, from 9.11.0 on. For large lists each join value adds at least 3 counted bytes to the packed points and at most about 4.5 omitted bytes to the score list, so the omission alone lets a query hold at most about 2.5 times what it reports (the from query's own estimate is a separate matter), and a cache full of such keys hold at most about 2.5 times its budget in them, however many queries pass through it. The hunt's probe measured 2.29x the budget at worst on main and 2.39x on 10.5.2; the
ScoreMode.Nonecontrol held 1.01x what it was charged (at most 0.99x the budget). - Larger before 9.11.0. In 8.11.0 to 9.10.0 the list held boxed
Floats and the cache already chargedramBytesUsed(): on 8.11.0 the whole cache reports 64,240 bytes after caching a 20,000-value join that holds 381,712 (5.9x), so a cache full of such joins could hold about 6 times its budget. - Not affected. Which documents match and how they score: cached and uncached joins return the same hits.
The test shows that the scoring numeric join query from JoinUtil.createJoinQuery(..., Integer.class, ..., ScoreMode.Max) (PointInSetIncludingScoreQuery) leaves its per-value score list out of ramBytesUsed().
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.join;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.search.Query;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.RamUsageTester;
import org.apache.lucene.util.Accountable;

public class TestNumericScoreJoinRamBytesUsed extends LuceneTestCase {

  public void testRamBytesUsed() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        for (int i = 0; i < 5000; i++) {
          Document doc = new Document();
          doc.add(new NumericDocValuesField("from", i));
          w.addDocument(doc);
        }
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        Query q =
            JoinUtil.createJoinQuery(
                "from",
                false,
                "to",
                Integer.class,
                new MatchAllDocsQuery(),
                new IndexSearcher(reader),
                ScoreMode.Max);
        long retained = RamUsageTester.ramUsed(q);
        // expected: ramBytesUsed() within 5% of the retained heap (as in TestPointQueries)
        assertEquals((double) retained, (double) ((Accountable) q).ramBytesUsed(), retained / 20.d);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-402/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/join/build/libs/lucene-join-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.join.TestNumericScoreJoinRamBytesUsed
- Expected vs actual
- Expected
ramBytesUsed()within 5% of the heap RamUsageTester measures (37,224 bytes for 5,000 join values); actual 16,504 (expected:<37224.0> but was:<16504.0>), with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<37224.0> but was:<16504.0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:555)
       org.junit.Assert.assertEquals(Assert.java:685)
org.apache.lucene.search.join.TestNumericScoreJoinRamBytesUsed.testRamBytesUsed(TestNumericScoreJoinRamBytesUsed.java:56)Accountable#ramBytesUsedestimates the object's heap, andJoinUtil's javadoc says a scoring join keeps "a float value per unique join value".- The string-key twin
TermsIncludingScoreQuerycounts its scores; both sums come from the same commit (LUCENE-8855). - Upstream fixed a far smaller omission of the same kind in
PointInSetQueryas a bug (GITHUB#16405, 10.6.0).
The full argument196 words
- The contract.
Accountable#ramBytesUsed: "Returns an estimate of the JVM heap memory used by this object in bytes" (Accountable.java:35-40). The list is on the heap, created by the constructor, referenced only by the query, and its largest structure (21,368 of 37,224 bytes here; 32-59% in the measured cases). - The class's own docs say the floats exist. "when the scoreMode isn't set to
ScoreMode#Nonea float value per unique join value is kept in memory for computing scores" (JoinUtil.java:76-79); the numeric overload adds that "memory consumption might be higher" (:121-125). - The twin, same commit.
TermsIncludingScoreQuerysumssizeOfObject(scores)(TermsIncludingScoreQuery.java:81-89). Both sums were added ina76c962ee61f(LUCENE-8855): the string join got its scores, the numeric join did not. - Precedent. GITHUB#16405, "PointInSetQuery#ramBytesUsed now accounts for the retained lowerPoint and upperPoint bounds arrays" (
CHANGES.txt:761-762, Lucene 10.6.0), with a regression test (TestPointQueries.java:2636-2651) next to the 5%RamUsageTestertest (:2653-2668). - Tests and history. No join test mentions
ramBytesUsed; the sum has not changed since 2019 except for the LUCENE-9570 reformat (7f8b7ffbcad2); no comment, test, CHANGES or MIGRATE entry says the scores are left out on purpose.
The devil's-advocate check172 words
The intended-behaviour verifier built the strongest case: ramBytesUsed() is only an estimate and LUCENE-8855 accepted rough numbers; Accountable is @lucene.internal and JoinUtil @lucene.experimental; the join package tells users to choose ScoreMode.None when they do not need scores; and the open #16113 shows that Lucene has no settled rule for what an Accountable should count.
Why it fails: the LUCENE-8855 tolerance was about JVM layout differences and default sizes for unknown objects, and the same discussion asked to over-estimate rather than under-estimate for caches; here a whole owned structure, the largest one, is missing. Under any ownership rule #16113 proposes, a list the constructor allocates and only the query references belongs to the query. @lucene.experimental allows API changes, not wrong numbers, and the ScoreMode.None advice is about speed and memory, not a precondition. Both reading-only reviews rated the intended argument weak and the intended-behaviour check rejected each argument it tested; the later read-only fact check rated it moderate: enough for low priority and no backport, not enough to make the omission intended.
Recommended Count the score list in ramBytesUsed()
Add RamUsageEstimator.sizeOfObject(this.aggregatedJoinScores) to the sum in the constructor (PointInSetIncludingScoreQuery.java:141-146). FloatArrayList is Accountable, so this is O(1). The 5,000-value join then reports 37,872 bytes for 37,224 held; the test, TestJoinUtil and the whole join test module pass.
    this.ramBytesUsed =
        BASE_RAM_BYTES
            + RamUsageEstimator.sizeOfObject(this.field)
            + RamUsageEstimator.sizeOfObject(
                this.originalQuery, RamUsageEstimator.QUERY_DEFAULT_RAM_BYTES_USED)
            + RamUsageEstimator.sizeOfObject(this.sortedPackedPoints)
            + RamUsageEstimator.sizeOfObject(this.aggregatedJoinScores);
All options and trade-offs3 options · 369 words
One fix was built and checked; the other two items are an optional extra and a change that is not a fix.
One file, +2/-1 (the same change as the finder's): add the list as a fifth term of the sum the constructor caches.
    this.ramBytesUsed =
        BASE_RAM_BYTES
            + RamUsageEstimator.sizeOfObject(this.field)
            + RamUsageEstimator.sizeOfObject(
                this.originalQuery, RamUsageEstimator.QUERY_DEFAULT_RAM_BYTES_USED)
            + RamUsageEstimator.sizeOfObject(this.sortedPackedPoints)
            + RamUsageEstimator.sizeOfObject(this.aggregatedJoinScores);
Trade-offs
No correctness downside found; the cache charge for such joins grows to their real size, so a cache evicts them sooner, which is the point. sizeOfObject returns FloatArrayList.ramBytesUsed() once, in the constructor. The estimate includes the list's growth slack, which is real heap: 37,872 reported for 37,224 held with 5,000 values (1.7% over, within the 5% margin of upstream's RamUsageTester tests); 149,400 for 149,456 with 20,000 values.
What the checks validated
In a scratch worktree of 645d4fe14a20 with the test added and this change applied (seed DEADBEEF): the test passes with assertions on and off (stock: fails both); TestJoinUtil passes (16 tests); the whole :lucene:join:test passes with assertions on (17 classes, 105 tests, 0 failures, 3 skipped), where the same run without the fix has 1 failure, the test; :lucene:join:checkGoogleJavaFormat passes. The standalone runner with the fixed class passes with -ea and -da.
Call aggregatedJoinScores.trimToSize() (FloatArrayList.java:303) after the constructor's loop, so the query keeps exactly 4 bytes per value.
Trade-offs
Saves the growth slack: 332 of the 5,332 slots with 5,000 values, up to about 1/8 of the size for large lists and proportionally more for lists of a few values, where ArrayUtil.oversize adds at least 3 slots. Not needed for correct accounting. Not run.
A needsScores() == false path like TermsIncludingScoreQuery's (TermsIncludingScoreQuery.java:132-139) would return another query's weight when scores are not needed. The cache keys on the returned weight's query (IndexSearcher.java:976-982, LRUQueryCache.java:834-841), so this would likely keep this class and its list out of the cache.
Trade-offs
ramBytesUsed() would stay wrong for every caller that reads it: a possible separate change, not a substitute for the fix. Not run.
Of the downstream projects read, none reaches this path: Solr's score join builds the query per request and turns Lucene's query cache off, and Elasticsearch and OpenSearch use the global-ordinals join.
A hunt unit compared ramBytesUsed() with the heap that the test framework's RamUsageTester measures, for 26 public-API constructions of Accountable queries. It flagged the numeric Max join at 2.4x under while the ScoreMode.None join was within 2%; reading the constructor found the missing term, and a JUnit on the stock jars confirmed it.
The method in full152 words
Method: semi-formal (the hunt's tier for a systematic differential harness, short of model checking or proof).
- Differential. The harness built 26 public-API constructions of
Accountablequeries (12 query classes) from core, join and spatial3d and compared eachramBytesUsed()with theRamUsageTesterwalk, before and after a search through an always-cachingLRUQueryCache, with a knownAutomatonQueryunder-count (LFV-192) as positive control. 11 constructions were flagged more than 2x under; one was "JoinUtil numeric ScoreMode.Max" (61,560 vs 149,440, 2.4x) while "JoinUtil numeric ScoreMode.None" was 1.0x. - Trace. Reading
PointInSetIncludingScoreQuery's constructor showed the score list missing from the sum, next to the twinTermsIncludingScoreQuerythat counts its scores. - Confirmation. A JUnit on the stock jars (100,000 values) failed on main with assertions on and off, on 10.5.2 and on 9.12.3; the one-term fix made it pass. Independent verifiers then reproduced it with their own tests, and a 2026-10-29 minimisation cut it to 5,000 values.
No prior report found in apache/lucene issues, PRs and commits, the JIRA archive, the mailing lists, Elasticsearch, OpenSearch, Solr or the web (2026-10-26, refreshed 2026-10-31). The closest item is the fixed PointInSetQuery omission (#16405 / #16406).
Searches4 searches
Searches recorded in the follow-up, then a read-only refresh for this doc. Context, not reports: #9898 / LUCENE-8855 introduced the code (its discussion never mentions join scores); #16405 / #16406 fixed the same kind of omission in PointInSetQuery; the open #16113 / #16114 discuss Accountable ownership and do not name this class. Limits: keyword search only; inline PR review comments and private channels are not searchable.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; JIRA archive; dev@, java-user@, issues@, commits@; Elasticsearch, OpenSearch, Solr; web | 2026-10-26 | three scripted prior-report searches (51, 51 and 25 queries; 1,096, 1,042 and 88 hits screened): PointInSetIncludingScoreQuery, aggregatedJoinScores, TermsIncludingScoreQuery, JoinUtil, FloatArrayList, ramBytesUsed, sizeOfObject, LRUQueryCache, LUCENE-8855, "score join", under-reports | no report; 23 items read, none the same bug |
| GitHub (manual), mailing lists, JIRA, web | 2026-10-26 | 21 GitHub, 16 list, 8 JIRA and 7 web queries | no report |
| Open apache/lucene PRs | 2026-10-26 | changed files of all 413 open PRs | only #16847 touches the file, in scorerSupplier, not ramBytesUsed |
| apache/lucene issues and PRs, upstream main and branch_10_6 | 2026-10-31 | PointInSetIncludingScoreQuery, aggregatedJoinScores, "join ramBytesUsed", "JoinUtil ramBytesUsed"; changed files of the 53 open PRs updated since 2026-10-26; file contents | only older unrelated items (#13745, #9053, #11793, #8332, #8861); no PR touches the file; main 2f424fd428da and branch_10_6 unchanged |
Introduced in 8.2.0 by LUCENE-8855 (2019), which made the class Accountable without the score list; the query cache charges it since 8.11.0 / 9.0.0 (LUCENE-10103). Every release from 8.2.0 to 10.6.0 and main is affected; 8.1.1 has no ramBytesUsed().
Versions tested8 rows
Introduced by a76c962ee61f (2019-06-26, "LUCENE-8855: Add Accountable to some Query implementations."; CHANGES credits "ab, Adrien Grand"; a JIRA patch, migrated as #9898) on main, backported to branch_8x as 81208427d25f, first released in 8.2.0. The same diff counted TermsIncludingScoreQuery's scores. Not a regression: the sum was incomplete from the start.
Later changes moved the size and the reach, not the bug. LUCENE-10103 (6a41bc6310e, 8.11.0 and 9.0.0) made LRUQueryCache charge ramBytesUsed(); before it, the cache charged a flat amount per query. #13406 (444d4e7c42b, first released in 9.11.0) replaced the List<Float> by FloatArrayList, so the omitted part shrank (6.20x to 2.43x on the same 20,000 values). Not fixed upstream as of 2026-10-31.
| Version or commit | Verdict | Result |
|---|---|---|
| 8.1.1 | API absent | the query is not Accountable |
| 8.2.0, 8.8.1, 8.8.2, 8.9.0, 8.10.0, 8.10.1 | no cache charge | 20,000 values: 61,560 reported vs 381,712 held (6.20x); the cache charges a flat amount per query |
| 8.11.0-8.11.4, 9.0.0 | affected | 6.20x, and the cache under-charges |
| 9.1.0, 9.10.0 | affected | the minimal test fails; 9.10.0: 95,928 held vs 16,504 reported for 5,000 values |
| 9.11.0, 9.12.3, 10.0.0 | affected | FloatArrayList: 2.26x for 5,000 values (9.11.0, 9.12.3), 2.43x for 20,000 (10.0.0: 20,000 values only) |
| 10.5.2, 10.6.0 | affected | the minimal test fails |
main 645d4fe14a20 | affected | fails through gradle and the standalone runner, assertions on and off; passes with the fix |
upstream main 2f424fd428da, branch_10_6 (2026-10-31) | read | the four-term sum (no score list) is unchanged |
Confirmed by an independent reproducer, a devil's-advocate verifier, a reviewer from another model family (OpenAI GPT-5.6) and an adjudication, then re-run by a credibility audit, the minimisation and this doc's gradle run. The only dissent was a procedural "not real" from a read-only review that could not run code.
Checks and verdicts292 words
Each check ran or read independently; the paths name its record.
| Check | Verdict | What it found |
|---|---|---|
| Finder (RAM differential, then JUnit) | candidate | Its JUnit (100,000 values) fails on main with assertions on and off, 10.5.2 and 9.12.3: 304,248 reported vs 710,632 held; the fix passes it and upstream TestJoinUtil (16 of 16). |
| Refute review (OpenAI GPT-5.6, read-only) | not real (procedural, low) | Could not run code; agrees on the root cause and that the inputs are in contract; no substantive refutation. A separate re-run fails. |
| Independent reproducer | real | Own 5% RamUsageTester test fails 2 of 2 on main, 10.5.2 and 9.12.3 (61,560 vs 149,456; None 1.017); random Integer and Long keys 1.89x and 1.49x; the fix brings the estimate within 0.04% (149,400 vs 149,456). |
| Works-as-designed lens (OpenAI GPT-5.6, read-only) | real (medium) | Rates the intended argument weak; separate re-runs fail. |
| Intended-behaviour devil's advocate | real (high) | Rejected six intended, misuse and reachability arguments; with the default caching policy the 100,000-value join is cached and charged 304,408 bytes while it holds 710,632. |
| Adjudication | confirmed (high), class minor | Re-ran the independent reproduction's test (fails with assertions on and off; passes with the fix); asked to state 1.5x to 2.4x, not "less than half". |
| Credibility audit | keep | Re-ran the independent reproduction's test: fails 2 of 2, passes with the fix; impact minor confirmed. |
| Minimisation | verified | 5,000 values, RamUsageTester within 5%: fails on 645d4fe14a20 (37,224 vs 16,504), passes with the fix, standalone runner. |
| This doc's runs (2026-10-31) | reproduced; fix validated | The public-API test fails through gradle and standalone and on six release lines; the fix passes it and the join module. Found that the RamUsageTester oracle cannot run in the join module's gradle tests. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 580 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,431 words
- Registry title
- PointInSetIncludingScoreQuery.ramBytesUsed() leaves out its per-value score list, so scoring numeric JoinUtil joins (ScoreMode Max, Min, Avg, Total) under-report their heap (1.5x-2.4x on 9.11.0 and later, 6.2x or more in 8.2.0-9.10.0) and LRUQueryCache under-charges them (since 8.2.0)
- Area
- join / JoinUtil numeric query-time join RAM accounting (PointInSetIncludingScoreQuery, Accountable#ramBytesUsed; core LRUQueryCache RAM budget)
- Priority
- Low, rank 732: Scoring numeric JoinUtil joins under-report ramBytesUsed() by about 1.5x to 2.4x so LRUQueryCache under-charges them, a bounded RAM-accounting defect like LFV-400 and LFV-192.
- Impact class
- minor
- Impact note
- Applications that build a numeric JoinUtil join (the createJoinQuery overload with a NumberType) with ScoreMode Max, Min, Avg or Total and use it where scores are not needed (filter, MUST_NOT, ConstantScoreQuery, count) on a searcher with a query cache (the IndexSearcher default in 8.11-10.6.0; application-installed on main, where caching is off by default) are hit: every such query leaves out the one float per join value it keeps (about 4 to 4.5 bytes per value), so ramBytesUsed() is 1.5x-2.4x too low on 9.11.0 and later (6.2x or more in 8.2.0-9.10.0, when the list held boxed Floats) and the cache can hold at most about 2.5 times its maxRamBytesUsed in such keys (measured 2.29x on main and 2.39x on 10.5.2 with the worst-case keys), a fixed bound; hits are always correct, ScoreMode.None joins are accounted correctly, and no extreme scale is needed (100,000 join values: 304,248 bytes reported, 710,632 retained).
- Summary
- You build a numeric query-time join with JoinUtil.createJoinQuery(fromField, multipleValuesPerDocument, toField, numberType, fromQuery, fromSearcher, ScoreMode.Max) (or Min, Avg, Total) and expect its ramBytesUsed() to estimate the heap the query holds, which is what Accountable promises, what LRUQueryCache charges against maxRamBytesUsed, and what the string-field scoring join (TermsIncludingScoreQuery) and the ScoreMode.None numeric join (PointInSetQuery) do. Instead the PointInSetIncludingScoreQuery it returns adds up only its base object, field, from-query and packed join values, and leaves out aggregatedJoinScores, the FloatArrayList with one float per join value that its constructor fills: with 100,000 join values it reports 304,248 bytes while it retains 710,632 (2.3x; 1.5x-2.4x depending on how compactly the keys prefix-code), against 303,272 vs 304,544 for ScoreMode.None. A query cache holding such a join as a filter charges it the same low number (304,408 bytes charged, 710,632 retained), so the cache can hold up to about 2.5 times its budget in these keys; the matching documents are correct.
- Introduced
- a76c962ee61f5185d30ff5bd94a23c16d21a5a98 (main, then master, first released in 9.0.0; branch_8x backport 81208427d25f4541957eeeb03d971e1c45226428, first released in 8.2.0), LUCENE-8855 'Add Accountable to some Query implementations' (a JIRA patch by GitHub sigram, reviewed by jpountz; no pull request; migrated issue apache/lucene#9898): it made PointInSetIncludingScoreQuery Accountable with ramBytesUsed = BASE_RAM_BYTES + field + originalQuery + sortedPackedPoints and never added the score list that the same constructor fills, while the same commit counted TermsIncludingScoreQuery's scores array [read: git blame on main's lines 141-146 points only to this commit and the LUCENE-9570 reformatting 7f8b7ffbcad; git log -G ramBytesUsed on the file lists only those two] [exec: 8.1.1 has no Accountable on the class; 8.2.0 fails]. A branch_8_1 copy (5dfdc3029b2) was reverted the next day (edea7ebfbfb), so no 8.1.x release has it. Present since the method was written; not a regression of later work (2019-06-26)
- First affected version
- 8.2.0 [exec] (8.1.1 and earlier: the query is not Accountable and has no ramBytesUsed() [exec: API absent]). The query-cache consequence starts in 8.11.0 and 9.0.0 (LUCENE-10103, apache/lucene#346, 6a41bc6310e: LRUQueryCache charges Accountable queries their ramBytesUsed()); in 8.2.0-8.10.x the cache charged a flat amount per query whatever the query [exec: 3,648 / 3,704 bytes for the None / Max join on 8.10.1], so there the wrong value reached only direct callers of ramBytesUsed()
- Affected versions
- 8.2.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.6.0 (10.6.0 by reading) and main ea57360912ed. [exec, every one fails the 5% RamUsageTester check while the ScoreMode.None control is at 1.017-1.018]: 8.2.0, 8.8.1, 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0-8.11.4, 9.0.0, 9.10.0, 9.11.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da); the finder's JUnit also fails on 10.5.2 and 9.12.3. [read]: 8.3.0-8.7.0, 8.8.0, 9.1.0-9.9.2, 9.11.1, 9.12.0-9.12.2, 10.1.0-10.5.1 (each tag implements Accountable and leaves the list out). Size [exec, 20,000 sequential Integer values]: 6.20x in 8.2.0-9.10.0 (List<Float> of boxed Floats; a lower bound) and 2.43x from 9.11.0 (FloatArrayList since apache/lucene#13406); on main random Integer keys give 1.89x and random Long keys 1.49x. Not fixed upstream: upstream main cf398bfb142 (2026-10-26) still sums only field, originalQuery and sortedPackedPoints, the last commit touching the file is ce50d3a135d (2025-02-24), and branch_10x and branch_10_6 were unfixed at the prior-art check (2026-10-26). Executed only on aarch64 Linux with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (2026-10-26, the prior-report record verdict new; all read-only): three scripted prior-report searches (51, 51 and 25 queries over apache/lucene issues, PRs and commits, the Elasticsearch, OpenSearch and Solr repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and 6 web queries; 1,096, 1,042 and 88 hits screened), 18 manual GitHub, 3 downstream, 16 mailing-list, 8 JIRA and 8 web queries, the changed files of the open module:join PRs and of all 413 open apache/lucene PRs, and the file's history; 23 items recorded, all same_bug false. Not fixed: upstream main cf398bfb142 (2026-10-26) still leaves aggregatedJoinScores out of ramBytesUsed (re-checked), and the only open PR touching the file (#16847) changes scorerSupplier, not ramBytesUsed. Closest items, not this bug: #9898 / LUCENE-8855 (introduced the code; none of its comments mentions join queries or scores), #16405 / #16406 (PointInSetQuery#ramBytesUsed omitted its retained bounds arrays, fixed as a bug in 2026-07: precedent), #16113 / #16114 (open; Accountable ownership semantics and double counting of shared state such as GlobalOrdinals*Query's OrdinalMap; this class is not named), #15097 / #15124, #12614, #16657, #15026 and #16743 (other accounting paths), #16378 (numeric join score precision; never mentions ramBytesUsed). Gaps: GitHub's search rate limit was reached (rate-limited queries were retried until they returned), the broad 'ramBytesUsed' GitHub query was truncated at 50 of 113 hits, inline PR review comments are not indexed, and private security@ reports are invisible
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off, through gradle in a scratch worktree and through a standalone runner; with the recommended fix it passes, together withTestJoinUtiland the whole join test module. Release jars: the test fails on 9.1.0, 9.10.0, 9.11.0, 9.12.3, 10.5.2 and 10.6.0. The follow-up's history runs (the independent reproduction's measured-heap test, and an older port of it for 8.x and 9.0.0) ran on 20 targets from 8.1.1 (noramBytesUsed()) to 10.5.2 (all affected from 8.2.0); the other release tags were read from source. Only OpenJDK 25.0.3 on Linux aarch64 was used.
- Finding record
lucene/join/src/java/org/apache/lucene/search/join/PointInSetIncludingScoreQuery.java:54 (implements Accountable), :81 (final FloatArrayList aggregatedJoinScores), :107 and :135 (filled with one float per join value), :141-146 (ramBytesUsed = BASE_RAM_BYTES + field + originalQuery + sortedPackedPoints), :235-236 (isCacheable returns true) @ ea57360912edlucene/join/src/java/org/apache/lucene/search/join/TermsIncludingScoreQuery.java:81-89 (ramBytesUsed includes sizeOfObject(scores)) and lucene/join/src/java/org/apache/lucene/search/join/JoinUtil.java:76-79 ('a float value per unique join value is kept in memory' when scoreMode isn't None) @ ea57360912edlucene/core/src/java/org/apache/lucene/util/Accountable.java:35-40 ('Returns an estimate of the JVM heap memory used by this object in bytes') and lucene/core/src/java/org/apache/lucene/internal/hppc/FloatArrayList.java:37, :388-389 (Accountable; ramBytesUsed includes the buffer) @ ea57360912edlucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:468-471 (queryRamBytesUsed = RamUsageEstimator.sizeOf(query, 32)), lucene/core/src/java/org/apache/lucene/util/RamUsageEstimator.java:378-381 (returns ramBytesUsed() for an Accountable query), lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:82-84 (caching disabled by default on main) and lucene/CHANGES.txt:325 (GITHUB#14187) @ ea57360912ed (from the security record and the verifier write-ups)
- The finding in 30 seconds
lucene/join/src/java/org/apache/lucene/search/join/JoinUtil.java:142-150, :155, :405-420 @ 645d4fe14a20lucene/join/src/java/org/apache/lucene/search/join/PointInSetIncludingScoreQuery.java:76, :81, :107-137, :141-146, :156-160, :235-236, :259, :380-383 @ 645d4fe14a20lucene/core/src/java/org/apache/lucene/internal/hppc/FloatArrayList.java:37, :388-390; lucene/core/src/java/org/apache/lucene/util/RamUsageEstimator.java:80 (QUERY_DEFAULT_RAM_BYTES_USED = 1024), :378-381, :413; lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:465-471, :994; lucene/core/src/java/org/apache/lucene/search/UsageTrackingQueryCachingPolicy.java:33-53, :122-124 @ 645d4fe14a20lucene/join/src/java/org/apache/lucene/search/join/TermsIncludingScoreQuery.java:132-139 @ 645d4fe14a20
- Who is affected
lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:251-253; lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:82-84; lucene/CHANGES.txt:343 (GITHUB#14187) @ 645d4fe14a20lucene/join/src/java/org/apache/lucene/search/join/JoinUtil.java:54 (@lucene.experimental) @ 645d4fe14a20
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/util/Accountable.java:30, :35-40 @ 645d4fe14a20lucene/join/src/java/org/apache/lucene/search/join/JoinUtil.java:76-79, :121-125 @ 645d4fe14a20; lucene/join/src/java/org/apache/lucene/search/join/package-info.java:77-80lucene/CHANGES.txt:761-762 (GITHUB#16405, Lucene 10.6.0); lucene/core/src/test/org/apache/lucene/search/TestPointQueries.java:2636-2651, :2653-2668 @ 645d4fe14a20
- Suggested fix
lucene/core/src/java/org/apache/lucene/internal/hppc/FloatArrayList.java:303 (trimToSize); lucene/join/src/java/org/apache/lucene/search/join/TermsIncludingScoreQuery.java:132-139 @ 645d4fe14a20lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:976-982; lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:834-841; lucene/core/src/java/org/apache/lucene/util/ArrayUtil.java:157-163 @ 645d4fe14a20
- TestNumericScoreJoinRamBytesUsed.java (JUnit test):
repro/LFV-402/src/org/apache/lucene/search/join/TestNumericScoreJoinRamBytesUsed.java(60 lines)
Made in parallel with this doc from the same 5,000-value probe on main 645d4fe14a20; frame notes are in the diagram's README.
assets/LFV-402/bug.png(580 KB)