SortingCodecReader.wrap(reader, docMap, null)presents a segment's documents in a new order;addIndexesthen writes them in that order. The reader is meant only for merging.BPReorderingMergePolicyreorders the segments its merges write,addIndexesincluded, with a pluggable reorderer: the postingsBPIndexReordereror the vectorBpVectorReorderer.- A field's vector values number their vectors with ordinals;
copy()returns an independent view of them, whichBpVectorReordererneeds once per thread.
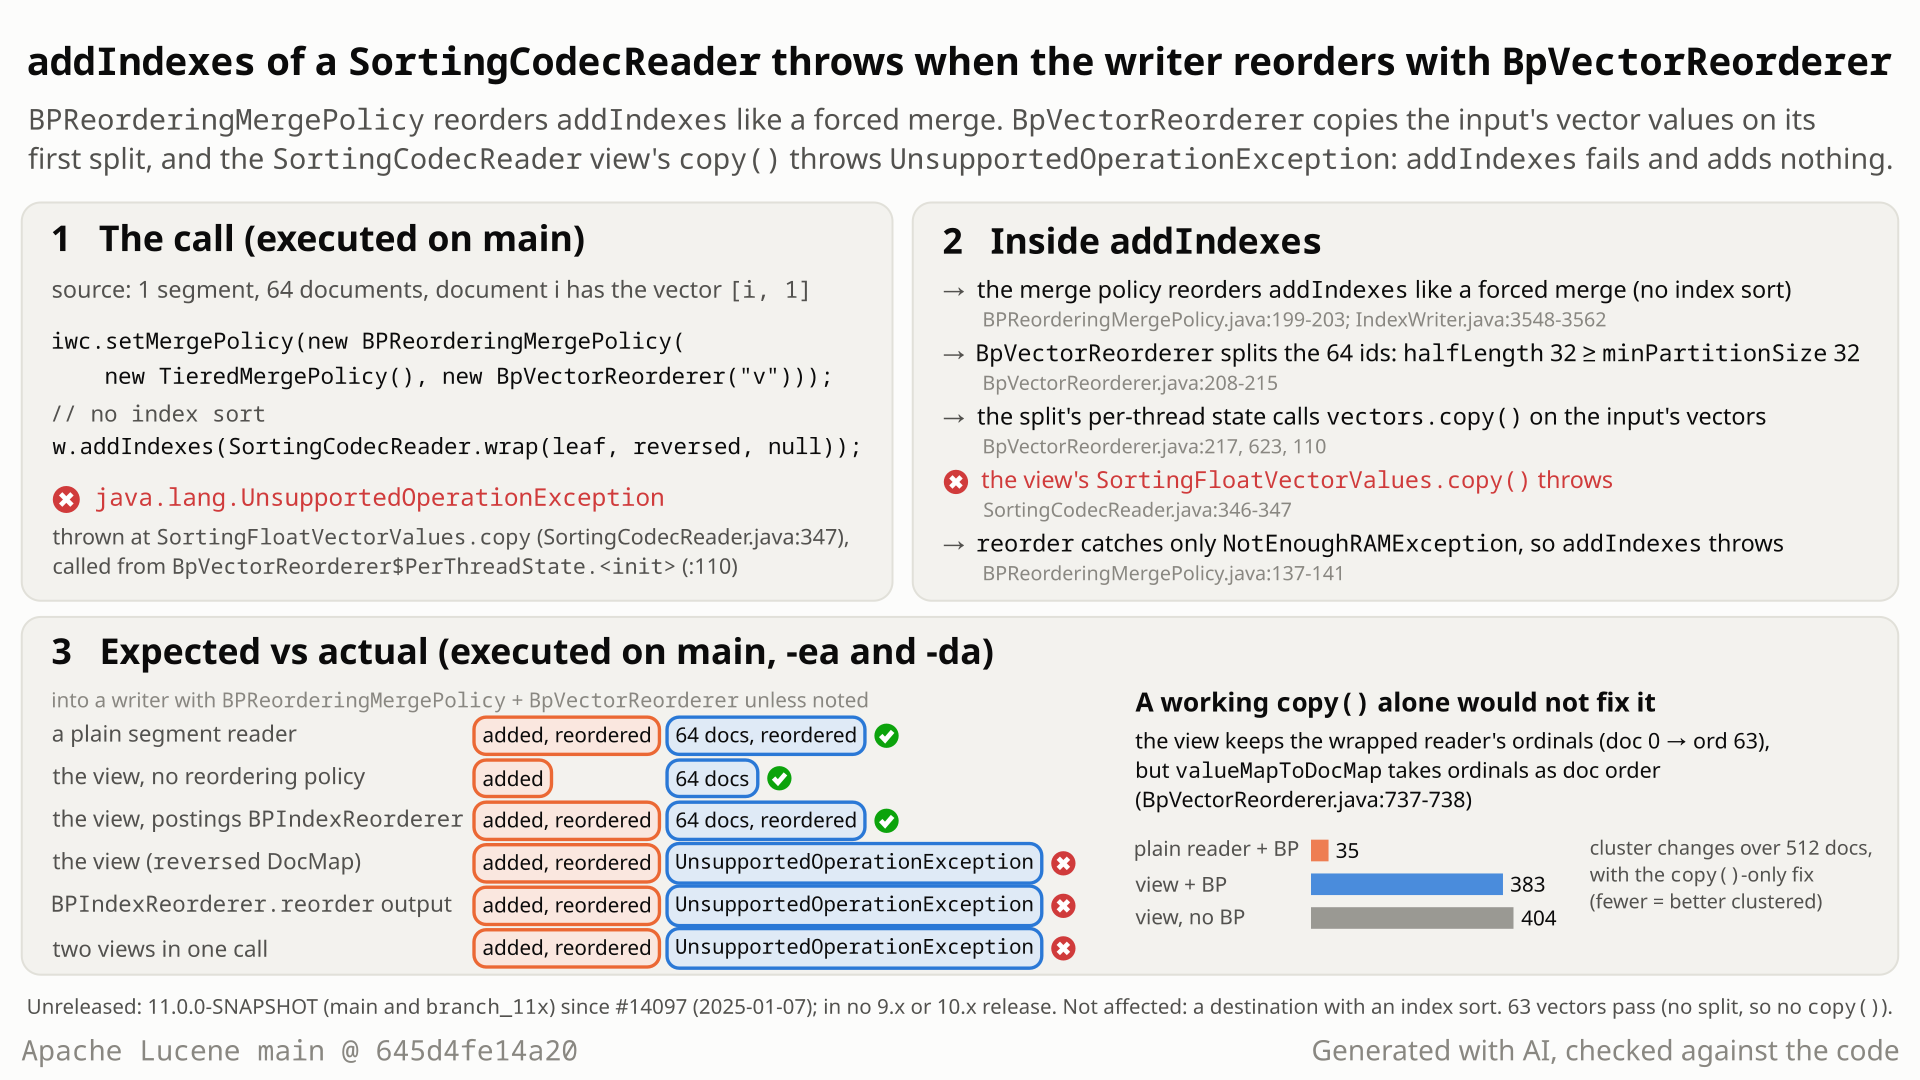
SortingCodecReader of 64 vectors goes into addIndexes, the policy hands it to BpVectorReorderer, and its per-thread copy() throws; then expected vs actual, and why a copy()-only fix moves the wrong documents. Select the still to open it at full size. Generated with AI, checked against the code.- Index 64 documents with a 2-dimensional vector field
v, then wrap the segment withSortingCodecReader.wrap(leaf, docMap, null), using a doc map that reverses it (doc 0 becomes doc 63).BPIndexReorderer.reorderreturns a reader of this kind and says to pass it toaddIndexes. - Call
addIndexeson a writer withnew BPReorderingMergePolicy(new TieredMergePolicy(), new BpVectorReorderer("v"))and no index sort. You expect the 64 documents to be added and reordered by their vectors, as happens for a plain segment reader, and for this reader with the postingsBPIndexReorderer. - Instead
addIndexesthrowsUnsupportedOperationExceptionand adds 0 documents. The policy reordersaddIndexeslike a forced merge; from 64 vectors on (twice the default minimum partition size of 32)BpVectorReordererasks the vectors for acopy(), andSortingCodecReader's vector views throw fromcopy(). - The writer stays open and the index is unchanged. A
copy()-only fix is a trap: the reorderer then reads the view's vector ordinals as doc order and moves the wrong documents (0 of 512 positions right in a probe).
Only code on main or branch_11x (unreleased 11.0.0) that uses the opt-in BPReorderingMergePolicy with BpVectorReorderer on a writer without an index sort, and passes a SortingCodecReader with 64 or more vectors to addIndexes. Then every such call fails. A destination with an index sort is not affected.
Mechanism, terms and numbers567 words
IndexWriter#addIndexes(CodecReader...) of a SortingCodecReader into a writer whose merge policy is BPReorderingMergePolicy with a BpVectorReorderer, and that has no index sort, throws UnsupportedOperationException and adds nothing. The policy reorders addIndexes as a forced merge; BpVectorReorderer copies the input's float vector values for its per-thread state on the first split (from 64 FLOAT32 vectors with default settings); SortingCodecReader's vector views throw from copy(). The reader from the documented BPIndexReorderer.reorder -> addIndexes recipe hits it when added to such a writer, while the postings BPIndexReorderer accepts the same input under the same policy. The failure is clean (writer open, not tragic, index unchanged). Making copy() work is not enough: BpVectorReorderer.valueMapToDocMap then reads the view's ordinals as doc order, so the reorder is applied to the wrong documents. Main and branch_11x only, since #14097 (2025-01-07); no release is affected.
BPReorderingMergePolicy.findMerges(CodecReader...): "addIndexes is considered a forced merge" (BPReorderingMergePolicy.java:199-203), with no minimum size (:103-105).IndexWriter.addIndexesReaderMergeskips reordering only if the destination has an index sort (or blocks without a parent field), and otherwise callsmerge.reorder(SlowCompositeCodecReaderWrapper.wrap(readers), ...)(IndexWriter.java:3548-3562). With one input,wrapreturns the input itself (SlowCompositeCodecReaderWrapper.java:49-58).BpVectorReorderer.computeDocMaptakesreader.getFloatVectorValues(field)(BpVectorReorderer.java:590) and bisects the ordinal range. A range is split only if each half holds at leastminPartitionSizevectors (:208-211, default 32), so with the default from 64 vectors on (a missing or non-FLOAT32 field returns null first,:586-589,:699-724). The first split creates the thread's state (:217,:619-624), and its constructor callsvectors.copy()(:108-111).SortingCodecReader'sSortingFloatVectorValues.copy()isthrow new UnsupportedOperationException()(SortingCodecReader.java:346-347; byte:393-394and float16:436-437likewise, latent becauseBpVectorReordererhandles FLOAT32 only). With several inputs the merged view'scopy()copies each input (SlowCompositeCodecReaderWrapper.java:306-307,:903-909) and reaches the same throw.- The policy catches only
NotEnoughRAMException(BPReorderingMergePolicy.java:136-141);addIndexesrethrows the merge's exception (IndexWriter.java:3380-3382), and only anErrorwould be tragic (:3390-3392). The reorder (:3562) runs before theSegmentMergeris created (:3568), so nothing is written.
BpVectorReorderer.valueMapToDocMap (BpVectorReorderer.java:735-789) returns the ordinal permutation itself as the doc map when every document has a vector (:737-739), and otherwise numbers ordinals by position in doc order (:744-764). A SortingCodecReader view keeps the wrapped reader's ordinals: its iterator's index() "may skip around, not increasing monotonically as iteration proceeds" (SortingCodecReader.java:264-266), and vectorValue(ord) reads in the delegate's ordinal space (:323-327). So once copy() works, the permutation computed over the vectors is applied to other documents.
- 64 documents, 2-dimensional vectors
{i, 1}, one reversingSortingCodecReader:addIndexesthrows, 0 documents added, with assertions on and off, 20 of 20 random seeds. With 63 documents nothing is split and nothing throws. - The same failure for the reader
BPIndexReorderer.reorder(leaf, dir, null)returns, forSortingCodecReader.wrap(leaf, Sort)into a writer without an index sort, with the defaultConcurrentMergeScheduler, and for two 32-document sorting readers in one call. - With only
copy()fixed, a 512-vector index wrapped by a reversing view gets a doc map equal to the plain reader's at 512 of 512 positions and to the correctly re-based map at 0 of 512; cluster changes in doc order after BP: 383 (plain reader with BP: 35; no BP: 404).
Exposure and likelihood245 words
- Who is exposed. Applications that combine
BPReorderingMergePolicy(..., new BpVectorReorderer(field))(lucene/misc, opt-in), a destination without an index sort (and not the document-blocks caseIndexWriteralso skips,IndexWriter.java:3550-3556), andaddIndexeswith aSortingCodecReaderinput:SortingCodecReader.wrap(reader, Sort),wrap(reader, docMap, null), or the output ofBPIndexReorderer.reorder(its documented recipe). For example, an offline postings-BP pass whose output is added to a writer that also reorders by vectors, or a re-sort or rewrite job feeding such a writer. - What it takes. At least 64 FLOAT32 vectors in the reordered field across the call's inputs (two times the default
minPartitionSizeof 32). Default settings, ordinary data,SerialMergeSchedulerorConcurrentMergeScheduler. No scale is needed. With several inputs, one without vectors for the field may hit aNullPointerExceptionin the merged view'scopy()instead (LFV-269). - Not affected. A destination with an index sort (IndexWriter then skips the reorder); plain segment readers; the postings
BPIndexReorderer; every release (the class is on main andbranch_11xonly). - What the user sees. A clean, unchecked
UnsupportedOperationException(no message) fromaddIndexes, within milliseconds. Nothing is added, nothing is lost; the writer stays open and is not tragic. - Workarounds. Give the destination an index sort, write the sorted index first and add plain segment readers, or do not use the vector reorderer on that writer.
- How likely. Rare: the combination reorders the data twice, because the vector reorder discards the order the
SortingCodecReaderprovides. Once on that path, it fails on every call.
One JUnit test in the misc module, public API only: 64 two-dimensional vectors in one segment, a reversing SortingCodecReader, and one addIndexes call into a writer with BPReorderingMergePolicy and BpVectorReorderer. Single thread, deterministic; it fails with assertions on and off and passes with the fix.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.misc.index;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.KnnFloatVectorField;
import org.apache.lucene.index.CodecReader;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.SerialMergeScheduler;
import org.apache.lucene.index.Sorter;
import org.apache.lucene.index.SortingCodecReader;
import org.apache.lucene.index.TieredMergePolicy;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestBpVectorReorderSortingCodecReader extends LuceneTestCase {

  public void testAddIndexesOfSortingCodecReader() throws IOException {
    try (Directory source = new ByteBuffersDirectory();
        Directory target = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(source, new IndexWriterConfig())) {
        for (int i = 0; i < 64; i++) {
          Document doc = new Document();
          doc.add(new KnnFloatVectorField("v", new float[] {i, 1}));
          w.addDocument(doc);
        }
      }
      IndexWriterConfig iwc =
          new IndexWriterConfig()
              .setMergePolicy(
                  new BPReorderingMergePolicy(new TieredMergePolicy(), new BpVectorReorderer("v")))
              .setMergeScheduler(new SerialMergeScheduler());
      try (DirectoryReader reader = DirectoryReader.open(source);
          IndexWriter w = new IndexWriter(target, iwc)) {
        Sorter.DocMap reversed =
            new Sorter.DocMap() {
              @Override
              public int oldToNew(int docID) {
                return 63 - docID;
              }

              @Override
              public int newToOld(int docID) {
                return 63 - docID;
              }

              @Override
              public int size() {
                return 64;
              }
            };
        CodecReader leaf = (CodecReader) getOnlyLeafReader(reader);
        try {
          w.addIndexes(SortingCodecReader.wrap(leaf, reversed, null));
        } catch (UnsupportedOperationException e) {
          throw new AssertionError(
              "expected addIndexes to add (and reorder) the 64 documents, got " + e, e);
        }
      }
    }
  }
}
cd $LUCENE   # an apache/lucene checkout at 645d4fe14a20 (or a later main / branch_11x)
cp $REPRO/TestBpVectorReorderSortingCodecReader.java lucene/misc/src/test/org/apache/lucene/misc/index/
./gradlew :lucene:misc:test --tests org.apache.lucene.misc.index.TestBpVectorReorderSortingCodecReader -Ptests.seed=5EED0404
# assertions off: add -Ptests.asserts=false
- Expected
addIndexesadds the 64 documents, reordered by their vectors.- Observed
UnsupportedOperationExceptionfromSortingFloatVectorValues.copy(), called byBpVectorReorderer's per-thread state; 0 documents added.
More files, environment, full output203 words
Put the file in lucene/misc/src/test/org/apache/lucene/misc/index/ (the package of the upstream BP tests) and run the command. The formatter leaves it unchanged. 64 is the smallest input that reaches the throw (63 vectors are never split); the reversing doc map has the shape BPIndexReorderer.reorder returns, without needing postings; SerialMergeScheduler keeps everything in the test thread. The AssertionError states expected vs actual and keeps the cause. The same test is the suggested regression test; it does not check the doc-space half of the fix (see Suggested fix).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): affected; upstream main and branch_11x are unchanged in these files; no release has BpVectorReorderer (10.6.0, 10.5.2: the test does not compile) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
# stock 645d4fe14a20, the env command, seed 5EED0404; the same with -Ptests.asserts=false
TestBpVectorReorderSortingCodecReader > testAddIndexesOfSortingCodecReader FAILED
    java.lang.AssertionError: expected addIndexes to add (and reorder) the 64 documents, got java.lang.UnsupportedOperationException
        at org.apache.lucene.misc.index.TestBpVectorReorderSortingCodecReader.testAddIndexesOfSortingCodecReader(TestBpVectorReorderSortingCodecReader.java:74)
        Caused by:
        java.lang.UnsupportedOperationException
            at org.apache.lucene.index.SortingCodecReader$SortingFloatVectorValues.copy(SortingCodecReader.java:347)
            at org.apache.lucene.misc.index.BpVectorReorderer$PerThreadState.<init>(BpVectorReorderer.java:110)
            at org.apache.lucene.misc.index.BpVectorReorderer$1.initialValue(BpVectorReorderer.java:623)
            at org.apache.lucene.util.CloseableThreadLocal.get(CloseableThreadLocal.java:70)
            at org.apache.lucene.misc.index.BpVectorReorderer$ReorderTask.compute(BpVectorReorderer.java:217)
            at org.apache.lucene.misc.index.BpVectorReorderer.computeDocMap(BpVectorReorderer.java:591)
            at org.apache.lucene.misc.index.BPReorderingMergePolicy$1.reorder(BPReorderingMergePolicy.java:138)
            at org.apache.lucene.index.IndexWriter.addIndexesReaderMerge(IndexWriter.java:3562)
            at org.apache.lucene.index.IndexWriter.addIndexes(IndexWriter.java:3312)
1 test completed, 1 failed

# with the recommended fix: the same command, with and without assertions
:lucene:misc:test (SUCCESS): 1 test

# (some frames and the module prefixes are left out)- Both
SortingCodecReaderandBPIndexReorderer.reorderdocument passing such a reader toaddIndexes; the failure is inside that merge. - The postings
BPIndexReordereraccepts the same input under the same policy, which #14097 opened to either reorderer. copy()throws on purpose (#13779), for views read only by iteration; #16705 fixed the same throw in another wrapper.
The full argument259 words
- Contracts.
SortingCodecReader(SortingCodecReader.java:47-52): re-sort an index "by wrapping all readers of the index with this reader and adding it to a fresh IndexWriter viaIndexWriter#addIndexes(CodecReader...). NOTE: This reader should only be used for merging."BPIndexReorderer.reorder(BPIndexReorderer.java:825-842): the returned reader "should typically be used in a call toIndexWriter#addIndexes(CodecReader...)"; its class example ends inw.addIndexes(reorderedReaderView)(:73-89).IndexReorderer.computeDocMaptakes anyCodecReader(IndexReorderer.java:25-35). The policy "simply skips reordering in order not to fail the merge" when RAM is short (BPReorderingMergePolicy.java:34-37). - Tests.
TestBPReorderingMergePolicyrandomly plugsBpVectorReordererinto the policy, includingtestReorderOnAddIndexes(:49-57,:147-148), but only withSlowCodecReaderWrapperinputs (:189). No test, javadoc, CHANGES or MIGRATE entry excludesSortingCodecReaderinputs. - History. #13779 (
6053e1e3137, 2024-09-28, by msokolov) made the sorting views'copy()throw on purpose; its body relies "on testing to catch missing required methods", because "some of these readers would only ever be used iteratively", and a review comment by benwtrent asked that sub-classes "purposefully indicate that this is unsupported" (oncreateIterator(), about the pattern in general, not oncopy()). #14097 (02a09f6ab12, 2025-01-07, same author) added the copyingBpVectorReordererand "refactored to make BpVectorReorderer compatible with BPIndexReorderer so that either can plug into BPReorderingMergePolicy"; none of its comments mentioncopy(),SortingCodecReaderoraddIndexes. - Precedent. #16705 (by goankur, merged 2026-10-01) replaced the throwing
copy()ofExitableDirectoryReader's vector views with a delegating copy because a new consumer needed one; the same commit editedSortingCodecReader.javaand left itscopy()throwing. - Framing.
The devil's-advocate check169 words
Strongest case for "intended or harmless": the throw is deliberate (#13779); SortingCodecReader is @lucene.experimental and "should only be used for merging"; and the combination is pointless, because the vector reorder throws away the order the caller just built, so a user who wants vector BP should pass plain readers.
Why it fails: this is merging, the documented use, with the documented output of BPIndexReorderer.reorder. #13779's own rationale expects a method that a real consumer needs to be caught and filled in, and #14097, by the same author, says either reorderer should plug into the policy; the postings reorderer accepts the same input. For a reorder it cannot afford (not enough RAM) the policy skips the reorder rather than fail the merge; that rule is about RAM only, and nothing documents what should happen when the reorderer cannot read an input. Redundancy lowers the likelihood (rare), but it does not make an exception from an accepted call correct. Verdict: a defect. Expect the "why reorder twice?" question in review.
Recommended A: make copy() work and map ordinals through the iterator
Make the sorting views' copy() return a view over delegate.copy() that shares the immutable doc mapping, and have BpVectorReorderer take each document's ordinal from the iterator (it.index()) instead of counting positions. The test, the closest suites and the misc module pass, and the reorder lands on the right documents. Land it with the fix for LFV-278.
// SortingCodecReader: each Sorting*VectorValues (float shown)
@Override
public FloatVectorValues copy() throws IOException {
  return new SortingFloatVectorValues(delegate.copy(), iteratorSupplier);
}

// BpVectorReorderer.valueMapToDocMap: no dense shortcut; ordinals from the iterator
KnnVectorValues.DocIndexIterator it = values.iterator();
for (int nextDoc = it.nextDoc(); nextDoc != NO_MORE_DOCS; nextDoc = it.nextDoc()) {
  // ... documents without a vector go to the end, as before
  int newOrd = valueMap.oldToNew(it.index()); // was: valueMap.oldToNew(ord++)
All options and trade-offs5 options · 710 words
One fix (option A) was built and validated in a scratch worktree at 645d4fe14a20 (removed afterwards); the doc-space half was also checked with the verifiers' probes. Options B-D were not run. Option E is the first, incomplete fix, kept to show why it is not enough.
Two halves, +31/-15 lines in two files, no API change. (1) In SortingCodecReader, each sorting vector view gets a private constructor taking a delegate and the existing SortingIteratorSupplier, and copy() returns new Sorting*VectorValues(delegate.copy(), iteratorSupplier); the supplier's arrays are never modified after construction, so copies can share them, as iterator() already does. (2) In BpVectorReorderer.valueMapToDocMap, drop the "every document has a vector" shortcut and look up each document's new position by its own ordinal, it.index(). For a plain reader the result is identical, because its ordinals follow doc order.
// SortingCodecReader: each Sorting*VectorValues (float shown)
@Override
public FloatVectorValues copy() throws IOException {
  return new SortingFloatVectorValues(delegate.copy(), iteratorSupplier);
}

// BpVectorReorderer.valueMapToDocMap: no dense shortcut; ordinals from the iterator
KnnVectorValues.DocIndexIterator it = values.iterator();
for (int nextDoc = it.nextDoc(); nextDoc != NO_MORE_DOCS; nextDoc = it.nextDoc()) {
  // ... documents without a vector go to the end, as before
  int newOrd = valueMap.oldToNew(it.index()); // was: valueMap.oldToNew(ord++)
Trade-offs
- Land with LFV-278. With two
SortingCodecReaderinputs in one call, this fix makesaddIndexessucceed, and then the merged view's iterator puts the wrong vector on 64 of 64 documents (LFV-278). With both fixes, all 5 failing shapes and 5 controls of the tie-break probe pass. - Below 64 vectors nothing is split, and the doc map now follows the wrapped reader's ordinals instead of being the identity: in a 63-document control the output follows the underlying reader's order, not the reversed view's. No contract fixes the output order of a reorder that found nothing to split; mention the change in the PR and leave it to the maintainers whether it is acceptable. Starting the bisection from the view's doc order instead is an untested alternative.
- The dense case builds two
int[maxDoc]arrays instead of reusing the permutation; small next to the bisection. copy()now delegates, so a sorting view is only as copyable as the vector values it wraps.- The regression test checks only that
addIndexessucceeds; the doc-space half is covered by the probes, not by the test; an upstream PR should add a test of the doc map.
What the checks validated
- Stock
645d4fe14a20: the test fails 1 of 1 through gradle, assertions on and off. With the fix: passes, assertions on and off. TestBpVectorReorderer,TestBPReorderingMergePolicy,TestBPIndexReorderer: 19 tests, 0 failures, 2 skipped (@Nightly); the first two with-Ptests.nightly=true -Ptests.iters=5: 55 tests, 0 skipped, 0 failures.TestSortingCodecReaderandTestIndexSorting(core): 65 tests, 0 failures.:lucene:misc:test: 24 classes, 317 tests, 9 skipped, 0 failures, assertions on and off;:lucene:core:check -x test :lucene:misc:check -x testpasses.- Doc space (stock jars with the patched classes shadowed): a 512-vector index behind a reversing view gets the correctly re-based doc map at 512 of 512 positions; cluster changes after BP 35, the same as for the plain reader (copy()-only: 0 of 512 and 383).
Build each per-thread state from reader.getFloatVectorValues(field) instead of vectors.copy().
Trade-offs
Works for any reader without copy(), but costs a new doc mapping (an int[maxDoc] plus a bit set) per thread for sorting views, and still needs the ordinal half of option A.
BPReorderingMergePolicy catches it like NotEnoughRAMException and leaves the merge unreordered.
Trade-offs
Hides the incompatibility; the input silently stays unreordered (bp.reordered=false); the catch is broad.
Say that SortingCodecReader inputs are unsupported with BpVectorReorderer.
Trade-offs
Leaves the documented BPIndexReorderer.reorder -> addIndexes recipe broken for this policy.
Only half (1) of option A, the first fix the hunt wrote.
Trade-offs
The test passes, but the reorder is applied to other documents: the doc map equals the plain reader's at 512 of 512 positions and the correctly re-based one at 0 of 512; cluster changes 383 instead of 35.
For a downstream service this is a failed import or re-sort job, not data damage: only the application's own addIndexes call with this configuration reaches the throw, and it fails before anything is written.
A hand-written end-to-end JUnit from a hunt unit on vector doc/ordinal mappings re-sorts a segment with SortingCodecReader, adds it with addIndexes to a vector-reordering writer and checks that every document keeps its vector; it failed earlier, with this exception. A second unit then inventoried every copy() implementation and caller and found this the only unreported throwing pair.
The method in full149 words
Method: non-formal (the first signal was a hand-written JUnit).
- A hunt unit (vector doc/ordinal mapping, 2026-10-26) wrote a public-API test that re-sorts a segment with
SortingCodecReader, adds it to a writer withBPReorderingMergePolicy(BpVectorReorderer)and checks that every document keeps its own vector; it failed earlier, with thisUnsupportedOperationException. - A hunt unit analysed it: a bytecode inventory of the 128
KnnVectorValues/RandomVectorScorerSupplierimplementations and every productioncopy()call site, and a bounded check of every reachable (view, caller) pair (7,488 checks plus 576 scorer-supplier checks, assertions on and off). This was the only reachable throwing pair that was neither registered nor already known. - Then: reviews by an independent reviewer from another model family (OpenAI GPT-5.6, reading only), an independent reproducer, a devil's advocate who measured the doc-space problem, an adjudication, a credibility audit, a re-verification on
645d4fe14a20, and a tie-breaker with its own plainmain()probe.
No prior report found: 193 logged queries on 2026-10-26 and a fresh search on 2026-10-30 (GitHub issues, PRs and commits, all open PRs' files, downstream projects, four mailing lists, the JIRA archive, the web). The closest item is #16705, the same kind of fix in another wrapper.
Searches4 searches
The documented searches found no public issue, PR, review comment, commit, list post, JIRA entry or downstream report that describes this failure or the follow-on ordinal assumption, and no merged or open change that fixes it. Limits: keyword search; broad terms are truncated at 50 results (specific class-name phrasings were read in full); private reports cannot be seen.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) and downstream repositories | 2026-10-26 | three scripted prior-report searches (main terms; the ordinal / doc-order follow-on and the BPIndexReorderer.reorder -> addIndexes angle; the general 'copy() unsupported in a merge' class), 24 apache/lucene and 12 downstream GraphQL searches; 193 logged queries in all | no report; related only: #16705, #13779, #14097, #14092, #16383, #16879, #13565, #13831 / #13872, #14123 / #14125, #15003, #15430 |
| GitHub (fresh search) | 2026-10-30 | three fresh runs of the scripted search; 58 own GraphQL phrasings incl. date-bounded ones; SortingFloatVectorValues, valueMapToDocMap and 'BpVectorReorderer UnsupportedOperationException' return 0 hits | no report; #16879 (open, graph reuse through SortingCodecReader, no copy() change) is the top hit |
| Open PRs | 2026-10-26, 2026-10-30 | the file lists of all 411 (then 408) open PRs; 12 relevant patches read | none changes Sorting*VectorValues.copy() or the copy() in BpVectorReorderer |
| Mailing lists, JIRA archive, web | 2026-10-26, 2026-10-30 | dev@, java-user@, issues@, commits@ (40 direct queries); 12 JQL queries; 21 and 11 web queries | no report; JIRA hits predate copy() on these views |
Introduced by #14097 (02a09f6ab12, merged 2025-01-07), which added BpVectorReorderer and its copying per-thread state; the sorting views' throw dates from #13779 (2024, released in 10.0.0) but nothing released reaches it. Main and branch_11x only; no release is affected.
Versions tested6 rows
Introduced by #14097 "HNSW BP reordering" (msokolov, merged to main 2025-01-07 as 02a09f6ab12, milestone 11.0.0, not backported to 10.x): it added BpVectorReorderer, whose per-thread state copies the vectors (BpVectorReorderer.java:110, unchanged since), and let BPReorderingMergePolicy take any IndexReorderer. CHANGES.txt:164 lists GITHUB#14097 under 11.0.0. Precondition: the float and byte sorting views throw from copy() since 6053e1e3137 (#13779, 2024-09-28); the float16 view since #16383 (bfe5c847d3c, 2026-07-27, on main and branch_11x). Upstream main (now 12.0.0-SNAPSHOT, 2f424fd428da on 2026-10-30) and branch_11x (d0c0decc6606) still have both halves; the first affected release would be 11.0.0.
| Version or commit | Verdict | Result |
|---|---|---|
| 9.12.3, 10.0.0, 10.1.0, 10.2.0, 10.5.2, 10.6.0 | not affected | no BpVectorReorderer: the repro does not compile; the policy with the postings BPIndexReorderer on a SortingCodecReader passes (10.0.0, 10.1.0, 10.5.2) |
main 72d93de50c2 (parent of #14097) | bisect | the repro does not compile; a direct copy() probe already throws |
main 02a09f6ab12 (#14097) | first affected | UnsupportedOperationException, same frames, assertions on and off |
main ea57360912ed, a9779ef3c193 | fails loudly | the finder's and verifiers' tests fail the same way |
main 645d4fe14a20 | fails loudly | the minimal test fails 1 of 1 (gradle and harness, assertions on and off, 20 of 20 seeds) |
main 645d4fe14a20 + fix A | not affected | the test, the closest suites and the misc module pass; doc map correctly re-based (512 of 512) |
An independent reproducer, reviews by OpenAI GPT-5.6, a devil's advocate, an adjudication, an audit, a re-verification on 645d4fe14a20 and a tie-breaker say real. One dissent: a third GPT-5.6 refute review returned not real (low) without running a command; the tie-breaker weighed it as procedural. With no executed refute review, the adjudication's confidence is medium.
Checks and verdicts313 words
All checks ran with assertions on and off, with the fixed seeds recorded in their result files.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit) | candidate | 4-test JUnit (200 documents): the one-reader and two-reader tests fail, both controls pass; 20 of 20 iterations. Bytecode inventory and bounded check of every (view, caller) pair. |
| Reviews (OpenAI GPT-5.6, reading only) | real (medium), twice | Intended lens: root cause agreed, inputs in contract, intended-behaviour argument moderate. Root-cause lens: flagged the valueMapToDocMap ordinal assumption. |
| Independent reproducer | real | Own JUnit outside Lucene's packages: 6 run, 4 failed; controls pass; 10.5.2 and 9.12.3 do not compile it. |
| Devil's advocate | real (medium) | No exclusion in any javadoc, test or discussion; the BPIndexReorderer.reorder -> addIndexes recipe fails; measured that a copy()-only fix applies the reorder in the wrong doc space. |
| Adjudication | confirmed (medium) | Re-ran the independent reproduction's and the finder's tests with fresh seeds; medium only because no executed refute review exists. |
| Re-verification on 645d4fe14a20 | real | The one-test repro fails 1 of 1 with assertions on and off; 10.5.2 does not compile it. |
| Refute review (OpenAI GPT-5.6, reading only) | not real (low), procedural | Third of three refute-lens attempts (2026-10-30); the first two (2026-10-26) returned no verdict. It could not run code, so it had no test of its own and gave a procedural "not real"; its notes call it "not a substantive refutation" and the mismatch "credible". |
| Tie-breaker | real | Own plain main() probe: 5 bug shapes fail, 5 controls pass; fail-closed; weighed the third refute attempt's not real (low confidence) as procedural: it could not run a command, and its own notes call the mismatch credible. |
| This doc | fix A validated | Ran the repro through gradle on stock and fixed main and validated fix A on the closest suites, the misc module and the doc-space probes. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 587 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,182 words
- Registry title
- addIndexes of a SortingCodecReader (including the reader that BPIndexReorderer.reorder returns) into a writer that uses BPReorderingMergePolicy with BpVectorReorderer throws UnsupportedOperationException, because SortingCodecReader's vector views do not support copy()
- Area
- misc / index: BpVectorReorderer merge-time reordering (BPReorderingMergePolicy) over core / index: SortingCodecReader vector views
- Priority
- Low, rank 665: AddIndexes of a SortingCodecReader into a writer that reorders with BpVectorReorderer fails loudly and adds nothing, but it is unreleased and needs a rare double-reorder combination, so it follows the opt-in crash rows LFV-296, LFV-438 and LFV-265.
- Impact class
- crash
- Impact note
- Only applications on unreleased main (11.0.0-SNAPSHOT) that opt into the expert lucene/misc BPReorderingMergePolicy with a BpVectorReorderer on a writer without an index sort and pass a SortingCodecReader to IndexWriter#addIndexes(CodecReader...) (re-sorted by a Sort or a DocMap, or the reader that BPIndexReorderer.reorder returns, which its javadoc says to pass to addIndexes) with at least 64 FLOAT32 vectors in the reordered field are hit, on every such call: addIndexes throws a clean unchecked UnsupportedOperationException within milliseconds and adds nothing, while the writer stays open and non-tragic and the index is unchanged (executed with both merge schedulers); a destination that carries the index sort (the usual re-sort recipe) skips reordering and is not affected, no released version contains BpVectorReorderer, and no scale is needed.
- Summary
- You pass a SortingCodecReader, for example the reader that BPIndexReorderer.reorder returns or SortingCodecReader.wrap(reader, docMap, null), to IndexWriter#addIndexes on a writer whose merge policy is BPReorderingMergePolicy with a BpVectorReorderer, and expect the documents to be added and reordered, as they are for plain segment readers and as the same policy does with the postings BPIndexReorderer. Instead addIndexes throws UnsupportedOperationException and adds nothing: the policy reorders addIndexes as a forced merge, BpVectorReorderer's per-thread state calls copy() on the input's float vector values, and SortingCodecReader's vector views throw from copy() (with several such readers in one call the throw comes through SlowCompositeCodecReaderWrapper's merged copy()). Making copy() work is not enough on its own: BpVectorReorderer then treats the sorting view's ordinals as doc order, so the reordering is silently applied in the wrong doc space.
- Introduced
- 02a09f6ab124e994fd1af42965617c8b5ec67bcc, apache/lucene#14097 'HNSW BP reordering' (by msokolov, merged to main 2025-01-07, milestone 11.0.0, never backported): it added BpVectorReorderer, whose PerThreadState constructor calls vectors.copy() (BpVectorReorderer.java:110, unchanged since), and let BPReorderingMergePolicy take any IndexReorderer [exec: commit-level A/B; at the parent 72d93de50c2 the copy() throw is already present (a direct copy() probe fails) but the repro does not compile because BpVectorReorderer does not exist; at 02a09f6ab12 the repro fails 2 of 4 with -ea and -da, with the same frames as on main]. Precondition, not the failure by itself: SortingFloatVectorValues.copy() and SortingByteVectorValues.copy() throw UnsupportedOperationException since 6053e1e3137 (apache/lucene#13779, 2024-09-28, a deliberate partial implementation; first released in 10.0.0); the float16 view's throw came with bfe5c847d3c (#16383, 2026-07-27, main only). (2025-01-07 (the latent copy() throw: 2024-09-28))
- First affected version
- unreleased (main only, 11.0.0-SNAPSHOT; CHANGES.txt lists GITHUB#14097 under 11.0.0; BpVectorReorderer.java is absent from all 16 9.12.x and 10.x release tags, from branch_10x and from branch_10_6 [read: git ls-tree]); the first affected release would be 11.0.0 if nothing changes
- Affected versions
- main from 02a09f6ab12 (2025-01-07) to ea57360912ed (2026-10-24) [exec: both fail 2 of 4 with -ea and -da; read: git blame, no commit in between changes either half]; upstream main cf398bfb142c (2026-10-26) still has both halves [read]. Not affected: 9.12.3, 10.0.0, 10.1.0, 10.2.0 and 10.5.2 [exec: the repro does not compile; on 10.x the only missing symbol is BpVectorReorderer]. The latent half, the float and byte sorting views' copy() throw, is in every 10.x release [read: 12 tags; exec: a direct copy() probe fails on 10.0.0, 10.1.0 and 10.5.2], but no released in-tree caller copies those views [read, partial: source grep of the 10.5.2 call sites], and the closest released composition, BPReorderingMergePolicy with the postings BPIndexReorderer on a SortingCodecReader input, passes on 10.0.0, 10.1.0, 10.5.2 and main [exec].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an adjudication that ruled it real, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-26 plus the finder's run, read-only; the prior-report record verdict new, 193 logged queries: three scripted prior-report searches (main terms; the follow-on ordinal / doc-order and BPIndexReorderer.reorder -> addIndexes angle; the general 'vector values copy() unsupported in a merge' class) over apache/lucene issues, PRs and commits, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists and the JIRA archive, plus 24 apache/lucene and 12 downstream GraphQL searches, the file lists of all 411 open apache/lucene PRs, direct lists.apache.org and JQL queries and 21 web queries). Closest item, a sibling fix and not a report: #16705 (by goankur, merged 2026-10-01) made ExitableDirectoryReader's vector views wrap delegate.copy() instead of throwing; the same commit touched SortingCodecReader's views for prefetch but left their copy() throwing, and nobody mentioned it. Context, not the same bug: #13779 (added the throw deliberately), #14097 (added the copying caller; no comment mentions SortingCodecReader, copy() or addIndexes), #14092 (the merged view copies its subs), #16383 (float16 view), open #16879 (HNSW graph reuse through SortingCodecReader; does not touch copy(); states that the views keep the wrapped reader's ordinals), #13565, #13831 / #13872, #14123 / #14125 (a different NPE in the same reader), #15003, open #15430. Not fixed upstream (main cf398bfb142c, 2026-10-26).
- Lucene commit tested
- main
645d4fe14a20(gradle in a scratch worktree and the standalone harness, assertions on and off, 20 of 20 random seeds); earlier mainea57360912edanda9779ef3c193; the introducing commit02a09f6ab12and its parent72d93de50c2(commit-level A/B); release jars 9.12.3, 10.0.0, 10.1.0, 10.2.0, 10.5.2 and 10.6.0 (the repro does not compile there); the fix in a scratch worktree at645d4fe14a20.
- Finding record
lucene/core/src/java/org/apache/lucene/index/SortingCodecReader.java:47-52 (class javadoc: addIndexes use, 'only be used for merging'), 265-266 (index() 'may skip around'), 345-348, 392-395, 435-438 (copy() throws)lucene/misc/src/java/org/apache/lucene/misc/index/BpVectorReorderer.java:108-111 (PerThreadState copies the vectors), 684-697 (reorderIndexDirectory), 735-764 (valueMapToDocMap)lucene/misc/src/java/org/apache/lucene/misc/index/BPReorderingMergePolicy.java:35-39 (skips reordering rather than fail on RAM shortage), 199-203 (addIndexes is a forced merge)lucene/misc/src/java/org/apache/lucene/misc/index/BPIndexReorderer.java:73-89 (usage example ends in w.addIndexes(reorderedReaderView)), 825-842 (reorder() returns SortingCodecReader.wrap(reader, docMap, null))lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3548-3564 (no reordering when the destination has an index sort; merge.reorder before the SegmentMerger)lucene/core/src/java/org/apache/lucene/index/KnnVectorValues.java:95-99 (copy() contract)lucene/CHANGES.txt:158 (GITHUB#14097 under Lucene 11.0.0)
- The finding in 30 seconds
lucene/misc/src/java/org/apache/lucene/misc/index/BPReorderingMergePolicy.java:103-105, 136-141, 199-203 (645d4fe14a20)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3380-3382, 3390-3392, 3548-3568 (645d4fe14a20)lucene/misc/src/java/org/apache/lucene/misc/index/BpVectorReorderer.java:108-111, 208-217, 590, 619-624, 735-789 (645d4fe14a20)lucene/core/src/java/org/apache/lucene/index/SortingCodecReader.java:264-266, 323-327, 346-347, 393-394, 436-437, 630-631 (645d4fe14a20)lucene/core/src/java/org/apache/lucene/index/SlowCompositeCodecReaderWrapper.java:49-58, 306-307, 903-909 (645d4fe14a20)lucene/misc/src/java/org/apache/lucene/misc/index/AbstractBPReorderer.java:25 (DEFAULT_MIN_PARTITION_SIZE = 32)
- Who is affected
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3548-3562 (no reorder with an index sort)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/SortingCodecReader.java:47-52 (645d4fe14a20)lucene/misc/src/java/org/apache/lucene/misc/index/BPIndexReorderer.java:73-89, 825-842 (645d4fe14a20)lucene/misc/src/java/org/apache/lucene/misc/index/IndexReorderer.java:25-35; BPReorderingMergePolicy.java:34-37 (645d4fe14a20)lucene/misc/src/test/org/apache/lucene/misc/index/TestBPReorderingMergePolicy.java:49-57, 147-148, 189 (645d4fe14a20)
- History
lucene/CHANGES.txt:164 (645d4fe14a20)
- TestBpVectorReorderSortingCodecReader.java (1 test, misc module):
repro/LFV-404/src/org/apache/lucene/misc/index/TestBpVectorReorderSortingCodecReader.java(80 lines)
assets/LFV-404/bug.png(587 KB)