One numeric field, three documents, one flush: after nextDoc() and intoBitSet(2, ...), doc 2 reports doc 0's value.
- At flush, IndexWriter passes the codec's
DocValuesConsumerone iterator per doc-values field, built over the values buffered in memory. - That iterator has a doc cursor (which documents have the field) and a value cursor that reads the buffered values in order.
nextDoc()moves both by one document. intoBitSet(upTo, bits, offset)is a bulk call: it sets a bit for every document from the current one up toupTo, and must leave the iterator exactly where the equivalentnextDoc()loop would.
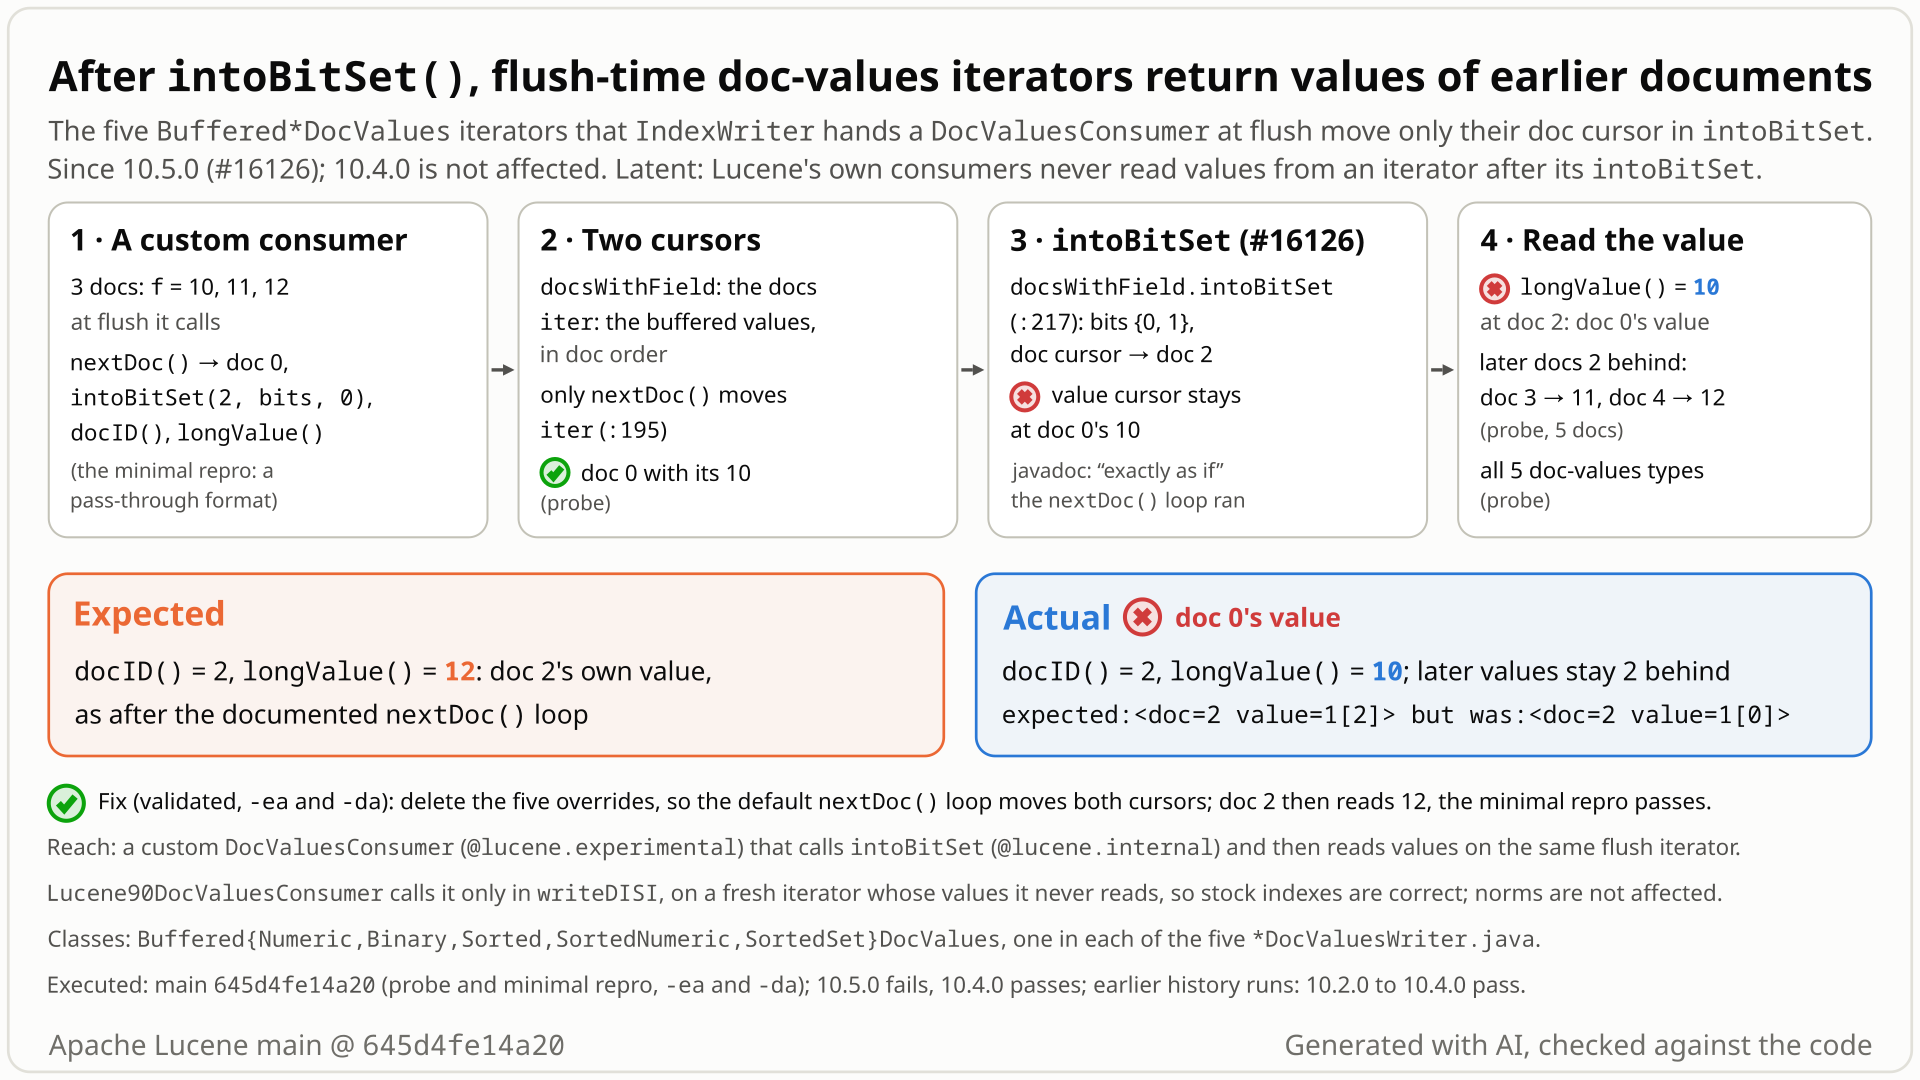
intoBitSet(2, ...): the doc cursor jumps to doc 2, the value cursor stays on doc 0. Select the still to open it at full size. Generated with AI, checked against the code.- A custom doc-values codec gets, at flush, the iterator over numeric field
f, whose docs 0, 1, 2 hold 10, 11, 12. It callsnextDoc()(doc 0), thenintoBitSet(2, bits, 0)to collect docs 0 and 1 in one call, then reads the current value. - You expect what the documented
nextDoc()loop gives: bits 0 and 1 set, the iterator on doc 2, andlongValue()= 12. - Instead the bits and
docID()are right, butlongValue()returns 10, doc 0's value.intoBitSet()moved only the doc cursor; the value cursor, which onlynextDoc()moves, stayed on doc 0. - With more documents it stays shifted: in a 6-document test the next
nextDoc()gives doc 3 with 11 instead of 13. BINARY, SORTED, SORTED_NUMERIC and SORTED_SET fields behave the same, with assertions on or off; in this call order nothing reports an error.
Only custom doc-values codecs whose consumer calls intoBitSet() on a flush iterator and then reads values from that same iterator; they could write each later value against the wrong document, usually silently. The default codec and norms are not affected, nor are flushes that re-sort documents for an index sort. 10.5.0 to 10.6.0 and main.
Mechanism, terms and numbers694 words
When a segment is flushed, IndexWriter hands the codec's DocValuesConsumer one iterator per doc-values field. Each of the five flush-time iterators (Buffered{Numeric,Binary,Sorted,SortedNumeric,SortedSet}DocValues) has a doc cursor and a sequential value cursor, and only nextDoc() moves the value cursor from one document to the next. Since #16126 (10.5.0) their intoBitSet() delegates to the doc cursor alone, so after nextDoc() and intoBitSet(2, bits, 0) over values 10, 11, 12 the iterator reports doc 2 with doc 0's value 10, and every later value stays shifted by the same two documents. That breaks DocIdSetIterator#intoBitSet's rule that an override "should behave exactly as" the nextDoc() loop. It is latent: Lucene's own consumer calls intoBitSet() only on fresh iterators whose values it never reads, so stock indexes are correct, and only an application-installed custom doc-values codec that mixes the two calls on one iterator could write values against the wrong documents, usually silently. 10.5.0 through 10.6.0 and main are affected; removing the five overrides fixes it.
- Flush iterators. For each doc-values field of an unsorted segment, the writer's
flushpasses a producer whosegetNumeric(getBinary,getSorted,getSortedNumeric,getSortedSet) returns a newBuffered*DocValuesiterator over the in-memory buffers (NumericDocValuesWriter.java:134-172at645d4fe14a20). Two routes add a singleton wrapper: a SORTED_NUMERIC field whose documents all have one value is handed over asDocValues.singleton(BufferedNumericDocValues)(SortedNumericDocValuesWriter.java:215-225) and shows the same bug; a single-valued SORTED_SET field asDocValues.singleton(BufferedSortedDocValues)(SortedSetDocValuesWriter.java:274-285), where the wrapper adds its own stale ordinal (LFV-091). With an index sort and a flush that must re-sort, theSorting*views are used instead; they read values by doc ID and are not affected. - Two cursors.
docsWithFieldisDocIdSetIterator.all(n)while every document so far has the field (as in the example), otherwise aBitSetIterator; the values come from aPackedLongValues.Iterator(or a lengths iterator plus a bytes input). OnlynextDoc()moves the value side from one document to the next (NumericDocValuesWriter.java:191-198:value = iter.next()); in a multi-valued documentnextValue()andnextOrd()also step through that document's values. intoBitSetcontract. "This should behave exactly as if implemented as below, which is the default implementation:for (int doc = docID(); doc < upTo; doc = nextDoc()) { bitSet.set(doc - offset); }" (DocIdSetIterator.java:186-210).NumericDocValues#longValue"Returns the numeric value for the current document ID".
- #16126 (10.5.0) added the same override to all five iterators:
intoBitSet(...) { docsWithField.intoBitSet(upTo, bitSet, offset); }(NumericDocValuesWriter.java:215-218,BinaryDocValuesWriter.java:213-216,SortedDocValuesWriter.java:347-350,SortedNumericDocValuesWriter.java:318-321,SortedSetDocValuesWriter.java:385-388). docsWithField.intoBitSet(DocIdSetIterator.all(n)'s range iterator in the example, aBitSetIteratorfor a sparse field) sets the range of bits and advances the doc cursor toupTo; nothing touches the value cursor.- So the doc cursor is ahead of the value cursor by the number of
nextDoc()steps the reference loop would have taken: the documents with the field thatintoBitSetmoved over, counting the one it lands on. Every value read afterwards belongs to that many documents earlier. In this call order (nextDoc(),intoBitSet(), then reads) the value cursor only lags, nothing throws, and the values of the last documents are simply never returned. - Not always silent:
intoBitSet()also leaves the per-document count and position alone. If a SORTED_SET consumer has already read the current document's ords, the nextnextOrd()reads pastBufferedSortedSetDocValues's per-document array: with 2 values per document,nextDoc(), twonextOrd(),intoBitSet(1, ...),nextOrd()throwsArrayIndexOutOfBoundsException: Index 2 out of bounds for length 2(executed on645d4fe14a20, assertions on and off; returns doc 1's ords with the fix).
| type | expected at doc 2 / doc 3 | got |
|---|---|---|
| NUMERIC | 12 / 13 | 10 / 11 |
| BINARY, SORTED | t2 / t3 | t0 / t1 |
| SORTED_NUMERIC | 12;102 / 13;103 | 10;100 / 11;101 |
| SORTED_SET (2 values per doc) | t2;u2 / t3;u3 | t0;u0 / t1;u1 |
The hunt's five-type test (6 documents): field values are 10 + d (or "t" + d) on doc d; after nextDoc() and intoBitSet(2, bits, 0) the bits (0 and 1) and docID() (2) are right in every case. Norms are not affected (NormValuesWriter.BufferedNorms has no override).
Exposure and likelihood264 words
- Who is hit. Authors of a custom
DocValuesFormat(the codec extension point;DocValuesConsumeris@lucene.experimental) whose consumer calls the@lucene.internalintoBitSet()on a flush-time iterator and then reads values from the same iterator, for example a single pass that writes the docs-with-field bit set and the values together. A customIndexSorterreads these iterators at flush too and could hit it the same way (code reading only, not executed). Beyond installing the custom codec (IndexWriterConfig.setCodec), no setting is needed. - Not hit: stock Lucene.
Lucene90DocValuesConsumercallsintoBitSet()only throughIndexedDISI.writeBitSet, always on a fresh iterator used only for doc IDs (Lucene90DocValuesConsumer.java:166-174,:472-475,:658-661), and reads values from other fresh iterators withnextDoc(). Soft-delete counting usesnextDoc()only. Norms have no override. - Usually silent. Bits and doc IDs are right; only values (and, for SORTED_NUMERIC and SORTED_SET, value counts) are wrong. The one exception found: a SORTED_SET consumer that read the current document's ords before
intoBitSet()gets anArrayIndexOutOfBoundsExceptionfrom its nextnextOrd(). The format test forintoBitSet(BaseDocValuesFormatTestCase#doTestRandomIntoBitSet) runs on a merged segment's reader and checks onlydocID()and the bits, so no test reads flush-iterator values afterintoBitSet(). - Scale. Every flushed segment with the field; deterministic; 3 documents are enough.
- How likely. Rare: no in-tree consumer has the pattern and nobody has reported it since 10.5.0. The pattern does exist downstream: one columnar codec folds a value pass into
IndexedDISI.writeBitSetand keeps the defaultintoBitSet()loop on purpose, documenting that delegating it "would advance the underlying cursor behind this iterator's back".
One JUnit test, 3 documents, one flush. A pass-through doc-values format (the default format's name, delegating to it) calls nextDoc() and intoBitSet(2, ...) on the flush iterator of field f, records docID() and longValue(), and the test checks them after the writer closes.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.io.IOException;
import org.apache.lucene.codecs.DocValuesConsumer;
import org.apache.lucene.codecs.DocValuesFormat;
import org.apache.lucene.codecs.DocValuesProducer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;
import org.apache.lucene.util.FixedBitSet;

public class TestFlushNumericDocValuesIntoBitSet extends LuceneTestCase {

  private String observed;

  public void testValueAfterIntoBitSet() throws IOException {
    DocValuesFormat real = TestUtil.getDefaultDocValuesFormat();
    DocValuesFormat observing =
        new DocValuesFormat(real.getName()) {
          @Override
          public DocValuesConsumer fieldsConsumer(SegmentWriteState state) throws IOException {
            DocValuesConsumer in = real.fieldsConsumer(state);
            return new DocValuesConsumer() {
              @Override
              public void addNumericField(FieldInfo field, DocValuesProducer producer)
                  throws IOException {
                NumericDocValues values = producer.getNumeric(field);
                values.nextDoc();
                values.intoBitSet(2, new FixedBitSet(3), 0);
                observed = "doc=" + values.docID() + " value=" + values.longValue();
                in.addNumericField(field, producer);
              }

              @Override
              public void addBinaryField(FieldInfo field, DocValuesProducer producer)
                  throws IOException {
                in.addBinaryField(field, producer);
              }

              @Override
              public void addSortedField(FieldInfo field, DocValuesProducer producer)
                  throws IOException {
                in.addSortedField(field, producer);
              }

              @Override
              public void addSortedNumericField(FieldInfo field, DocValuesProducer producer)
                  throws IOException {
                in.addSortedNumericField(field, producer);
              }

              @Override
              public void addSortedSetField(FieldInfo field, DocValuesProducer producer)
                  throws IOException {
                in.addSortedSetField(field, producer);
              }

              @Override
              public void close() throws IOException {
                in.close();
              }
            };
          }

          @Override
          public DocValuesProducer fieldsProducer(SegmentReadState state) throws IOException {
            return real.fieldsProducer(state);
          }
        };

    IndexWriterConfig iwc =
        new IndexWriterConfig().setCodec(TestUtil.alwaysDocValuesFormat(observing));
    try (Directory dir = newDirectory();
        IndexWriter w = new IndexWriter(dir, iwc)) {
      for (int d = 0; d < 3; d++) {
        Document doc = new Document();
        doc.add(new NumericDocValuesField("f", 10 + d));
        w.addDocument(doc);
      }
    }

    // as after the documented nextDoc() loop, doc 2 is current with value 12; actual: doc 0's 10
    assertEquals("doc=2 value=12", observed);
  }
}
cp $REPRO/TestFlushNumericDocValuesIntoBitSet.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestFlushNumericDocValuesIntoBitSet -Ptests.seed=DEADBEEF -Ptests.asserts=true
# same failure with -Ptests.asserts=false
- Expected
doc=2 value=12: the iterator is on doc 2 and returns doc 2's value, as after the documentednextDoc()loop.- Observed
doc=2 value=10: the right document with doc 0's value (expected:<doc=2 value=1[2]> but was:<doc=2 value=1[0]>).
More files, environment, full output288 words
Public Java API only (in the visibility sense; FixedBitSet and intoBitSet are @lucene.internal): IndexWriter, IndexWriterConfig, the codec SPI (DocValuesFormat, DocValuesConsumer, DocValuesProducer, FieldInfo, SegmentWriteState, SegmentReadState), NumericDocValues and FixedBitSet; from the test framework LuceneTestCase and TestUtil.getDefaultDocValuesFormat() / TestUtil.alwaysDocValuesFormat(...). The package org.apache.lucene.index is only a convention. The observing format delegates to the default one, so the segment it writes is an ordinary default-format segment (the test does not reopen it or run CheckIndex), and the assertion runs after the writer is closed, so a failure is a plain ComparisonFailure. It passes when doc 2 is current with value 12, which is what the fix gives.
It covers NUMERIC only; the other four iterators have the same one-line override. The hunt's five-type test and an independent reproducer's dense/sparse suite showed all five fail the same way, but they are not part of the repro.
The test is lint-clean as is: with it in lucene/core/src/test, checkGoogleJavaFormat, ecjLintMain, ecjLintTest, forbiddenApisMain and forbiddenApisTest pass.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails with assertions on and off; with the fix: passes |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
# gradle, scratch worktree of main 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (the same with asserts=false)
TestFlushNumericDocValuesIntoBitSet > testValueAfterIntoBitSet FAILED
    org.junit.ComparisonFailure: expected:<doc=2 value=1[2]> but was:<doc=2 value=1[0]>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:1AC0B0C3115D08D5]:0)
        at app//org.junit.Assert.assertEquals(Assert.java:117)
        at app//org.junit.Assert.assertEquals(Assert.java:146)
        at app//org.apache.lucene.index.TestFlushNumericDocValuesIntoBitSet.testValueAfterIntoBitSet(TestFlushNumericDocValuesIntoBitSet.java:101)
1 test completed, 1 failed

# standalone, same seed: the same message on main (-ea, -da), 10.6.0 (-ea, -da), 10.5.2, 10.5.0; 10.4.0 (-ea, -da) passes

# the hunt's five-type test (6 documents; main ea57360912ed, the same on 645d4fe14a20), NUMERIC case: the shift persists to doc 3
expected:<bits=2 doc=2 value=1[2 next doc=3 value=13]> but was:<bits=2 doc=2 value=1[0 next doc=3 value=11]>DocIdSetIterator#intoBitSet"should behave exactly as if implemented as" thenextDoc()loop, andlongValue()returns the value "for the current document ID".- A regression of an optimisation: #16126 (10.5.0) replaced the default loop to "just delegate"; 10.2.0 to 10.4.0 were correct.
- Upstream fixed an analogous omission in the
SortedSetSelectorwrappers from that PR as a bug (#16714).
The full argument301 words
- The contract is explicit.
DocIdSetIterator.java:186-204: an override "should behave exactly as if implemented as" thedocID()/nextDoc()loop. These overrides reproduce the loop's doc IDs and bits but not its effect on the values.NumericDocValues#longValue"Returns the numeric value for the current document ID" (NumericDocValues.java:31-37); the documented restrictions onintoBitSetare thatoffsetis at most the current doc ID and the iterator is positioned (DocIdSetIterator.java:196-197) and, for doc-values iterators, not afteradvanceExactreturned false (DocValuesIterator.java:30-31); the repro meets all three, and none says values are undefined afterwards. The argument is an inference: the javadoc gives the reference loop and does not separately say that a subclass's value state must follow it. - A regression. #16126 ("Implement #intoBitSet and #docIDRunEnd in DocValuesWriter implementations", iverase, merged 2026-05-26, milestone 10.5.0) says only: "This are mostly iterators wrapping other iterators so we just delegate the method to the underlaying iterators." One approving review, no comments, no tests for these iterators; CHANGES lists it under Optimizations. From 10.2.0 (#14069) to 10.4.0 the inherited loop kept the values right.
- Precedent. #16714 (dweiss, merged 2026-09-25, 10.6.0) added the missing
setOrd()afterin.intoBitSetin the fourSortedSetSelectorwrappers that #16126 added in the same commit: "it also did find a bug in there so it's piggybacked". It did not touch the writers. Analogous, not identical: there a wrapper's cached ordinal was not refreshed; here a direct iterator's value cursor is not advanced. - Lucene's other iterators keep their value state coherent. The reader side resets its per-document state in
intoBitSet(Lucene90DocValuesProducer.java:2258-2260,set = false), and the test framework'sAssertingNumericDocValuesleaveslongValue()legal afterintoBitSet(AssertingLeafReader.java:815-823,:846-850). - Nothing permits it. No javadoc, CHANGES or MIGRATE entry, test or PR discussion says values are undefined after
intoBitSet.
The devil's-advocate check186 words
The strongest case (cross-model reviews and the devil's-advocate verifier): intoBitSet is @lucene.internal, the codec API @lucene.experimental; the Buffered* iterators are package-private and sequential-only (advance and advanceExact throw); DocValuesConsumer's javadoc lets an implementation "iterate over the values multiple times" (DocValuesConsumer.java:60-64), and the in-tree consumer does exactly that, one fresh iterator per pass. So mixing intoBitSet() and value reads on one iterator is unsupported use of internal API, and the overrides are a fair optimisation for every real caller. A maintainer may also read @lucene.internal as limiting behavioural guarantees, not only compatibility; the cross-model fact check rated this case moderate.
Why it fails: @lucene.internal is about API stability, not a licence for an iterator to report doc 2 with doc 0's value; the method's own javadoc states what an override must preserve. The project fixed an analogous omission in the SortedSetSelector wrappers from the same PR as a bug (#16714). And the error is usually silent: the doc IDs are right, so misplaced values surface nowhere. What survives is the severity: latent and custom-codec only. Verdict: not intended, a minor latent defect.
Recommended A. Remove the five delegating intoBitSet overrides
Remove the five delegating intoBitSet() overrides so the default nextDoc() loop moves both cursors (5 files, +5/-24 lines). Validated: the repro passes, 3032 core index and codecs tests ran with 0 failures (178 skipped), and the lint passes. Cost: gives back #16126's speed-up when the default codec writes sparse fields at flush (not measured).
// NumericDocValuesWriter.BufferedNumericDocValues; the same in the other four Buffered* classes
-    @Override
-    public void intoBitSet(int upTo, FixedBitSet bitSet, int offset) throws IOException {
-      docsWithField.intoBitSet(upTo, bitSet, offset);
-    }
+    // No intoBitSet override: the default nextDoc() loop also advances the value iterator.
All options and trade-offs3 options · 524 words
One fix was built and validated; the others are sketches with their trade-offs.
Delete intoBitSet from BufferedNumericDocValues, BufferedBinaryDocValues, BufferedSortedDocValues, BufferedSortedNumericDocValues and BufferedSortedSetDocValues, so they inherit the default nextDoc() loop, which moves both cursors; drop the four FixedBitSet imports that become unused (5 files, +5/-24 lines with a one-line comment in each class). Keep the docIDRunEnd overrides: they do not move any cursor.
// NumericDocValuesWriter.BufferedNumericDocValues; the same in the other four Buffered* classes
-    @Override
-    public void intoBitSet(int upTo, FixedBitSet bitSet, int offset) throws IOException {
-      docsWithField.intoBitSet(upTo, bitSet, offset);
-    }
+    // No intoBitSet override: the default nextDoc() loop also advances the value iterator.
Trade-offs
- Gives back #16126's speed-up where the default codec calls
IndexedDISI.writeBitSeton these iterators at flush (fields that some but not all documents have): the loop now also decodes each value it passes. Not measured. - Restores the 10.2.0-10.4.0
intoBitSetbehaviour (the default loop), which was correct; thedocIDRunEndoverrides, which 10.4.0 did not have, stay. - A single-valued SORTED_SET field flushes as
DocValues.singleton(BufferedSortedDocValues); thereSingletonSortedSetDocValues.intoBitSetstill leaves a one-document stale ordinal (LFV-091, a separate one-line fix).
What the checks validated
- Gradle in a scratch worktree of
645d4fe14a20(--offline, seed DEADBEEF, JDK 25.0.3). Stock: the repro fails with assertions on and off. - With the fix: the repro plus
TestLucene90DocValuesFormat,TestLucene90DocValuesFormatMergeInstance,TestLucene90DocValuesFormatVariableSkipInterval,TestIndexedDISI,TestPerFieldDocValuesFormat,TestDocValuesIndexing,TestDocValues,TestDocsWithFieldSet,TestIndexSorting,TestMultiDocValuesand the four doc-values update suites pass with assertions on and off (15 suites, 884 tests, 0 failures, 69 skipped). - Every core test in
org.apache.lucene.index.*andorg.apache.lucene.codecs.*with the fix (266 suites, 3032 tests, 0 failures, 178 skipped), andTestSimpleTextDocValuesFormatin:lucene:codecs(148 tests, 0 failures, 10 skipped). - Lint with the fix:
checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMainandforbiddenApisTestpass. - On
645d4fe14a20with the same diff shadowed in: the hunt's five-type test, 5 of 5 pass (assertions on); the single-valued SORTED_NUMERIC route and the SORTED_SET read-ords-then-intoBitSet()order, 2 of 2 pass (assertions on and off). Limits: the gradle regression test is NUMERIC only, and single-valued SORTED_SET stays broken until LFV-091 is fixed. - Earlier, the hunt's equivalent fix passed the finder's five-type test, the independent reproducer's 10 tests and the adjudication's re-run.
After docsWithField.intoBitSet(...), advance the value cursor by the number of documents with the field that were passed (for SORTED_NUMERIC and SORTED_SET also the per-document counts), then load the current document's value.
Trade-offs
The iterator does not know that count today (it would need the DocsWithFieldSet bits or a running counter), and PackedLongValues.Iterator has only hasNext() and next() (no skip), so the value side still steps entry by entry: more code in five classes for a gain that was never measured.
A javadoc note on the flush producers.
Trade-offs
Contradicts DocIdSetIterator#intoBitSet's "behave exactly as" rule, and a consumer has no way to tell a flush iterator from any other NumericDocValues.
Downstream codecs that fold a value pass into the docs-with-field bit set are the pattern at risk; the one found (Elasticsearch's columnar code) keeps the default intoBitSet() loop on purpose and is not affected.
Bounded-exhaustive checking: a harness ran every sequence of up to 3 iterator calls on segments of up to 5 documents, for 26 doc-values and norms views, and compared each step with a plain nextDoc() walk. The sequence nextDoc(), intoBitSet(), value read mismatched on the flush iterators of all five types; a JUnit test on the stock jars confirmed it.
The method in full161 words
Method: bounded-exhaustive translation validation (the hunt's "semi-formal" tier), hunt unit (doc-values and norms cursor coherence), 2026-10-26, main ea57360912ed.
- The harness (
Coherence.java) enumerated every legal move sequence of depth <= 3 overnextDoc,advance,advanceExact,intoBitSet,docIDRunEnd,intoArrayand the bulk value calls, on segments of <= 5 documents, for 26 doc-values and norms views, including the flush-time iterators handed to a pass-throughDocValuesConsumer. After every step it compared the iterator state with a freshnextDoc()enumeration of the same view. - The sequence
nextDoc > intoBitSet > value readon the flush-time view mismatched for all five doc-values types. The finder reduced it to a public-API JUnit test on the stock main jars (5 of 5 fail, assertions on and off), and the hunt later minimized it to one NUMERIC test. - Earlier units had noted the same pattern by code reading (one as a possible latent defect, one as benign), without a repro.
No prior report found (2026-10-26): four scripted searches (179 queries over GitHub, the mailing lists, JIRA and downstream projects), about 40 manual GitHub searches and the changed files of all 411 open PRs. Closest: #16714, which fixed an analogous omission in other wrappers. Not proof that no report exists.
Searches5 searches
No matching public report was found in the documented searches (not proof that none exists): no issue, PR, review comment, commit, list thread, JIRA entry or downstream report found there describes the flush iterators' intoBitSet() leaving the value cursor behind. #16714 is the closest item and is read as precedent, not as a report.
| Where | When | How | Found |
|---|---|---|---|
| GitHub apache/lucene issues, PRs and commits (scripted searches, four runs) | 2026-10-26 | 179 queries in total: the five Buffered* and writer class names, intoBitSet with longValue/ordValue/nextOrd/binaryValue, DocValuesConsumer, IndexedDISI.writeBitSet, DocsWithFieldSet, PackedLongValues, "values shifted", "wrong document", SortedSetSelector, setOrd, 16126, 16714 | no high-overlap hit; every top hit read |
| GitHub, manual (GraphQL) | 2026-10-26 | about 40 phrasings; each Buffered* class name; every intoBitSet item created since #16126 (28, triaged) | 0 hits for each class name; no report |
| Open PRs | 2026-10-26 | changed-file lists of all 411 open apache/lucene PRs | only #14475 and #13948 touch the writer files; neither changes intoBitSet |
| Mailing lists and JIRA archive | 2026-10-26 | dev@, java-user@, issues@, commits@; the migrated JIRA archive | no report |
| Downstream (Elasticsearch, OpenSearch, Solr) | 2026-10-26 | code and issue search for intoBitSet and writeBitSet | Elasticsearch #159643 and #159942 document the hazard for their own wrappers; not a report of this defect |
Introduced in 10.5.0 by #16126 (88f3d24ce7e on main, backport ef8dd5fb8bc, 2026-05-26) and bisected to it. Affects 10.5.0, 10.5.1, 10.5.2, 10.6.0 and main; 10.2.0 to 10.4.0 are correct; older versions lack intoBitSet().
Versions tested8 rows
Introduced by #16126 "Implement #intoBitSet and #docIDRunEnd in DocValuesWriter implementations" (iverase; main commit 88f3d24ce7e, one parent; branch_10x backport ef8dd5fb8bc, the copy shipped in 10.5.0, same patch-id, 2026-05-26). Limited to the writers' directory, git log --all -S 'docsWithField.intoBitSet' -- lucene/core/src/java/org/apache/lucene/index/ returns only these two copies (without the path it also returns #14293 and #14532, which touch TermOrdValComparator), and git blame attributes all five overrides to 88f3d24ce7e. DocIdSetIterator#intoBitSet itself dates from 10.2.0 (#14069). Not fixed on main, branch_10_6 or branch_10_5 (a Lucene clone fetched 2026-10-31); branch_10x no longer holds code: #16911 (48cf3f515d6, 2026-10-29) decommissioned it and removed all its files, and its last code state (657014b3c579) still had all five overrides; upstream main 2f424fd428da (2026-10-30) has no change to the five writer files since 645d4fe14a20.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails, assertions on and off (gradle and standalone) |
| 10.6.0 | affected | minimal test fails, assertions on and off |
| 10.5.0, 10.5.1, 10.5.2 | affected | fails (minimal test on 10.5.0 and 10.5.2; five-type test on all three, assertions off too on 10.5.0 and 10.5.2) |
branch_10x ef8dd5fb8bc (#16126 backport) vs parent dff210480d1 | bisect | the backport fails, its parent passes |
main 88f3d24ce7e (#16126) vs parent 928b8e3d4d3 | bisect | the commit fails, its parent passes (with newer codec jars; supporting evidence) |
| 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2, 10.4.0 | not affected | pass: the iterators inherit the default nextDoc() loop |
| 9.12.3, 10.0.0, 10.1.0 | API absent | the hunt's five-type test does not compile: intoBitSet does not exist |
| fix (remove the five overrides) | not affected | the minimal test passes; related core suites pass |
The finder, an independent reproducer, a devil's-advocate verifier, cross-model reviews (OpenAI GPT-5.6) and an adjudication agree on the root cause. The reviews that rated it not real did so on scope, and in one case also for lacking its own executed repro. Every executed run reproduced it and passed with the fix.
Checks and verdicts406 words
Every executed check reproduced the shifted values and passed with the fix; the split is only about whether a latent bug behind internal API counts.
| Check | Verdict | What it found |
|---|---|---|
| finder (bounded-exhaustive harness, then JUnit) | reproduced | Five-type test fails 5 of 5 on main (-ea, -da), 10.5.2 and 10.5.0; passes on 10.4.0 and with the fix. |
| cross-model review, refute lens (OpenAI GPT-5.6, reading only) | not real (high): scope, and no repro of its own | Agrees with the root cause; rates the trigger out of scope (@lucene.internal, no in-tree caller) and notes that a real verdict "requires an independently executed reproduction", which it could not provide (it could only read the code). A separate run of the repro: 5 of 5 fail. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | "@lucene.internal and @lucene.experimental limit API stability; they do not document internally contradictory iterator state." |
| independent reproducer | real | Own test, dense and sparse fields of all five types: 10 of 10 fail on main (-ea, -da), 10.5.2 and 10.5.0, 50 of 50 over five iterations; passes on 10.4.0 and with the fix. |
| cross-model review, root-cause lens (OpenAI GPT-5.6, reading only) | not real (high), scope | It treats internal API as out of scope, so it rated it not real "despite the genuine internal state-coherence defect". Separate runs: fails on main and 10.5.2, passes with the fix; removing only the NUMERIC override fixes only NUMERIC. |
| devil's-advocate verifier | real (latent) | No doc, test or discussion says values are undefined after intoBitSet; #16714 fixed the same omission as a bug. |
| adjudication | confirmed, high; minor | Re-ran the independent reproduction with a new seed: 10 of 10 fail, 10 of 10 pass with the fix. |
| credibility audit and main refreshes | reproduces | New seed on main: 5 of 5 fail; still reproduces on main a9779ef3c193; the minimized test fails on 645d4fe14a20 and passes with the fix. |
| fact checks of this doc (independent re-run, cross-model fact check, scope runs) | real; corrections applied | An independent re-run reproduced the repro, the fix, three releases and the five-type test on 645d4fe14a20; a cross-model fact check (OpenAI GPT-5.6) found wording errors, fixed here (scope of the singleton routes, the SORTED_SET exception, branch_10x). Scope runs: single-valued SORTED_NUMERIC fails the same way and the SORTED_SET read-ords-then-intoBitSet() order throws; both pass with the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 453 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,422 words
- Registry title
- The flush-time doc-values iterators that IndexWriter hands to a DocValuesConsumer move only their doc-ID cursor in intoBitSet(), so values read afterwards belong to earlier documents (NUMERIC, BINARY, SORTED, SORTED_NUMERIC, SORTED_SET; latent: Lucene's own consumers never read values after intoBitSet on the same iterator)
- Area
- index / doc values flush (DocValuesWriter Buffered*DocValues iterators handed to DocValuesConsumer)
- Priority
- Low, rank 1205: Only a custom single-pass doc-values consumer that reads values after intoBitSet sees shifted values, and Lucene's own consumers never do.
- Impact class
- minor
- Impact note
- Latent: only a custom DocValuesFormat consumer (public codec extension point, @lucene.experimental), or other custom code handed these iterators at flush, that calls the @lucene.internal DocIdSetIterator#intoBitSet on an unsorted flush-time doc-values iterator and then reads values from the same iterator is hit, and it would then silently write every later value of that field in the segment against the wrong document; Lucene's own consumers never do this (Lucene90DocValuesConsumer calls intoBitSet only through IndexedDISI.writeBitSet on a fresh iterator whose values it never reads, and the SimpleText, PerField, Asserting, Cranky and backward Lucene80 consumers never call it), nor do the downstream consumers read, norms are not affected, no scale or non-default IndexWriterConfig is needed, and 10.5.0 to 10.6.0 are affected.
- Summary
- A custom doc-values codec receives, at flush, the iterator over a field's buffered values; it calls nextDoc(), bulk-loads the next documents into a bit set with intoBitSet(), and then reads the value of the current document, expecting what the documented nextDoc() loop gives. Instead the five flush-time iterators (one per doc-values type) move only their doc-ID cursor in intoBitSet(), so the value read belongs to an earlier document, and every later value of the field in that segment stays shifted by the same number of documents (doc 2 reports doc 0's value, doc 3 reports doc 1's). Lucene's own doc-values consumer never reads values after intoBitSet() on the same iterator, so indexes written by stock Lucene are correct.
- Introduced
- 88f3d24ce7e1b3e7b6716d078b69b0098d467a8c (main merge commit of PR #16126 'Implement #intoBitSet and #docIDRunEnd in DocValuesWriter implementations', author iverase, one approving review by martijnvg ('LGTM'), no comments, no tests for these iterators; CHANGES 10.5.0 Optimizations) and its branch_10x backport ef8dd5fb8bc466ce8a22eb41d167f036554fc64a (same git patch-id, the copy that shipped in 10.5.0), which added 'intoBitSet(...) { docsWithField.intoBitSet(upTo, bitSet, offset); }' to BufferedNumericDocValues, BufferedBinaryDocValues, BufferedSortedDocValues, BufferedSortedNumericDocValues and BufferedSortedSetDocValues [read: git log -S 'docsWithField.intoBitSet' and git log -S intoBitSet on the five writer files return only this commit, git blame attributes all five overrides to it; exec: commit-level runs flip from pass at the parent to fail at the commit on branch_10x (dff210480d1 -> ef8dd5fb8bc, core sources shadowed ahead of the 10.5.0 jars) and on main (928b8e3d4d3 -> 88f3d24ce7e, ahead of the main jars, a hybrid and supporting evidence only), and the core source diff between parent and commit is exactly the 8 Java files of #16126]. A regression from an optimisation: from 10.2.0 to 10.4.0 these iterators inherited the default intoBitSet loop, which calls nextDoc() and keeps the value cursor in step (2026-05-26 (main merge 88f3d24ce7e and branch_10x backport ef8dd5fb8bc, same day))
- First affected version
- 10.5.0 [exec] (release commit f6eaee8148b, tagged 2026-06-25); 10.4.0 is the last unaffected release [exec, -ea and -da]: it has DocIdSetIterator#intoBitSet but these iterators use the default nextDoc() loop; the method first shipped in 10.2.0 (#14069), and 10.1.0 and earlier, including all of 9.x, lack it [exec: the repro does not compile on 9.12.3, 10.0.0 and 10.1.0]
- Affected versions
- 10.5.0, 10.5.1, 10.5.2, 10.6.0 and main (ea57360912ed, a9779ef3c193 and 645d4fe14a20) [exec: the minimal test fails on 10.5.0, 10.5.2, 10.6.0 and main 645d4fe14a20 (-ea; also -da on 10.6.0 and main) and passes on 10.4.0 (-ea and -da); the finder's JUnit fails 5 of 5 on 10.5.0, 10.5.1, 10.5.2 and main ea57360912ed, also with -da on 10.5.0, 10.5.2 and main; the independent reproduction's own JUnit fails 10 of 10 on main (-ea and -da), 10.5.2 (-ea and -da) and 10.5.0; commit-level runs isolate #16126 (see introduced_commit)]. Not affected: 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2 and 10.4.0 [exec: pass 5 of 5; 10.4.0 also with -da]. Not applicable (API absent): 10.1.0 and earlier, including all of 9.x [exec: compile error on 9.12.3, 10.0.0 and 10.1.0; read for the rest]. Not fixed: the five delegating overrides are still on upstream main (cf398bfb142c at search time, 2026-10-26), branch_10_6 (10.6.0, released 2026-10-29), branch_10x and branch_10_5 [read: file contents and git blame; no merged commit has changed them since #16126]. All runs on one aarch64 Linux host with JDK 25.0.3
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check; also reached by code reading
- Upstream and prior reports
- none found (2026-10-26): four scripted searches over apache/lucene issues, PRs and commits, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the Elasticsearch, OpenSearch and Solr repositories (the finder's: 39 queries, 193 hits, 0 high; identifiers: 51 queries, 297 hits, 0 high; consumer side and symptom: 51 queries, 240 hits, 0 high; sibling defects and precedent: 38 queries, 202 hits, 0 high), about 40 manual GitHub GraphQL phrasings (each of the five Buffered* class names: 0 hits; every intoBitSet item created since #16126: 28, triaged), the changed files of all 411 open apache/lucene PRs, manual list and web queries; read, not reports: #16126 (introduced it; one LGTM, no comments, no cross-references, no follow-up), #16714 (dweiss, merged 2026-09-25: added the missing setOrd() after in.intoBitSet in the four SortedSetSelector wrappers that #16126 added, did not touch the writers), #14618, #14529, #16097, #14552, #16180, #16513, #14475 and #13948 (the only open PRs that touch the writer files; neither changes intoBitSet), Elasticsearch #159643 and #159942 (document the same hazard for their own wrappers and deliberately keep the default intoBitSet loop); not fixed: upstream main, branch_10x, branch_10_6 and branch_10_5 still have the five overrides; gaps: GitHub text search does not index diffs (covered by the open-PR file scan and branch content checks), and private reports to security@lucene.apache.org are not visible
- Lucene commit tested
- main
645d4fe14a20(2026-11-01): the minimal test fails through gradle in a scratch worktree with assertions on and off, and standalone on main (-ea,-da) and on the release jars of 10.5.0, 10.5.2 and 10.6.0 (10.6.0 also-da); it passes on 10.4.0 (-ea,-da). With the recommended fix it passes, together with 14 related core suites (15 suites with the repro, 884 tests, 0 failures, assertions on and off), every core test inorg.apache.lucene.index.*andorg.apache.lucene.codecs.*(3032 tests, 0 failures, 178 skipped),TestSimpleTextDocValuesFormatand the core lint; the hunt's five-type test and the single-valued SORTED_NUMERIC and SORTED_SET-exception checks also pass with it on645d4fe14a20. Upstream main2f424fd428da(2026-10-30) has no change to the five writer files since645d4fe14a20(read). Earlier, the hunt's and verifiers' tests ran on mainea57360912edanda9779ef3c193and on releases 9.12.3 to 10.5.2, and the introducing commit was bisected.
- Finding record
lucene/core/src/java/org/apache/lucene/index/NumericDocValuesWriter.java:192-198 (BufferedNumericDocValues.nextDoc reads value = iter.next()) and :215-218 (intoBitSet only calls docsWithField.intoBitSet)lucene/core/src/java/org/apache/lucene/index/BinaryDocValuesWriter.java:213-216, SortedDocValuesWriter.java:347-350, SortedNumericDocValuesWriter.java:318-321, SortedSetDocValuesWriter.java:385-388 (the same delegating override; value cursors advanced only in nextDoc)lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:186-210 (intoBitSet 'should behave exactly as if implemented as' the docID()/nextDoc() loop; @lucene.internal)lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesConsumer.java:166-174, :472-475, :658-661 (writeDISI on a fresh getSortedNumeric/getBinary iterator) and IndexedDISI.java:213 (writeBitSet calls intoBitSet)lucene/core/src/java/org/apache/lucene/codecs/DocValuesConsumer.java:68 (@lucene.experimental)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/NumericDocValuesWriter.java:134-172, 176-229 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/index/{Binary,Sorted,SortedNumeric,SortedSet}DocValuesWriter.java (overrides at :213-216, :347-350, :318-321, :385-388; nextDoc at :187-196, :322-330, :278-290, :355-368)lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:186-210; lucene/core/src/java/org/apache/lucene/index/NumericDocValues.java:31-37lucene/core/src/java/org/apache/lucene/util/BitSetIterator.java:122-134; lucene/core/src/java/org/apache/lucene/index/DocsWithFieldSet.java:102-104lucene/core/src/java/org/apache/lucene/index/SortedNumericDocValuesWriter.java:215-225, 308-311; lucene/core/src/java/org/apache/lucene/index/SortedSetDocValuesWriter.java:274-285, 341, 371-373; lucene/core/src/java/org/apache/lucene/index/SingletonSortedNumericDocValues.java:67-90; lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:91-99
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesConsumer.java:166-174, 472-475, 658-661, 734-738, 1047-1050; lucene/core/src/java/org/apache/lucene/codecs/lucene90/IndexedDISI.java:210-213lucene/core/src/java/org/apache/lucene/index/PendingSoftDeletes.java:256-268; lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:191-239lucene/core/src/java/org/apache/lucene/codecs/DocValuesConsumer.java:68 (@lucene.experimental); lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:203 (@lucene.internal)lucene/test-framework/src/java/org/apache/lucene/tests/index/BaseDocValuesFormatTestCase.java:1041-1090
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:186-210; lucene/core/src/java/org/apache/lucene/index/NumericDocValues.java:31-37; lucene/core/src/java/org/apache/lucene/index/DocValuesIterator.java:30-31lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesProducer.java:2258-2260; lucene/test-framework/src/java/org/apache/lucene/tests/index/AssertingLeafReader.java:815-823, 846-850lucene/core/src/java/org/apache/lucene/codecs/DocValuesConsumer.java:60-64GitHub apache/lucene #16126 and #16714 (gh pr view, read-only, 2026-11-01: body, author, merge date, milestone)
- Suggested fix
lucene/core/src/java/org/apache/lucene/util/packed/PackedLongValues.java:131-173 (Iterator: hasNext, next)
- History
a Lucene clone: git log -1 releases/lucene/10.6.0; git grep docsWithField.intoBitSet releases/lucene/10.4.0, 10.5.0, 10.6.0; git diff --stat 645d4fe14a20 origin/main (2f424fd428da) on the five writer files
- TestFlushNumericDocValuesIntoBitSet.java:
repro/LFV-418/src/org/apache/lucene/index/TestFlushNumericDocValuesIntoBitSet.java(103 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the repro's input and output.
assets/LFV-418/bug.png(453 KB)