A half of a split whose vectors cancel out has no direction, but the reorderer still divides its vector sum by the sum's length, which is 0.
BpVectorReorderer(lucene/misc; main andbranch_11x, unreleased) renumbers the documents of a segment so that similar vectors get nearby doc IDs. It is opt-in: you callcomputeDocMap, run its offline tool, or plug it intoBPReorderingMergePolicy.- It splits the documents in half by doc ID and gives each half a centroid. For DOT_PRODUCT and COSINE the centroid is the sum of the half's vectors, scaled to length 1.
- Each document gets a bias, how much more it prefers the other half's centroid, and documents swap halves by bias for up to 20 rounds. Then each half is split again, until the halves would have fewer than 32 documents.
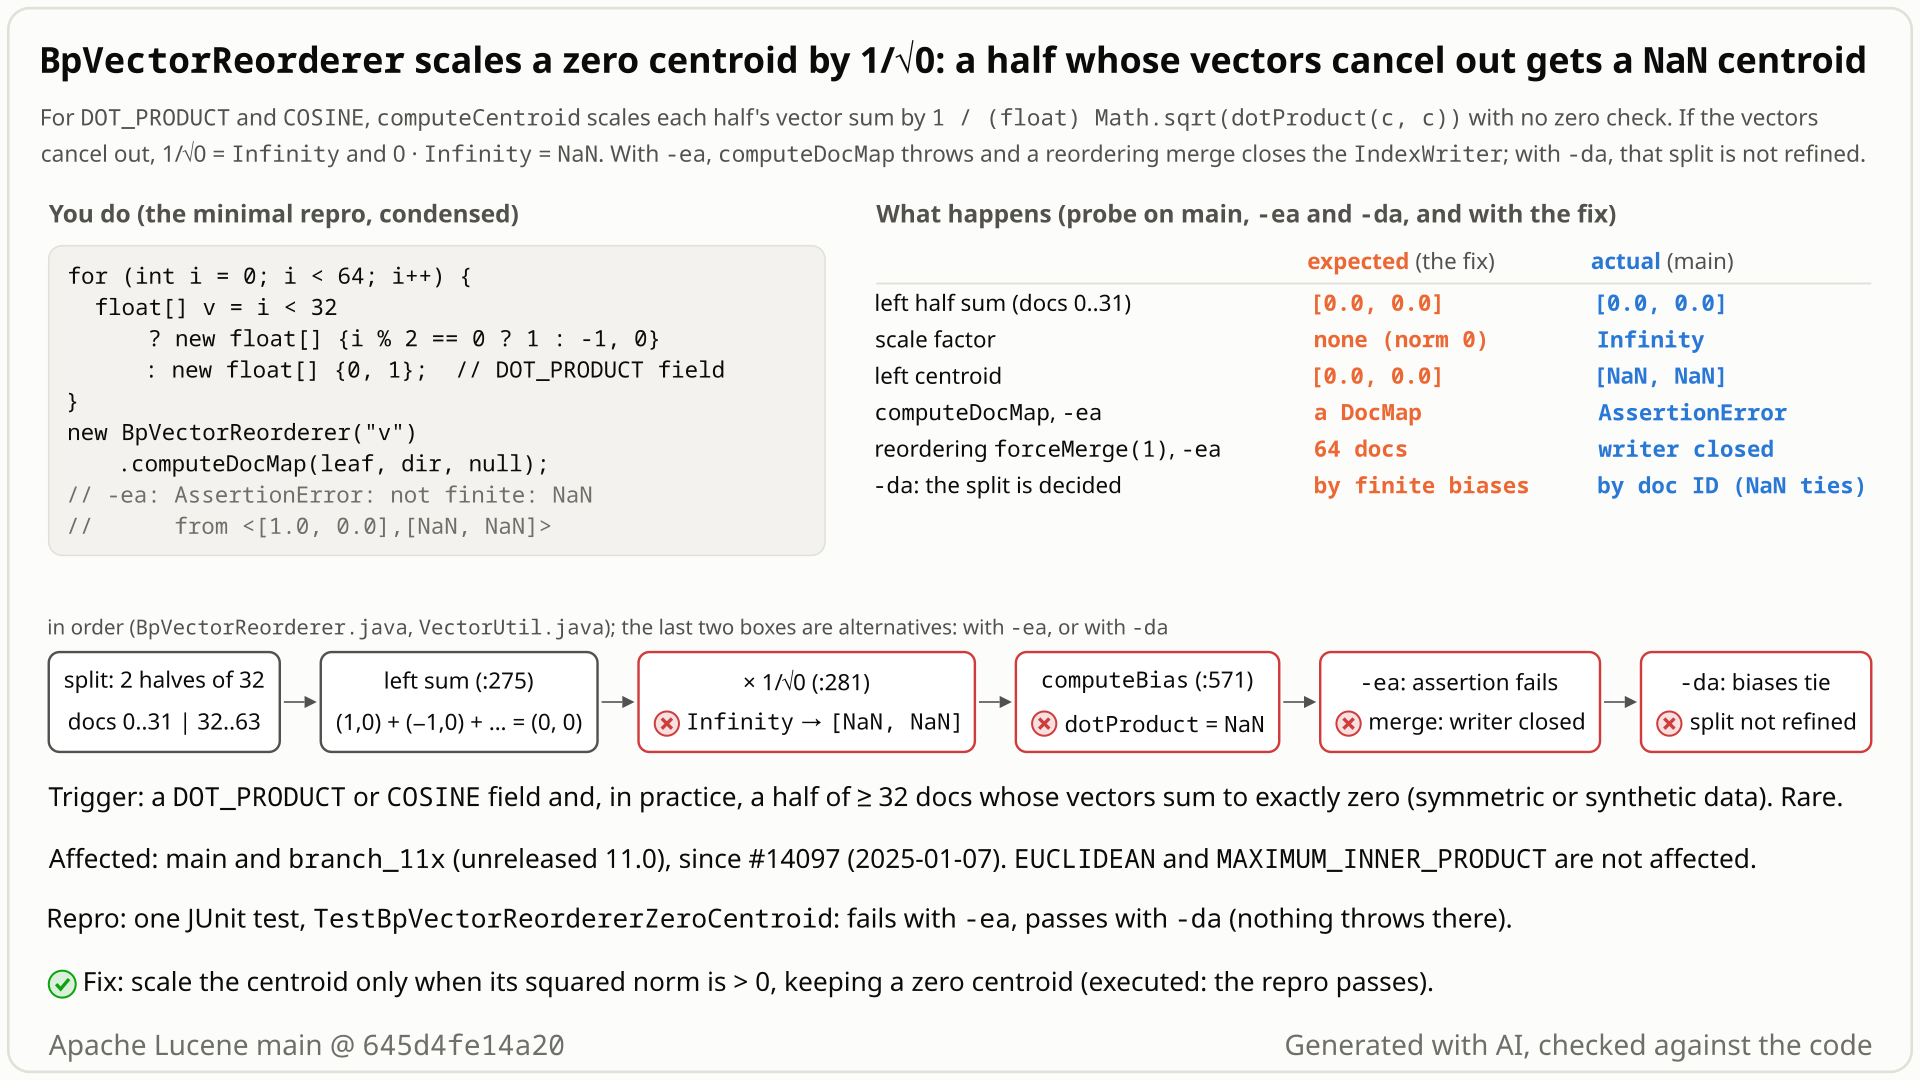
- Index 64 documents with a 2-dimensional DOT_PRODUCT vector field: docs 0-31 alternate (1, 0) and (-1, 0), docs 32-63 are (0, 1), all unit vectors. Reorder the segment with
BpVectorReorderer.computeDocMap, or merge it throughBPReorderingMergePolicy. - With the default
minPartitionSizeof 32 the reorderer splits once, docs 0-31 against docs 32-63, and describes each half by its vector sum scaled to length 1. You expect a doc map, as for any other legal vectors. - Docs 0-31 sum to (0, 0). The scale factor is 1/sqrt(0) = Infinity, and 0 × Infinity makes that half's centroid (NaN, NaN).
- With assertions on, Lucene's own finite check fails:
AssertionError: not finite: NaN from <[1.0, 0.0],[NaN, NaN]>, and a reordering merge closes the writer. With assertions off nothing throws, but that split stays in doc-ID order.
Only unreleased main and branch_11x: applications that opt into BpVectorReorderer on a DOT_PRODUCT or COSINE field, through BPReorderingMergePolicy, computeDocMap or the offline tool. In practice it takes a half of 32 or more vectors that sums to exactly zero, which needs symmetric or synthetic data. The visible failure needs assertions on, as in test suites.
Mechanism, terms and numbers522 words
BpVectorReorderer (lucene/misc; main and branch_11x, unreleased; opt-in) renumbers documents so that similar vectors get nearby doc IDs. For DOT_PRODUCT and COSINE, computeCentroid sums a half's vectors and scales the sum by 1 / (float) Math.sqrt(VectorUtil.dotProduct(centroid, centroid)) with no zero check (BpVectorReorderer.java:279-281). When the vectors of a half cancel out exactly, for example 32 documents alternating (1, 0) and (-1, 0), the sum is (0, 0), the factor is Infinity and the centroid becomes (NaN, NaN). The next dot product with it trips Lucene's own finite-result assertion (VectorUtil.java:68-75): AssertionError: not finite: NaN from <[1.0, 0.0],[NaN, NaN]>. Through BPReorderingMergePolicy that error fails the merge and IndexWriter closes as a tragic event. With assertions off nothing throws and the doc map is a valid permutation, but the NaN biases leave that split in doc-ID order. The inputs are legal unit vectors with default settings; the class comment states no non-zero precondition for the centroid, and upstream fixed a closely related NaN-centroid assertion in another class as a bug (#15209 / #15213, where the centroid had zero samples). Skipping the normalization when the squared norm is 0 fixes it; no release contains the class.
- Split.
ReorderTask.computesplits a partition in half when each half has at leastminPartitionSizedocuments (BpVectorReorderer.java:207-215; default 32,AbstractBPReorderer.java:25) and computes one centroid per half (:224-225). With 64 documents there is exactly one split, docs 0-31 against docs 32-63. - Centroid.
computeCentroid(:267-283) adds up the half's vectors. EUCLIDEAN and MAXIMUM_INNER_PRODUCT then divide by the count (:278); DOT_PRODUCT and COSINE scale by1 / (float) Math.sqrt(VectorUtil.dotProduct(centroid, centroid))(:279-281). For docs 0-31 the sum is (0, 0): the dot product is 0, sqrt(0) is 0, 1/0 is Infinity, andvectorScalarMul(:481-485) multiplies each 0 by Infinity, which gives NaN. - Bias.
computeBias(:564-574) returnsdotProduct(vector, rightCentroid) - dotProduct(vector, leftCentroid). - Assertions on.
VectorUtil.dotProduct(float[], float[])asserts a finite result (VectorUtil.java:68-75). Doc 0, (1, 0), against the NaN centroid fails it:AssertionError: not finite: NaN from <[1.0, 0.0],[NaN, NaN]>, thrown fromcomputeBias(:571) insidecomputeDocMap(:591). - On the merge path.
BPReorderingMergePolicycatches onlyNotEnoughRAMExceptionaroundcomputeDocMap(BPReorderingMergePolicy.java:133-146), andIndexWriter.mergehands anyThrowabletotragicEvent(IndexWriter.java:5109-5113), which closes the writer. - Assertions off. Every bias is NaN, so
gain(:324) andscale(:315) are NaN and the stop test500 * gain <= scale(:336) is false. The selector compares biases withFloat.compare, which treats NaN as equal to NaN, and breaks ties on doc ID (:353-357), so the split stays in doc-ID order. Recursion then continues where the halves are large enough (read; in the repro the 32-document halves are too small to split again), and the doc map is always a valid permutation.
The same line is reached after a round of swaps too, because centroids are recomputed from scratch after every round that moved documents (MAX_CENTROID_UPDATES = 0, :88, :240-248; read, not executed separately).
Exposure and likelihood411 words
- Entry points.
BPReorderingMergePolicy(forced merges were executed; natural merges are reordered too, sinceminNaturalMergeNumDocsdefaults to 1,BPReorderingMergePolicy.java:46, read only), the publiccomputeDocMap(executed), and the offlinemain()/reorderIndexDirectorytool (BpVectorReorderer.java:653-697, read only). - What it takes. A half of a split, at least 32 documents with default settings, whose float32 vector sum has a squared norm of 0. In practice that is a sum that is exactly zero: antipodal pairs such as (1, 0) and (-1, 0), or v, v, v, -3v for COSINE. Learned embeddings essentially never cancel exactly; test fixtures and generated vectors can. Strictly, a non-zero sum whose square underflows does it too: 32 COSINE vectors (
Float.MIN_VALUE, 0) sum to (4.5E-44, 0), whose squared norm is 0 (arithmetic checked throughVectorUtil.dotProduct, not run through the reorderer); the recommended fix covers that too. EUCLIDEAN and MAXIMUM_INNER_PRODUCT divide by the count and are not affected: an executed EUCLIDEAN control passes; for MAXIMUM_INNER_PRODUCT this is from the code. - With assertions on (most of Lucene's own test runs, and downstream test suites that enable them):
computeDocMapthrows, and a reordering merge fails and closes the writer. In an executed probe the 8 documents added after the last commit were lost (116 live documents instead of 124) and a fresh writer failed the same forced merge again; the last commit stayed intact and CheckIndex-clean, so the demonstrated loss is the changes since the last commit. - With assertions off (the Java default): nothing throws, the merge succeeds, every document keeps its own vector, deletes stay deleted and CheckIndex is clean. The cancelling split is just not refined. On the repro's own 64 documents stock main (assertions off) and the fixed code both return the identity doc map, so nothing differs there; on another 128-document set (docs 0-63 alternate (0, 1) and (0, -1), the rest are 48 × (0, 1) and 16 × (1, 0)) the mean dot product of adjacent documents is -0.244 on stock main and 0.496 with the fix. The cost in compression or search speed was not measured.
- Not slower, in one probe. The NaN path stops early: 16,384 64-dimensional antipodal-pair vectors took 15.5 ms against 272 ms for random unit vectors, with 0 documents moved (medians of 3 runs on one machine).
- How likely. Rare. The searches found no upstream report or CI failure of this kind since the class was added in January 2025; a search cannot prove there is none.
One JUnit test, one method: 64 legal DOT_PRODUCT unit vectors in one segment, then computeDocMap with default settings. Public API only, single thread; it failed at every seed tried, and the test method takes about 0.2 s. It fails with assertions on (-Ptests.asserts=true); with them off it passes, which is the bug's quiet path, not a fix.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.misc.index;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.KnnFloatVectorField;
import org.apache.lucene.index.CodecReader;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.VectorSimilarityFunction;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestBpVectorReordererZeroCentroid extends LuceneTestCase {

  public void testHalfThatSumsToZero() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        for (int i = 0; i < 64; i++) {
          float[] v = i < 32 ? new float[] {i % 2 == 0 ? 1 : -1, 0} : new float[] {0, 1};
          Document doc = new Document();
          doc.add(new KnnFloatVectorField("v", v, VectorSimilarityFunction.DOT_PRODUCT));
          w.addDocument(doc);
        }
      }
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        CodecReader leaf = (CodecReader) r.leaves().get(0).reader();
        // expected a DocMap; actual: docs 0..31 sum to (0, 0), the centroid is scaled by 1/sqrt(0) to NaN
        assertNotNull(new BpVectorReorderer("v").computeDocMap(leaf, dir, null));
      }
    }
  }
}
cp TestBpVectorReordererZeroCentroid.java $LUCENE/lucene/misc/src/test/org/apache/lucene/misc/index/
cd $LUCENE && ./gradlew :lucene:misc:test --tests org.apache.lucene.misc.index.TestBpVectorReordererZeroCentroid -Ptests.seed=DEADBEEF -Ptests.asserts=true
# -Ptests.asserts=false: the test passes (nothing throws; the split is just not refined)
- Expected
computeDocMapreturns a doc map, as it does for any other legal vectors.- Observed
AssertionError: not finite: NaN from <[1.0, 0.0],[NaN, NaN]>fromVectorUtil.dotProduct, called byBpVectorReorderer$ComputeBiasTask.computeBias(BpVectorReorderer.java:571).
More files, environment, full output290 words
The test sits in org.apache.lucene.misc.index next to the upstream TestBpVectorReorderer and uses only public API. It asserts only that a doc map comes back; the failure is Lucene's own assertion, whose message shows the NaN centroid. It failed at every seed tried (DEADBEEF, and 5EED1234 with 5 iterations). The reorderer's arithmetic uses no randomness, but LuceneTestCase randomizes the default codec behind new IndexWriterConfig(), and only these seeds were run.
It does not assert the effect with assertions off, because reorder quality is not part of the DocMap contract and on this data even the fixed code returns the identity order.
Not shown by this one test, all from the same line and executed elsewhere: the COSINE variant, the BPReorderingMergePolicy merge that closes the writer (isOpen() false, the AssertionError as tragic exception), and the unrefined split with assertions off.
As the regression test: the same test, for example as a new method of TestBpVectorReorderer. The comment on line 44 is over the 100-column limit, so ./gradlew tidy wraps it; nothing else changes. With that, :lucene:misc:check -x test (google-java-format, ecj lint, forbidden APIs) passes with the recommended fix.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); no release contains BpVectorReorderer |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestBpVectorReordererZeroCentroid.java $LUCENE/lucene/misc/src/test/org/apache/lucene/misc/index/
cd $LUCENE && ./gradlew :lucene:misc:test --tests org.apache.lucene.misc.index.TestBpVectorReordererZeroCentroid -Ptests.seed=DEADBEEF -Ptests.asserts=true
# -Ptests.asserts=false: the test passes (nothing throws; the split is just not refined)
# gradle, main 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true
TestBpVectorReordererZeroCentroid > testHalfThatSumsToZero FAILED
    java.lang.AssertionError: not finite: NaN from <[1.0, 0.0],[NaN, NaN]>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:28C0EB26BD6F4DE9]:0)
        at org.apache.lucene.core@11.0.0-SNAPSHOT/org.apache.lucene.util.VectorUtil.dotProduct(VectorUtil.java:74)
        at org.apache.lucene.misc.index.BpVectorReorderer$ComputeBiasTask.computeBias(BpVectorReorderer.java:571)
        at org.apache.lucene.misc.index.BpVectorReorderer$ComputeBiasTask.compute(BpVectorReorderer.java:552)
        at org.apache.lucene.misc.index.BpVectorReorderer$ReorderTask.shuffle(BpVectorReorderer.java:313)
        at org.apache.lucene.misc.index.BpVectorReorderer$ReorderTask.compute(BpVectorReorderer.java:233)
        at org.apache.lucene.misc.index.BpVectorReorderer.computePermutation(BpVectorReorderer.java:627)
        at org.apache.lucene.misc.index.BpVectorReorderer.computeValueMap(BpVectorReorderer.java:606)
        at org.apache.lucene.misc.index.BpVectorReorderer.computeDocMap(BpVectorReorderer.java:591)
        at org.apache.lucene.misc.index.TestBpVectorReordererZeroCentroid.testHalfThatSumsToZero(TestBpVectorReordererZeroCentroid.java:45)

1 test completed, 1 failed

# gradle, same seed, -Ptests.asserts=false: :lucene:misc:test (SUCCESS): 1 test- The class comment sets no non-zero precondition; a zero sum has no direction, so keeping a zero centroid is natural.
- Lucene's own arithmetic makes the NaN from legal unit vectors and default settings, and it trips Lucene's own finite-result assertion.
- Upstream fixed a closely related NaN-centroid assertion elsewhere as a bug (#15209 / #15213, a centroid with zero samples).
The full argument330 words
- The class comment sets no non-zero precondition.
BpVectorReorderer.java:57-75derives the centroid assum(v) / n. Its last sentence starts with the max-inner-product case and ends: "since all collinear vectors of whatever scale will generate the same partition for these angular scores, we are free to choose any scale and ignore the normalization factor" (:71-74). It says nothing about a zero sum, which has no direction to normalize; keeping it as a zero centroid is a natural convention, though the comment does not settle it. - Legal input, default settings. (1, 0), (-1, 0) and (0, 1) are unit vectors, as the DOT_PRODUCT javadoc asks (
VectorSimilarityFunction.java:52-58);KnnFloatVectorField's value checks reject non-finite components (KnnFloatVectorField.java:105) and, for COSINE, the all-zero vector (:53-56); its other checks cover null, empty and over-long vectors. - The assertion predates the class. The finite-result assertion in
VectorUtil.dotProductcame with #12281 (2023); #15213 (2025) only added its "not finite" message. The reorderer was written against it. - Upstream treats this symptom as a bug. In #15209 a NaN centroid tripped the same assertion in the scalar-quantization writer. benwtrent wrote "it does smell like a bug. The centroid is
nan", and msokolov, who also wroteBpVectorReorderer, answered "Seems like divide by zero when there are no samples. I'll post a fix". #15213 fixed that writer only. The zero centroid there came from an empty sample set, not from cancellation: a close precedent, not the same root cause. - The merge policy avoids failing merges over reordering, for low RAM. Its javadoc: when reordering lacks RAM, "it simply skips reordering in order not to fail the merge" (
BPReorderingMergePolicy.java:34-39). That covers only the out-of-RAM case: a hint of intent, not a contract for this one. - No comment, test or discussion covers a zero sum. The upstream DOT_PRODUCT test uses random angles on the unit circle (
TestBpVectorReorderer.java:272-310), so no half cancels; the #14097 review ofcomputeCentroidwas about a stray semicolon.
The devil's-advocate check219 words
The strongest case for "not a bug": the failure is an assertion, so production (assertions off) never throws; the doc map is then a valid permutation and the DocMap contract promises no reorder quality; the data is degenerate (an exactly cancelling half of 32 or more vectors); and the class is unreleased and, in its author's words in #15219, "hasn't gotten a lot of real-world testing".
Why it fails: Lucene uses these assertions as invariants and runs most of its own tests with them on (about 75% of seeds by default), so legal input that trips one is a bug, as #15209 / #15213 show for the same assertion with a close mechanism (a centroid normalized with zero samples). The DocMap contract indeed promises no reorder quality, so the case rests on that invariant and on the effect with assertions off, which is not a designed fallback: it works only because Float.compare orders NaN and ties break on doc ID, and it skips refinement that the fixed code performs (-0.244 against 0.496 on the 128-document set). Degenerate but legal data lowers the priority, not the validity. GPT review lenses rated the intended argument weak; a later GPT fact check rated it moderate and still called it a bug, because of the effect with assertions off and the #15213 precedent.
Recommended Skip the normalization when the squared norm is 0
Skip the normalization when the half's squared norm is 0 and keep the zero centroid (a few lines in computeCentroid). The repro then passes with assertions on and off, and the whole lucene/misc test suite passes (317 tests, 0 failures).
case DOT_PRODUCT, COSINE -> {
  float norm2 = VectorUtil.dotProduct(centroid, centroid);
  // vectors that cancel out (e.g. v and -v) have no direction: keep the zero centroid
  // rather than scaling it by 1/0, which turns it into NaN
  if (norm2 > 0) {
    vectorScalarMul(1 / (float) Math.sqrt(norm2), centroid);
  }
}
All options and trade-offs3 options · 551 words
One option was validated with gradle on 645d4fe14a20; a second was run as a data point; a third is a design question.
In computeCentroid, compute the squared norm once and scale only when it is positive, so a half whose vectors cancel keeps the zero centroid. A zero centroid adds 0 to every bias, so documents are placed by the other half's centroid alone and the split is still refined. This is the finder's guard.
case DOT_PRODUCT, COSINE -> {
  float norm2 = VectorUtil.dotProduct(centroid, centroid);
  // vectors that cancel out (e.g. v and -v) have no direction: keep the zero centroid
  // rather than scaling it by 1/0, which turns it into NaN
  if (norm2 > 0) {
    vectorScalarMul(1 / (float) Math.sqrt(norm2), centroid);
  }
}
Trade-offs
- Nothing changes for a half whose squared norm is positive: the same expression runs.
- When both halves are zero, gain and scale are 0 and the existing stop test ends the round.
- Matches the class comment ("free to choose any scale") and the "don't normalize" fix of #15213.
- Open PR #15430, which moves the class to core, copies the unguarded line and would need the same change.
- The guard targets a squared norm of 0, including a sum of tiny vectors whose square underflows. A squared norm that overflows to Infinity (very large COSINE vectors) is a separate edge it leaves as it is: with assertions on,
VectorUtil.dotProduct(centroid, centroid)itself asserts; with them off the factor is 0 and the centroid becomes zero (arithmetic checked, not run through the reorderer).
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20: the repro fails on stock main with assertions on and passes with this fix, with-Ptests.asserts=trueand=false. - With the fix:
TestBpVectorReorderer8 tests, 0 failures; the wholelucene/miscsuite 24 classes, 317 tests, 0 failures, 9 skipped;:lucene:misc:check -x testpasses with the repro test in place once./gradlew tidyhas wrapped its long comment. - Earlier runs of the same guard: an independent 4-test reproducer (DOT_PRODUCT, COSINE, merge path, EUCLIDEAN control) 4 of 4 with assertions on, and the merge in the integrity probe completes with assertions on.
- On the 128-document set it reorders the split that stock main leaves in doc-ID order (mean adjacent dot product 0.496 against -0.244).
Use sum(v) / n, the centroid the class comment derives, for DOT_PRODUCT and COSINE too. A zero sum then stays zero.
Trade-offs
Changes the centroids, and possibly the order, for DOT_PRODUCT and COSINE inputs whose two halves' mean vectors differ in length: the bias becomes dot(v, sumR / nR - sumL / nL) instead of dot(v, unit(sumR) - unit(sumL)). It would need a reorder-quality benchmark.
What the checks validated
Data point only: with this change the repro passes with assertions on and the 8 upstream TestBpVectorReorderer tests pass (gradle, seed DEADBEEF); no quality comparison was run.
Whether COSINE centroids should sum each document's normalized vector, so every document weighs the same, rather than the raw vectors.
Trade-offs
A separate change; untested. It does not remove the zero case by itself, because antipodal unit vectors still cancel.
Downstream code on main that enables BpVectorReorderer and runs its tests with assertions on can see reordering and merges fail on symmetric synthetic vectors; with assertions off the index stays intact and only some reordering is lost.
Semi-formal: a bounded-exhaustive harness ran computeDocMap from the real jar on every segment of up to 7 documents with 1-dimensional vectors (-1, 0 or +1; no 0 for DOT_PRODUCT, COSINE) for all four similarities. With assertions on it hit 12,736 'not finite: NaN' failures; with them off, 0 doc-map violations in 401,744 checks. A JUnit test with default settings followed.
The method in full160 words
Method: bounded-exhaustive translation validation (the study's "semi-formal" tier). The harness enumerated every segment of up to 7 documents, each with no vector or a 1-dimensional vector in {-1, 0, +1} (without 0 for DOT_PRODUCT and COSINE, which ask for unit or non-zero vectors), under all four similarity functions, with minPartitionSize 1 or 2 and maxIters 1 or 20, and checked each computeDocMap result from the stock main jar against the DocMap contract (a permutation of the live documents).
- With assertions on: 12,736 runs failed with
AssertionError: not finite: NaN, for example the DOT_PRODUCT segment (-1), (1), (-1) withminPartitionSize1, whose second half (1), (-1) sums to 0. - With assertions off: 401,744 checks, 0 violations, 0 exceptions. So every doc map in this domain was valid; the defect is the NaN itself.
The finder then wrote a JUnit test with default settings (128 documents, computeDocMap and a reordering merge), which was later reduced to the one 64-document test above.
No prior report found: 164 queries and checks over GitHub issues, PRs and commits, four downstream projects, the mailing lists, JIRA and the web (2026-10-26), refreshed 2026-11-01. Closest precedent: #15209 / #15213, the same NaN-centroid assertion, fixed in another class.
Searches6 searches
No issue, PR, review comment, commit, mailing-list post, JIRA entry, downstream report or web page describes this bug, and no merged or open change guards the normalization. #15209 / #15213 is a precedent, not an earlier report: it fixed a NaN centroid with zero samples in Lucene104ScalarQuantizedVectorsWriter only, and neither thread mentions the reorderer. Limits: keyword search only; GitHub search does not match diffs; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | a scripted prior-report search (40 issue/PR and 3 commit queries) and 44 manual GraphQL searches: class and method names (BpVectorReorderer, BPReorderingMergePolicy, computeCentroid, computeBias, vectorScalarMul), symptom phrases ("not finite: NaN", "zero centroid", "divide by zero") | no report; related items #14097 (introduced it), #13683, #13565, #14117, #14110, #14143, #15219, #15285, #15430 |
| Open apache/lucene PRs | 2026-10-26 | changed-file lists of all 411 open PRs | five touch the reorderer files; none guards the line; #15430 copies it into core |
| Downstream projects | 2026-10-26 | GitHub searches in elastic/elasticsearch, opensearch-project/OpenSearch, opensearch-project/k-NN and apache/solr | no report; no use of BpVectorReorderer found |
| Mailing lists and JIRA archive | 2026-10-26 | 20 scripted queries; 24 direct archive queries over dev@, java-user@, issues@, commits@ and builds@, plus a check that builds@ is searchable; 4 JIRA-archive queries | no report (only mirrors of the GitHub items) |
| Web | 2026-10-26 | 6 scripted queries and 7 general searches | no report |
| GitHub refresh | 2026-11-01 | GraphQL searches for items updated since 2026-10-25 (BpVectorReorderer, BPReorderingMergePolicy, "not finite" NaN, centroid NaN), with a control search; the file's commit list on upstream main | nothing new; the file has no new commit and #15430 is unchanged |
Since 02a09f6ab124 (#14097, 2025-01-07), which added the class; the line never changed. Unreleased: main and branch_11x have it, no release through 10.6.0 does, and open PR #15430 copies the line into core.
Versions tested9 rows
Introduced by 02a09f6ab124 "HNSW BP reordering (#14097)" by Michael Sokolov, 2025-01-07. git blame of computeCentroid shows only this commit, and git log -S on the normalization expression returns only it. Later commits to the file, b7c7fe064ce1 (#14117, stopping heuristic) and 54283150a81 (#16255, build checks; in this file only a typo fix in the class comment), do not touch it. The finite assertion is older (#12281, 2023), so this is not a regression: the class behaved this way from its first commit.
CHANGES.txt lists GITHUB#14097 under 11.0.0. No release has the class yet; 11.0.0 would ship it unless fixed.
| Version or commit | Verdict | Result |
|---|---|---|
72d93de50c2d (parent of the introducing commit) | no class | the repro does not compile |
02a09f6ab124 (#14097, introducing) | affected | fails with assertions on, passes with them off; the guard fixes it there |
b7c7fe064ce1 (#14117) | affected | fails with assertions on, passes with them off |
main ea57360912ed, a9779ef3c193, 645d4fe14a20 | affected | fails with assertions on, passes with them off (gradle and standalone on 645d4fe14a20) |
upstream main f815e679bf6c (2026-11-01) | read | the same unguarded code |
branch_11x 603af870375 (2026-10-29) | read | the same file (the same blob as at 645d4fe14a20; 02a09f6ab124 is an ancestor); not run |
| 9.12.3, 10.1.0, 10.2.0, 10.5.2 | no class | the repro does not compile |
| all 68 release tags through 10.6.0; branch_10x, branch_10_6, branch_10_5 | no class | the file is absent; the 10.6.0 misc jar has no BpVectorReorderer class |
| open PR #15430 (BP Reordering Codec) | read | moves the class to core and copies the unguarded line |
Every check that ran code reproduced it: the finder, an independent reproducer, the intended-behaviour devil's advocate, the adjudication and a credibility audit. Read-only reviews by a model from another family agreed on the root cause; one said "not real" on procedure only. The audit downgraded it to minor because only assertions fail.
Checks and verdicts337 words
Each check worked from the claim and its own evidence; the cross-model reviews (OpenAI GPT-5.6) could not run code (reading only), so separate runs ran the repro for them.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | Bounded-exhaustive check (12,736 assertion failures on, 0 doc-map violations in 401,744 checks off); JUnit 2 of 2 fail on, 0 of 2 off; guard 2 of 2 and the 8 upstream tests pass. |
| cross-model review, intended lens (OpenAI GPT-5.6) | real (medium) | Root cause agreed, inputs in contract, intended argument weak; read-only, a separate re-run failed 2 of 2. |
| Independent reproducer | real | Own JUnit: DOT_PRODUCT, COSINE and the merge path fail with assertions on (writer closed), EUCLIDEAN control passes; 30 of 30 over 10 iterations; also with the scalar vector code; 0 of 4 off; own guard 4 of 4. |
| Cross-model adversary, refute lens (OpenAI GPT-5.6) | not real (low), procedural | Could not run code and called its verdict "not a substantive refutation"; on substance it agreed with the root cause and found the inputs in contract. |
| Intended-behaviour devil's advocate | real; not intended | No intended, misuse or unreachability argument survives; the probe with assertions off shows the unrefined split (-0.244 against 0.496). |
| adjudication | confirmed (high) | Re-ran the independent reproduction's test (3 of 4 fail at two seeds, 0 of 4 off), the finder's test and the guard. |
| security screen | none | Executed probe: index intact with assertions off; writer close and lost uncommitted documents with them on. |
| credibility audit | downgrade to minor | Re-ran stock on and off and the guard; an assertion-only failure is not a production crash. |
| this doc | reproduced; fix validated | Gradle on 645d4fe14a20: fails on, passes off; with the guard the repro, TestBpVectorReorderer and the whole lucene/misc suite pass. |
| fact checks of this doc (Claude; OpenAI GPT-5.6, read-only) | real; wording corrected | Re-ran the repro (stock on and off, the guard) and the gradle command, and probed the repro's doc map; the corrections are applied. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 447 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,227 words
- Registry title
- BpVectorReorderer scales a zero DOT_PRODUCT/COSINE centroid by 1/sqrt(0), so a split whose vectors cancel out gets a NaN centroid: with assertions on, reordering fails and a reordering merge closes the IndexWriter; with assertions off, that split is silently not refined
- Area
- misc / BP merge-time reordering (BpVectorReorderer centroid arithmetic)
- Priority
- Low, rank 1180: This unreleased NaN centroid shows only with assertions on, on contrived exactly-cancelling vectors, and the audit downgraded it.
- Impact class
- minor
- Impact note
- Only applications on unreleased main and branch_11x (11.0.0-SNAPSHOT) that opt into the lucene/misc BpVectorReorderer (through BPReorderingMergePolicy, computeDocMap or the offline tool) on a DOT_PRODUCT or COSINE float vector field, and only when the vectors of one half of a recursive split (at least minPartitionSize, default 32, documents) sum to exactly zero in float32, as with symmetric or synthetic data such as alternating (1,0)/(-1,0): with Java assertions enabled (-ea, for example test suites) reordering throws AssertionError and a reordering merge closes the IndexWriter as a tragic event, losing the uncommitted documents; with assertions disabled (the production default) nothing throws, the DocMap is a valid permutation and the only effect is that this split stays in doc-ID order; ordinary scale (64 documents suffice).
- Summary
- You index DOT_PRODUCT or COSINE float vectors and reorder them with BpVectorReorderer, by calling computeDocMap or by merging through BPReorderingMergePolicy, for example 64 legal unit vectors where docs 0..31 alternate (1,0) and (-1,0) and docs 32..63 are (0,1); you expect a valid reordering, as for any other legal vectors. Instead the half whose vectors cancel out sums to the zero vector, computeCentroid normalizes it by 1/sqrt(0) = Infinity and the centroid becomes NaN. With assertions on, VectorUtil.dotProduct then fails with 'AssertionError: not finite: NaN from <[1.0, 0.0],[NaN, NaN]>' and the merge path closes the IndexWriter; with assertions off nothing throws, but the NaN biases leave that split in doc-ID order.
- Introduced
- 02a09f6ab124 (#14097 'HNSW BP reordering' by msokolov, main) [exec: the finder's repro fails 2 of 2 with -ea and passes with -da at 02a09f6ab124, passes there with the one-line guard shadowed, and does not compile at its parent 72d93de50c2d, which has no BpVectorReorderer; read: git blame and git log -S show that every line of computeCentroid, including the unguarded 1 / (float) Math.sqrt(VectorUtil.dotProduct(centroid, centroid)), comes from 02a09f6ab124 and never changed]; the finite-result assertion in VectorUtil.dotProduct predates the class (071461ece541, #12281, 2023-06-13; #15213 only added the 'not finite' message); not a regression: the class has had this behaviour since it was added (2025-01-07)
- First affected version
- unreleased (main and branch_11x, 11.0.0-SNAPSHOT; CHANGES.txt lists GITHUB#14097 under 11.0.0 and no release tag contains BpVectorReorderer)
- Affected versions
- main from 02a09f6ab124 (2025-01-07) through 645d4fe14a20 [exec: 02a09f6ab124, b7c7fe064ce1 (#14117, the only later behavioural change to the class) and ea57360912ed fail 2 of 2 with -ea and pass with -da; a9779ef3c193 and 645d4fe14a20 fail with -ea and pass with -da]; branch_11x 603af870375 has the same file and contains 02a09f6ab124 [read]; upstream main cf398bfb142c (2026-10-26) still has the unguarded line [read]; open PR #15430 (moves the class to core) copies it [read]. Not affected: 9.12.3, 10.1.0, 10.2.0 and 10.5.2, where the repro does not compile because BpVectorReorderer does not exist [exec]; every release tag through 10.6.0 and branch_10x, branch_10_6 and branch_10_5 lack the file [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, all read-only: 164 logged queries and checks, namely a scripted prior-report search with 40 GitHub issue/PR, 3 commit, 2 downstream-repo, 20 mailing-list (dev@, java-user@, issues@, commits@), 4 JIRA-archive and 6 web queries; 44 manual GitHub GraphQL searches, including elastic/elasticsearch, opensearch-project/OpenSearch, opensearch-project/k-NN and apache/solr; 24 direct mailing-list archive queries over builds@, dev@, issues@, commits@ and java-user@; 7 web searches; a changed-file scan of all 411 open PRs; the body, comments and review comments of #14097 read; the finder's run, the independent reproduction and the intended-behaviour check found nothing either); precedent, not a report of this bug: #15209 / #15213 (the same 'not finite: NaN' assertion from normalizing a centroid with no samples, fixed in Lucene104ScalarQuantizedVectorsWriter only); related items: #14097 (introduced it), #13683, #13565, #14117, #14110, #14143, #15219; open #15430 (moves the class to core and keeps the unguarded line) and #15285 (renames dotProduct, same assertion) would carry it along
- Lucene commit tested
- main
645d4fe14a20(the minimal repro through gradle with-Ptests.asserts=trueand=falseon stock main and with fix A, and with=trueunder fix B; fix A withTestBpVectorReorderer, the wholelucene/misctest suite and:lucene:misc:check -x test; fix B withTestBpVectorReorderer, assertions on; standalone runs with assertions on and off and a second seed; a doc-map probe of the repro's 64 documents, stock with assertions off and fix A with them on); by the hunt and its verifiers, mainea57360912edanda9779ef3c193and the commits02a09f6ab124(introducing),b7c7fe064ce1and72d93de50c2d(its parent: does not compile); the repro does not compile on 9.12.3, 10.1.0, 10.2.0 and 10.5.2, and no release tag through 10.6.0 has the class (read). Every Lucene source file cited with a line number here is byte-identical atea57360912ed,645d4fe14a20andbranch_11x603af870375(read, blob ids);lucene/CHANGES.txtis not, so its line number is given for645d4fe14a20. The code is unchanged on upstream mainf815e679bf6c(2026-11-01, read).
- Finding record
a Lucene main checkout lucene/misc/src/java/org/apache/lucene/misc/index/BpVectorReorderer.java:57-74 (class comment: the centroid is sum(v)/n; 'we are free to choose any scale and ignore the normalization factor'), :267-283 (computeCentroid; :279-281 scale DOT_PRODUCT/COSINE sums by 1 / (float) Math.sqrt(VectorUtil.dotProduct(centroid, centroid)) with no zero check), :481-485 (vectorScalarMul), :564-574 (computeBias calls VectorUtil.dotProduct with the centroids), :230-237 (maxIters loop), :336 (stop test '500 * gain <= scale'), :353-357 (Float.compare with doc-ID tie-break), :578-593 (computeDocMap)a Lucene main checkout lucene/core/src/java/org/apache/lucene/util/VectorUtil.java:63-77 (dotProduct: 'assert Float.isFinite(r) : "not finite: ..."')a Lucene main checkout lucene/misc/src/java/org/apache/lucene/misc/index/BPReorderingMergePolicy.java:34-39 (javadoc: skips reordering when RAM is short 'in order not to fail the merge'), :46 (minNaturalMergeNumDocs = 1), :133-146 (reorder catches only NotEnoughRAMException)a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:5109-5113 (any Throwable in a merge calls tragicEvent)a Lucene main checkout lucene/misc/src/java/org/apache/lucene/misc/index/AbstractBPReorderer.java:25, :31 (DEFAULT_MIN_PARTITION_SIZE = 32, DEFAULT_MAX_ITERS = 20)a Lucene main checkout lucene/CHANGES.txt:158 (GITHUB#14097 under 11.0.0)
- The finding in 30 seconds
lucene/misc/src/java/org/apache/lucene/misc/index/BpVectorReorderer.java:207-215, :224-225, :240-248, :267-283 (:279-281), :315, :324, :336, :353-357, :481-485, :564-574, :591lucene/misc/src/java/org/apache/lucene/misc/index/AbstractBPReorderer.java:25, :31lucene/misc/src/java/org/apache/lucene/misc/index/BPReorderingMergePolicy.java:133-146lucene/core/src/java/org/apache/lucene/util/VectorUtil.java:63-77lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:5109-5113
- Who is affected
lucene/misc/src/java/org/apache/lucene/misc/index/BPReorderingMergePolicy.java:46, :133-146lucene/misc/src/java/org/apache/lucene/misc/index/BpVectorReorderer.java:653-697 (main, reorderIndexDirectory)
- Minimal repro
build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/TestsAndRandomizationPlugin.java:240-248 (tests.asserts default)
- Why it looks unintended
lucene/misc/src/java/org/apache/lucene/misc/index/BpVectorReorderer.java:57-75 (class comment; quote at :72-74)lucene/core/src/java/org/apache/lucene/index/VectorSimilarityFunction.java:52-58lucene/core/src/java/org/apache/lucene/document/KnnFloatVectorField.java:53-56, :105lucene/misc/src/java/org/apache/lucene/misc/index/BPReorderingMergePolicy.java:34-39lucene/misc/src/test/org/apache/lucene/misc/index/TestBpVectorReorderer.java:272-310build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/TestsAndRandomizationPlugin.java:240-248 (tests.asserts default: on for about 75% of seeds)
- History
lucene/CHANGES.txt:164 (:158 at ea57360912ed, :174 on branch_11x)a Lucene clone origin/branch_11x 603af870375 (git rev-parse of BpVectorReorderer.java: blob f2b987b3a516, as at 645d4fe14a20; merge-base --is-ancestor 02a09f6ab124)
- TestBpVectorReordererZeroCentroid.java (JUnit, one test):
repro/LFV-421/src/org/apache/lucene/misc/index/TestBpVectorReordererZeroCentroid.java(49 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the repro's input and output.
assets/LFV-421/bug.png(447 KB)