SortRescorer.rescore(searcher, hits, topN) re-sorts first-pass hits by a Sort and keeps the best topN. Which hits are kept, their order and their sort values are computed from each hit's own score. Only the last step, which writes ScoreDoc.score back, pairs hits by position instead of by document.
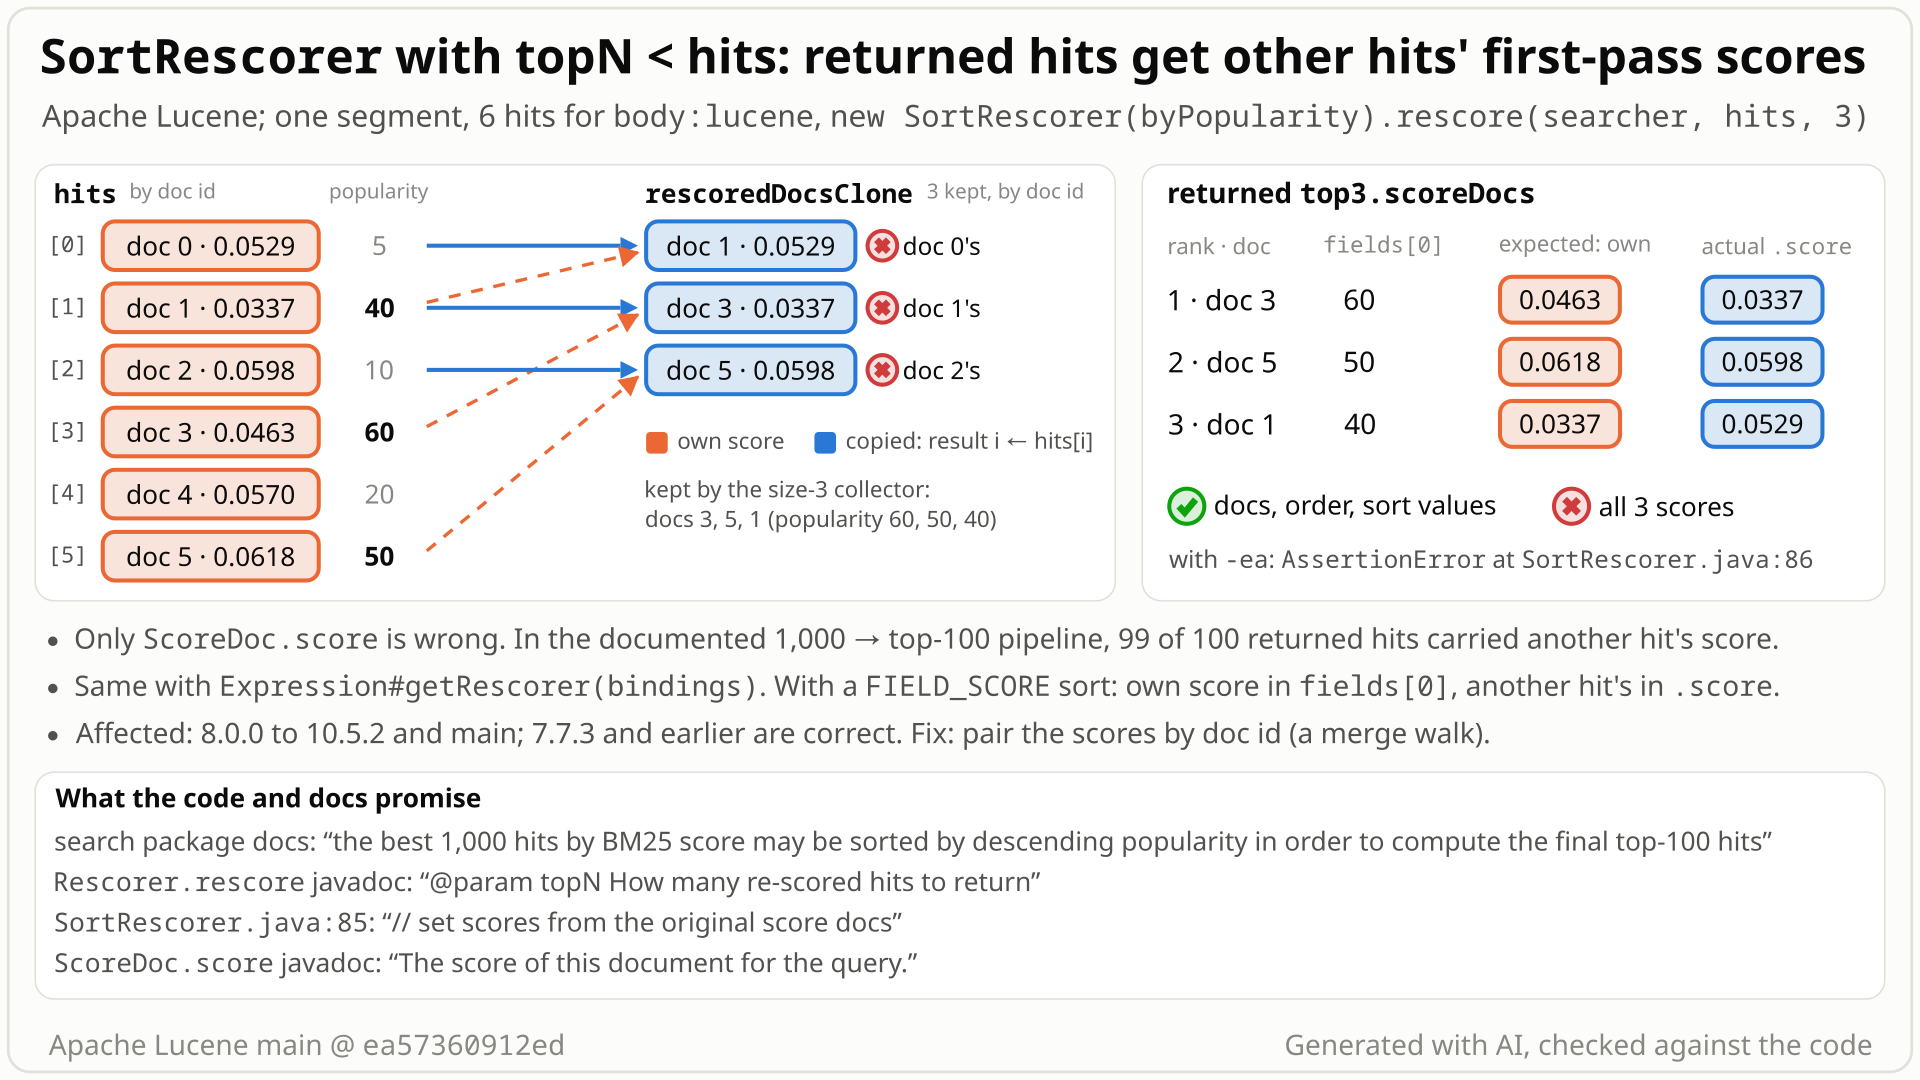
hits[i], so doc 1 gets doc 0's score, doc 3 doc 1's and doc 5 doc 2's, while the documents, order and sort values stay right. Select the still to open it at full size. Generated with AI, checked against the code.- Search
body:luceneover six documents: BM25 ranks doc 5 first (0.0618) and doc 1 last (0.0337). Re-sort the 6 hits bypopularityand keep 3:new SortRescorer(sort).rescore(searcher, hits, 3), as the search package docs suggest for "the best 1,000 hits" and "the final top-100". - You expect the 3 most popular, docs 3, 5, 1 (popularity 60, 50, 40), each with its own first-pass score: 0.0463, 0.0618, 0.0337.
- You get docs 3, 5, 1 in that order with the right sort values, but with scores 0.0337, 0.0598, 0.0529: those of docs 1, 2 and 0. No error; with assertions on, an
AssertionErroratSortRescorer.java:86instead. - Why: to put scores back,
rescoresorts the 3 kept hits by doc id (1, 3, 5) and copies, position by position, the scores of all 6 hits sorted by doc id (0, 1, 2, ...). A kept hit gets its own score only if no hit with a smaller doc id was dropped; here docs 0, 2 and 4 were dropped, so none does. - In a probe of the documented pipeline (1,000 hits re-sorted to a top 100) 99 of 100 kept hits had a wrong score. Rescoring with topN equal to the number of hits is correct. Fix: pair the scores by doc id.
Anyone who calls SortRescorer or Expression#getRescorer with topN below the number of first-pass hits, the use the search docs describe, and then reads ScoreDoc.score: to show scores, apply a threshold or combine with another pass. Documents and order stay right. Default codec and settings, any index size, every release since 8.0.0.
Mechanism, terms and numbers828 words
SortRescorer.rescore(searcher, firstPassTopDocs, topN) re-sorts first-pass hits by a Sort and keeps the best topN; the search package docs give exactly this use: "the best 1,000 hits by BM25 score may be sorted by descending popularity in order to compute the final top-100 hits". Since 8.0.0 the method puts the first-pass scores back on the kept hits by position: it sorts the kept hits by doc id and gives the i-th of them the score of the i-th first-pass hit by doc id. That is sure to pair each hit with itself only when no hit was dropped, which is what the assert just before the copy assumes; otherwise a kept hit keeps its own score only if no hit with a smaller doc id was dropped. With topN smaller than the number of hits, the documents, their order and their FieldDoc sort values are right, but kept hits typically carry other hits' scores (how many depends on the sort; none with a FIELD_DOC sort): keeping 3 of 6 hits, docs 3, 5, 1 come back with the scores of docs 1, 2, 0, and in a probe of the documented 1,000 -> 100 pipeline 99 of 100 kept hits had a wrong score. With assertions enabled every call with topN < hits throws AssertionError at SortRescorer.java:86. Expression#getRescorer returns an ExpressionRescorer, which extends SortRescorer without overriding rescore, and behaves the same. 4.8.0 to 7.7.3 returned each hit's own score; the copy and the assert came with LUCENE-8412 (55bfadbce115, released in 8.0.0). The fix pairs the scores by doc id instead of by position.
- Rescorer: takes the top hits of a cheap first search and re-orders them with something more expensive.
Rescorer.rescore(searcher, firstPassTopDocs, topN)returns "How many re-scored hits to return" (Rescorer.java:40). SortRescorer(sort): a rescorer that re-sorts the first-pass hits by aSort(a field such as popularity, the score itself, or an expression).Expression#getRescorer(bindings)returns anExpressionRescorer, aSortRescorersubclass that only adds a more detailedexplain.- Doc id: a document's number in the index. The first-pass hits come best first;
SortRescorerworks on them in doc-id order.
rescoreclones the first-pass hits and sorts the clone by doc id (SortRescorer.java:41-44).- It creates a field-sorted collector that keeps the best
min(topN, hits)entries (TopFieldCollectorManager(sort, topN, null, Integer.MAX_VALUE),:48-49) and feeds it every hit, in doc-id order, with that hit's own score (:57-82, the score at:77). So the kept set, its order and the sort values (alsoFIELD_SCOREand expressions over_score) are right. - The collector's
topDocs()(:84) carries no scores (NaN): a field-sorted collector does not track them since LUCENE-8412 (executed:[doc 3 fields[0]=60 score=NaN] ...). - To put scores back (
:85-91, comment "set scores from the original score docs") it sorts the kept hits by doc id and runsrescoredDocsClone[i].score = hits[i].score(:90), wherehitsholds all first-pass hits by doc id. The k-th smallest kept doc id gets the score of the k-th smallest first-pass doc id: the same document exactly when no hit with a smaller doc id than that kept hit was dropped, which topN >= hits guarantees. The assert just before,hits.length == rescoredDocs.scoreDocs.length(:86), states that assumption. - With
-eathe assert throws on every call with topN < hits. With-da(production) the copy runs silently. The clone shares itsScoreDocobjects with the returned array, so the returned hits get the wrong values. ExpressionRescorer(ExpressionRescorer.java:37-47) never overroderescore, soExpression#getRescorer(Expression.java:112-114) has the same defect.- Not triggered with topN >= hits. A
FIELD_DOCsort keeps the smallest doc ids, so the positions line up by accident under-da(-eastill throws).
Main ea57360912ed, assertions off, one segment, BM25. Docs 0-5: 8 words each with "lucene" 3, 1, 5, 2, 4, 6 times; popularity 5, 40, 10, 60, 20, 50. First pass body:lucene: doc 0 0.0529, doc 1 0.0337, doc 2 0.0598, doc 3 0.0463, doc 4 0.0570, doc 5 0.0618.
| rescorer, topN | kept, in order | expected scores | returned scores (whose) |
|---|---|---|---|
SortRescorer, popularity desc, 3 | docs 3, 5, 1 | 0.0463, 0.0618, 0.0337 | 0.0337, 0.0598, 0.0529 (docs 1, 2, 0) |
Expression#getRescorer for popularity, 3 | docs 3, 5, 1 | 0.0463, 0.0618, 0.0337 | 0.0337, 0.0598, 0.0529 (docs 1, 2, 0) |
SortRescorer, FIELD_SCORE, 3 | docs 5, 2, 4; fields[0] 0.0618, 0.0598, 0.0570 | 0.0618, 0.0598, 0.0570 | 0.0598, 0.0529, 0.0337 (docs 2, 0, 1) |
SortRescorer, popularity desc, 6 (control) | docs 3, 5, 1, 4, 2, 0 | own scores | own scores |
| any of the above, with the fix | same | own scores | own scores |
| documented pipeline, one probe corpus: 3,000 docs, BM25 top 1,000 by popularity, 100 | right 100, right order | own scores | 99 of 100 wrong |
With assertions on, every topN < hits row throws AssertionError at SortRescorer.java:86.
Exposure and likelihood385 words
- Who is exposed. Callers of
new SortRescorer(sort).rescore(searcher, hits, topN)orexpression.getRescorer(bindings).rescore(...)with topN <hits.scoreDocs.length: the use the search package docs give (1,000 hits re-sorted to a top 100,package-info.java:371-373) and the typical use theRescorerjavadoc describes ("collecting the top few hundred hits perhaps"). - What goes wrong. Only
ScoreDoc.score. Each kept hit gets the first-pass score of another hit from the same result, sometimes of a hit that was not kept. Code that displays scores, applies a minimum score, merges result lists by score or feeds the score into a later pass gets those values. With aFIELD_SCOREsort the sameFieldDocholds its own score infields[0]and another hit's in.score. - Not affected. Which documents are returned, their order and their sort values. Calls with topN >= hits.
- How often. With assertions on, every call with topN < hits throws. With assertions off, the number of kept hits with a wrong score ranges from 0 to topN and depends on how the sort reorders doc ids: 3 of 3 in the 6-document example, 99 of 100 in one probe corpus of the documented pipeline, 0 with a
FIELD_DOCsort. A randomized check on 30 random indexes confirmed the doc-id-rank pairing in all 2,072 cases it checked; in 1,737 of the 1,832 cases with topN < hits at least one kept hit had a wrong score, and in the other 95 the pairing happened to give every kept hit its own score. - With assertions enabled (
-ea, as in Lucene's own test runs) the call throwsAssertionError, so an application test that covers this path with assertions on fails. - Settings. Opt-in API, nothing else non-default:
new IndexWriterConfig()(so BM25) and a plainIndexSearcher; the diagram and security probes also ran Lucene's default codec, the JUnit tests the test framework's randomized default codec, which does not change BM25 scores; 2 hits and topN = 1 suffice.RescorerandExpressionRescorerare@lucene.experimental;SortRescoreritself carries no experimental tag. - Downstream (code search of default branches): Solr and OpenSearch do not reference
SortRescorerorExpressionRescorer; Elasticsearch has noSortRescorerand wrapsExpression#getRescorerin its expression module, with only a unit test found calling it. A 2021 java-user thread recommendsSortRescorerfor re-sorting results. Private code is not visible.
SortRescorer.rescore(searcher, hits, topN) with topN (1) smaller than the number of hits (2) gives the returned hit another hit's first-pass score.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSortRescorerTopNScore extends LuceneTestCase {

  public void testTopHitKeepsItsOwnScore() throws Exception {
    ByteBuffersDirectory dir = new ByteBuffersDirectory();
    IndexWriter w = new IndexWriter(dir, new IndexWriterConfig());
    for (long popularity : new long[] {1, 2}) {
      Document doc = new Document();
      doc.add(new NumericDocValuesField("popularity", popularity));
      w.addDocument(doc);
    }
    w.close();
    DirectoryReader r = DirectoryReader.open(dir);
    TopDocs firstPass =
        new TopDocs(
            new TotalHits(2, TotalHits.Relation.EQUAL_TO),
            new ScoreDoc[] {new ScoreDoc(0, 2f), new ScoreDoc(1, 1f)});
    Sort byPopularity = new Sort(new SortField("popularity", SortField.Type.LONG, true));
    TopDocs top1 = new SortRescorer(byPopularity).rescore(new IndexSearcher(r), firstPass, 1);
    r.close();
    dir.close();
    assertEquals(1, top1.scoreDocs[0].doc);
    // expected: doc 1 keeps its own first-pass score 1.0; actual: doc 0's score 2.0
    assertEquals("score of doc 1", 1f, top1.scoreDocs[0].score, 0f);
  }
}
# in a copy of this finding's repro folder (repro/LFV-424/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.TestSortRescorerTopNScore
- Expected vs actual
- Expected: doc 1 keeps its own score 1.0. Actual: doc 0's score 2.0 with
-da; with-eaan AssertionError at SortRescorer.java:86.
More files, environment, full output28 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError
       org.apache.lucene.search.SortRescorer.rescore(SortRescorer.java:86)
org.apache.lucene.search.TestSortRescorerTopNScore.testTopHitKeepsItsOwnScore(TestSortRescorerTopNScore.java:44)- The search package docs give this exact use: re-sort "the best 1,000 hits" into "the final top-100 hits".
- The code means to keep scores ("set scores from the original score docs") and does when topN >= hits; 7.7.3 and earlier did for every topN.
- The assert at
:86encodes the broken assumption; no doc restricts topN.
The full argument268 words
- The contracts. Search package docs (
package-info.java:371-373): "SortRescorer, to rescore using aSort. For instance, the best 1,000 hits by BM25 score may be sorted by descending popularity in order to compute the final top-100 hits."Rescorer(Rescorer.java:21-25,:40): "collecting the top few hundred hits perhaps, and then use this class to mix in a more costly second pass scoring"; "@param topN How many re-scored hits to return". The code's comment (SortRescorer.java:85): "set scores from the original score docs".ScoreDoc.score(ScoreDoc.java:25): "The score of this document for the query."ExpressionRescorer(ExpressionRescorer.java:30-33): "Functionally this is the same asSortRescorer... except for the explain method". - History. 4.8.0 (LUCENE-5545) to 7.7.3 created the collector with
trackDocScores=true, so every kept hit recorded its own score; all 14 releases 7.0.0-7.7.3 pass (7.4.1 and 7.5.1 have CHANGES sections but were never released). LUCENE-8412 (55bfadbce115, 8.0.0) removed that option and added the comment, the assert and the positional copy. Its CHANGES entry says scores "need to be set on top hits via TopFieldCollector#populateScores instead" and its MIGRATE entry explains an efficiency change; neither says rescored scores became undefined, and the issue discussion (#9459) never mentionsSortRescoreror topN. - Untested case.
TestSortRescorercallsrescorewith topN 10 for 3 hits (TestSortRescorer.java:96,:134) or topN == hits (testRandom,:179-186);TestExpressionRescorerwith topN 10 for 3 hits (:106). None asserts a score after rescoring. - No 'by design' record. No issue, PR, review comment, list thread or JIRA entry calls the current behaviour intended.
The devil's-advocate check235 words
The strongest case for "intended" (built by a devil's-advocate verifier and by an OpenAI GPT-5.6 reviewer): the class javadoc promises only that it "re-sorts according to a provided Sort"; since LUCENE-8412 a field-sorted collector computes no scores, so scores of re-sorted hits are unspecified; the assert at :86 states a precondition, topN >= hits; Rescorer is @lucene.experimental; and for ExpressionRescorer the javadoc says it assigns "second pass scores", so the first-pass score is not the obvious expected value.
Why it fails: the code sets the scores on purpose (the comment at :85) and returns each hit's own score whenever topN >= hits; without the copy the scores would be NaN, and what it returns is neither NaN nor "unspecified" but another document's plausible score. The assert encodes an internal assumption that the documented use contradicts, not a documented precondition: no javadoc, CHANGES or MIGRATE text restricts topN, and the package docs give topN < hits as the example. LUCENE-8412 was an efficiency refactor that announced no SortRescorer change, and 4.8.0-7.7.3 returned own scores. @lucene.experimental allows API changes, not wrong values. For ExpressionRescorer, another hit's first-pass score is wrong under every reading. That few callers read scores after a re-sort argues for low impact, not for intended behaviour. The independent reproducer, the devil's advocate and the adjudication rejected the intended-behaviour argument, and the cross-model review records rate it weak. Verdict: a defect.
Recommended A: copy each kept hit's own score by a doc-id merge walk
Pair the scores by document, not by position: walk the kept hits and all first-pass hits together in doc-id order and copy each kept hit's own score (+9/-4 lines, SortRescorer.java only, same order of cost). The tests, every core rescorer suite and the whole expressions module pass with it, with assertions on and off.
assert rescoredDocs.scoreDocs.length == Math.min(topN, hits.length);
ScoreDoc[] rescoredDocsClone = rescoredDocs.scoreDocs.clone();
Arrays.sort(rescoredDocsClone, docIdComparator);
int h = 0;
for (ScoreDoc rescored : rescoredDocsClone) {
  while (hits[h].doc != rescored.doc) {
    h++;
  }
  rescored.score = hits[h].score;
}
All options and trade-offs4 options · 529 words
The kept hits are a subset of the first-pass hits and both arrays are already sorted by doc id, so a merge walk restores each hit's own score. One option was built and validated in a scratch worktree at ea57360912ed (removed afterwards); the others are not built.
Replace the positional loop at SortRescorer.java:89-91 by a walk over both doc-id-sorted arrays, and change the assert to what is actually true: rescoredDocs.scoreDocs.length == Math.min(topN, hits.length). +9/-4 lines in SortRescorer.java; ExpressionRescorer inherits the fix.
assert rescoredDocs.scoreDocs.length == Math.min(topN, hits.length);
ScoreDoc[] rescoredDocsClone = rescoredDocs.scoreDocs.clone();
Arrays.sort(rescoredDocsClone, docIdComparator);
int h = 0;
for (ScoreDoc rescored : rescoredDocsClone) {
  while (hits[h].doc != rescored.doc) {
    h++;
  }
  rescored.score = hits[h].score;
}
Trade-offs
- Cost. The positional loop becomes a walk of at most
hits.lengthsteps (O(hits + topN)), next to the existing O(hits log hits) doc-id sort; no new allocation. - Safety. Every kept doc is a first-pass hit, so the walk cannot run past the end. This relies on the documented input contract that the first-pass hits come from the same searcher (
Rescorer.java:38-39); caller-builtTopDocsthat break it were not examined. - Rebase. Open draft #16847 (long doc ids) changes the doc-id types in this file but not these lines.
What the checks validated
- Stock: both new test classes fail through gradle with assertions on and off, and over 5 iterations of a second seed.
- Patched, assertions on and off: every core rescorer suite (
TestSortRescorer,TestSortRescorerTopNScores,TestQueryRescorer,TestDoubleValuesSourceRescorer,TestLateInteractionRescorer,TestRescoreTopNQuery,TestRescoreTopNQueryPrefetch,TestRescoreTopNQueryFloat16Prefetch: 27 tests, 0 failures, 2 skipped as@Nightly) and the whole expressions module (14 classes, 0 failures). - Patched, seed
5EED1234, 10 iterations ofTestSortRescorer*(with its random-index test) andTestExpressionRescorer*: 0 failures. checkGoogleJavaFormat,ecjLintandforbiddenApispass on core and expressions (in the logged run Gradle reused an earlier successful run of the core tasks on the same inputs, UP-TO-DATE; the expressions main-source lint was not requested, as no expressions source changed).- Earlier hunt checks of the same change: the bounded-exhaustive harness at up to 3 documents (203,720 checks, 0 mismatches), a randomized check on 30 random indexes (0 wrong scores) and the diagram's 6-document probe (own scores).
Arrays.binarySearch(hits, rescored, docIdComparator) for each kept hit, or a doc-to-score map built before collection.
Trade-offs
Same result and does not depend on walking in step, but O(N log M) or an extra map; option A is simpler and cheaper.
Call rescore(searcher, hits, hits.scoreDocs.length) and keep the first topN entries; then the positional copy lines up.
Trade-offs
Executed in the verifier's 1,000 -> 100 probe: the same 100 documents in the same order (compared with assertions off), each with its own score. Costs a collector queue the size of the first pass (1,000 instead of 100).
Throw IllegalArgumentException when topN < hits, or document the restriction.
Trade-offs
Contradicts the search package docs' own example and the typical use the Rescorer javadoc describes.
Code reading, then checking. The hunt plan pointed at the positional copy; an AI tool then compared the stock jar with an independent reference on every index of up to 5 documents (41 million checks): every wrong score has topN < hits, none has topN >= hits. Independent verifiers and an adjudication confirmed it.
The method in full233 words
Method: code reading, bounded by bounded-exhaustive translation validation, then a public-API JUnit.
- A hunt unit (2026-10-26) swept the siblings of earlier rescorer findings. Its plan named the lead from code reading: with topN < hits, the copy at
SortRescorer.java:90pairs the i-th smallest doc id of all hits with the i-th smallest doc id of the top N. - The finder, an AI tool, compared the stock jar with an independent reference (the first min(topN, hits) hits in sort order, each with its own score and sort values) on every index of up to 5 documents in every segment layout, plus zero-leaf and empty readers, every value assignment, every first-pass hit subset, topN 1 to hits + 1 and 11 sorts (including
FIELD_SCORE,FIELD_DOC, a values-source sort field and 3 expressions): 41,261,000 checks with assertions off and 32,369,216 with them on, of which 20,630,500 in each mode check scores, the doc set, order and sort values (the rest checktotalHits, a separate observation). - Every wrong score and every
AssertionErrorhad topN < hits; there were none with topN >= hits, and 0 doc-set, order or sort-value mismatches. Two injected mutants ofSortRescorer(the collector size, the collected score) were detected, so the check is not vacuous. - A public-API JUnit on the stock jars followed; then the cross-model reviews, verifiers, an adjudication, the release sweep, the prior-report search and the security screen.
No prior report found: 201 queries plus manual reads on 2026-10-26 over GitHub issues, PRs, review comments and commits, the file lists of all 411 open PRs, the mailing lists, JIRA, downstream code and the web. Not fixed upstream; the nearest items are the change that introduced it and the one that added the class.
Searches5 searches
No issue, PR, review comment, JIRA entry, mailing-list thread or downstream report describes this bug, and no open PR fixes it. GitHub search returns at most 50 results per query (the one truncated Lucene query was completed by hand; two broad downstream queries for the word "rescore" stayed truncated, while the queries naming the classes returned nothing), private reports are not visible, and a search cannot prove absence.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | three scripted prior-report search runs, 201 distinct queries: class and method names; the assert text, the symptom and score-copy terms; LUCENE-8412, trackDocScores, populateScores | no report; only feature work (#6608, #6552, #9459) and unrelated items |
| Review comments and open PRs | 2026-10-26 | the inline review comments of the 9 PRs that touched SortRescorer since 2020; the changed-file lists of all 411 open PRs | none mentions the copy; only draft #16847 (long doc ids) touches the file and leaves the copy loop |
| JIRA | 2026-10-26 | LUCENE-8412, LUCENE-5545, LUCENE-5489, LUCENE-8956 with all comments; JIRA archive queries | LUCENE-8412's discussion never mentions SortRescorer or topN; LUCENE-8956 is about QueryRescorer |
| Mailing lists | 2026-10-26 | dev@, java-user@, issues@, commits@ (and the other lucene.apache.org and solr.apache.org lists) for SortRescorer, ExpressionRescorer, getRescorer | no report; a 2021-11-30 java-user thread only recommends SortRescorer |
| Downstream and web | 2026-10-26 | code search of Solr, Elasticsearch and OpenSearch; their rescore issues; 22 web queries | no report; each engine's rescore issues concern its own code |
Introduced in 8.0.0 by LUCENE-8412 (55bfadbce115, 2018), which stopped the collector from tracking scores and added the positional copy and the assert. All 60 releases 8.0.0-10.5.2 and main fail; all 14 releases 7.0.0-7.7.3 pass. Not fixed upstream.
Versions tested7 rows
Introduced by 55bfadbce115, LUCENE-8412 "TopFieldCollector no longer takes a trackDocScores option" (jpountz, 2018-07-23, master only; JIRA patch workflow, no GitHub PR; the issue is now #9459). It replaced TopFieldCollector.create(sort, topN, true, true), which tracked each kept hit's own score, and added the comment, the assert and the positional copy; git blame and git log -L84,92 attribute these lines only to it (besides cbd8cacc50c, which created the class). No commit-level bisect (it would need the 2018 build); the release bracket confirms it. SortRescorer and Expression#getRescorer exist since 4.8.0 (LUCENE-5545), so this is a regression. Upstream main (a9779ef3c193), branch_10x and branch_10_6 (10.6.0, released 2026-10-29) still have the assert and the copy (read 2026-10-26); the lines are unchanged since 2018.
| Version or commit | Verdict | Result |
|---|---|---|
| 4.8.0 to 6.6.6 | read, not run | the collector tracked each hit's own score (trackDocScores=true) |
| 7.0.0 to 7.7.3 (14 releases) | not affected | every kept hit has its own score (assertions off; on as well for 7.4.0 and 7.7.3) |
| 8.0.0 | first affected | doc 1 gets doc 0's score (0.0782976 instead of 0.13434221); assertions on: AssertionError at SortRescorer.java:91 |
| 8.1.0 to 10.5.1 | affected | the same wrong score in every release (assertions off); assertions on for 8.11.4 (:91), 9.0.0 (:86), 9.12.3 (:89), 10.0.0 (:88) |
| 10.5.2 | affected | this doc's core test 2 of 3 fail, assertions on (:86) and off; the 6-document probe: the same three wrong scores |
main ea57360912ed | affected | this doc's tests fail through gradle and the harness, assertions on (:86) and off |
| main + the fix | not affected | both tests pass; every core rescorer suite and the expressions module pass, assertions on and off |
An independent reproducer, a root-cause verifier (a reading-only review by OpenAI GPT-5.6 plus its own executed randomized check), a devil's advocate and an adjudication all say real; earlier reading-only GPT-5.6 reviews agreed on the root cause. This doc's tests were run through gradle and on 10.5.2 and 9.12.3, and the fix was validated.
Checks and verdicts453 words
Every check ran on main ea57360912ed with assertions on and off unless noted. The OpenAI GPT-5.6 reviews were reading-only (the reviewer could not run Java); their execution evidence is separate re-runs of the finder's test (3 of 4 fail each time) and the cross-model review's own randomized check, run by the verifier, not by the reviewer.
| Check | Verdict | What it found |
|---|---|---|
| Refute review (OpenAI GPT-5.6) | not real, low (procedural) | It could not run its own test, so it could not vote real; it agreed on the root cause and the inputs, rated the intended argument weak, and added the search package docs' 1,000 -> 100 contract. A separate re-run of the finder's test failed 3 of 4. |
| Intended-behaviour review (OpenAI GPT-5.6) | real, medium; intended argument weak | Its strongest counter-argument (re-sorting promises no scores, NaN would be defensible) fails because the class deliberately copies scores and returns another document's plausible score. |
| Independent reproducer | real | Own 6-test JUnit in a separate package, written from the claim only: 4 of 6 fail on main, 10.5.2 and 9.12.3, both controls pass. Its main() confirmed the pairing rule (topN 4: kept docs 1, 3, 4, 5 get the scores of docs 0, 1, 2, 3), 7.7.3 correct and 8.0.0 wrong. |
| Root-cause verifier (review by OpenAI GPT-5.6, reading only) | real, medium | The reviewer's root cause agrees exactly (assert at :86, copy at :90) and it found no other entry point besides ExpressionRescorer. The verifier's own randomized check (30 random indexes of 5 to 64 docs) confirmed the doc-id-rank pairing in all 2,072 cases it checked; 1,737 of the 1,832 with topN < hits had at least one wrong score; with the fix, 0 wrong scores. |
| Devil's advocate | real, high | No intended, documented or misuse argument survives. Its probe of the documented 1,000 -> 100 pipeline: 99 of 100 wrong on main, 10.5.2 and 9.12.3; AssertionError with assertions on; controls pass. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test with fresh seeds: 4 of 6 fail with assertions on and off, controls pass; checked with git show that 55bfadbce115 added the copy and the assert. |
| Security screen | none (high) | Own probe (6,000 docs, 9 segments, deletions, a tenant filter): 0 safety failures in 508,797 checks with assertions off and 302,098 on, the same on 10.5.2 and 9.12.3; only scores move, always between the caller's own hits. |
| This doc's runs | reproduces; fix validated | Both new tests fail through gradle on main (assertions on and off, a second seed over 5 iterations) and the core test on 10.5.2 and 9.12.3; with the fix they pass, as do 27 core rescorer tests, the expressions module and the static checks. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 463 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,440 words
- Registry title
- SortRescorer and ExpressionRescorer give returned hits another hit's first-pass score when topN is smaller than the number of first-pass hits (AssertionError with -ea)
- Area
- search / rescoring (SortRescorer; expressions ExpressionRescorer inherits rescore())
- Priority
- Medium, rank 58: Documented, plausible SortRescorer or ExpressionRescorer use with topN below the hit count silently gives nearly every hit a wrong score while order and documents stay correct.
- Impact class
- silent wrong results
- Impact note
- Applications that call SortRescorer.rescore or Expression#getRescorer(bindings).rescore with topN smaller than the number of first-pass hits (the use the search package docs describe: the best 1,000 BM25 hits re-sorted by popularity into the final top 100) get, with the default codec, IndexWriterConfig and searcher, at any scale and in every release since 8.0.0, another first-pass hit's score in ScoreDoc.score on nearly every returned hit (99 of 100 in that documented pipeline), while the documents, their order and the FieldDoc sort values are correct, so only callers that read the scores (display, score thresholds, combining with a later pass) are misled; with -ea the same call throws AssertionError at SortRescorer.java:86 instead.
- Summary
- You run a search, take its top hits and call new SortRescorer(sort).rescore(searcher, hits, topN), or Expression#getRescorer(bindings).rescore, with topN smaller than the number of hits, for example to re-sort the best 1,000 hits by popularity and keep the top 100 as the search package docs suggest. You expect the top N hits in sort order, each with its own first-pass score, which is what every release up to 7.7.3 returned and what you still get when topN is at least the number of hits. Instead the documents and their order are right, but the k-th smallest doc id among the returned hits gets the score of the k-th smallest doc id among all first-pass hits, so nearly every returned hit carries another hit's score (with 2 hits and topN=1, doc 1 comes back with doc 0's score), and with assertions enabled rescore throws AssertionError at SortRescorer.java:86.
- Introduced
- 55bfadbce115a825a75686fe0bfe71406bc3ee44 (LUCENE-8412 'TopFieldCollector no longer takes a trackDocScores option', by jpountz, master only, 2018 JIRA patch workflow without a GitHub PR; the issue was later migrated as apache/lucene#9459) [read: git blame and git log -L84,92 on SortRescorer.java list only this commit for lines 84-92 (topDocs(), the comment 'set scores from the original score docs', the assert, the doc-id sort of the clone and the copy loop), besides cbd8cacc50c, which created the class; git log -S on the copy line finds it on master; git show confirms it replaced TopFieldCollector.create(sort, topN, true, true), which tracked each hit's own score; exec: the release jars bracket it, 7.7.3 passes and 8.0.0 fails with the AssertionError at the assert this commit added]. No commit-level bisect (building 55bfadbce11^ and 55bfadbce11 would need the 2018 build). Regression: SortRescorer and Expression#getRescorer exist since 4.8.0 (LUCENE-5545, cbd8cacc50c) and returned each hit's own score until 7.7.3 (2018-07-23 (55bfadbce11 on master; first release tag containing it: 8.0.0, 2019-03-08))
- First affected version
- 8.0.0 [exec: -ea AssertionError at SortRescorer.java:91, -da doc 1 returned with doc 0's score 0.0782976 instead of its own 0.13434221; 7.7.3 and every other 7.x release pass]
- Affected versions
- all 60 releases from 8.0.0 to 10.5.2 (8.0.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.5.2) and main ea57360912ed [exec: -da on every one with the version-portable main() SortRescorerHistoryMain; -ea also on 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main, each throwing AssertionError at the assert (line 91 in 8.x, 86 in 9.0.0, 89 in 9.12.3, 88 in 10.0.0, 86 in 10.5.2 and main); the JUnit repro fails 3 of 4 on 9.12.3, 10.5.2 and main with -ea and -da]; not affected: all 14 releases from 7.0.0 to 7.7.3 [exec, -da; -ea also on 7.4.0 and 7.7.3] and 4.8.0-6.6.6 [read only: the collector was created with trackDocScores=true]; upstream main cf398bfb142c and branch_10x still have the assert and the copy loop [read 2026-10-26]; branch_10_6 (10.6.0, released 2026-10-29) still has the assert and the copy [read 2026-10-26; the lines are unchanged since 2018]; not fixed anywhere
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-26, follow-up prior-report record verdict new, read-only: three scripted prior-report searches with 201 distinct queries (class and method names; the assert text, the symptom and the score-copy terms; LUCENE-8412, trackDocScores and populateScores) over apache/lucene issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and 22 web queries; manual: JIRA LUCENE-8412, LUCENE-5545, LUCENE-5489 and LUCENE-8956 with all comments, the inline review comments of the 9 PRs that touched SortRescorer since 2020, the changed-file lists of all 411 open apache/lucene PRs, the upstream file contents and history on main and branch_10x, and downstream code search). Not fixed upstream: main cf398bfb142c and branch_10x still have the assert and the copy loop; the last change to the file, e5eb7e763acb (#14852, 2025-06-30), is an unrelated rename. Related, not reports: #9459 (LUCENE-8412, introduced the code; its 12 JIRA comments and follow-up commits never mention SortRescorer or topN), #6608 (LUCENE-5545, added SortRescorer when each hit's own score was tracked), #16847 (open draft by jimczi, long doc ids: the only open PR touching SortRescorer.java, it changes only doc-id types and the explain signature and leaves the assert and copy loop unchanged), #16542 (exhaustive ScoreMode, unrelated), #9999 (LUCENE-8956, topN handling in QueryRescorer only), a 2021-11-30 java-user thread that only recommends SortRescorer. Gaps: GitHub search returns 50 results per query (the one truncated apache/lucene query was completed with page 2; two broad downstream 'rescore' queries stayed truncated, while the queries naming the classes returned 0), private reports are not visible, and searches cannot prove absence
- Lucene commit tested
- main
ea57360912ed(2026-10-26): this doc's two tests through gradle in a scratch worktree (assertions on and off; a second seed over 5 iterations) and the core test through a standalone JUnit harness on main and on the Maven Central jars of 10.5.2 and 9.12.3 (assertions on and off); the fix in that worktree (removed afterwards) with every core rescorer suite and the whole expressions module (assertions on and off), 10 iterations of a second seed, and the google-java-format, ecjLint and forbidden-API checks; the hunt's release sweep ran a version-portable repro on all 74 releases 7.0.0 to 10.5.2; the diagram's 6-document probe ran on main (assertions on and off, and with the fix), 10.5.2, 8.0.0 and 7.7.3.
- Finding record
lucene/core/src/java/org/apache/lucene/search/SortRescorer.java:38-93 (42-44 clone and doc-id sort of all hits; 48-49 TopFieldCollectorManager(sort, topN, ...); 77 each hit's own score into SimpleScorable; 84 topDocs(); 85 comment 'set scores from the original score docs'; 86 assert hits.length == rescoredDocs.scoreDocs.length; 87-88 doc-id sort of the top N; 89-91 positional copy, 90 rescoredDocsClone[i].score = hits[i].score)lucene/core/src/java/org/apache/lucene/search/Rescorer.java:21-24 (typical use: 'collecting the top few hundred hits perhaps'; @lucene.experimental at :30), :40 ('@param topN How many re-scored hits to return')lucene/core/src/java/org/apache/lucene/search/package-info.java:371-373 ('the best 1,000 hits by BM25 score may be sorted by descending popularity in order to compute the final top-100 hits')lucene/core/src/java/org/apache/lucene/search/ScoreDoc.java:25 ('The score of this document for the query.')lucene/expressions/src/java/org/apache/lucene/expressions/ExpressionRescorer.java:29-47 ('Functionally this is the same as SortRescorer'; @lucene.experimental; extends SortRescorer without overriding rescore()); Expression.java:112-114 (getRescorer returns an ExpressionRescorer)lucene/core/src/test/org/apache/lucene/search/TestSortRescorer.java:96, 134, 186 and lucene/expressions/src/test/org/apache/lucene/expressions/TestExpressionRescorer.java:106 (upstream tests rescore only with topN 10 > 3 hits or topN == hits)
- The finding in 30 seconds
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/SortRescorer.java:27-93 (41-44 clone and doc-id sort; 48-49 collector of size topN; 57-82 collection with each hit's own score, 77; 84 topDocs; 85 comment; 86 assert; 87-91 positional copy, 90)Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/Rescorer.java:21-25, 30, 40Lucene main ea57360912ed: lucene/expressions/src/java/org/apache/lucene/expressions/ExpressionRescorer.java:29-47; Expression.java:112-114
- Who is affected
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/package-info.java:371-373; Rescorer.java:21-25, 30; SortRescorer.java:27Lucene main ea57360912ed: lucene/expressions/src/java/org/apache/lucene/expressions/ExpressionRescorer.java:35
- Why it looks unintended
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/package-info.java:371-373; Rescorer.java:21-25, 40; SortRescorer.java:27, 85-86; ScoreDoc.java:25Lucene main ea57360912ed: lucene/expressions/src/java/org/apache/lucene/expressions/ExpressionRescorer.java:30-33, 42Lucene main ea57360912ed: lucene/core/src/test/org/apache/lucene/search/TestSortRescorer.java:96, 134, 179-186; lucene/expressions/src/test/org/apache/lucene/expressions/TestExpressionRescorer.java:106
- TestSortRescorerTopNScore.java (JUnit test):
repro/LFV-424/src/org/apache/lucene/search/TestSortRescorerTopNScore.java(51 lines)
A summary card (bug.png): the first pass, the collector keeping the 3 most popular hits, topDocs() without scores, the assert, and the positional copy. Every value on it comes from the probe runs on ea57360912ed; the alt text was checked against the still.
assets/LFV-424/bug.png(463 KB)