When a query matches more documents than sampleSize, RandomSamplingFacetsCollector counts facets on a random sample, and amortizeFacetCounts scales each count back up (count / samplingRate), capped at an upper bound it reads from the index. Since 8.9.0, FacetsConfig can skip the index terms that bound comes from.
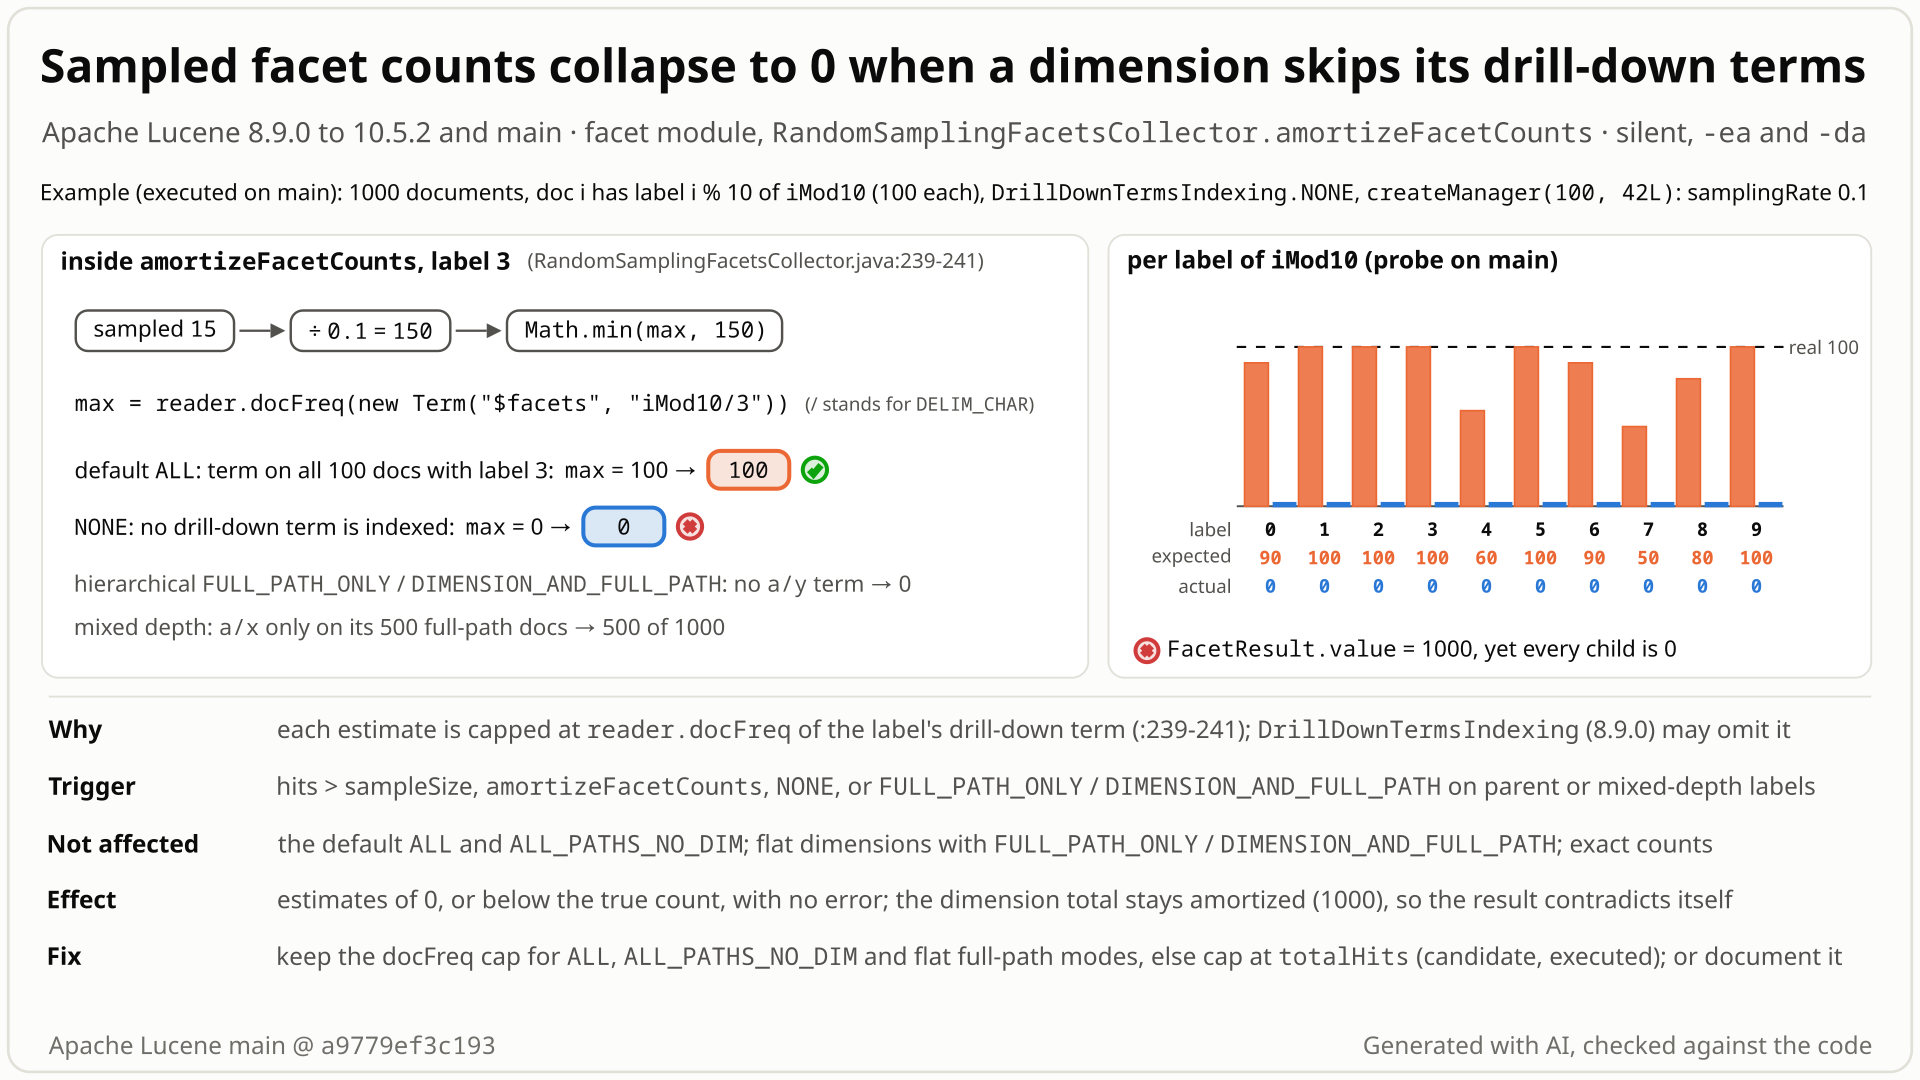
iMod10 inside amortizeFacetCounts: sampled 15, divided by 0.1 gives 150, then capped at the docFreq of iMod10/3: 100 with the default ALL, 0 with NONE. Beside it, expected against actual for all ten labels on main. Select the still to open it at full size. Generated with AI, checked against the code.- Index 1,000 documents with a facet dimension
iMod10(labels 0 to 9, 100 documents each) and setDrillDownTermsIndexing.NONEon it: the application counts facets but never drills down. Search all of them withRandomSamplingFacetsCollector.createManager(100, 42L), a 10% sample. - The sample sees label 3 fifteen times. You expect
amortizeFacetCountsto scale that to 150 and cap it at the label's 100 documents: 100, which is what the default configuration returns. - You get 0 for label 3, and 0 for all ten labels, while the same result's dimension total says 1000. Sorted-set doc values facets give the same zeros.
- Why: the cap is the document frequency of the label's drill-down term
iMod10/3, andNONEnever indexes that term, so the cap is 0. On a hierarchical dimensionFULL_PATH_ONLYindexes only full paths: parent labels get 0, and a label where half of its documents stop gets 500 instead of 1000. - No error is raised. Using the docFreq cap only for indexing modes that guarantee the term on every document with the label fixes it, and the whole facet test suite passes.
Applications that call amortizeFacetCounts on sampled results for a dimension set to DrillDownTermsIndexing.NONE, or to a full-path mode on a hierarchical dimension. Both settings are opt-in; the default ALL is fine. Then a query with more hits than sampleSize returns 0, or too little, for the affected labels (every label under NONE, parent and mixed-depth labels otherwise), with no error.
Mechanism, terms and numbers715 words
When a query matches more documents than sampleSize, RandomSamplingFacetsCollector counts facets on a random sample and amortizeFacetCounts scales each sampled label count back up, sampled / samplingRate, capped at what its javadoc calls "the upper bound for each facet value": the document frequency of the label's drill-down term. That was a true bound when the cap was written in 2014, because every drill-down term was always indexed. Since 8.9.0 (LUCENE-9385) FacetsConfig.setDrillDownTermsIndexing can skip those terms: under NONE every amortized count of the dimension is 0, under FULL_PATH_ONLY or DIMENSION_AND_FULL_PATH every parent label of a hierarchical dimension is 0, and a label that is the full path of some documents and a parent of others can be capped below its true count (in the repro, 500 instead of 1000). The dimension total stays amortized, so one FacetResult reports 1000 next to children of 0, with no error. Taxonomy facets fail this way on every tested release from 8.9.0 to 10.5.2 and on main, sorted-set facets on every tested release from 9.2.0. The method already holds the dimension's DimConfig; choosing the bound from its drillDownTermsIndexing fixes it, and the whole facet test suite passes with that change.
- Facet sampling:
RandomSamplingFacetsCollector(sampleSize, seed)(orcreateManager) keeps aboutsampleSizeof the matching documents when there are more;getSamplingRate()issampleSize / totalHits. Facet counts computed over it are counts in the sample. - Amortizing:
amortizeFacetCounts(result, config, searcher)turns sampled counts into estimates of the full counts: "you can amortize the sampled counts by calling this method. Uses theFacetsConfigand theIndexSearcherto determine the upper bound for each facet value" (RandomSamplingFacetsCollector.java:215-219). - Drill-down terms: for each facet path,
FacetsConfig.buildcan add terms such asiMod10/3to an indexed field ($facetsby default) so thatDrillDownQuerycan filter on a label. The counts themselves come from doc values (taxonomy ordinals or sorted-set values), not from these terms. DrillDownTermsIndexing(8.9.0, LUCENE-9385), per dimension:ALL(default: the dimension, every sub-path and the full path),ALL_PATHS_NO_DIM,DIMENSION_AND_FULL_PATH,FULL_PATH_ONLY, andNONE("Index no drill down terms") (FacetsConfig.java:74-106).
amortizeFacetCountsreturns its input whentotalHits <= sampleSize(RandomSamplingFacetsCollector.java:222-224). Otherwise, for each label it builds the pathdim/.../label(:231-238), readsmax = reader.docFreq(new Term(dimConfig.indexFieldName, fullPath))(:239), computes(int) (sampled / samplingRate)(:240) and keepsMath.min(max, estimate)(:241). It never looks atdimConfig.drillDownTermsIndexing, although it holds theDimConfig(:228).FacetsConfig.indexDrillDownTerms(FacetsConfig.java:419-460, called for taxonomy, sorted-set and association fields at:400,:501,:530) adds no term underNONE(:421), only the full path underFULL_PATH_ONLY(:423-427), and the bare dimension plus the full path underDIMENSION_AND_FULL_PATH(:434-438). OnlyALL_PATHS_NO_DIMandALLadd every sub-path (:439-452).- So the docFreq is 0 for every label under
NONE, 0 for every parent label of a hierarchical dimension under the two full-path modes, and only the documents that stop at the label for a mixed-depth label. Each of those stops being an upper bound: a docFreq of 0 always caps a returned label below its real count, and a partial docFreq does so when it is below both the estimate and the label's count in the query (it counts the whole index, the facet count only the query). - The dimension total is capped by
reader.numDocs()instead (:245-250) and stays amortized, so the result contradicts itself: total 1000, children 0.
| dimension and mode | label | sampled | estimate | true count | docFreq of the term | expected | amortized |
|---|---|---|---|---|---|---|---|
flat iMod10, ALL (default) | 3 | 15 | 150 | 100 | 100 | 100 | 100 (right) |
flat iMod10, NONE (taxonomy or sorted-set) | 3 (and all 10) | 15 | 150 | 100 | 0 | 100 | 0 |
hierarchical a, FULL_PATH_ONLY (taxonomy or sorted-set), docs a/x/{0..4}, a/y/{0..4} | y | 55 | 550 | 500 | 0 | 500 or more | 0 |
hierarchical a, FULL_PATH_ONLY, half a/x, half a/x/1 | x | 100 | 1000 | 1000 | 500 | 1000 | 500 |
The amortized dimension total is 1000 in every row. Not affected: ALL, ALL_PATHS_NO_DIM, and the full-path modes on a flat dimension or at the leaf level, where every document with the label carries its term.
Exposure and likelihood355 words
- Who is exposed. Applications that sample facets with
RandomSamplingFacetsCollector, callamortizeFacetCounts, and configure the dimension withNONE(the "count but never drill down" case LUCENE-9385 was built for), or withFULL_PATH_ONLY/DIMENSION_AND_FULL_PATHon a hierarchical dimension. Taxonomy facets and sorted-set doc values facets, flat and hierarchical, were run. Association fields are written through the same drill-down helper, but association facets sum values and the method's javadoc covers countingFacetsonly, so whether amortizing them applies was neither established nor run. - Default vs opt-in. Two independent opt-ins on one dimension.
ALL(the default),ALL_PATHS_NO_DIMand the full-path modes on flat dimensions are unaffected.FacetsConfigis@lucene.experimental. - Scale. Every query with more hits than
sampleSize. UnderNONEevery returned label comes back 0; under the full-path modes every returned parent label of a hierarchical dimension does, and a mixed-depth label is capped whenever its partial docFreq is below the estimate. 1000 documents are enough; in the layouts tested more documents do not shrink the error (the cap is 0, or a fixed fraction of the true count). - Silent. No exception or log line, and the dimension total looks right. An application that hides zero-count values shows an empty facet.
- How likely. Rare: a read-only code search found no use of
RandomSamplingFacetsCollectororsetDrillDownTermsIndexingin Elasticsearch, OpenSearch or Solr (default branches), and nothing has been reported since 8.9.0 (2021). A 2024 java-user@ thread describes applications that sample facets and use the amortized counts; nobody in it mentionsDrillDownTermsIndexing. - Possibly wider, not run.
amortizeFacetCountsaccepts anyFacetResult. Counting implementations whose labels are not written asFacetsConfigdrill-down terms (StringValueFacetCounts,LongRangeFacetCounts,DoubleRangeFacetCounts) may find no term to cap with, in any indexing mode. Nothing here executed that, and fix A would not change it (an unconfigured dimension reads the defaultALL). - Not affected. Exact (unsampled) counts; which documents match; drill-down, beyond what the chosen mode already implies (these modes make a
DrillDownQueryon an omitted path find nothing, by design); the index; queries with at mostsampleSizehits. Nothing is stored wrong, so a fix needs no reindex.
with DrillDownTermsIndexing.NONE, RandomSamplingFacetsCollector.amortizeFacetCounts caps a sampled label's count at the docFreq of a drill-down term that was never indexed.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.facet;

import org.apache.lucene.document.Document;
import org.apache.lucene.facet.sortedset.DefaultSortedSetDocValuesReaderState;
import org.apache.lucene.facet.sortedset.SortedSetDocValuesFacetCounts;
import org.apache.lucene.facet.sortedset.SortedSetDocValuesFacetField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestAmortizeWithoutDrillDownTerms extends LuceneTestCase {

  public void testAmortizedCountWithDrillDownTermsIndexingNone() throws Exception {
    FacetsConfig config = new FacetsConfig();
    config.setDrillDownTermsIndexing("dim", FacetsConfig.DrillDownTermsIndexing.NONE);
    ByteBuffersDirectory dir = new ByteBuffersDirectory();
    IndexWriter w = new IndexWriter(dir, new IndexWriterConfig());
    for (int i = 0; i < 2; i++) {
      Document doc = new Document();
      doc.add(new SortedSetDocValuesFacetField("dim", "x"));
      w.addDocument(config.build(doc));
    }
    w.close();
    DirectoryReader r = DirectoryReader.open(dir);
    IndexSearcher searcher = new IndexSearcher(r);
    RandomSamplingFacetsCollector sampler =
        searcher.search(
            MatchAllDocsQuery.INSTANCE, RandomSamplingFacetsCollector.createManager(1, 42));
    FacetResult sampled =
        new SortedSetDocValuesFacetCounts(
                new DefaultSortedSetDocValuesReaderState(r, config), sampler)
            .getTopChildren(10, "dim");
    FacetResult amortized = sampler.amortizeFacetCounts(sampled, config, searcher);
    r.close();
    dir.close();
    // expected: 1 sampled hit / sampling rate 0.5 = 2 (both docs have x); actual: 0
    assertEquals("amortized count of dim/x", 2, amortized.labelValues[0].value.intValue());
  }
}
# in a copy of this finding's repro folder (repro/LFV-425/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/facet/build/libs/lucene-facet-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.facet.TestAmortizeWithoutDrillDownTerms
# the module(s) facet also need their third-party runtime jars
- Expected vs actual
- Expected: 1 sampled hit / sampling rate 0.5 = 2 (both documents have dim/x). Actual: 0.
More files, environment, full output37 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: amortized count of dim/x expected:<2> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.facet.TestAmortizeWithoutDrillDownTerms.testAmortizedCountWithDrillDownTermsIndexingNone(TestAmortizeWithoutDrillDownTerms.java:57)- The javadoc promises "the upper bound for each facet value"; 0 for a label sampled 15 times is no upper bound.
- Upstream
TestRandomSamplingFacetsCollectorexpects the estimate capped at the true count; no doc says sampling needs drill-down terms. - The cap dates from 2014, when every drill-down term was indexed; LUCENE-9385 made them optional in 8.9.0 without touching sampling.
The full argument310 words
- Contract.
RandomSamplingFacetsCollector.java:215-219: "you can amortize the sampled counts by calling this method. Uses theFacetsConfigand theIndexSearcherto determine the upper bound for each facet value." The class javadoc (:38-40): "since the counts of the top-facets is based on the sampled set, you can amortize the counts". A bound below the number of sampled documents with the label, or below its true count, is not an upper bound. - No stated precondition.
DrillDownTermsIndexing(FacetsConfig.java:74-106) and its setter (:216-226) describe only which terms are indexed. The facet package overview presents drill-down terms as something that "can be used at search time for drill-down", withNONEas a choice, and its sampling section states no dependency (lucene/demo/.../facet/package-info.java:231-243,:377-388).CHANGES.txtandMIGRATE.mdsay nothing either. - Tests.
TestRandomSamplingFacetsCollector.java:135-149asserts, in the default configuration, that every amortized count ismin(5 * sampled, numDocs / 10.f)within 1.0: the estimate capped at about the label's document count (numDocs / 10.fstands in for it; the slack is there becausenumDocsneed not divide by 10). No upstream test combines sampling with a non-defaultDrillDownTermsIndexing. - History. LUCENE-5476 (#6539, 2014) added the cap after a design-review suggestion: "The
docFreqof the category drill-down term is an upper bound - and could be used as a limit"; then every prefix of every path was indexed. LUCENE-9385 (#10425, PR #25, 2021) made the terms optional; its discussion wanted "to decouple the idea of indexing data required for facet counting separate from the ability to actually drill down" (@gsmiller), and it never mentions sampling. It changed onlyFacetsConfig.javaand two drill-down tests. - Self-contradiction. The same
FacetResultamortizes the dimension total to 1000 while every child is 0; the exact unsampled counts are 100 per label. - Precedent. LUCENE-5522 (#6585, 4.7.1), drill-down terms missing for association facets, was fixed as a bug.
The devil's-advocate check286 words
The strongest "intended" case: amortized counts are only estimates; FacetsConfig is @lucene.experimental; the javadoc says the method uses the FacetsConfig and the IndexSearcher, so it obviously needs the indexed terms; whoever drops the drill-down terms also drops the statistic the heuristic uses, and under NONE a DrillDownQuery on the label finds 0 documents too, so 0 is "consistent". Two facts strengthen it: the facet package overview describes the usual workflow as finding the top facets on the sample and then computing exact counts for those over all matching documents (lucene/demo/.../facet/package-info.java:383-385), so amortization is a convenience; and in the five years since 8.9.0 nobody has reported this, and no known user combines both opt-ins.
Why it fails: the method estimates the unsampled count (the class javadoc, and the upstream test compares with it), which is 100 per label under NONE, and the same call amortizes the total to 1000 next to children of 0. A bound below the sampled count is not a bound, no document states the precondition, and the method already holds the DimConfig it would need to check. @lucene.experimental allows API change, not silently wrong numbers, and NONE is exactly the "count but never drill down" case LUCENE-9385 was built for. The tests check only bounds, not exact estimates. The exact-recount workflow and the missing reports argue for a low priority or a documentation fix, not for the numbers being right. Verdict: a defect (adjudication: confirmed, high; the independent reproduction, the cross-model review and the intended-behaviour check real; the intended case rated moderate by the cross-model reviews, moderate-to-weak by the independent reproduction, weak by the intended-behaviour check). A maintainer may still prefer a documentation fix; it is offered below.
Recommended Choose the bound from DrillDownTermsIndexing
In amortizeFacetCounts, keep the docFreq cap only when the indexing mode guarantees that every document with the label indexes the label's drill-down term (ALL, ALL_PATHS_NO_DIM, or a full-path mode on a flat dimension); otherwise cap at the number of hits. The repro, upstream TestRandomSamplingFacetsCollector and the whole facet suite pass, assertions on and off.
All options and trade-offs4 options · 930 words
The default and the complete modes keep exactly today's docFreq cap; in the other modes the plain estimate sampled / samplingRate is kept, bounded by totalHits. That bound can bind: the 2014 design review argued the estimate essentially cannot exceed totalHits, but LFV-437 shows amortized counts up to twice too high (1999 hits, sampleSize 1000, every hit sampled, dimension total 3996). The switch is exhaustive, so a new DrillDownTermsIndexing value will not compile until someone picks its bound. The javadoc names the bound. Workaround until a fix ships: compute sampled / getSamplingRate() yourself for such dimensions. Open draft PR #16847 rewrites the same lines (long doc counts), so whichever lands second needs a trivial rebase. Only query-time numbers change; no reindex.
RandomSamplingFacetsCollector.java:228 and :239: decide once per dimension whether the indexing mode guarantees that every document with a label carries the label's term, and use the docFreq only then; otherwise use totalHits. +17/-2 lines, javadoc included (the finder's sketch, with the javadoc added). This is version 2: after the fact checks the javadoc and the comment name the modes; the code is the same as in version 1, which the checks validated.
    DimConfig dimConfig = config.getDimConfig(res.dim);
+    // the docFreq of a label's drill-down term bounds the label's count only if the indexing mode
+    // guarantees that every document with the label indexes that term
+    final boolean drillDownTermForEveryDoc =
+        switch (dimConfig.drillDownTermsIndexing) {
+          case ALL, ALL_PATHS_NO_DIM -> true;
+          case FULL_PATH_ONLY, DIMENSION_AND_FULL_PATH -> dimConfig.hierarchical == false;
+          case NONE -> false;
+        };
     ...
-      int max = reader.docFreq(new Term(dimConfig.indexFieldName, fullPath));
+      int max =
+          drillDownTermForEveryDoc
+              ? reader.docFreq(new Term(dimConfig.indexFieldName, fullPath))
+              : totalHits;
Trade-offs
- In the other modes the estimate is no longer capped by the label's own document count, so sampling noise can push it above the true count, as for any uncapped estimate.
- Conservative for hierarchical dimensions: a full-path mode guarantees the label's term at no level (any document may have a longer path through the label), so the fix uses
totalHitsat every level, including leaf labels where today's docFreq cap happens to be right. There it is looser than stock: leafa/x/2under hierarchicalFULL_PATH_ONLY(sampled 13, true count 100) gives 100 on main and 130 with the fix (diagram probe). - A path-aware bound (
min(totalHits, sum of the docFreqs of all full-path terms under the label)) would cost a terms-dictionary scan per label, can still exceed the true count on a multi-valued hierarchical dimension (one document can carry several paths under the label), and gives nothing underNONE; not proposed. - The switch expression needs Java 14 or later. Upstream's maintained branches (main, and branch_10x, which requires Java 21) compile it; there is no maintained 8.x or 9.x branch, whose older Java levels would need a classic
switch. - Not covered by any test here: multi-valued hierarchical dimensions, and a query narrower than all documents, where documents outside the query raise the index-wide docFreq.
What the checks validated
- Scratch worktree of
a9779ef3c193, gradle, JDK 25: the new test fails 5 of 6 on stock with assertions on and off; with the fix, the new test and upstreamTestRandomSamplingFacetsCollectorpass 7 of 7, on and off, andTestRandomSamplingFacetsCollectorpasses 20 of 20 iterations; the whole:lucene:facet:testpasses, 40 suites and 312 tests, 0 failures, with assertions on (7 skipped) and off (8 skipped);:lucene:facet:check -x test(google-java-format, ecj lint, forbidden APIs) and:lucene:facet:renderJavadocpass. - Standalone runner with the fix shadowed: the new test 6 of 6 (
-eaand-da), the finder's test 4 of 4, the independent reproducer's test 9 of 9 (5 of 9 fail stock), upstreamTestRandomSamplingFacetsCollector10 of 10 iterations. - Version 2 (javadoc and comment only), re-validated after the fact checks:
applyGoogleJavaFormatleaves it unchanged;:lucene:facet:check -x testand:lucene:facet:renderJavadocpass; the new test and upstreamTestRandomSamplingFacetsCollector7 of 7 with assertions on and off; the whole:lucene:facet:test, 40 suites and 312 tests, 0 failures, on (7 skipped) and off (8 skipped); standalone: the new test 6 of 6 (-ea,-da), the finder's 4 of 4, the independent reproducer's 9 of 9, upstream 10 of 10 iterations.
Say in the amortizeFacetCounts javadoc and on DrillDownTermsIndexing that the upper bound is the docFreq of each value's drill-down term, so amortization needs ALL, ALL_PATHS_NO_DIM or a flat dimension, and that other modes cap the counts too low, down to 0.
Trade-offs
No behaviour change and the smallest diff, but it leaves a silent 0 for a configuration Lucene accepts; callers must compute the estimate themselves. Not validated (nothing to run).
Throw IllegalArgumentException from amortizeFacetCounts when the dimension's drill-down terms are incomplete.
Trade-offs
Turns a silent wrong number into an error, but breaks existing callers of these modes: a behaviour change for a minor release. Not validated.
Cap every label at totalHits, in every mode. Run only to show why the cap must stay for the default.
Trade-offs
Fixes the new test (6 of 6), but upstream TestRandomSamplingFacetsCollector fails 10 of 10 iterations (for example an amortized count of 1220 against 1172.7, the test's numDocs / 10.f stand-in for the label's 1172 or 1173 documents): in the default configuration the estimate then exceeds the label's true count, which the docFreq cap prevents.
What the checks validated
Executed with the standalone runner on main a9779ef3c193, as a negative control.
An application that hides zero-count facet values shows an empty facet for an affected dimension; counts only go down, and matching, totals and the index are unchanged.
Code reading. While listing every count the facet module reports, an AI hunting AI tool noticed that the amortized count is capped by a drill-down term's document frequency, an index structure LUCENE-9385 had made optional. It confirmed this with a public-API JUnit over the DrillDownTermsIndexing values.
The method in full147 words
Method: code reading (the hunt's "non-formal" tier), a hunt unit ("every count or statistic a module reports equals a brute-force count over the live documents that pass its filters"), 2026-10-26, stock main jars.
- While building the inventory of every place
lucene/facetproduces a reported count, the hunting AI tool saw thatamortizeFacetCountscaps each estimate withreader.docFreqof a drill-down term, and that LUCENE-9385 had made those terms optional per dimension. - It wrote a public-API JUnit over the
DrillDownTermsIndexingvalues for a flat and a hierarchical dimension (1000 documents, a 10% sample). A read-only review by another model family (OpenAI GPT-5.6, refute lens) pointed out the wider mixed-depth case, which the finder then added and ran (500 instead of 1000). - Then independent AI tools reproduced, reviewed and judged it (see the checks), and this doc's test added the hierarchical sorted-set case, which had only been read before.
No prior report found (2026-10-26, best effort): 201 logged queries and checks over GitHub, four mailing lists, JIRA, downstream projects and the web, including the changed files of all 411 open PRs. Nearest: #6539, which introduced the cap in 2014, and #10425, which made the terms optional.
Searches4 searches
No issue, PR, JIRA entry, list thread or web page found reports amortizeFacetCounts capping counts at a drill-down term docFreq that DrillDownTermsIndexing may leave missing or partial, or sampled facet counts that come out 0 or below the true count. Upstream main and branch_10x had no commit to the collector since 2024-09-10 (committer date), and the cap lines were unchanged (2026-10-26).
Nearest items, none of them this bug: #6539 (LUCENE-5476, introduced the cap on the premise that docFreq "is an upper bound", true then); #10425, #25 and lucene-solr#2471 (LUCENE-9385, made the terms optional, never discuss sampling); open draft #16847 (@jimczi, "Support more than 2^31 documents per index (long global doc ids)": widens the cap lines to long but keeps the cap); #9414 (LUCENE-8367, made only the bare dimension term optional); #6585 (LUCENE-5522, missing drill-down terms for associations, fixed in 4.7.1); #11520, #11286, #9415. Gaps: keyword search only; GitHub Discussions were not searched; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | two scripted prior-report search runs (28 issue and PR queries, 5 commit queries) and 35 read-only GraphQL searches: class, method and option names (FULL_PATH_ONLY, DIMENSION_AND_FULL_PATH, ALL_PATHS_NO_DIM), "drill down terms", "amortized counts", LUCENE-9385, LUCENE-5476; 17 related items read in full | no report; the items listed above |
| Open PRs | 2026-10-26 | the changed files of all 411 open apache/lucene PRs, plus the full file lists of the 3 largest | draft #16847 is the only one that touches the collector; it keeps the cap |
| Mailing lists and JIRA | 2026-10-26 | 40 tool queries and 36 direct archive queries over dev@, java-user@, issues@ and commits@; 3 threads read in full; 8 tool and 7 direct JIRA searches | no report; a 2024 java-user@ thread describes applications that sample facets, and nobody in it mentions DrillDownTermsIndexing |
| Downstream repositories and web | 2026-10-26 | Elasticsearch, OpenSearch, Solr, Lucene.NET and all of GitHub: 3 tool queries and 19 GraphQL searches; 11 web queries | no report; the only downstream amortizeFacetCounts user found is on Lucene.NET 4.8, which lacks the option |
The cap is from 2014 (LUCENE-5476, 4.8.0), when every drill-down term was indexed. LUCENE-9385 (#25, 8.9.0, 2021) made the terms optional without touching sampling. Every executed release from 8.9.0 to 10.5.2 and main fails; 8.8.2 lacks the option. Not fixed upstream.
Versions tested5 rows
An interaction. The cap lines are from LUCENE-5476 (e50b392f467c, 2014-03-20, 4.8.0); git blame in the full history attributes RandomSamplingFacetsCollector.java:236-243 to it, and at that commit FacetsConfig added a drill-down term for every prefix of every path, so docFreq was a true bound. LUCENE-8367 (7.5.0) made only the bare dimension term optional, which the cap never reads. Introduced by LUCENE-9385 (commit and CHANGES title "Add FacetsConfig option to control which drill-down terms are indexed for a FacetLabel"; PR #25 "LUCENE-9385: Add option to skip indexing facet drill down terms"; @zacharymorn, 3648a1020a8a, merged 2021-03-27; branch_8x backport e812a5085904, lucene-solr#2471, 2021-03-29), first released in 8.9.0. It changed only FacetsConfig.java, TestDrillDownQuery.java and TestSortedSetDocValuesFacets.java. Hierarchical sorted-set facets (9.1.0) use the same term indexing and are affected too.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test: 5 of 6 fail (gradle and the standalone runner, assertions on and off); control passes |
| 10.5.2, 10.0.0, 9.12.3, 9.2.0 | affected | this doc's test: 5 of 6 fail, the same numbers (standalone runner, assertions on; the fact check also ran 10.5.2 and 9.2.0 with them off) |
8.9.0, 8.11.4, 9.0.0, 9.2.0, 9.12.3, 10.0.0, 10.5.2, main ea57360912ed | release sweep | ports of the finder's test: 3 of 4 fail with identical numbers (assertions on; main also with them off, and 10.5.2 and 9.12.3 in the fact check) |
| 8.8.2 | no option | DrillDownTermsIndexing does not exist (compile error); the older requireDimensionDrillDown=false control passes 4 of 4 (also on 8.9.0) |
| main + the fix | not affected | every repro passes; upstream TestRandomSamplingFacetsCollector and the whole facet suite pass |
An independent reproducer, a devil's advocate and an adjudication (who re-ran both tests) found it real (adjudication: confirmed, high); read-only reviews by another model family, neither able to run Java, agreed on the root cause, one with a procedural "not real". This doc's runs reproduced it on main a9779ef3c193; fact checks found description errors, now fixed.
Checks and verdicts450 words
Every check that ran code used stock jars, on main with assertions on and off. The reviews by the other model family were read-only (they could not execute code); a separate run re-ran the finder's test for them, and it failed as claimed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API JUnit fails 3 of 4 on main (-ea, -da), 10.5.2, 9.12.3 and 9.2.0; the fix sketch passes it and upstream TestRandomSamplingFacetsCollector (5 iterations). |
| cross-model review, refute lens | not real (low, procedural) | OpenAI GPT-5.6, read-only: could not run Java; agreed with the root cause, found the inputs in contract, rated the intended case moderate, and found the mixed-depth trigger. |
| Independent reproducer | real | Own 9-test class (10,000 documents): 5 of 9 fail on main (-ea, -da), 10.5.2 and 9.12.3; 4 boundary controls pass; the verbose run shows a total of 10,000 next to children of 0. |
| Cross-model review, intended lens | real (medium) | OpenAI GPT-5.6, read-only: the intended case is moderate and fails because no document links the two features; a separate re-run failed 3 of 4. |
| Devil's advocate | real | No intended, misuse or unreachability argument survives; probe: exact counts 100 per label under NONE, a DrillDownQuery with 0 hits, amortized total 1000 with every child 0. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's test (5 of 9 fail) and the finder's (3 of 4) with -ea and -da; corrected the first affected release to 8.9.0. |
| security assessment | none | Trusted configuration triggers it; counts only go down (840 labels per run against ALL), totals and matching unchanged. |
| registry re-runs and audit | keep | Fresh seeds on main: the finder's test fails 3 of 4 (-ea, -da), the independent reproduction's 5 of 9, and the independent reproduction's passes 9 of 9 with the fix sketch; a fourth independent re-run kept the score. |
| this doc's validation | reproduced, fix validated | New 6-test class: 5 of 6 fail on main a9779ef3c193 (gradle and standalone, -ea and -da) and on 10.5.2, 10.0.0, 9.12.3 and 9.2.0 (-ea), including hierarchical sorted-set facets; with the fix it passes, and so do upstream TestRandomSamplingFacetsCollector and the whole facet suite. |
| fact checks of this doc | errors fixed | A fact check re-ran the repro, the fix and the release runs itself and found 2 wording errors; a read-only review by another model family (OpenAI GPT-5.6) found 9 more, the largest that the fix's javadoc promised a more precise bound than the code applies. All were fixed (the fix's javadoc and comment were tightened and re-validated) and the diagram re-rendered; the diagram check passed. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 386 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,397 words
- Registry title
- RandomSamplingFacetsCollector.amortizeFacetCounts caps each amortized label count at the docFreq of the label's drill-down term, so with a non-default FacetsConfig DrillDownTermsIndexing (NONE on any dimension, or FULL_PATH_ONLY / DIMENSION_AND_FULL_PATH on a hierarchical dimension) it silently returns 0, or a value below the true count
- Area
- facet / sampling (RandomSamplingFacetsCollector.amortizeFacetCounts x FacetsConfig drill-down term indexing)
- Priority
- Low, rank 333: Needs two independent opt-ins on one dimension (facet sampling with amortizeFacetCounts and a non-default DrillDownTermsIndexing), and the output is an estimate.
- Impact class
- silent wrong results
- Impact note
- Only applications that sample facets with RandomSamplingFacetsCollector, call amortizeFacetCounts while sampling is active (more hits than sampleSize) and give the dimension a non-default FacetsConfig.setDrillDownTermsIndexing (opt-in since 8.9.0) are hit, and then on every such query: with NONE every amortized label count of the dimension is 0, with FULL_PATH_ONLY or DIMENSION_AND_FULL_PATH on a hierarchical dimension every label above the leaf level is 0, and a label that is the full path of some documents and only an ancestor of others is capped at the docFreq of its full-path term (500 instead of 1000 in the repro), while the dimension total stays amortized; taxonomy and sorted-set doc values facets [exec], ordinary scale (1000 documents suffice), deterministic, with -ea and -da.
- Summary
- You sample facet counts with RandomSamplingFacetsCollector on a dimension whose FacetsConfig skips drill-down terms (DrillDownTermsIndexing NONE, or FULL_PATH_ONLY / DIMENSION_AND_FULL_PATH on a hierarchical dimension), call amortizeFacetCounts to scale the sampled counts up to estimates of the full counts, and expect what the default indexing gives: about sampled / samplingRate per label, capped by the label's real count. Instead each label is capped at reader.docFreq of its drill-down term, which these modes do not index at all (docFreq 0) or index only for the documents whose full path is that label, so a label seen 15 times in a 10% sample comes back as 0 and a label on 1000 documents comes back as 500. Nothing fails, and in the same FacetResult the amortized dimension total (for example 1000) no longer matches its children (all 0).
- Introduced
- 3648a1020a8ab6b729ed53e0360499e624bb0cd1, apache/lucene#25 LUCENE-9385 'Add option to skip indexing facet drill down terms' (zacharymorn, merged to main 2021-03-27); first released through the branch_8x backport e812a5085904 (apache/lucene-solr#2471, 2021-03-29; hash and PR number from the JIRA commit-bot comment, the commit itself not inspected) [exec: release bracket 8.8.2 (FacetsConfig.DrillDownTermsIndexing absent, compile error; the older requireDimensionDrillDown=false control passes 4/4) / 8.9.0 (fails 3/4); read: the commit touches only FacetsConfig.java, TestDrillDownQuery.java and TestSortedSetDocValuesFacets.java]. An interaction, not a change to the faulty lines: the docFreq cap (RandomSamplingFacetsCollector.java:239-241, still the lines of e50b392f467c, LUCENE-5476, 4.8.0, 2014, by git blame) was a real upper bound while every drill-down term was always indexed, and LUCENE-9385 made those terms optional without updating amortizeFacetCounts (2021-03-27 (main; branch_8x backport 2021-03-29); the cap itself dates from 2014-03-20)
- First affected version
- 8.9.0 [exec: fails 3/4 with the same numbers as main]; 8.8.2 lacks the trigger API [exec: compile error, and its pre-8.9 requireDimensionDrillDown control passes 4/4]
- Affected versions
- 8.9.0 through 10.5.2 and main ea57360912ed; not fixed upstream (upstream main and branch_10x have no commit to RandomSamplingFacetsCollector.java since 2024-09-10 and the cap lines are unchanged on upstream main, read 2026-10-26). [exec] The finder repro (the same documents, config and assertions in three API-version ports) fails the same 3 of 4 tests with the same numbers on 8.9.0, 8.11.4, 9.0.0, 9.2.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea; -da also on main); the independent reproduction's independent test fails 5 of 9 on 9.12.3, 10.5.2 and main (-ea, and -da on main). [read] 8.10.x, 8.11.0-8.11.3, 9.1.0, 9.3.0-9.12.2 and 10.1.0-10.5.1: the same code as the executed endpoints. Not affected: 8.8.2 and older, where the option does not exist and every dim/.../label drill-down term is indexed [exec on 8.8.2, read for older]. Unreleased 10.x branches other than branch_10x were not checked. Old releases ran on JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, all read-only; the prior-report record verdict new: 201 logged queries and checks, namely 90 from the scripted prior-report search in two runs over apache/lucene issues, PRs and commits, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web; 54 read-only GitHub GraphQL searches (apache/lucene, downstream projects, Lucene.NET, all of GitHub); 36 direct mailing-list archive queries; 7 JIRA searches; 11 web searches; a changed-file scan of all 411 open apache/lucene PRs; an upstream branch check; 18 hits read and judged, none the same bug; the finder's and the intended-behaviour check's own searches found only #6539 as well). History, not reports: LUCENE-5476 / #6539 (2014) introduced the cap on the stated premise 'The docFreq of the category drill-down term is an upper bound', true then; LUCENE-9385 / #10425 with PRs #25 and lucene-solr#2471 (2021) made the terms optional, and its issue, PR body, reviews and review comments never mention sampling, amortization or docFreq. Open #16847 (jimczi, 'Support more than 2^31 documents per index') is the only open PR that touches the cap lines: it widens them to long but keeps the docFreq cap, so it does not fix this bug and a fix PR would conflict with it textually. Context: LUCENE-8367 / #9414 (made only the bare dimension term optional), LUCENE-5522 / #6585 (an earlier missing-drill-down-terms bug, precedent), LUCENE-10484 / #11520, LUCENE-10250 / #11286, #9415, and a 2024 java-user thread showing production use of the sampling collector
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2, 10.0.0, 9.12.3 and 9.2.0 release jars with assertions on (this doc's test; the fact check added 10.5.2 and 9.2.0 with them off). Earlier checks ran on mainea57360912ed, whose facet module is identical, and the history stage ran a port of the finder's test on 8.8.2, 8.9.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2. The fix was validated in the scratch worktree: this doc's test, upstreamTestRandomSamplingFacetsCollector(also 20 iterations), the wholelucene/facetsuite with assertions on and off, and:lucene:facet:check -x test; version 2 of the fix (javadoc and comment only) was re-validated the same way after the fact checks, on 2026-10-27.
- Finding record
a Lucene main checkout lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:32-41 (class javadoc: 'since the counts of the top-facets is based on the sampled set, you can amortize the counts'), :214-219 (amortizeFacetCounts javadoc: 'Uses the FacetsConfig and the IndexSearcher to determine the upper bound for each facet value'), :220-254 (amortizeFacetCounts; :239 max = reader.docFreq(new Term(dimConfig.indexFieldName, fullPath)); :241 correctedCount = Math.min(max, correctedCount); :248-249 total capped by reader.numDocs())a Lucene main checkout lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java:69-106 (DrillDownTermsIndexing javadoc: NONE 'Index no drill down terms', FULL_PATH_ONLY 'No dimension nor sub-path indexing', DIMENSION_AND_FULL_PATH, ALL_PATHS_NO_DIM, ALL default), :216-226 (setDrillDownTermsIndexing), :419-460 (indexDrillDownTerms: NONE adds nothing; FULL_PATH_ONLY only the full path; DIMENSION_AND_FULL_PATH the dimension and the full path)a Lucene main checkout lucene/facet/src/test/org/apache/lucene/facet/TestRandomSamplingFacetsCollector.java:134-149 (default config: amortized == min(5 * sampled, numDocs / 10))a Lucene main checkout lucene/CHANGES.txt:5302 (Lucene 8.9.0 section), :5337 (LUCENE-9385 entry), :12417 (LUCENE-5476 under 4.8.0)
- The finding in 30 seconds
lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:32-41 (class javadoc), :215-219 (method javadoc), :220-254 (amortizeFacetCounts; :222-224 early return, :228 DimConfig, :239 docFreq cap, :240 estimate, :241 min, :245-250 total)lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java:74-106 (DrillDownTermsIndexing javadoc), :127 (default ALL), :216-226 (setter), :400, :501, :530 (callers), :419-460 (indexDrillDownTerms)
- Who is affected
lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java:57 (@lucene.experimental)lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:216 ("if you use a counting Facets implementation"); FacetsConfig.java:127 (default ALL), :530 (association fields)
- Why it looks unintended
lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:38-40, :215-219lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java:74-106, :216-226lucene/demo/src/java/org/apache/lucene/demo/facet/package-info.java:231-243, :377-388 (exact recount: :383-385)lucene/facet/src/test/org/apache/lucene/facet/TestRandomSamplingFacetsCollector.java:135-149lucene/CHANGES.txt:5318, :5353 (8.9.0, LUCENE-9385), :12375, :12433 (4.8.0, LUCENE-5476), :12672 (LUCENE-5522)
- TestAmortizeWithoutDrillDownTerms.java (JUnit test):
repro/LFV-425/src/org/apache/lucene/facet/TestAmortizeWithoutDrillDownTerms.java(59 lines)
A light summary card, made in parallel with this doc from an executed per-label probe on main a9779ef3c193 (assertions on and off, and with the fix as a control); the PNG is the summary card.
assets/LFV-425/bug.png(386 KB)