build() loops over the entries and, for each one, over its analyzed paths, writing every path into the suggester. The entry counter is incremented in the header of that inner loop, so an entry with two paths counts twice. The number is published when the build ends, saved by store(), read back by load() and returned by getCount().
AnalyzingSuggester(and its subclassFuzzySuggester) runs each suggestion entry through an index analyzer and stores the analyzed text. A lookup analyzes what the user typed, matches it against the stored text and returns the original entries.- An analyzer can stack tokens at one position. The synonym rule fast -> {fast, quick} turns
fast carinto a small token graph with two paths,fast carandquick car. The suggester stores both, so typingquickfindsfast car. getCount()reports how many entries the suggester was built from.
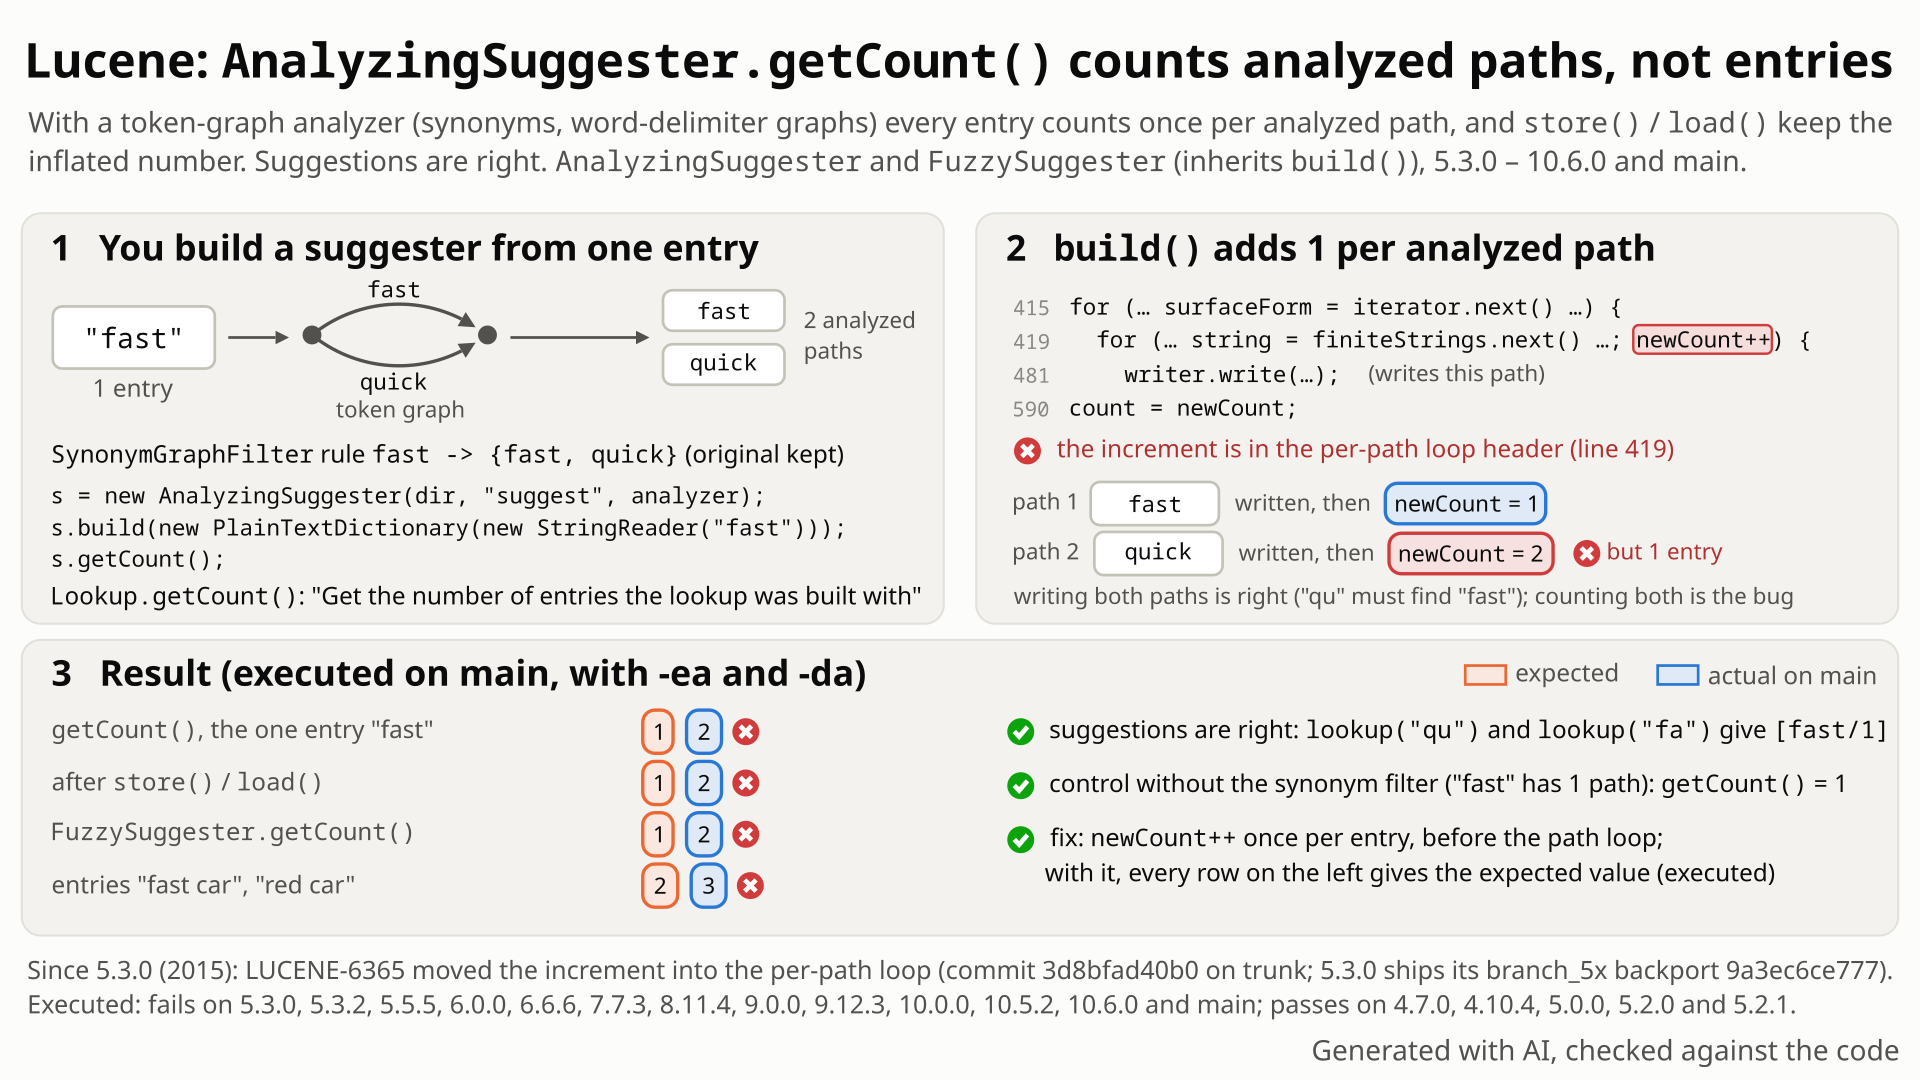
fast, fans out into two analyzed paths, fast and quick; build() counts each path, so getCount() says 2 for one entry, and store()/load() keep it. Select the still to open it at full size. Generated with AI, checked against the code.- Build an
AnalyzingSuggesterfrom one entry,fast, with an index analyzer whose synonym rule is fast -> {fast, quick}. The analyzer turns the entry into two analyzed paths,fastandquick; the suggester indexes both, so typingquorfasuggestsfast. - You expect
getCount()to return 1: it is documented as "the number of entries the lookup was built with". - You get 2:
build()adds 1 for every analyzed path, not once per entry. Two entriesfast carandred cargive 3; the single entrywifi wifi wifiwith a synonym forwifigives 8 (2 x 2 x 2 paths). store()/load()keep the wrong number andFuzzySuggesterinherits it. 4.7.0 to 5.2.1 counted entries; a 2015 loop rewrite moved the increment into the per-path loop. Counting once per entry again is a one-line fix.
Applications that build AnalyzingSuggester or FuzzySuggester with synonyms or a word-delimiter graph in the index analyzer, a setup the class javadoc describes, and read getCount() to show, log or check the dictionary size. The count is inflated by the number of paths per entry; suggestions, weights and build work are unaffected.
Mechanism, terms and numbers597 words
Lookup#getCount returns "the number of entries the lookup was built with". AnalyzingSuggester.build (inherited by FuzzySuggester) indexes every analyzed path of each entry, and it increments its counter in the header of that per-path loop (AnalyzingSuggester.java:419), so with an index analyzer that stacks tokens (a synonym graph, a word-delimiter graph with PRESERVE_ORIGINAL) each entry counts once per path: one entry fast with the rule fast -> {fast, quick} gives 2, the entries fast car and red car give 3, and the entry wifi wifi wifi with a stacked synonym gives 8. The same per-path increment leaves out an entry that analyzes to no token at all, such as an entry of only stop words. store() writes the number and load() reads it back. Suggestions are correct and no production code in Lucene calls getCount(), so only applications that show or check the count are affected. The count was per entry from 4.7.0, when it was added, to 5.2.1; LUCENE-6365 moved the increment while rewriting the loop, first released in 5.3.0. Every release run from 5.3.0 to 10.6.0 and main is affected, and moving newCount++ before the per-path loop fixes it.
- One entry, many paths. For each entry
buildanalyzes it into an automaton and iterates its finite strings, at mostmaxGraphExpansionsof them (AnalyzingSuggester.java:415-417). The 3- and 4-argument constructors of both classes pass-1, no limit (:173-176,:182-196;FuzzySuggester.java:98-129). The class knows paths and entries differ:maxAnalyzedPathsForOneInputis the "Highest number of analyzed paths we saw for any single input surface form. For analyzers that never create graphs this will always be 1." (:153-157). - The increment is in the per-path loop header (
:415-419; the end-of-line comments are ours):
   for (BytesRef surfaceForm; (surfaceForm = iterator.next()) != null; ) {       // once per entry
     LimitedFiniteStringsIterator finiteStrings =
         new LimitedFiniteStringsIterator(toAutomaton(surfaceForm, ts2a), maxGraphExpansions);

for (IntsRef string; (string = finiteStrings.next()) != null; newCount++) { // once per path- Published, stored, reloaded.
count = newCountat the end of the build (:590);store()writes it (:601),load()reads it back (:614),getCount()returns it (:851-852). - FuzzySuggester extends
AnalyzingSuggester(FuzzySuggester.java:66) and overrides neitherbuildnorgetCount.
| entries | index analyzer | paths | getCount() | expected |
|---|---|---|---|---|
fast | whitespace + synonym fast -> {fast, quick} | 2 | 2, also after store()/load() and with FuzzySuggester | 1 |
fast car, red car | the same | 2 + 1 | 3, also after store()/load(), both suggesters | 2 |
fast fast | the same | 4 | 4, also after store()/load() | 1 |
wifi wifi wifi | whitespace + a filter that stacks wireless on wifi | 8 | 8 | 1 |
| 2 entries | WordDelimiterGraphFilter with PRESERVE_ORIGINAL | 3 | 3 | 2 |
fast car, red car | synonym, maxGraphExpansions = 1 | 1 + 1 | 2 | 2 |
the, fast car | whitespace + StopFilter for the | 0 + 1 | 1 | 2 |
fast car, a blank line, red car | whitespace only | 1 + 0 + 1 | 2 | 3 |
Entries with exactly one analyzed path are counted right. An entry that analyzes to no token (a blank entry, or only stop words) has no path, because the automaton TokenStreamToAutomaton builds reaches an accept state only through a position that a token created (TokenStreamToAutomaton.java:244-255), so the per-path increment leaves it out: 5.2.1 counted it (2 for the, fast car), 5.3.0 does not (1), and the fix counts it again (2). Every lookup checked in these runs returned the right suggestions.
Exposure and likelihood199 words
- Who. Users of
AnalyzingSuggesterandFuzzySuggester(both@lucene.experimental) whose index analysis gives an entry several paths, asSynonymGraphFilterwith a matching rule andWordDelimiterGraphFilterwithPRESERVE_ORIGINALon a token it splits do in the runs. The class javadoc itself shows a synonym setup (AnalyzingSuggester.java:78-80). - Effect. A silently wrong number from
getCount(): the inflation factor is the number of analyzed paths per entry, 2x for one matching synonym and, with independent two-way synonym alternatives, 2^k for k matching tokens in one entry (8 forwifi wifi wifi); the default constructors set no cap (maxGraphExpansions-1). Entries that analyze to no token are left out of the count. A suggester saved withstore()and reloaded withload()reports the same wrong number until it is rebuilt. - Not affected. Suggestions, weights, payloads and build work: every path is indexed whether or not it is counted. No production code in Lucene calls
getCount()(store()only writes the field), and Solr's suggester code does not call it either (other downstream code was not surveyed). - Likelihood: plausible. Deterministic on every such build, but only applications that read the count notice; the searches found no public report since 5.3.0.
One JUnit test in lucene/suggest, using only public suggester and analysis APIs: build an AnalyzingSuggester from the single entry fast with the stock SynonymGraphFilter rule fast -> {fast, quick}, then check getCount(). It fails on main with assertions on and off, and on the 10.6.0 and 10.5.2 release jars.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.analyzing;

import java.io.StringReader;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.analysis.synonym.SynonymGraphFilter;
import org.apache.lucene.analysis.synonym.SynonymMap;
import org.apache.lucene.search.spell.PlainTextDictionary;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.CharsRef;

public class TestAnalyzingSuggesterGetCount extends LuceneTestCase {

  public void testSynonymDoesNotInflateCount() throws Exception {
    SynonymMap.Builder builder = new SynonymMap.Builder(true);
    builder.add(new CharsRef("fast"), new CharsRef("quick"), true);
    SynonymMap synonyms = builder.build();
    try (Analyzer analyzer =
            new Analyzer() {
              @Override
              protected TokenStreamComponents createComponents(String fieldName) {
                Tokenizer tokenizer = new WhitespaceTokenizer();
                return new TokenStreamComponents(
                    tokenizer, new SynonymGraphFilter(tokenizer, synonyms, true));
              }
            };
        Directory dir = newDirectory()) {
      AnalyzingSuggester suggester = new AnalyzingSuggester(dir, "suggest", analyzer);
      suggester.build(new PlainTextDictionary(new StringReader("fast")));
      // one entry, two analyzed paths (fast, quick): expected 1, actual 2
      assertEquals("number of entries the lookup was built with", 1, suggester.getCount());
    }
  }
}
cp $REPRO/TestAnalyzingSuggesterGetCount.java $LUCENE/lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/
cd $LUCENE && ./gradlew :lucene:suggest:test --tests org.apache.lucene.search.suggest.analyzing.TestAnalyzingSuggesterGetCount -Ptests.seed=DEADBEEF -Ptests.asserts=true
# also with -Ptests.asserts=false
- Expected
getCount()returns 1, the one entry the suggester was built from.- Observed
AssertionError: number of entries the lookup was built with expected:<1> but was:<2>, assertions on and off.
More files, environment, full output293 words
lucene/suggest already depends on lucene/analysis/common, so the test drops into the module's test tree as is. The test framework randomizes settings such as locale and directory, but the suggester uses the directory only for temporary sort files (AnalyzingSuggester.java:396-400) and the count does not depend on the seed. It failed the same way with every seed tried: DEADBEEF through gradle with assertions on and off, and on a standalone runner with -ea and -da; 5EED0001 with -ea; FC431A01 (-ea) and FC431A02 (-da). The standalone runner records the main checkout as dirty, because of two untracked files outside lucene/suggest (neither is a .java source); the tracked diff is empty, and the gradle runs in a clean scratch checkout fail the same way.
Suggested regression test: this same test, for example as a method of TestAnalyzingSuggester.
Not shown by this test (same cause, same fix): FuzzySuggester, the store()/load() round trip, larger inflation with more stacked tokens. Two entries fast car, red car give 3 instead of 2 for both suggesters, before and after store()/load(), while lookup("quick") and lookup("fast") each return the one entry.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also the 10.6.0 and 10.5.2 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the code path is pure Java) |
TestAnalyzingSuggesterGetCount > testSynonymDoesNotInflateCount FAILED
    java.lang.AssertionError: number of entries the lookup was built with expected:<1> but was:<2>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:10604C74227CF345]:0)
        at junit@4.13.2/org.junit.Assert.fail(Assert.java:89)
        at junit@4.13.2/org.junit.Assert.failNotEquals(Assert.java:835)
        at junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:647)
        at org.apache.lucene.search.suggest.analyzing.TestAnalyzingSuggesterGetCount.testSynonymDoesNotInflateCount(TestAnalyzingSuggesterGetCount.java:49)

:lucene:suggest:test (FAILURE): 1 test, 1  failure
1 test completed, 1 failed

# the same with -Ptests.asserts=false, on the standalone runner with -ea and -da,
# and on the 10.6.0 and 10.5.2 release jars; with the recommended fix: passesLookup#getCount: "Get the number of entries the lookup was built with"; the class tracks analyzed paths separately (maxAnalyzedPathsForOneInput).- 4.7.0 to 5.2.1 counted once per entry; the 2015 loop rewrite (LUCENE-6365) moved the increment without discussing counting.
- Not the internal record count either: dropped duplicates are counted, and the number changes with
maxGraphExpansions.
The full argument233 words
- Contract.
Lookup#getCount: "Get the number of entries the lookup was built with" / "@return total number of suggester entries" (Lookup.java:171-176). The field: "Number of entries the lookup was built with" (AnalyzingSuggester.java:166).Lookup.build(Dictionary)feedsdict.getEntryIterator()(Lookup.java:145-146), so the entries are what the dictionary yields. - The class separates paths from entries.
maxAnalyzedPathsForOneInputcounts "analyzed paths ... for any single input surface form" (:153-157);maxGraphExpansions"only matters if your analyzer makes lots of alternate paths (e.g. contains SynonymFilter)" (:144-147). - History. LUCENE-5404 (#6467, "Add support to get number of entries a Suggester Lookup was built with and minor refactorings";
b5926da2d67on trunk andfdf4595051aon branch_4x, which 4.7.0 ships) putcount++after the loop over an entry's paths, so every entry counted once, also one with no path. LUCENE-6365 (#7425,3d8bfad40b0and branch_5x9a3ec6ce777, 2015-07-04, first released in 5.3.0) replaced that loop with an iterator loop and moved the increment into its header; its commit message, CHANGES entry and issue discussion say nothing about counting. LUCENE-10292 (#11328) renamed the counter tonewCountand kept it there. That the move was an accident is an inference from this record; nobody upstream has said so. - Tests. Every upstream
getCountassertion for these classes usesMockAnalyzer, where paths equal entries (TestAnalyzingSuggester.java:181, 193, 1028, 1051;TestFuzzySuggesterhas none). The whole suggest suite passes with the fix.
The devil's-advocate check172 words
Strongest case (the devil's-advocate verifier and the adjudication): "entries" means the suggester's internal records, the analyzed-form and surface-form pairs it writes into its FST, so counting paths is by design; getCount is loose across lookups anyway (inputs a, a, b give 2 in WFSTCompletionLookup, 3 in TSTLookup and FSTCompletionLookup); and the classes are experimental.
Why it fails: the count is not the record count either. With a keyword analyzer a, a, b gives 3 although the duplicate surface form is dropped from the FST, and fast car twice with the synonym gives 4. A documented "number of entries" that changes with the maxGraphExpansions tuning knob (3 or 2 for the same two entries) is implausible, and #6467 and the 4.7.0 to 5.2.1 code count entries. The per-path count also drops entries that 5.2.1 counted: an entry that analyzes to no token adds 0. Experimental status bears on severity, not on intent. Still, a maintainer who puts compatibility first may prefer to document today's count rather than change a stored statistic.
Recommended Count once per entry, before the per-path loop
Increment newCount once per entry, just before the loop over its analyzed paths, instead of in that loop's header (one file, +2/-1). This restores the 4.7.0 to 5.2.1 count. The repro, TestAnalyzingSuggester, TestFuzzySuggester and the whole suggest test suite pass with it.
        LimitedFiniteStringsIterator finiteStrings =
            new LimitedFiniteStringsIterator(toAutomaton(surfaceForm, ts2a), maxGraphExpansions);

-        for (IntsRef string; (string = finiteStrings.next()) != null; newCount++) {
+        newCount++; // one entry, however many analyzed paths it has
+        for (IntsRef string; (string = finiteStrings.next()) != null; ) {
All options and trade-offs4 options · 575 words
The recommended fix is the finder's one-line change, applied to 645d4fe14a20 in a scratch worktree with git apply and run through gradle. An equivalent placement and two alternatives follow. Fix A changes the stored count once a suggester is rebuilt, so the issue can ask the maintainers whether compatibility makes them prefer documenting the current count (option C).
In AnalyzingSuggester.build, move newCount++ out of the header of the loop over finiteStrings to the line before it.
        LimitedFiniteStringsIterator finiteStrings =
            new LimitedFiniteStringsIterator(toAutomaton(surfaceForm, ts2a), maxGraphExpansions);

-        for (IntsRef string; (string = finiteStrings.next()) != null; newCount++) {
+        newCount++; // one entry, however many analyzed paths it has
+        for (IntsRef string; (string = finiteStrings.next()) != null; ) {
Trade-offs
- Restores the 4.7.0 to 5.2.1 meaning: one per input entry, duplicates included, as
TSTLookupandFSTCompletionLookupcount. Entries with exactly one analyzed path count as today; an entry with several paths counts once instead of once per path, and an entry that analyzes to no token counts once instead of zero times, as in 5.2.1. - No format change:
store()/load()are untouched. Suggesters saved by affected versions keep their inflated count until rebuilt; worth a CHANGES line. - Behaviour change to weigh: once rebuilt, a suggester whose entries have several paths or none reports a different number than before (smaller, or larger), so an application that compares counts across a Lucene upgrade sees a one-time step. A maintainer who puts compatibility first may prefer documenting the current count.
- No change to suggestions or build work: the loop body is untouched.
What the checks validated
- Stock + repro through gradle: fails (
expected:<1> but was:<2>). + fix: the repro passes with assertions on and off. - + fix:
TestAnalyzingSuggester(23 tests),TestFuzzySuggester(14) and the repro pass, 38 of 38. - + fix: the whole
:lucene:suggest:test, 32 suites, 237 tests, 0 failures, 7 skipped by their own markers (assertions on); the first doc round got the same counts with assertions off. :lucene:suggest:check -x test(google-java-format, ecjLint, forbiddenApis, with the test in the tree): passes.- In the hunt (fixed class shadowed): the finder's 2 tests, the independent reproducer's 6 tests and the cross-model stage's probe pass; the first fact check's probe gives the entry count for every case, including entries with no token.
- Not run: the full Lucene test suite, nightly tests, benchmarks.
Put newCount++ after the loop, next to the maxAnalyzedPathsForOneInput update (AnalyzingSuggester.java:484).
Trade-offs
Identical to the recommended fix for every entry, including one with no path: both add 1 once per entry. Executed by the fact check with the fixed class shadowed: the repro passes with assertions off, and every probe value, the zero-token cases included, equals the recommended fix's.
Say in the field comment and an AnalyzingSuggester#getCount javadoc that the count is of analyzed paths.
Trade-offs
Keeps today's numbers but contradicts Lookup#getCount, makes the number depend on maxGraphExpansions, and is still not the record count (duplicates are counted, entries with no token are not). It is the option for a maintainer who puts compatibility first.
Count the distinct analyzed-form and surface-form pairs written into the FST.
Trade-offs
Also changes the count for analyzers without graphs (a, a, b would give 2) and has no basis in the javadoc.
Products that show a suggester's entry count, for example as a dictionary-size statistic, report inflated numbers when their suggest analyzer uses synonyms; the suggestions themselves are unaffected.
Code reading, no formal tool. While listing what every Lookup implementation counts and comparing it with the getCount javadoc, the finder saw the increment in the header of the per-path loop. A public-API JUnit with the stock SynonymGraphFilter confirmed it, and the git history dated it to 2015.
The method in full123 words
Method: non-formal (code reading plus an executed test), a hunt unit (counts and statistics across modules), 2026-10-26, main ea57360912ed.
- The finder inventoried what each suggester's
getCount()counts and read it against the javadoc;AnalyzingSuggester.java:419was the one place that counts analyzed paths rather than inputs (the inventory also noted thatWFSTCompletionLookupcounts distinct keys, an ambiguity it did not file). - A JUnit on the stock jars (entries
fast carandred car,WhitespaceTokenizer+SynonymGraphFilter, lookups asserted before the count) failed for both suggesters: 3 instead of 2. - The history clone (
git log -Gon the counting line,git showof the four commits that touched it) and release runs from 4.6.1 to 10.5.2 dated the change to LUCENE-6365.
No prior public report found in these best-effort searches: 162 queries over GitHub (Lucene and downstream projects), the JIRA archive, four mailing lists and the web, plus all open PRs (2026-10-26), refreshed three times on 2026-10-30. Closest: #6467, which added getCount counting per entry, and #7425, the change that moved the increment; neither reports this.
Searches5 searches
Context, not reports: #6467 / LUCENE-5404 (2014) added getCount as the number of entries a lookup was built with and counted once per entry; #7425 / LUCENE-6365 (2015) is the introducing change, whose discussion is about the iterator API; #11328 / LUCENE-10292 (2022) made getCount() consistent with lookup() during a concurrent rebuild and kept the per-path increment; a 2014 java-user thread is about an AnalyzingInfixSuggester.getCount() NPE before build(). Lucene.NET's port, based on 4.8, still counts per entry. Search limits: keyword search only; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; Elasticsearch, OpenSearch, Solr; dev@, java-user@, issues@, commits@; LUCENE JIRA; the web | 2026-10-26 | 111 queries with a scripted prior-report search in three runs (42 issue/PR incl. comments, 7 commit, 2 downstream, 44 mailing-list, 10 JIRA, 6 web) | no report |
| GitHub (incl. apache/lucene-solr, apache/lucenenet, apache/solr, elastic/elasticsearch, opensearch-project/OpenSearch), Solr's suggester sources, the Lucene.NET port | 2026-10-26 | 51 manual searches (issue/PR, commit, code, web); full reads of the 9 most relevant issues and one java-user thread | no report; Solr's suggester code does not call getCount |
| Open apache/lucene PRs | 2026-10-26 | the changed files of all 411 open PRs | none touches AnalyzingSuggester.java, FuzzySuggester.java or Lookup.java |
| Refresh: upstream main, file history, issue/PR search, recently updated PRs | 2026-10-30 (morning) | upstream head and the newest commits of the three files; searches for AnalyzingSuggester or FuzzySuggester with getCount, getCount with synonym or analyzed paths, new suggester issues since 2026-10-25; the files of the 90 PRs updated since 2026-10-26 | no new item; AnalyzingSuggester.java last changed 2026-06-14 (#16255) |
| Refresh: upstream main and issue/PR search | 2026-10-30 | upstream head 2f424fd428da, AnalyzingSuggester.java read there; "AnalyzingSuggester getCount", "FuzzySuggester getCount", "suggester getCount synonym", "getCount analyzed paths" (issues and PRs, any state); open PRs updated since 2026-10-30 matching "suggest" | 0 results each; no matching open PR; the increment is still in the loop header at line 419 |
Introduced by LUCENE-6365 (2015), which moved the increment into the per-path loop while rewriting it; first released in 5.3.0. 4.7.0 to 5.2.1 counted once per entry. Every release run from 5.3.0 to 10.6.0 and main is affected; upstream main still has it.
Versions tested9 rows
LUCENE-5404 (#6467, b5926da2d67 on trunk and fdf4595051a on branch_4x, 2014-02-07; 4.7.0 ships the branch_4x commit) added getCount() with count++ after the loop over an entry's paths. LUCENE-6365 "Optimized iteration of finite strings" (#7425; Subversion era, reviewed as JIRA patches, no PR) replaced that loop with for (IntsRef string; (string = finiteStrings.next()) != null; count++), in 3d8bfad40b0 on trunk and 9a3ec6ce777 on branch_5x, both 2015-07-04; the loop-header increment was already in the contributor patch of 2015-07-03. LUCENE-10292 (#11328, 5015dc6dbb8) renamed the counter to newCount and kept the increment. Every release tag from 5.3.0 to 10.5.2 in the history clone contains the change (8.8.2 to 8.11.4 are untagged there; 8.11.4 was run). The old releases ran on OpenJDK 25 with a version-portable main() and a hand-written stacking filter, because SynonymGraphFilter exists only from 6.4.
| Version or commit | Verdict | Result |
|---|---|---|
| 4.6.1 | API absent | no getCount(); the repro does not compile |
| 4.7.0, 4.10.4, 5.0.0, 5.2.0, 5.2.1 | not affected | 2 for 2 entries, also after store()/load(); 5.2.1 also counts an entry of only stop words (2 for the, fast car) |
| 5.3.0 | first release | 3 for 2 entries, also after store()/load(), both suggesters; an entry of only stop words is not counted (1 for the, fast car) |
| 5.3.2, 5.5.5, 6.0.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 10.0.0 | affected | 3 for 2 entries, also after store()/load() |
| 9.12.3, 10.5.2 | affected | the same; the finder's JUnit fails 2 of 2 with -ea and -da |
10.6.0 (4ae946e5a9b) | affected | the one-method repro fails: 2 instead of 1 |
main 645d4fe14a20 | affected | the repro fails through gradle and on the standalone runner, assertions on and off |
upstream main 2f424fd428da (2026-10-30) | read | same code: the increment is still in the loop header; AnalyzingSuggester.java last changed by #16255 (2026-06-14) |
with the fix (main 645d4fe14a20) | not affected | the repro, TestAnalyzingSuggester, TestFuzzySuggester and the whole lucene/suggest suite pass |
The finder, an independent reproducer, a devil's-advocate verifier, a cross-model stage and an adjudication rate it real, and a credibility audit kept it; each re-ran a repro. A cross-model review said not real only because it could not run code; it agreed with the root cause. This doc's runs reproduced it and validated the fix.
Checks and verdicts548 words
The cross-model reviews (OpenAI GPT-5.6) ran read-only; the executed evidence comes from the finder, the reproducer, the cross-model stage's own runs, the devil's advocate, the adjudication, the audit, the minimization step, the first and second doc rounds' fact checks and this doc's runs.
| Check | Verdict | What it found |
|---|---|---|
| finder (a hunt unit) | candidate | Public-API JUnit (fast car, red car, lookups asserted first) fails 2 of 2 on main (-ea, -da), 10.5.2 and 9.12.3: 3 instead of 2, both suggesters; passes with the fix; upstream TestAnalyzingSuggester and TestFuzzySuggester 37 of 37 with it. |
| cross-model review, refute lens | not real (low), procedural | Read-only, could not run Java, so it voted not real on procedure only; root cause agrees, inputs in contract, intended-behaviour argument weak. A separate run re-ran the repro: 2 of 2 fail. |
| Independent reproducer | real | Own 6-test JUnit fails 5 of 6 on main (-ea, -da), 10.5.2 and 9.12.3 (5 for 3 entries, 5 after store()/load(), 8 for wifi wifi wifi, FuzzySuggester, WordDelimiterGraphFilter); the no-graph control passes; 6 of 6 with the fix; 5.2.1 passes, 5.3.0 fails. |
| cross-model review, intended lens | real (medium) | Intended-behaviour argument weak. Separate runs: the repro fails on main and 10.5.2 and passes with the fix; one entry fast fast gives 4, also after store()/load(), and 1 with the fix. |
| Devil's advocate | real | The internal-records reading fails on 7 grounds; probe: a, a, b gives 3, fast car twice gives 4, maxGraphExpansions -1/1/2 gives 3/2/3. |
| adjudication | confirmed (high) | Re-ran the finder's JUnit (-ea, -da: 2 of 2 fail) and the independent reproduction's (-ea: 5 of 6 fail, control passes). |
| credibility audit | keep | Fresh-seed re-run on main: 2 of 2 fail; class minor kept, score not inflated. |
| minimization | verified | Reduced to the one-method test; fails on 645d4fe14a20 (-ea, -da, two seeds), passes with the fix shadowed. |
| Fact checks and diagram check of this doc | bug holds; wording corrected | First round: an independent fact check re-ran the doc's gradle command (assertions on and off), the fix with the whole suggest suite, the repro on main, 10.6.0 and 10.5.2 at fresh seeds, fix B, its own probe of every quoted count and the history boundary; it found that an entry that analyzes to no token is not counted either. A read-only cross-model fact check (OpenAI GPT-5.6) re-read every citation, and a diagram check found the visuals correct. Second round, on the rewritten doc: the fact check re-ran the gradle command in a fresh clone, the fix with the closest suites, the repro on main, 10.6.0 and 10.5.2 at fresh seeds, its own probe and the 5.2.1/5.3.0 boundary, and found one overclaim about the finder's inventory; the cross-model fact check found no factual error and four overclaims; the diagram check found the summary card's version range stale (it left out 10.6.0), and the card was re-rendered. All errors are fixed in this doc. |
| this doc's runs | reproduced, fix validated | The one-method test on main through gradle and on the standalone runner, assertions on and off; with the fix the repro, the two closest suites, the whole suggest suite and the module's static checks pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 489 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,362 words
- Registry title
- AnalyzingSuggester and FuzzySuggester getCount() counts analyzed paths instead of entries when the analyzer produces a token graph (synonyms, word-delimiter graphs), and store()/load() persist the inflated count
- Area
- suggest / analyzing suggester (AnalyzingSuggester.build and getCount, inherited by FuzzySuggester)
- Priority
- Low, rank 636: AnalyzingSuggester and FuzzySuggester getCount() is inflated whenever the analyzer makes token graphs while lookups stay correct, and only apps that display the count notice.
- Impact class
- minor
- Impact note
- Only a statistic is wrong: applications that build an AnalyzingSuggester or FuzzySuggester (every release from 5.3.0 to 10.5.2 and main) with an index analyzer that emits stacked tokens, such as SynonymGraphFilter or WordDelimiterGraphFilter with PRESERVE_ORIGINAL, get from getCount(), and from a suggester reloaded with load(), the number of analyzed paths (up to maxGraphExpansions per entry, unlimited in the convenience constructors) instead of the number of entries, on every build and at any scale; suggestions are unchanged, and nothing in Lucene reads the value.
- Summary
- You build an AnalyzingSuggester or FuzzySuggester from the two entries 'fast car' and 'red car' with an analyzer whose synonym rule maps fast to {fast, quick}, and you expect getCount() to return 2, because Lookup#getCount is documented as 'the number of entries the lookup was built with'. It returns 3: build() increments its counter once for every analyzed path of an entry ('fast car' and 'quick car' here), not once per entry, so each entry counts as often as its token graph has paths (8 for the single entry 'wifi wifi wifi' with one stacked synonym), and store() and load() keep the inflated number. Lookups are correct, and analyzers that produce no token graph give the right count.
- Introduced
- 3d8bfad40b0217a9a2faa193e3086e876caab041 (trunk, svn r1689192) and its branch_5x backport 9a3ec6ce7778e8b6cf23f99e4524827b12263baf (svn r1689193), the one in the first affected release: LUCENE-6365 'Optimized iteration of finite strings' (migrated issue apache/lucene#7425; Subversion era, reviewed as JIRA patches, no GitHub PR; committed by mikemccand; the loop-header increment is already in the contributor patch FiniteStrings_noreuse.patch of 2015-07-03) [read: the diff replaces the per-entry 'count++' after 'for (IntsRef path : paths)' with 'for (IntsRef string; (string = finiteStrings.next()) != null; count++)'; git log -G on the counting line lists only f2f91bae46c (class added), b5926da2d67, 3d8bfad40b0 and 5015dc6dbb8; exec: the release bracket 5.2.1 pass / 5.3.0 fail]. No commit-level bisect. Regression: Lookup#getCount was added by LUCENE-5404 (apache/lucene#6467; b5926da2d67 on trunk, fdf4595051a on branch_4x, 2014-02-07, first released in 4.7.0), which counted once per entry; LUCENE-10292 (5015dc6dbb8, apache/lucene#11328) later renamed the counter to newCount and kept the per-path increment (2015-07-04 (3d8bfad40b0 on trunk and 9a3ec6ce777 on branch_5x; first release 5.3.0, 2015-08-20))
- First affected version
- 5.3.0 [exec: the version-portable main() gives getCount 3 for 2 entries for AnalyzingSuggester and FuzzySuggester, also after store()/load(), with a no-graph control of 2; the independent reproduction's own boundary main() gives 5 for 3 entries]; 5.2.1 is the last unaffected release [exec: 2 for 2 entries; the independent reproduction: 3 for 3]
- Affected versions
- every release from 5.3.0 to 10.5.2 (103 releases: 5.3.0-5.5.5, 6.0.0-6.6.6, 7.0.0-7.7.3, 8.0.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.5.2) and main ea57360912ed [exec: the portable main() fails on 5.3.0, 5.3.2, 5.5.5, 6.0.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main; the finder's JUnit with the stock SynonymGraphFilter fails 2 of 2 on 9.12.3, 10.5.2 and main with -ea and -da; the independent reproduction's JUnit fails 5 of 6 on main (-ea and -da), 10.5.2 and 9.12.3; read: every release tag from 5.3.0 to 10.5.2 contains 9a3ec6ce777 or 3d8bfad40b0 (git tag --contains; 8.8.2-8.11.4 are untagged in the history clone, and 8.11.4 was executed), and the counting line changed later only by the LUCENE-10292 rename]; not affected: 4.7.0-4.10.4 (never received LUCENE-6365) and 5.0.0-5.2.1 [exec on 4.7.0, 4.10.4, 5.0.0, 5.2.0 and 5.2.1]; 4.6.1 and earlier have no getCount() [exec: compile error]; upstream main cf398bfb142c and branch_10x still have the per-path increment [read 2026-10-26]; other unreleased maintenance branches not checked; not fixed anywhere. Caveats: old releases ran on JDK 25; the portable repro uses a hand-written posInc=0 stacking TokenFilter because SynonymGraphFilter exists only from 6.4
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, follow-up prior-report record verdict new: 162 queries, 111 by a scripted prior-report search in three runs (42 GitHub issue/PR incl. comments, 7 commit, 2 downstream, 44 mailing-list over dev@, java-user@, issues@ and commits@, 10 JIRA, 6 web) and 51 manual (27 GitHub searches incl. apache/lucene-solr, apache/lucenenet, apache/solr, elastic/elasticsearch and opensearch-project/OpenSearch, 3 commit, 3 code, 2 web), plus the file lists of all 411 open apache/lucene PRs, Solr's suggester sources, the Lucene.NET port, full reads of the 9 most relevant issues and one java-user thread; the intended-behaviour check's gh searches agree): no issue, PR, commit, JIRA entry, list thread or downstream report describes getCount() counting analyzed paths; not fixed: upstream main cf398bfb142c and branch_10x still increment newCount in the header of the per-path loop (AnalyzingSuggester.java:419), and no open PR touches AnalyzingSuggester.java, FuzzySuggester.java or Lookup.java; related, not reports of this bug: #6467 (LUCENE-5404, added getCount and counted once per entry), #7425 (LUCENE-6365, the introducing change; its discussion is about the iterator API and never mentions counting), #11328 (LUCENE-10292, made getCount() consistent with lookup() during a concurrent build and kept the per-path increment), a 2014 java-user thread on an AnalyzingInfixSuggester.getCount() NPE before build(); gaps: GitHub search is phrase-like and best effort, GitHub's search rate limit was reached, list search matches words not code identifiers, private reports are not visible
- Lucene commit tested
- main
645d4fe14a20(11.0.0-SNAPSHOT, commit of 2026-10-28), this doc's runs on 2026-10-30: the one-method repro on the standalone runner (-ea,-da) and through gradle in a scratch worktree, stock (fails) and with the fix (passes, assertions on and off); with the fix alsoTestAnalyzingSuggester,TestFuzzySuggesterand the wholelucene/suggestsuite, and:lucene:suggest:check -x test; the worktree was removed afterwards. The first doc round also ran the whole suite with the fix and assertions off, and the repro on the 10.6.0 (4ae946e5a9b) and 10.5.2 release jars. The hunt and its reviews ran on mainea57360912ed, wherelucene/suggestis identical, and the history step on release jars from 4.6.1 to 10.5.2. Upstream main2f424fd428dawas read on 2026-10-30. Only Linux aarch64 and OpenJDK 25.0.3 were run.
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/Lookup.java:171-176 (getCount javadoc: 'Get the number of entries the lookup was built with' / '@return total number of suggester entries')lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:78, 98, 153-157, 166-167, 410, 416-419, 590, 600-601, 613-614, 851-852 (SynonymFilter example in the class javadoc, @lucene.experimental, maxAnalyzedPathsForOneInput 'analyzed paths ... for any single input surface form', count field 'Number of entries the lookup was built with', newCount, the per-path increment, publish, store, load, getCount)lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FuzzySuggester.java:64 (@lucene.experimental; inherits build() and getCount())
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:153-157, 173-196, 410-419, 484, 590, 601, 614, 851-852a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FuzzySuggester.java:66, 98-129a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/Lookup.java:171-176a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:244-255
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:78-80, 98, 173-196; lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FuzzySuggester.java:64
- Minimal repro
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:396-400 (the directory holds the offline sort's temp files)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/Lookup.java:145-146, 171-176; lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:144-147, 153-157, 166a Lucene main checkout (645d4fe14a20) lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestAnalyzingSuggester.java:181, 193, 1028, 1051
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:415-419, 484
- TestAnalyzingSuggesterGetCount.java (lucene/suggest test, one method):
repro/LFV-431/src/org/apache/lucene/search/suggest/analyzing/TestAnalyzingSuggesterGetCount.java(52 lines)
A summary card (PNG), made in parallel with this doc from the code at 645d4fe14a20 and its own probe runs (main with -ea and -da, and the fixed class). The alt text was written from the current PNG; check it again if the diagram changes.
assets/LFV-431/bug.png(489 KB)