Sampling keeps one hit per bin. A bin that a segment boundary cuts in two is meant to continue in the next segment; when its chosen hit is that segment's first hit, the carry-over is not recorded and the bin loses its sample.
- Facet sampling.
RandomSamplingFacetsCollector(lucene/facet, opt-in) counts facets on a sample of the hits when a query has more thansampleSizehits.amortizeFacetCountsdivides the sampled counts by the sampling rate,sampleSize / totalHits, to estimate the full counts. - One hit per bin. It walks the hits in doc order across segments, cuts them into bins of
binSize= totalHits / sampleSize (rounded down) hits, and keeps the hit at a random offset in each bin. - Carry-over. Each segment is sampled on its own. When a segment ends inside a bin, two fields carry the rest of the bin into the next segment: how many of its hits are still to come (
leftoverBin) and the offset of the hit to sample there (leftoverIndex, or -1 if the bin was already sampled).
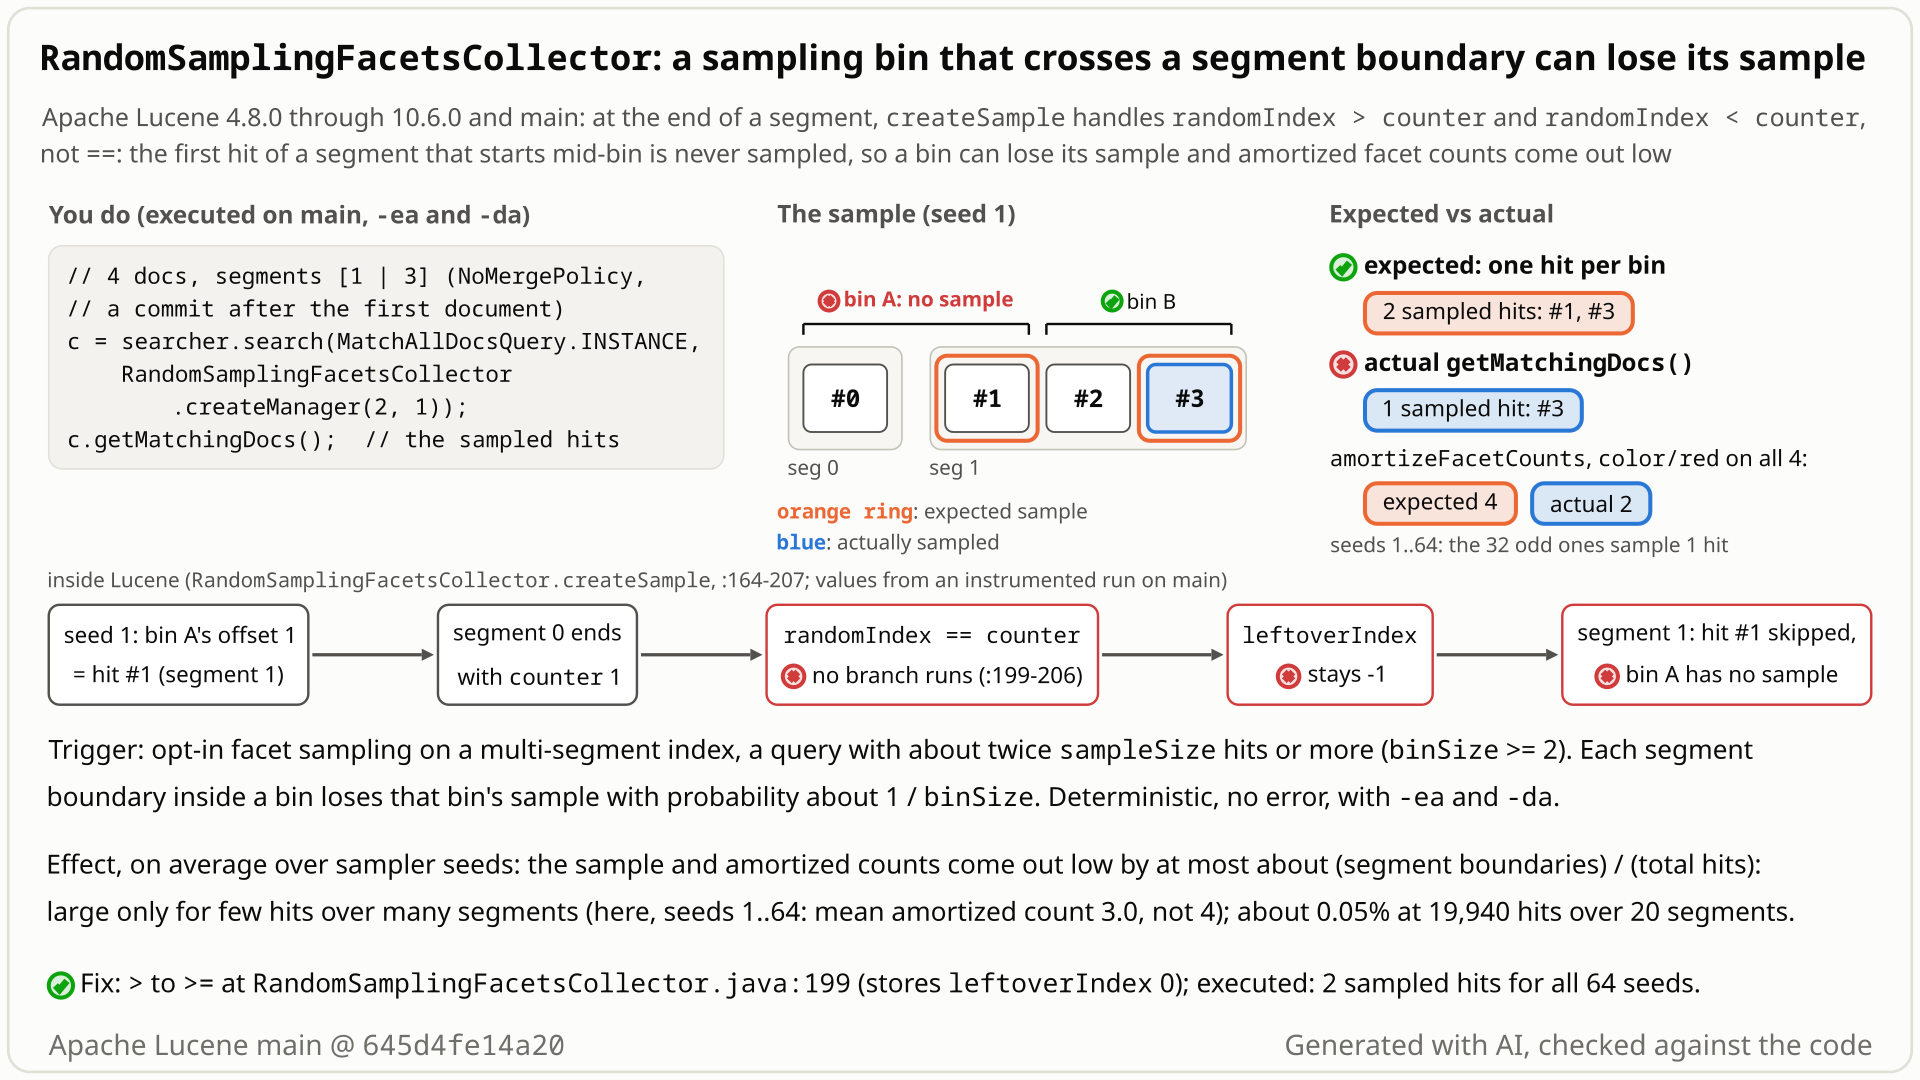
>= both bins are sampled. Select the still to open it at full size. Generated with AI, checked against the code.- Index 4 documents in two segments, 1 then 3 (
NoMergePolicy, a commit after the first). Run a match-all query throughRandomSamplingFacetsCollector.createManager(2, 1): sample size 2, sampler seed 1. - 4 hits and sample size 2 give a sampling rate of 0.5. The collector cuts the hits, in order across segments, into runs ("bins") of 2, {hit 0, hit 1} and {hit 2, hit 3}, and keeps one random hit from each. You expect 2 sampled hits.
- Seed 1 picks the second hit of the first bin, hit 1, which is the first hit of segment 2. You get 1 sampled hit: the first bin contributes nothing, and for a label on all 4 documents
amortizeFacetCountsreports 2 instead of 4. - Why: when a segment ends inside a bin, the code carries the choice over only if it lies beyond the hits seen (
randomIndex > counter), or marks the bin done if already sampled (<). The equal case, the next segment's first hit, matches neither branch, so that hit is never sampled. - Nothing fails. On average the sample shrinks by at most about (segment boundaries) / (hits): a quarter here, where half the seeds lose half the sample, and about 0.05% at 19,940 hits over 20 segments. Changing
>to>=fixes it.
Applications that opt in to facet sampling with RandomSamplingFacetsCollector, on multi-segment indexes, for queries with at least twice sampleSize hits. Each segment boundary inside a bin loses that bin's sample with probability about 1/binSize, so counts are on average low by at most about (boundaries) / (hits): large for few hits over many segments, about 0.05% at 19,940 hits.
Mechanism, terms and numbers781 words
RandomSamplingFacetsCollector (lucene/facet, opt-in) estimates facet counts from a sample: when a query has more than sampleSize hits, it cuts the hits, in doc order across segments, into bins of binSize = (int) (1.0 / samplingRate) hits and keeps the hit at a random offset in each bin; amortizeFacetCounts divides the sampled counts by samplingRate = sampleSize / totalHits. A bin that a segment boundary cuts in two is carried into the next segment through leftoverBin and leftoverIndex. At the end of a segment createSample handles only randomIndex > counter and randomIndex < counter; when the chosen hit is the first hit of the next segment (randomIndex == counter) neither branch runs, so the carried bin gets no sample, or one at a stale offset. The first hit of a segment that starts mid-bin is therefore never sampled, the sample is smaller than getSamplingRate() says, and amortized counts come out low, silently, in every release since 4.8.0. On average the sample shrinks by at most about (segment boundaries) / (hits): for 4 hits in segments [1 | 3] half the seeds sample 1 hit instead of 2, at 19,940 hits over 20 segments the loss is about 0.05%. The fix is > to >=.
- Sampling starts in
getMatchingDocs()whentotalHits > sampleSize(RandomSamplingFacetsCollector.java:132-134):samplingRate = (1.0 * sampleSize) / totalHits(:137);createSamplethen runs once per segment, in order (:149-155), withbinSize = (int) (1.0 / samplingRate)(:164). - A segment's first bin (
:169-177): if a bin was carried over,limit = leftoverBinandrandomIndex = leftoverIndex("either NOT_CALCULATED, which means we already sampled from that bin, or the next document to sample"); otherwiselimit = binSizeandrandomIndex = random.nextInt(binSize). - The loop (
:179-189): the hit atcounter == randomIndexis sampled (:180-181, the onlysampleDocs.set); whencounterreacheslimita new bin starts with a freshrandomIndex. - End of segment (
:191-207):counter == 0clears the carry-over (:196): the segment ended on a bin edge, or had no hits. A segment with no hits still gets its ownMatchingDocs, so it ends an outstanding carry-over (the loss the comment at:191-195accepts) and the next segment starts a fresh bin, not mid-bin. OtherwiseleftoverBin = limit - counter(:198), thenif (randomIndex > counter)(:199, "the document to sample is in the next bin") setsleftoverIndex = randomIndex - counter(:201), andelse if (randomIndex < counter)(:202) setsNOT_CALCULATED(:205). WithrandomIndex == counterthe hit to sample is offset 0 of the next segment, but neither branch runs. - What is left in
leftoverIndex. Usually -1 (its initial value,:83, or cleared at:196/:205): the carried bin starts withrandomIndex = -1and gets no sample. If an earlier carry left an offset k >= 1 that nothing cleared, the carried bin samples offset k instead of 0, or nothing when k is past the bin's end (follows from the code; not isolated in a test). A bin is never sampled twice. - Consequence.
leftoverIndexis only ever -1 or >= 1 (:83,:196,:201,:205), and a segment that starts mid-bin starts its loop withcounter = 0, so its first hit is never sampled.
In the repro, XORShift64Random(1).randomLong() is 0x2200011 (odd), so the first nextInt(2) is 1 (:55-71). Segment 1 (1 hit): limit 2, randomIndex 1; counter ends at 1, equal to randomIndex, so leftoverBin = 1 and leftoverIndex stays -1. Segment 2 (3 hits): the carried bin has limit 1 and randomIndex -1, so hit 1 is skipped; hits 2 and 3 form a fresh bin and one of them is sampled. Total 1; with >= it is 2.
A boundary inside a bin hits the equal case with probability about 1/binSize, so a query with B such boundaries loses up to about B/binSize of its about totalHits/binSize sampled hits: at most about B/totalHits. Executed: a bounded-exhaustive check on the stock jar (3-12 hits, sampleSize 2-3, every split into 1-3 segments, 50 seeds) left 8,429 of 76,250 complete bins without a sample and none with two, 0 with the fix. At 20 segments of 997 hits (sampleSize 200, binSize 99, 3,000 seeds) the first hit of a segment that starts mid-bin was sampled 0 of 57,000 times, 577 with the fix (about 576 expected); the mean sample was 201.285 against 201.393.
Exposure and likelihood232 words
- Who. Only applications that opt in to facet sampling with
RandomSamplingFacetsCollector(its constructors, orcreateManager(sampleSize, seed)withIndexSearcher.search). A read-only code search (2026-10-26) found no use of the class in Elasticsearch, OpenSearch or Solr. - When. A multi-segment index and a query with
totalHits >= 2 * sampleSize, so thatbinSize >= 2; withbinSize1 every hit is sampled and no bin crosses a boundary. Each segment boundary that falls inside a bin then triggers it with probability about 1/binSize, as long as the next segment has hits (a segment with no hits drops the carried bin anyway). Deterministic for a given seed and segment layout, with assertions on and off. - What the user sees. Silently smaller samples than
getSamplingRate()implies and amortized counts biased low. The first hit of every segment that starts mid-bin has sampling probability exactly 0: a systematic bias, not sampling noise. - How much. Large only for few hits over many segments: in the repro half the seeds sample 1 hit instead of 2 and the mean amortized count is 3.0 instead of 4; in small filtered multi-segment probe indexes 66 of 2,400 searches got an empty sample and so no facet result, 0 with the fix. Negligible at the scale the feature targets (CHANGES.txt: "in cases where there are millions of hits"): about 0.05% of the sample at 19,940 hits over 20 segments.
One JUnit test on the public API: 4 empty documents in segments [1 | 3], a match-all query, createManager(2, 1). It counts the sampled hits and expects 2, one per bin. Deterministic: the sampler seed is fixed in the test, and the test seed does not change the outcome.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.facet;

import org.apache.lucene.document.Document;
import org.apache.lucene.facet.FacetsCollector.MatchingDocs;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.NoMergePolicy;
import org.apache.lucene.search.DocIdSetIterator;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestRandomSamplingSegmentBoundary extends LuceneTestCase {

  public void testBinCrossingSegmentBoundaryIsSampled() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w =
          new IndexWriter(dir, new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE))) {
        w.addDocument(new Document());
        w.commit();
        for (int i = 0; i < 3; i++) {
          w.addDocument(new Document());
        }
      }
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        RandomSamplingFacetsCollector c =
            new IndexSearcher(r)
                .search(
                    MatchAllDocsQuery.INSTANCE, RandomSamplingFacetsCollector.createManager(2, 1));
        int sampled = 0;
        for (MatchingDocs md : c.getMatchingDocs()) {
          DocIdSetIterator it = md.bits().iterator();
          while (it.nextDoc() != DocIdSetIterator.NO_MORE_DOCS) {
            sampled++;
          }
        }
        // bins {0,1} {2,3}; seed 1 picks hit 1, the first of segment 2: expected 2, actual 1
        assertEquals("sampled hits", 2, sampled);
      }
    }
  }
}
cd $LUCENE && ./gradlew :lucene:facet:test --tests TestRandomSamplingSegmentBoundary -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
- 2 sampled hits, one from each bin, {hit 0, hit 1} and {hit 2, hit 3}.
- Observed
- 1 sampled hit:
AssertionError: sampled hits expected:<2> but was:<1>, with assertions on and off.
More files, environment, full output314 words
ByteBuffersDirectory, NoMergePolicy and one commit give exactly the segments [1 | 3]; a plain IndexSearcher without an executor runs one slice on the calling thread. Segments [1 | 3] put a boundary inside bin {0,1}; sampleSize 2 on 4 hits gives binSize 2 exactly, so the binSize truncation of LFV-437 plays no part; sampler seed 1 makes the first draw 1, the equal case (any small odd seed does the same). Bin {2,3} lies wholly in segment 2 and is always sampled, so one total count is enough. The test sits in package org.apache.lucene.facet only to live next to TestRandomSamplingFacetsCollector; it uses nothing package-private.
It compiles against 10.4.0 and later: MatchAllDocsQuery.INSTANCE first appears in 10.4.0 (#15499), and the unchanged test does not compile against the 10.3.2 jars. It fails on main and on the 10.6.0 and 10.5.2 jars. For 10.0-10.3 use new MatchAllDocsQuery(): that one-token variant fails the same way on 10.0.0. It does not compile against 9.x (MatchingDocs fields, not record accessors), where the hunt's per-era variants show the same failure.
Regression test: this same test; it passes with the recommended fix and fits as one more method of TestRandomSamplingFacetsCollector.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; with the fix: passes. Releases 10.6.0 and 10.5.2: fail |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the code path is integer logic in one method) |
cp $REPRO/TestRandomSamplingSegmentBoundary.java $LUCENE/lucene/facet/src/test/org/apache/lucene/facet/
cd $LUCENE && ./gradlew :lucene:facet:test --tests TestRandomSamplingSegmentBoundary -Ptests.seed=DEADBEEF -Ptests.asserts=true
# the same with -Ptests.asserts=false (without the flag, seed DEADBEEF also runs with assertions off)
# gradle, stock 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=false (stack trimmed; the same with assertions on)
TestRandomSamplingSegmentBoundary > testBinCrossingSegmentBoundaryIsSampled FAILED
    java.lang.AssertionError: sampled hits expected:<2> but was:<1>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:C327B571467E623A]:0)
        at junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:647)
        at org.apache.lucene.facet.TestRandomSamplingSegmentBoundary.testBinCrossingSegmentBoundaryIsSampled(TestRandomSamplingSegmentBoundary.java:57)

# with '>' changed to '>=' at RandomSamplingFacetsCollector.java:199
# result: BUILD SUCCESSFUL, 1 test, 0 failures, with assertions on and off- The carry-over exists for this case: its comment reads "the document to sample is in the next bin".
- The javadoc promises "a sample ratio of sampling size / totalN", which
amortizeFacetCountsdivides by; the real ratio is lower. - The only loss the code accepts is after a segment with no hits; here the segment has hits.
The full argument236 words
- The comments. The branch that misses the case reads "the document to sample is in the next bin" (
RandomSamplingFacetsCollector.java:200); the read-back saysleftoverIndexis "either NOT_CALCULATED, which means we already sampled from that bin, or the next document to sample" (:171-172). In the equal case neither holds: the bin was not sampled. - The contract. The
sampleSizejavadoc: "sampling will be done using a sample ratio of sampling size / totalN" (:97-99);getSamplingRate()"Returns the sampling rate that was used" (:256-259), andamortizeFacetCountsdivides by it (:240,:249). - Design history (#6539, LUCENE-5476). An early patch's notes (Rob Audenaerde) listed that in a small segment "there might be a few hits that are never touched", and Michael McCandless replied "I think these limitations are acceptable?". Shai Erera then noted that
createSample"doesn't carry over the bin residue to the next segment ... it might affect the total sample size", and their last patch revision before the commit "Fixed a bug in how carryOver was implemented – replaced by two membersleftoverBinandleftoverIndex", asking for "another look, to make sure this time leftover works well". The equal case was never discussed. - Tests. The only upstream test,
TestRandomSamplingFacetsCollector, checks a chi-square bound on per-segment sample proportions and amortized counts within 1.0 of the expected value. Both tolerate this loss; it passes with and without the fix.
The devil's-advocate check208 words
The strongest case for "intended" (rated moderate by the cross-model reviews): sampleSize is only "The preferred sample size" (:97); getMatchingDocs warns that per-segment MatchingDocs "might be empty (not containing any hits) as result of sampling" (:115-116); the comment at :191-195 accepts dropping the carry-over after a segment with no hits ("complicates the code and doesn't seem so important"); and the 2014 thread called small-segment losses acceptable.
Why it fails: that accepted loss is scoped to the counter == 0 branch, whose comment covers a segment that ends exactly on a bin edge (nothing is lost) and a segment with no hits (the only case that drops an outstanding carry-over); here the segment has hits and the else branch computes the carry-over with the wrong comparison. The "acceptable" remark concerned an early patch with no carry-over, which was then added to fix it. The bug is not limited to tiny segments: any boundary inside a bin hits it with probability 1/binSize. Giving a reachable hit sampling probability 0, or reusing a stale offset from an earlier bin, is not a trade-off, and the fix costs nothing. Verdict: not intended, a defect (the independent reproduction, the cross-model review, the intended-behaviour check and the adjudication).
Recommended Change > to >= at RandomSamplingFacetsCollector.java:199 (validated)
Change if (randomIndex > counter) to >= at RandomSamplingFacetsCollector.java:199, so the equal case carries offset 0 into the next segment. The repro then passes with assertions on and off, and so do TestRandomSamplingFacetsCollector (10 runs) and the whole facet module (307 tests).
       } else {
         leftoverBin = limit - counter;
-        if (randomIndex > counter) {
+        if (randomIndex >= counter) {
           // the document to sample is in the next bin
           leftoverIndex = randomIndex - counter;
         } else if (randomIndex < counter) {
All options and trade-offs3 options · 535 words
Option A was built and run through gradle. B is the same behaviour written as one assignment, so that no stale value can survive; C (document the loss) is not recommended. Workarounds that need no fix: exact counting with a plain FacetsCollector when the hit count is small relative to the number of segments, or a single-segment index.
In the equal case leftoverIndex becomes 0, so the next segment samples its first hit. The comment "the document to sample is in the next bin" then covers the equal case too ("next segment" would be clearer). One file, +1/-1.
       } else {
         leftoverBin = limit - counter;
-        if (randomIndex > counter) {
+        if (randomIndex >= counter) {
           // the document to sample is in the next bin
           leftoverIndex = randomIndex - counter;
         } else if (randomIndex < counter) {
Trade-offs
- Cost. None: one comparison per segment.
- Behaviour change. For a fixed seed, which hits are sampled changes whenever the equal case occurs: the bin that lost its sample gets one again, so the sample and amortized counts rise. Tests or applications that pin a seed and expect exact sampled counts would see different numbers. Worth a CHANGES.txt entry under Bug Fixes.
- Scope. A closes only the equal case. The
binSizetruncation (LFV-437, so the sample can still exceedsampleSize: mean 201.393 forsampleSize200 in the scale check with the fix), the documented drop of a carried bin after a segment with no hits (:191-196) and the multi-slice reduce (LFV-765) are unchanged. - Neighbours. Open PR #16847 edits
createSample(maxDoc()tomaxLeafDoc()), so a fix may need a rebase; LFV-437, LFV-425 and LFV-765 in the same collector have their own fix sites.
What the checks validated
Applied to a scratch worktree of 645d4fe14a20 and run through gradle with OpenJDK 25.0.3, seed DEADBEEF (2026-10-31):
- stock: the minimal test fails with assertions on and off;
- with the fix: the minimal test passes with assertions on and off;
- the closest suite
TestRandomSamplingFacetsCollectorpasses with-Ptests.iters=10(10 runs, 0 failures); - the whole
:lucene:facet:test, the new test included, passes (40 classes, 307 tests, 0 failures, 7 skipped); checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMainandforbiddenApisTestfor facet pass.- Earlier, the same change made the finder's test, the independent reproduction's 5 tests (0 of 58,240 bins empty), the bounded-exhaustive model (0 of 76,250), the upstream sampling test (5 iterations), the 4.8.0 history run and the security probe (first hits of mid-bin segments sampled 1,665 of 5,200 times instead of 0) come out right.
leftoverIndex = randomIndex >= counter ? randomIndex - counter : NOT_CALCULATED; after leftoverBin = limit - counter;.
Trade-offs
Same behaviour as A by reading (A's else if (randomIndex < counter) is always true when reached), and it shows that leftoverIndex is always assigned. A slightly larger diff.
Say in the javadoc that a bin crossing a segment boundary may lose its sample.
Trade-offs
Keeps a reachable hit at sampling probability 0 and a sampling rate that overstates the real one, for no saving: the fix is one character.
An application that shows sampled facet counts gets slightly low numbers (no facet result for some very small hit sets); every sampled hit is still one of the query's own live, filtered hits.
A hunt unit read createSample while inventorying the facet module's counts: the > / < pair leaves the equal case unhandled. A bounded-exhaustive check on the stock jar (3-12 hits, every split into 1-3 segments, 50 seeds) found 8,429 of 76,250 complete bins without a sample, 0 with the fix; a public-API JUnit confirmed it.
The method in full127 words
Method: non-formal (the hunt's tier for findings from code reading and directed testing).
- Code reading. While building the count and statistic inventory of lucene/facet, the finder noticed that the end-of-segment block of
createSampletests onlyrandomIndex > counterandrandomIndex < counter. - Bounded-exhaustive check. A driver over the stock jar checked the invariant the code comments state, one sampled hit per complete bin in doc order across segments, for
sampleSize2-3, 3-12 hits, every split into 1-3 segments and 50 sampler seeds: 8,429 of 76,250 complete bins empty, none doubly sampled; 0 empty with the one-character fix. - JUnit. A public-API test (4 documents in [1 | 3], sampler seeds 1..20) failed on main, 10.5.2 and 9.12.3; a 2026-10-29 minimization cut it to the one-seed test above.
No prior report found: 117 logged searches and checks on 2026-10-26 (GitHub issues, PRs and commits, the JIRA archive, the mailing lists, downstream projects, the web) and a GitHub re-check on 2026-10-31. Closest: the 2014 design thread #6539, which added the carry-over and never discusses this case.
Searches3 searches
- #6539 (LUCENE-5476, the design thread that added the carry-over; the equal case is never mentioned); a 2014 dev@ CI-failure thread on
testRandomSampling, diagnosed by the committer as a test of the wrong statistic ("it was just wrong and tested the wrong thing") and fixed in the test (5b00b2e9814); open PR #16847 (long doc ids), the only open PR touching the file, which changescreateSample'smaxDoc()and the amortize arithmetic but not the comparison; #11520 / #765 (LUCENE-10484,createManager), #13542 (intra-segment concurrency). - Same collector, the hunt's own findings (different root causes and fix sites): LFV-437 (
binSizetruncation inflates amortized counts; registered as known through the #6539 review), LFV-425 (docFreq cap inamortizeFacetCounts), LFV-765 (the multi-slice reduce samples twice). - Limits: keyword search only; one web query was rate-limited; two manual GitHub phrasings hit the search quota (the tool runs and the intended-behaviour check cover the same terms); GitHub Discussions were not searched; private lists and reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive; Elasticsearch, OpenSearch, Solr, Lucene.NET) | 2026-10-26 | the scripted prior-report search in two runs (32 issue and PR queries, 6 commit queries, 4 downstream queries) and manual full-text and comment searches (RandomSamplingFacetsCollector, randomIndex counter sampling, sampling carryOver facet, systematic sampling), plus the changed-file lists of all 411 open apache/lucene PRs | 12 hits read, none the same bug; only #16847 among open PRs touches the file |
| Mailing lists (dev@, java-user@, issues@, commits@, builds@), JIRA archive, git history, web | 2026-10-26 | 45 list queries with the user and CI-failure threads read in full, 8 JIRA-archive queries, git log -S on the comparison and on leftoverIndex, 9 web queries (1 rate-limited) | no report; the comparison has never changed since the class was added |
| GitHub issues and PRs (apache/lucene) | 2026-10-31 | items updated since 2026-10-20 for RandomSamplingFacetsCollector, leftoverIndex, facet sampling, amortizeFacetCounts; all-time search for RandomSamplingFacetsCollector | 0 recent results; the 6 all-time items (#6539, #765, #11520, #240, #11041, #9415) are not this bug |
Present since the class was added: LUCENE-5476 (e50b392f467, 2014-03-20), first released in 4.8.0; the comparison has never changed. Fails on 12 releases from 4.8.0 to 10.5.2, on 10.6.0 and on main; unchanged on upstream main, branch_11x and branch_10_6.
Versions tested6 rows
Introduced by e50b392f467cf1e3dea3999b5449c48742cf2084, "LUCENE-5476: add RandomSamplingFacetsCollector" (Shai Erera, 2014-03-20; a JIRA patch from the svn era, no PR; issue mirrored as #6539); the 4.x copy is the same-day backport 4d26f04cedc. git blame of lines 199-202 at 645d4fe14a20 gives e50b392f467 for every line, and git log -S / -G on the comparison find no later change. Not a regression: the defect is in the first committed version of the carry-over. 4.7.2 does not have the class.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails with assertions on and off (gradle and standalone runner); passes with the fix |
| 10.6.0, 10.5.2 | affected | minimal test fails (release jars, assertions off) |
4.8.0, 4.9.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2, main ea57360912ed | affected | history driver: 10 of 40 complete bins empty, 30 sampled hits instead of 40, identical on every version |
4.8.0 and main ea57360912ed with the fix | fix | history driver: 0 of 40 bins empty |
| 4.7.2 | no such class | the repro does not compile: RandomSamplingFacetsCollector does not exist |
upstream main 2f424fd428d, branch_11x 603af870375, branch_10_6 7e5aec4370e | same code | the same > / < pair at lines 199 and 202 (read, not run) |
Confirmed by an independent reproducer, a devil's-advocate verifier, a reviewer from another model family (OpenAI GPT-5.6) and an adjudication, then re-run by a credibility audit, the minimization and this doc's gradle run. The only dissent was a procedural "not real" from a read-only review that could not run code.
Checks and verdicts366 words
Every check that ran code reproduced the failure on main and saw it pass with the one-character fix. The cross-model reviews could only read code; a separate run ran the repro for them.
| Check | Verdict | What it found |
|---|---|---|
| Finder (code reading, bounded-exhaustive check, JUnit) | candidate | 8,429 of 76,250 complete bins empty on the stock jar, 0 with the fix; the JUnit fails on main (-ea, -da), 10.5.2 and 9.12.3; the upstream sampling test passes with the fix. |
| Refute review (OpenAI GPT-5.6, read-only) | not real (procedural, low) | Could not run code; agrees on the root cause and that the inputs are in contract; rates the intended-behaviour argument moderate. A separate run re-ran the repro: fails 1/1. |
| Independent reproducer | real | Own 5-test class: 4 of 5 fail on main, 10.5.2 and 9.12.3; [1 | 3] and [3 | 1] leave a bin empty for 32 of 64 seeds; amortized mean 3.0 instead of 4; controls pass; its fix passes 5/5. |
| Intended-behaviour lens (OpenAI GPT-5.6, read-only) | real (medium) | The intended argument is moderate and fails: the accepted loss covers only a segment with no hits. Re-runs fail on main and pass with the fix. |
| Intended-behaviour devil's advocate | real, minor | No intended, documented, misuse or unreachability argument survives; scale check 0 of 57,000 against 577 of 57,000 segment-first-hit inclusions. |
| Adjudication | confirmed (high), class minor | Re-ran the independent reproduction's tests (4 of 5 fail with -ea and -da, 0 with the fix) and the finder's repro (fails 1/1). |
| Follow-up history and security probe | affected since 4.8.0; not security-sensitive | 12 releases and main fail with identical counts; 2,400 filtered searches per run: every sampled hit an original, live, filtered hit. |
| Credibility audit (4th check) | keep, minor | Re-ran the finder's test and the independent reproduction's tests on main; the fix passes. |
| Minimal repro and this doc | verified | The one-method test fails on 645d4fe14a20 (2 seeds, assertions on and off) and passes with the fix; this doc re-ran it through gradle in a scratch worktree (the fix also passes the closest suite, the facet module and lint) and on the 10.6.0 and 10.5.2 jars (fail). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 466 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,537 words
- Registry title
- RandomSamplingFacetsCollector never samples the first hit of a segment that starts mid-bin: createSample does not handle randomIndex == counter at the end of a segment, so a sampling bin that crosses a segment boundary loses its sample (or samples at a stale offset)
- Area
- facet / sampling (RandomSamplingFacetsCollector.createSample, cross-segment bin carry-over)
- Priority
- Low, rank 741: With opt-in facet sampling, a bin that crosses a segment boundary loses its sample, a bounded bias that is negligible at the scale the feature targets.
- Impact class
- minor
- Impact note
- Only applications that opt in to facet sampling with RandomSamplingFacetsCollector are hit, on any multi-segment index once a query has about twice sampleSize hits or more (binSize >= 2): each segment boundary that falls inside a bin loses that bin's sample with probability about 1/binSize, so the sample is smaller than getSamplingRate() implies and amortized counts come out low by at most about (#segment boundaries)/totalHits; that is large only for few hits over many segments (4 hits in segments [1 | 3], sampleSize 2: half the seeds sample 1 hit instead of 2, mean amortized count 3.0 instead of 4; in small filtered probe indexes 66 of 2,400 searches got an empty sample and no facet result, 0 with the fix) and negligible at the scale the feature targets (about 0.05% of the sample at 19,940 hits over 20 segments); deterministic, -ea and -da, every release since 4.8.0.
- Summary
- You count facets with RandomSamplingFacetsCollector on a multi-segment index for a query with many more hits than sampleSize, and expect systematic sampling: one random hit out of every run of binSize consecutive hits, with a run that is cut by a segment boundary continued in the next segment, so every hit has about a 1/binSize chance to be sampled. Instead, when the hit picked for such a run is the first hit of the next segment, createSample leaves its carry-over state unset (it tests only randomIndex > counter and randomIndex < counter), so that run contributes no sample, or one at a stale offset, and the first hit of a segment that starts mid-bin is never sampled. Nothing fails; the sample and the amortized counts are just smaller than the reported sampling rate implies (4 hits in segments [1 | 3], sampleSize 2: half the seeds sample 1 hit instead of 2).
- Introduced
- e50b392f467cf1e3dea3999b5449c48742cf2084, 'LUCENE-5476: add RandomSamplingFacetsCollector' (trunk, svn r1579594; no PR, a JIRA patch; issue mirrored as apache/lucene#6539; committer shaie), shipped in 4.x through the same-day branch_4x backport 4d26f04cedcdc487b8c8541bc23ff24df6b71f6a (svn r1579598) [read: git blame of RandomSamplingFacetsCollector.java:191-207 on main, and git log -S'randomIndex > counter' / -G'randomIndex [<>]=? ?counter' find no later change of the comparison; exec: 4.7.2 lacks the class (compile error), 4.8.0 fails]. Not a regression: the defect is in the first committed version of the carry-over (2014-03-20)
- First affected version
- 4.8.0 [exec: fails with -ea and -da, 10 of 40 complete bins empty; 4.8.0 with the one-character fix passes]; 4.7.2 does not have RandomSamplingFacetsCollector [exec: compile error; the pre-4.7 org.apache.lucene.facet.sampling package was different code, removed before 4.7.0]
- Affected versions
- 4.8.0 through 10.5.2 (the last release before 10.6.0) and main ea57360912ed; not fixed upstream (upstream main and branch_10x still read 'randomIndex > counter' at line 199; the last commit to the file is fafd6af004e, 2024-09-10, already in the tested tree; read 2026-10-26). [exec] The history driver (4 documents, segments [1 | 3], sampleSize 2, sampler seeds 1..20, one small API adapter per era) fails with identical counts (10 of 40 complete bins empty, 0 doubly sampled, 30 of 40 intended sampled hits) on 4.8.0, 4.9.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-da also on 4.8.0, 9.12.3 and main), with both IndexSearcher.search(Query, Collector) (4.x-9.x) and createManager (10.x); the finder's JUnit fails on main (-ea, -da), 10.5.2 and 9.12.3; the independent reproduction's JUnit fails 4 of 5 on main (-ea, -da), 10.5.2 and 9.12.3. [read] The unchanged '>' / '<' block is in all 107 release tags from 4.8.0 to 10.5.2 in the history clone (8.9.0-8.11.x are not tagged there; 8.11.4 was executed). Not affected: 4.7.2 and older (no such class). Old releases ran on JDK 25 with their published jars
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-26, all read-only; the prior-report record verdict new: 117 logged queries and checks, namely 95 from the scripted prior-report search in two runs (32 GitHub issue/PR queries on apache/lucene, 6 commit queries, 4 downstream queries over Elasticsearch, OpenSearch and Solr, 45 queries over the dev@, java-user@, issues@, commits@ and builds@ lists, 8 JIRA-archive queries), 13 manual checks (GitHub full-text and comment searches, a changed-file scan of all 411 open apache/lucene PRs, Lucene.NET and downstream repositories, mailing-list archive listings with the user and CI-failure threads read in full, git history, upstream main) and 9 web queries (1 rate-limited); 12 hits read and judged, none the same bug; the finder's and the intended-behaviour check's own searches found the same items). History, not reports: LUCENE-5476 / #6539 (2014) is the design thread that added the carry-over: an early patch accepted that small segments may leave hits unsampled, then the committer (shaie) added leftoverBin/leftoverIndex in the final revision ('Fixed a bug in how carryOver was implemented') and invited another look 'to make sure this time leftover works well'; the randomIndex == counter case is never mentioned. A 2014 dev@ CI-failure thread on TestRandomSamplingFacetsCollector was diagnosed by the committer as a too-strict test bound and fixed in the test (5b00b2e9814); nobody suspected the sampler. Open #16847 (jimczi, 'Support more than 2^31 documents per index') is the only open PR touching the file: it changes createSample's maxDoc() to maxLeafDoc() and widens the amortize arithmetic, but not the carry-over comparison (its per-file patch read 2026-10-26), so it neither reports nor fixes this bug. Context only: #11520 / #765 (LUCENE-10484, createManager), #13542 (intra-segment concurrency), #4575 (the old, deleted sampling package), #11041, #240, #9415
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off, through gradle in a scratch worktree and a standalone runner; with the one-character fix it passes, together withTestRandomSamplingFacetsCollectorand the whole facet module. Release jars: the test fails on 10.6.0 and 10.5.2. The hunt ran on mainea57360912ed, whose facet module is identical, and its history driver fails with identical counts on 12 releases from 4.8.0 to 10.5.2. Upstream main2f424fd428d,branch_11x603af870375,branch_10_67e5aec4370eand the 10.6.0 tag carry the same comparison (read, 2026-10-30 refs).
- Finding record
a Lucene main checkout lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:74 (NOT_CALCULATED = -1), :82-83 (leftoverBin, leftoverIndex fields), :97-100 (sampleSize javadoc: 'preferred sample size', 'a sample ratio of sampling size / totalN'), :115-116 (per-segment MatchingDocs 'might be empty ... as result of sampling'), :132-138 (samplingRate = sampleSize / totalHits when totalHits > sampleSize), :164 (binSize = (int) (1.0 / samplingRate)), :169-177 (carried bin: limit = leftoverBin, randomIndex = leftoverIndex), :178-189 (sampling loop; the only sampleDocs.set at :181), :191-195 (counter == 0 branch and its comment accepting the loss after a segment with no hits), :196-206 (carry-over: 'if (randomIndex > counter)' at :199, 'else if (randomIndex < counter)' at :202; no equal case), :220-254 (amortizeFacetCounts divides by samplingRate)a Lucene main checkout lucene/facet/src/test/org/apache/lucene/facet/TestRandomSamplingFacetsCollector.java (the only upstream test: a per-segment chi-square bound, which tolerates this loss); a Lucene main checkout lucene/CHANGES.txt:12417 (LUCENE-5476 under 4.8.0)upstream apache/lucene#6539 (LUCENE-5476 design thread; comments by shaie on the carry-over, read with gh 2026-10-26) and apache/lucene#16847 (open, jimczi; per-file patch of RandomSamplingFacetsCollector.java read with gh api 2026-10-26: maxDoc() to maxLeafDoc() and long arithmetic in amortizeFacetCounts only)
- The finding in 30 seconds
lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:55-71, (at 645d4fe14a20) :74, :82-83, :132-139, :149-155, :164, :169-177, :179-189, :191-207lucene/facet/src/java/org/apache/lucene/facet/FacetsCollector.java:117-125 (at 645d4fe14a20) and lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:813-815, :862 (one MatchingDocs per visited segment, also for a segment with no hits)
- Who is affected
lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:132-139, (at 645d4fe14a20) :164, :240, :249, :256-259lucene/CHANGES.txt:12450-12452 (at 645d4fe14a20) (LUCENE-5476, 4.8.0)
- Why it looks unintended
lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:97-100, (at 645d4fe14a20) :115-116, :171-172, :191-206, :240, :249, :256-259lucene/facet/src/test/org/apache/lucene/facet/TestRandomSamplingFacetsCollector.java:115-133 (at 645d4fe14a20) (chi-square), :135-149 (amortized counts)apache/lucene#6539 (LUCENE-5476; comments by Rob Audenaerde 13917870, Michael McCandless 13917922, Shai Erera and the final revision 13940616; read with gh 2026-10-31)
- Suggested fix
upstream apache/lucene#16847 (open; per-file patch of RandomSamplingFacetsCollector.java read 2026-10-26)
- History
a Lucene clone refs of 2026-10-30 (origin/main 2f424fd428d, origin/branch_11x 603af870375, origin/branch_10_6 7e5aec4370e, tag releases/lucene/10.6.0 4ae946e5a9b; git show of lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java)
- TestRandomSamplingSegmentBoundary.java (one test):
repro/LFV-432/src/org/apache/lucene/facet/TestRandomSamplingSegmentBoundary.java(61 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the minimal repro. The diagram numbers segments from 0, as Lucene numbers its leaves: "seg 0" and "seg 1" are segments 1 and 2 of the text.
assets/LFV-432/bug.png(466 KB)