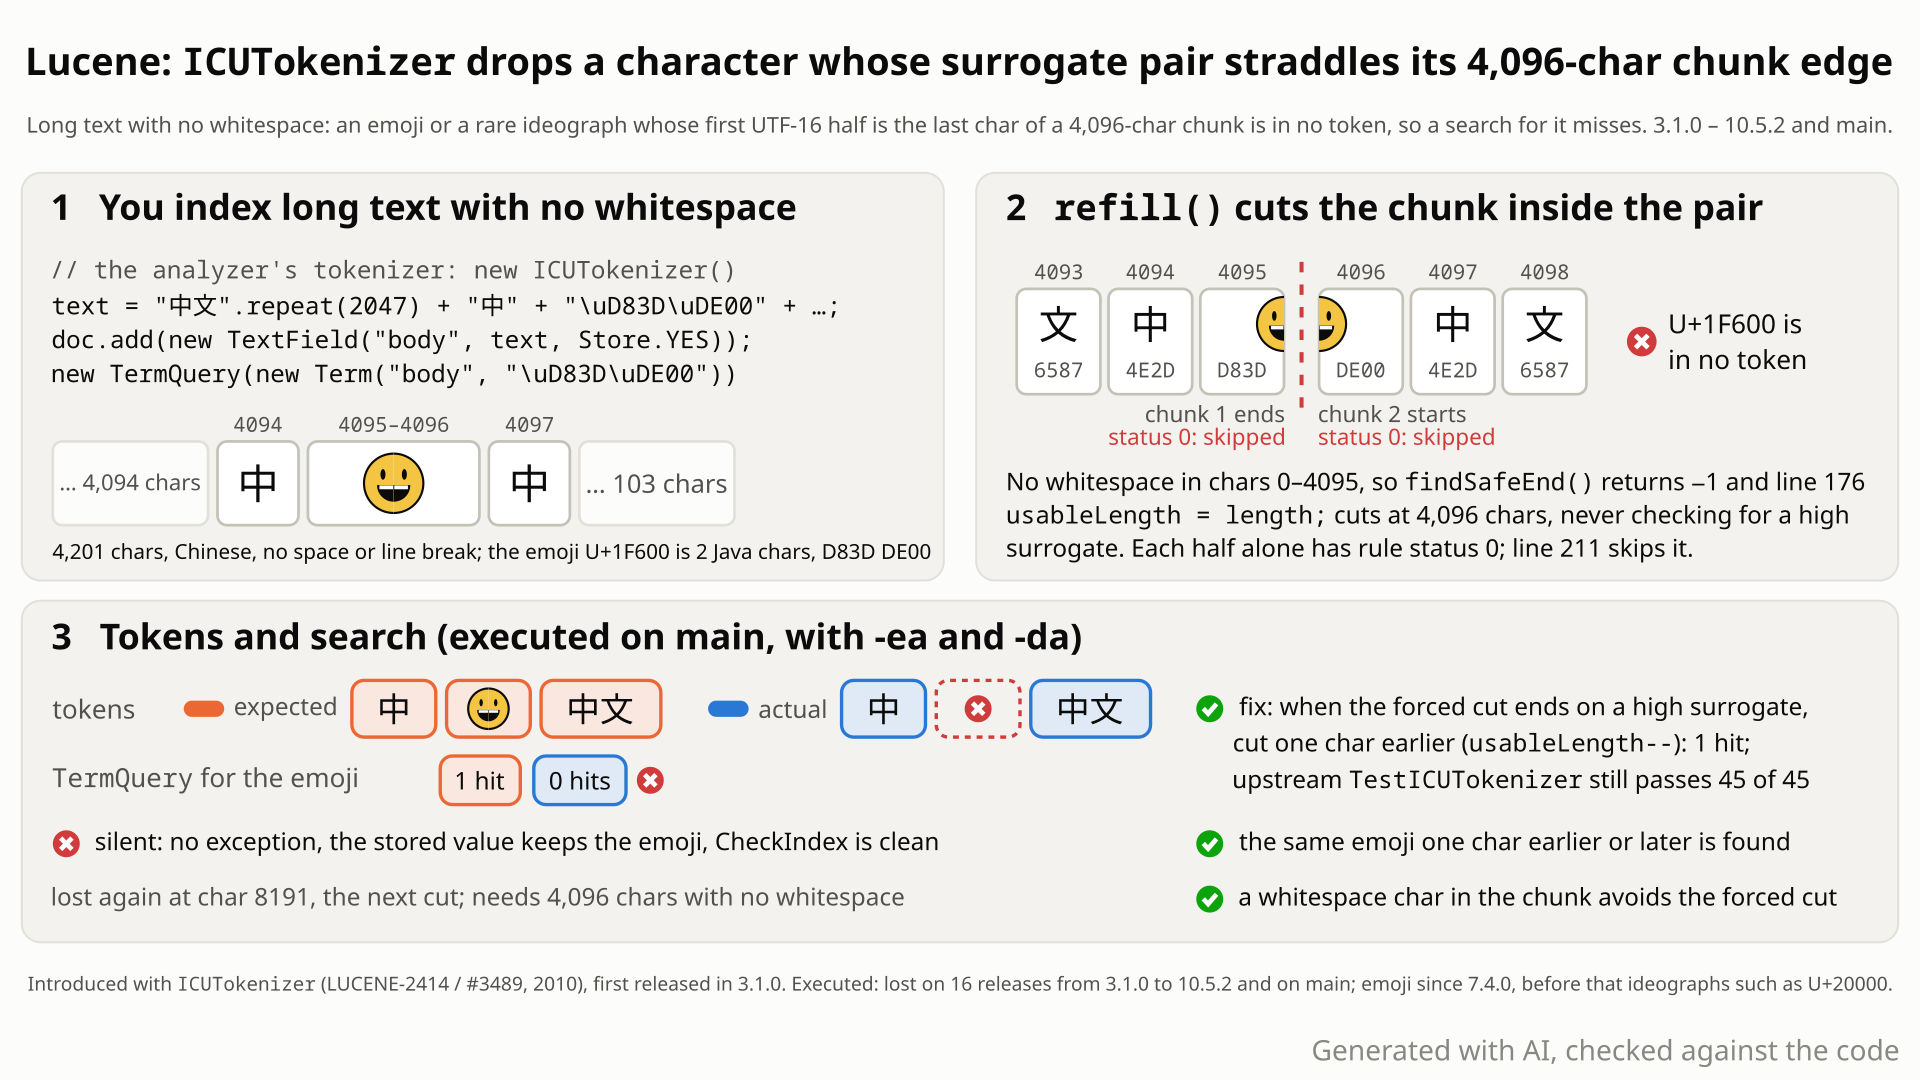
Java stores an emoji or a rare CJK character as two chars, a surrogate pair. ICUTokenizer reads 4,096 chars at a time, and when a chunk has no whitespace it ends the chunk exactly there, even between the two halves.
- Tokenize about 4,200 characters of Chinese with no spaces (
中文中文…) withnew ICUTokenizer(), with the ideograph U+20000 (𠀀, two Java chars) starting at char 4095. You expect the token𠀀[4095,4097), as at char 4094 ([4094,4096)) or 4096 ([4096,4098)). - You get no token for it:
中[4094,4095)is followed by中文[4097,4099). The emoji U+1F600 at char 4095 vanishes the same way, and so does U+20000 at char 8191 through theicufactory. - Index three documents with U+20000 at chars 4094, 4095 and 4096:
TermQuery(U+20000)finds 2 instead of 3. - Why: the tokenizer reads 4,096 chars at a time and ends each chunk after its last whitespace. With none, it ends at char 4096, between the two halves of U+20000; neither half alone is a word, so both are skipped.
- No error: the stored text keeps the character and CheckIndex is clean. Keeping a trailing first half for the next chunk (4 lines) fixes it, and the ICU module's 163 tests run with 0 failures.
Users of ICUTokenizer from the optional analysis-icu module, through its constructors or the icu factory with default settings, and downstream icu_tokenizer factories built on it. The text needs more than 4,096 chars without any whitespace, such as long CJK or Thai text with line breaks removed, and a supplementary character exactly at the cut: one character per such window.
Mechanism, terms and numbers854 words
ICUTokenizer reads its input in 4096-char chunks; while more input follows, it ends each chunk after the chunk's last whitespace character. When a full chunk has no whitespace at all, it uses the whole chunk without checking whether the last char is the first half (high surrogate) of a supplementary character. The ICU word breaker then sees a lone high surrogate at the end of one chunk and a lone low surrogate at the start of the next; neither is a word, both are skipped, and the character is in no token. In about 4,200 chars of Chinese without spaces, U+20000 (an Extension B ideograph) or U+1F600 (an emoji) at char 4095 is lost, while at char 4094 or 4096 it is a token, and a TermQuery for U+20000 over three such documents finds 2 instead of 3. It happens with new ICUTokenizer() and the icu factory with default parameters, on all 16 releases executed from 3.1.0 to 10.5.2 and on main (with and without assertions on main), and every release tag that contains the class has the same fallback. Nothing throws, no malformed term is indexed, CheckIndex is clean and the stored text keeps the character. A 4-line hold-back of the trailing high surrogate fixes it, and the ICU module's 163 tests run with 0 failures with it.
- Supplementary character, surrogate pair: a code point above U+FFFF, such as an emoji (U+1F600) or a CJK Extension B ideograph (U+20000). Java stores it as two
chars: a high surrogate (U+D800-U+DBFF) followed by a low surrogate (U+DC00-U+DFFF). Neither half is a character on its own. - Chunk:
ICUTokenizerkeeps a fixed 4096-char buffer (ICUTokenizer.java:41-42). It hands the ICU word breaker the part of the buffer up to the last whitespace and carries the rest over to the front of the next chunk. - Rule status 0: the ICU word breaker marks spans that are not words (spaces, punctuation, unmatched chars) with rule status 0; the tokenizer skips them.
findSafeEnd()(:143-150) returns the position after the lastUCharacter.isWhitespacechar of the buffer, or -1.refill()(:158-181) carries the unused tail over, reads up to the buffer size and, when the input is not exhausted, usesfindSafeEnd()(:170). If that is -1, the fallback isusableLength = length;(:176), under the comment "more than IOBUFFER of text without space, gonna possibly truncate tokens" (:172-175). It never checks whetherbuffer[length - 1]is a high surrogate.breaker.setText(buffer, 0, usableLength)(:180) gives the breaker a chunk that ends in a lone high surrogate; the nextrefill()starts with the lone low surrogate.incrementTokenBuffer()skips every span with rule status 0 (:211). Both lone halves get status 0 (printed for U+1F600 by the diagram probe), so the character is in no token, and the offsets jump from the high surrogate's position to after the low surrogate.
The cut falls at char 4096k-1 in text with no whitespace at all (4095, 8191, 16383, ...), otherwise 4096 chars after the last whitespace, because each chunk starts with the previous chunk's leftover. Lucene's own helper CharacterUtils.fill holds back a trailing high surrogate for exactly this reason (lucene/core/.../CharacterUtils.java:158-161, 203-204).
The numbers (main; text = 中文 repeated to at least 4,200 chars, probe at char pos; tokens as term[start,end))
| probe, pos, entry point | tokens near the probe | lost | with the fix |
|---|---|---|---|
U+20000 at 4094, new ICUTokenizer() | 𠀀[4094,4096) | nothing | same |
U+20000 at 4095, new ICUTokenizer() | 中文[4092,4094), 中[4094,4095), 中文[4097,4099) | U+20000 | 𠀀[4095,4097) |
U+20000 at 4096, new ICUTokenizer() | 𠀀[4096,4098) | nothing | same |
U+1F600 at 4095, new ICUTokenizer() | 中文[4092,4094), 中[4094,4095), 中文[4097,4099) | U+1F600 | 😀[4095,4097) |
U+20000 at 8191, icu factory, defaults | 中文[8188,8190), 中[8190,8191), 中文[8193,8195) | U+20000 | the token |
TermQuery(U+20000) over 3 documents (4094, 4095, 4096) | 2 hits | the 4095 document | 3 hits |
A bounded-exhaustive sweep (13 fillers x 13 probes x 7 buffer boundaries x 9 positions) flagged the icu tokenizer with default, cjkAsWords=false and myanmarAsWords=false settings at exactly chars 4095, 8191 and 16383, for every supplementary probe (emoji, Extension B ideograph, flag, ZWJ sequence; the oracle counts each probe's first code point) and every whitespace-free BMP filler (9 of the 13 fillers): 324 of 324 such cases, and these are all the violations the sweep recorded for the three icu configurations. Of the other fillers, 2 contain spaces, and the 2 made of surrogate pairs were never probed at the cut, because the sweep skips insertion points on a low surrogate. BMP base characters at 4095 (U+4E00, U+2764) are kept. An audit with two short lines and then one long Japanese line misses only the document with U+2000B exactly 4095 chars after the last line break.
Scope. The same forced cut also orphans a BMP combining mark that becomes the first char of the next chunk (e + U+0301, or Thai U+0E01 + U+0E34, at 4095-4096: the mark is in no token). That is a separate, grapheme-level effect; this bug is the cut inside a code point, which loses a whole character. The recommended fix does not change the combining-mark case.
Exposure and likelihood321 words
- Who is hit. Applications that analyze text with
ICUTokenizer:new ICUTokenizer(),new ICUTokenizer(config), or theicufactory (CustomAnalyzer, factory-based configs) with default,cjkAsWords=falseormyanmarAsWords=falsesettings (all executed). Theicu_tokenizerfactories of Elasticsearch and OpenSearch callnew ICUTokenizer()/new ICUTokenizer(config)directly, and Elasticsearch'sicu_analyzerchains it (read, not executed downstream). Lucene's default analysis (StandardAnalyzer) is not affected, and the class is@lucene.experimental. - What triggers it. A run of more than 4,096 chars without any whitespace, not even a line break, and a supplementary character whose high surrogate is exactly the last char of the chunk. Realistic mainly for long unbroken CJK or Thai text (for example extracted text whose newlines were stripped) that contains emoji, Extension B+ ideographs or supplementary-plane letters. The chance per cut is roughly the share of supplementary chars in that text (reasoning, not measured).
- What goes wrong. One character per affected 4096-char window is missing from that field's terms; if it occurs nowhere else in that field, a
TermQueryor aMUST_NOTexclusion on it misses the document (executed), and a phrase query containing it would miss too (reasoning, not run). Before 7.4.0 emoji were not tokens at all, so there the loss shows on ideographs such as U+20000; from 7.4.0 (LUCENE-8125) emoji are lost too. - Silent and deterministic. No exception or warning, no lone-surrogate or U+FFFD term,
CheckIndexclean, stored text intact, other documents and fields unaffected, the same with-eaand-da. The cut position depends only on the text. - Not more than that. No hang and no clear extra cost: 1,048,576-char inputs run at 0.97-1.20x a shifted control (single host, best of 3, noisy).
- Long-lived. Present since the class was added in 2010 (executed on 16 releases; the same fallback in every release tag). Fixing it changes the tokens of exactly the affected documents; existing indexes need a reindex to gain the lost characters.
The test shows that ICUTokenizer drops U+20000 when its high surrogate is the last char (char 4095) of a whitespace-free 4096-char read chunk, because refill() splits the surrogate pair.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.icu.segmentation;

import java.io.StringReader;
import java.util.ArrayList;
import java.util.Collections;
import java.util.List;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestICUTokenizerRefillSurrogatePair extends LuceneTestCase {

  public void testSupplementaryCharAtChunkEnd() throws Exception {
    String extB = new String(Character.toChars(0x20000));
    String text = "中文".repeat(2048).substring(0, 4095) + extB + "中文";
    List<String> terms = new ArrayList<>();
    try (Tokenizer tokenizer = new ICUTokenizer()) {
      tokenizer.setReader(new StringReader(text));
      CharTermAttribute term = tokenizer.addAttribute(CharTermAttribute.class);
      tokenizer.reset();
      while (tokenizer.incrementToken()) {
        terms.add(term.toString());
      }
      tokenizer.end();
    }
    // high surrogate of U+20000 is the last char of the 4096-char chunk: expected 1, actual 0
    assertEquals("tokens equal to U+20000", 1, Collections.frequency(terms, extB));
  }
}
# in a copy of this finding's repro folder (repro/LFV-445/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/analysis/icu/build/libs/lucene-analysis-icu-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.icu.segmentation.TestICUTokenizerRefillSurrogatePair
# the module(s) analysis-icu also need their third-party runtime jars
- Expected vs actual
- Expected U+20000 to be 1 token (as at any other position); actual 0 tokens.
More files, environment, full output37 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: tokens equal to U+20000 expected:<1> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.analysis.icu.segmentation.TestICUTokenizerRefillSurrogatePair.testSupplementaryCharAtChunkEnd(TestICUTokenizerRefillSurrogatePair.java:43)- The class describes UAX #29 word segmentation, which never breaks inside a character; the only stated limit is a 4,096-char maximum word, which the fix keeps.
- One char earlier or later the character is a token, and upstream tests require emoji to be tokens.
- Lucene keeps surrogate pairs whole at buffer edges elsewhere and fixed split pairs as bugs before.
The full argument370 words
- The public description is UAX #29 (tailored per script). Class javadoc: "Breaks text into words according to UAX #29: Unicode Text Segmentation" (
ICUTokenizer.java:31-32), then "Words are broken across script boundaries, then segmented according to the BreakIterator and typing provided by the ICUTokenizerConfig" (:34-35); package javadoc: "Tokenizer that breaks text into words with the Unicode Text Segmentation algorithm" (package-info.java:18). UAX #29 boundaries, and script-boundary breaks, fall between code points. No public javadoc of the class, the factory or the package mentions the chunking. - The only stated limit is a maximum word length. Internal comment: "So there is a maximum word limit of 4kB since it will not try to grow the buffer in this case" (
:133-135; "4kB" is the 4,096-char buffer, not bytes) and "gonna possibly truncate tokens" (:173-174).TestICUTokenizer.testHugeTerm2(:47) pins that as a lossless split: 40,960abecome exactly ten 4096-char tokens. Here no long word is split; a 2-char character disappears. The fix keepstestHugeTerm2passing. - Upstream tests require supplementary characters to be tokens.
testEmoji(:447) andtestEmojiTokenization(:491) expect<EMOJI>tokens, including next to CJK text (💩中國💩). In LUCENE-1488 (#2562), the issue that led to the ICU module, rmuir described the planned components in 2009: "All of these components should also work correctly with surrogate-pair data". - Lucene treats split surrogate pairs as bugs.
CharacterUtils.fillguarantees that "high and low surrogate pairs will always be preserved across buffer boarders" (CharacterUtils.java:158-161), andICUNormalizer2CharFilterin the same module reads through it (:96);TestStandardAnalyzer.testSplitSurrogatePairWithSpoonFeedReader(:696); CHANGES: "LUCENE-8325: Fixed the smartcn tokenizer to not split UTF-16 surrogate pairs" (lucene/CHANGES.txt:7463) and GITHUB#15899/#15900, TruncateTokenFilter "no longer produce half surrogates" (:1182-1183), even for a filter whose job is truncation. - No intent in the history to split a pair. The bounded 4,096-char truncation is deliberate (the comment above), but nothing in the history mentions cutting a character. The fallback came with the class (LUCENE-2414, 2010); its discussion (#3489: 12 comments before a 2011 bulk-close note) is about tailoring, the build and the API, nothing about chunk ends or surrogates, and no commit on the file ever mentions surrogates.
The devil's-advocate check246 words
Strongest case for "intended" (all cross-model review records rated it moderate, the independent reproduction weak, the intended-behaviour check weak to moderate): the class is @lucene.experimental; its comment accepts degraded output when 4kB have no whitespace ("binary data", "possibly truncate tokens"), and testHugeTerm2 locks in arbitrary 4096-char cuts. Tokenizers drop rule-status-0 text by design, and nothing promises that every character is indexed. The forced cut already orphans combining marks. In open #10793 a maintainer called the chunking "a failsafe" that "can cause other issues that look nothing like this, too".
Why it fails: truncating a token gives shorter words that are still indexed; it does not license cutting one valid code point into two non-token halves that the input never contained, and the same character is a token one char earlier or later. Status 0 marks spans the word breaker does not treat as words (spaces, punctuation and other non-word text); the two halves of a valid emoji or ideograph get it only because the cut separates them. @lucene.experimental marks API that may change, not undefined behaviour on valid text. The combining-mark loss is real and is kept out of this claim. #10793 admits the chunking is weak and wants it fixed; it never describes this failure, and the fix keeps the bounded 4096-char buffer. Verdict: not intended, a defect. The minimal fix is local, and #10793's prototype (ICUTokenizer on SegmentingTokenizerBase) would carry the same cut into that class, whose fallback has the same gap.
Recommended A: keep a trailing high surrogate for the next chunk
In refill()'s no-whitespace branch, when the chunk's last char is the first half of a surrogate pair, leave it for the next chunk (4 lines). The repro passes, and the ICU module's 163 tests run with 0 failures, with and without assertions.
        usableLength = length;
        // do not cut a surrogate pair in half: keep a trailing high surrogate for the next chunk
        if (usableLength > 1 && Character.isHighSurrogate(buffer[usableLength - 1])) {
          usableLength--;
        }
All options and trade-offs3 options · 719 words
Fix A and fix B were each validated with gradle in a scratch worktree at ea57360912ed (OpenJDK 25.0.3) and through the repro runner; fix B fails one pinned upstream test. Option C was not run. The similar SegmentingTokenizerBase bug (smartcn and Thai, a 1024-char buffer, the same fallback) is separate.
In the no-whitespace branch of refill() (ICUTokenizer.java:176), if the last char of the full chunk is a high surrogate, end the chunk one char earlier. That char becomes the first char of the next chunk, so the pair is tokenized whole with correct offsets (𠀀[4095,4097)); documents where the hold-back never fires are unchanged. It is the pattern of CharacterUtils.fill. The finder wrote this patch, and an independent verifier wrote the same hold-back. The other two branches cannot end inside a pair: the whitespace branch ends right after a BMP whitespace char, and the end-of-input branch ends where the input ends.
        usableLength = length;
        // do not cut a surrogate pair in half: keep a trailing high surrogate for the next chunk
        if (usableLength > 1 && Character.isHighSurrogate(buffer[usableLength - 1])) {
          usableLength--;
        }
Trade-offs
- Progress: in this branch the buffer is always full (4,096 chars), so holding back one char still advances each refill by at least 4,095 chars; the
usableLength > 1guard is defensive and never fires there. With the fix, 1,048,576 lone high surrogates finish in 56 ms. - Output change only for documents where the hold-back fires: they gain the lost character (existing indexes need a reindex to gain it). In those documents every later forced cut in the same whitespace-free run moves one char earlier (after char 8190 instead of 8191, and so on) until a whitespace char resets it, so tokens near those later cuts can differ too, for example where a forced cut splits a long word (reasoning from
refill(), not run). - Ill-formed text: it also holds back a lone high surrogate, as
CharacterUtils.filldoes. - Does not change the separate orphaning of a combining mark at the forced cut (executed).
- Not benchmarked: one array read per no-whitespace refill.
What the checks validated
- The repro: 4 of 5 fail on stock, 5 of 5 pass with the fix (gradle with assertions on and off; the repro runner with
-eaand-da). - All of
:lucene:analysis:icu:test: 17 suites, 163 tests (including the 5 new), 0 failed, 10 skipped, with assertions on (seed 1C0DE445) and off (seed 77AA0445);TestICUTokenizer45 of 45, includingtestHugeTerm2. Stock: the same 163 tests, 4 failed (all new), the same 10 skipped (@AwaitsFixinTestICUTokenizerCJK). :lucene:analysis:icu:check -x testpasses (checkGoogleJavaFormat, ecjLint, forbiddenApis).- The finder's JUnit (4 of 4), an independent verifier's (8 of 8), the audit probe and the security probe pass with the same hold-back.
In the same branch, ask an ICU character BreakIterator (getCharacterInstance(ULocale.ROOT) over the module's CharArrayIterator) for the start of the last grapheme cluster and end the chunk there (+11 lines).
Trade-offs
- Changes pinned behaviour:
TestICUTokenizer.testHugeTerm2fails, because a run ofanow splits into 4,095-char tokens instead of 4,096. - Wider: it also keeps the combining marks that the forced cut orphans (U+0301, Thai U+0E34; executed).
- Not complete for one huge cluster: if the whole buffer is one grapheme cluster,
preceding(length)returns 0 and thelastCluster > 0guard keeps the full buffer, so that cluster (and a pair at its end) can still be cut (read from the code, not run). - A second break iterator per tokenizer and a
setTextper no-whitespace refill; not benchmarked. - It is the kind of chunking change open #10793 discusses; propose it there, not as the bug fix.
What the checks validated
- The repro: 5 of 5 pass (the repro runner
-ea; gradle module run). :lucene:analysis:icu:test: 163 tests, 1 failed (testHugeTerm2);checkGoogleJavaFormatpasses.
The prototype attached to #10793 (LUCENE-9754, never merged) replaces the ICU chunking with SegmentingTokenizerBase.
Trade-offs
Not a fix on its own: SegmentingTokenizerBase.refill has the same no-safe-end fallback, so the cut would remain unless that class gets the same hold-back. Not run.
A verifier checking a similar bug in SegmentingTokenizerBase first saw it in a token dump. A hunt then swept factory-built analysis chains over buffer-edge positions and flagged ICUTokenizer at exactly chars 4095, 8191 and 16383 for every supplementary probe in every whitespace-free BMP filler. No formal tool was involved.
The method in full266 words
Method: a bounded-exhaustive buffer-edge sweep with a metamorphic oracle (the hunt's semi-formal tier for the hunt; the first signal was non-formal).
- First signal. While verifying the similar
SegmentingTokenizerBasebug (smartcn and Thai), a verifier dumped ICUTokenizer's tokens on main and saw U+20000 at chars 4095-4096 in no token; that bug's adjudication noted it as a separate fix site that needs its own candidate. - The sweep. A hunt over analysis chains built through the factory names ran 13 fillers x 13 probes x 7 buffer boundaries x 9 positions with the oracle "the probe appears as often as at a control position". It flagged the
icutokenizer (default,cjkAsWords=false,myanmarAsWords=false) at exactly chars 4095, 8191 and 16383, for every supplementary probe (emoji, Extension B ideograph, flag, ZWJ sequence) and every whitespace-free BMP filler (9 of the 13 fillers; the two fillers made of surrogate pairs were never probed at the cut): 324 of 324 such cases, all the violations the sweep recorded for these three configurations. The finder reduced it to a public-API JUnit. - Checks. Claude verifiers wrote their own tests (the independent reproduction: Latin and Han fillers, a position sweep and an index; the intended-behaviour check: a devil's advocate who found the combining-mark caveat), an adjudication re-ran the independent reproduction's test with a fresh seed, and an audit wrote an end-to-end probe with a line-broken Japanese document. Review records by a model from another family (OpenAI GPT-5.6) could only read the code; all agreed with the root cause (one real, medium confidence; two procedural "not real", low confidence, because they could not run anything).
No report of this bug found (searched 2026-10-26, 345 logged queries and reads). The nearest item, open #10793, concerns the same 4k chunking but a different symptom (script splitting); it never mentions surrogates or lost characters.
Searches4 searches
Novelty new: no issue, PR, commit, JIRA entry, mailing-list thread, forum post or web page reports ICUTokenizer losing a supplementary character, or splitting a surrogate pair, at the chunk end, and nobody else has reported its no-whitespace fallback as a bug. Borderline item: open #10793 / LUCENE-9754 (by others, 2021, from elastic/elasticsearch#27290) is about the same class's 4k chunking, but its symptom is script-run splitting when the whitespace cut point moves; a maintainer there called the chunking "a failsafe" that "can cause other issues that look nothing like this, too", and its prototype would not fix this bug. The prior-report step and the adjudication judged it not a partial overlap. The SegmentingTokenizerBase reports #8559 and #10153/#16727 concern another class. Gaps: keyword search only; GitHub's search rate limit slowed one run; Stack Overflow only through the general web index; private security reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (3 runs) | 2026-10-26 | 158 queries over apache/lucene issues, PRs and commits, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists and the JIRA archive | no report; #10793 the nearest item |
| GitHub (GraphQL) | 2026-10-26 | 74 searches, including full listings of every apache/lucene item matching "surrogate", "ICUTokenizer", "ICU tokenizer" and "supplementary"; 41 items read in full | #10793 (different symptom), #8559 and #10153/#16727 (other class), precedents #9372 and #15899/#15900 |
| Open PRs | 2026-10-26 | changed files of all 410 open apache/lucene PRs | none touches ICUTokenizer.java |
| JIRA, lists, forums, web | 2026-10-26 | JQL over LUCENE, SOLR, OPENNLP; Solr lists; Elastic and OpenSearch forums; general web | nothing reporting this bug |
Present since ICUTokenizer was added (LUCENE-2414, 2010; first release 3.1.0), in all 131 release tags with the class; a probe or a JUnit loses the character on 16 releases from 3.1.0 to 10.5.2 and on main. Emoji are lost from 7.4.0, when they became tokens. Not fixed upstream.
Versions tested8 rows
Introduced with the class by LUCENE-2414 ("Add ICUTokenizer, tailorable impl of Unicode Text Segmentation", rmuir): trunk 5abbf3429cf (2010-05-03) and the branch_3x backport a1602caf91e (2010-05-06), first released in 3.1.0. The same commit added the 4096-char buffer, the usableLength = length fallback and the status-0 skip. Later changes to refill() kept the fallback: c20242721f9 (LUCENE-3894, read fully; trunk, first tagged in 4.0.0-alpha; in 3.6.0 via the branch_3x backport aec8aacfd95) and 7f8b7ffbcad (LUCENE-9570, formatting, 9.0.0). All 131 release tags that contain the class have the same fallback with no surrogate check; ignoring whitespace, braces and comments, their refill()/findSafeEnd() come in two variants (before and after LUCENE-3894).
Not fixed upstream: ICUTokenizer.java last changed in de3b294be44 (2023-10-11, formatting); main, branch_10x, branch_10_6 and branch_9_12 still have the fallback, and no open PR touches the file (2026-10-26). So the released 10.6.0 (2026-10-29) is affected too (code reading).
| Version or commit | Verdict | Result |
|---|---|---|
main ea57360912ed | affected | this page's repro fails 4 of 5 with -ea and -da; the finder's JUnit 3 of 4 |
main a9779ef3c193 | later main | the finder's JUnit fails 3 of 4, identical messages |
| 10.5.2, 9.12.3 | affected | this page's repro fails 4 of 5 (-da); the finder's JUnit 3 of 4; the probe loses U+20000 and U+1F600 |
| 10.0.0, 9.1.0 | affected | the finder's JUnit fails 3 of 4 (10.0.0 also with the probe) |
| 9.0.0, 8.11.4, 7.7.3, 7.4.0 | affected | the probe loses U+20000 and U+1F600 |
| 7.3.0, 7.2.1, 6.6.6, 5.0.0, 4.10.4, 4.0.0, 3.6.2, 3.1.0 | ideographs | the probe loses U+20000 (3.1.0 also with -da); emoji are not tokens before 7.4.0 |
| 3.0.3 | not affected | no ICUTokenizer (no analysis-icu artifact) |
| main with fix A | fix | the repro passes 5 of 5; the ICU module's 163 tests: 0 failed |
Reproduced by the finder, independent verifiers with their own tests, an adjudication with a fresh seed and an audit with a line-broken Japanese document, with and without assertions. Cross-model review records could only read the code; all agreed with the root cause. Fact checks of this page; their corrections are applied.
Checks and verdicts459 words
Each check worked from the code or its own runs. This page's runs added a new repro, a second fix, gradle runs of the whole ICU module and a combining-mark scope check.
| Check | Verdict | What it found |
|---|---|---|
| Finder's sweep and JUnit | candidate | 324 of 324 supplementary cases in whitespace-free BMP fillers flagged at chars 4095, 8191 and 16383, and no other violations for the three icu configurations; the JUnit fails 3 of 4 on main with -ea and -da, on 10.5.2 and 9.12.3; the fix passes 4 of 4 and upstream TestICUTokenizer 45 of 45. |
| Cross-model reviews (OpenAI GPT-5.6, reading only) | real (medium); two procedural "not real" (low) | The reviewer could not run code; all the reviews agreed with the root cause and found the inputs in contract; the refute lens wrote "Static evidence instead strongly favors a genuine defect". A separate run re-ran the finder's JUnit each time (3 of 4 fail). |
| Independent reproducer | real | Own JUnit in another package: 6 of 8 fail on main (-ea, -da), 10.5.2 and 9.12.3; a sweep of chars 4088-4104 and 8184-8200 loses the character only at 4095 and 8191; a TermQuery misses only the 4095 document; own fix 8 of 8. |
| Cross-model review stage re-runs | reproduced | The finder's JUnit 3 of 4 fail with -ea and -da (seed C0FFEE); a token dump shows chars 4095-4096 uncovered (the token [4094,4095) is followed by [4097,4099)). |
| Intended-behaviour devil's advocate | real (medium-high) | Intended argument weak to moderate; BMP base characters at the cut are kept, supplementary characters are lost; found the combining-mark caveat and the related open #10793. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's JUnit with seed 1A2B3C4D: 6 of 8 fail with -ea and with -da, 0 with the fix. |
| Security screen | none | No hang or amplification, no malformed term, CheckIndex clean, stored text intact, nothing from other documents. |
| Audit | confirmed; priority lowered | Finder's JUnit 3 of 4 with a fresh seed, -ea and -da; own line-broken Japanese probe misses only the 4095 document on main and 10.5.2; impact lowered because the module is opt-in and experimental. |
| This page's runs | fails 4 of 5 on main, 10.5.2, 9.12.3; fix A passes | The repro runner and gradle, -ea and -da; the whole ICU module and its static checks with fix A; fix B and the combining-mark probe. |
| Fact checks of this page | corrections applied | An independent Claude AI tool re-ran the repro (4 of 5 fail with -ea and -da, fix A 5 of 5) and checked every citation; OpenAI GPT-5.6 checked the brief read-only; a third AI tool checked the diagrams. All confirmed the bug, root cause and fix; their wording, count and caveat corrections are applied. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 454 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,341 words
- Registry title
- ICUTokenizer loses a supplementary character (an emoji, a CJK Extension B ideograph) whose surrogate pair straddles the end of its 4096-char read chunk in text with no whitespace, because refill() cuts the pair in half
- Area
- analysis / ICU (ICUTokenizer chunked buffer refill; ICUTokenizerFactory 'icu')
- Priority
- Low, rank 290: Needs more than 4096 whitespace-free characters with a supplementary character exactly at the chunk cut, and each hit loses one character.
- Impact class
- silent wrong results
- Impact note
- Applications that analyze text with ICUTokenizer (the analysis-icu module: new ICUTokenizer(), the 'icu' factory with default or cjkAsWords=false / myanmarAsWords=false parameters, or a downstream icu_tokenizer built on it) lose one supplementary character whenever its high surrogate is the last char of a full 4096-char chunk that contains no whitespace (char 4096k-1 in fully whitespace-free text, otherwise 4096 chars after the last whitespace), so a TermQuery for that character misses the document, with -ea and -da, in every release from 3.1.0 to 10.6.0 (10.6.0 by reading); nothing throws, no malformed term is indexed, CheckIndex is clean, the stored value is intact and the rest of the text is tokenized normally.
- Summary
- You index a long Chinese paragraph with no spaces or line breaks through the stock ICUTokenizer, and it contains an emoji or a rare ideograph such as U+20000; you expect that character to be a token wherever it falls, as it is one position earlier or later. Instead, when its first UTF-16 half is the last char of the tokenizer's 4096-char read chunk, refill() gives the word breaker a chunk that ends in a lone high surrogate and starts the next chunk with the lone low surrogate; both halves get rule status 0 and are skipped, so the character is in no token. A TermQuery for it finds 0 documents instead of 1, with no error.
- Introduced
- 5abbf3429cfa2288f5bf1ff8b19945f67e0d459d (trunk, svn r940447; LUCENE-2414 / GitHub #3489 'Add ICUTokenizer, tailorable impl of Unicode Text Segmentation', rmuir; pre-GitHub, no PR; parent issue #2562 / LUCENE-1488) and its branch_3x backport a1602caf91e2688df47ea1f30de568f92000561a (svn r941706), which shipped in 3.1.0. The commit added refill() with the no-whitespace fallback 'usableLength = length', IOBUFFER = 4096 and the rule-status-0 skip in incrementTokenBuffer(), so the defect is original to the class [read: git log -L and blame -w -M -C of refill() in the history clone; git log --all -S 'usableLength = length' finds only this commit, its backport and a branch-note commit; -G 'isHighSurrogate|isSurrogate' finds nothing; the later changes c20242721f9 (LUCENE-3894, read fully, 3.6.0) and 7f8b7ffbcad (LUCENE-9570, formatting, 9.0.0) kept the fallback; exec: 3.0.3 has no ICUTokenizer, 3.1.0 affected] (2010-05-03 (trunk commit); 2010-05-06 (branch_3x backport))
- First affected version
- 3.1.0 [exec] (3.0.3, the last release before, has no ICUTokenizer [exec: no lucene-icu 3.0.3 artifact, and the probe does not compile against core plus analyzers 3.0.3]; the emoji form shows from 7.4.0 on, when LUCENE-8125 made emoji tokens; before that the loss shows on supplementary letters and ideographs such as U+20000 [exec])
- Affected versions
- every release from 3.1.0 to 10.5.2 (the latest release before 10.6.0) and main ea57360912ed (unreleased 11.0): a public-API main() probe is affected on 3.1.0 (-ea and -da), 3.6.2, 4.0.0, 4.10.4, 5.0.0, 6.6.6, 7.2.1, 7.3.0, 7.4.0, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da) [exec]; the finder's JUnit fails 3 of 4 on 9.1.0, 9.12.3, 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da) [exec, also by the independent reproduction, the intended-behaviour check and the adjudication with their own seeds or tests]; all 131 release tags in the history clone that contain ICUTokenizer.java (3.1 to 10.5.2) have one of two normalized refill()/findSafeEnd() variants, both with the same fallback and no surrogate check [read] (8.8.2 to 8.11.3 are untagged in the clone; 8.11.4 was executed). Not affected: 3.0.3 and earlier (no ICUTokenizer). Not fixed upstream: main, branch_10x, branch_10_6 and branch_9_12 unchanged as of 2026-10-26 [read-only check], so the released 10.6.0 (2026-10-29) is affected too [read].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-26 plus the finder's run, read-only; the prior-report record: 345 logged queries and reads, namely the scripted prior-report search in 3 runs (158 queries over apache/lucene issues, PRs and commits, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists and the JIRA archive), 74 GitHub GraphQL searches including full listings of every apache/lucene item matching 'surrogate', 'ICUTokenizer', 'ICU tokenizer' and 'supplementary', JIRA queries over LUCENE, SOLR and OPENNLP, the Solr lists, the Elastic and OpenSearch forums and the web; 41 GitHub items read in full; the changed files of all 410 open apache/lucene PRs); not fixed upstream (ICUTokenizer.java last changed in de3b294be44, 2023-10-11, formatting only, on main and branch_10x as of main head c50bc9523db3; no open PR touches it). Related items, none reporting this bug: open #10793 / LUCENE-9754 (by others, 2021: inconsistent script-run splitting when the whitespace safe end of the same 4k chunking moves; a maintainer there called the chunking 'a failsafe' that 'can cause other issues that look nothing like this, too'; it never mentions surrogates, lost characters or text without whitespace, and its prototype patch, which rebases ICUTokenizer on SegmentingTokenizerBase, would not fix this bug) and its origin elastic/elasticsearch#27290; the sibling SegmentingTokenizerBase reports #8559 / LUCENE-7508 (open) and #10153 / LUCENE-9112 (closed by #16727), which belong to LFV-233 and do not touch ICUTokenizer.java; precedents for half surrogates fixed as bugs: LUCENE-8325 / #9372 and #15899/#15900. Gaps: keyword search cannot rule out differently worded reports; GitHub's search rate limit slowed one tool run (re-run from cache to completion); Stack Overflow was covered only through the general web index; private reports to security@lucene.apache.org are not visible.
- Lucene commit tested
- main
ea57360912ed(commit 2026-10-24; tested 2026-10-26) on OpenJDK 25.0.3, Linux aarch64: this page's JUnit repro through the repro runner with -ea and -da and through gradle in a scratch worktree, stock, with fix A and with fix B (the worktree was removed after the runs); the ICU module's test suite and static checks with fix A; the 10.5.2 and 9.12.3 release jars; a public-API probe on 15 releases from 3.1.0 to 10.5.2 and the finder's JUnit on 9.1.0, 9.12.3, 10.0.0 and 10.5.2 (history step); a later main,a9779ef3c193, with the finder's JUnit (still reproduces).
- Finding record
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizer.java:30-39 (class javadoc 'Breaks text into words according to UAX #29', @lucene.experimental), :41 (IOBUFFER = 4096), :124-135 (4kB chunk comment, 'maximum word limit of 4kB'), :143-150 (findSafeEnd: last UCharacter.isWhitespace), :158-181 (refill; no-safe-end fallback usableLength = length at :176, breaker.setText at :180), :205-226 (incrementTokenBuffer; rule-status-0 skip at :211)lucene/analysis/icu/src/test/org/apache/lucene/analysis/icu/segmentation/TestICUTokenizer.java:47 (testHugeTerm2: a 40,960-char 'a' run gives ten 4096-char tokens)lucene/core/src/java/org/apache/lucene/analysis/CharacterUtils.java:158-161 (fill javadoc: 'high and low surrogate pairs will always be preserved across buffer boarders')
- The finding in 30 seconds
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizer.java:41-42, 124-136, 143-150, 158-181, 205-226 (buffer, comment, findSafeEnd, refill fallback at :176, setText at :180, status-0 skip at :211)lucene/core/src/java/org/apache/lucene/analysis/CharacterUtils.java:158-161, 203-204 (surrogate hold-back)
- Who is affected
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizer.java:38 (@lucene.experimental), :69-71 (default config)lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizerFactory.java:74 (NAME = "icu"), :96-97 (defaults), :156 (new ICUTokenizer)
- Why it looks unintended
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizer.java:31-35, 38, 133-135, 172-175lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/package-info.java:18lucene/analysis/icu/src/test/org/apache/lucene/analysis/icu/segmentation/TestICUTokenizer.java:47 (testHugeTerm2), :447 (testEmoji), :491 (testEmojiTokenization)lucene/core/src/java/org/apache/lucene/analysis/CharacterUtils.java:158-161; lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/ICUNormalizer2CharFilter.java:96lucene/core/src/test/org/apache/lucene/analysis/standard/TestStandardAnalyzer.java:696lucene/CHANGES.txt:1182-1183, 7463
- TestICUTokenizerRefillSurrogatePair.java (JUnit test):
repro/LFV-445/src/org/apache/lucene/analysis/icu/segmentation/TestICUTokenizerRefillSurrogatePair.java(45 lines)
A summary diagram (PNG), made separately from this text from the code at ea57360912ed and an executed probe (DiagramFacts, main with -ea and -da, and with the fix). The drawn example uses the emoji U+1F600; the text above mostly uses U+20000, which behaves the same way.
assets/LFV-445/bug.png(454 KB)