Multi-term interval sources check their expansion limit twice, once for search and once for Weight#matches; the two checks disagree by one term.
- An interval query (
IntervalQuery) matches positions of terms in a field.Intervals.prefix,wildcard,regexp,range,fuzzyTermandmultitermturn a pattern into the disjunction of every indexed term it matches. - To keep that disjunction small, each takes
maxExpansions(default 128).prefix,wildcard,rangeandmultitermdocument that they throwIndexSearcher.TooManyClauses(IllegalStateExceptionon 10.x) if the pattern expands to more thanmaxExpansionsterms;regexptakes the same argument and checks it, though its@throwsnames the default limit, andfuzzyTermdocuments no@throws. - Search reads the intervals through
intervals(). Highlighters askWeight#matches(leaf, doc)for one document's match positions, which goes through a second method,matches(), with its own copy of the check.
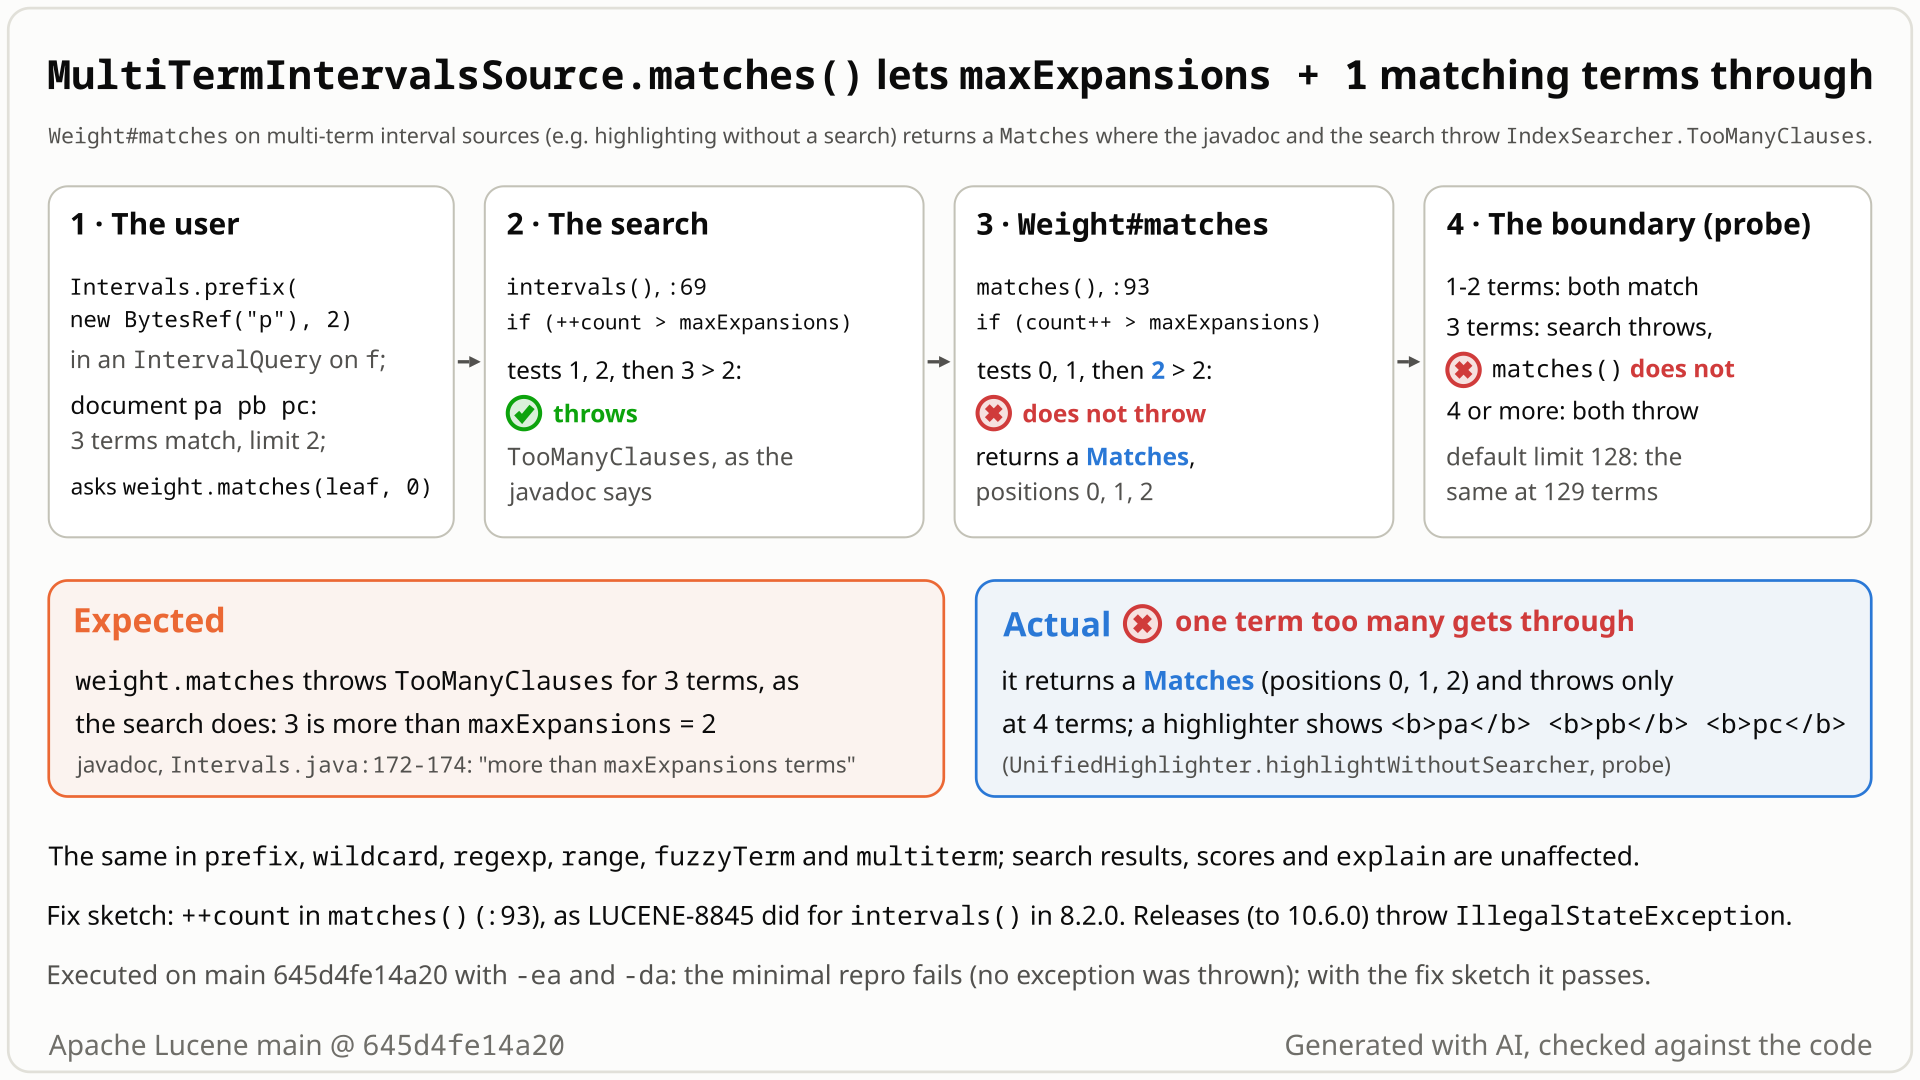
pa pb pc: the search check throws at the 3rd term, the Matches check only at a 4th. Select the still to open it at full size. Generated with AI, checked against the code.- Index one document whose field
fholdspa pb pc: 3 distinct terms that start withp. BuildIntervalQuery("f", Intervals.prefix(new BytesRef("p"), 2)), a prefix query allowed to expand to at most 2 terms. - Search with it: as documented, it throws
IndexSearcher.TooManyClauses("Automaton [p*] expanded to too many terms (limit 2)"), because 3 > 2. - Now ask the same query's
Weight#matchesfor that document, as a highlighter does, for exampleUnifiedHighlighter.highlightWithoutSearcher. You expect the same exception. - Instead you get a
Matches, and the highlighter returns<b>pa</b> <b>pb</b> <b>pc</b>. Only a 4th term makes it throw. With the default limit of 128, 129 matching terms pass and 130 throw. - Why: the search check adds a term, then tests
++count > maxExpansions(3 > 2, throw). The Matches check testscount++ > maxExpansions, the count before the current term (2 > 2, no throw). A 2019 change fixed the same post-increment in the search copy only.
Code that calls Weight#matches without first running the same query on the same reader: UnifiedHighlighter.highlightWithoutSearcher (weight matches on by default), a highlight query that differs from the search query, or Matches tooling. Only for a document with exactly maxExpansions + 1 matching terms (129 by default). Search results never change. Rare.
Mechanism, terms and numbers605 words
The multi-term interval sources (Intervals.prefix, wildcard, regexp, range, fuzzyTerm, multiterm) take one limit, maxExpansions; prefix, wildcard, range and multiterm document that they throw if the pattern expands to more than maxExpansions terms (the regexp javadoc names the default limit instead, a javadoc slip, and fuzzyTerm has no @throws). MultiTermIntervalsSource checks it in two places. The search path, intervals(), tests ++count > maxExpansions after adding each term and throws at the (maxExpansions + 1)-th term, as documented. The Matches path, matches(), used by Weight#matches and so by highlighters, tests count++ > maxExpansions after adding each term the document contains, so it throws only at the (maxExpansions + 2)-th. A document with exactly maxExpansions + 1 matching terms (3 with limit 2, 129 with the default 128) is rejected by the search and accepted by Weight#matches: UnifiedHighlighter.highlightWithoutSearcher highlights it instead of throwing. Search results, scores and explain never change, and the returned positions are the document's own. Both checks were count++ in 8.0.0; LUCENE-8845 (8.2.0) changed only the search one; #16899 (2026-10-26, on main and branch_11x) changed both throws to TooManyClauses and kept count++. All 61 releases from 8.0.0 to 10.6.0 are affected. The fix is one line, ++count in matches().
- Multi-term interval source:
MultiTermIntervalsSource, built byIntervals.prefix,wildcard,regexp,range,fuzzyTermandmultiterm. It walks the segment's terms that the pattern's automaton accepts and combines them into one disjunction. - maxExpansions: the documented maximum number of terms; the constructor only rejects values above
IndexSearcher.getMaxClauseCount()(MultiTermIntervalsSource.java:45-52). - Weight#matches: returns the match positions of one document (
@lucene.experimental,Weight.java:76). The UnifiedHighlighter uses it by default (DEFAULT_ENABLE_WEIGHT_MATCHES = true,UnifiedHighlighter.java:110).
- Search path,
intervals()(MultiTermIntervalsSource.java:57-77): for every accepted term of the segment,subSources.add(...)(:68), thenif (++count > maxExpansions) { throw tooManyTerms(); }(:69-71). The count includes the current term, so the (maxExpansions + 1)-th term throws.explainuses this path too (IntervalQuery.java:158-159). - Matches path,
matches()(:79-148), called fromIntervalWeight.matches(IntervalQuery.java:171-175): for every accepted term the document contains (TermIntervalsSource.java:164-169returns null otherwise),subMatches.add(mi)(:92), thenif (count++ > maxExpansions) { throw tooManyTerms(); }(:93-95). The comparison uses the count from before the current term. - With limit 2 and the document
pa pb pc: afterpcthe search check compares 3 > 2 and throws; the Matches check compares 2 > 2 and goes on, and returns aMatcheswith the three positions. A 4th term would compare 3 > 2 and throw. - Both throws build the same exception through
tooManyTerms()(:150-153) since #16899; only the increment differs. - In the usual flow (a scoring or top-hits search, then highlighting its hits with the same query on the same reader) the search has already thrown: it builds the interval iterator of every segment, and a document's matching terms are a subset of the segment's. The bad check shows when
matches()runs without such a search. A count alone is no such guarantee:BooleanWeight.count(BooleanWeight.java:167) can answer from the required clauses alone, without building the SHOULD clauses.
Limit 2: 2 terms pass both paths; 3 terms: search throws, Weight#matches returns a Matches; 4 terms throw on both. Default limit 128: 128 pass both; 129: search throws, Matches passes; 130 throw on both. highlightWithoutSearcher on pa pb pc with limit 2 returns <b>pa</b> <b>pb</b> <b>pc</b>; with the fix it throws TooManyClauses.
Exposure and likelihood392 words
- Who is hit. Callers of
Weight#matchesorIntervalsSource#matcheson a multi-term interval source that did not first run a scoring or top-hits search of the same query on the same reader. Examples, not a complete list:UnifiedHighlighter.highlightWithoutSearcher(UnifiedHighlighter.java:1096), which uses weight matches by default; a highlighter or other Matches consumer given a highlight query that differs from the search query;MatchRegionRetriever(MatchRegionRetriever.java:405), which callsWeight#matchesdirectly; directWeight#matchescalls. The same holds for a multi-term source nested inside a composite interval source (ordered, unordered, filtered, difference, ...), which passmatches()down to their sub-sources (ConjunctionIntervalsSource.java:75,FilteredIntervalsSource.java:113). - What it takes. A document whose field holds exactly maxExpansions + 1 distinct matching terms: 3 with limit 2, 129 with the default 128 (
Intervals.java:64). One fewer passes both paths, one more throws on both. This is about positive limits; the constructor does not rejectmaxExpansions < 1. - What happens. That one call returns a correct
Matches(the document's own positions) instead of the documentedTooManyClauses(IllegalStateExceptionon 10.x). Code that relies onmatches()throwing once a document holds more than maxExpansions matching terms gets a highlight instead. (Search andmatches()already differ by design elsewhere:matches()counts only the document's terms, so a document with at most maxExpansions matching terms gets aMatcheseven where the segment is over the limit. The off-by-one adds the case where the document itself is over the limit.) - What does not happen. Search results, hit counts, scores and
explainnever change; nothing over-matches; no hang, and the worst-case work per call does not change: a document within the limit already walks all of the segment's matching terms, opening a postings enum for each (MultiTermIntervalsSource.java:89-97,TermIntervalsSource.java:166). On the trigger input the stock code also walks the rest of them, where the fix stops at the (maxExpansions + 1)-th: in the study's probe (505 matching terms in the segment, limit 2), 506 term-enum steps on stock and 3 with the fix for that document, and at most 506 for any document either way. The returnedMatchesholds at most one more sub-iterator. - Default vs opt-in. The default writer, codec, searcher and limit suffice. The intervals package calls its classes experimental and
Weight#matchesis@lucene.experimental, but the UnifiedHighlighter uses it by default. Every multi-term factory is affected.
One JUnit test on the public API: one document pa pb pc, IntervalQuery("f", Intervals.prefix(p, 2)), and Weight#matches for that document. It expects the documented TooManyClauses and fails because no exception is thrown. Deterministic, single thread; the same with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queries.intervals;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.ScoreMode;
import org.apache.lucene.search.Weight;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestMultiTermIntervalsMatchesLimit extends LuceneTestCase {

  public void testMatchesThrowsAtMaxExpansionsPlusOne() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new TextField("f", "pa pb pc", Field.Store.NO));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        IntervalQuery query = new IntervalQuery("f", Intervals.prefix(new BytesRef("p"), 2));
        Weight weight = searcher.createWeight(query, ScoreMode.COMPLETE_NO_SCORES, 1f);
        // Expected TooManyClauses (3 terms > maxExpansions 2, as search throws); actual: a Matches.
        expectThrows(
            IndexSearcher.TooManyClauses.class, () -> weight.matches(reader.leaves().get(0), 0));
      }
    }
  }
}
cp TestMultiTermIntervalsMatchesLimit.java $LUCENE/lucene/queries/src/test/org/apache/lucene/queries/intervals/
cd $LUCENE && ./gradlew :lucene:queries:test --tests org.apache.lucene.queries.intervals.TestMultiTermIntervalsMatchesLimit -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
- Expected
IndexSearcher.TooManyClauses("Automaton [p*] expanded to too many terms (limit 2)"), as the search of the same query throws.- Observed
- No exception:
Weight#matchesreturns aMatches("Expected exception TooManyClauses but no exception was thrown"), with assertions on and off.
More files, environment, full output188 words
Public API only: IndexWriter with the default IndexWriterConfig, ByteBuffersDirectory, TextField, IndexSearcher.createWeight, Weight#matches, IntervalQuery, Intervals.prefix(BytesRef, int); the class sits in the intervals package by Lucene test convention but uses no package-private API. 20 random seeds fail 20 of 20 on main and pass 20 of 20 with the fix.
On 10.x the documented type is IllegalStateException; the test as written fails there too with "no exception was thrown" (10.5.2, assertions on and off). A 10.x backport of the test should expect IllegalStateException.
As the regression test: this same test, for example as a method in TestIntervals.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the same test also fails on 10.5.2; every release from 8.2.0 to 10.6.0 shows the pattern |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestMultiTermIntervalsMatchesLimit.java $LUCENE/lucene/queries/src/test/org/apache/lucene/queries/intervals/
cd $LUCENE && ./gradlew :lucene:queries:test --tests org.apache.lucene.queries.intervals.TestMultiTermIntervalsMatchesLimit -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
TestMultiTermIntervalsMatchesLimit > testMatchesThrowsAtMaxExpansionsPlusOne FAILED
    junit.framework.AssertionFailedError: Expected exception TooManyClauses but no exception was thrown
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:6CD3F92D246F7B78]:0)
        at org.apache.lucene.tests.util.LuceneTestCaseParent.expectThrows(LuceneTestCaseParent.java:1432)
        at org.apache.lucene.tests.util.LuceneTestCaseParent.expectThrows(LuceneTestCaseParent.java:1418)
        at org.apache.lucene.queries.intervals.TestMultiTermIntervalsMatchesLimit.testMatchesThrowsAtMaxExpansionsPlusOne(TestMultiTermIntervalsMatchesLimit.java:47)

# gradle, main 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=false; identical with assertions on- The javadoc gives one limit for every path: throw "if the prefix expands to more than maxExpansions terms"; the search check does exactly that.
- LUCENE-8845 fixed the same post-increment in the search copy in 2019, "a general accuracy improvement"; the Matches copy was most likely missed.
- The only Matches limit test uses limit + 2 terms, which throws either way.
The full argument246 words
- Contract.
Intervals.prefix(BytesRef, int): "@param maxExpansions the maximum number of terms to expand to", "@throws org.apache.lucene.search.IndexSearcher.TooManyClauses if the prefix expands to more than {@code maxExpansions} terms" (Intervals.java:172-174).wildcard(:201-203) andmultiterm(:364-367) say the same; so doesrange(:275-277), though its@throwstext says "wildcard glob" (a copy-paste slip).regexphas the same@param(:232), but its@throwsreads "more than {@link #DEFAULT_MAX_EXPANSIONS} terms" (:233-234), a javadoc slip: the code checks itsmaxExpansionsargument.fuzzyTermhas no@throws; its@paramreads "the maximum number of terms to match" (:329). No exception for the Matches path. - The sibling check implements it (
++count,MultiTermIntervalsSource.java:69), and #16899 gave both paths one message helper so that "both paths produce the same message". - History. LUCENE-8646 (
7d7ab14776b, 8.0.0) wrote both checks ascount++. LUCENE-8845 (e8950f4a528, 8.2.0), which made the limit configurable, changed only the search line to++count, with no CHANGES note on the off-by-one, and tested onlyintervals(). Asked about it on #9889, the author (romseygeek) said: "This is a general accuracy improvement, which was only picked up when I added specific tests for the expansion cap." Nobody mentionedmatches(). - Tests. The only Matches limit assertion, added by #16899 in
TestIntervals.testPrefix(TestIntervals.java:984-997), uses limit 1 on a document with three matching terms ("pease", "porridge", "pot"): limit + 2, which throws with either increment.
The devil's-advocate check168 words
The strongest case for "intended" (the study's intended-behaviour verifier and the cross-model reviewers): matches() is only a safety net that the normal search-then-highlight flow never reaches; it already counts only one document's terms, so it is more lenient than search by design and one more term changes nothing; and the intervals package and Weight#matches are experimental.
Why it fails: nothing documents an extra term for the Matches path; per-document counting is a separate design choice that the fix leaves alone (with ++count, matches() still counts only the document's terms, now with the documented threshold); experimental means the API may change, not that the documented @throws does not apply; and the project fixed the very same post-increment in the sibling line as "a general accuracy improvement". The argument supports low priority. Verdict: most likely not intended, a defect (a well-supported inference from the javadoc, the sibling line and its history; no maintainer has said either way). Not security: no over-matching and no change to the worst-case work.
Recommended A. Pre-increment in matches() (one line)
Use ++count instead of count++ in MultiTermIntervalsSource.matches(): one line, and both copies of the check then throw at the (maxExpansions + 1)-th term. With it the repro passes with assertions on and off, as do the 118 intervals-package tests, the 144 highlighter tests that use interval queries and the queries module's static checks.
--- a/lucene/queries/src/java/org/apache/lucene/queries/intervals/MultiTermIntervalsSource.java
+++ b/lucene/queries/src/java/org/apache/lucene/queries/intervals/MultiTermIntervalsSource.java
@@ -90,7 +90,7 @@
       MatchesIterator mi = TermIntervalsSource.matches(te, doc, field);
       if (mi != null) {
         subMatches.add(mi);
-        if (count++ > maxExpansions) {
+        if (++count > maxExpansions) {
           throw tooManyTerms();
         }
       }
All options and trade-offs2 options · 350 words
Fix A was validated through gradle in a scratch worktree of 645d4fe14a20. B is an alternative that was not run.
Count the current term before comparing, exactly as intervals() does (MultiTermIntervalsSource.java:69). On 10.x the same line is :99.
--- a/lucene/queries/src/java/org/apache/lucene/queries/intervals/MultiTermIntervalsSource.java
+++ b/lucene/queries/src/java/org/apache/lucene/queries/intervals/MultiTermIntervalsSource.java
@@ -90,7 +90,7 @@
       MatchesIterator mi = TermIntervalsSource.matches(te, doc, field);
       if (mi != null) {
         subMatches.add(mi);
-        if (count++ > maxExpansions) {
+        if (++count > maxExpansions) {
           throw tooManyTerms();
         }
       }
Trade-offs
- The two checks then use the same threshold expression (the search still counts the segment's terms,
matches()the document's); a document with exactly maxExpansions + 1 matching terms now throws on the Matches path as on the search path. - Callers that today get a highlight for such a document get the documented exception instead, which is what the limit is for.
- Keeps the per-document counting of
matches()unchanged (a separate design point, not part of this bug).
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20, seedDEADBEEF, 2026-11-01: without the fix the repro fails with assertions on and off; with it, it passes with assertions on and off. ./gradlew :lucene:queries:test --tests 'org.apache.lucene.queries.intervals.*': 8 classes (includingTestIntervals, 43 tests,TestIntervalQuery, 34, and the repro), 118 tests, 0 failures.TestUnifiedHighlighterTermIntervals,TestMatchRegionRetrieverandTestMatchHighlighter: 144 tests, 0 failures../gradlew :lucene:queries:check -x testwith the fix and the repro as a new test file: passes (google-java-format, ecj lint, forbidden APIs). The full Lucene test suite was not run.- Earlier: with the fix shadowed into the stock jars, the finder's, the independent verifier's and the cross-model reviewer's own tests pass, and the bounded-exhaustive checker finds 0 failures.
Replace both counters with if (subSources.size() > maxExpansions) in intervals() and if (subMatches.size() > maxExpansions) in matches(), right after the add.
Trade-offs
- Same behaviour as A, and the two copies can no longer drift apart.
- Touches the search path for no behaviour change there; a slightly larger review.
Applications that highlight interval queries without running them first (for example with highlightWithoutSearcher) get a highlight instead of the over-expansion error for a document with exactly maxExpansions + 1 matching terms; search results do not change.
Semi-formal: an AI tool built a bounded-exhaustive checker that compared the real multi-term interval sources with an independent expansion (1,597 sources over a three-segment index, at limits n - 1, n and n + 1). The only failures were documents with exactly maxExpansions + 1 matching terms on the Matches path.
The method in full166 words
Method: bounded-exhaustive translation validation of the real jar against an independent reference, public API only (study unit on the intervals builder and multi-term sources, main ea57360912ed, 2026-10-26).
- Index: 150 documents in 3 segments over the 14 terms {a,b}^1..3.
- Sources: 1,597 (15 prefix, 84 wildcard, 602 regexp, 360 fuzzyTerm, 536 range), each checked per segment at maxExpansions n - 1, n and n + 1, where n is the size of a reference expansion computed with independent predicates (startsWith, a recursive glob, java.util.regex, Levenshtein or optimal-string-alignment distance, String order): 731,742 checks per seed.
- Result: one failing category, "no throw although the document is over the limit", 9,124 checks with seed 42 and 9,211 with seed 7, every one with exactly maxExpansions + 1 matching terms in the document. 0 failures with the fix; a mutant that loosens the search check by one is caught (4,578 failures), so the checker is not vacuous.
- The finder then wrote the public-API JUnit; the one-test repro was reduced from it.
The recorded searches found no prior report in GitHub issues, PRs, review comments and commits, the JIRA archive, the Lucene mailing lists, downstream projects or the web (searched 2026-10-26 and 2026-11-01). Closest: #16899 (merged 2026-10-26) rewrote both throws but kept count++; LUCENE-8845 (#9889, 2019) fixed only the search copy. Not fixed upstream as of 2026-10-30.
Searches5 searches
Closest items, none a report of this bug: #16899 ("Throw TooManyClauses on intervals over-expansion", merged 2026-10-26, on main and branch_11x, not 10.x: both throws and the Matches message changed, count++ kept, one "LGTM" review, its new Matches test uses limit + 2 terms); #9889 / LUCENE-8845 (2019, fixed the same post-increment in intervals() only); #9692 / LUCENE-8646 (added both checks; discussion covers only the 128 default); elastic/elasticsearch#162297 and #162833 (the over-expansion error as HTTP 500 vs 400: exception type, not the threshold); requests for a configurable limit (OpenSearch#14909, elasticsearch#65505). Other multi-term-intervals issues (#10074, #11113, #10092, #9331) are about other things. Gaps: GitHub search does not index PR diffs, so closed unmerged PRs could only be found by their text; list search is token-based.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs, review comments and commits | 2026-11-01 | two scripted prior-report searches with different term sets (MultiTermIntervalsSource, matches, maxExpansions, "expanded to too many terms", off-by-one, TooManyClauses; the six factories, UnifiedHighlighter, highlightWithoutSearcher, count++, post-increment, expansion cap); 14 manual queries; the files of all 410 open PRs; every issue and PR updated since 2026-10-22 with their comments | no report; #16899 edits the same throws and keeps count++ |
| Mailing lists, JIRA archive, downstream, web | 2026-11-01 | dev@, java-user@, issues@ and commits@ (20 more queries; the #16899 mails read in full); JIRA; Solr, Elasticsearch and OpenSearch; 9 web queries | no report |
| Git history of the file | 2026-11-01 | pickaxe searches for both forms of the check; log grep for maxExpansions | LUCENE-8646 wrote both checks; LUCENE-8845 changed only the search one |
| Earlier study searches | 2026-10-26 | 176 query records: three scripted prior-report searches, manual GitHub searches, the files of all 408 open PRs, 8 web searches | no report |
| Upstream branches | 2026-11-01 | file contents on main 2f424fd428da, branch_11x d0c0decc6606 and branch_10_6 91eaab4fb298 | not fixed: count++ still in matches() |
The faulty line came with LUCENE-8646 (7d7ab14776b, 8.0.0), where both checks used count++; the reported divergence since LUCENE-8845 (e8950f4a528, 8.2.0), which fixed only the search check. All 61 releases from 8.0.0 to 10.6.0 executed: every one affected. Not fixed upstream as of 2026-10-30.
Versions tested5 rows
Faulty line written by LUCENE-8646 (commit subject "LUCENE-8646: Multi-term intervals"; #9692, romseygeek, JIRA patch): 7d7ab14776b on main (2019-01-22), backport ceadb5f1339. Divergence from LUCENE-8845 (commit subject "LUCENE-8845: Allow configurable maxExpansions for prefix/wildcard intervals"; #9889): e8950f4a528 (2019-06-10), backport 74a695ee444, which changed only the intervals() line. #16899 (f4cc6ac2097, 2026-10-26, on main and branch_11x) changed the exception to TooManyClauses and kept count++; 10.6.0 still throws IllegalStateException. git blame -w -M -C -C puts the count++ line at 7d7ab14776b: many later commits changed the file (among them the LUCENE-8856 move from sandbox to queries and the LUCENE-9570 reformat), but not that line; #16899 rewrote the throws and the loop header around it.
Factories, each affected from the release that added it: prefix, wildcard 8.0.0 (configurable limit 8.2.0); multiterm 8.4.0; fuzzyTerm 9.1.0; regexp, range 9.12.0.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | search throws TooManyClauses, Weight#matches returns a Matches (limit 2 with 3 terms; default 128 with 129); minimal repro fails with assertions on and off (standalone and gradle) |
| 8.2.0 to 10.6.0 (58 releases) | affected | the same pattern with IllegalStateException; 128 terms pass and 130 throw on both paths (controls) |
| 8.0.0, 8.1.0, 8.1.1 | both paths off by one | search and Matches both let 129 terms through with the then fixed limit 128 (they agree, both against the javadoc) |
| 7.7.3 | API absent | no MultiTermIntervalsSource or Intervals.prefix (compile error) |
8.0.0 with both checks ++count; 8.2.0 and main with only matches() changed | fix (shadow) | both paths throw at maxExpansions + 1; controls hold |
Confirmed by the study's independent verifiers and its adjudication, the re-verification on main, a reviewer from another model family (OpenAI GPT-5.6) that ran its own test and judged it real with high confidence, and this doc's gradle run. The one-line fix passed every check it was given.
Checks and verdicts337 words
The study's checks: finder, independent verifiers, two read-only cross-model passes, an adjudication; then a re-verification on 645d4fe14a20, an executed cross-model review and this doc's gradle run.
| Check | Verdict | What it found |
|---|---|---|
| finder | fails on main, 9.1.0, 9.12.3, 10.5.2 | Public-API JUnit with a search control: the search throws, Weight#matches returns a Matches; passes with the fix. |
| Independent reproducer | real | Own test from the claim alone: for limits 1 to 4, mismatches only at maxExpansions + 1 terms; all six factories mismatch at limit 2 with 3 terms; main, 10.5.2 and 9.12.3; 7 of 7 pass with the fix. |
| Intended-behaviour devil's advocate | real, low impact | Built the strongest "intended" case and rejected it; showed highlightWithoutSearcher highlighting pa pb pc with limit 2; explain is not affected. |
| read-only cross-model passes (OpenAI GPT-5.6) | real (medium); not real (low, procedural) | Could not run code; the refute pass's "not real" is procedural, and it agreed on the root cause. Superseded by the executed review below. |
| adjudication | confirmed, high | Re-ran both tests with a fresh seed and checked that LUCENE-8845 changed exactly one line, in intervals(). |
| re-verification on main | still reproduces | After #16899 the old repro failed at its control (new exception type); adapted, it fails as before on a9779ef3c193. The minimal repro fails on 645d4fe14a20 and 10.5.2 with assertions on and off and passes with the fix. |
| cross-model review, refute lens (OpenAI GPT-5.6, ran code) | real, high confidence | Its own test fails 3 of 3 with assertions on and off and passes with the fix; re-run on 645d4fe14a20. It rated the intended-behaviour case "moderate" and rejected it: "no public contract requires search-first use or grants the per-document counter one extra term". |
| this doc's gradle run | fails stock, passes fixed | Gradle in a scratch worktree of 645d4fe14a20: the repro fails with assertions on and off and passes with fix A; the intervals tests, the interval highlighter tests and :lucene:queries:check -x test pass with it. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 409 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,313 words
- Registry title
- MultiTermIntervalsSource.matches() checks the expansion limit with a post-increment ('count++ > maxExpansions'), so Weight#matches, and highlighting through it, accepts a document with exactly maxExpansions + 1 matching terms, where the javadoc and the search path (which uses '++count') reject it (IllegalStateException; IndexSearcher.TooManyClauses on main since #16899)
- Area
- queries / intervals (MultiTermIntervalsSource behind Intervals.prefix, wildcard, regexp, range, fuzzyTerm and multiterm; Weight#matches / IntervalsSource#matches)
- Priority
- Low, rank 1123: MultiTermIntervalsSource.matches() lets exactly maxExpansions + 1 terms through instead of throwing, which needs a matches-only path and an exact term count and still returns correct positions.
- Impact class
- wrong error
- Impact note
- Only code that calls Weight#matches or IntervalsSource#matches on a multi-term interval source without first running the same query on the same reader (UnifiedHighlighter.highlightWithoutSearcher, a highlight query that differs from the search query, or Matches-based tooling), and only for a document that holds exactly maxExpansions + 1 distinct matching terms in the field (129 with the default limit of 128): it gets a Matches with that document's correct positions instead of the documented over-expansion exception (IllegalStateException; IndexSearcher.TooManyClauses on main since #16899); search results, scores and explain are never affected; default writer, codec, searcher and limit suffice; in every release from 8.2.0 through 10.6.0 and on main.
- Summary
- You build IntervalQuery("f", Intervals.prefix(new BytesRef("p"), 2)) over a document 'pa pb pc' (three terms match p*) and call Weight#matches for it, as a highlighter does. You expect the over-expansion exception (IllegalStateException; IndexSearcher.TooManyClauses on main since #16899), because the javadoc says the source throws if the prefix 'expands to more than maxExpansions terms', and searching the same query on the same segment does throw. Instead matches() tests 'count++ > maxExpansions' after adding each term, so it returns a Matches for exactly maxExpansions + 1 matching terms in the document and throws only at maxExpansions + 2; the same holds for wildcard, regexp, range, fuzzyTerm and multiterm.
- Introduced
- 7d7ab14776b7257e09679d840182a4286928e452 (main) and its branch_8x backport ceadb5f1339fe5bf09f9818470872d4957b63ba5, both 'LUCENE-8646: Add multi-term intervals' (JIRA patch, no GitHub PR; migrated issue apache/lucene#9692; by romseygeek), which wrote 'if (count++ > maxExpansions)' in both intervals() and matches() [read: git blame of MultiTermIntervalsSource.java:99 in the history clone, whose copy of the file is byte-identical to main ea57360912ed]. The reported divergence (search throws at maxExpansions + 1, matches() does not) starts with e8950f4a528605f9be17c644eef4f47d0659317b (branch_8x backport 74a695ee444d195421c9e5cceeee28a813b42cea), 'LUCENE-8845: Allow maxExpansions to be set on multi-term Intervals' (JIRA patch; migrated issue apache/lucene#9889; by romseygeek), which changed only the intervals() check to '++count > maxExpansions' and added limit tests for intervals() only [read: git show; exec: release sweep]. (2019-01-22 (faulty matches() line, 7d7ab14776b; authored 2019-01-17); 2019-06-10 (divergence, e8950f4a528))
- First affected version
- 8.0.0 for the faulty matches() line: in 8.0.0, 8.1.0 and 8.1.1 both checks used 'count++', so with the then fixed limit of 128 both the search and matches() accepted 129 terms (the two paths agreed, both one term over the javadoc limit) [exec]; 8.2.0 for the reported symptom, matches() accepting maxExpansions + 1 terms while the search throws [exec]. 7.7.3 has no MultiTermIntervalsSource and no Intervals.prefix [exec: compile error].
- Affected versions
- every release that has the API and main [exec: official release jars, SHA-1 checked, JDK 25.0.3, all 61 lucene-core releases from 8.0.0 to 10.6.0]: 8.0.0, 8.1.0, 8.1.1 show both checks off by one (paths agree); 8.2.0 through 10.6.0 (58 releases) and main ea57360912ed (-ea and -da) show the reported pattern, where only matches() lets maxExpansions + 1 terms through (limit 2 with 3 terms; default limit 128 with 129 terms); 128 terms allowed and 130 rejected on both paths in every release (controls). The finder's JUnit also fails on 9.1.0, 9.12.3 and 10.5.2, the independent reproduction's on 9.12.3 and 10.5.2. Not fixed upstream: apache/lucene main 49483e82b357, branch_10x and branch_10_6 still have 'if (count++ > maxExpansions)' at line 99 [read 2026-10-26], and so does the 10.6.0 release commit 4ae946e5a9b [read, 2026-10-30]; #16899 (merged 2026-10-26 as f4cc6ac2097) keeps it. Affected factories, each from the release that added it [read]: prefix and wildcard 8.0.0 (configurable limit since 8.2.0), multiterm 8.4.0, fuzzyTerm 9.1.0, regexp and range 9.12.0. Tags 8.8.2-8.11.4 are not in the history clone; for those the result comes from executing the release jars only.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, 176 query records: three scripted prior-report searches over apache/lucene GitHub issues and PRs, commit messages, the migrated JIRA, the dev@, java-user@, issues@ and commits@ lists and the Elasticsearch, OpenSearch and Solr repositories; manual GitHub searches; the file lists of all 408 open apache/lucene PRs; 8 web searches; the full git history of the file, including pickaxe searches for both forms of the check): no issue, PR, review comment, commit, JIRA entry, list thread or web page reports that matches() lets maxExpansions + 1 terms through. Not fixed: upstream main 49483e82b357, branch_10x and branch_10_6 still have the line. Nearest items, not reports of this bug: #16899 (mayya-sharipova, 'Throw TooManyClauses on intervals over-expansion', approved by romseygeek, merged on 2026-10-26 as f4cc6ac2097; an earlier read-only re-check that day still saw it open) rewrites the throw in both checks (exception type IndexSearcher.TooManyClauses, matches() message now uses the pattern) but keeps 'count++ > maxExpansions' in matches(), and its new matches() test (3 terms, limit 1) throws with either increment; #9889 / LUCENE-8845 (2019) changed only the intervals() check from count++ to ++count (the author called it 'a general accuracy improvement, which was only picked up when I added specific tests for the expansion cap') and nobody mentioned matches(); #9692 / LUCENE-8646 (the introducing change; discussion covers only the 128 limit); elastic/elasticsearch#162297 and #162833 (the over-expansion error surfaces as HTTP 500; exception type, not the threshold); feature requests for a configurable limit (OpenSearch#14909, elasticsearch#65505, OpenSearch#1857).
- Lucene commit tested
- main
645d4fe14a20: the minimal repro with assertions on and off, standalone and through gradle; the recommended fix in a scratch worktree with allorg.apache.lucene.queries.intervals.*tests, the three highlighter suites that use interval queries and:lucene:queries:check -x test; the highlighter probe. SHA-1-checked release jars: all 61 releases from 8.0.0 to 10.6.0 (and 7.7.3, which lacks the API); the minimal repro on 10.5.2. The study ran on mainea57360912edand re-checkeda9779ef3c193, whose intervals sources are identical to645d4fe14a20.MultiTermIntervalsSource.javais unchanged on upstream main2f424fd428da(2026-10-30, read).
- Finding record
lucene/queries/src/java/org/apache/lucene/queries/intervals/MultiTermIntervalsSource.java:58-82 (intervals(): ':69 if (++count > maxExpansions)'), :85-104 (matches(): sub-match added only for terms present in the document, then ':99 if (count++ > maxExpansions)'; the message prints the last term, not the pattern)lucene/queries/src/java/org/apache/lucene/queries/intervals/Intervals.java:64 (DEFAULT_MAX_EXPANSIONS = 128), :172-173 (prefix: '@param maxExpansions the maximum number of terms to expand to', '@throws IllegalStateException if the prefix expands to more than {@code maxExpansions} terms'), :200-201 (wildcard), :231-232 (regexp), :274-275 (range), :328 (fuzzyTerm)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:110 (DEFAULT_ENABLE_WEIGHT_MATCHES = true), :1096 (highlightWithoutSearcher)lucene/core/src/java/org/apache/lucene/search/Weight.java:76 (matches is @lucene.experimental)
- The finding in 30 seconds
lucene/queries/src/java/org/apache/lucene/queries/intervals/MultiTermIntervalsSource.java:45-52, :57-77, :79-148, :150-153 (at 645d4fe14a20)lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalQuery.java:158-159, :171-175; TermIntervalsSource.java:164-169 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/search/Weight.java:76; lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:110, :1096 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/search/BooleanWeight.java:167 (count) and reqCount (at 645d4fe14a20)
- Who is affected
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:110, :1096 (at 645d4fe14a20)lucene/queries/src/java/org/apache/lucene/queries/intervals/Intervals.java:64; package-info.java:21 (at 645d4fe14a20)lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/MatchRegionRetriever.java:405; lucene/queries/src/java/org/apache/lucene/queries/intervals/ConjunctionIntervalsSource.java:75, FilteredIntervalsSource.java:113, MultiTermIntervalsSource.java:45-52, :89-97, TermIntervalsSource.java:166 (at 645d4fe14a20)
- Why it looks unintended
lucene/queries/src/java/org/apache/lucene/queries/intervals/Intervals.java:172-174, :201-203, :232-234, :275-277, :329, :364-367 (at 645d4fe14a20)lucene/queries/src/test/org/apache/lucene/queries/intervals/TestIntervals.java:984-997 (at 645d4fe14a20)
- TestMultiTermIntervalsMatchesLimit.java (JUnit, one test):
repro/LFV-462/src/org/apache/lucene/queries/intervals/TestMultiTermIntervalsMatchesLimit.java(52 lines)
Made in parallel with this doc from the mechanism in the brief; the PNG is the summary frame.
assets/LFV-462/bug.png(409 KB)