FileDictionary splits every line of the file with line.split(fieldDelimiter). String.split does not take a separator: it takes a regular expression. So a delimiter that contains a character with a regex meaning (|, ., +, $, ^, *, ?, (, [, {, \) does not cut the line where that character is.
- A suggester (
Lookup) is built from aDictionary: an iterator of entries, each a suggestion text with a weight and an optional payload. FileDictionaryis theDictionaryfor a plain text file: one entry per line,suggestion, then optionallyfieldDelimiterweight, then optionallyfieldDelimiterpayload. The default delimiter is a TAB; the constructorsFileDictionary(Reader, String)andFileDictionary(InputStream, String)take any other string.
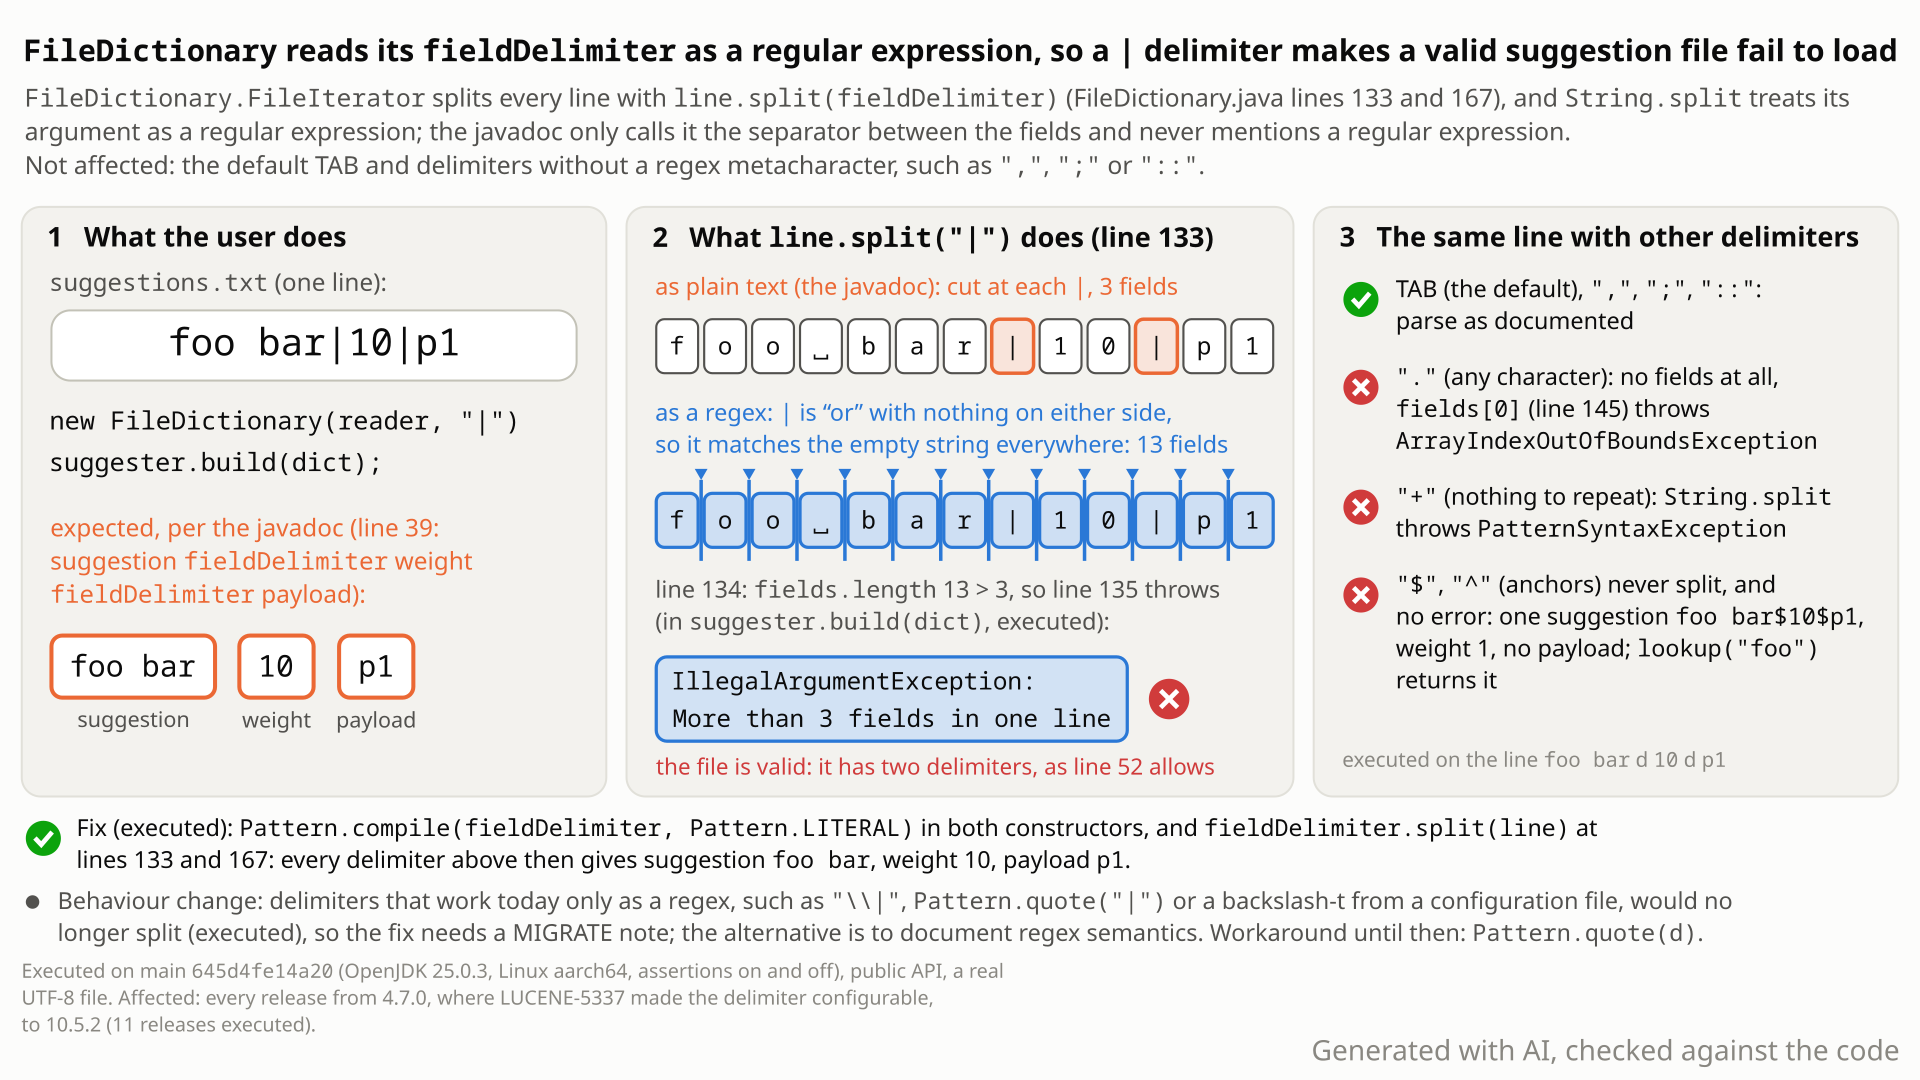
line.split("|") does to it compared with a plain-text split, the exception, the same line with other delimiters, and the fix. Select the still to open it at full size. Generated with AI, checked against the code.- Write a suggestion file in the documented format with a pipe between the fields: the one line
foo bar|10(suggestionfoo bar, weight 10). Read it withnew FileDictionary(reader, "|"). - You expect one entry,
foo barwith weight 10: the javadoc's format issuggestion fieldDelimiter weight, and the line has one delimiter. - You get
IllegalArgumentException: More than 3 fields in one linefromgetEntryIterator(), so the suggester cannot be built. - Why: each line is split with
line.split(fieldDelimiter), andString.splittreats its argument as a regular expression.|means "empty or empty", which matches between every two characters, sofoo bar|10becomes 10 fields:f,o,o,b,a,r,|,1,0. - Other delimiters:
.throwsArrayIndexOutOfBoundsException,+throwsPatternSyntaxException, and$or^never split, so every line silently becomes one suggestion such asfoo bar$10$p1with weight 1 and no payload. TAB,,,;and::work.
Code that gives FileDictionary a non-default delimiter with a regex metacharacter; Solr passes its suggester's configured fieldDelimiter straight through. The default TAB is unaffected. With |, a common text-file separator, a valid file with weights fails on the first build with a message that blames the file; $ or ^ silently fold weights and payloads into the suggestions.
Mechanism, terms and numbers722 words
FileDictionary reads a text file with one suggestion per line: the suggestion, optionally followed by fieldDelimiter and a weight, and fieldDelimiter and a payload. The default delimiter is a TAB, and two public constructors take any string "to separate out the fields in a line". The iterator splits each line with line.split(fieldDelimiter) (FileDictionary.java:133 and :167 on main 645d4fe14a20), and String.split compiles its argument as a regular expression. With "|" the valid line foo bar|10 splits into 10 one-character fields and getEntryIterator() throws IllegalArgumentException: More than 3 fields in one line; . throws ArrayIndexOutOfBoundsException, + and other lone metacharacters throw PatternSyntaxException, and the anchors $ and ^ never split, so every line silently becomes one suggestion such as foo bar$10$p1 with weight 1 and no payload. TAB and plain delimiters such as ,, ;, :: or " , " work. The regex split came with the configurable delimiter in LUCENE-5337 (2013, first released in 4.7.0); every release from 4.7.0 to 10.6.0 and main is affected. Regex-style delimiters such as "\\|" or the text backslash-t work today only because of this, so a literal-split fix is a behaviour change that needs a MIGRATE note; documenting regex semantics is the alternative.
- Contract. The class javadoc (
:30-59) defines an entry assuggestion,suggestion fieldDelimiter weightorsuggestion fieldDelimiter weight fieldDelimiter payload(:36-40), says the defaultfieldDelimiteris TAB (:42) and "An entry cannot have more than twofieldDelimiter" (:52).DEFAULT_FIELD_DELIMITER = "\t": "Tab-delimited fields are most common thus the default, but one can override this via the constructor" (:62-66). Both two-argument constructors use "fieldDelimiterto separate out the fields in a line" (:91-109) and store the string as given. - Split. The first line is split in the
FileIteratorconstructor,String[] fields = line.split(fieldDelimiter);(:133), every later line innext()the same way (:167).String.split(regex)compiles the argument as a regular expression and drops trailing empty strings. - Count. More than 3 fields throws
IllegalArgumentException("More than 3 fields in one line")(:134-135,:168-169). 3 fields are suggestion, weight, payload; 2 are suggestion, weight (parsed withLong.parseLong, thenDouble.parseDouble,:207-214); otherwisefields[0]is the suggestion and the weight is 1 (:144-146,:182-184).
- TAB,
,,;,::," , ",#,~and 10 more (no metacharacter: the regex matches only itself): parse as documented. |and||(alternations of empty patterns: they match the empty string between every two characters):foo bar|10gives 10 fields andIllegalArgumentException: More than 3 fields in one line(the same with||). With|, a 3-character line such asa|0givesNumberFormatExceptioninstead, and a short line whose second character is a digit loads silently wrong (a1becomesawith weight 1,a12becomesawith weight 1 and payload2)." | "("space or space": it matches each single space):foo bar | 10splits at every space into 4 fields,foo,bar,|,10, and throws the sameIllegalArgumentException;a | 0givesNumberFormatExceptionfor"|"..(any character: every field is empty and all are dropped): on any non-empty linefields[0]on an empty array throwsArrayIndexOutOfBoundsException(:145), even for a line without a delimiter.+,*,?,(,),[,{,\(not a valid pattern on its own):PatternSyntaxExceptionon the first line read, even without a delimiter (an empty file reads no line and loads).$,^(anchors at the line ends: they never split): no error; the whole line is the suggestion (foo bar$10$p1), weight 1, no payload, and a suggester built from it returns that key.
The *, ?, (, ), [, {, \, ^ and || cases come from the bounded-exhaustive harness only; the others were also executed by independent tests (" | " only by them, it is not among the harness's 30 delimiters). The fact check's per-delimiter probe later ran every delimiter named here on the stock main jar, with the same results.
Exposure and likelihood227 words
- Who is hit. Applications that build a suggester (
Lookup.build) from a text file throughFileDictionary(Reader, String)orFileDictionary(InputStream, String)with a delimiter that contains a regex metacharacter. Lucene itself has no caller ofFileDictionaryoutside its tests. Solr'sFileDictionaryFactoryhas passed the suggester'sfieldDelimiterparameter to this constructor unchanged since the same release (SOLR-5378, 4.7.0) and still does on current Solr main. - Default vs opt-in. Opt-in: the default TAB and delimiters without a metacharacter (
,,;,::," , ") are unaffected. - What goes wrong.
|(the likeliest such delimiter) makes a valid file with weights fail at build time with "More than 3 fields in one line" for a line with one delimiter (in the harness 27,927 of 27,930 valid files fail or load wrongly; the 3 others contain only the one-character suggestiona);.and+fail with low-level exceptions;$and^fail silently: every line becomes one suggestion that contains the weight and payload text, with weight 1 and no payloads. - Scale. None needed: one line is enough. Deterministic, assertions on or off.
- Workaround. Pass
Pattern.quote(d)or an escaped regex such as"\\|", or use TAB. - How likely. Plausible: whoever picks
|hits it on first use, which also makes it visible during development; the silent case needs the unusual$or^.
One JUnit method on the public API, in the suggest package like the upstream tests: a one-line file foo bar|10 read with new FileDictionary(reader, "|"). No randomness; fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest;

import java.io.IOException;
import java.io.StringReader;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestFileDictionaryPipeDelimiter extends LuceneTestCase {

  public void testPipeDelimiter() throws IOException {
    FileDictionary dictionary = new FileDictionary(new StringReader("foo bar|10\n"), "|");
    // expected: "foo bar" with weight 10; actual: IllegalArgumentException "More than 3 fields"
    InputIterator it = dictionary.getEntryIterator();
    assertEquals(new BytesRef("foo bar"), it.next());
    assertEquals(10, it.weight());
  }
}
cp $REPRO/TestFileDictionaryPipeDelimiter.java $LUCENE/lucene/suggest/src/test/org/apache/lucene/search/suggest/
cd $LUCENE && ./gradlew :lucene:suggest:test --tests org.apache.lucene.search.suggest.TestFileDictionaryPipeDelimiter -Ptests.seed=DEADBEEF
- Expected
- One entry: suggestion
foo barwith weight 10. - Observed
getEntryIterator()throwsIllegalArgumentException: More than 3 fields in one line(FileDictionary.java:135).
More files, environment, full output169 words
Copy the test into lucene/suggest/src/test/org/apache/lucene/search/suggest/ of a Lucene checkout and run it with gradle (command below). It fails before reaching its assertions: getEntryIterator() already throws. With the literal-split fix it passes unchanged, so it doubles as the regression test.
Executed: gradle on a fresh scratch worktree of 645d4fe14a20 (fails); the standalone runner on the main jars with -ea and -da (built from the hunt's 645d4fe14a20 checkout, whose only changes are untracked files) and on the 10.6.0 release jar (fails, same exception).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; also fails on the 10.6.0, 10.5.2 and 9.12.3 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (plain string handling, nothing platform-specific) |
cp $REPRO/TestFileDictionaryPipeDelimiter.java $LUCENE/lucene/suggest/src/test/org/apache/lucene/search/suggest/
cd $LUCENE && ./gradlew :lucene:suggest:test --tests org.apache.lucene.search.suggest.TestFileDictionaryPipeDelimiter -Ptests.seed=DEADBEEF
# gradle, main 645d4fe14a20, -Ptests.seed=DEADBEEF
TestFileDictionaryPipeDelimiter > testPipeDelimiter FAILED
    java.lang.IllegalArgumentException: More than 3 fields in one line
        at org.apache.lucene.search.suggest.FileDictionary$FileIterator.<init>(FileDictionary.java:135)
        at org.apache.lucene.search.suggest.FileDictionary.getEntryIterator(FileDictionary.java:114)
        at org.apache.lucene.search.suggest.TestFileDictionaryPipeDelimiter.testPipeDelimiter(TestFileDictionaryPipeDelimiter.java:29)

# standalone runner, seed DEADBEEF
main 645d4fe14a20  -ea / -da   tests_run=1 failures=1   same exception
10.6.0 -ea tests_run=1 failures=1 same exception- The javadoc treats the delimiter as text, "An entry cannot have more than two
fieldDelimiter", and never mentions regular expressions. - The upstream test builds its lines by appending the delimiter verbatim; its only custom delimiter,
" , ", has no metacharacter. - Before 4.7.0 the split was on a fixed TAB; the change that made it configurable never discussed regular expressions.
The full argument180 words
- Contract.
FileDictionary.java:30-59: the line grammarsuggestion fieldDelimiter weight fieldDelimiter payload, "An entry cannot have more than twofieldDelimiter" (:52); the constructors use it "to separate out the fields in a line" (:91-109); the default is a literal TAB character (:66). No javadoc, package doc,CHANGES.txtorMIGRATE.mdentry mentions regular expressions. Equally, nothing says the delimiter is literal. - Tests.
TestFileDictionary.generateFileEntryappends the delimiter verbatim (sb.append(fieldDelimiter),:41,:47) and expects the original fields back;testFileWithDifferentDelimiteruses" , "(:176-181). - History. Before LUCENE-5337 the code was
line.split("\t").99255ff0da68(2013-11-13, "Add Payload support to FileDictionary (Suggest) and make it more configurable", now #6401) replaced it withline.split(fieldDelimiter)and added the delimiter constructors. The issue asks "to let the users configure the field delimiter"; its 13 comments never mention regular expressions or escaping. An independent port, Lucene.NET'sFileDictionary, splits on the literal string. - Effect. Read as documented, a valid file with
|should load, and$should not fold weights and payloads into the suggestion text.
The devil's-advocate check194 words
The strongest case for "works as designed": regex semantics have been the actual behaviour since 4.7.0, and callers rely on them. "\\|" and "\\s*,\\s*" work today, and so does the two-character text backslash-t, which is how Solr's suggester guide writes the default: in an XML config it reaches FileDictionary as a backslash and a t and matches a TAB only because it is parsed as a regex (a 2016 solr-user config does this). A reliance test pins all three: it passes on main and 9.12.3 and fails 3 of 3 with the literal fix. SOLR-9368 resolved another FileDictionary format mismatch (comment lines) with a doc fix.
Why it fails: in SOLR-9368 the javadoc matched the code; here nothing documents regex semantics, every written description (javadoc, test generator, Solr guide wording, the Lucene.NET port) reads naturally as a literal delimiter, and nothing written suggests that | should break a valid file. The reliance limits the fix, not the finding: because callers depend on the regex behaviour, documenting it may well be the least disruptive resolution, not only a fallback; a literal split needs a MIGRATE note. Verdict: a defect, a mismatch between code and documentation.
Recommended Split on the literal delimiter (Pattern.LITERAL), with a MIGRATE note
Split on the literal delimiter: compile it once with Pattern.compile(fieldDelimiter, Pattern.LITERAL) and use fieldDelimiter.split(line) at both split sites (+6/-5 lines). The minimal test and the whole suggest test suite pass. Trade-off: regex-style delimiters such as "\\|" or the text backslash-t silently stop splitting, so it needs a MIGRATE note and fits the next major release.
private final Pattern fieldDelimiter;

public FileDictionary(Reader reader, String fieldDelimiter) {
  in = new BufferedReader(reader);
  this.fieldDelimiter = Pattern.compile(fieldDelimiter, Pattern.LITERAL);
}
// same in FileDictionary(InputStream, String)

String[] fields = fieldDelimiter.split(line); // was: line.split(fieldDelimiter), at :133 and :167
All options and trade-offs2 options · 369 words
Two options. The literal split was validated with gradle in a scratch worktree at 645d4fe14a20; the doc-only option changes no behaviour. A natural split: the literal split on main for the next major release with a MIGRATE entry, the doc fix on the 10.x branch.
Split on the literal delimiter (Pattern.LITERAL), with a MIGRATE note (validated by the checks) (recommended)
In FileDictionary.java, store the delimiter as a Pattern compiled with Pattern.LITERAL in both two-argument constructors and split with it at :133 and :167. Pattern.quote(fieldDelimiter) at the call sites is equivalent.
private final Pattern fieldDelimiter;

public FileDictionary(Reader reader, String fieldDelimiter) {
  in = new BufferedReader(reader);
  this.fieldDelimiter = Pattern.compile(fieldDelimiter, Pattern.LITERAL);
}
// same in FileDictionary(InputStream, String)

String[] fields = fieldDelimiter.split(line); // was: line.split(fieldDelimiter), at :133 and :167
Trade-offs
- Literal delimiters (TAB,
,," , ", ...) behave exactly as before. - Behaviour change for regex-reliant callers, and a silent one:
"\\t"(the text backslash-t, as Solr configs write the default),"\\|"and"\\s*,\\s*"stop splitting, and every line becomes one suggestion with weight 1 and no payload (a reliance test: 3 of 3 pass today, 3 of 3 fail with the fix). Hence a MIGRATE note and the next major release. - Side effect: the pattern is compiled once instead of on every line for delimiters that
String.splitdoes not fast-path.
What the checks validated
- Gradle, scratch worktree at
645d4fe14a20, JDK 25,-Ptests.seed=DEADBEEF: the minimal test passes unchanged andTestFileDictionarypasses 5 of 5;:lucene:suggest:checkGoogleJavaFormatpasses, and the whole:lucene:suggest:testsuite passes: 237 tests in 32 suites, 7 skipped, 0 failures. - Earlier shadow runs of the same diff: the finder's 4 tests and an independent reproducer's 6 tests pass, upstream
TestFileDictionary5 of 5.
State in the class and constructor javadoc that fieldDelimiter is a regular expression as in String.split, and that a literal delimiter such as | must be passed as Pattern.quote("|").
Trade-offs
No behaviour change, safe to backport; SOLR-9368 is a doc-fix precedent for this class. But the | trap and its misleading "More than 3 fields" message stay, only documented, and $/^ still mis-parse silently.
What the checks validated
Not executed (documentation only).
In Solr the delimiter is the suggester's fieldDelimiter setting, so a configuration with | fails the same way; the delimiter and the file are operator configuration, not user input.
A bounded-exhaustive comparison: every small suggestion file (1-3 lines) was read with 30 delimiters and compared with a simple parser that splits on the literal delimiter, as the javadoc describes. The 17 plain delimiters agreed on every file; the 13 with a regex metacharacter disagreed on nearly all. Code reading then found the String.split call.
The method in full193 words
Method: bounded-exhaustive translation validation (the hunt's semi-formal tier), in a hunt unit on whether suggest dictionaries preserve their (suggestion, weight, payload) tuples, run on the stock main jars at ea57360912ed.
- Every file of 1-3 lines over 3 suggestions x 4 weights (including none) x 3 payloads (including none; a payload only after a weight), 27,930 files per delimiter, for 30 delimiter strings (2,954 for the space delimiter: the harness skips files in which a suggestion or payload contains the delimiter, which happens only for the space, in the suggestion
a band the payloadq r). - Reference: a parser that splits each line on the literal delimiter text, following the class javadoc.
- Result: the 17 delimiters without a regex metacharacter (TAB, space,
,,;,::," , ",#,~, ...) agree on every file; the 13 with one ($ ( ) * + . ? [ \ ^ { | ||) disagree on 27,891 to 27,930 of 27,930 files each. - Code reading then located
line.split(fieldDelimiter), and the finding was reduced to a public-API JUnit test, later to the single test shown here.
No prior report found (2026-10-26, re-checked 2026-10-30) in GitHub issues, PRs and commits including the JIRA archive, the Lucene and Solr mailing lists, downstream projects or the web. Related only: LUCENE-5337 (#6401) introduced the configurable delimiter without discussing regex semantics; SOLR-9368 is a different format mismatch resolved by a doc fix.
Searches4 searches
Coverage limits: GitHub's search rate limit was saturated during the main search (most GitHub queries ran through issue/PR list search), and Stack Overflow pages were mostly not fetchable. Related, not this bug: #6401 (LUCENE-5337, the introducing change; description and 13 comments never mention regular expressions), SOLR-9368 (comment lines in FileDictionary files, Not A Bug, doc fix), SOLR-5683 and the Solr suggester guide (describe fieldDelimiter as a plain separator, default written as backslash-t), a 2016 solr-user config with backslash-t (relies on the regex parsing, does not discuss it), SOLR-11288 (String.split in Solr parameter parsing).
| Where | When | How | Found |
|---|---|---|---|
| Search tool (GitHub issues/PRs/commits incl. the JIRA archive, dev@, java-user@, issues@, commits@, solr-user@, downstream, web) | 2026-10-26 | two runs, 86 queries: FileDictionary, fieldDelimiter, the exception text, PatternSyntaxException, regex/escape/split phrasings | 0 high-overlap hits; none about this bug |
| GitHub (apache/lucene) and JIRA | 2026-10-26 | 26 manual issue/PR phrasings, 12 JQL queries | #6401, SOLR-9368, SOLR-5683, SOLR-11288: related, none the same bug |
| Open PRs and downstream repositories | 2026-10-26 | changed files of all 408 open apache/lucene PRs; Solr, Lucene.NET, Elasticsearch, OpenSearch | no PR touches FileDictionary.java; no downstream report |
| GitHub, re-check | 2026-10-30 | issue/PR search for FileDictionary, fieldDelimiter, FileDictionary delimiter regex, "More than 3 fields in one line"; open PRs mentioning FileDictionary; commits on FileDictionary.java | only #6401 and #7545 (unrelated); 0 open PRs; the file unchanged on upstream main 716d6f216f52 |
Introduced by LUCENE-5337 (99255ff0da68, 2013-11-13, first released in 4.7.0 through the branch_4x backport afdc5611a1c9), which made the delimiter configurable and replaced the fixed split("\t") with split(fieldDelimiter). Every release from 4.7.0 to 10.6.0 and main is affected.
Versions tested6 rows
Before the change the only delimiter was a hard-coded TAB, which has no metacharacter, so the regex split behaved like a literal one; the regex behaviour appeared once callers could choose the string. No later commit changed the split lines: git blame at 645d4fe14a20 assigns both to 99255ff0da68, and on main's history git log -S 'split(fieldDelimiter)' on the file finds only that commit (with --all it also lists the branch_4x backport afdc5611a1c9 and two side-branch commits, 527c6f350c5 and aad44bc6e36, that only move or delete the whole file). 110 release tags from 4.7.0 to 10.5.2 contain the change; releases between the executed points are affected by reading only. Old releases ran on JDK 25.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails (gradle; standalone -ea and -da) |
| 10.6.0 | affected | the minimal test fails |
| 9.12.3, 10.0.0, 10.5.2 | affected | the finder's JUnit fails 4 of 4 |
| 4.7.0 to 10.5.2 | 11 releases | a portable main() probe fails identically on 4.7.0 (-ea, -da), 4.10.4, 5.5.5, 6.0.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2 |
| 4.6.1 and older | not affected | no delimiter constructors; the fixed TAB format parses |
literal-split fix (scratch worktree at 645d4fe14a20) | not affected | the minimal test and the whole suggest suite pass (237 tests, 0 failures) |
An independent reproducer with its own tests and a different suggester, an intended-behaviour devil's advocate, a review by a model from another family (reading only), an adjudication and a fresh-seed registry re-run all confirm it; the history sweep and this doc's gradle runs add the version range and the fix check.
Checks and verdicts378 words
The cross-model reviewer could not run Java, so its refute-lens review voted not real at low confidence, on procedure only, while all its evidence items supported real; a re-run of the repro for each review failed (4 of 4). Among the verifiers' tests, the *, ?, (, ), [, {, \, unquoted ^ and || delimiters are covered only by the finder's bounded-exhaustive harness; the fact check's per-delimiter probe later ran all of them on the stock main jar, with the same results.
| Check | Verdict | What it found |
|---|---|---|
| finder (bounded-exhaustive harness) | candidate | 17 plain delimiters agree on every file, 13 metacharacter delimiters disagree on nearly all; its JUnit fails 4 of 4 on main (-ea, -da), 10.5.2 and 9.12.3. |
| cross-model review (OpenAI GPT-5.6, lenses, reading only) | refute: procedural "not real" (low); intended: real (high); root cause: real (medium) | Could not run Java; agreed on the root cause and that the inputs are in contract; strongest counter-argument (moderate): callers may rely on regex delimiters. |
| independent reproducer | real | Own 6-test JUnit with WFSTCompletionLookup end to end fails 6 of 6 on main (-ea, -da), 10.5.2 and 9.12.3; a Pattern.quote control passes 7 of 7; a literal-split shadow passes. |
| intended-behaviour devil's advocate | real (moderate) | Built the works-as-designed case and rejected it; its reliance test shows the literal fix changes regex-style delimiters (pass 3 of 3 today, fail 3 of 3 with the fix). |
| adjudication | confirmed (medium) | Re-ran the reproducer's JUnit (-ea, -da: 6 of 6 fail) and the finder's (4 of 4 fail); impact class wrong error. |
| registry re-run | keep | Fresh seeds: the finder's JUnit fails on main (-ea, -da) and 10.5.2 and passes with the fix; the reproducer's fails 6 of 6; the reliance test passes stock and fails with the fix. |
| history sweep | affected since 4.7.0 | Portable probe on 11 releases (4.7.0-10.5.2) and main; the 4.6.1 boundary pair. |
| this doc | gradle repro and fix check | The minimal test with gradle on a clean 645d4fe14a20 (fails) and with the literal-split fix (passes; the whole suggest suite, 237 tests, 0 failures); the minimal test on the 10.6.0 jar (fails). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 548 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,242 words
- Registry title
- FileDictionary treats its fieldDelimiter as a regular expression, so a delimiter such as '|', '.', '+' or '$' makes a valid suggestion file fail to load or silently mis-parse
- Area
- suggest / FileDictionary (text-file dictionary for Lookup.build)
- Priority
- Low, rank 622: A '|' delimiter makes FileDictionary fail loudly on first build with a misleading error (only the unusual '$' or '^' mis-parse silently), so it shows up during development and has an easy workaround, and it follows the runtime empty-key crash LFV-251 among the suggester rows.
- Impact class
- wrong error
- Impact note
- Only applications that give FileDictionary a non-default delimiter containing a regular-expression metacharacter are hit (directly through the two-argument constructors, or in Solr through the suggester's fieldDelimiter parameter), with no scale needed: the likeliest such delimiter, '|', makes every valid file fail at build time with a misleading 'More than 3 fields in one line', '.' and '+' fail with ArrayIndexOutOfBoundsException and PatternSyntaxException, and the unusual anchors '$' or '^' silently fold weight and payload into the suggestion text; the default TAB and plain delimiters such as ',', ';', '::' and ' , ' are unaffected.
- Summary
- You build a suggester from a text file with lines such as 'foo bar|10|p1', read with new FileDictionary(reader, "|"), and expect the entry (suggestion 'foo bar', weight 10, payload 'p1') that the class javadoc's line format describes. Instead FileDictionary passes the delimiter to String.split, which reads it as a regular expression: '|' (an empty alternation) splits between every character, so getEntryIterator() throws IllegalArgumentException 'More than 3 fields in one line'; '.' and '+' throw ArrayIndexOutOfBoundsException and PatternSyntaxException. With '$' or '^' no line is ever split, so every line silently becomes one suggestion such as 'foo bar$10$p1' with weight 1 and no payload, and a suggester built from it returns that key.
- Introduced
- 99255ff0da685e6727d08833ed1c7feca18525ce (trunk, svn r1541341) and its branch_4x backport afdc5611a1c9af803e90d0e3833c1f88d60274c0 (svn r1541360), LUCENE-5337 'Add Payload support to FileDictionary (Suggest) and make it more configurable' (now apache/lucene#6401; JIRA and svn patch era, no PR; patch by areek, committed by ErickErickson). It added the constructors FileDictionary(Reader, String) and FileDictionary(InputStream, String) and replaced line.split("\t") with line.split(fieldDelimiter) [read: git log -S 'split(fieldDelimiter)' finds only these two commits, and git blame -w -M -C assigns both split lines (main :133 and :167) to 99255ff0da6] [exec: on 4.6.1 the probe does not compile because the delimiter API is absent, while the pre-change control parses the fixed TAB format; 4.7.0 fails; between 4.6.1 and 4.7.0 only this change and a method rename touched the file; no commit-level build was made] (2013-11-13 (trunk 00:56:37 UTC, branch_4x 02:22:58 UTC))
- First affected version
- 4.7.0 [exec, -ea and -da; via the branch_4x backport; the trunk commit first ships in 6.0.0]; 4.6.1 and older are not affected [exec 4.6.1; read 4.5.1, 4.6.0]: the delimiter constructors do not exist there and the only delimiter is a hard-coded literal TAB
- Affected versions
- Every release from 4.7.0 through 10.5.2 (110 release tags [read]: git tag --contains gives 27 tags 4.7.0-5.5.5 via afdc5611a1c and 83 tags 6.0.0-10.5.2 via 99255ff0da6), 10.6.0 (released 2026-10-29; the doc's minimal test fails on its release jar [exec]) and main ea57360912ed. [exec] with a portable public-API probe, identical output on every one: 4.7.0 (-ea, -da), 4.10.4, 5.5.5, 6.0.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea, -da); the finder's JUnit fails 4 of 4 on 9.12.3, 10.0.0, 10.5.2 and main (-ea, -da); the independent reproduction's JUnit fails 6 of 6 on 9.12.3, 10.5.2 and main (-ea, -da). Releases between the executed points are affected by [read] only. Not fixed upstream: main a9779ef3c193 (2026-10-26) still calls line.split(fieldDelimiter) [read]. Executed only on aarch64 Linux with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check; also reached by code reading
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record, plus the finder's scripted prior-report search and the intended-behaviour check's targeted search): two scripted prior-report searches (GitHub issues, PRs and commits on apache/lucene; Elasticsearch, OpenSearch and Solr; the dev@, java-user@, issues@, commits@ and solr-user@ lists; LUCENE and SOLR JIRA; the web), 26 manual GitHub issue/PR phrasings (for example 'FileDictionary', 'fieldDelimiter', '"More than 3 fields in one line"', 'PatternSyntaxException', 'Pattern.LITERAL split'), 12 JQL queries, downstream repositories (apache/solr, apache/lucenenet, elastic/elasticsearch, opensearch-project/OpenSearch), and the changed files of all 408 open apache/lucene PRs (none touches FileDictionary.java). Related, not this bug: #6401 (LUCENE-5337, the introducing change; description and all 13 comments never mention regular expressions or escaping), SOLR-9368 (a different FileDictionary format mismatch, '#' comment lines, resolved Not A Bug by a doc fix), SOLR-5683 and the Solr suggester guide (describe fieldDelimiter as a plain separator, default written as backslash-t), a 2016 solr-user mail with a fieldDelimiter backslash-t config (de facto reliance on regex parsing, not a report), SOLR-11288 (String.split of configured values in Solr parameter parsing, different code). Coverage limits: GitHub's search rate limit was saturated (most GitHub queries ran through issue/PR list search), Stack Overflow pages mostly could not be fetched, 2 planned web queries stayed pending.
- Lucene commit tested
- main
645d4fe14a20(11.0.0-SNAPSHOT): the minimal test with gradle and with the standalone runner (-ea,-da), and the literal-split fix in a scratch worktree with the whole suggest test suite (237 tests, 0 failures); the 10.6.0 release jar (the minimal test fails). The hunt ran on mainea57360912ed, whereFileDictionary.javais identical, and on the 10.5.2 and 9.12.3 jars; the history sweep ran a portable probe on 11 releases from 4.7.0 to 10.5.2.FileDictionary.javais unchanged on upstream main716d6f216f52(2026-10-29).
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/FileDictionary.java:30-59 (at ea57360912ed) (class javadoc: line format 'suggestion fieldDelimiter weight fieldDelimiter payload', 'An entry cannot have more than two fieldDelimiter', TAB example), :62-66 (DEFAULT_FIELD_DELIMITER = "\t", 'Tab-delimited fields are most common'), :91-98 and :100-109 (constructors: 'Using fieldDelimiter to separate out the fields in a line'), :133 and :167 (line.split(fieldDelimiter)), :134-135 and :168-169 ('More than 3 fields in one line'), :144-146 (fields[0] on an empty split array)lucene/suggest/src/test/org/apache/lucene/search/suggest/TestFileDictionary.java:33-47 (at ea57360912ed) (generateFileEntry appends the delimiter verbatim, :41 and :47), :176-181 (testFileWithDifferentDelimiter, the only custom-delimiter test: ' , ', no metacharacter)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/FileDictionary.java:30-59, :62-66, :91-109, :127-149, :157-195, :207-214
- Who is affected
a Lucene main checkout (645d4fe14a20) grep: FileDictionary is referenced in lucene/*/src/java only by FileDictionary.java itself
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/FileDictionary.java:30-59, :62-66, :91-109a Lucene main checkout (645d4fe14a20) lucene/suggest/src/test/org/apache/lucene/search/suggest/TestFileDictionary.java:33-54 (generateFileEntry; sb.append(fieldDelimiter) at :41, :47), :176-181
- Diagrams
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/FileDictionary.java:133, :134-135, :145, :167
- TestFileDictionaryPipeDelimiter.java (lucene/suggest, package org.apache.lucene.search.suggest, 1 test):
repro/LFV-478/src/org/apache/lucene/search/suggest/TestFileDictionaryPipeDelimiter.java(33 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and an executed probe on the stock main jars (assertions on and off) and with the fix. The diagram uses the three-field line foo bar|10|p1 (13 regex fields); the minimal test uses the two-field line foo bar|10 (10 fields).
assets/LFV-478/bug.png(548 KB)