The dateRecognizer filter keeps only tokens that parse as a date. Its factory builds one java.text.DateFormat and passes the same object to the filter of every thread. DateFormat keeps its parse state inside itself and is not thread-safe, so two threads parsing at once corrupt each other's parse, and the exception escapes analysis.
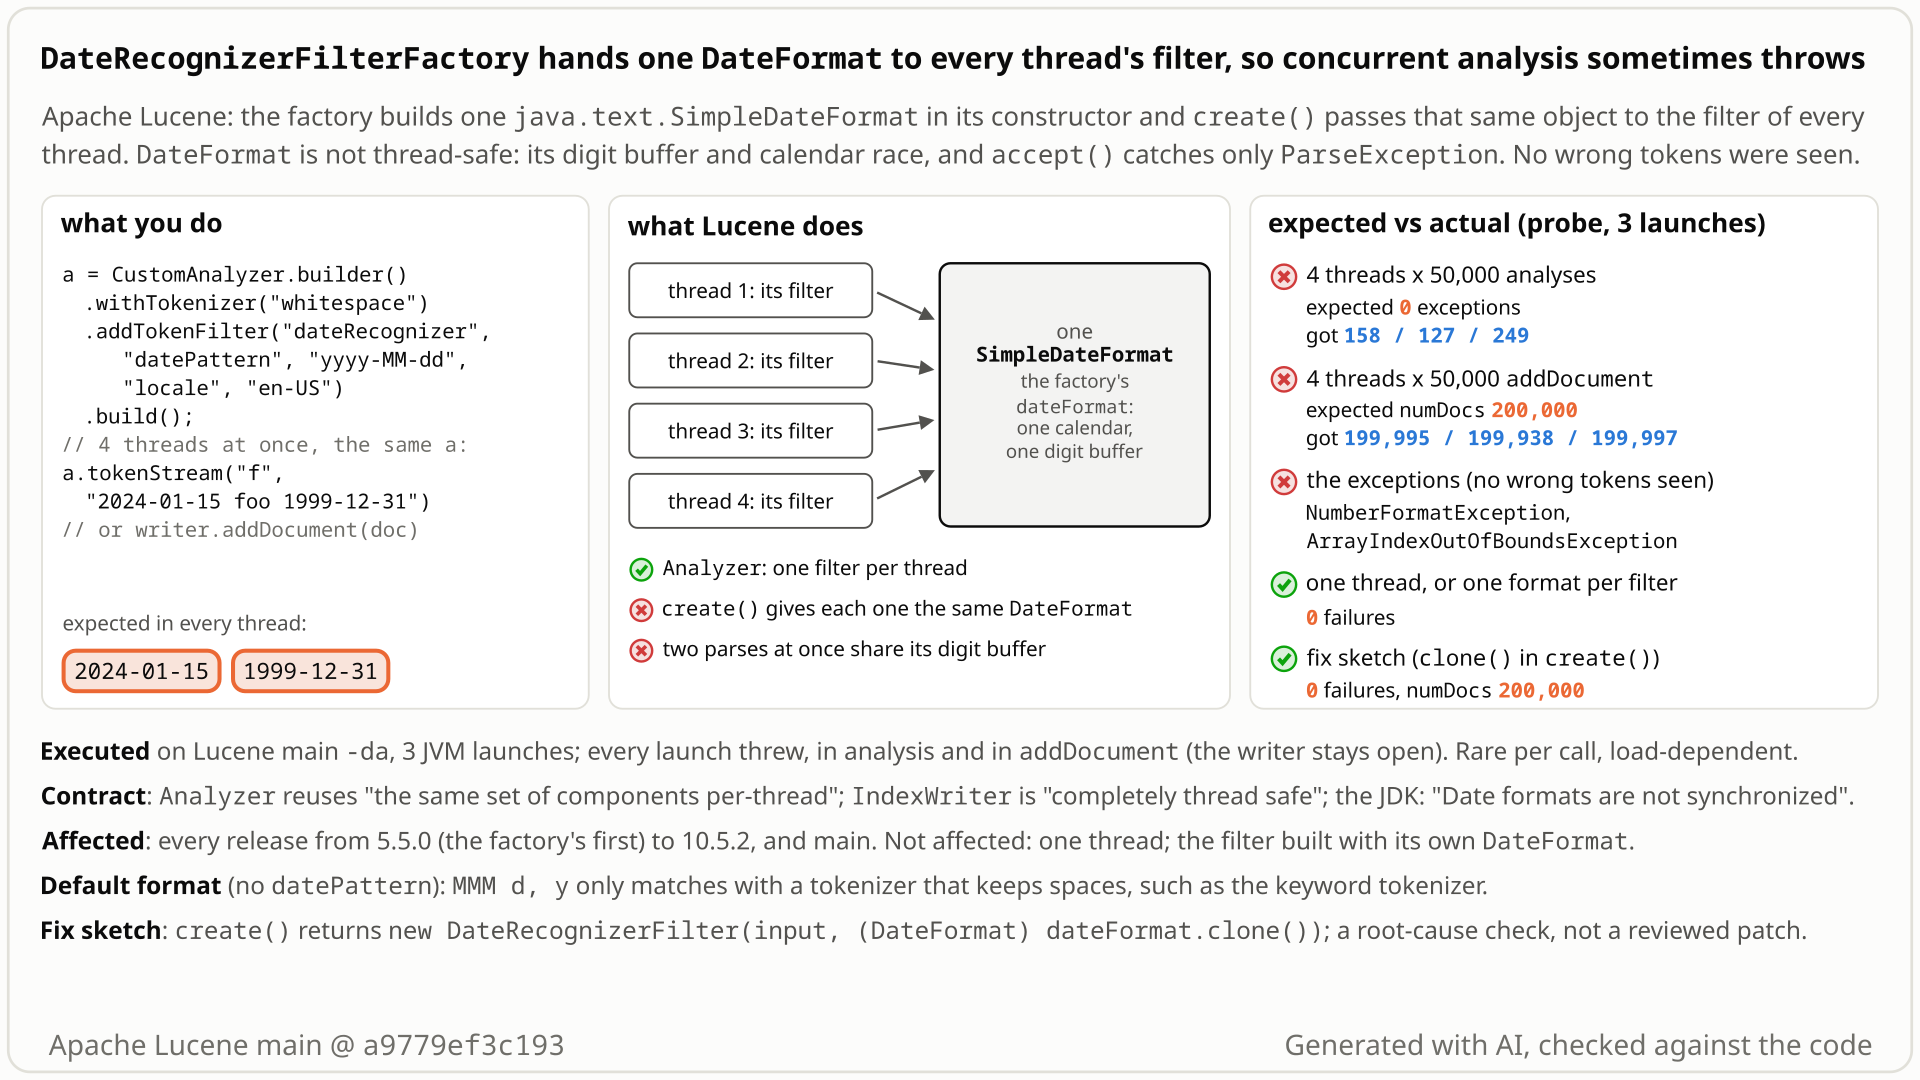
CustomAnalyzer with dateRecognizer, used by 4 threads), what Lucene does (4 filters, one shared SimpleDateFormat), and what happens on main: 127 to 249 of 200,000 analyses throw; one thread, one format per filter, or the clone fix give 0. Select the still to open it at full size. Generated with AI, checked against the code.- Build an analyzer with
CustomAnalyzer: the whitespace tokenizer plus thedateRecognizerfilter withdatePattern=yyyy-MM-dd, as the factory javadoc shows. On one thread,2024-01-15 foo 1999-12-31 bar 2001-07-04 baz 1970-01-01keeps the 4 dates. - Analyse that text from 4 threads at once with the same analyzer, as an
IndexWriter's indexing threads do. You expect the 4 dates every time:Analyzergives each thread its own copy of the filter. - Instead some analyses throw
NumberFormatException(multiple points,For input string: "202420024024E202420024024E4") orArrayIndexOutOfBoundsException: 127 to 249 of 200,000 analyses (4 threads x 50,000, the diagram probe's shorter text2024-01-15 foo 1999-12-31) per run on main, and a 4-thread test failed in 50 of 50 JVM launches. - The cause: the factory creates one
DateFormatand hands that same object to every thread's filter. Two parses at the same moment mix up its internal state, such as the digit buffer of its number parser, and the filter catches onlyParseException. - With
IndexWriter, thataddDocumentcall throws and the document is not indexed: 3 to 62 of 200,000 concurrent calls per run (the diagram probe), while the writer stays open. One thread, or the filter's public constructor with oneDateFormatper thread, works.
Applications that build an analyzer with the opt-in dateRecognizer factory (CustomAnalyzer, the SPI name or a Solr-style schema) and use it from more than one thread: any IndexWriter with several indexing threads, or concurrent query parsing. Ordinary dates trigger it, with assertions on or off, on every release since 5.5.0.
Mechanism, terms and numbers813 words
DateRecognizerFilterFactory (SPI name dateRecognizer) builds one java.text.DateFormat in its constructor (DateRecognizerFilterFactory.java:53, :60) and create() passes that same object to every DateRecognizerFilter it creates (:72-74). An Analyzer keeps one set of components per thread (Analyzer.java:91-96), so CustomAnalyzer calls create() once per thread on the same factory (CustomAnalyzer.java:161-168) and every thread's filter parses with the one shared format. The JDK documents DateFormat as not synchronized. When two threads parse at once, DateFormat.parse throws NumberFormatException (multiple points, For input string: "") or ArrayIndexOutOfBoundsException (and, in one launch each on 9.0.0 and 9.12.3, a single ClassCastException), and DateRecognizerFilter.accept() catches only ParseException (DateRecognizerFilter.java:50-61), so the exception escapes incrementToken(). With an IndexWriter, whose indexing threads share one analyzer, that addDocument throws and the document is not indexed; in every run with assertions off the writer stayed open. No special input or scale is needed, and it fails with assertions on and off. It fails on all 10 releases run, from 5.5.0 to 10.5.2, and on main; the code is unchanged since 5.5.0. Passing (DateFormat) dateFormat.clone() in create() fixes it; with that change all of :lucene:analysis:common:test passes (1,911 tests, 18 skipped, 0 failures).
DateRecognizerFilter: a token filter inlucene/analysis/commonthat keeps a token only if ajava.text.DateFormatcan parse it ("Filters all tokens that cannot be parsed to a date").DateRecognizerFilterFactorybuilds it by name (dateRecognizer) forCustomAnalyzeror a Solr-style schema, with optionaldatePatternandlocalearguments.- Per-thread components: an
Analyzerbuilds its tokenizer and filters once per thread and reuses them (Analyzer.java:91-96, aCloseableThreadLocal).CustomAnalyzerbuilds them by callingcreate()on the same factory objects in every thread (CustomAnalyzer.java:161-168). DateFormat: the JDK's date parser. Its class javadoc says: "Date formats are not synchronized. It is recommended to create separate format instances for each thread."
- The factory builds one format in its constructor:
private final DateFormat dateFormat;(DateRecognizerFilterFactory.java:53),this.dateFormat = getDataFormat(get(args, DATE_PATTERN));(:60).getDataFormat(:84-90) returns aSimpleDateFormatfordatePattern, elseDateFormat.getDateInstance(DateFormat.DEFAULT, locale). create()passes that same object to every filter:return new DateRecognizerFilter(input, dateFormat);(:72-74). The filter keeps the reference (DateRecognizerFilter.java:42-48).- So with an analyzer used by 4 threads, 4 filters share one
DateFormat. The state the race damages is mainly aCalendarand aNumberFormat, the two fieldsDateFormat.clone()deep-copies (JDK source;SimpleDateFormat.parsealso writes a few minus-sign fields in a one-time setup). The JDK'sDecimalFormatcollects the digits of each number field in one buffer and hands them toLong.parseLongorDouble.parseDouble, which is consistent with the garbled strings seen, such as202420024024E202420024024E4. accept()(DateRecognizerFilter.java:50-61) callsdateFormat.parse(...)and catches onlyParseException, so theNumberFormatExceptionorArrayIndexOutOfBoundsExceptionescapesincrementToken().- At index time an exception from the token stream is non-aborting: the document is marked deleted (
IndexingChain.java:1989-1994,DocumentsWriterPerThread.java:302-307),addDocumentthrows, and the writer stays open. At query time, building the query fails.
| configuration | result |
|---|---|
whitespace + datePattern=yyyy-MM-dd (the text plus the lenient date 2024-13-45), 4 threads x 50,000 analyses, 3 launches | 1,014 / 1,065 / 1,015 of 200,000 threw (mostly NumberFormatException, 22-83 ArrayIndexOutOfBoundsException) |
keyword tokenizer, no datePattern (default format), Jan 15, 2024, 4 threads x 50,000, 3 launches | 62 / 18 / 120 of 200,000 threw |
| the 4-thread JUnit (20,000 analyses per thread), 50 JVM launches per mode | 50 of 50 fail with assertions on, 50 of 50 off; the per-component control 0 of 50 |
the same JUnit through gradle on a9779ef3c193, -Ptests.iters=10 | 10 of 10 repetitions fail; the control passes 10 of 10 |
IndexWriter, 4 threads x 10,000 addDocument, assertions off | 15 calls threw (the first recorded: NumberFormatException); numDocs 39,985 of 40,000; writer open |
main a9779ef3c193, assertions off, 3 launches, the diagram probe's shorter text 2024-01-15 foo 1999-12-31: 4 threads x 50,000 analyses, then 4 x 50,000 addDocument | analyses: 158 / 127 / 249 threw; addDocument: 5 / 62 / 3 threw, numDocs 199,995 / 199,938 / 199,997, writer open; with the fix 0 and 200,000 |
| security probe, 2 runs, assertions off | 0 silent token changes in 9,558,115 analyses and 895,103 query builds: only exceptions (an observation on JDK 25, not a proof: a race that made a valid date throw ParseException would drop that token silently; none was seen) |
Single-threaded, the factory-built and the constructor-built analyzers give identical tokens. The exceptions are mostly NumberFormatException, then ArrayIndexOutOfBoundsException; the version sweep also saw one ClassCastException in one launch each on 9.0.0 and 9.12.3. With JDK system assertions on (-esa), a JDK-internal calendar AssertionError can fire instead and leave the shared calendar broken; that is a test-JVM artifact (-ea -dsa gives the same rates as -da).
Exposure and likelihood295 words
- Who is exposed. Users of the
dateRecognizerfactory: throughCustomAnalyzer, the SPI name, or a Solr-style schema such as the factory javadoc's own example. No Lucene analyzer adds it by default, and a read-only code search of Solr, Elasticsearch and OpenSearch found no default configuration that uses it. - What it takes. More than one thread using the analyzer:
IndexWriteris "completely thread safe" and its indexing threads share the one analyzer of its config (IndexWriter.java:167-168); concurrent query analysis does the same. No special input: withdatePattern, any date-shaped token can race; with nodatePattern, the default format needs a tokenizer that keeps spaces (keyword): a whitespace token has no ordinary space, so it does not matchJan 15, 2024(a date written with non-breaking spaces stays one token and does parse on JDK 25). - What the damage looks like. An unchecked exception reported to the caller: the document is rejected (marked deleted, other documents indexed, the writer stays open), or the query cannot be built. The caller can retry. No silent wrong tokens were seen. These are observations on JDK 25 with the tested configurations; another JDK could fail differently, for example with an
Error, on whichIndexWritercloses itself (IndexWriter.java:162-165). - Not affected. Single-threaded use, and the filter built through its public constructor with one
DateFormatper component. - Scale and rate. No data volume needed. Per operation it is rare: in the recorded runs that failed, from about 15 per million (3 of 200,000
addDocumentcalls) to 0.53% (1,065 of 200,000 analyses), depending on load and configuration, and some runs saw none. Even so, a 4-thread test fails in every launch. - How likely. Plausible (registry): ordinary multi-threaded use of an opt-in filter; no report in ten years.
The test shows that an analyzer built with DateRecognizerFilterFactory (via CustomAnalyzer) throws when two threads use it at once: every filter the factory creates gets the same java.text.DateFormat, which is not thread-safe.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import java.util.concurrent.atomic.AtomicReference;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.custom.CustomAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestDateRecognizerFactoryThreads extends LuceneTestCase {

  public void testTwoThreadsShareOneAnalyzer() throws Exception {
    Analyzer analyzer =
        CustomAnalyzer.builder()
            .withTokenizer("keyword")
            .addTokenFilter("dateRecognizer", "datePattern", "yyyy-MM-dd")
            .build();
    AtomicReference<Throwable> failure = new AtomicReference<>();
    Runnable analyse =
        () -> {
          try {
            for (int i = 0; i < 1_000; i++) {
              try (TokenStream ts = analyzer.tokenStream("f", "2024-01-15")) {
                ts.reset();
                while (ts.incrementToken()) {}
                ts.end();
              }
            }
          } catch (Throwable t) {
            failure.compareAndSet(null, t);
          }
        };
    Thread other = new Thread(analyse);
    other.start();
    analyse.run();
    other.join();
    analyzer.close();
    // expected: no exception (one filter per thread); actual: the shared DateFormat throws
    Throwable t = failure.get();
    if (t != null) {
      throw new AssertionError("expected no exception, but analysis threw " + t, t);
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-483/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestDateRecognizerFactoryThreads
- Expected vs actual
- Expected no exception (Analyzer gives each thread its own filter); actual
NumberFormatExceptionout ofSimpleDateFormat.parseinDateRecognizerFilter.accept(-ea and -da; needs two CPUs running the threads in parallel).
More files, environment, full output47 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected no exception, but analysis threw java.lang.NumberFormatException: multiple points
       org.apache.lucene.analysis.miscellaneous.TestDateRecognizerFactoryThreads.testTwoThreadsShareOneAnalyzer(TestDateRecognizerFactoryThreads.java:56)
     Caused by: java.lang.NumberFormatException: multiple points
       java.base/jdk.internal.math.FloatingDecimal.checkMultiplePoints(FloatingDecimal.java:2308)
       java.base/jdk.internal.math.FloatingDecimal.readJavaFormatString(FloatingDecimal.java:1909)
       java.base/jdk.internal.math.FloatingDecimal.parseDouble(FloatingDecimal.java:110)
       java.base/java.lang.Double.parseDouble(Double.java:971)
       java.base/java.text.DigitList.getDouble(DigitList.java:173)
[...]Analyzerkeeps "the same set of components per-thread", andIndexWritershares one analyzer across its threads:create()output is meant to run concurrently.- JDK: "Date formats are not synchronized." The factory hides its instance, so users cannot synchronize it.
PhoneticFilterFactorybuilds a new encoder percreate()("Must be thread-safe");DateToolskeeps per-thread copies.
The full argument282 words
create()output runs on many threads by design.Analyzer.java:93-96("reusing the same set of components per-thread"),CustomAnalyzer.java:161-168(onecreate()per thread on shared factories) andIndexWriter.java:167-168("completely thread safe, meaning multiple threads can call any of its methods, concurrently").- The JDK contract. "Date formats are not synchronized. It is recommended to create separate format instances for each thread. If multiple threads access a format concurrently, it must be synchronized externally." The factory creates the format privately and never exposes it.
- Lucene's tests expect it.
BaseTokenStreamTestCase.checkRandomDatarepeats the same analysis in 2-4 threads: "we do the EXACT same thing we did before in each thread, so this should only really fail from another thread if it's an actual thread problem" (BaseTokenStreamTestCase.java:1086-1089). The nightlyTestFactoriesruns it on every SPI factory it can build without arguments,dateRecognizerincluded, but behind a whitespace tokenizer, whose tokens practically never parse with the default format. - Sibling code.
PhoneticFilterFactory.getEncoder(): "Must be thread-safe." "Commons-Codec doesn't offer any thread-safe guarantees so we must play it safe and instantiate every time." (PhoneticFilterFactory.java:160-164, called fromcreate()).DateToolskeeps per-thread clones of its formats (DateTools.java:55-61;:192"should be cloned before use, since it's not threadsafe"). - Precedent. LUCENE-940 (#2015, 2007, "SimpleDateFormat used in a non thread safe manner") and LUCENE-6564 (#7622, 2015, the static shared
SimpleDateFormatofPrintStreamInfoStream) fixed a sharedSimpleDateFormatas a bug in other components. LUCENE-1472 (#2546) later replacedDateTools' synchronized shared formats with per-thread copies, for performance: those formats were already guarded by a lock. - No decision says otherwise. No javadoc restricts the factory to one thread. The introducing issue (LUCENE-6973, #8030, 40 comments) discusses locales and tests, never threads.
The devil's-advocate check187 words
The strongest case for "intended": (a) no javadoc on TokenFilterFactory or this factory promises that create() output is thread-safe, and Analyzer never says "thread-safe" in so many words; (b) the filter's two-argument constructor takes a caller-owned DateFormat, and the JDK says a shared one "must be synchronized externally", so sharing could be called the caller's problem; (c) the default configuration with a whitespace tokenizer practically never parses, so the affected configurations are narrow; (d) nobody reported it in ten years.
Why it fails: (a) the per-thread component design, IndexWriter's shared analyzer, the multi-threaded checkRandomData run on every factory it can build (this one included) and the PhoneticFilterFactory comment all strongly imply that create() output must survive concurrent use (no single javadoc sentence states it); (b) here Lucene's own factory creates the format and hides it, so the user cannot synchronize it; (c) the javadoc's own configuration uses a datePattern, which is enough; (d) the upstream tests never parse dates concurrently and the 2016 review never considered threads. The cross-model reviews, the devil's advocate and the adjudication all rated the intended-behaviour case weak or none.
Recommended A. Clone the DateFormat in create()
Clone the format in create(): return new DateRecognizerFilter(input, (DateFormat) dateFormat.clone());. Each thread's filter then gets its own copy. Validated: the new test passes 10 of 10 repetitions, all of :lucene:analysis:common:test passes (1,911 tests, 18 skipped, 0 failures), and so do the nightly TestFactories and check.
   @Override
   public TokenStream create(TokenStream input) {
-    return new DateRecognizerFilter(input, dateFormat);
+    // DateFormat is not thread-safe: give every filter (one per analysis thread) its own copy
+    return new DateRecognizerFilter(input, (DateFormat) dateFormat.clone());
   }
All options and trade-offs6 options · 610 words
Two options were applied in a scratch worktree of a9779ef3c193 and run through gradle: A with the new test, the module's tests, the nightly TestFactories and check; B with the DateRecognizer tests. The worktree was removed afterwards.
One line in DateRecognizerFilterFactory.create() (DateRecognizerFilterFactory.java:72-74). The factory keeps its instance as a template; every filter gets a deep copy.
   @Override
   public TokenStream create(TokenStream input) {
-    return new DateRecognizerFilter(input, dateFormat);
+    // DateFormat is not thread-safe: give every filter (one per analysis thread) its own copy
+    return new DateRecognizerFilter(input, (DateFormat) dateFormat.clone());
   }
Trade-offs
- One clone per
create()call, not per token or document. WithCustomAnalyzer(Analyzer's defaultGLOBAL_REUSE_STRATEGY) that is once per thread and analyzer;PER_FIELD_REUSE_STRATEGYbuilds one chain per thread and field, and direct callers of the factory get one copy per call. DateFormat.clone()deep-copies the calendar and the number format, andSimpleDateFormat.clone()the date format symbols, so the copies do not share the calendar and number-format state that parsing changes (the compiled pattern and the century-start date stay shared; parsing does not change them). This holds for the formats the stockgetDataFormatbuilds; an override that returns a customDateFormatneeds aclone()that copies its mutable state.- An invalid
datePatternstill fails when the factory is built.
What the checks validated
TestDateRecognizerFactoryThreadspasses with assertions off and on, and all 10 repetitions with-Ptests.iters=10; withTestDateRecognizerFilterandTestDateRecognizerFilterFactory: 5 tests, 0 failures (stock: 1 failure).- All of
:lucene:analysis:common:testwith assertions on: 340 classes, 1,911 tests, 18 skipped, 0 failures, 0 errors. TestFactorieswith-Ptests.nightly=truepasses.:lucene:analysis:common:check -x testpasses (checkGoogleJavaFormat,ecjLint,forbiddenApis), with the new test file.- Earlier: the finder's test, the independent reproducer's 5 tests (
numDocs40,000 of 40,000) and anIndexWritertest pass with the same change; the adjudication's re-run passed 5 of 5.
Keep the pattern instead of the format, call getDataFormat(datePattern) in create(), and call it once in the constructor too so an invalid pattern still fails early.
Trade-offs
With the stock getDataFormat the same effect as A, with a few more changed lines and a little more work per create() (the pattern is parsed again). B calls a subclass's override of getDataFormat on every create(), while A clones the result the constructor got from it; an override that returned the same instance every time would bring the race back under B, not under A.
What the checks validated
TestDateRecognizerFactoryThreads,TestDateRecognizerFilterandTestDateRecognizerFilterFactorypass with assertions off and on (5 tests, 0 failures). The module suite,checkand repetitions were run only for A.
this.dateFormat = (DateFormat) dateFormat.clone() in DateRecognizerFilter.java:42-48.
Trade-offs
Also protects callers of the public two-argument constructor who share one instance, but changes that constructor's semantics (the filter no longer uses the caller's object). A design decision; not tried.
Lock the shared format around parse in accept().
Trade-offs
Serializes every analysis thread on one lock; Lucene replaced exactly that in DateTools with per-thread copies (LUCENE-1472). A ThreadLocal would work, but a copy per filter already is one per thread.
Treat any exception from parse as "not a date".
Trade-offs
Turns the race into silent dropping of valid dates, which is worse than an exception.
The JDK's immutable, thread-safe alternative.
Trade-offs
An API change (the public constructor takes a DateFormat) and different, stricter default parsing; not a bug fix.
An application that shares one analyzer with this filter across request threads, as IndexWriter does across its indexing threads, would reject documents and fail queries the same way (inferred from the code; no downstream product was run).
A static inventory of every analysis factory's constructor and create() flagged that this factory hands an object it owns to every filter. A concurrency differential over 210 factory configurations, single-threaded versus 3-8 threads on one analyzer, then found it as the only mismatch; the finder reduced it by hand to a public-API test.
The method in full147 words
Method: a concurrency stress differential (registry tier semi-formal: a hypothesis from a static inventory, witnessed by a differential, not by a formal tool).
- The hunt unit compared every SPI analysis factory with the public constructor it wraps. A static inventory extracted the constructor and
create()bodies of all 167 SPI factory registrations; reading the factory fields showed thatDateRecognizerFilterFactorypasses one factory-ownedDateFormatto every filter. - A concurrency differential then ran every constructible factory configuration (210) on the stock main jars: the tokens of a single-threaded run against 3-4 concurrent threads on the same analyzer locally, and 8 on separate build machines. 209 configurations were clean; this was the only mismatch.
- The finder reduced it to the public-API JUnit with a per-component control, measured the hit rate (50 of 50 JVM launches with assertions on and off) and the exception kinds, and checked the one-line clone fix.
No prior report found (searched 2026-10-26): GitHub issues, PRs and commits, the changed files of all 409 open apache/lucene PRs, JIRA, the Lucene and Solr mailing lists, Solr, Elasticsearch, OpenSearch and the web. The introducing issue #8030 never mentions threads; LUCENE-940 fixed the same bug class elsewhere in 2007.
Searches5 searches
No report was found of DateRecognizerFilterFactory sharing one DateFormat, or of concurrent-analysis failures of DateRecognizerFilter. Searches cannot prove absence.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search, two runs | 2026-10-26 | 14 GitHub, 3 commit, 2 downstream, 16 mailing-list and 3 JIRA queries; then 11 GitHub, 3 commit, 3 downstream, 20 mailing-list, 4 JIRA and 6 web queries (getDataFormat, dateRecognizer, "multiple points", ArrayIndexOutOfBoundsException) | no high-overlap hit; the medium hits are the related items below |
| GitHub (manual) | 2026-10-26 | each class name in apache/lucene, apache/lucene-solr, apache/solr, elastic/elasticsearch and opensearch-project/OpenSearch; bug-class variants (SimpleDateFormat thread / clone, factory thread safety) | only #8030 (introducing issue) and #9563 (unrelated TestRandomChains failure) |
| Open apache/lucene PRs | 2026-10-26 | the changed files of all 409 open PRs | only #16911 (branch_10x decommission) touches the DateRecognizer files |
| JIRA and mailing lists | 2026-10-26 | JIRA REST over all projects; lists.apache.org: dev@, java-user@, issues@, commits@, the old and new Solr lists | no report; LUCENE-6973 and LUCENE-8517 only |
| Related items (read) | 2026-10-26 | #8030 (all 40 comments), #2015 (LUCENE-940), #7622 (LUCENE-6564), #2546 (LUCENE-1472), #11955 | #2015 and #7622: the same bug class (a shared SimpleDateFormat) fixed as bugs in other components; #2546: DateTools' lock-guarded shared formats replaced with per-thread copies for performance (an enhancement, not a thread-safety fix); #11955 states the one-object-per-token-stream rule |
Introduced with the factory in 5.5.0 (LUCENE-6973, 073dbdc17e3 and backport 1ff4e84f89f, 2016-01-15) and unchanged since. A version-portable repro fails 3 of 3 launches on each of 10 releases from 5.5.0 to 10.5.2 and on main; 5.4.1 has no such factory. Not fixed upstream.
Versions tested9 rows
Introduced by LUCENE-6973 "Improve TeeSinkTokenFilter" (migrated as #8030; SVN era, no pull request): trunk 073dbdc17e3 and branch_5x backport 1ff4e84f89f, both 2016-01-15. It added DateRecognizerFilter (replacing sinks/DateRecognizerSinkFilter, which took a caller-supplied format and had no factory) and DateRecognizerFilterFactory with the single DateFormat field. git blame attributes the field, the assignment and create() on main to it; later commits changed only imports, javadoc (markup, @since, @lucene.spi), the SPI name, the default constructor, formatting, a catch variable and the file mode. javap -c of create() in every executed jar passes the field without a clone (transcript re-run for this doc). Main a9779ef3c193 and branch_10x still share the instance.
All runs used JDK 25 on aarch64 Linux; rates under the JDKs of each release era were not measured. 8.9-8.11 come from the lucene-solr repository and were checked through 8.11.4 only.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the new test fails through gradle (assertions off and on); 10 of 10 repetitions fail |
main ea57360912ed | affected | history repro fails 3 of 3 (385-440 bad of 200,000); every hunt and verifier JUnit fails |
| 10.5.2, 10.0.0 | affected | history repro fails 3 of 3 (314-1,127 bad of 200,000); JUnit tests fail on 10.5.2 |
| 9.12.3, 9.0.0 | affected | history repro fails 3 of 3 (146-796 bad of 200,000); JUnit tests fail on 9.12.3 |
| 8.11.4, 7.7.3, 6.6.6, 6.0.0 | affected | history repro fails 3 of 3 (139-712 bad of 200,000) |
| 5.5.5, 5.5.0 | first release | history repro fails 3 of 3 (188-771 bad of 200,000) |
| 5.4.1 | no such API | the factory does not exist (compile error); only DateRecognizerSinkFilter with a caller-supplied format |
| per-component control, every version | not affected | passes 3 of 3 everywhere |
fix A on a9779ef3c193 | not affected | the new test passes 10 of 10 repetitions; the module's 1,911 tests pass |
An independent reproducer, an intended-behaviour devil's advocate and an adjudication each re-ran it with their own tests and confirmed it; reviews by a reviewer from another model family (OpenAI GPT-5.6, reading only) agreed on the root cause. A credibility audit kept it, and this doc's gradle run validated the fix.
Checks and verdicts408 words
Every executed check ran public-API tests on the stock jars; the run records are in the sources. Neither GPT review executed code, so all execution evidence comes from the other checks and the harness. The hunt's checks ran on main ea57360912ed, whose DateRecognizer, Analyzer, CustomAnalyzer and IndexWriter sources are identical to a9779ef3c193's.
| Check | Verdict | What it found |
|---|---|---|
| cross-model review | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: root cause agrees, fix fixes it, trigger legal, intended-behaviour argument none; warned not to claim silent wrong tokens. |
| Independent reproducer | real | Own 5-test JUnit fails on main (assertions on and off), 10.5.2 and 9.12.3; 18 of 20 repetitions fail (control 0 of 20); 15 of 40,000 addDocument calls threw; passes with the fix. |
| Cross-model works-as-designed review | real (medium) | Reading only; intended case weak, medium only because it could not run code. The refute-lens run gave no verdict. The executed checks recorded with it: an IndexWriter test threw in 122 of 20,000 calls and passes with the fix. |
| Intended-behaviour devil's advocate | real (high) | Built the strongest "intended" case and rejected it; its 2-thread IndexWriter test fails on main and 10.5.2 while the control indexes all 40,000 documents. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's test with a new seed, assertions off: 2 of 5 fail (108 of 480,000 analyses threw); 5 of 5 pass with the fix. |
| Credibility audit | keep | Fresh seed: the finder's test fails on main, passes with the fix; a committer would accept it as a regular public issue, pitched as rare exceptions, not data loss. |
| This doc's validation | reproduces; fix A validated | Gradle on a9779ef3c193: the new test fails on stock (10 of 10 repetitions) and passes with fix A; the module's 1,911 tests, the nightly TestFactories and check pass with it; fix B passes the DateRecognizer tests. |
| Fact checks of this doc | bug confirmed; wording corrected | An independent fact check re-ran the test through gradle on a clean a9779ef3c193 (fails with assertions off and on; 10 of 10 factory repetitions fail, the control passes; with fix A 50 tests, 0 failures), a cross-model fact check by OpenAI GPT-5.6 (reading only) and a diagram check found the bug, the repro and the fix sound. They asked for one precedent correction (LUCENE-1472 was not a fix of this bug class) and precision fixes in the wording. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 504 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,473 words
- Registry title
- DateRecognizerFilterFactory gives every filter it creates the same java.text.DateFormat, so an analyzer built from it throws NumberFormatException or ArrayIndexOutOfBoundsException when several threads analyse text at the same time
- Area
- analysis / analysis-common miscellaneous filters (DateRecognizerFilterFactory, DateRecognizerFilter)
- Priority
- Medium, rank 230: Ordinary multi-threaded indexing or query analysis with the opt-in dateRecognizer factory sometimes throws and leaves that document unindexed, which is plausible in use but loud.
- Impact class
- crash
- Impact note
- Applications that build an analyzer with the opt-in dateRecognizer factory (CustomAnalyzer, the SPI name, or a Solr-style schema as in the factory javadoc) and use it from several threads at once, that is concurrent IndexWriter indexing threads or concurrent query-time analysis, get occasional unchecked NumberFormatException or ArrayIndexOutOfBoundsException out of analysis on ordinary date tokens: that addDocument call throws and the document is not indexed (the writer stays open with -da), or the query cannot be built; it needs no scale and no special input, happens with -ea and -da on default JVM settings, and is in every release since 5.5.0. Each analysis fails rarely (from a few per million to about 0.5% of analyses, depending on load and configuration), but the finder's 4-thread JUnit failed in 50 of 50 JVM launches with -ea and with -da, and the 4-thread x 50,000-analysis history repro in 3 of 3 launches on every release tried. The default format (no datePattern) is reached only with a tokenizer that keeps spaces, such as the keyword tokenizer. No silent wrong tokens were seen. Single-threaded use, and the filter built through its public constructor with its own DateFormat, are not affected.
- Summary
- You build an analyzer with CustomAnalyzer from a whitespace tokenizer and the dateRecognizer filter (datePattern=yyyy-MM-dd, locale=en-US) and analyse text such as '2024-01-15 foo 1999-12-31' from four threads at once, as IndexWriter does with its indexing threads. You expect every thread to get the same date tokens as a single-threaded run, because Analyzer gives each thread its own set of token stream components. Instead some analyses throw NumberFormatException ('multiple points', 'For input string: ""') or ArrayIndexOutOfBoundsException, because DateRecognizerFilterFactory creates one java.text.DateFormat, which is not thread-safe, and create() passes that same instance to the filter of every thread.
- Introduced
- 073dbdc17e31708077dadbfb316220f76d7b10df (LUCENE-6973 'Improve TeeSinkTokenFilter', migrated as apache/lucene#8030, Shai Erera; trunk svn r1724789, SVN era, no pull request) and its branch_5x backport 1ff4e84f89f804998d7f6f9486bc9dcb692e5846 (svn r1724795), which shipped in 5.5.0. It added DateRecognizerFilter (replacing sinks/DateRecognizerSinkFilter, which took a caller-supplied DateFormat and had no factory) and DateRecognizerFilterFactory with the single DateFormat field [read: git log --follow on the factory starts at 073dbdc17e3; git blame -w -M -C attributes the field (:53), the constructor assignment (:60) and create() (:72-74) on main to it; git log --all -S 'new DateRecognizerFilter(input, dateFormat)' finds only the two LUCENE-6973 commits plus two whole-tree deletions on retired side branches]. Not a regression: the sharing is in the factory's first version, and git diff -w 5.5.0..main shows only imports, the SPI NAME, the throwing default constructor (LUCENE-8778, LUCENE-9281), formatting and the catch variable name (2016-01-15 (trunk 073dbdc17e3 and branch_5x 1ff4e84f89f the same day; first released in 5.5.0))
- First affected version
- 5.5.0 [exec, -da: the factory repro fails in 3 of 3 JVM launches, 188 / 286 / 771 bad analyses per 200,000, while the per-component control passes] (the first release with DateRecognizerFilterFactory; 5.4.1 has no such API [exec: compile error] and only sinks/DateRecognizerSinkFilter, whose caller supplies the DateFormat); 6.0.0 [exec] on the trunk line
- Affected versions
- every release from 5.5.0 through 10.5.2 and main ea57360912ed; never fixed. [exec, follow-up version-portable main() repro, -da, 3 JVM launches each, JDK 25] 5.5.0, 5.5.5, 6.0.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main: the factory-built analyzer fails 3 of 3, the per-component control passes 3 of 3; -ea -dsa on 5.5.0 and main gives the same rates as -da; the finder's JUnit fails on main (-ea and -da) and on 9.12.3 and 10.5.2 (-ea), the independent reproduction's JUnit on 9.12.3, 10.5.2 and main (-ea and -da), the intended-behaviour check's IndexWriter JUnit on main (-ea, -da) and 10.5.2 (-ea). [read] javap of create() in every executed jar shows getfield dateFormat passed straight to the filter, with no clone; the other releases have the same source (git diff -w 5.5.0..main); 8.9-8.11 come from the separate lucene-solr repository and were checked through 8.11.4 only. Upstream main a9779ef3c193 and branch_10x still pass the shared instance [read, 2026-10-26]. Every target ran on JDK 25 (aarch64): the Lucene-side sharing is identical in every release, but rates and exception types under the JDKs current at each release (Java 7/8 for 5.x) were not measured
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading; also reached by stress
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record, verdict new): two scripted prior-report searches (GitHub issues, PRs and commits, Solr, Elasticsearch and OpenSearch, the dev@, java-user@, issues@ and commits@ lists plus the old and new Solr lists, the JIRA archive and the web), manual GitHub searches of each class name in apache/lucene, apache/lucene-solr and the downstream repositories, JIRA REST and lists.apache.org queries, and the changed files of all 409 open apache/lucene PRs (only #16911, the branch_10x decommission, touches DateRecognizerFilter*.java). Related, not this bug: #8030 (LUCENE-6973, the introducing issue; its 40 comments never discuss threads), #9563 (LUCENE-8517, unrelated TestRandomChains failure), #2015 (LUCENE-940, 2007), #7622 (LUCENE-6564) and #2546 (LUCENE-1472): the same class of bug (a shared SimpleDateFormat) fixed in other components; open PR #11955 (OpenNLP factory thread safety, another module). Not fixed upstream (main a9779ef3c193 and branch_10x unchanged). GitHub's search rate limit was reached
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree, removed afterwards: the new test on stock (fails with assertions off and on; 10 of 10 repetitions with-Ptests.iters=10, control 10 of 10 pass) and with fix A (passes, 10 of 10 repetitions with-Ptests.iters=10; all of:lucene:analysis:common:test; the nightlyTestFactories;:lucene:analysis:common:check -x test), fix B with the DateRecognizer tests. The hunt's and the verifiers' JUnit tests on mainea57360912ed(the factory, filter,Analyzer,CustomAnalyzerandIndexWritersources are identical toa9779ef3c193's), 10.5.2 and 9.12.3; a version-portablemain()repro on the Maven Central jars 5.5.0, 5.5.5, 6.0.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2 and on main (5.4.1: no such factory). JDK 25, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DateRecognizerFilterFactory.java:26-44 (at ea57360912ed) (javadoc: Solr example with datePattern and locale, no thread restriction), :53 (private final DateFormat dateFormat), :60 (built once in the constructor), :72-74 (create() returns new DateRecognizerFilter(input, dateFormat)), :84-90 (getDataFormat: new SimpleDateFormat or DateFormat.getDateInstance)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DateRecognizerFilter.java:42-48 (at ea57360912ed) (stores the supplied DateFormat by reference), :51-61 (accept() calls dateFormat.parse and catches only ParseException)lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:91-96 (at ea57360912ed) (CloseableThreadLocal storedValue; 'reusing the same set of components per-thread'); lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:161-168 (createComponents calls filter.create(ts) on the shared factories); lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:167 ('completely thread safe')lucene/test-framework/src/java/org/apache/lucene/tests/analysis/BaseTokenStreamTestCase.java:1086-1088 (at ea57360912ed) (multi-threaded checkRandomData: 'this should only really fail from another thread if it's an actual thread problem'); lucene/analysis/phonetic/src/java/org/apache/lucene/analysis/phonetic/PhoneticFilterFactory.java:160-164 ('Must be thread-safe', instantiate every time)
- The finding in 30 seconds
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DateRecognizerFilterFactory.java:26-44 (javadoc), :53, :60, :72-74, :84-90a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DateRecognizerFilter.java:26, :42-48, :51-61a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:91-96; lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:161-168a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1989-1994; lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:302-307JDK 25 src.zip java.base/java/text/DateFormat.java:147-153 (Synchronization), :867-873 (clone copies calendar and numberFormat); java/text/DigitList.java:168-203, :790-798 (reused StringBuilder for parseLong/parseDouble)JDK 25 src.zip java.base/java/text/SimpleDateFormat.java:1502, :2577-2598 (checkNegativeNumberExpression, called from parse)
- Who is affected
a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:167-168a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DateRecognizerFilterFactory.java:29-36 (Solr-style example)a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:162-165 (on an Error the writer closes itself)
- Why it looks unintended
a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:93-96; lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:161-168; lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:167-168a Lucene main checkout (a9779ef3c193) lucene/test-framework/src/java/org/apache/lucene/tests/analysis/BaseTokenStreamTestCase.java:1086-1089; lucene/analysis/common/src/test/org/apache/lucene/analysis/core/TestFactories.java:51-57, :88-101, :136-139, :155-159a Lucene main checkout (a9779ef3c193) lucene/analysis/phonetic/src/java/org/apache/lucene/analysis/phonetic/PhoneticFilterFactory.java:160-164, :179-181; lucene/core/src/java/org/apache/lucene/document/DateTools.java:55-61, :192JDK 25 src.zip java.base/java/text/DateFormat.java:147-153
- Suggested fix
JDK 25 src.zip java.base/java/text/DateFormat.java:867-873 (clone), :154-155 (apiNote: DateTimeFormatter)JDK 25 src.zip java.base/java/text/SimpleDateFormat.java:2446-2449 (clone copies formatData only), :507, :537 (compiledPattern, defaultCenturyStart); a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:468-510 (reuse strategies)
- History
a Lucene clone release tags (git tag --contains 1ff4e84f89f: releases/lucene-solr/5.5.0)
- TestDateRecognizerFactoryThreads.java (JUnit test):
repro/LFV-483/src/org/apache/lucene/analysis/miscellaneous/TestDateRecognizerFactoryThreads.java(59 lines)
Summary card (bug.png). The numbers come from the diagram probe (main a9779ef3c193, assertions off, 3 launches, stock and fix), which analyses the shorter text 2024-01-15 foo 1999-12-31. An independent diagram check compared every frame with the code, the JDK sources and the probe traces.
assets/LFV-483/bug.png(504 KB)