ConcatenatingTokenStream joins several token streams into one field. Since 7.7.0 it carries the hole a source ends with (for example a stop word removed at its end) over to the first token of the next source. A source that produces no tokens breaks that carry-over.
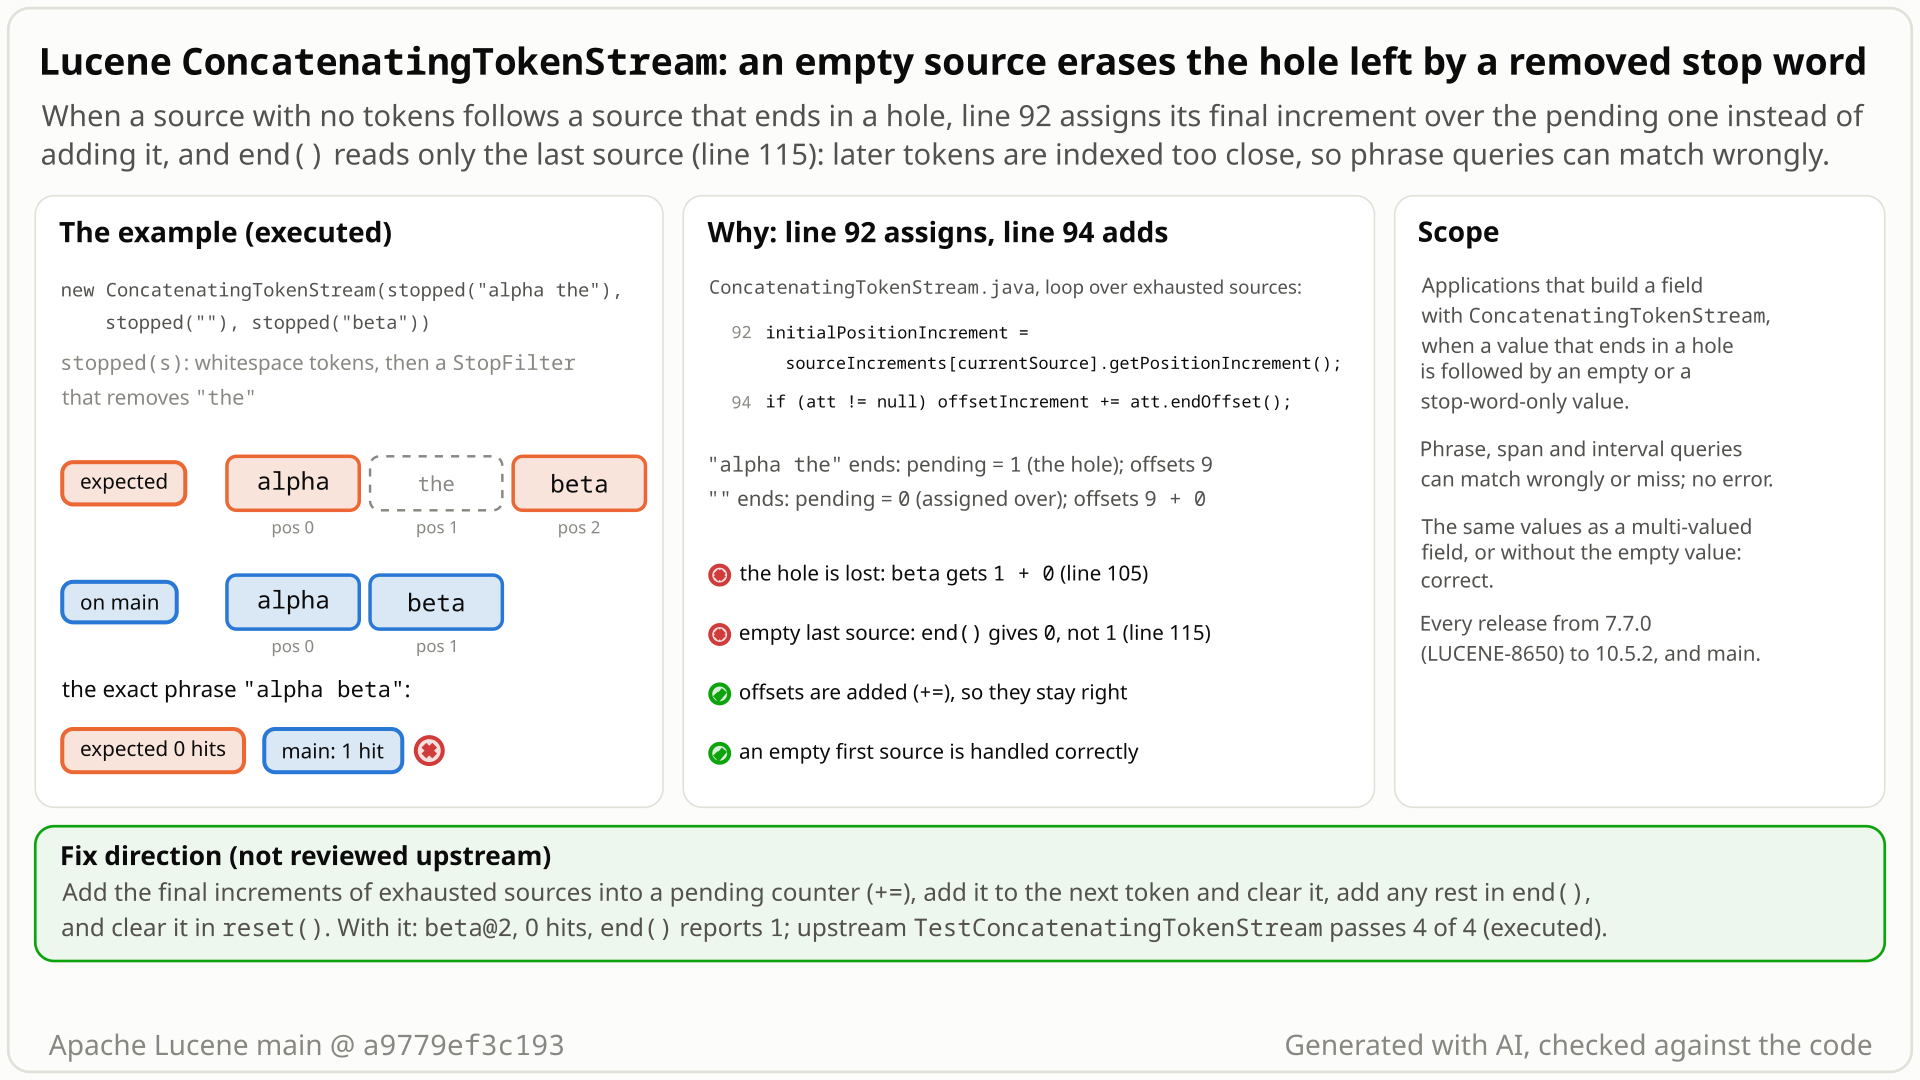
beta lands right after alpha and the exact phrase matches. The summary card adds the cause, the scope and the fix direction. Select the still to open it at full size. Generated with AI, checked against the code.- You build one field from three values with
new ConcatenatingTokenStream(...):"alpha the",""and"beta", each throughWhitespaceTokenizerand aStopFilterthat removesthe. The first value ends in a hole: itsend()reports a final position increment of 1. - You expect
betaat position 2, two steps afteralphaat 0. That is what you get without the empty value, and what the same three values give as a multi-valued field. - You get
betaat position 1. The loop that skips finished sources stores each one's final increment with=(line 92), so the empty value's 0 overwrites the pending 1. Offsets in the same loop are added with+=and stay right. - So the exact phrase
"alpha beta"gets 1 hit instead of 0. If the empty value comes last,end()reports 0 instead of 1. No error, andCheckIndexis clean. - It is the case LUCENE-8650 (7.7.0) missed when it added the carry-over: every release from 7.7.0 to 10.5.2 and main. Run with assertions on at 8 releases and main, and with them off on 9.12.3, 10.5.2 and main.
Applications that build a token stream with new ConcatenatingTokenStream(...), usually one field from several values, and can pass an empty or stop-word-only value after a value that ends in a removed word. Phrase, span and interval queries on that field see the later tokens too close. The class has no factory, no in-tree caller and no known downstream use.
Mechanism, terms and numbers734 words
ConcatenatingTokenStream joins several token streams into one field. Since LUCENE-8650 (7.7.0) it carries each source's final position increment, for example the hole left by a stop word that a StopFilter removed at the end of a value, over to the first token of the next source. It stores that increment with an assignment for every finished source (ConcatenatingTokenStream.java:92), while the same loop adds offsets (:94), and end() reads only the last source (:115). So a source that emits no tokens, such as an empty value or one made only of stop words, overwrites the pending hole, and an empty last source makes end() report 0. With the values "alpha the", "" and "beta", beta is indexed at position 1 instead of 2 (the multi-valued field and the concatenation without the empty value give 2), and the exact phrase "alpha beta" gets 1 hit instead of 0. Nothing throws and CheckIndex is clean. Reach is narrow: the class has no factory and no in-tree caller, and no downstream use was found. The fix is to add the increments up in a pending counter (+8/-4 lines), validated with the module's whole test suite.
- Position increment: how many positions a token moves on from the previous one. A removed stop word leaves a hole: the next token gets increment 2 instead of 1.
- Final position increment: what a stream reports from
end()after its last token, for a hole at its very end ("alpha the"withtheremoved reports 1). - Source: one of the streams
ConcatenatingTokenStreamjoins. A source with no tokens is an empty value, a whitespace-only value, or one made only of removed words.
// ConcatenatingTokenStream.java:89-97 at a9779ef3c193, incrementToken(): skip finished sources
while (sources[currentSource].incrementToken() == false) {
  if (currentSource >= sources.length - 1) return false;                              // :90
  sources[currentSource].end();
  initialPositionIncrement = sourceIncrements[currentSource].getPositionIncrement();   // :92  '=' overwrites
  OffsetAttribute att = sourceOffsets[currentSource];
  if (att != null) offsetIncrement += att.endOffset();                                 // :94  offsets use '+='
  currentSource++;
  newSource = true;
}
// :103-106 the stored value is added to the first token of the next source that has one
// :115 end(): int finalPosInc = sourceIncrements[currentSource].getPositionIncrement(); (last source only)alphacomes out with increment 1 (position 0). Source 0 ends; itsend()reports 1 (the removedthe), stored at:92.- Source 1 (
"") has no token; itsend()reports 0, and:92replaces the pending 1 with 0. Its offset, 0, is added to the running offset 9. - Source 2 emits
betawith1 + 0 = 1: position 1 instead of 2.
In a run of finished sources, the sum of the final increments of all of them except the last is lost: two empty values in a row lose the same hole, and foo+hole followed by two sources with no tokens and final increments 2 and 1 gives bar 2 instead of 5. If the last source is empty, incrementToken() returns at :90 and end() reads only that source, so end() reports 0. An empty first value ("", final increment 0) is handled correctly; a first value made only of stop words follows the same rule (concat("the", "the", "bar") gives bar increment 2, the single text 3). The assignment and a pending counter that starts at 0 and is cleared once applied agree whenever every source has a token, which is why the LUCENE-8650 test passes.
you build (foo+hole = token foo, final increment 1) | expected posIncs / end() | main |
|---|---|---|
concat(foo+hole, bar) (control) | [1, 2] / 0 | [1, 2] / 0 |
concat(foo+hole, EmptyTokenStream, bar) | [1, 2] / 0 | [1, 1] / 0 |
concat(foo+hole, <no tokens, final 1>, bar) | [1, 3] / 0 | [1, 2] / 0 |
concat(foo+hole, EmptyTokenStream) | [1] / 1 | [1] / 0 |
index "alpha the", "", "beta" | beta at 2; exact "alpha beta" 0 hits | beta at 1; 1 hit |
index "alpha the", "the", "beta" | beta at 3; "alpha beta"~1 0 hits | beta at 2; 1 hit |
The expected column of the two index rows was run as a multi-valued field (position gap 0). For the stream rows it is what the indexing chain would give for the same values (read from IndexingChain.java:2105-2109) and what the fix gives (executed); the first row is also what the class gives today.
Exposure and likelihood357 words
- Who is hit. Code that joins several values into one field with this public
analysis-commonclass (not marked experimental or expert), or uses it in its own analysis or query code (not run), when a value that ends in a removed token is followed by one or more values with no tokens. Such values are ordinary (an empty subtitle, a value made only of stop words), but the class is rarely used. - Reach. No analysis factory or SPI name, so
CustomAnalyzerand schema-driven setups cannot use it; no caller outside its own file and test; read-only code search of default branches found no use in Elasticsearch, OpenSearch or Solr. No prior report was found in the documented searches. - What goes wrong. Every token after the empty value moves closer by the lost hole. An exact phrase across a removed stop word matches (
"alpha beta": 1 hit instead of 0), and a phrase that needs the hole stops matching (QueryBuilderturnsfoo the barinto"foo ? bar", which then misses the document). OnlyPhraseQuerywas run; spans and intervals read the same positions. - Empty last value.
end()reports 0 instead of the hole. When such a stream is one value of a multi-valued field, the next value starts closer; the position gap between values is kept (a value ending in three removed words,"x the the the", then an empty source, then a second value, with gap 100: 101 instead of 104). - Silent and stored. No exception and
CheckIndexclean; on main with assertions on and off; the diagram probe indexed with the default codec, the gradle tests with the test framework's randomized codec. The wrong positions are in the index, so documents indexed before a fix keep them until reindexed. - Size. The tokens after a run of values with no tokens move closer by the final increments of every finished source in the run except the last: with one such value, the removed trailing tokens of the value before it; with several in a row, more. Positions only move closer and stay in order. No scale needed: one document, three values.
The test shows that ConcatenatingTokenStream loses the hole of a removed trailing stop word when the next source is empty: ('alpha the' with 'the' stopped, empty, 'beta').
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import java.io.StringReader;
import java.util.List;
import org.apache.lucene.analysis.CharArraySet;
import org.apache.lucene.analysis.StopFilter;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestConcatenatingEmptySourceHoles extends BaseTokenStreamTestCase {

  public void testEmptySourceKeepsPendingHole() throws Exception {
    TokenStream ts =
        new ConcatenatingTokenStream(stop("alpha the"), new EmptyTokenStream(), stop("beta"));
    // the hole of the removed "the" must survive the empty source: expected [1, 2], actual [1, 1]
    assertTokenStreamContents(ts, new String[] {"alpha", "beta"}, new int[] {1, 2});
  }

  private static TokenStream stop(String text) {
    Tokenizer tokenizer = new WhitespaceTokenizer();
    tokenizer.setReader(new StringReader(text));
    return new StopFilter(tokenizer, new CharArraySet(List.of("the"), false));
  }
}
# in a copy of this finding's repro folder (repro/LFV-488/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestConcatenatingEmptySourceHoles
- Expected vs actual
- Expected position increments [1, 2] (as without the empty source); actual [1, 1].
More files, environment, full output41 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: posIncrement 1 term=beta expected:<2> but was:<1>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:274)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:699)
org.apache.lucene.analysis.miscellaneous.TestConcatenatingEmptySourceHoles.testEmptySourceKeepsPendingHole(TestConcatenatingEmptySourceHoles.java:34)- LUCENE-8650 (7.7.0) fixed the class for "not propagating final position increments from its child streams correctly"; this is the case it missed.
- The same values as a multi-valued field keep the hole:
betaat 2. - The same loop adds offsets (
+=) but overwrites positions (=).
The full argument293 words
- CHANGES, Lucene 7.7.0 (
CHANGES.txt:6928-6930): "LUCENE-8650: ConcatenatingTokenStream did not correctly clear its state in reset(), and was not propagating final position increments from its child streams correctly." In #9696 the committer wrote that the patch "also handles final position increments (to allow for things like stop words being removed at the end of a tokenstream)". A stop-word-only value is exactly that case. - The upstream test
testOffsetGaps(TestConcatenatingTokenStream.java:63-83) expects a child's final increment 2 to be added to the next child's first token: posIncs{1, 1, 3, 1}(:76). Both children have tokens, and itsend()value 2 (:79) is the last child's own, so neither half of this bug is tested.testBasichas put anEmptyTokenStreambetween children since the class was added (:44), so empty sources are legal input. - The indexing chain (
IndexingChain.java:2105-2109) callsend()and adds the final increment for every value, including a value with no tokens, then the position gap (:2122). Executed: the multi-valued field"alpha the","","beta"putsbetaat 2; the concatenation of the same streams at 1. - The analysis docs:
TokenStream.end()says skipped positions "(such as those removed by a stopfilter) can be applied to the position increment" (TokenStream.java:152-154); the package docs say the components "must put accurate values into the token attributes to reflect the situation at the end of the field" (analysis/package-info.java:276-281). An empty last source makesend()report 0 although a hole is pending. - History: LUCENE-2529 and LUCENE-2668 (2010) fixed, as bugs, empty or stop-word-only values of multi-valued fields that shifted later positions or offsets in the indexing chain; LUCENE-3849 moved trailing holes into
end()so that multi-valued fields keep them.
The devil's-advocate check229 words
"Positions across an empty source are unspecified." The class javadoc promises "as if all the inputs were from a single source" only for offsets, end() says "can", not "must", and no test combines an empty source with a pending hole. It fails because LUCENE-8650 made carrying child final increments the stated and tested behaviour, the same loop adds offsets but overwrites positions, and no comment, test or discussion drops the increments of empty sources on purpose.
"Phrases across sources are loose anyway: the class adds no position gap." No gap is a separate, deliberate choice. The defect is that the same tokens get different positions depending on whether an empty value sits between them: concat("alpha the", "beta") puts beta at 2, concat("alpha the", "", "beta") at 1. An empty source should change nothing.
"What a stop-word-only middle value should add is a design question." Possibly; summing its own hole gives the positions of the multi-valued field and of the single text ([1, 3] for foo the + the + bar), which is the natural reading. The case is strongest for an empty value (final increment 0), which should change nothing, and for the empty last value's end(); it is weakest for how several stop-word-only values combine, which no document spells out. Verdict of every verifier and the adjudication: not intended (an opinion; the contracts are above).
Recommended A. Accumulate a pending increment
Keep a pending counter: add (+=) each finished source's final increment, add it to the next token and clear it, add any rest in end(), and clear it in reset() (+8/-4 in one file). Validated: the three repro classes pass, and the module's 1,909 tests and static checks pass. Inputs where every source has a token are unchanged.
-      initialPositionIncrement = sourceIncrements[currentSource].getPositionIncrement();
+      pendingPositionIncrement += sourceIncrements[currentSource].getPositionIncrement();
 ...
-      posIncAtt.setPositionIncrement(posInc + initialPositionIncrement);
+      posIncAtt.setPositionIncrement(posInc + pendingPositionIncrement);
+      pendingPositionIncrement = 0;
 ...
-    int finalPosInc = sourceIncrements[currentSource].getPositionIncrement();
+    int finalPosInc =
+        pendingPositionIncrement + sourceIncrements[currentSource].getPositionIncrement();
 ...
+    pendingPositionIncrement = 0;   // in reset()
All options and trade-offs4 options · 696 words
Option A was validated through gradle; B is the minimal-looking variant a reviewer might suggest, C an alternative a maintainer might raise, D a workaround for users today.
Rename initialPositionIncrement to pendingPositionIncrement (starting at 0), add to it instead of assigning, clear it once it is applied to a token, add what is left in end(), and clear it in reset(). The regression test: the four methods of the repro, added to TestConcatenatingTokenStream.
-      initialPositionIncrement = sourceIncrements[currentSource].getPositionIncrement();
+      pendingPositionIncrement += sourceIncrements[currentSource].getPositionIncrement();
 ...
-      posIncAtt.setPositionIncrement(posInc + initialPositionIncrement);
+      posIncAtt.setPositionIncrement(posInc + pendingPositionIncrement);
+      pendingPositionIncrement = 0;
 ...
-    int finalPosInc = sourceIncrements[currentSource].getPositionIncrement();
+    int finalPosInc =
+        pendingPositionIncrement + sourceIncrements[currentSource].getPositionIncrement();
 ...
+    pendingPositionIncrement = 0;   // in reset()
Trade-offs
- Positions change only for inputs that hit the bug (a pending hole followed by a source with no tokens, or an empty last source); when every source has a token, the assignment and the pending counter give the same values, and the upstream tests pass unchanged.
- No extra work per token. Documents indexed before the fix keep their wrong positions until reindexed; the CHANGES entry should say so and reference LUCENE-8650.
- A stop-word-only middle value adds its own hole too (
[1, 3]), matching a multi-valued field; a maintainer may want that spelled out in the javadoc.
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, JDK 25.0.3, seed DEADBEEF::lucene:analysis:common:testwith the fix and the three repro classes added passes with assertions on and off: 342 classes, 1,923 tests, 0 failures, 18 skipped. That is the module's 1,909 upstream tests (among themTestConcatenatingTokenStream4 of 4) plus the 14 repro tests, which fail 10 of 14 on stock main. - Static checks:
:lucene:analysis:common:check -x testwith the fix and the doc's test passes (checkGoogleJavaFormat,ecjLint,forbiddenApis,checkLicenses; error-prone is skipped in this build). - Earlier, with the standalone runner: the finder's version of the same fix passes the finder's 4, the independent reproducer's 6 and the security probe's 6 tests; the reproducer wrote the same fix independently.
- The fact check's probe also ran fix A on two sources with no tokens in a row, an empty first value, a stop-word-only middle value, an empty last value and reuse after
reset(): every value matches the multi-valued field. An all-empty stream and early or repeatedend()calls were not run.
The one-character change a reviewer may suggest first. The field starts at 1 (line 48) and reset() never clears it, so a bare += also breaks inputs where every source has a token.
Trade-offs
- Executed (a
main()probe on the stock classes with each variant):+=alone gives the controlconcat(foo+hole, bar)[1, 3]instead of[1, 2], thetestOffsetGapsinput{1, 1, 4, 1}instead of{1, 1, 3, 1}(the upstream test would fail), and three plain one-token sources[1, 2, 2]. - Adding the clear once applied and the rest in
end()still gives the control[1, 3]andtestOffsetGaps{1, 1, 4, 1}, givesend()2 instead of 1 for an empty last source, and leaks state acrossreset()(the next document'sx,yget[1, 3]). - Only with all four changes (start at 0, clear once applied, add the rest in
end(), clear inreset()) is every case right, and that is option A.
A javadoc note that positions are not carried across a source with no tokens.
Trade-offs
- Keeps the silent shift and the mismatch with multi-valued fields, and contradicts what LUCENE-8650 set out to fix.
- Not run.
Index the values as a multi-valued field instead: the indexing chain keeps the holes (executed: beta at 2). Dropping empty values before concatenating avoids the empty case, but not a value made only of stop words.
Trade-offs
- A multi-valued field applies the analyzer's position and offset gaps between values (0 by default for the position gap), which may differ from what the application wanted from one concatenated stream.
Code search of default branches found no use of this class in Elasticsearch, OpenSearch or Solr, so only applications that build a field's token stream in their own Java code are affected.
Code reading, not a formal method. A hunt unit on attribute and end-of-stream contracts ran an end-to-end harness over stream-combining classes, which pointed at end() and position handling; reading this class found the = next to the +=, and a small probe confirmed the lost hole.
The method in full103 words
Method: code reading (the study's "non-formal" tier), hunt unit "attribute and char-array contracts", main ea57360912ed, 2026-10-26.
- The unit's end-to-end attribute and end-state harness ran
ConcatenatingTokenStreamwith one source only, which passes; it pointed the search atend()and position handling in classes that copy attributes between streams. - Reading the class found the assignment at line 92 next to the offset
+=at line 94; a probe with an empty middle source confirmed the lost hole. - An AI finder then wrote the public-API test, traced the cause and wrote a fix sketch; independent AI tools reproduced, argued and judged it (see the checks).
No prior report: 144 queries over GitHub (Lucene, Solr, Elasticsearch, OpenSearch, Lucene.NET), JIRA, the mailing lists and the web, plus the changed files of all 408 open PRs (2026-10-26). Closest: LUCENE-8650 (#9696), the fix that wrote these lines without discussing an empty source.
Searches5 searches
Verdict: new. The related items are other code or the origin of the defect: #9696/LUCENE-8650 (closed, 7.7.0: the fix that wrote the lines; its tests and discussion never put a source with no tokens after a pending hole), #9697/LUCENE-8651 (open, Tokenizer reuse in the class), #8928/LUCENE-7877 (added the class), #4922/LUCENE-3849, #3603/LUCENE-2529 and #3742/LUCENE-2668 (precedents in the indexing chain), #9408/LUCENE-8361 (open, a generic position check), #16577 (a final-increment fix in FixedShingleFilter) and #16911 (open; it deletes branch_10x and is the only open PR touching the file). Limits: word-based search; private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | the scripted prior-report search (20 issue and PR queries, 3 commit queries) and 42 GraphQL searches: the class name, initialPositionIncrement, LUCENE-8650, "final position increment" with empty, stop word, hole, multi-valued; the file's commit history on main and branch_10x | only #9696, #9697 and #8928 name the class; none reports this |
| Downstream projects and ports | 2026-10-26 | GraphQL over lucene-solr, solr, elasticsearch, OpenSearch, lucenenet and all of GitHub; GitHub code search for the field name | no issue names the class; every copy of the code has the same assignment |
| Mailing lists and JIRA | 2026-10-26 | dev@, java-user@, issues@ and commits@ (20 queries), seven more Lucene and Solr list archives, and dev@, java-user@ and issues@ again through a second archive; JIRA across all projects | only notifications and commit mails for LUCENE-7877, LUCENE-8650 and LUCENE-8651 |
| Open PRs | 2026-10-26 | the changed files of all 408 open apache/lucene PRs | only #16911 (it deletes branch_10x) touches the file |
| Web | 2026-10-26 | 9 queries | nothing relevant |
Introduced in 7.7.0 by LUCENE-8650 (7713a4f2458c, 2019), which added the carry-over of final increments with an assignment and a last-source-only end(): an incomplete fix, not a regression. Affected on every release run from 7.7.0 to 10.5.2 and main; the tagged releases in between hold the same file. Before 7.7.0 the same inputs were already wrong, for an older reason.
Versions tested7 rows
Introduced by LUCENE-8650 = #9696 ("ConcatenatingTokenStream does not end() nor reset() properly"), commit 7713a4f2458c "LUCENE-8650: Fix end() and reset() in ConcatenatingTokenStream" (authored 2019-01-22, committed 2019-01-28; backports 874ff046dfd0 to branch_7x and f062a18ae716 to branch_8x; a JIRA patch, no PR). git blame on main assigns lines 92 and 115 to it.
The class itself dates from LUCENE-7877 (a948e1714609, 2017, first released in 7.0.0). In 7.0.0-7.6.0 no child final increment was carried at all, so the same inputs were wrong there for that older, broader bug, which LUCENE-8650 fixed. The only later change to the file is the LUCENE-9570 reformat (whitespace and javadoc, 9.0.0). The release tags hold three versions of the file (7.0.0-7.6.0, 7.7.0-8.8.1, 9.0.0-10.5.2, the last identical to main); 8.9.0-8.11.4 are not tagged in the history clone, and 8.11.4 was run. The release probes ran with assertions on; main, 9.12.3 and 10.5.2 also ran with them off (the class has no assert statement). Main a9779ef3c193 still has the assignment.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the doc's test 3 of 4, the finder's 3 of 4 and the reproducer's 4 of 6 fail (gradle, assertions on and off) |
| 10.5.2, 9.12.3 | affected | the doc's test 3 of 4 fail; the finder's and the reproducer's tests fail; the probe's 4 empty-source cases fail |
| 10.0.0, 9.0.0, 8.11.4, 8.0.0, 7.7.3 | affected | probe: the 4 controls pass, the 4 empty-source cases fail |
| 7.7.0 | first | the first release with LUCENE-8650: the controls pass, the 4 empty-source cases fail |
| 7.0.0, 7.6.0 | older bug | no child final increment carried at all: the controls fail too (the broader bug LUCENE-8650 fixed) |
| 6.6.6 | no API | the class does not exist (compile error) |
| main with fix A | fixed | all 14 repro tests pass; the module's 1,909 tests pass with assertions on and off |
An independent reproducer, a devil's advocate and an adjudication found it real; a reviewer from another model family (OpenAI GPT-5.6), which could only read code, agreed on the intended-behaviour lens. A credibility audit kept it. This doc re-ran the repros through gradle on main and validated the fix with the module's whole suite.
Checks and verdicts381 words
Each check wrote or ran its own tests against stock jars on main ea57360912ed (identical class and test) and release jars; the doc's runs used main a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | The 4-test JUnit fails 3 of 4 on main (on and off), 10.5.2 and 9.12.3, and a main() probe fails on 8.11.4 and 7.7.3; with its fix 4 of 4, and upstream TestConcatenatingTokenStream 4 of 4. |
| refute review (OpenAI GPT-5.6) | not real, low (procedural) | Could not run Java (reading only), and it voted not real on procedure only; it agreed on the root cause and that the inputs are legal. A separate run re-ran the finder's test: 3 of 4 fail. |
| intended review (OpenAI GPT-5.6) | real, medium | Rated the "unspecified" argument moderate but weakened by LUCENE-8650 and testOffsetGaps; reading only, a separate run re-ran the repro on main (on and off) and 10.5.2, and the fix check. |
| Independent reproducer | real | Own 6-test class outside Lucene's packages: 4 of 6 fail on main (on and off), 10.5.2 and 9.12.3; 2 controls pass; its own, independently written fix passes 6 of 6. |
| Devil's advocate | real, high that it is not intended | Showed that offsets add up across an empty source while positions do not, and that the multi-valued field keeps the hole the concatenation loses. |
| adjudication | confirmed, high | Re-ran the reproducer's test (4 of 6 fail, on and off), the finder's (3 of 4), and the reproducer's with the fix (6 of 6). |
| security screen | none | A 6-test probe: 2 effect tests fail on main and 10.5.2, 4 containment tests pass (other documents unaffected, gap kept, CheckIndex clean, no state across reuse); 6 of 6 with the fix. |
| credibility audit | keep | Re-ran the finder's test with a fresh seed (3 of 4 fail). Two contract phrasings in its notes are overstated (single-source positions, "must be applied"); this doc does not use them. |
| this doc | reproduced; fix validated | Gradle at a9779ef3c193: 10 of 18 repro tests fail on stock (on and off), upstream 4 of 4 pass; with the fix the whole module passes (1,923 tests) and its static checks pass; the doc's test fails 3 of 4 on 10.5.2 and 9.12.3. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 429 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,464 words
- Registry title
- ConcatenatingTokenStream loses a source's trailing position increment (for example a removed stop word) when the next source produces no tokens, so later tokens are indexed too close and phrase queries over-match
- Area
- analysis / common miscellaneous (ConcatenatingTokenStream#incrementToken and #end: carry-over of child final position increments)
- Priority
- Low, rank 488: A position hole lost across value boundaries, in the rarely used ConcatenatingTokenStream with no factory or in-tree caller.
- Impact class
- silent wrong results
- Impact note
- Only applications that hand-build a field's token stream with ConcatenatingTokenStream (a public analysis-common class with no analysis factory, no in-tree caller and no use found in Elasticsearch, OpenSearch or Solr) are hit, and only when a source that ends in a hole (typically a trailing stop word removed by a StopFilter) is followed by one or more sources that emit no tokens (an empty value, or one made only of removed tokens): the hole is lost, so later tokens of that field are indexed too close, or end() reports 0 instead of the hole, and phrase, span and interval queries on the affected document can over-match or miss, with -ea and -da and the default codec; no scale is needed, nothing throws and CheckIndex stays clean.
- Summary
- You build one field from several token streams with ConcatenatingTokenStream, for example the values 'alpha the', '' and 'beta', each run through a StopFilter that removes 'the'. You expect the hole left by the removed 'the' to survive, as it does when no empty value sits in between and as IndexWriter keeps it for the same values in a multi-valued field, because LUCENE-8650 (7.7.0) made the class carry each source's final position increment over to the next token. Instead each exhausted source overwrites the pending increment instead of adding to it, and end() reports only the last source's own increment, so a source with no tokens erases the hole: 'beta' is indexed directly after 'alpha', the exact phrase "alpha beta" matches this document but not the single value 'alpha the beta', and with an empty last source end() reports 0 instead of 1.
- Introduced
- 7713a4f2458c77de08193dc548807b9e90214aaf (LUCENE-8650 = apache/lucene#9696 'ConcatenatingTokenStream does not end() nor reset() properly'; commit 'LUCENE-8650: Fix end() and reset() in ConcatenatingTokenStream' by romseygeek; JIRA patch workflow, no PR; backports branch_7x 874ff046dfd0 and branch_8x f062a18ae716): it added the carry-over of child final position increments as an assignment (ConcatenatingTokenStream.java:92) and an end() that reads only the last source (:115) [read: git blame on main assigns both lines to it; the only later change to the file is the LUCENE-9570 reformat 8ef6a0da568, whitespace and javadoc only] [exec: 7.6.0, the last release before it, propagates no child increment at all (all 8 probe cases wrong, controls included); 7.7.0, the first release with it, gets the 4 controls right and the 4 empty-source cases wrong]. An incomplete fix, not a regression: the class itself dates from LUCENE-7877 (a948e1714609, #8928, 2017-06-22, first released in 7.0.0) (2019-01-22 (authored), 2019-01-28 (committed))
- First affected version
- 7.7.0 [exec] (the first release with the LUCENE-8650 carry-over; 7.0.0-7.6.0 have the class but propagate no child final increment at all, so the same inputs were already wrong there for that older and broader root cause, which LUCENE-8650 fixed [exec 7.0.0 and 7.6.0]; 6.6.6 and older do not have the class [exec: compile error])
- Affected versions
- 7.7.0-7.7.3, 8.0.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.5.2 (the last release before 10.6.0) and main ea57360912ed. [exec] a portable main() probe (4 controls and 4 empty-source cases) fails with only the empty-source cases on 7.7.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da), and passes on main with the fix shadowed; the finder's JUnit fails 3 of 4 on main (-ea, -da), 10.5.2 and 9.12.3 (it cannot compile on 9.0.0 because of the test-framework package move in 9.1.0); the independent reproduction's JUnit fails 4 of 6 on main, 10.5.2 and 9.12.3 (-ea and -da); the finder's main() probe fails on 8.11.4 and 7.7.3. [read] the release tags hold only three versions of the file (7.0.0-7.6.0 original, 7.7.0-8.8.1 LUCENE-8650, 9.0.0-10.5.2 reformatted and identical to main); 8.9-8.11 are not tagged in the local history, 8.11.4 was executed. Not fixed upstream: upstream main a9779ef3c193 (2026-10-26) still has the assignment at line 92, and no open PR changes the logic [read]. Executed only on aarch64 Linux with JDK 25 (plain Java logic)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record, verdict new; plus the finder's and the intended-behaviour check's searches): 144 queries, namely a scripted prior-report search over apache/lucene GitHub issues, PRs and commits, downstream repositories (Elasticsearch, OpenSearch, Solr), the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web; 42 GitHub GraphQL searches over apache/lucene, lucene-solr, solr, elasticsearch, OpenSearch, lucenenet and all of GitHub; ten more list archives including the Solr lists; JIRA across all projects; GitHub code search; the changed files of all 408 open apache/lucene PRs; the file's commit history on main and branch_10x. Related, not this bug: #9696/LUCENE-8650 (closed, 7.7.0: the fix that wrote the defective lines; a source with no tokens after a pending increment is never discussed), #9697/LUCENE-8651 (open, Tokenizer reuse), #8928/LUCENE-7877 (introduced the class), #4922/LUCENE-3849 (the end() trailing-hole contract), #3603/LUCENE-2529 and #3742/LUCENE-2668 (2010 indexing-chain analogues for empty or stop-word-only values, fixed as bugs), #9408/LUCENE-8361 (open, a generic TestRandomChains position check), #16577 (FixedShingleFilter final increment, other class), #16911 (open, deletes branch_10x; the only open PR touching the file). Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree (2026-10-28), assertions on and off, stock and with the fix; the doc's test on the 10.5.2 and 9.12.3 release jars (2026-10-28). The hunt and its checks ran on mainea57360912ed, whoseConcatenatingTokenStream.javaandTestConcatenatingTokenStream.javaare identical, and a portable probe ran with assertions on at 6.6.6, 7.0.0, 7.6.0, 7.7.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2 (2026-10-26).
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenatingTokenStream.java:29-37 (at ea57360912ed) (class javadoc: offsets incremented 'to behave as if all the inputs were from a single source'; no experimental or expert tag), :48 (initialPositionIncrement = 1, never read before :92 overwrites it), :89-97 (loop over exhausted sources: :92 assignment of the final increment, :94 offsets with +=), :103-106 (pending value added to the first token of the next non-empty source only), :111-119 (end(): :115 reads the last source only), :121-129 (reset())lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestConcatenatingTokenStream.java:33-56 (at ea57360912ed) (testBasic, EmptyTokenStream child at :44 with no pending increment), :63-83 (testOffsetGaps: posIncs {1,1,3,1} at :76; its end() value 2 is the last child's own)lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:152-154 (at ea57360912ed) (end(): 'any skipped positions (such as those removed by a stopfilter) can be applied to the position increment')lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2050-2054 (at ea57360912ed) (stream.end() then the final increment added for every value, including a value with no tokens), :2067 (position increment gap)lucene/CHANGES.txt:6912-6914 (at ea57360912ed) (LUCENE-8650 under Lucene 7.7.0: 'was not propagating final position increments from its child streams correctly')Lucene main ea57360912ed: grep of lucene/**/*.java outside src/test finds ConcatenatingTokenStream only in its own file; no reference under lucene/analysis/common/src/resources (no factory or SPI name)
- The finding in 30 seconds
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenatingTokenStream.java:48, :89-97 (:90, :92, :94), :103-106, :111-119 (:115), :121-129
- Who is affected
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/resources (no reference to the class); grep of lucene/ outside src/test (only the class itself and CHANGES.txt)
- Why it looks unintended
a Lucene main checkout (a9779ef3c193) lucene/CHANGES.txt:6891 (Lucene 7.7.0), :6928-6930 (LUCENE-8650)a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestConcatenatingTokenStream.java:33-61 (testBasic, EmptyTokenStream at :44), :63-83 (testOffsetGaps, posIncs :76, end() :79)a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2105-2109, :2122a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:152-154; lucene/core/src/java/org/apache/lucene/analysis/package-info.java:276-281a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenatingTokenStream.java:29-37 (class javadoc, offsets only)
- History
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenatingTokenStream.java:92 (the assignment is still there)
- TestConcatenatingEmptySourceHoles.java (JUnit test):
repro/LFV-488/src/org/apache/lucene/analysis/miscellaneous/TestConcatenatingEmptySourceHoles.java(42 lines)
A light, step-by-step picture of the "alpha the", "", "beta" example and a summary card, made in parallel with this doc. Its numbers come from an executed probe on main a9779ef3c193, stock and with the fix; the PNG is the summary card.
assets/LFV-488/bug.png(429 KB)