The highlighter keeps a field's values as one string with an invisible U+0000 between them and finds sentences inside each value. When nothing in the field matches, it shows the field's first few sentences, but the loop that collects them also counts the 1-character separator as a sentence.
- Highlighting shows the sentences of a stored field that contain the query's matches, with the matches marked, for example
First <b>value</b>. - If a hit has no match in that field, the UnifiedHighlighter shows a default summary instead: the field's first
maxPassagessentences (a per-call argument; the 3-argumenthighlightcall uses 1). - A field can hold several values. The highlighter joins them into one string with the invisible character U+0000 between values, and finds sentences inside each value separately, so no sentence spans two values.
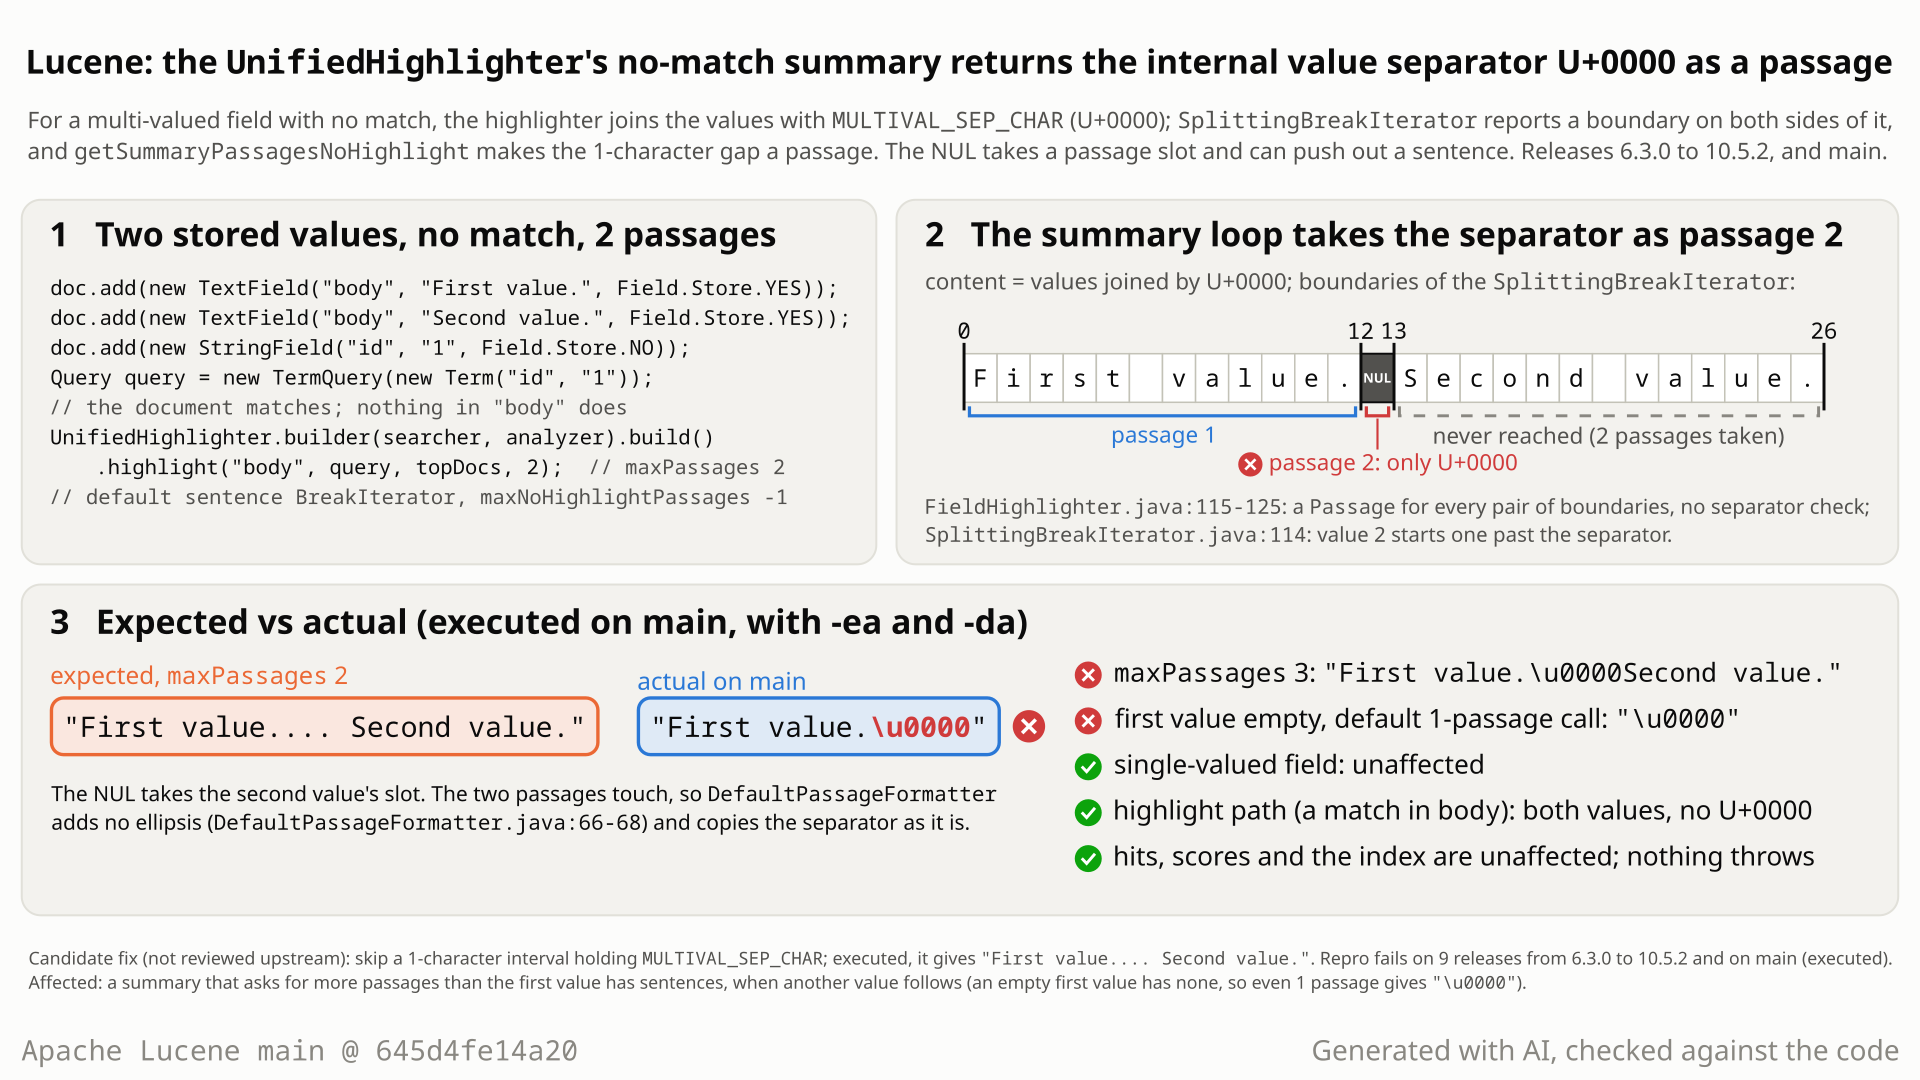
First value.\u0000 instead of First value.... Second value. Select the still to open it at full size. Generated with AI, checked against the code.- You store two values in one field,
First value.andSecond value., run a query that matches the document but nothing in that field, and ask the UnifiedHighlighter, with its default settings, for 2 passages of that field. - You expect the documented default summary, the field's first 2 sentences, joined the way highlighted values are joined:
First value.... Second value. - You get
First value.\u0000: a raw U+0000, invisible on screen, where the second sentence should be. With 3 passages you getFirst value.\u0000Second value.; with an empty first value even the default 1-passage call returns only\u0000. No error; hits and scores are unchanged. - Why: the highlighter joins the values with U+0000 and reports a sentence boundary on both sides of it, at 12 and 13 (the other boundaries are 0 and 26). The summary loop makes a passage of every pair of neighbouring boundaries, so the 1-character gap from 12 to 13, the separator alone, becomes passage 2.
Applications that use the UnifiedHighlighter directly on multi-valued stored fields, with default settings, for hits with no match in that field. Asking for 2 or more passages hits it when the first value has fewer sentences than asked; an empty first value hits even the default 1-passage call. Only the snippet text is wrong.
Mechanism, terms and numbers647 words
When a hit has no match in a highlighted field, the UnifiedHighlighter returns a default summary, documented as "the first maxPassages sentences from the field". For a multi-valued stored field it joins the values with its internal separator U+0000 and reports a boundary on both sides of each separator. The summary loop turns every pair of neighbouring boundaries into a passage, so the 1-character separator becomes a passage of its own: it takes one of the requested slots and is copied into the snippet as a raw NUL. Two values First value. and Second value. with 2 passages give First value.\u0000; with an empty first value even the default 1-passage call gives \u0000. Hits, scores and the index are unaffected. The code dates from the UnifiedHighlighter's introduction (6.3.0, 2016): the test fails on the 9 releases tried from 6.3.0 to 10.5.2 and on main, and the code is the same at every other tagged release. Skipping that 1-character interval in the summary loop fixes it (7 added lines, one of them an import; validated with the whole highlighter module).
- Values are joined with U+0000.
UnifiedHighlighter.MULTIVAL_SEP_CHAR = (char) 0(UnifiedHighlighter.java:98), appended between the stored values (:1463). The example content isFirst value.+ U+0000 +Second value.: 26 characters, the separator at index 12. - The field's iterator is wrapped. Every field's
BreakIteratoris wrapped innew SplittingBreakIterator(getBreakIterator(field), MULTIVAL_SEP_CHAR)(UnifiedHighlighter.java:1135), which "virtually slices the text on both sides of every occurrence" of the separator, so that "the enclosed BreakIterator will never 'see' the splitting character" (SplittingBreakIterator.java:24-28). Itsnext()returns the end of value 1 and then, one character later, the start of value 2 (:104-124,:114). Boundaries: 0, 12, 13, 26. This is intended and tested (TestSplittingBreakIterator:aa|aagives^ ^^ ^), and the highlight path needs the boundary at 13 so that a passage in value 2 starts at its first character. - No match, so a summary. When no passage has a match,
FieldHighlightercallsgetSummaryPassagesNoHighlight(maxNoHighlightPassages == -1 ? maxPassages : maxNoHighlightPassages)(FieldHighlighter.java:89-94); -1 is the default. - The loop counts the gap. "By default this just returns the first maxPassages sentences" (
FieldHighlighter.java:104-108), but the loop (:115-125) makes a passage of every pair of consecutive boundaries: [0, 12)First value., then [12, 13), which holds only U+0000, then [13, 26)Second value.. - The formatter copies it.
DefaultPassageFormatteradds its ellipsis"... "only between passages that do not touch (DefaultPassageFormatter.java:66-68); these touch, so the NUL is copied verbatim and no ellipsis appears.
| stored values | maxPassages | stock | with the fix |
|---|---|---|---|
First value., Second value. | 1 | First value. | First value. |
| same | 2 | First value.\u0000 | First value.... Second value. |
| same | 3 | First value.\u0000Second value. | First value.... Second value. |
empty, Second value. | 1 | \u0000 | Second value. |
empty, Second value. | 2 | \u0000Second value. | Second value. |
A one., B two., C three. | 3 | A one.\u0000B two. (third value lost) | A one.... B two.... C three. |
First one. First two., Second value. | 2 | First one. First two. | unchanged |
control: a query matching value in both values | 2 | First <b>value</b>.... Second <b>value</b>. | unchanged |
The same with each of the three offset sources (re-analysis, offsets in postings, term vectors), each executed as a test of its own, and with the whole-text iterator; the hunt's exhaustive harness saw it with every iterator family it covered (sentence, word, custom separator, whole, length goal). When every value is empty the summary is \u0000 alone instead of no passage. All of this assumes stored values without a U+0000 of their own (a stored U+0000 is a separate bug, LFV-599). Every upstream no-match summary test is single-valued, which is why the tests miss it.
Exposure and likelihood421 words
- Who is hit. Direct users of Lucene's UnifiedHighlighter on multi-valued stored fields, for hits with no match in the highlighted field (common when several fields are highlighted and the query matches only some), with the default no-match summary, and either 2 or more passages (
maxPassages, orwithMaxNoHighlightPassages(n)with n >= 2) while the first value has fewer sentences than asked, or an empty first value. The default 1-passage call with a non-empty first value is not affected (for stored values without a U+0000 of their own; that case is LFV-599). - Reach limit (read). The separator is only added while the field's
maxLengthbudget lasts (default 10,000 characters): the stored-field visitor truncates the first value tomaxLengthand adds no further value once the budget is used up (UnifiedHighlighter.java:1446-1452). A custommaxLengththat ends inside the first value prevents this summary shape. - Defaults. Default builder, default sentence iterator, default
maxNoHighlightPassages(-1), all three offset sources (each executed separately).UnifiedHighlighteris@lucene.experimental;FieldHighlighteris@lucene.internal, but users never pick it: the UnifiedHighlighter builds it. - What happens. Display text only: a raw U+0000 in the snippet, which takes one of the requested passage slots and so pushes out a real sentence or value whenever the field has one left (2 values and 2 passages: the second value is lost; 3 values and 3 passages: the third). With nothing left to push out, the NUL is still there (2 one-sentence values and 3 passages:
First value.\u0000Second value.). Hits, scores and the index are unaffected; nothing throws. The NUL is invisible on screen. An application that writes the snippet into XML without escaping control characters produces a document an XML parser rejects (run only with the JDK's own XML writer and parser as a stand-in; control characters from document text do the same; no real product was run). - Scale. Deterministic per document and field, independent of index size.
- Downstream (by reading their source as examined during the hunt, not run; not a guarantee for their current code). Elasticsearch and OpenSearch override
getSummaryPassagesNoHighlightand skip the separator, so in the examined source they are not exposed. Solr's default summary is off unlesshl.defaultSummary=true; then Solr's own snippet separator is also U+0000 and it splits on it, which hides the NUL but returns one snippet fewer thanhl.snippets(emulated). - Workarounds (not run).
withMaxNoHighlightPassages(0)turns the summary off; or overridenewFieldHighlighterto return aFieldHighlighterwhose summary skips the separator. Stripping U+0000 from the snippet afterwards still leaves a sentence missing.
The test shows that the UnifiedHighlighter's no-match summary of a two-valued field ('First value.', 'Second value.') with maxPassages 2 returns the internal U+0000 value separator as the second passage.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.uhighlight;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TopDocs;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestUHSummaryMultiValueSeparator extends LuceneTestCase {

  public void testNoMatchSummaryOfMultiValuedFieldHasNoSeparator() throws Exception {
    Analyzer analyzer = new StandardAnalyzer();
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
        Document doc = new Document();
        doc.add(new TextField("body", "First value.", Field.Store.YES));
        doc.add(new TextField("body", "Second value.", Field.Store.YES));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        Query query = MatchAllDocsQuery.INSTANCE;
        TopDocs topDocs = searcher.search(query, 1);
        UnifiedHighlighter highlighter = UnifiedHighlighter.builder(searcher, analyzer).build();
        String summary = highlighter.highlight("body", query, topDocs, 2)[0];
        // expected: the field's first 2 sentences, no U+0000; actual: "First value." + U+0000
        assertFalse(
            "2-passage summary contains the U+0000 value separator: "
                + summary.replace("\u0000", "\\u0000"),
            summary.contains("\u0000"));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-498/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/highlighter/build/libs/lucene-highlighter-$V.jar
CP=$CP:$LUCENE/lucene/memory/build/libs/lucene-memory-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.uhighlight.TestUHSummaryMultiValueSeparator
- Expected vs actual
- Expected the field's first 2 sentences with no U+0000 ("the first maxPassages sentences from the field"); actual:
First value.\u0000, with-eaand-da.
More files, environment, full output39 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: 2-passage summary contains the U+0000 value separator: First value.\u0000
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
       org.junit.Assert.assertFalse(Assert.java:65)
org.apache.lucene.search.uhighlight.TestUHSummaryMultiValueSeparator.testNoMatchSummaryOfMultiValuedFieldHasNoSeparator(TestUHSummaryMultiValueSeparator.java:53)- The javadoc promises "the first maxPassages sentences from the field"; U+0000 is not from the field, and the sentence iterator is documented never to see it.
- With a match, the same document joins its values with the formatter's ellipsis, as a test asserts.
- No test covers a multi-valued summary; one skips values containing the separator ("will throw things off").
The full argument220 words
- The public contract.
highlight(field, query, topDocs, maxPassages): "If no highlights were found for a document, the first maxPassages sentences from the field will be returned" (UnifiedHighlighter.java:759-761); the 3-argument form: "the first sentence for the field" (:742). The separator is inserted by the highlighter (:1463), andSplittingBreakIteratorpromises that the user's iterator "will never 'see' the splitting character" (SplittingBreakIterator.java:28). - The highlight path. For the same document with a matching query, values come out as separate passages joined by the ellipsis:
TestUnifiedHighlighter.java:339assertshighlightedValue + "... " + highlightedValue. LUCENE-7438 (#8490), which introduced the highlighter: "a passage will never span across values". - Lucene's own tests treat the separator as non-content.
TestUnifiedHighlighterMTQ.java:1139skips random values that contain it ("will throw things off"). Every no-match summary test is single-valued. No javadoc, CHANGES or MIGRATE entry sanctions a separator in the summary or a dropped value. - Downstream fixed it for themselves. Elasticsearch's override of the summary method (2017) skips leading separators and ends the passage at the next one (code reading).
- Origin, not intent. The loop is a near-verbatim copy of
PostingsHighlighter.getEmptyHighlight, whose multi-value separator was a visible, configurable space (getMultiValuedSeparatorreturned' ') that its iterator saw. LUCENE-7438 replaced it with a hidden control character and did not adapt the loop.
The devil's-advocate check241 words
Strongest case for "intended" (built by the cross-model reviews, the independent reproducer, the devil's advocate and the adjudication): getMaxNoHighlightPassages says "the number of leading passages (as delineated by the BreakIterator)", and the iterator FieldHighlighter holds is the SplittingBreakIterator, which deliberately reports both sides of each separator (javadoc and TestSplittingBreakIterator), so [12, 13) is literally a delineated passage; the loop came from the PostingsHighlighter, where summaries contained the visible separator; FieldHighlighter is @lucene.internal, the UnifiedHighlighter and SplittingBreakIterator are @lucene.experimental, and the summary method is a protected override hook; Solr's U+0000 snippet separator hides the NUL.
Why it fails: the iterator's boundaries are fine, the summary loop's use of them is the defect, and the more specific public promise is sentences "from the field"; the literal reading also does not explain why a real sentence is pushed out. The PostingsHighlighter lineage explains where the bug came from, not that anyone wanted it. The labels allow API change; they do not make the output correct. Solr still loses a snippet (emulated), and Elasticsearch replaced the loop. The cross-model reviews rated the intended case moderate; the devil's advocate and the adjudication rejected it. Verdict: a defect; expect the literal reading to come up, and answer it with the highlight() javadoc and the dropped value. In the end it is a contract call for the maintainers: the boundaries are documented and tested, but nothing documents the separator as a summary passage.
Recommended B. Skip the separator interval in the summary loop, reading the character from a copy
In the summary loop, skip a boundary pair that encloses exactly the U+0000 separator, so it never counts as a passage, and read that character from a copy of the iterator's text: +7 lines in FieldHighlighter. The test passes, and so do the module's other 722 tests and its checks.
     List<Passage> passages = new ArrayList<>(Math.min(maxPassages, 10));
+    // a copy, so that reading characters cannot move the break iterator
+    CharacterIterator text = (CharacterIterator) breakIterator.getText().clone();
     int pos = breakIterator.current();
     ...
       if (next == BreakIterator.DONE) {
         break;
       }
+      if (next - pos == 1 && text.setIndex(pos) == UnifiedHighlighter.MULTIVAL_SEP_CHAR) {
+        pos = next; // the separator between two values is not a passage
+        continue;
+      }
       Passage passage = new Passage();
All options and trade-offs4 options · 763 words
Two options were applied and tested with gradle on main 645d4fe14a20 (option B recommended, option A the hunt's original); two more were considered and not run. A and B skip exactly the same interval; they differ only in how they read the character.
B. Skip the separator interval in the summary loop, reading the character from a copy (validated by the checks) (recommended)
In FieldHighlighter.getSummaryPassagesNoHighlight (FieldHighlighter.java:109-128), take a copy of the iterator's text once before the loop and skip a boundary pair of length 1 whose character is MULTIVAL_SEP_CHAR. +7 lines, one of them the import of java.text.CharacterIterator.
What it changes. Only the no-match summary. The separator interval no longer counts toward maxPassages, so the next value's first sentence takes the slot; the two values' passages no longer touch (12 != 13), so the formatter puts its ellipsis between them, as on the highlight path. An empty first value gives the second value's first sentence; when every value is empty there is no passage and the snippet is null, as with maxNoHighlightPassages 0 (FieldHighlighter.java:96-100, read, not run). Single-valued fields (whose value holds no U+0000) and matched highlighting are unchanged.
     List<Passage> passages = new ArrayList<>(Math.min(maxPassages, 10));
+    // a copy, so that reading characters cannot move the break iterator
+    CharacterIterator text = (CharacterIterator) breakIterator.getText().clone();
     int pos = breakIterator.current();
     ...
       if (next == BreakIterator.DONE) {
         break;
       }
+      if (next - pos == 1 && text.setIndex(pos) == UnifiedHighlighter.MULTIVAL_SEP_CHAR) {
+        pos = next; // the separator between two values is not a passage
+        continue;
+      }
       Passage passage = new Passage();
Trade-offs
- One
getText()and oneclone()per summary call (two smallStringCharacterIteratorobjects with the default iterator). - It recognises the separator by its value, so a stored value that itself contains U+0000 is still mis-split; that is a separate known bug (LFV-599).
- No CHANGES entry is drafted. Engines that override the summary method are unaffected either way.
What the checks validated
- Gradle in a scratch worktree of main
645d4fe14a20: the 5-test repro passes with assertions on and off and with 3 seeds (stock: 3 of 5 fail); everyuhighlightclass, 15 classes and 476 tests (470 upstream), 0 failures; all of:lucene:highlighter:test, 36 classes and 728 tests (722 upstream), 0 failures. :lucene:highlighter:check -x testpasses with the repro added (google-java-format, ecjLint, forbiddenApis).- With the fixed class shadowed in the repro harness on
645d4fe14a20: the hunt's test passes 2 of 2 and the independent reproducer's test 4 of 4 (3 offset sources); stock they fail 2 of 2 and 3 of 4.
A. The same skip, reading the character through breakIterator.getText() (the hunt's 5-line form) (validated by the checks)
Five added lines in the same loop: if (next - pos == 1 && breakIterator.getText().setIndex(pos) == UnifiedHighlighter.MULTIVAL_SEP_CHAR) { pos = next; continue; }. With the highlighter's own wrapping it is correct, because SplittingBreakIterator.getText() returns a new StringCharacterIterator each time (SplittingBreakIterator.java:59-64).
+      if (next - pos == 1
+          && breakIterator.getText().setIndex(pos) == UnifiedHighlighter.MULTIVAL_SEP_CHAR) {
+        pos = next; // the separator between two values is not a passage
+        continue;
+      }
Trade-offs
- Breaks custom iterators (executed). A
FieldHighlightercan get anyBreakIteratorthrough the protectednewFieldHighlighterhook. A JDKRuleBasedBreakIterator(the sentence and word instances) returns its liveCharacterIteratorfromgetText(), sosetIndex(pos)moves the iterator back and the nextnext()repeats a boundary. With a raw JDK word iterator over the same two values and 8 passages, A gives[0,5)[5,6)[6,6)[6,11)[11,12)[12,12)[13,13)[13,19), three of them empty; stock gives[0,5)[5,6)[6,11)[11,12)[12,13)[13,19)[19,20)[20,25)and B[0,5)[5,6)[6,11)[11,12)[13,19)[19,20)[20,25)[25,26). - That is a custom,
@lucene.internalconfiguration, but option B avoids it at no cost.
What the checks validated
- The same results as option B for the repro (assertions on and off, 3 seeds), the 476
uhighlighttests and the 728 module tests (722 upstream), andcheck -x test.
Remove the second boundary, so the separator is never an interval of its own.
Trade-offs
Not recommended: the two-sided boundaries are documented and tested (TestSplittingBreakIterator), and the highlight path relies on the boundary at a value's start (breakIterator.preceding(...), FieldHighlighter.java:178-182) so that a passage in a later value does not begin with the separator.
Compute the separator positions from the content, or test breakIterator instanceof SplittingBreakIterator.
Trade-offs
The protected getSummaryPassagesNoHighlight(int) has no content parameter, and changing its signature would break the overrides downstream engines ship; B gets the same result without that.
In the source examined during the hunt, Elasticsearch and OpenSearch replace this summary method and are not exposed; Solr's default summary is off, and with hl.defaultSummary=true it shows one snippet fewer (by reading their code and an emulation, not run).
A bounded-exhaustive check of the real highlighter against a reference written from its javadoc. For every 2-3 value content of up to 5 characters and 61 iterator configurations, the oracle "the summary is the first N sentences of the values, never the separator" failed for every iterator family, on multi-valued content only. A public-API JUnit followed.
The method in full159 words
Method (semi-formal): bounded-exhaustive translation validation of the real highlighter jar against a reference semantics written from the javadoc, not from the code.
- The reference says: when no passage has a match, the summary is the first N passages of the values in order, as delineated by the user's BreakIterator, and never the separator (N = maxPassages when maxNoHighlightPassages < 0).
- Multi-valued tiers: every content of 2-3 values over
a, space and.up to 5 characters (8,657 contents, 7 plain and 54 length-goal iterator configurations, 3,168,462 checks), and with a supplementary character up to 4 characters (2,096 contents, 31 configurations, 584,784 checks). - The failure class
P2-summary-separator-passageappeared for every iterator family (sentence, word, custom separator, whole, length goal), on multi-valued content only; the same class also caught the all-values-empty case. The hypothesis came first from readinggetSummaryPassagesNoHighlightwhile the reference was written; the harness confirmed it on its first multi-valued scope. The finder then wrote the public-API JUnit.
No prior report found (searched 2026-10-26, refreshed 2026-10-29: GitHub issues, PRs and commits, JIRA, the Lucene and Solr lists, downstream repositories, the web and all 408 open PRs' files). Closest: apache/solr#5126 notes a related U+0000 symptom on highlighted matches, which is a different bug.
Searches5 searches
Closest, all different (16 hits classified, none the same bug):
- apache/solr#5126 (by dsmiley, merged 2026-10-27): its description notes that with
hl.method=unified, multi-valued fields can return a leading empty snippet because Lucene's value separator and Solr's snippet separator are both U+0000, and that this "deserves its own issue". Their example is a highlighted match; an executed emulation reproduces it only withLengthGoalBreakIteratoron the match path (the sibling bug LFV-494), not with this summary loop. It never mentions the default summary or a dropped value; no follow-up issue was found. - Elasticsearch and OpenSearch override
getSummaryPassagesNoHighlightand skip the separator (since 2017): a workaround in code, with no issue text describing the Lucene defect. - #8490 / LUCENE-7438: the introduction ("a passage will never span across values").
- #10135 / LUCENE-9093: changed
LengthGoalBreakIteratorfor the default summary; single-valued.
Gaps: downstream trackers were searched by keyword, not exhaustively; private reports cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, apache/lucene-solr, apache/solr, elastic/elasticsearch, opensearch-project/OpenSearch, hibernate/hibernate-search, apache/lucenenet) | 2026-10-26 | 53 manual searches (for example getSummaryPassagesNoHighlight, MULTIVAL_SEP_CHAR, SplittingBreakIterator, maxNoHighlightPassages, defaultSummary multivalued, unified highlighter null character) | no report; apache/solr#5126 is the closest (a different bug) |
| The hunt's scripted prior-report search (GitHub issues, PRs and commits, downstream repositories, dev@, java-user@, issues@ and commits@, the JIRA archive, the web) | 2026-10-26 | three runs, 45, 51 and 45 queries; 243, 332 and 119 distinct hits | no report; #8490 and #10135 the most relevant |
| Open apache/lucene PRs | 2026-10-26 | the changed files of all 408 open PRs | none touches the summary loop or SplittingBreakIterator |
| JIRA (LUCENE, SOLR, Hibernate), mailing lists, web | 2026-10-26 | 13 JQL queries, 23 list queries, 9 web queries | no report |
| Refresh: apache/lucene and apache/solr | 2026-10-29 | the same key terms plus highlighter items created since 2026-10-25 and Solr snippet-separator issues since 2026-10-01; apache/solr#5126 re-read | nothing new (#5126 merged 2026-10-27 with the same note) |
Present since the UnifiedHighlighter was added: LUCENE-7438 (722e82712435, 2016-10-04), first released in 6.3.0. Executed on 6.3.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main: affected everywhere. Not a regression, never fixed.
Versions tested6 rows
Introduced by LUCENE-7438 "UnifiedHighlighter" (now #8490): commit 722e82712435 on master and its branch_6x cherry-pick 4b6794368df, both 2016-10-04, by dsmiley. It added the whole uhighlight package, including all three pieces the bug needs: the summary loop, the two-sided SplittingBreakIterator.next() and the wrapping on (char) 0. The contribution PR apache/lucene-solr#79 was closed without a GitHub merge; the code was committed directly. Later edits to the loop (LUCENE-7559, LUCENE-8145, #16056) are cosmetic. At every release tag from 6.3.0 to 10.5.2 in the history clone the code is the same (read; 8.8.2 to 8.11.3 are not tagged there, so they are inferred from 8.8.1, read, and 8.11.4, executed); branch_10_6 has the same summary loop and iterator (read, not run).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the doc's JUnit fails 3 of 5 (gradle, assertions on and off, 3 seeds); the hunt's and the reproducer's tests fail |
| 10.5.2, 9.12.3, 9.1.0 | affected | the doc's JUnit fails 3 of 5; the hunt's fails 2 of 2 |
| 10.0.0, 9.0.0, 8.11.4, 7.7.3, 6.6.6 | affected | the hunt's JUnit (or its pre-9.1 port) fails 2 of 2 |
| 6.3.0 | first release | fails 2 of 2 with assertions on and off; passes with the fix applied to the 6.3.0 source |
| 6.2.1 | no UnifiedHighlighter | the API does not exist (the test does not compile) |
fix B / fix A on 645d4fe14a20 | not affected | the JUnit passes, and so do the 722 upstream highlighter tests |
An independent reproducer, reviews by a reviewer from another model family, a devil's advocate, an adjudication and a credibility audit re-ran or re-read it; every executed check reproduced it. This doc re-ran it through gradle on the latest main and validated two fixes.
Checks and verdicts402 words
Each check had a lens; the adjudication then re-ran both tests, the reproducer's with a new seed.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model review, refute lens | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: it votes not real without a run of its own. Root cause agrees, inputs in contract, intended case moderate; a separate re-run failed 2 of 2. |
| Independent reproducer | real | Its own JUnit, 3 offset sources, outside the uhighlight package: 3 of 4 fail on main (-ea, -da), 10.5.2 and 9.12.3; 30 of 30 bug cases with 10 iterations; main() variants fail on 8.11.4 and 6.3.0; 4 of 4 pass with the fix. |
| Cross-model review, intended lens | real (medium) | The same reviewer, reading only; a separate probe showed the separator with the sentence and whole-text iterators, with 2 and 3 values and an empty first value, and single-valued output unchanged by the fix. |
| Devil's advocate | real (medium-high) | Built the strongest works-as-designed case and rejected it; its probe showed that the default 1-passage call is hit only with an empty first value, and that a NUL-splitting consumer still loses a value. |
| Adjudication | confirmed (high), minor | Re-ran the reproducer's test with a new seed (-da, 3 of 4 fail) and the hunt's (-ea, 2 of 2 fail). |
| Follow-up and credibility audit | keep | History sweep over 9 releases and main, a security differential probe (none), a prior-art search (new); the audit re-ran the hunt's test on main and 10.5.2 and kept impact class minor. |
| This doc | reproduced; two fixes validated | Gradle on main 645d4fe14a20, stock and with fixes A and B; the hunt's and the reproducer's tests through the harness on 645d4fe14a20; the new test on 10.5.2, 9.12.3 and 9.1.0; a probe that found option A's problem with live-text iterators. |
| Fact checks of this doc | wording fixed; nothing refuted | An independent fact check (re-ran the gradle command, both fixes and the harness), a cross-model fact check by a reviewer from another model family (OpenAI GPT-5.6, reading only) and a diagram check. They found tagging and wording overclaims (releases run vs read, the observed-output excerpt, offset sources, 'one sentence fewer'), now fixed; a follow-up probe ran each offset source as its own test (6 of 6 fail on main, pass with fix B). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 529 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,550 words
- Registry title
- UnifiedHighlighter's no-match summary of a multi-valued field counts the internal U+0000 value separator as a passage, so the summary contains a NUL character and shows one value or sentence fewer than requested
- Area
- highlighter / UnifiedHighlighter default summary (FieldHighlighter.getSummaryPassagesNoHighlight over the SplittingBreakIterator that splits multi-valued fields on MULTIVAL_SEP_CHAR)
- Priority
- Low, rank 546: With default UnifiedHighlighter settings the no-match summary of a multi-valued field returns a NUL and one passage too few, ordinary data but display text only.
- Impact class
- minor
- Impact note
- Applications on any release from 6.3.0 through 10.6.0 (10.6.0 by reading) or on main that highlight a multi-valued stored field with the UnifiedHighlighter in its default configuration (default sentence BreakIterator, default maxNoHighlightPassages -1) get a wrong default summary for every hit with no match in that field whenever maxPassages (or maxNoHighlightPassages) is 2 or more and the leading passages reach a value boundary, or whenever the first value is empty (then even the default 1-passage call returns just U+0000): the snippet contains a raw U+0000 and one value or sentence fewer than requested; hits, scores and the index are unaffected, nothing throws, no index size is needed, and by code reading Elasticsearch and OpenSearch (which override the summary method) and Solr with its default hl.defaultSummary=false are not exposed.
- Summary
- You store two values in one field ('First value.' and 'Second value.'), run a query that matches the document but not that field, and ask the UnifiedHighlighter for 2 passages; you expect the documented default summary, the first 2 sentences from the field (for example 'First value.... Second value.', the way the highlight path joins values). Instead you get 'First value.\u0000': the highlighter joins the values with an internal U+0000 separator, its SplittingBreakIterator reports a boundary on both sides of that character, and FieldHighlighter.getSummaryPassagesNoHighlight turns the 1-character gap into a passage, so the NUL is returned and takes the second value's slot (3 passages give 'First value.\u0000Second value.'). With an empty first value even 1 passage returns just '\u0000'.
- Introduced
- 722e82712435ecf46c9868137d885484152f749b on master and its branch_6x twin 4b6794368df (LUCENE-7438 'New UnifiedHighlighter' by dsmiley, 2016-10-04; JIRA issue now GitHub #8490; the contribution PR apache/lucene-solr#79 by Timothy055 was closed without a GitHub merge, the code was committed directly) [read: git blame of the summary loop and of SplittingBreakIterator#next(), git log -G for the wrapping line, git tag --contains in the full-history clone; exec: the repro fails on 6.3.0, the first release with the API, and does not compile on 6.2.1, where the API is absent]. The commit added all three pieces the bug needs: the summary loop that makes a passage of every consecutive pair of boundaries, SplittingBreakIterator#next() reporting both sides of the separator, and UnifiedHighlighter wrapping every field iterator in a SplittingBreakIterator on MULTIVAL_SEP_CHAR = (char) 0. Later edits to the loop (LUCENE-7559 c51e89014ac, LUCENE-8145 9422609a5d4, #16056 dbf0d1426f1) are cosmetic. Not a regression (2016-10-04)
- First affected version
- 6.3.0 [exec] (first release with the UnifiedHighlighter, from branch_6x commit 4b6794368df; release commit a66a44513ee8, 2016-11-02); 6.2.1 has no org.apache.lucene.search.uhighlight package (the repro does not compile there) [exec]
- Affected versions
- every release with the UnifiedHighlighter, 6.3.0 through 10.6.0 (10.6.0 by reading), and main ea57360912ed [exec: the finder's JUnit, or its pre-9.1 port with identical test bodies, fails 2 of 2 on 6.3.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main, also with -da on 6.3.0, 9.0.0, 9.12.3, 10.5.2 and main; the independent reproduction's JUnit fails 3 of 4 on main (-ea, -da), 10.5.2 and 9.12.3, and its main() variants fail on 8.11.4 and 6.3.0; read: at every release tag from 6.3.0 to 10.5.2 the wrapping, the (char) 0 separator and the summary loop without a separator check are present, and SplittingBreakIterator#next() is identical after whitespace normalisation (8.8.2 to 8.11.4 are not tagged in the history clone; 8.11.4 was executed)]; not affected: releases up to 6.2.1, which have no UnifiedHighlighter [exec]; not fixed upstream [read, not executed: at upstream main a9779ef3c193 the last commit on FieldHighlighter.java is dbf0d1426f13 (#16056) and on SplittingBreakIterator.java 6faa4f98e048 (2020), and no open PR touches the summary loop or the separator handling]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (2026-10-26, the prior-report record, plus the finder's run: three runs of the scripted prior-report search (45, 51 and 45 queries over apache/lucene issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web; 243, 332 and 119 distinct hits, none this bug); 53 manual GitHub searches over apache/lucene, apache/lucene-solr, apache/solr, elastic/elasticsearch, opensearch-project/OpenSearch, hibernate/hibernate-search and apache/lucenenet; the changed files of all 408 open apache/lucene PRs; 13 JIRA queries (SOLR, LUCENE) plus the Hibernate JIRA; 23 list queries; 9 web queries; 16 hits classified, all same_bug false); not fixed upstream (read, not executed: upstream main a9779ef3c193, no CHANGES entry, no open PR touches the code); closest items, not reports: apache/solr#5126 (open, by dsmiley, 2026-10-13: notes that with hl.method=unified multi-valued fields can return a leading empty snippet because Lucene's value separator and Solr's snippet separator are both U+0000; an executed emulation shows that their example needs LengthGoalBreakIterator on the match path, the sibling candidate's code, not this summary loop), the Elasticsearch and OpenSearch CustomFieldHighlighter override of getSummaryPassagesNoHighlight (a downstream workaround in code from 2017; no issue or PR text describes the Lucene defect), and #8490 / LUCENE-7438 (the introduction: 'a passage will never span across values')
- Lucene commit tested
- main
645d4fe14a20(2026-10-28) through gradle in a scratch worktree (removed afterwards), seeds DEADBEEF, 5E9A0498 and C0FFEE150, assertions on and off: stock, the 5-test JUnit fails 3 of 5 (its 2 controls pass); with fix B and, separately, fix A it passes, together with everyuhighlighttest class (470 upstream tests) and all of:lucene:highlighter:test(722 upstream tests), and:lucene:highlighter:check -x testpasses with the repro added. Through the repro harness: the new JUnit on 10.5.2, 9.12.3 and 9.1.0 (3 of 5 fail each); the hunt's and an independent reproducer's JUnit on645d4fe14a20, stock (fail) and with fix B (pass); a probe with one test per offset source (re-analysis, postings offsets, term vectors) on645d4fe14a20, 6 of 6 fail with assertions on and off and pass with fix B. The hunt, its checks and the history sweep ran on mainea57360912ed, whose highlighter module is identical, and on 6.3.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0 and 10.5.2. OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/FieldHighlighter.java:88-94 (at ea57360912ed) (no passages -> getSummaryPassagesNoHighlight(maxNoHighlightPassages == -1 ? maxPassages : maxNoHighlightPassages)), :104-108 (javadoc: 'By default this just returns the first maxPassages sentences'), :109-128 (summary loop: a Passage for every consecutive pair of breakIterator.next() boundaries, no separator check)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/SplittingBreakIterator.java:23-31 (at ea57360912ed) (class javadoc: slices 'on both sides of every occurrence'; 'the enclosed BreakIterator will never "see" the splitting character'; @lucene.experimental), :103-124 (next(): end of value k, then sliceStartIdx = sliceEndIdx + 1, the start of value k+1)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:98 (at ea57360912ed) (MULTIVAL_SEP_CHAR = (char) 0), :634-639 (getMaxNoHighlightPassages javadoc: 'the number of leading passages (as delineated by the BreakIterator)', default -1 = maxPassages), :742-748 (highlight(field, query, topDocs) = maxPassages 1, 'the first sentence'), :759-761 (highlight(..., maxPassages): 'the first maxPassages sentences from the field will be returned'), :1135 (every field iterator wrapped in new SplittingBreakIterator(getBreakIterator(field), MULTIVAL_SEP_CHAR)), :1410 and :1463 (LimitedStoredFieldVisitor appends the separator between stored values)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/DefaultPassageFormatter.java:66-68 (at ea57360912ed) (no ellipsis between connected passages, so the separator passage is copied verbatim); lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/TestUnifiedHighlighter.java:339 (testMaxLengthWithMultivalue asserts value + '... ' + value on the highlight path)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:98, :1135, :1410, :1463a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/SplittingBreakIterator.java:24-28 (class javadoc), :104-124 (next), :114a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/FieldHighlighter.java:89-94 (summary call), :104-108 (javadoc), :109-128 (summary loop), :178-182 (highlight path passage start via preceding)a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/DefaultPassageFormatter.java:39-40 (default ellipsis), :66-68 (no ellipsis between touching passages)a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/TestSplittingBreakIterator.java:58-60; TestUnifiedHighlighter.java:759, :823, :858 (single-valued summary tests)
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:94 (@lucene.experimental), :116 (default -1), :401 (withMaxNoHighlightPassages), :1143-1161 (newFieldHighlighter); FieldHighlighter.java:32 (@lucene.internal)a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:100 (DEFAULT_MAX_LENGTH 10000), :1446-1452 (maxLength budget in LimitedStoredFieldVisitor)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:635-638 (getMaxNoHighlightPassages javadoc), :742, :759-761, :1463a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/SplittingBreakIterator.java:24-31a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/TestUnifiedHighlighter.java:339; TestUnifiedHighlighterMTQ.java:1139; TestSplittingBreakIterator.java:58-60
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/FieldHighlighter.java:96-100, :109-128, :178-182; SplittingBreakIterator.java:59-64; UnifiedHighlighter.java:1143-1161
- History
a Lucene clone origin/branch_10_6 4ae946e5a9b9 (git diff against 645d4fe14a20 over the four uhighlight files: cosmetic only)
- TestUHSummaryMultiValueSeparator.java (JUnit test):
repro/LFV-498/src/org/apache/lucene/search/uhighlight/TestUHSummaryMultiValueSeparator.java(60 lines)
A summary still (bug.png) from the user's call to the joined string, the boundaries, the summary loop, expected vs actual, and the fix. Values and line numbers come from the code at 645d4fe14a20 and an executed probe.
assets/LFV-498/bug.png(529 KB)