ProtectedTermFilterFactory applies other filters to every token that is not protected. In its wrappedFilters form it builds those filters itself and never passes them its luceneMatchVersion, so, unless one is given its own filterName.luceneMatchVersion, they behave like the newest version even when you pin an older one.
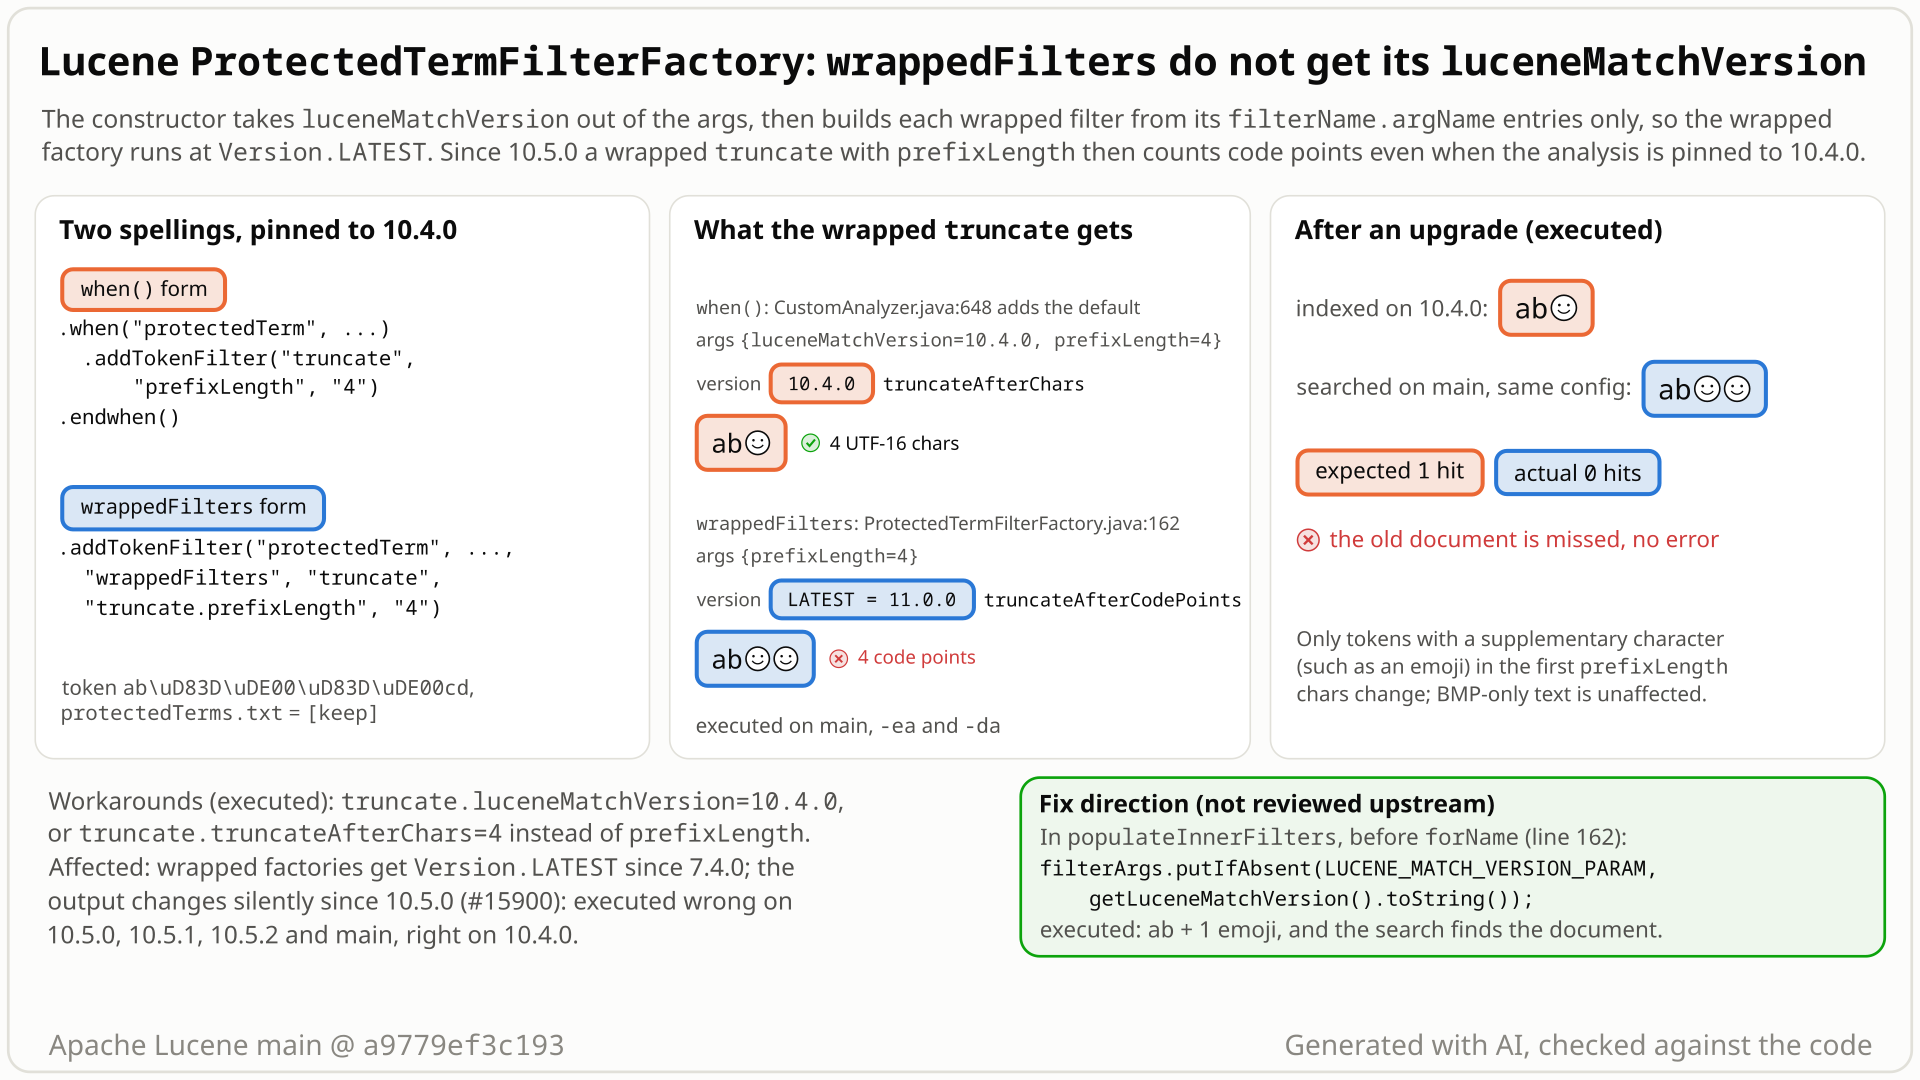
when() form the version reaches truncate and ab😀😀cd becomes ab😀; in the wrappedFilters form the version is dropped, ab😀😀 comes out, and a document indexed on 10.4.0 is no longer found. Select the still to open it at full size. Generated with AI, checked against the code.- You index on Lucene 10.4.0 with
ProtectedTermFilterFactory,wrappedFilters=truncateandtruncate.prefixLength=4(the shape of the class javadoc's Solr example). The tokenab😀😀cd(8 UTF-16 chars, 6 code points) is indexed asab😀, its first 4 UTF-16 chars. - You upgrade to 10.5 or later and pin
luceneMatchVersion=10.4.0, the documented way to keep old analysis. For the deprecatedprefixLength, a version below 10.5 means "count UTF-16 chars"; 10.5 and later count code points. - You expect the query
ab😀😀cdto analyse toab😀again, as the sametruncatedoes on its own or insideCustomAnalyzer'swhen()/endwhen(), and to find the document: 1 hit. - You get
ab😀😀, the first 4 code points, and 0 hits, with no error. The factory reports version 10.4.0, but it builds each wrapped filter from itstruncate.*arguments only, so the wrappedtruncateruns as the latest version. - Only tokens with an emoji or another supplementary character in the first
prefixLengthchars change. Workarounds: addtruncate.luceneMatchVersion=10.4.0, or usetruncateAfterChars=4.
Users of the wrappedFilters form (factory arguments, Solr-style schemas, or CustomAnalyzer.addTokenFilter("protectedTerm", ...)) on 10.5 or later who pin luceneMatchVersion below 10.5 and wrap truncate with prefixLength or no length. Tokens with an emoji in the prefix get different terms, so queries miss documents indexed the legacy way. Opt-in and rare.
Mechanism, terms and numbers607 words
ProtectedTermFilterFactory runs other filters on every token that is not protected. You can name them with CustomAnalyzer's when()/endwhen() or with the factory's own wrappedFilters and filterName.argName parameters (the Solr-style spelling); the class javadoc shows both, each wrapping truncate prefixLength=4. In the wrappedFilters form the factory builds each wrapped filter from the filterName.* arguments only, and its own luceneMatchVersion, already consumed by AbstractAnalysisFactory, is never passed on, so every wrapped factory without its own filterName.luceneMatchVersion runs at Version.LATEST. Since 10.5.0 (#15900) truncate's deprecated prefixLength keeps N UTF-16 chars below version 10.5 and N code points from 10.5, so with luceneMatchVersion=10.4.0 the token ab😀😀cd becomes ab😀 unwrapped and in the when() form, but ab😀😀 in the wrappedFilters form. A document indexed on 10.4.0 with this configuration is found by the when() form on main (1 hit) but not by the wrappedFilters form (0 hits). The missing forwarding is in every release since 7.4.0; with stock filters it silently changes terms since 10.5.0. A one-line putIfAbsent in populateInnerFilters fixes it; the analysis module's tests pass with it.
luceneMatchVersion: every analysis factory reads it from its arguments (AbstractAnalysisFactory) and usesVersion.LATESTwhen there is none. Pinning it to an older version keeps that version's analysis after an upgrade.CustomAnalyzer.Builder.withDefaultMatchVersionadds it to every factory it builds.- Two spellings of a protected chain:
CustomAnalyzer.builder()...when("protectedTerm", ...)+addTokenFilter("truncate", "prefixLength", "4")+endwhen(), or one factory withwrappedFilters=truncateandtruncate.prefixLength=4(the Solr-style spelling). The class javadoc shows both (ProtectedTermFilterFactory.java:38-61). truncate prefixLength(deprecated): since 10.5.0 (#15900) it keeps N UTF-16 chars when the version is below 10.5 and N code points from 10.5 (TruncateTokenFilterFactory.java:93-97). With no length parameter at all it takes the same path with N = 5 (:81-82).
- The constructor's
super(args)takesluceneMatchVersionout of the argument map into the factory's own field (AbstractAnalysisFactory.java:94-109). handleWrappedFilterArgsmakes a fresh map per wrapped filter and moves only thefilterName.argNameentries into it (ProtectedTermFilterFactory.java:116-152).populateInnerFilterscallsTokenFilterFactory.forName(filterName, filterArgs)with that map (:154-165, the call at:162). Unless the configuration gave that filter its ownfilterName.luceneMatchVersion, the map has no version, so the wrapped factory takesVersion.LATEST(AbstractAnalysisFactory.java:98-99).- The
when()form does not have this gap:ConditionBuilder.addTokenFilteradds the default version to each wrapped filter (CustomAnalyzer.java:646-650, throughapplyDefaultParams,:596-602).
| configuration | expected (legacy) | actual |
|---|---|---|
truncate prefixLength=4 on its own | ab😀 | ab😀 |
the same inside when("protectedTerm", ...)/endwhen() | ab😀 | ab😀 |
wrappedFilters=truncate, truncate.prefixLength=4 (through CustomAnalyzer or the factory API) | ab😀 | ab😀😀 |
the javadoc's Solr example (truncate,lowercase, ignoreCase) on AB😀😀CD | ab😀 | ab😀😀 |
wrapped truncate with no length (5) | ab😀 + lone high surrogate (5 chars) | ab😀😀c (7 chars) |
workaround truncate.luceneMatchVersion=10.4.0, or truncateAfterChars=4 | ab😀 | ab😀 |
BMP-only token abécdef | abéc | abéc |
Token ab😀😀cd = 8 UTF-16 chars, 6 code points. The legacy no-length result splits a surrogate pair: that is the pre-10.5 behaviour the pinned version asks for. The table shows the analyzer's term text; when such a term is indexed, the UTF-16 to UTF-8 conversion writes the lone surrogate as U+FFFD, so an index built before 10.5 holds ab😀 followed by U+FFFD for that token (CharTermAttributeImpl.java:92-94, UnicodeUtil.java:172-176). The same on 10.5.2. Upgrade scenario: one document written with the 10.4.0 jars and this configuration holds the term ab😀; searching it on 10.5.2 or main with the same configuration finds 0 hits in the wrappedFilters form and 1 in the when() form (1 and 1 with the fix).
Exposure and likelihood265 words
- Who is exposed. The
wrappedFiltersform ofProtectedTermFilterFactory(SPI nameprotectedTerm): factory arguments, Solr-style schemas, orCustomAnalyzer.addTokenFilter("protectedTerm", ..., "wrappedFilters", ...). Thewhen()/endwhen()form is not affected. - What it takes. Lucene 10.5.0 or later,
luceneMatchVersionpinned below 10.5.0, a wrappedtruncatewith the deprecatedprefixLength(or no length parameter), and a supplementary character (emoji, many CJK extension characters) in the firstprefixLengthchars of a token that is not protected. - What changes. Such tokens get the 10.5+ code-point prefix (at most
2 * prefixLengthchars) instead of the pinned legacy one. Queries miss documents indexed with the legacy analysis (before an upgrade, or by thewhen()form): 0 hits instead of 1 in the upgrade probe. Mixed index generations analyse the same text differently. No error and no exception; the extra work is bounded (the code-point branch scans at mostprefixLengthcode points,TruncateTokenFilter.java:97-112). - What does not change. BMP-only text, protected terms, unpinned configurations, versions pinned to 10.5.0 or later, and the
when()form. - Beyond truncate. On main,
truncateis the only stock factory whose output reads the version, but any application factory used insidewrappedFiltersthat readsluceneMatchVersionhas receivedVersion.LATESTsince 7.4.0, unless it was given its ownfilterName.luceneMatchVersion. From 8.4.0 to 9.12.3 the only stock consequence was loud: a wrappedconcatenateGraphrejectedpreserveSepunder a version below 8.4.0. - How likely. Rare: each ingredient is ordinary (the class javadoc's Solr example is this configuration, and pinning the version is how users keep an old index after an upgrade), but all together they are uncommon in direct Lucene use today.
The test shows that ProtectedTermFilterFactory with luceneMatchVersion=10.4.0, wrappedFilters=truncate and truncate.prefixLength=4 builds the wrapped truncate at Version.LATEST, so it truncates by code points instead of the legacy UTF-16 chars.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import org.apache.lucene.analysis.TokenFilterFactory;
import org.apache.lucene.tests.analysis.BaseTokenStreamFactoryTestCase;
import org.apache.lucene.tests.util.StringMockResourceLoader;
import org.apache.lucene.util.Version;

public class TestProtectedTermWrappedFiltersMatchVersion extends BaseTokenStreamFactoryTestCase {

  public void testWrappedTruncateUsesFactoryMatchVersion() throws Exception {
    TokenFilterFactory factory =
        tokenFilterFactory(
            "protectedTerm",
            Version.LUCENE_10_4_0,
            new StringMockResourceLoader("protectedword"),
            "protected", "protected.txt",
            "wrappedFilters", "truncate",
            "truncate.prefixLength", "4");
    // expected (10.4.0 prefixLength = 4 UTF-16 chars): "ab" + 1 emoji; actual (LATEST = 4 code points): "ab" + 2 emoji
    assertTokenStreamContents(
        factory.create(whitespaceMockTokenizer("ab😀😀cd")),
        new String[] {"ab😀"});
  }
}
# in a copy of this finding's repro folder (repro/LFV-510/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestProtectedTermWrappedFiltersMatchVersion
- Expected vs actual
- Expected the token
ab😀😀cdto becomeab😀(4 UTF-16 chars, the 10.4.0 behaviour); actualab😀😀(4 code points), with-eaand-da.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: term 0 expected:<ab😀[]> but was:<ab😀[😀]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:689)
org.apache.lucene.analysis.miscellaneous.TestProtectedTermWrappedFiltersMatchVersion.testWrappedTruncateUsesFactoryMatchVersion(TestProtectedTermWrappedFiltersMatchVersion.java:36)withDefaultMatchVersionpasses the version "as default to all tokenizers or filters"; thewhen()form gives it to the same wrappedtruncate.prefixLengthis kept "for backwards compatibility" and "depends on the luceneMatchVersion parameter"; #15900's review: "Old indexes and schemas then use old behaviour".- The Synonym factories forward their version to their tokenizer factory; SOLR-4251 fixed a similar defect in 2013.
The full argument325 words
- CustomAnalyzer's contract.
withDefaultMatchVersion's javadoc: "This match version is passed as default to all tokenizers or filters. It is used unless you pass the parameter {code luceneMatchVersion} explicitly." (CustomAnalyzer.java:242-243, verbatim;{code ...}is a malformed tag in the source). The wrappedtruncateis a filter of that analyzer and does not get it; in thewhen()form it does (:648).TestCustomAnalyzer.testVersionAwareFilter(:111-127) checks that version-aware filters receive the default; it checks a top-level filter only, not a filter insidewhen()orwrappedFilters. - truncate's back-compat purpose.
prefixLength"is still supported" "for backwards compatibility" and "its behaviour depends on the luceneMatchVersion parameter" (TruncateTokenFilterFactory.java:32-37). In the #15900 review, uschindler wrote "Old indexes and schemas then use old behaviour". Pinning the version is how a schema keeps the old terms; thewrappedFilterspath defeats it. - The two spellings disagree. The class javadoc shows the
when()form and thewrappedFiltersform next to each other, both wrappingtruncate prefixLength=4; under the same pinned version they give different terms (the two examples also differ in tokenizer and in how they name the factory; the repro removes those differences). The javadoc does not call them equivalent, and nothing promises that wrapped filters inherit the version. - Precedent. SOLR-4251 (fixed in 4.1, 2013):
SynonymFilterFactory's delegate "is not propagating the LUCENE_MATCH_VERSION"; its fix (a973191f2de) forwarded the version to the delegate. Today both Synonym factories forward their version to the tokenizer factory they build, through lines from later commits (SynonymFilterFactory.java:112, SOLR-4813, 2013;SynonymGraphFilterFactory.java:109, LUCENE-6664, 2016). They put the version first and then copy thetokenizerFactory.*arguments, so an explicittokenizerFactory.luceneMatchVersionstill wins (executed): the same semantics as the recommendedputIfAbsentfix. - Nothing pins the current behaviour. The introducing commit and the 87 comments of #9320 never mention the version.
TestProtectedTermFilterFactorywrapstruncate.prefixLength(testMultipleWrappedFiltersWithParams,:83-99), but only with ASCII text atVersion.LATEST. #15900 never mentionsProtectedTermFilterFactory.
The devil's-advocate check238 words
The checkers built the strongest case for "works as designed": (a) no javadoc line says wrapped filters inherit the version; (b) luceneMatchVersion is an ordinary factory argument, so truncate.luceneMatchVersion=10.4.0 is a valid filterName.argName setting, and it works; (c) each component meets its own contract read literally (AbstractAnalysisFactory defaults to LATEST, CustomAnalyzer does pass the version to the factory it builds, truncate follows the version it gets); (d) prefixLength is deprecated, and truncateAfterChars (a parameter since 10.5.0) gives the legacy result at any luceneMatchVersion.
Why it fails: no documentation mentions filterName.luceneMatchVersion for wrapped filters (the class javadoc describes filterName.argName in general), and Solr fills in the schema's default version for every factory that does not set its own, so users normally set it once per schema; withDefaultMatchVersion promises the version to "all tokenizers or filters", and the when() form delivers it; #15900 kept prefixLength so that pinned schemas keep their old terms; the Synonym factories pass their version on to the tokenizer factory they build, and SOLR-4251 fixed the same kind of defect in 2013 by forwarding the version. No test, commit or PR says the gap is deliberate. The strongest remaining reading is that withDefaultMatchVersion covers only the factories CustomAnalyzer builds itself; the when() form and the Synonym factories show that Lucene otherwise passes the version on to child factories. The remaining pushback is about severity (narrow), not validity. Every checker rejected the works-as-designed case.
Recommended Forward the factory's version to each wrapped filter, unless it has its own
Forward the version: in populateInnerFilters, call filterArgs.putIfAbsent(LUCENE_MATCH_VERSION_PARAM, getLuceneMatchVersion().toString()) before TokenFilterFactory.forName(...). An explicit truncate.luceneMatchVersion still wins, and unpinned configurations are unchanged. Validated: the new tests, the closest suites, all analysis-module tests and check pass.
           if (idSuffixPos != -1) { // Strip '-id' suffix, if any, prior to SPI lookup
             filterName = filterName.substring(0, idSuffixPos);
           }
+          // wrapped filters use this factory's luceneMatchVersion, unless they were given their own
+          // (filterName.luceneMatchVersion)
+          filterArgs.putIfAbsent(LUCENE_MATCH_VERSION_PARAM, getLuceneMatchVersion().toString());
           innerFilters.add(TokenFilterFactory.forName(filterName, filterArgs));
All options and trade-offs4 options · 666 words
The recommended fix was applied in a scratch worktree of main a9779ef3c193 and run through gradle with assertions on and off; the worktree was removed afterwards. A put variant was run to check that the new guard test catches it.
Forward the factory's version to each wrapped filter, unless it has its own (validated by the checks) (recommended)
In populateInnerFilters (ProtectedTermFilterFactory.java:154-165), before forName, add the outer factory's version to each wrapped filter's arguments with putIfAbsent, as CustomAnalyzer does for the when() form (applyDefaultParams, CustomAnalyzer.java:599) and as the Synonym factories in effect do for their tokenizer factory (version first, then the tokenizerFactory.* arguments, so an explicit per-tokenizer version wins). +3 lines, 2 of them comments. It is the hunt's sketch with a different comment.
New output. Every row of the table equals the when() form: ab😀 for prefixLength=4 and the javadoc's Solr example, the legacy 5-char result with no length; the workarounds and the unpinned configuration are unchanged; the upgrade probe finds the 10.4.0 document (1 hit).
           if (idSuffixPos != -1) { // Strip '-id' suffix, if any, prior to SPI lookup
             filterName = filterName.substring(0, idSuffixPos);
           }
+          // wrapped filters use this factory's luceneMatchVersion, unless they were given their own
+          // (filterName.luceneMatchVersion)
+          filterArgs.putIfAbsent(LUCENE_MATCH_VERSION_PARAM, getLuceneMatchVersion().toString());
           innerFilters.add(TokenFilterFactory.forName(filterName, filterArgs));
Trade-offs
- A configuration pinned below 10.5 that ran on 10.5.0-10.5.2 indexed code-point terms for affected tokens; after the fix it produces the legacy terms again, so such an index needs a reindex, or the user keeps the code points with
truncate.luceneMatchVersion=10.5.0ortruncateAfterCodePoints; that only avoids a reindex when all affected terms were written on 10.5.0-10.5.2, and an index that mixes pre-10.5 and 10.5.x terms needs a reindex either way. Worth a CHANGES line (none drafted). - An application factory inside
wrappedFiltersthat readsluceneMatchVersionnow sees the configured version instead ofLATEST: the point of the fix, but a behaviour change since 7.4.0. - The wrapped factories'
getOriginalArgs()now includeluceneMatchVersion; the wrapped factories are not reachable from outside (ConditionalTokenFilterFactory.innerFiltersis private).
What the checks validated
- The 5 new tests and the closest upstream suites (
TestProtectedTermFilterFactory,TestProtectedTermFilter,TestTruncateTokenFilterFactory,TestTruncateTokenFilter,TestConditionalTokenFilter,TestCustomAnalyzer) pass with assertions on and off: 59 of 59; stock: the 2 bug tests fail. - All of
:lucene:analysis:common:testwith assertions on: 340 classes, 1,914 tests, 18 skipped, 0 failures. :lucene:analysis:common:check -x testpasses (google-java-format, ecjLint, forbiddenApis).- Through the repro harness with the fix shadowed: the new test 5 of 5; the hunt's runs of the same line: the finder's JUnit 4 of 4, the reproducer's 6 of 6, and the version-neutral history probe on 7.4.0 and main.
- The module-wide run used the test file before a comment-only javadoc reflow (the first
checkflagged only that); the final file then ran withcheckand the six suites (assertions on). - Coverage gap: no dedicated test covers a wrapped filter with an
-idsuffix or a conditional factory nested inwrappedFilters; the fact check's probe ran atruncate-xchild, which gets 10.4.0 with the fix and 11.0.0 without it.
Uses an unconditional put after the per-filter arguments are collected (the Synonym factories also call put, but before they copy the tokenizerFactory.* arguments, so an explicit per-tokenizer version still wins there).
Trade-offs
So it overrides an explicit truncate.luceneMatchVersion with the outer version, which breaks the filterName.argName mechanism for this one argument. With it the guard test testWrappedFilterOwnVersionWins fails (expected:<ab😀[😀]> but was:<ab😀[]>), the other 4 pass.
Document that wrapped filters need filterName.luceneMatchVersion, and point to truncateAfterChars / truncateAfterCodePoints.
Trade-offs
Leaves withDefaultMatchVersion's "all tokenizers or filters" broken and the two spellings inconsistent; not validated.
A small protected helper (for example in AbstractAnalysisFactory) that copies the version into a child factory's arguments, used by ProtectedTermFilterFactory and the Synonym factories.
Trade-offs
A broader API change for a one-line bug; only if a reviewer asks. Not validated.
Solr passes its schema's luceneMatchVersion to every factory that does not set its own, and its reference guide shows exactly this wrappedFilters="truncate,lowercase" truncate.prefixLength="4" configuration, so pinned Solr schemas would be affected once Solr moves to Lucene 10.5 (read, not run in Solr).
Code reading: while checking how analysis factories pass their arguments to the factories they create, a finder saw that ProtectedTermFilterFactory builds its wrapped filters without its luceneMatchVersion, and that truncate is the one stock filter whose output depends on it. A public-API JUnit confirmed it; independent checkers followed.
The method in full92 words
- Method (non-formal): code reading in the hunt's unit on analysis factory/constructor equivalence: every place that builds an inner analysis factory (
forName,getConstructor(Map.class)insrc/java) was read while modelling how factory arguments reach constructors.luceneMatchVersionis the one argumentAbstractAnalysisFactoryconsumes for every factory, andTruncateTokenFilterFactory(since #15900) is the one stock factory whose output depends on it. - Confirmation. A public-API JUnit comparing the
wrappedFiltersform with thewhen()form and an unwrappedtruncate(2 of 4 fail on main and 10.5.2, assertions on and off), then the checks below.
No prior report found (searched 2026-10-26, about 318 logged queries over GitHub issues, PRs and commits, JIRA, the Lucene and Solr lists, downstream repositories and the web, plus a changed-file scan of all 408 open PRs). Closest: SOLR-4251 (2013), the same kind of defect in SynonymFilterFactory, fixed there.
Searches4 searches
No hit describes this bug. #9320 / LUCENE-8273 introduced the code; #15900 made it visible and never mentions ProtectedTermFilterFactory; SOLR-4251 is a precedent for the fix, not a report. Keyword search only; GitHub's search rate limit caused many HTTP 403s (every query was retried to completion); 22 planned web queries were not run; for non-analysis open PRs only the first 100 changed files were checked; private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (five term variants) | 2026-10-26 | 72 apache/lucene issue and PR queries, 15 commit, 10 downstream, 19 JIRA and 96 mailing-list queries; 11 web queries | no report |
| GitHub (manual) and open PRs | 2026-10-26 | 15 apache/lucene and 6 downstream queries (apache/solr, apache/lucene-solr, Elasticsearch, OpenSearch); all 408 open apache/lucene PRs by changed file (full file lists for the 16 labelled module:analysis, the first 100 changed files of the other 392) | no report; the only open PR touching the file (#16911) deletes branch_10x |
| ASF JIRA (LUCENE, SOLR) and lists.apache.org | 2026-10-26 | 18 REST JQL queries; about 40 list-archive queries over dev@, java-user@, issues@, commits@ and the Solr lists | no report; SOLR-4251 (the same defect class in SynonymFilterFactory, fixed in 4.1) |
| Closest items (read in full) | 2026-10-26 | comment threads and review comments | #9320 / LUCENE-8273 (87 comments, no match-version discussion), #15900 and #15899 (back-compat intent, no mention of protected or wrapped filters), SOLR-4251, #10061 / LUCENE-9018, #9418 / #9423 |
The missing forwarding came with wrappedFilters in d91273ddf0b (LUCENE-8273, 2018, 7.4.0). It first changed terms silently with stock filters in 10.5.0, when #15900 made truncate prefixLength depend on the version. Wrong on 10.5.0, 10.5.1, 10.5.2 and main; right on 10.4.0; not fixed upstream.
Versions tested7 rows
Introduced by d91273ddf0b (master, 2018-05-20, Steve Rowe, "LUCENE-8273: ... Allow ProtectedTermFilterFactory to be used outside of CustomAnalyzer, including in Solr, by allowing wrapped filters and their parameters to be specified on construction"; branch_7x backport 97490ac7c66), committed from a JIRA patch. It added wrappedFilters, filterName.argName and populateInnerFilters; since then only the 2020 reformat (8ef6a0da568) touched the line.
Made silent by #15900 (fixes #15899; 86ba05a5982 on main, b858e81d1be on branch_10x, merged 2026-04-06, 10.5.0), which made truncate prefixLength depend on the version. #15900 itself is correct. From 8.4.0 to 9.12.3 the only stock consequence was loud (a wrapped concatenateGraph rejected preserveSep).
Not fixed upstream. Upstream main's file (re-read 2026-10-26) is identical; branch_10x and branch_10_6 lack the forwarding; no CHANGES entry.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | new test 2 of 5 fail through gradle (assertions on and off) and the repro harness |
| 10.5.0, 10.5.2 | affected | new test 2 of 5 fail; upgrade probe on 10.5.2: 0 hits instead of 1 |
| 10.5.1 | affected | the finder's JUnit: 2 of 4 fail |
| 7.4.0 to 10.4.0 (run: 7.4.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.4.0) | defect, no silent stock effect | the pass-through probe: the wrapped factory gets the release's LATEST, not the configured version; the symptom tests pass on 10.4.0 and 9.12.3 (truncate is not version-dependent before 10.5) |
| 8.4.0, 8.11.4, 9.12.3 | fails loudly | wrapped concatenateGraph with preserveSep under a version below 8.4.0: "Unknown parameters" (unwrapped accepts it) |
| 7.3.1 | no such API | ProtectedTermFilterFactory does not exist |
fix on main a9779ef3c193 | not affected | new test 5 of 5, the six closest suites 59 of 59 (assertions on and off), all analysis-module tests and check pass |
An independent reproducer (own 6-test JUnit), an intended-behaviour devil's advocate, an adjudication and a credibility audit judged it real and re-ran it; a reviewer from another model family, reading only, agreed, and its refute pass said "not real" only because it could not run code.
Checks and verdicts281 words
Every verdict below that re-ran a repro did so on main ea57360912ed, whose analysis module is identical to a9779ef3c193; the reading-only cross-model reviews were followed by a separate re-run of the repro (fails). This doc's own test and fix validation ran on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model review | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: root cause and fix agreed, trigger legal, intended-behaviour argument weak. |
| Cross-model refute review | not real (low), procedural | The same reviewer family with a refute lens, reading only: it needs an executed repro of its own, so it could not say "real"; it called this "not an affirmative technical refutation" and said the static evidence "strongly favors the report". A separate run re-ran the repro (2 of 4 fail); a cross-check JUnit fails 1 of 4 (the claim), its 3 controls pass. |
| Independent reproducer | real | Own public-API JUnit written from the claim: 2 of 6 fail on main (assertions on and off), 10.5.0 and 10.5.2; 6 of 6 pass on 10.4.0 and 9.12.3; 4 controls pass; its own copy of the one-line fix passes 6 of 6. |
| Intended-behaviour devil's advocate | real (moderate-high) | Built the strongest works-as-designed case and rejected it; re-ran the finder's JUnit (2 of 4 fail on main and 10.5.2); its characterisation test shows both workarounds give the legacy result. |
| Adjudication | confirmed (high) | Re-ran the reproducer's JUnit with assertions on and off (2 of 6 fail, same wrong token). |
| Credibility audit | keep | Re-ran the finder's JUnit (fails on main and 10.5.0, passes with the fix), re-read the code, upheld the impact class. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 456 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,387 words
- Registry title
- ProtectedTermFilterFactory does not pass its luceneMatchVersion to the filters it builds from wrappedFilters, so since 10.5 a wrapped truncate with prefixLength under a pinned pre-10.5 version truncates by code points instead of the legacy UTF-16 chars
- Area
- analysis / common miscellaneous (ProtectedTermFilterFactory#populateInnerFilters: wrappedFilters factory construction; symptom in TruncateTokenFilterFactory prefixLength)
- Priority
- Low, rank 496: Silent analysis drift only for the wrappedFilters form of ProtectedTermFilterFactory with a pinned pre-10.5 version, a wrapped prefixLength truncate and supplementary characters.
- Impact class
- silent wrong results
- Impact note
- Narrow, opt-in configuration only: analyzers that use ProtectedTermFilterFactory's wrappedFilters form (factory args, Solr-style schemas, or CustomAnalyzer.addTokenFilter("protectedTerm", ..., "wrappedFilters", ...); the when()/endwhen() form is not affected) on Lucene 10.5.0 or later, with luceneMatchVersion pinned below 10.5.0 and a wrapped truncate that uses the deprecated prefixLength (by reading, also truncate with no length parameter); then tokens with supplementary characters such as emoji inside the prefix keep prefixLength code points instead of prefixLength UTF-16 chars, so terms differ from the pinned legacy analysis (missed matches against segments indexed before the upgrade, mixed analysis across index generations) with no error; BMP-only text is unaffected, no scale is needed, and truncate.luceneMatchVersion=<version> or truncateAfterChars are workarounds.
- Summary
- You configure ProtectedTermFilterFactory with wrappedFilters=truncate and truncate.prefixLength=4 and pin luceneMatchVersion to 10.4.0 (in the factory args, or through CustomAnalyzer.withDefaultMatchVersion), on Lucene 10.5 or later. You expect the wrapped truncate to keep the legacy behaviour that the pinned version selects for back-compat, the first 4 UTF-16 chars, as an unwrapped truncate and the equivalent when()/endwhen() form do under the same version. Instead populateInnerFilters builds the wrapped factory from the 'truncate.*' arguments only, so it runs at Version.LATEST and keeps 4 code points: the token 'ab😀😀cd' becomes 'ab😀😀' instead of 'ab😀', with no error.
- Introduced
- d91273ddf0b524e14ebcc2a90bbedd8d9ae319d4 (master) and its branch_7x backport 97490ac7c66313625c9526a466ab96981e249746, LUCENE-8273 (#9320 'Add a ConditionalTokenFilter'; JIRA-era patch, no GitHub PR; author sarowe), which added the wrappedFilters / filterName.argName parameters and populateInnerFilters [read: git log -L on populateInnerFilters shows only this commit and the LUCENE-9570 reformat 8ef6a0da568; all 58 local release tags 7.4.0-10.5.2 have the same forName(filterName, filterArgs) call and never mention a match version] [exec: a version-neutral probe fails on 7.4.0 and passes with the one-line fix there; 7.3.1 lacks the API]. The silent symptom with stock filters was enabled by #15900 (fixes #15899; 86ba05a598257883b4494307cae7ca00d0fb2d4d on main, b858e81d1be5ae9737e76c17fd1cb35a2c4e5222 on branch_10x; merged by msokolov, co-authored by uschindler), which made truncate prefixLength depend on luceneMatchVersion; #15900 itself is correct (2018-05-20 (defect, d91273ddf0b); 2026-04-06 (#15900 merged, which made it silently change output))
- First affected version
- 7.4.0 for the defect (wrapped factories get Version.LATEST) [exec]; 10.5.0 for silent wrong analysis with stock Lucene filters (wrapped truncate prefixLength) [exec]; last release without the silent symptom 10.4.0 [exec]
- Affected versions
- defect in every release from 7.4.0: 7.4.0-7.7.3, 8.0.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.6.0 (10.6.0 by reading) and main ea57360912ed [exec: version-neutral probe with a pass-through factory that records its luceneMatchVersion fails on 7.4.0 (-ea and -da), 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.4.0, 10.5.0, 10.5.1, 10.5.2 and main, all 3 controls pass, and it passes with the fix on 7.4.0 and main; 7.3.1 has no such API]. Silent wrong analysis with stock filters only in 10.5.0, 10.5.1, 10.5.2, 10.6.0 (by reading) and main [exec: finder's JUnit fails on 10.5.0, 10.5.1, 10.5.2 (-ea and -da) and main (-ea and -da); the independent reproduction's JUnit fails on 10.5.0, 10.5.2 and main; both pass on 10.4.0, the independent reproduction's also on 9.12.3]. 8.4.0-9.12.3 had only a loud consequence: a wrapped concatenateGraph rejects preserveSep ('Unknown parameters') under luceneMatchVersion < 8.4.0 while the unwrapped filter accepts it [exec 8.4.0, 8.11.4, 9.12.3; 8.3.1 passes]. Intermediate releases by reading only (identical code); tags 8.8.2-8.11.3 are not in the local clone. branch_10x and branch_10_6 heads of 2026-10-24 lack the forwarding [read]. Not fixed upstream: upstream main ProtectedTermFilterFactory.java re-read 2026-10-26 is identical (last change 378ca8d1bbf3, javadoc only) and CHANGES.txt has no entry [read]. Executed only on aarch64 Linux with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record, verdict new, on top of the finder's scripted prior-report search and the independent reproduction's and the intended-behaviour check's checks): a scripted prior-report search in five term variants over apache/lucene GitHub issues and PRs (72 tool and 15 manual queries), commits (15), downstream repositories (apache/solr, apache/lucene-solr, Elasticsearch, OpenSearch; 10 tool and 6 manual), the LUCENE and SOLR JIRA archives (19 tool and 18 manual), the Lucene and Solr mailing lists (96 tool and about 40 manual), 11 web queries, and the changed files of all 408 open apache/lucene PRs. Related, not reports: #9320/LUCENE-8273 (closed, 7.4.0: the introducing change; none of its 87 comments discusses the match version), #15900 (merged, 10.5.0: made prefixLength depend on the version; its review states the back-compat intent, 'Old indexes and schemas then use old behaviour', and never mentions ProtectedTermFilterFactory), #15899 (closed: the surrogate-pair report behind #15900), SOLR-4251 (fixed in 4.1, 2013: the same class of defect in SynonymFilterFactory, which was then made to forward the version; precedent, other code), #10061/LUCENE-9018 (ConcatenateGraph version dependence; affected-version context), #9418/#9423 (LUCENE-8371/8376: another ConditionalTokenFilter bug, in end()), #14416 (context), #16911 (open: deletes branch_10x; the only open PR touching the file). Not fixed upstream. Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree: the new 5-test class withTestProtectedTermFilterFactory,TestProtectedTermFilter,TestTruncateTokenFilterFactory,TestTruncateTokenFilter,TestConditionalTokenFilterandTestCustomAnalyzer, assertions on and off (stock: 2 of 59 tests fail, the 2 bug tests; with the fix: 59 of 59 pass), all of:lucene:analysis:common:testwith the fix (340 classes, 1,914 tests, 18 skipped, 0 failures) and:lucene:analysis:common:check -x test(passes: google-java-format, ecjLint, forbiddenApis); the worktree was removed afterwards. The new test through the repro harness on main (-ea,-da), 10.5.0 and 10.5.2; a 10-row probe on stock main, 10.5.2 and main with the fix; the diagram's upgrade probe (one document written with the 10.4.0 jars, searched on 10.5.2 and main, stock and fixed). The hunt's runs on mainea57360912ed(its analysis module is identical) and its history probe on 7.3.1 to 10.5.2. OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ProtectedTermFilterFactory.java:38-61 (at ea57360912ed) (class javadoc: the CustomAnalyzer when()/endwhen() example and the Solr wrappedFilters example, both wrapping truncate prefixLength=4), :98-109 (constructor), :116-152 (handleWrappedFilterArgs copies only 'filterName.argName' entries into each wrapped filter's map), :154-165 (populateInnerFilters: :162 TokenFilterFactory.forName(filterName, filterArgs) with no luceneMatchVersion)lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:94-109 (at ea57360912ed) (the constructor consumes luceneMatchVersion into its own field and defaults to Version.LATEST when the map has none)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/TruncateTokenFilterFactory.java:32-37 (at ea57360912ed) (javadoc: 'For backwards compatibility the old prefixLength is still supported and its behaviour depends on the luceneMatchVersion parameter'), :62 (prefixLength @Deprecated), :81 (no length parameter selects the prefixLength path), :93-97 (legacyPrefixLengthFactory: code points from LUCENE_10_5_0, UTF-16 chars before)lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:241-245 (at ea57360912ed) (withDefaultMatchVersion: 'This match version is passed as default to all tokenizers or filters'), :596-602 (applyDefaultParams putIfAbsent), :646-648 (ConditionBuilder.addTokenFilter applies the default to when() children)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymGraphFilterFactory.java:108-109 (at ea57360912ed) and synonym/SynonymFilterFactory.java:111-112 (both copy their luceneMatchVersion into the args of the TokenizerFactory they build)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ProtectedTermFilterFactory.java:38-61, :98-109, :116-152, :154-165 (:162) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:94-109, :156-158 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/TruncateTokenFilterFactory.java:32-37, :62, :81-82, :93-97 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:241-245, :596-602, :646-650 @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/CharTermAttributeImpl.java:92-94; lucene/core/src/java/org/apache/lucene/util/BytesRefBuilder.java:146-148; lucene/core/src/java/org/apache/lucene/util/UnicodeUtil.java:172-176 @ a9779ef3c193 (an unpaired surrogate is indexed as U+FFFD)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ProtectedTermFilterFactory.java:38-61, :86 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/TruncateTokenFilter.java:97-112 @ a9779ef3c193 (code-point loop vs setLength)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:241-245, :648 @ a9779ef3c193lucene/analysis/common/src/test/org/apache/lucene/analysis/custom/TestCustomAnalyzer.java:111-127, :508-521 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/TruncateTokenFilterFactory.java:32-37 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymGraphFilterFactory.java:109; lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymFilterFactory.java:112 @ a9779ef3c193lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestProtectedTermFilterFactory.java:83-99 @ a9779ef3c193
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ProtectedTermFilterFactory.java:154-165 @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:596-602 @ a9779ef3c193
- TestProtectedTermWrappedFiltersMatchVersion.java (JUnit test):
repro/LFV-510/src/org/apache/lucene/analysis/miscellaneous/TestProtectedTermWrappedFiltersMatchVersion.java(40 lines)
assets/LFV-510/bug.png(456 KB)