ConcatenateGraphFilter glues all tokens of a field into one term, with a separator between them. Since 8.4.0 you can pick the separator. Internally it still treats your separator like the hidden one-byte separator U+001F it was built for, and that breaks in two ways: doubling and truncation.
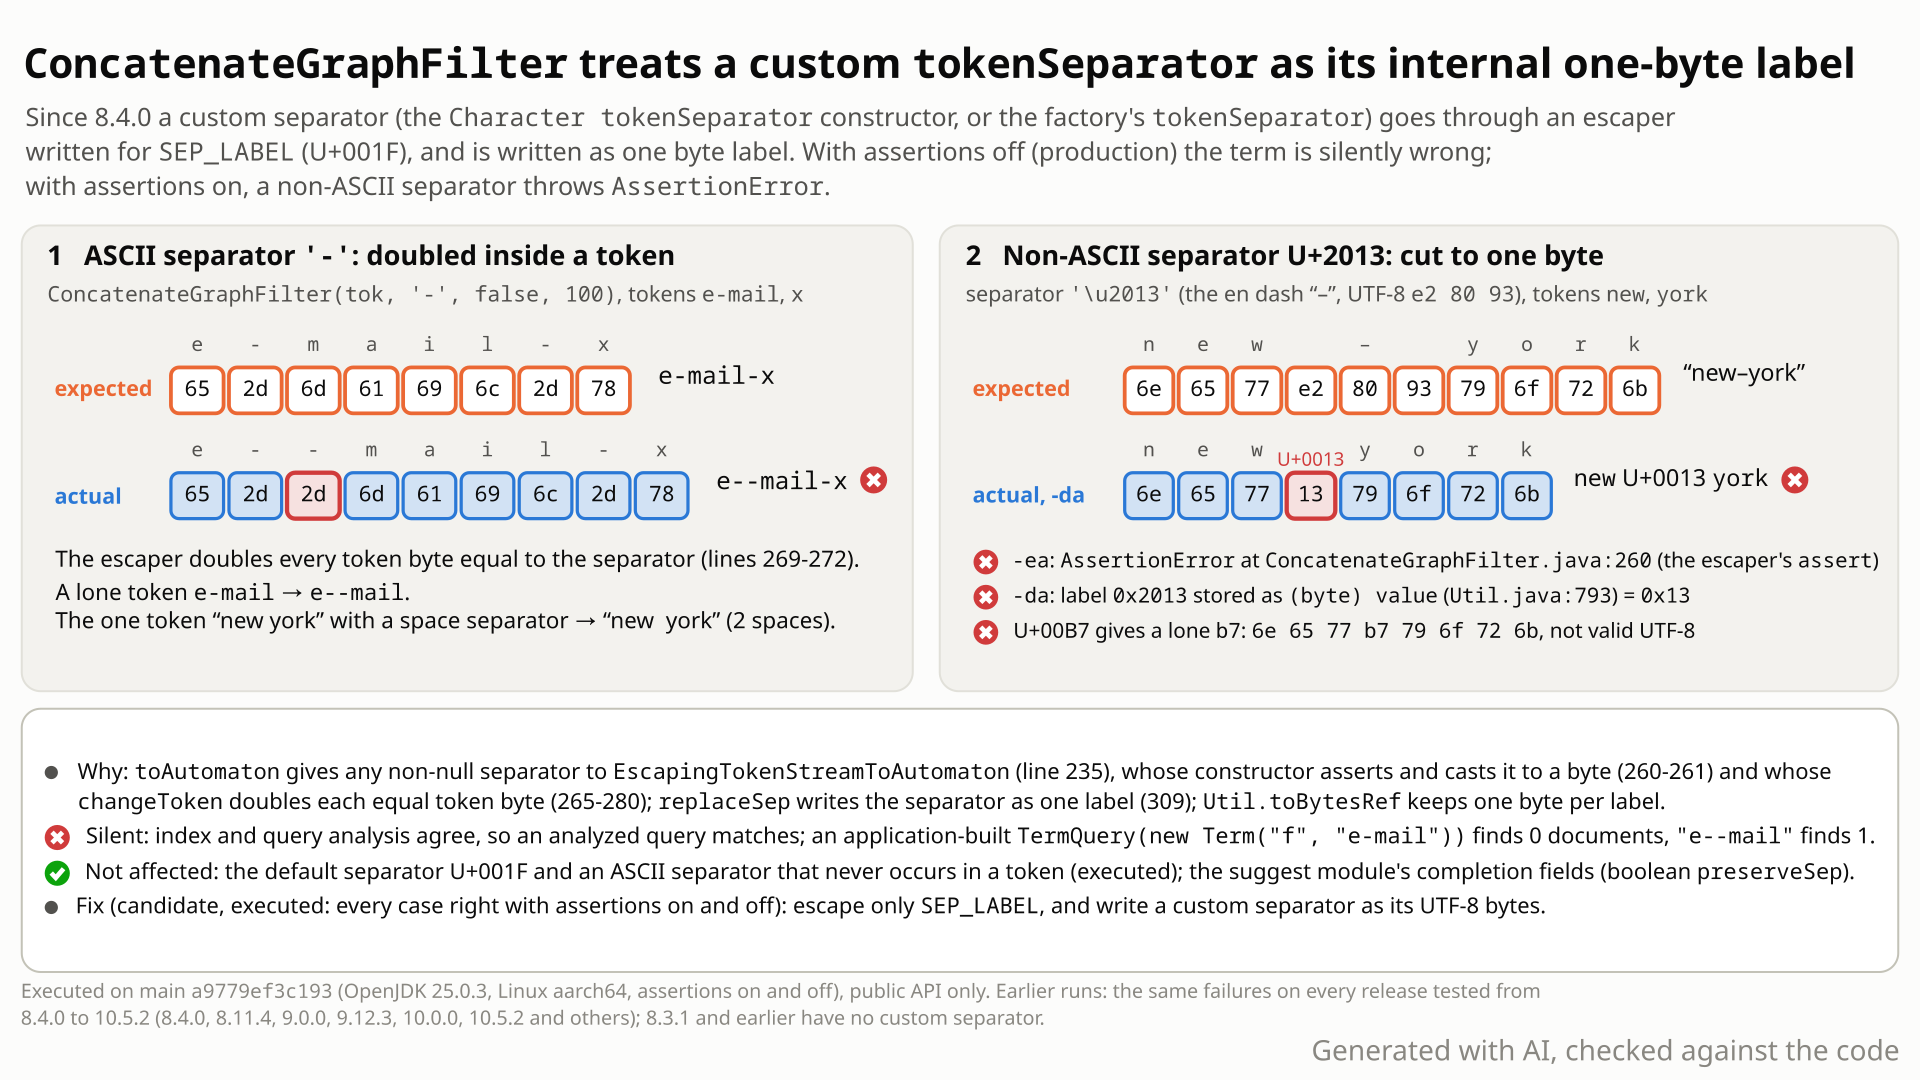
- doubled, and an en dash cut to one byte (or an assertion error); then why it stays silent and the fix direction. The PNG is the summary card. Select the still to open it at full size. Generated with AI, checked against the code.- You join a field's tokens into one term with a separator of your choice:
new ConcatenateGraphFilter(tokens, '-', false, 100), ortokenSeparatoron theconcatenateGraphfactory. The javadoc says it joins every token with that separator. - You expect the single token
e-mailto staye-mail,e-mailandxto givee-mail-x, andnewandyorkjoined with an en dash (U+2013) to give the UTF-8 bytes6e 65 77 e2 80 93 79 6f 72 6b. - You get
e--mailande--mail-x. The filter hands your separator to an escaper written for its internal one-byte separator U+001F, which doubles that character wherever it occurs inside a token. - With the en dash you get
6e 65 77 13 79 6f 72 6b(new, U+0013,york), and with a middle dot (U+00B7) a loneb7byte, which is not valid UTF-8: the separator is cut to its low byte. With assertions on, every stream throws anAssertionErrorinstead. - The same input analyzes alike at index and query time, so an analyzed query for it still matches;
TermQuery("e-mail")finds 0 documents andTermQuery("e--mail")finds 1. Every release from 8.4.0 to 10.5.2 and main.
Analysis chains that set a custom tokenSeparator, through the constructor or the concatenateGraph factory; the default separator and the suggester's completion fields are not affected. Doubling needs a token that already contains the separator, such as e-mail with - or a multi-word synonym with a space. A non-ASCII separator breaks every joined term, and every document with assertions on.
Mechanism, terms and numbers992 words
ConcatenateGraphFilter joins all tokens of a field into one term "with a separator". Since LUCENE-9018 (8.4.0) the separator is configurable, through the Character tokenSeparator constructor or the concatenateGraph factory, which accepts any one-char string. The code still treats a custom separator like the internal one-byte label U+001F it was written for: it passes the separator to an escaper (ConcatenateGraphFilter.java:235) that doubles every token byte equal to it (:265-280) and that asserts the separator fits in a signed byte and casts it to one (:259-262), and it emits the separator as one transition label (:309) that the byte path cuts to its low byte. So with - the single token e-mail becomes e--mail; with U+2013 new and york become new, U+0013, york when assertions are off and an AssertionError when they are on; U+00B7 gives a lone b7 byte, invalid UTF-8. The same input analyzes alike at index and query time, so an analyzed query for it still matches; the wrong term shows wherever it is compared with a string built outside the analyzer, and some different inputs collide (e-mail and e, a removed stop word, mail). Only chains with a custom separator are affected; the default separator and the suggest module's completion fields are not. The fix escapes only the internal label and writes a custom separator as given, as its UTF-8 bytes when non-ASCII (+41/-5 lines), validated with the analysis-common and suggest test suites.
- Join: the filter reads all tokens of a field and emits one term per path through the token graph, the tokens "joined with a separator" (one term for a plain token stream; more with synonyms).
- SEP_LABEL: the default separator, the control character U+001F, one byte in UTF-8. Because a token can itself contain that byte, the filter escapes it inside tokens by doubling it (
a\u001fbgivesa 1f 1f b, on every version since 7.4.0). - Byte automaton: the filter builds an automaton whose transition labels are the UTF-8 bytes of the tokens, with a separator label between tokens, and reads the joined terms from it. Each label must fit in one byte (
Util.toBytesRef: "you must ensure the int values fit into a byte").
// ConcatenateGraphFilter.java at a9779ef3c193, toAutomaton()
if (tokenSeparator != null) {
  tsta = new EscapingTokenStreamToAutomaton(tokenSeparator);   // :235  any custom separator goes to the escaper
...
/** Just escapes the {@link #SEP_LABEL} byte with an extra. */  // :253
public EscapingTokenStreamToAutomaton(int sepLabel) {
  assert sepLabel <= Byte.MAX_VALUE;                            // :260  fails for any separator above U+007F
  this.sepLabel = (byte) sepLabel;                              // :261  U+2013 -> 0x13
}
// :265-280 changeToken(): every token byte equal to sepLabel is written twice
// :309 replaceSep(): the token boundary becomes ONE label, tokenSeparator (0x2013 on a byte automaton)
// Util.java:793 toBytesRef(): scratch.setByteAt(i, (byte) value) -> 0x13- Doubling. LUCENE-9018 replaced
EscapingTokenStreamToAutomaton(SEP_LABEL)withEscapingTokenStreamToAutomaton(tokenSeparator). So with-the escaper doubles every-inside a token:e-mailbecomese--maileven when it is the only token and nothing is joined. - Truncation. The escaper's
assertis the only upfront check of the separator, and the first assertion reached (Util.java:792asserts later that each label is in -128..255). With assertions on it fails for every stream once the separator is above U+007F. With assertions off, the separator label is cut to its low byte when the term bytes are written: U+2013 (UTF-8e2 80 93) becomes13, a different, valid character; U+00B7 (c2 b7) becomes a loneb7, which is not valid UTF-8. Two separators with the same low byte give the same terms (from the code; not executed). The escaper also compares every token byte with that low byte, so equal in-token bytes are doubled even in a single token: with U+00B7, the tokena·b(61 c2 b7 62) becomes61 c2 b7 b7 62, and U+00F7 (c3 b7) becomesc3 b7 b7. - A third symptom with assertions off (executed with U+00F7 only): the filter also decodes the term bytes into its
CharTermAttribute. When the cut byte is a UTF-8 lead byte (0xC0-0xFF) near the end of the term, the decoder reads up to 3 bytes past the term, left over from an earlier, longer term on the same thread (only the low 6 bits of each reach the decoded char); when the term exactly fills the buffer,incrementTokenthrowsArrayIndexOutOfBoundsExceptionand that one document is rejected. The indexed bytes never contain the leftovers, and the index passed theCheckIndexthat the test framework runs when the probe's directory closes. - A token pushed over the term limit (assertions off): the doubling turns a 20,000-byte token of
-into 40,000 bytes, andIndexWriterrejects that document as an immense term ("bytes can be at most 32766 in length; got 40000"); the writer stays open.
| tokens | separator | expected | actual |
|---|---|---|---|
new, york (control) | - | new-york | new-york |
e-mail (one token) | - | e-mail | e--mail |
e-mail, x | - | e-mail-x | e--mail-x |
new york (one keyword token, factory) | space | new york | new york |
new, york | U+2013 | 6e 65 77 e2 80 93 79 6f 72 6b | 6e 65 77 13 79 6f 72 6b |
new, york | U+00B7 | 6e 65 77 c2 b7 79 6f 72 6b | 6e 65 77 b7 79 6f 72 6b |
abc (one token) | U+00B7 | 61 62 63 | 61 62 63 (unchanged) |
a·b (one token) | U+00B7 | 61 c2 b7 62 | 61 c2 b7 b7 62 (invalid UTF-8) |
With assertions on, the four non-ASCII rows throw AssertionError at ConcatenateGraphFilter.java:260. With the unicode-aware automaton (toAutomaton(true), public) the code point U+2013 comes out right between tokens with assertions off, but the escaper still runs on the token bytes first, so with the U+00B7 separator the token a·b gives U+0061 U+00B7 U+00B7 U+0062; the same assertion fails with assertions on.
Exposure and likelihood429 words
- Who is hit. Code or configuration that picks a custom separator. Example choices (
-,_, a space) hit tokens that already contain them:e-mailwith a whitespace tokenizer, a keyword-like token or a multi-word synonym with a space. An adaptation of two upstream tests (the synonymthree words synonymoftestSeparatorWithSynonyms, kept as one mapping on the inputmykeyword another, with the space separator oftestSeparator) givesthree words synonym another. A non-ASCII separator makes every joined term wrong and doubles in-token bytes equal to its low byte; with assertions off a single token without such a byte is unchanged, and with assertions on every document fails. - Downstream default. OpenSearch exposes the filter as
concatenate_graphwithtoken_separatordefaulting to a space and accepting any single character, so there the doubling needs no opt-in beyond using the filter. - What goes wrong. The same input doubles alike at index and query time, so analyzed searches look fine apart from the collisions below (
TermQuery("e--mail")finds the document). The term is wrong wherever it meets a string built outside the analyzer: an application-builtTermQueryor terms filter on the joined key (TermQuery("e-mail")finds nothing), stored or exported joined values, term facets, terms enumeration and display. A non-ASCII separator puts a control character (U+2013 to U+0013) or invalid UTF-8 (U+00B7 tob7) into the index. - Collisions. The doubled form is ambiguous: the single token
e-mailand the tokense, a removed stop word,mailgive the same terme--mailwith the defaultpreservePositionIncrements=true; a plain join keeps them apart (e-mailvse--mail). So with one analyzer on both sides an analyzed query can match an extra document: with a whitespace tokenizer, a stop filter fortheandConcatenateGraphFilter('-', true, 100), the querye the mailfinds the documente-mail(bothe--mail, 1 hit). Neither encoding is injective: the doubling keepse-mailapart frome,mailbut merges it withe, hole,mail; a plain join does the reverse. - Silent in production. With assertions off nothing throws, apart from two per-document rejections: the narrow char-view exception, and a token that the doubling pushes over the 32,766-byte term limit. With assertions on (test runs) a non-ASCII separator fails every stream, and inside
IndexWriterthe first document closes the writer. - How likely. It needs an opt-in separator plus matching characters, and the wrong term shows only outside analyzed matching; the recorded searches (2026-10-26) found no report since 8.4.0 (2019). No scale is needed: one document, one or two tokens.
The test shows that ConcatenateGraphFilter with the custom separator U+2013 (EN DASH) treats it as its internal one-byte separator label when joining new and york.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import java.io.StringReader;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.analysis.tokenattributes.TermToBytesRefAttribute;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestConcatenateGraphNonAsciiSeparator extends LuceneTestCase {

  public void testEnDashSeparator() throws Exception {
    Tokenizer tokenizer = new WhitespaceTokenizer();
    tokenizer.setReader(new StringReader("new york"));
    try (TokenStream ts = new ConcatenateGraphFilter(tokenizer, '–', false, 100)) {
      TermToBytesRefAttribute term = ts.addAttribute(TermToBytesRefAttribute.class);
      ts.reset();
      assertTrue(ts.incrementToken());
      // expected: UTF-8 of "new–york"; actual: AssertionError in the filter (-ea), new 0x13 york (-da)
      assertEquals(new BytesRef("new–york"), term.getBytesRef());
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-517/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestConcatenateGraphNonAsciiSeparator
- Expected vs actual
- Expected: the term bytes are the UTF-8 of
new–york,[6e 65 77 e2 80 93 79 6f 72 6b]. Actual: with-eaanAssertionErrorinside the filter (ConcatenateGraphFilter.java:260); with-da[6e 65 77 13 79 6f 72 6b](U+2013 cut to 0x13).
More files, environment, full output31 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError
       org.apache.lucene.analysis.miscellaneous.ConcatenateGraphFilter$EscapingTokenStreamToAutomaton.<init>(ConcatenateGraphFilter.java:260)
       org.apache.lucene.analysis.miscellaneous.ConcatenateGraphFilter.toAutomaton(ConcatenateGraphFilter.java:235)
       org.apache.lucene.analysis.miscellaneous.ConcatenateGraphFilter.toAutomaton(ConcatenateGraphFilter.java:222)
       org.apache.lucene.analysis.miscellaneous.ConcatenateGraphFilter.incrementToken(ConcatenateGraphFilter.java:164)
org.apache.lucene.analysis.miscellaneous.TestConcatenateGraphNonAsciiSeparator.testEnDashSeparator(TestConcatenateGraphNonAsciiSeparator.java:35)- The javadoc promises a join: "Concatenates/Joins every incoming token with a separator"; the factory accepts any one-
charstring. - The escaper "escapes the SEP_LABEL byte"; LUCENE-9018 swapped the custom separator in, with no test or doc of escaping.
- With a custom separator the in-band U+001F goes unescaped while a harmless character is doubled; the only non-ASCII guard is an
assert.
The full argument306 words
- The contract. Class javadoc: "Concatenates/Joins every incoming token with a separator into one output token for every path through the token stream" (
ConcatenateGraphFilter.java:40-41). Constructor: "@param tokenSeparatorSeparator to use for concatenation. Can be null, in this case tokens will be concatenated without any separators." (:101-102); the type isCharacter. Factory: "tokenSeparator: Separator to use for concatenation" (ConcatenateGraphFilterFactory.java:28-30), andgetCharacteraccepts any one-charstring (:81-94); a supplementary character is rejected. Nothing documents escaping or an ASCII-only rule. - The escaper was written for the internal label. Its javadoc: "Just escapes the {@link #SEP_LABEL} byte with an extra." (
:253); the comment at:237-238ties escaping to the "stolen" internal byte. It came from the suggester (LUCENE-8332:f9f5e837450on the main line, first released in 8.0.0, and its branch_7x cherry-pick9b61121ffb6in 7.4.0), when only U+001F was ever passed; LUCENE-9018 (e466d622c81) changedEscapingTokenStreamToAutomaton(SEP_LABEL)toEscapingTokenStreamToAutomaton(tokenSeparator)and the remap label fromsepLabeltotokenSeparator. - The tests assert plain joins.
testSeparator(' ', "not \u001F"),testSeparatorWithStopWords(B-C-F-H),testSeparatorWithStopWordsAndPreservePositionIncrements(-B-C---F--H),testSeparatorWithSynonyms(three words synonym-another-keyword) and the factory'stestSeparator. None puts the separator inside a token or uses a non-ASCII separator; all pass with the fix. - The discussion. #10061 (LUCENE-9018, 9 comments) covers the parameter name,
preserveSepand back-compat; nothing on escaping or non-ASCII separators. In LUCENE-8332's review a reviewer wrote thatSEP_LABEL"should only be used internally"; LUCENE-5030 chose U+001F so that it "survives to UTF8 as a single byte to keep replaceSep [relatively] simple": the one-byte assumption a non-ASCII separator breaks. - Sibling filters append their separator verbatim:
ShingleFilter.java:280,FixedShingleFilter.java:138-162,FingerprintFilter.java:172. Util.toBytesRefsays "you must ensure the int values fit into a byte" (Util.java:786); the separator label at:309does not.
The devil's-advocate check356 words
"The doubling is intended escaping." LUCENE-9018 did route the custom separator through the escaper on purpose; the filter's stated use is "fast analyzed exact-match lookup" (CHANGES, LUCENE-8332), where a doubled form is self-consistent at index and query time; and the class is @lucene.experimental. The verifiers rated this moderate, for the doubling only.
Why it is weak, but not settled: nothing documents or tests the doubling, and there is no unescape. That the doubled form cannot be decoded (e-mail collides with e, hole, mail, and ["e-", "mail"] with ["e", "-mail"], both e---mail) does not prove intent either way: the default escape is not injective with holes either (the single token a\u001fb and the tokens a, hole, b both give 61 1f 1f 62). The stronger point is what the escape protects. It exists for the in-band label U+001F; with a custom separator that label is no longer escaped and turns into the separator (a\u001fb c gives a-b-c), while a character that never needed escaping is doubled. That is what a mechanical substitution looks like, not a designed escape. With the default separator a single token holding U+001F also changes, by design; with - the single token e-mail changes to protect nothing.
"Non-ASCII separators are unsupported." No such rule exists: the API takes a Character and the factory any one-char string. The only upfront guard is a private assert from 2018 written for U+001F, and an assert is not argument validation: with assertions off the filter writes a different character or invalid UTF-8.
Verdicts. The finder, the independent reproduction, the intended-behaviour check, the adjudication and the intended-lens GPT review called the bug real; the refute-lens GPT review said not real only because it could not run Java. Every review rejected an intent defence for the non-ASCII half. For the ASCII doubling, the GPT lenses, the intended-behaviour check, the adjudication and the cross-model fact check of this doc rated the intent case moderate. Suggested framing upstream: the non-ASCII half is a clear defect; the doubling is undocumented behaviour that needs a maintainer decision (fix it, or document it).
Recommended A. Escape only the internal label; write a custom separator as given
Escape only the internal separator U+001F; write any other separator as given, as its UTF-8 bytes when non-ASCII (+41/-5 in one file). Validated: the repro tests pass, no upstream test of analysis-common (1,909, 18 skipped) or suggest (236, 7 skipped) fails with assertions on and off, and the static checks pass.
All options and trade-offs4 options · 1,002 words
Option A was validated through gradle; B and C are alternatives a maintainer may prefer; D is a workaround for users today.
A. Escape only the internal label; write a custom separator as given (validated by the checks) (recommended)
In toAutomaton, use EscapingTokenStreamToAutomaton(SEP_LABEL) only when the separator is the default SEP_LABEL; any other separator gets the plain TokenStreamToAutomaton. In replaceSep, emit the separator as one label when it is ASCII or the automaton is unicode-aware, and otherwise as the chain of its UTF-8 bytes through added states (their transitions are added after the copy loop, because Automaton takes each state's transitions in one run). The regression test: the doc's test, added to TestConcatenateGraphFilter.
-    if (tokenSeparator != null) {
-      tsta = new EscapingTokenStreamToAutomaton(tokenSeparator);
+    if (tokenSeparator != null && tokenSeparator == SEP_LABEL) {
+      // Only the internal SEP_LABEL byte needs escaping; a custom separator is written as given
+      tsta = new EscapingTokenStreamToAutomaton(SEP_LABEL);
 ...
-            result.addTransition(state, t.dest, tokenSeparator);
+            int from = state;
+            for (int k = 0; k < sepLabels.length; k++) {
+              int to = k == sepLabels.length - 1 ? t.dest : result.createState();
+              if (k == 0) {
+                result.addTransition(from, to, sepLabels[k]);
+              } else {
+                pending.add(new int[] {from, to, sepLabels[k]});
+              }
+              from = to;
+            }
 ...
+  private static int[] separatorLabels(Character tokenSeparator, boolean unicodeAware) {
+    if (tokenSeparator == null) {
+      return null;
+    }
+    if (unicodeAware || tokenSeparator < 0x80) {
+      return new int[] {tokenSeparator};
+    }
+    BytesRef utf8 = new BytesRef(String.valueOf(tokenSeparator));
+    int[] labels = new int[utf8.length];
+    for (int i = 0; i < utf8.length; i++) {
+      labels[i] = utf8.bytes[utf8.offset + i] & 0xFF;
+    }
+    return labels;
+  }
Trade-offs
- Only chains with a custom separator change: their terms lose the doubling, and non-ASCII separators become valid UTF-8. An index must be reindexed for exact lookups to match again only where its stored terms change: a custom separator that occurs inside tokens, or a non-ASCII separator. An ASCII separator that never occurs inside a token gives the same terms as before (the
new-yorkcontrol). The CHANGES entry should say so. The default separator (still escaped) andnullbehave as before, although the patch touches their path too (replaceSepbuilds a one-element label array and an empty list). No upstream test fails. - A plain join is not injective: after the fix the single token
e-mailand the tokense,mailboth givee-mail, as withShingleFilterorFingerprintFilter. The default separator is not an unambiguous key either: the single tokena\u001fband the tokensa, hole,bboth give61 1f 1f 62, stock and with the fix. - An unpaired surrogate as separator is written as U+FFFD (
ef bf bd), becauseUnicodeUtilreplaces it;new BytesRef(CharSequence)documents that its input must have no unpaired surrogates, so this relies on the implementation, and a maintainer may prefer to reject surrogates in the constructor and factory. - Neighbouring in-band label cases, unchanged by the fix and out of scope here: with a custom separator an in-token U+001F turns into the separator (
a\u001fb cgivesa-b-c); withnullan in-token U+001F is dropped (a\u001fbgivesab); with any separator an in-token U+001E is read as a hole and dropped (a\u001ebgivesab). - Cost: one small array and one list per
replaceSepcall, and extra states only for multi-byte separators. Not benchmarked.
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle 9.8.1, JDK 25.0.3, seed DEADBEEF: with the fix and the three repro classes added,:lucene:analysis:common:testand:lucene:suggest:test(both whole modules) with assertions on and off: analysis-common 342 classes, 1,929 tests, 1 failure, 18 skipped; suggest 31 classes, 236 tests, 0 failures, 7 skipped. - The 1,929 are the module's 1,909 upstream tests, none failing (18 of them skipped; among the rest
TestConcatenateGraphFilter12 of 12 andTestConcatenateGraphFilterFactory6 of 6), plus the doc's test (5 of 5), the finder's (6 of 6) and the reproducer's (8 of 9). The one failure is the reproducer's diagnostic, which pins today's collision (expected:<[[65 2d 2d 6d 61 69 6c]]> but was:<[[65 2d 6d 61 69 6c]]>): the fix removes it, as intended. - Static checks:
:lucene:analysis:common:check -x testwith the fix and the doc's test passes (checkGoogleJavaFormat,ecjLint,forbiddenApis); the final files are format-clean (format.logshows thattidyran; no before/after copy was kept). - With the standalone runner (fix shadowed on main
ea57360912ed): the doc's test passes 5 of 5 with assertions on and off, and the char-view probe no longer sees the over-read (the U+00F7 term is the valid UTF-861 62 c3 b7, no exception). Earlier, the finder's sketch of the same idea, combined with two sibling fixes of its hunt unit, passed 136 upstream tests of the filter, its factory,TestGraphTokenizersand the suggest module.
The same toAutomaton change as A, plus an IllegalArgumentException in the constructor (and so in the factory) for a separator above U+007F.
Trade-offs
- Smaller: no automaton change.
- Narrows the documented contract (a
Character; any single character in the factory), and configurations that use a non-ASCII separator today fail when the analyzer is built. - Not run.
A javadoc sentence ("occurrences of the separator inside a token are doubled") plus A's UTF-8 labels.
Trade-offs
- The escaper doubles single bytes, so doubling a multi-byte separator inside tokens would need new code.
- Weak: the in-band U+001F stays unescaped while a harmless character is doubled, and a single token still changes.
- Not run.
Use the default separator (escaped correctly) or an ASCII separator that cannot occur inside a token, and no non-ASCII separator.
Trade-offs
- A visible separator may be what the application needed; the default U+001F is a control character.
Downstream servers that expose the separator as an index setting (OpenSearch's concatenate_graph, default a space) inherit both symptoms; until a fix, an ASCII separator that never occurs inside tokens avoids them.
Bounded-exhaustive translation validation: the stock filter was compared with an independent plain-join reference over every small token graph, 1,041,120 join checks. Two of the mismatch buckets are this bug, an in-token custom separator doubled and a non-ASCII separator broken; a clean run without in-band characters gave 0 mismatches. An AI finder then reduced it to a JUnit test.
The method in full256 words
Method: bounded-exhaustive translation validation (the study's "semi-formal" tier), hunt unit "completion suggester indexing", main ea57360912ed, 2026-10-26. No model checker, SMT solver or prover was involved.
- A harness ran the stock main jar on every token graph of up to 3 positions (holes, 1-2 stacked tokens per position, an optional trailing hole) over the alphabet
a,b,ab, the empty token,a\u001fb,a-b, U+1F600 and U+00E9, with the separators U+001F,null,-, space and U+00B7, and compared the emitted terms with a reference that joins the tokens with the configured separator and escapes nothing: 1,041,120 join checks, 889,575 mismatches with assertions off. - The mismatches were bucketed. Two buckets are this bug: a custom separator doubled inside a token (100,896) and the non-ASCII separator U+00B7 (191,589 invalid-UTF-8 results with assertions off; 208,224
AssertionErrors with them on). The others are the default separator's intended escape (100,896, which the no-escape reference does not model), a separate empty-token finding (245,958), an in-token U+001F dropped withnull(97,176), and "OTHER" buckets (153,060) whose examples are an in-token U+001F turned into the custom separator, alone or mixed with the empty token (out of scope); a separatemaxGraphExpansionscheck had 41,780 mismatches of its own. A clean run without the empty token, U+001F or-inside tokens and with ASCII separators only gave 0 join mismatches in 178,416 checks. - An AI finder reduced it to the public-API JUnit test and wrote a fix sketch; independent AI tools reproduced, argued and judged it (see the checks).
No prior report: about 164 queries over GitHub (Lucene, Solr, Elasticsearch, OpenSearch, Lucene.NET), JIRA, the mailing lists and the web, plus the changed files of all 408 open PRs (2026-10-26). Closest: LUCENE-9018 (#10061), which introduced the behaviour without discussing escaping or non-ASCII separators.
Searches5 searches
Verdict: new; 22 hits read and classified, none the same bug. Related items: #10061 / LUCENE-9018 (closed, 8.4.0: introduced the custom separator; its 9 comments cover naming, preserveSep and back-compat), #9379 / LUCENE-8332 and its review apache/lucene-solr#384 (created the filter; SEP_LABEL "should only be used internally"), #4915 / LUCENE-3842 and #6094 / LUCENE-5030 (origin of the escaping and of the one-byte label, in the suggester), #9335 / LUCENE-8288 (open; a SEP_LABEL assertion on the suggest query side, a different path and cause) and opensearch-project/OpenSearch#2152 (added the downstream factory; its review discussed setting names only). Limits: word-based search; a report that never names the class or the setting could be missed, and private reports cannot be searched; 12 web queries finished and a 13th variant was rate-limited; of the four open PRs with 100 or more files, the file list of #16911 ("Decommission branch 10x", 7,630 files) was not paged. "No report" is a conclusion from this dated snapshot.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | the scripted prior-report search in three runs (25, 51 and 34 queries, including symptom wording such as "doubled separator" and "truncated to one byte") and 28 manual searches: ConcatenateGraphFilter with separator, unicode, escape; tokenSeparator; EscapingTokenStreamToAutomaton; SEP_LABEL; concatenateGraph | only #10061 (the feature itself) is high overlap; none reports either symptom |
| Downstream projects and ports | 2026-10-26 | OpenSearch (concatenate_graph, token_separator), elasticsearch, solr, lucene-solr, lucenenet, OpenSearch documentation, all of GitHub | OpenSearch#2152 added the factory (default separator a space); no report |
| JIRA and mailing lists | 2026-10-26 | LUCENE and SOLR text searches; dev@, java-user@, issues@, commits@ and the Solr lists | only the LUCENE-8332 and LUCENE-9018 threads, two older tagger threads and notifications |
| Open PRs | 2026-10-26 | the changed files of all 408 open apache/lucene PRs | none touches ConcatenateGraphFilter*.java, TokenStreamToAutomaton.java, CompletionTokenStream.java or CompletionAnalyzer.java (three of the four PRs with 100 or more files paged in full; #16911, 7,630 files, not) |
| Web | 2026-10-26 | 12 queries finished (6 planned, 6 variants); a 13th variant never got past the rate limit | javadoc mirrors and unrelated threads only |
Introduced in 8.4.0 by LUCENE-9018 (e466d622c81, 2019), which made the separator configurable but kept the escaper and the one-byte label written for U+001F. Affected on every release run from 8.4.0 to 10.5.2 and on main; earlier releases have no custom separator.
Versions tested7 rows
Introduced by LUCENE-9018 = #10061, commit e466d622c81 "LUCENE-9018: ConcatenateGraphFilter now has a configurable separator." (2019-11-14, a JIRA patch committed by @dsmiley; no PR), cherry-picked to branch_8x as e5f2b2380b6; first release 8.4.0, on the main line 9.0.0. It replaced boolean preserveSep with Character tokenSeparator, changed EscapingTokenStreamToAutomaton(SEP_LABEL) to EscapingTokenStreamToAutomaton(tokenSeparator), and made replaceSep emit the custom separator as one label. The escaper with its assertion and byte cast dates from LUCENE-8332 (f9f5e837450 on the main line, first released in 8.0.0; its branch_7x cherry-pick 9b61121ffb6 is in 7.4.0).
Later edits (the LUCENE-9570 reformat, LUCENE-9856, LUCENE-9981, a typo fix, and 1ddb01044a0 in 10.0.0, which removed only the factory's pre-8.4 fallback) did not change the behaviour; every tag that contains the commit has new EscapingTokenStreamToAutomaton(tokenSeparator). The commit and its parent were not built: it is bracketed by 8.3.1 (no API) and 8.4.0 (fails). The assertion is at line 236 in 8.x and 260 from 9.0.0 on (reformat).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the doc's test 4 of 5, the finder's 6 of 6 and the reproducer's 6 of 9 fail (gradle, assertions on and off) |
| 10.5.2, 9.12.3 | affected | the doc's test 4 of 5 fail (on and off); the finder's and the reproducer's tests fail; the probe's 6 checks fail |
| 10.0.0, 9.0.0, 8.11.4 | affected | probe: 6 of 6 checks fail with assertions on and off; the default-separator control passes |
| 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0-8.11.3 | affected | probe: 6 of 6 fail with assertions off |
| 8.4.0 | first | the first release with LUCENE-9018: 6 of 6 fail (the assertion at line 236 with assertions on) |
| 8.3.1, 7.4.0 | no API | only the boolean preserveSep constructor; the factory rejects tokenSeparator; the default separator behaves the same |
| main with fix A | fixed | the doc's and the finder's tests pass; no upstream test of the analysis-common and suggest suites fails (18 and 7 skipped), assertions on and off |
An independent reproducer, a devil's advocate and an adjudication found it real; a reviewer from another model family (OpenAI GPT-5.6), which could only read code, agreed on the intended-behaviour lens. A credibility audit kept it. This doc re-ran the repros through gradle on main and validated the fix with two whole module suites.
Checks and verdicts508 words
The finder, the independent reproduction and the intended-behaviour check wrote and ran their own tests, the adjudication and the audit re-ran the finder's and the independent reproduction's, and the cross-model reviews only read code (a separate run re-ran the finder's test), all against stock jars on main ea57360912ed (identical files) and release jars; the doc's runs and the fact checks used main a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Translation validation (1,041,120 checks), then a 6-test JUnit: 6 of 6 fail on main (on and off), 10.5.2 and 9.12.3; its fix sketch passes 6 of 6 and 136 upstream tests. |
| refute review (OpenAI GPT-5.6) | not real, low (procedural) | Reading only, so it could not reproduce, and it voted not real on procedure only; it agreed on the root cause, found the inputs legal and rated the intended-behaviour argument moderate. A separate run re-ran the finder's test: 6 of 6 fail. It raised the unpaired-surrogate edge. |
| Independent reproducer | real | Own 9-test JUnit written from the claim only: 6 of 9 fail on main, 10.5.2 and 9.12.3 (on and off); its main() variant fails on 8.4.0 and 8.11.4; 8.3.1 has no Character constructor. Its diagnostic shows e-mail and e, hole, mail give the same bytes. |
| Intended review (OpenAI GPT-5.6) | real, medium | Intended-behaviour argument moderate for the doubling, none for the non-ASCII half. Separate probes: the unicode-aware path also fails the assertion with assertions on, and with U+2013 an in-token U+0013 byte is doubled. |
| Devil's advocate | real | Built the "escaping by design" case from LUCENE-9018 and LUCENE-8332 and rejected it; replayed the repro (6 of 6 fail, on and off) and a 6-probe characterization: the escape is not decodable, the in-band U+001F is no longer escaped, TermQuery("e--mail") matches and TermQuery("e-mail") does not. |
| adjudication | confirmed, high | Re-ran the reproducer's test: 6 of 9 fail with assertions on and off. Impact silent wrong results. |
| registry re-runs and credibility audit | keep | Fresh seeds: the finder's test 6 of 6 fail (on and off) and pass with the fix sketch; the reproducer's 6 of 9 fail and 8 of 9 pass with the fix. The audit re-ran on main and 10.5.2 and re-read the code and the LUCENE-9018 diff. |
| this doc | reproduced; fix validated | Gradle on stock a9779ef3c193: 38 tests, 16 failed (the doc's 4 of 5, the finder's 6 of 6, the reproducer's 6 of 9; upstream 18 pass); with fix A no upstream test of analysis-common (1,909, 18 skipped) or suggest (236, 7 skipped) fails, on and off. |
| fact checks of this doc | bug holds; wording corrected | An independent fact check re-ran the repro and the fix through gradle and wrote two probes; a cross-model fact check (OpenAI GPT-5.6, reading only) and a diagram check read everything. None disputed the bug, its cause, the versions, the fix or the security classification. Their corrections (the analyzed-query collision, skipped tests, the single-token case, the bucket counts) are applied, and a resolution probe executed the new claims. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 495 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,501 words
- Registry title
- ConcatenateGraphFilter treats a custom tokenSeparator as its internal one-byte separator label: an ASCII separator is doubled wherever it already occurs inside a token ('e-mail' becomes 'e--mail'), and a non-ASCII separator fails an assertion with -ea or is written as one truncated byte with -da (U+2013 becomes U+0013, U+00B7 a lone 0xB7 byte, i.e. invalid UTF-8)
- Area
- analysis-common / ConcatenateGraphFilter and ConcatenateGraphFilterFactory (custom tokenSeparator)
- Priority
- Low, rank 489: A custom ConcatenateGraphFilter separator is doubled or truncated, but index and query analysis agree and it needs an opt-in separator plus matching characters.
- Impact class
- silent wrong results
- Impact note
- Only analysis chains that set a custom tokenSeparator are hit (the Character constructor or the concatenateGraph factory parameter, both since 8.4.0; the default separator and the suggest module's completion fields, which pass only the internal label, are not): in production (-da) a non-ASCII separator silently produces a wrong term on every joined output (a different character, or invalid UTF-8; separators with the same low byte collapse), with -ea every such token throws AssertionError, and an ASCII separator is doubled inside every token that already contains it; index and query analysis change the term in the same way, so analyzed-to-analyzed matching stays consistent and the wrong values show only where the term is compared with a string built outside the analyzer (an application-built term query, a stored joined key, term faceting or display) or read through the filter's char view; one downstream search server exposes the filter with a space as its default separator, so there the doubling needs no opt-in; no scale is needed.
- Summary
- You join tokens with ConcatenateGraphFilter (or the concatenateGraph factory) and a custom tokenSeparator, and expect what the javadoc says, every token joined with that separator: the single token 'e-mail' stays 'e-mail', 'e-mail' and 'x' joined with '-' give 'e-mail-x', and 'new' and 'york' joined with U+2013 give the UTF-8 bytes of new, U+2013, york. Instead the filter passes the custom separator to an escaper written for its internal one-byte label U+001F, so every occurrence of an ASCII separator inside a token is doubled ('e--mail', 'e--mail-x', and 'new york' for a keyword token with a space separator). A non-ASCII separator fails the escaper's assertion with -ea and, with -da, is cut to its low byte: U+2013 gives 'new' U+0013 'york', and U+00B7 gives the invalid UTF-8 term [6e 65 77 b7 79 6f 72 6b].
- Introduced
- e466d622c8161038d4e0730e2925474a0a05d596 (LUCENE-9018, 'Separator for ConcatenateGraphFilterFactory', now apache/lucene#10061; a JIRA patch committed by dsmiley, no pull request; the branch_8x cherry-pick e5f2b2380b6e93d48df5f1733113c6b6c0bc090c is the commit in 8.4.0) [read: git show and git blame in the history clone; every tagged release that contains the commit or its cherry-pick has 'new EscapingTokenStreamToAutomaton(tokenSeparator)', and no other tag does]. It replaced 'boolean preserveSep' with 'Character tokenSeparator', changed toAutomaton from new EscapingTokenStreamToAutomaton(SEP_LABEL) to new EscapingTokenStreamToAutomaton(tokenSeparator), and made replaceSep emit the custom separator as one transition label. The escaper, its 'assert sepLabel <= Byte.MAX_VALUE' and its byte cast date from f9f5e837450 (LUCENE-8332, 7.4.0), when only the internal SEP_LABEL U+001F was ever passed. Neither endpoint was built from source; the commit is bracketed by 8.3.1 (API absent) and 8.4.0 (fails) [exec] (2019-11-14)
- First affected version
- 8.4.0 [exec] (the first release with the Character tokenSeparator API). 8.3.1 [exec] has only the boolean preserveSep constructor, and its factory rejects tokenSeparator as an unknown parameter, so the bug cannot be triggered there; on the main line the first affected release is 9.0.0
- Affected versions
- every release from 8.4.0 through 10.5.2, and main ea57360912ed; never fixed. [exec] the follow-up's version-neutral main() probe fails 6 of 6 on 8.4.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main with -ea and -da, and on 8.8.2, 8.9.0, 8.10.0, 8.10.1 and 8.11.0-8.11.3 with -da, with default-separator controls passing on every version from 7.4.0; the finder's JUnit fails 6 of 6 on main, 10.5.2 (-ea and -da) and 9.12.3; the independent reproduction's JUnit fails 6 of 9 (two controls and one diagnostic pass) on main, 10.5.2 and 9.12.3 with -ea and -da, and the independent reproduction's main() variant fails on 8.4.0 and 8.11.4. [read] tag ancestry and the code check cover the releases in between; later edits to the file (LUCENE-9570 reformat, LUCENE-9856, LUCENE-9981, a typo fix, and 1ddb01044a0 in 10.0.0, which removed only the factory's pre-8.4 preserveSep fallback) did not change the behaviour, and no open PR touches the file. Not executed: branch_10_6, x86, other JDKs (aarch64 Linux with JDK 25 only)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record verdict new: about 164 recorded queries, namely the scripted prior-report search in three runs (25, 51 and 34 queries over apache/lucene issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web) plus 28 manual GitHub searches, 6 JIRA queries, 13 web searches, list-archive searches over the Lucene and Solr lists, git history and CHANGES/MIGRATE reads; 22 hits read and classified, none the same bug; the changed files of all 408 open apache/lucene PRs: none touches ConcatenateGraphFilter*.java, TokenStreamToAutomaton.java, CompletionTokenStream.java or CompletionAnalyzer.java). Closest items, not reports: #10061 / LUCENE-9018 (introduced the custom separator; its 9 comments cover naming, preserveSep semantics and back-compat, nothing on escaping, in-token separators or non-ASCII separators), #9379 / LUCENE-8332 and its review apache/lucene-solr#384 (created the filter; a reviewer said SEP_LABEL is for internal use only), #4915 / LUCENE-3842 and #6094 / LUCENE-5030 (origin of the escaping and of the one-byte label assumption, in the suggester, before the filter existed), #9335 / LUCENE-8288 (open; a SEP_LABEL assertion on the suggest query side, a different path and root cause), and downstream OpenSearch PR #2152 (added a concatenate_graph factory whose token_separator defaults to a space; its review discussed setting names only). No commit up to main ea57360912ed changed the escaping or replaceSep.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree (2026-10-28), assertions on and off, stock and with the fix; the doc's test on mainea57360912edand on the 10.5.2 and 9.12.3 release jars (2026-10-28). The hunt and its checks ran on mainea57360912ed, whoseConcatenateGraphFilter.java, factory, tests andUtil.javaare identical, and a version-neutral probe ran on 7.4.0, 8.3.1, 8.4.0, 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0-8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2 (2026-10-26). The fact checks' probes ran on maina9779ef3c193(2026-10-28), stock and with the fix, assertions on and off.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java:39-46 (at ea57360912ed) (class javadoc: 'Concatenates/Joins every incoming token with a separator into one output token'; @lucene.experimental), :59 and :62 (SEP_LABEL = TokenStreamToAutomaton.POS_SEP; DEFAULT_TOKEN_SEPARATOR = SEP_LABEL), :101-102 (@param tokenSeparator 'Separator to use for concatenation. Can be null'), :112-124 (Character constructor, no validation), :140 (the boolean preserveSep constructor passes DEFAULT_TOKEN_SEPARATOR or null), :185-189 (Util.toBytesRef, then the char view via bytesAtt.toUTF16()), :234-240 (toAutomaton: any non-null separator goes to EscapingTokenStreamToAutomaton), :248 (replaceSep(automaton, tokenSeparator)), :253 (comment 'Just escapes the SEP_LABEL byte with an extra'), :259-262 ('assert sepLabel <= Byte.MAX_VALUE'; '(byte) sepLabel'), :265-280 (changeToken doubles every token byte equal to the label), :305-309 (POS_SEP remapped to one transition labelled tokenSeparator)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilterFactory.java:28-30 (at ea57360912ed) ('tokenSeparator: Separator to use for concatenation'), :55-56, :76-79, :81-94 (getCharacter accepts any one-character string)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionTokenStream.java:46-61 (at ea57360912ed) (completion fields use the boolean preserveSep constructor, so the suggest module is not affected); lucene/core/src/java/org/apache/lucene/util/fst/Util.java:787-797 (toBytesRef casts each label to a byte)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java at a9779ef3c193 :39-47 (class javadoc), :59, :62, :226-251 (toAutomaton; :234-235, :248), :253-281 (escaper; :259-262 assert and cast; :265-280 changeToken), :285-333 (replaceSep; :305-309), :185-189 (char view)lucene/core/src/java/org/apache/lucene/util/fst/Util.java at a9779ef3c193 :786-797 (toBytesRef: javadoc, :792 assert, :793 cast)lucene/test-framework/src/java/org/apache/lucene/tests/store/BaseDirectoryWrapper.java at a9779ef3c193 :41-48 (CheckIndex on close); lucene/core/src/java/org/apache/lucene/util/UnicodeUtil.java :649, :652, :658-660 (6 bits per continuation byte); lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java :176 (changeToken before the unicode decode)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java at a9779ef3c193 :140 (boolean constructor: SEP_LABEL or null); lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionTokenStream.java at a9779ef3c193 :46-61
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java at a9779ef3c193 :40-46, :101-102, :237-238, :253, :259-262, :309; lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilterFactory.java at a9779ef3c193 :28-30, :81-94lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestConcatenateGraphFilter.java at a9779ef3c193 :169-177, :179-188, :190-199, :201-220; lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestConcatenateGraphFilterFactory.java at a9779ef3c193 :88-101lucene/analysis/common/src/java/org/apache/lucene/analysis/shingle/ShingleFilter.java at a9779ef3c193 :280; shingle/FixedShingleFilter.java :138-162; miscellaneous/FingerprintFilter.java :172
- Suggested fix
lucene/core/src/java/org/apache/lucene/util/UnicodeUtil.java at a9779ef3c193 :231-235 (unpaired surrogate replaced with U+FFFD)lucene/core/src/java/org/apache/lucene/util/BytesRef.java at a9779ef3c193 :77 (no unpaired surrogates); lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java :313-323 (HOLE becomes an epsilon); lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java :101 (HOLE = 0x1e)
- TestConcatenateGraphNonAsciiSeparator.java (JUnit test):
repro/LFV-517/src/org/apache/lucene/analysis/miscellaneous/TestConcatenateGraphNonAsciiSeparator.java(40 lines)
Its values are read at render time from an executed public-API probe on main a9779ef3c193, with assertions on and off, stock and with the candidate fix; the PNG is the summary card.
assets/LFV-517/bug.png(495 KB)