In a taxonomy, each facet label is one document and its ordinal is that document's doc ID. DirectoryTaxonomyWriter advances its ordinal counter only after IndexWriter.addDocument returns. A document that IndexWriter rejects still uses up a doc ID, so after one rejection the counter is one behind for every later label.
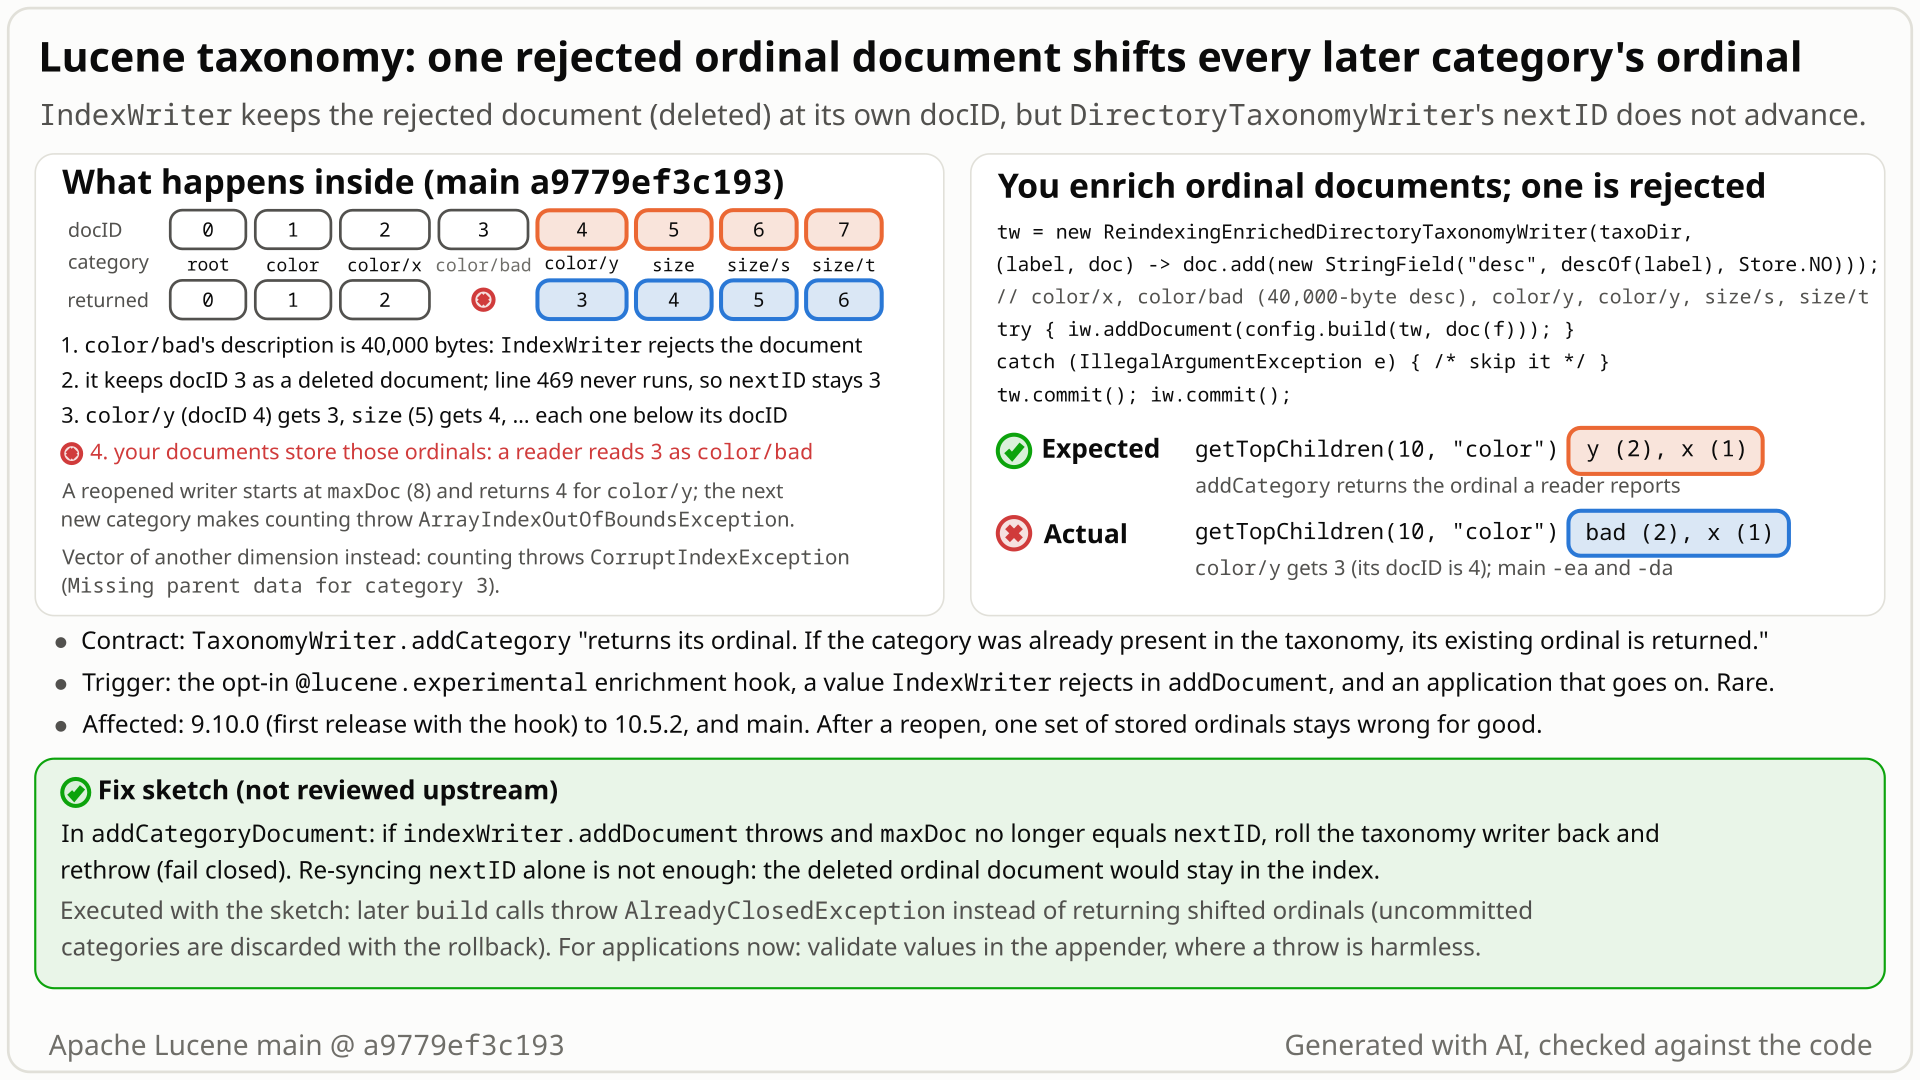
color/bad document keeps doc ID 3, the counter stays at 3, and every later label is one off. Select the still to open it at full size. Generated with AI, checked against the code.- You add your own fields to the taxonomy's category documents with
ReindexingEnrichedDirectoryTaxonomyWriter: each category gets adescriptionterm. A category's ordinal is its document's doc ID:coloris 1,color/xis 2. - One document's category,
color/bad, has a 32,767-byte description, one byte overIndexWriter's term limit.FacetsConfig.buildthrowsIllegalArgumentException; you skip that document and index twocolor/ydocuments and twosizeones. - You expect only
color/badto be missing:color: y (2), x (1). - Instead
IndexWriterkept the rejected document as deleted doc 3, but the writer's counter stayed at 3.color/yis doc 4 yet gets ordinal 3, which a reader resolves tocolor/bad: the counts saycolor: bad (2), x (1), and nothing throws. - It sticks: the wrong ordinals are stored in your documents and committed, and a reopened writer contradicts the first one (in the writer-only test, category
bgets 2, then 3). Other cases throwArrayIndexOutOfBoundsExceptionorCorruptIndexException.
Applications that add their own fields to taxonomy documents (ReindexingEnrichedDirectoryTaxonomyWriter or an enrichOrdinalDocument override: opt-in, experimental, 9.10.0 and later) where IndexWriter can reject a value, such as a term over 32,766 bytes or a vector of another dimension, and that keep the writer after the exception. Rare, but silent and persistent.
Mechanism, terms and numbers809 words
In a taxonomy index each facet label is one document, and its ordinal is that document's doc ID; the taxonomy must never contain deleted documents. Since 9.10.0, ReindexingEnrichedDirectoryTaxonomyWriter (or an enrichOrdinalDocument override) lets an application add its own fields to those documents. DirectoryTaxonomyWriter.addCategoryDocument calls the hook, then indexWriter.addDocument(d), and advances its ordinal counter only after that call returns. When IndexWriter rejects the document with a non-aborting exception, such as a term over 32,766 bytes or a vector of another dimension, it has already used up a doc ID and keeps the document as deleted. addCategory throws IllegalArgumentException, the application skips that category, and from then on, until a merge reclaims the deleted document, every new category gets an ordinal one below its doc ID: readers resolve it to the previous category (even the rejected label), main-index documents store it, and commit() persists it. In the repro two color/y documents are counted as color: bad (2), x (1) with no error, and a reopened writer returns 3 instead of 2 for a category that already exists. Other shapes throw ArrayIndexOutOfBoundsException or CorruptIndexException. The opt-in, experimental enrichment hook is the only demonstrated trigger; every release from 9.10.0 to 10.5.2, and main, is affected.
- Taxonomy and ordinal. Taxonomy facets store each label, such as
color/x, once in a side index, as one document; its doc ID is the label's ordinal. Main-index documents store ordinals, and facet counts are kept per ordinal. The writer's own notes say the taxonomy never has deleted documents: "internal docids of the configured index must not be altered. For that, categories are never deleted from the taxonomy index" (DirectoryTaxonomyWriter.java:227-229; also:364,:628-632). - Enrichment. Since 9.10.0,
ReindexingEnrichedDirectoryTaxonomyWriterlets an application "append arbitrary fields to the ordinal documents" through an appender, called from the protected,@lucene.experimentalhookenrichOrdinalDocument(ReindexingEnrichedDirectoryTaxonomyWriter.java:31-54,DirectoryTaxonomyWriter.java:440-446). - A non-aborting rejection.
IndexWriterrejects a document withIllegalArgumentExceptionwhen a term is longer thanMAX_TERM_LENGTH(32,766 bytes) or a vector's dimension differs from the field's, and stays open. It has already reserved a doc ID for the document: "Even on exception, the document is still added (but marked deleted), so we don't need to un-reserve at that point" (DocumentsWriterPerThread.java:283-290, deleted at:302-306).
addCategoryDocument(DirectoryTaxonomyWriter.java:452-482) builds the category document, callsenrichOrdinalDocument(d, categoryPath)(:466), thenindexWriter.addDocument(d)(:468), and only thenint id = nextID.getAndIncrement()(:469).- If
addDocumentrejects the document, the exception leaves between:468and:469:maxDocis k+1,nextIDis still k. - The next category is indexed as doc k+1 and handed ordinal k, and so on for every later category until a merge reclaims the deleted document. The writer's cache and parent array use its own ordinals (
:475,:479), so nothing fails inside the writer while its cache still holds the labels it added (true at repro scale). By code reading, not executed: once the 4,000-entry cache (:89) evicts a label added after the rejection, the writer looks it up on disk and finds its doc ID (:347-377,:484-494), so the same session can return a second ordinal for that label. - Readers resolve ordinals by doc ID: ordinal k is the deleted, rejected document (
getPathreturns its label, or throwsIllegalStateExceptionwhen it has no doc values, as in the vector case), andgetSize()returnsnumDocs, one less thanmaxDoc(DirectoryTaxonomyReader.java:429-456,:591-594). Main-index documents store the writer's ordinals (FacetsConfig.java:383), so they are counted under the previous category. - A reopened writer starts at
nextID = maxDoc(DirectoryTaxonomyWriter.java:174) and looks labels up by doc ID, so it returns 3 for a category the first writer returned as 2. - Enrichment fields are the only demonstrated trigger and the only route through the stock writer's own fields (an
openIndexWriteroverride may supply anotherIndexWriter,DirectoryTaxonomyWriter.java:203-217, not explored):FacetLabel.MAX_CATEGORY_PATH_LENGTH(8,191 characters,FacetLabel.java:32-39,:90-100) keeps a category's own term below the limit. An exception thrown by the appender itself, beforeaddDocument, is harmless (control test).
Facet scenario (this doc's test): color/x is doc 2 and committed; the document for color/bad (32,767-byte description) is rejected and stays as deleted doc 3; color/y, size, size/s, size/t are docs 4-7 but get ordinals 3-6. Reader: getSize() 7, maxDoc 8. FastTaxonomyFacetCounts.getTopChildren(10, "color") returns bad (2), x (1) instead of y (2), x (1). Writer view: after a (ordinal 1) and the rejected rejected, addCategory("b") returns 2; the reader says ordinal 2 is [rejected] and [b] is 3; a reopened writer returns 3 for b. With a 3-dimensional vector after 2-dimensional ones: the same 2 vs 3, and getPath(2) throws IllegalStateException. Same with assertions on and off, on main and 10.5.2.
Exposure and likelihood385 words
- Who is exposed. Users of the enrichment hook (
@lucene.experimental, 9.10.0 and later) whose enrichment value can be rejected insideIndexWriter.addDocument(two executed triggers: an unbounded per-category text indexed as aStringFieldlonger than 32,766 bytes, and a vector whose dimension differs from earlier category documents, for example after switching embedding models), and who keep using the writer afteraddCategoryorFacetsConfig.buildthrew. For these non-aborting failuresIndexWriterstays usable and documents that its own index stays consistent; no taxonomy javadoc says whether the taxonomy writer may be reused. The taxonomy writer's own stockIndexWriterConfig; single-threaded; the test framework randomizes the codec, the main index's config and the directories, and 40 of 40 bug-test runs fail with--iters 10. A plainDirectoryTaxonomyWritercannot hit it. - Downstream. A read-only code search of the default branches of Elasticsearch, OpenSearch and Solr found no use of
DirectoryTaxonomyWriter; custom applications that embed the facet module are the ones exposed. - Effect. Until a merge reclaims the deleted document, every category added after the rejection resolves to the previous one, across dimensions too (a probe's
langdimension showed{}instead of{en=1}). Counts go to the wrong labels silently (color: bad (2), x (1); with 1,100 earlier categories and a selective query, sparse counting, nothing throws either). Other shapes throwArrayIndexOutOfBoundsException; after a vector rejection every taxonomy facet request throwsCorruptIndexException: Missing parent data for category 3, and a restarted writer cannot add a new category. Each further rejection adds one more position (after 3: writer 3, reader 6). - Persistence. The wrong ordinals are stored in main-index documents and committed. Within one writer session, a merge that drops the deleted document realigns that session's ordinals; if a new writer reopened the taxonomy before that merge, one set of stored ordinals stays wrong for good. Once a reopened writer's ordinals are stored as well, repair means rebuilding the taxonomy and re-indexing the affected documents (inference from the design, not executed).
- Not affected. Drill-down filters use path terms, not ordinals, and matched exactly the right documents; no document is exposed; no hang or unbounded resource use.
- Likelihood. Rare: it needs the opt-in hook, a value
IndexWriterrejects, and continued use of the writer. The only upstream test of the hook adds small valid fields.
The test shows that after IndexWriter rejects one enriched ordinal document (a 40,000-byte term), DirectoryTaxonomyWriter returns an ordinal for the next category that the taxonomy reader maps to a different category.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.facet.taxonomy.directory;

import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.facet.taxonomy.FacetLabel;
import org.apache.lucene.store.AlreadyClosedException;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestTaxonomyWriterRejectedOrdinalDocument extends LuceneTestCase {

  public void testOrdinalAfterRejectedOrdinalDocument() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      DirectoryTaxonomyWriter tw =
          new ReindexingEnrichedDirectoryTaxonomyWriter(
              dir,
              (label, doc) -> {
                if (label.components[0].equals("bad")) {
                  doc.add(new StringField("big", "x".repeat(40_000), Field.Store.NO));
                }
              });
      expectThrows(IllegalArgumentException.class, () -> tw.addCategory(new FacetLabel("bad")));
      int b;
      try {
        b = tw.addCategory(new FacetLabel("b"));
      } catch (AlreadyClosedException e) {
        return; // a writer that closes itself after the rejection hands out no wrong ordinal
      }
      tw.close();
      try (DirectoryTaxonomyReader reader = new DirectoryTaxonomyReader(dir)) {
        assertEquals(
            "taxonomy ordinal of [b] vs the ordinal addCategory returned for it",
            reader.getOrdinal(new FacetLabel("b")),
            b);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-520/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/facet/build/libs/lucene-facet-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.facet.taxonomy.directory.TestTaxonomyWriterRejectedOrdinalDocument
# the module(s) facet also need their third-party runtime jars
- Expected vs actual
- Expected: addCategory(b) returns b's ordinal in the taxonomy (2), or the writer refuses further adds. Actual (-ea and -da): it returns 1, the docID of the rejected, deleted document.
More files, environment, full output44 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: taxonomy ordinal of [b] vs the ordinal addCategory returned for it expected:<2> but was:<1>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.facet.taxonomy.directory.TestTaxonomyWriterRejectedOrdinalDocument.testOrdinalAfterRejectedOrdinalDocument(TestTaxonomyWriterRejectedOrdinalDocument.java:48)TaxonomyWriter.addCategory: "If the category was already present in the taxonomy, its existing ordinal is returned." A reopened writer returns 3 for a category that got 2.- The writer assumes "categories are never deleted from the taxonomy index"; the rejected document is a deleted one.
- After this non-aborting rejection
IndexWriterstays usable; no javadoc asks for a rollback.
The full argument321 words
- Contract.
TaxonomyWriter.java:51-53: "addCategory() adds a category with a given path name to the taxonomy, and returns its ordinal. If the category was already present in the taxonomy, its existing ordinal is returned." No exception carve-out; the reopen test breaks it with the writer alone. - The writer's design. "internal docids of the configured index must not be altered. For that, categories are never deleted from the taxonomy index" (
DirectoryTaxonomyWriter.java:227-229); "liveDocs=null because the taxonomy has no deletes" (:364); "there are no deletions in the index" (:628-632). IndexWriter's contract. A term longer thanMAX_TERM_LENGTHmakesaddDocumentthrowIllegalArgumentException(IndexWriter.java:1480-1481), and after an exception "the index will be consistent, but this document may not have been added" (:1465-1466);IndexWriterstays open after this non-aborting rejection (executed). It closes itself on tragic events, such as "if you hit an Error, or disaster strikes during a checkpoint" (:162-165), an aborting indexing exception (DocumentsWriterPerThread.java:594-605,IndexWriter.java:1634-1639) or a failed merge (:5109-5113,:6090-6105); none of these happens here. The consistency promise coversIndexWriter's own index, not wrappers with their own invariants.- The hook's docs. "append arbitrary fields to the ordinal documents" (
ReindexingEnrichedDirectoryTaxonomyWriter.java:31-33); "modify the document corresponding to a category path before indexing it" (DirectoryTaxonomyWriter.java:441-442). Nothing restricts the fields or says the writer must be rolled back after a rejection; therollback()javadoc only describes rollback (:855-859). - Tests and history. #12337, which added the hook, and its issue and dev@ design thread never discuss fields that
IndexWriterrejects; its only test,TestOrdinalData, adds small valid fields. LUCENE-5048 (#6112, 2013) capped label length so that a label's terms stay below the indexer limit (the comment atFacetLabel.java:32-39names the drill-down term), which also keeps a category's own term below it; the hook added a second, uncapped way to put terms into the same document.
The devil's-advocate check199 words
Strongest case (the devil's advocate; the cross-model intended-lens reviewer rated it moderate): the hook is @lucene.experimental; "arbitrary fields" should mean valid fields; the application built the field that IndexWriter rejected and received an IllegalArgumentException; rollback() exists; IndexWriter only promises that the document "may not have been added".
What to concede: no API expressly promises that the taxonomy writer stays usable after an unchecked exception caused by the caller's enrichment, and IndexWriter's consistency promise covers its own index, not the taxonomy's ordinal invariants. Why it fails anyway: @lucene.experimental reserves the right to change the API (asked for in the #12337 review "so we reserve the right to break them on subsequent releases"), not to corrupt ordinals. The argument explains the one failed call, not the silent wrong ordinals of every later, valid category, nor one category getting two ordinals across sessions. "Roll back after any exception" is documented nowhere and is stricter than the IndexWriter the writer wraps, and the writer breaks its own stated invariant (no deleted documents). A rare trigger lowers severity, not intent. Verdict: a defect. Expect the reply "validate your fields or roll back"; answer with the addCategory contract and the reopen test.
Recommended Fail closed: roll back when the rejected document used up a doc ID
Fail closed: when indexWriter.addDocument throws after IndexWriter used up a doc ID (maxDoc != nextID), roll the taxonomy writer back and rethrow (+20/-1). The new test passes 6 of 6 and the facet module's 312 tests pass, assertions on and off. Callers then get AlreadyClosedException and lose uncommitted categories.
try {
  indexWriter.addDocument(d);
} catch (Throwable t) {
  // (abridged) a non-aborting failure still uses up a doc ID: roll back
  try {
    if (indexWriter.isOpen() && indexWriter.getDocStats().maxDoc != nextID.get()) {
      rollback();
    }
  } catch (Throwable t2) {
    t.addSuppressed(t2);
  }
  throw t;
}
int id = nextID.getAndIncrement();
All options and trade-offs5 options · 880 words
Option A was built and validated with gradle in a scratch worktree; option B was run and is not enough; options C to E were not run. Until a fix lands, applications can validate enrichment values inside the appender, where throwing is harmless (not a complete guard: analyzer output, the current field schema and codec limits cannot all be checked outside IndexWriter), and keep the enrichment schema fixed.
Fail closed: roll back when the rejected document used up a doc ID (validated by the checks) (recommended)
One file, DirectoryTaxonomyWriter.java. Wrap indexWriter.addDocument(d) in addCategoryDocument: if it throws while IndexWriter is open and its maxDoc no longer equals nextID, call rollback() (which closes the taxonomy writer) and rethrow, adding a secondary failure as suppressed. Plus a javadoc paragraph on enrichOrdinalDocument saying so, and that an exception thrown by the hook itself leaves the writer usable. The logic is the finder's sketch; the snippet abridges the patch's two-line comment (the full text is in the patch and in the brief).
try {
  indexWriter.addDocument(d);
} catch (Throwable t) {
  // (abridged) a non-aborting failure still uses up a doc ID: roll back
  try {
    if (indexWriter.isOpen() && indexWriter.getDocStats().maxDoc != nextID.get()) {
      rollback();
    }
  } catch (Throwable t2) {
    t.addSuppressed(t2);
  }
  throw t;
}
int id = nextID.getAndIncrement();
Trade-offs
- Why rollback: the writer can neither remove the deleted document nor reuse its doc ID. Only a later merge reclaims it, so a writer that keeps going commits a taxonomy with a hole that readers resolve wrongly until then, and a reopen before that merge leaves one set of ordinals wrong for good. The last commit is the one consistent state the writer can reach by itself. The rejected document never reaches a commit.
- Behaviour change: callers that continue today get
AlreadyClosedExceptionon their next call and must open a new writer. Every uncommitted category is lost, and main-index documents indexed since the last taxonomy commit must be discarded too (taxonomy first, then main index,TaxonomyWriter.java:36-42), since their ordinals will be handed out again. Executed in the diagram probe with the fix: a main-indexcolor/xdocument, indexed before the rejection and committed, stores ordinal 2, which the reopened writer hands tocolor/y, so it is counted asy. - Unchanged: an exception from the hook itself, before
addDocument, leaves the writer usable; an aborting failure that closesIndexWriteris rethrown as before; the normal path only gains atry. Not benchmarked; not reviewed upstream. - By code reading, not tested:
addCategorychecksensureOpen()and the cache outside the lock (DirectoryTaxonomyWriter.java:381-388) androllback()setsisClosedonly afterindexWriter.rollback()returns (:861-864), so only calls that start after the rollback reliably getAlreadyClosedException; a concurrent cache hit can still return an uncommitted ordinal. IfindexWriter.rollback()itself throws, the taxonomy writer is not marked closed. No targeted tests for these, for a tragic failure, or for a coordinated rollback of both writers; maintainers may prefer a poison-first variant (like option C) or a revised version that also blocks the cache fast path. - Taxonomies already damaged are not repaired.
DirectoryTaxonomyWriter.javais byte-identical from 10.0.0 to main; 9.x needs its own (same) patch.
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, JDK 25: the new test fails 4 of 6 on stock and passes 6 of 6 with the fix, assertions on and off; withTestDirectoryTaxonomyWriterandTestOrdinalData: 24 tests, 0 failures (1 skipped). - The whole facet module: 40 suites, 312 tests (306 upstream + 6 new), 0 failures, with assertions on (7 skipped) and off (8 skipped);
:lucene:facet:check -x test(google-java-format, ecjLint, forbiddenApis) passes. - Standalone runner with the patched class: the new test passes (assertions on and off) and the finder's JUnit passes; the independent reproducer's 4 bug tests get
AlreadyClosedException, because they keep using the writer after the rejection, which this fix forbids (its control passes).
After a failed addDocument, set nextID to maxDoc and rethrow.
Trade-offs
The deleted document stays: the reader's getSize() (numDocs) is one short of the highest ordinal. By code reading the hole also keeps the rejected label readable, lacks parent data in the vector case, and a later merge that drops it shifts every later doc ID again (not run with this variant).
What the checks validated
Gradle on main: the three ordinal tests pass, but the facet-count test throws ArrayIndexOutOfBoundsException: Index 7 out of bounds for length 7 in FastTaxonomyFacetCounts.count.
Mark the writer broken, like IndexWriter's tragic-event handling, so addCategory, commit and close throw until the application calls rollback().
Trade-offs
Same data loss as the recommended option, more code paths, and the application must know to roll back. Not run.
Count maxDoc instead of numDocs, give the hole placeholder parent data, and use a merge policy that never reclaims the deleted document.
Trade-offs
Invasive: it changes the reader, the taxonomy arrays and the merge policy. Not run, not recommended.
Javadoc only, on the hook and on ReindexingEnrichedDirectoryTaxonomyWriter.
Trade-offs
No code risk, but nothing stops the silent corruption.
An application that copies unbounded caller data into enrichment fields lets one rejected request mislabel the facet results of everyone who shares that taxonomy, while drill-down filters stay correct.
TLA+ model checking of the taxonomy writer's add path, with a non-aborting IndexWriter rejection modelled after DocumentsWriterPerThread. The finder formed the hypothesis while mapping failure points to the code; the model checker then showed the counter falling behind the documents after one rejection, and the trace was reduced to a JUnit on the stock jars.
The method in full170 words
Method: TLA+ model checking (TLC 1.8.0) (semi-formal tier: a hypothesis formed while modelling, then witnessed by the tool), in a hunt unit on concurrent adds to the taxonomy writer.
- The model (
TaxoWriterCache.tla, 518 lines) coversaddCategory, the writer's cache, its reader and parent array, with optional failure points; the rejection step followsDocumentsWriterPerThread's non-aborting path (the document keeps its doc ID and is deleted). - The invariant
SizeMatchesDocs(the writer's counter equals the number of taxonomy documents) fails after one rejection in all 8 rejection configurations (new and existing taxonomy, cache sizes 1, 2, 3 and unbounded; 15 states for the first one), while all 96 configurations without injected failures or rejections keep every invariant. The model is bounded; it corroborates the Java finding and proves nothing about the Java code. - The trace was reduced to a same-package JUnit on the stock jars, then checked by an independent reproducer, a reviewer from another model family (OpenAI GPT-5.6, reading only), a devil's advocate, an adjudication and an audit.
No prior report found (2026-10-26): GitHub issues and PRs, JIRA, four mailing lists, downstream projects, the web and all 409 open PRs. The PR that added the hook (#12337) never discusses rejected fields; LUCENE-5048 (#6112) capped label length so a category's own term cannot be rejected.
Searches4 searches
Verdict new. The nearest items added the hook, capped the label length, or fixed other causes of wrong ordinals; none describes a rejected ordinal document.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues and PRs (open and closed, migrated LUCENE issues), commits, downstream repositories | 2026-10-26 | three runs of a scripted prior-report search (48 GitHub, 6 commit, 2 downstream queries) and 31 GraphQL searches (apache/lucene, lucene-solr, Elasticsearch, OpenSearch, Solr, all of GitHub) | no report; ReindexingEnrichedDirectoryTaxonomyWriter finds only #12337, enrichOrdinalDocument nothing; related #12337, #12336, #6112 (LUCENE-5048), #9427 (LUCENE-8380), #5228, #5133, #5661, #6306 |
| JIRA archive, dev@, java-user@, issues@, commits@ | 2026-10-26 | 12 JIRA and 60 list queries through the tool, plus 7 direct JQL and 44 direct list-archive queries | no report; the 2023-05 dev@ design thread for the hook does not discuss failures |
| Web | 2026-10-26 | 10 queries | no report; two Stack Overflow pages unreadable, both about code without the hook |
| Open apache/lucene PRs | 2026-10-26 | all 409 open PRs listed with their changed files | none touches ReindexingEnrichedDirectoryTaxonomyWriter.java; #13951 only adds a cast in DirectoryTaxonomyWriter.createIndexWriterConfig |
Introduced in 9.10.0 by #12337 (merged 2024-02-08), which added the enrichment hook and so made a 2011 statement order reachable. Every release from 9.10.0 to 10.5.2 and main is affected; 9.9.2 lacks the API; never fixed.
Versions tested6 rows
Introduced by #12337 "Index arbitrary fields in taxonomy docs" (stefanvodita, for #12336), merged 2024-02-08: main f339e24e8ed6, branch_9x backport 2d713d904d01; CHANGES 9.10.0: "GITHUB#12336: Index additional data per facet label in the taxonomy." git log -S enrichOrdinalDocument finds only this commit. Older code it made reachable: addDocument before nextID++ dates from the faceting module's port (4291f52c70d7, LUCENE-3079, 2011), and IndexWriter's keep-the-doc-ID-and-delete comment from 858e309c7b1 (LUCENE-5843, 2014); before #12337 the stock writer's own fields could not make IndexWriter reject an ordinal document. Not fixed: DirectoryTaxonomyWriter.java is the same blob in 10.0.0, 10.5.2, a9779ef3c193, upstream main a95c754ee00, branch_10x and branch_10_6; the 9.x file has the same order.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test fails 4 of 6 (gradle and standalone, assertions on and off); passes 6 of 6 with the fix |
| 10.5.2 | affected | this doc's test fails 4 of 6, assertions on and off; the finder's and the independent reproducer's tests fail too |
| 9.10.0, 9.12.3, 10.0.0 | affected | the finder's JUnit fails 2 of 2 and the independent reproducer's 4 of 5 (9.10.0 also with assertions off) |
| 9.9.2 and earlier | not affected | the enrichment API is absent (both repros fail to compile); a plain-writer control passes |
| 9.9.2 jars + only the #12337 source hunks | commit-level check | both repros fail the same way: #12337 alone exposes the older code |
fix (scratch worktree at a9779ef3c193) | not affected | 6 of 6; facet module 312 tests, 0 failures |
Confirmed by an independent reproducer, a devil's advocate, a reviewer from another model family (OpenAI GPT-5.6, reading only), an adjudication and an audit; this doc's test and fix were re-run with gradle on main. The refute-lens review produced no verdict.
Checks and verdicts270 words
Each executing check wrote and ran its own test on the stock jars; the controls pass everywhere.
| Check | Verdict | What it found |
|---|---|---|
| independent reproducer | real | Own 5-test JUnit outside the taxonomy package: 4 fail on main (assertions on and off), 10.5.2, 9.12.3 and 9.10.0, the control passes; 40 of 40 with --iters 10. Found the cross-session contract break (2, then 3) and, with a merge probe, that merges move the error rather than repair it. |
| cross-model review, intended lens | real, medium; intended argument moderate | Read the code only; root cause agrees. A separate run re-ran the finder's JUnit: 2 of 2 fail. A separate probe counted color/y documents under the rejected label (bad (2), x (1)). |
| cross-model review, refute lens | no verdict | No attempt returned a verdict. |
| devil's advocate | real; no not-a-bug argument holds | Five not-a-bug arguments checked. Own probe: b session1=2 b session2=3. Corrected the persistence claim: a merge realigns a single session; a reopen before the merge makes it permanent. |
| adjudication | confirmed, high; duplicate of none | Re-ran the independent reproduction's JUnit on main with assertions on and off: 4 of 5 fail, control passes. |
| registry re-runs and audit | keep | Fresh seeds on main and 10.5.2: the independent reproduction's JUnit fails 4 of 5, the finder's 2 of 2; impact class upheld. |
| this doc's runs | reproduced; fix validated | New 6-test JUnit: 4 fail on main (gradle and standalone) and 10.5.2, assertions on and off; re-syncing the counter alone leaves the facet-count failure; the fail-closed fix passes the test and the facet module. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 566 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,482 words
- Registry title
- DirectoryTaxonomyWriter gives every later category a wrong ordinal after IndexWriter rejects one enriched ordinal document: the rejected document keeps its docID but the writer's ordinal counter does not advance
- Area
- facet / taxonomy writer (DirectoryTaxonomyWriter.addCategoryDocument with the ordinal-document enrichment hook: ReindexingEnrichedDirectoryTaxonomyWriter / enrichOrdinalDocument)
- Priority
- Low, rank 317: Needs the opt-in experimental ordinal-enrichment hook plus a rejected enrichment field and continued use of the writer.
- Impact class
- data corruption
- Impact note
- Only applications that use the opt-in, @lucene.experimental ordinal-document enrichment (ReindexingEnrichedDirectoryTaxonomyWriter or an enrichOrdinalDocument override, 9.10.0 and later; no use found in Elasticsearch, OpenSearch or Solr) are hit, and only after IndexWriter rejects one enriched ordinal document with a non-aborting exception (an indexed term over 32766 bytes or a vector of another dimension, both executed) while the application keeps using the same writer: from then on every new category gets an ordinal one below its docID, deterministically, single-threaded, at any size and with the default codec and IndexWriterConfig otherwise, those ordinals are written into main-index documents and committed, and facet labels and counts go to the wrong categories (silently with large taxonomies and selective queries [exec]) or faceting throws; a merge that drops the deleted ordinal document realigns that writer session's ordinals, but once a new writer has reopened the taxonomy before that merge, one set of ordinals stays wrong for good.
- Summary
- An application adds its own fields to taxonomy ordinal documents with ReindexingEnrichedDirectoryTaxonomyWriter (or an enrichOrdinalDocument override), IndexWriter rejects one category's field (for example a term over 32766 bytes or a vector of a different dimension), addCategory throws IllegalArgumentException, and the application skips that category and keeps going. You expect only that category to be missing and every later addCategory to return the category's ordinal, the one a taxonomy reader reports for it, with an existing category keeping its ordinal (TaxonomyWriter.addCategory). Instead IndexWriter keeps the rejected document as a deleted document that still uses up a docID while the writer's ordinal counter does not move, so every later category gets an ordinal one below its docID: readers resolve it to the previous category (even the rejected label), facet counts land under the wrong labels or throw ArrayIndexOutOfBoundsException or CorruptIndexException, and a reopened writer returns 3 instead of 2 for a category that already exists.
- Introduced
- f339e24e8ed64bf64ef4bb05111d252ecdacde1e (main) and its branch_9x backport 2d713d904d011767f5e98bbc763f84a0b4fa508f: apache/lucene#12337 'Index arbitrary fields in taxonomy docs' (author stefanvodita, for issue #12336; CHANGES 9.10.0 'GITHUB#12336: Index additional data per facet label in the taxonomy') [read: git log -S enrichOrdinalDocument finds only this commit, git blame puts the hook lines DirectoryTaxonomyWriter.java:446 and :465-466 on it; exec: stock 9.9.2 jars plus only the #12337 source hunks, via repro.sh --shadow-src, fail the same way (finder's JUnit 2 of 2 with -ea and -da, the independent reproduction's 4 of 5) while the plain-writer control passes]. It added the first way to put arbitrary, rejectable fields into an ordinal document and so made older code reachable: 'indexWriter.addDocument(d); int id = nextID++;' dates from 4291f52c70d7 (2011-06-29, LUCENE-3079, the faceting module port; nextID.getAndIncrement() since bcc116057d1, #11775, 2022), and IndexWriter's keep-the-docID-and-delete behaviour for non-aborting failures is documented in DocumentsWriterPerThread since 858e309c7b1 (2014, LUCENE-5843); before #12337 the category's own term could not be rejected because FacetLabel.MAX_CATEGORY_PATH_LENGTH (LUCENE-5048, a287431293e, 2013) keeps it below IndexWriter.MAX_TERM_LENGTH (2024-02-08 (#12337 merged 2024-02-08T11:02:12Z; PR opened 2023-05-27))
- First affected version
- 9.10.0 [exec] (first release with enrichOrdinalDocument and ReindexingEnrichedDirectoryTaxonomyWriter; 10.0.0 [exec] is the first affected 10.x release); not affected: 9.9.2 and earlier, where the API is absent (both repros fail to compile on 9.9.2 and the plain-writer control passes [exec])
- Affected versions
- every release from 9.10.0 through 10.5.2 (the last 10.x release before 10.6.0), including 9.12.3 (latest 9.x), plus main ea57360912ed; never fixed. [exec] fails: 9.10.0 (-ea and -da), 9.12.3, 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da), each with the finder's JUnit (2 of 2) and the independent reproduction's JUnit (4 of 5, control passes). [read] 9.11.0, 9.11.1, 9.12.0-9.12.2 and 10.1.0-10.5.1 by tag containment of the introducing commits and unchanged code of both writer files; upstream main, branch_10x and branch_10_6 have no commit on the two files after #12337 (GitHub commits API, 2026-10-26). Executed only on aarch64 Linux with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading; also reached by TLA+/TLC
- Upstream and prior reports
- none found (2026-10-26, read-only; follow-up prior-report record verdict new): three scripted prior-report searches (the finder's run and the follow-up's mechanism and symptom variants: 48 GitHub issue/PR queries on apache/lucene, 6 commit, 2 downstream-repository, 60 mailing-list queries over dev@, java-user@, issues@ and commits@, 12 JIRA-archive and 6 web queries; 0 high hits), 31 GitHub GraphQL searches (apache/lucene, the old lucene-solr repository, Elasticsearch, OpenSearch, Solr and all of GitHub: ReindexingEnrichedDirectoryTaxonomyWriter finds only #12337, enrichOrdinalDocument nothing), 44 direct list-archive and 7 direct JIRA queries, 10 web queries in total, the local history clone, and the changed files of all 409 open apache/lucene PRs (none touches ReindexingEnrichedDirectoryTaxonomyWriter.java; the only open PR on DirectoryTaxonomyWriter.java, #13951, adds a cast in createIndexWriterConfig). Closest, not the same bug: #12337 (added the hook; body, comments and reviews never discuss fields that IndexWriter rejects or a failed addCategory), #12336 and its 2023-05 dev@ design thread, #6112 (LUCENE-5048: capped the label length so a category's own term cannot hit the indexer limit), #9427 (LUCENE-8380: wrong ordinals from a since-removed cache bug), #5228, #5133, #5661 and #6306 (older DirectoryTaxonomyWriter getSize, concurrency and replaceTaxonomy work). Not fixed upstream (both writer files unchanged since #12337).
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) with gradle in a scratch worktree and with the standalone JUnit runner, assertions on and off; the 10.5.2 release jars (this doc's test). The hunt, the independent checks and the registry re-runs ran on mainea57360912ed, whose facet and core files involved here are byte-identical, and on the 9.10.0, 9.12.3, 10.0.0 and 10.5.2 release jars; 9.9.2 (API absent) and 9.9.2 plus only the #12337 source hunks mark the boundary. The recommended fix was validated in the scratch worktree: the new test,TestDirectoryTaxonomyWriter,TestOrdinalDataand the whole facet module (312 tests), assertions on and off, plus the module's format, ecjLint and forbiddenApis checks.
- Finding record
lucene/facet/src/java/org/apache/lucene/facet/taxonomy/directory/DirectoryTaxonomyWriter.java:227-229 (at ea57360912ed) (NOTE: 'internal docids of the configured index must not be altered. For that, categories are never deleted from the taxonomy index'), :364 (findCategory: 'liveDocs=null because the taxonomy has no deletes'), :440-446 (protected enrichOrdinalDocument hook, @lucene.experimental), :452-469 (addCategoryDocument: enrichOrdinalDocument :466, indexWriter.addDocument :468, nextID.getAndIncrement :469 only after a successful add), :627-632 (perhapsFillCache: 'there are no deletions in the index'), :665-681 (getTaxoArrays builds TaxonomyIndexArrays from the index)lucene/facet/src/java/org/apache/lucene/facet/taxonomy/directory/ReindexingEnrichedDirectoryTaxonomyWriter.java:31-55 (at ea57360912ed) ('append arbitrary fields to the ordinal documents', @lucene.experimental, the appender called from enrichOrdinalDocument)lucene/facet/src/java/org/apache/lucene/facet/taxonomy/TaxonomyWriter.java:52-53 (at ea57360912ed) (addCategory 'returns its ordinal. If the category was already present in the taxonomy, its existing ordinal is returned')lucene/facet/src/java/org/apache/lucene/facet/taxonomy/directory/DirectoryTaxonomyReader.java:590-594 (at ea57360912ed) (getSize() returns indexReader.numDocs()) and TaxonomyIndexArrays.java:212-216 (CorruptIndexException 'Missing parent data for category')lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:283-289 (at ea57360912ed) ('Even on exception, the document is still added (but marked deleted)', reserveOneDoc before processing) and IndexWriter.java:1465-1466 ('the index will be consistent, but this document may not have been added'), :1480-1481 (a term longer than MAX_TERM_LENGTH throws IllegalArgumentException), :258 (MAX_TERM_LENGTH = BYTE_BLOCK_SIZE - 2)lucene/facet/src/java/org/apache/lucene/facet/taxonomy/FacetLabel.java:38-39, (at ea57360912ed) :90-100 (MAX_CATEGORY_PATH_LENGTH = (BYTE_BLOCK_SIZE - 2) / 4 = 8191 characters) and FacetsConfig.java:383 (FacetsConfig.build passes addCategory's exception to the caller)
- The finding in 30 seconds
lucene/facet/src/java/org/apache/lucene/facet/taxonomy/directory/DirectoryTaxonomyWriter.java :89, :174, :181-182, :203-217, :227-229, :364, :381-402, :440-446, :452-482, :347-377, :484-494, :628-632lucene/facet/src/java/org/apache/lucene/facet/taxonomy/directory/ReindexingEnrichedDirectoryTaxonomyWriter.java :31-54lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java :283-290, :302-306lucene/core/src/java/org/apache/lucene/index/IndexWriter.java :258, :1480-1481lucene/facet/src/java/org/apache/lucene/facet/taxonomy/directory/DirectoryTaxonomyReader.java :270-313, :429-456, :591-594lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java :383lucene/facet/src/java/org/apache/lucene/facet/taxonomy/FacetLabel.java :32-39, :90-100
- Who is affected
lucene/facet/src/java/org/apache/lucene/facet/taxonomy/TaxonomyFacets.java :103-122, :134, :490-494lucene/facet/src/java/org/apache/lucene/facet/taxonomy/directory/TaxonomyIndexArrays.java :212-216lucene/facet/src/test/org/apache/lucene/facet/taxonomy/TestOrdinalData.java (the hook's only upstream test)
- Why it looks unintended
lucene/facet/src/java/org/apache/lucene/facet/taxonomy/TaxonomyWriter.java :51-53lucene/facet/src/java/org/apache/lucene/facet/taxonomy/directory/DirectoryTaxonomyWriter.java :227-229, :364, :441-442, :628-632, :855-859lucene/core/src/java/org/apache/lucene/index/IndexWriter.java :162-165, :1465-1466, :1480-1481, :1634-1639, :5109-5113, :6090-6105; lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java :594-605lucene/facet/src/java/org/apache/lucene/facet/taxonomy/directory/ReindexingEnrichedDirectoryTaxonomyWriter.java :31-33lucene/facet/src/java/org/apache/lucene/facet/taxonomy/FacetLabel.java :32-39
- Suggested fix
lucene/facet/src/java/org/apache/lucene/facet/taxonomy/TaxonomyWriter.java :36-42; lucene/facet/src/java/org/apache/lucene/facet/taxonomy/directory/DirectoryTaxonomyWriter.java :296-298, :381-388, :855-865a Lucene clone (DirectoryTaxonomyWriter.java blob bd4934fbb04 identical in 10.0.0, 10.5.2, a9779ef3c193, origin/main a95c754ee00, origin/branch_10x, origin/branch_10_6; 9.12.3 has the same order at :511-514)
- History
a Lucene clone (blobs of both writer files in the release tags, origin/main, origin/branch_10x, origin/branch_10_6)
- TestTaxonomyWriterRejectedOrdinalDocument.java (JUnit test):
repro/LFV-520/src/org/apache/lucene/facet/taxonomy/directory/TestTaxonomyWriterRejectedOrdinalDocument.java(55 lines)
A step-by-step picture made in parallel with this doc from an executed probe of the facet scenario on main a9779ef3c193 (stock and fix, assertions on and off). The diagram's probe uses a 40,000-byte desc term; the test uses 32,767 bytes, one over the limit; both are rejected the same way.
assets/LFV-520/bug.png(566 KB)