The document suggester indexes each context in front of the suggestion and runs both through the same completion analysis, which uses U+001E and U+001F internally. The value and the query text reject these two characters; a context is checked only for U+001D.
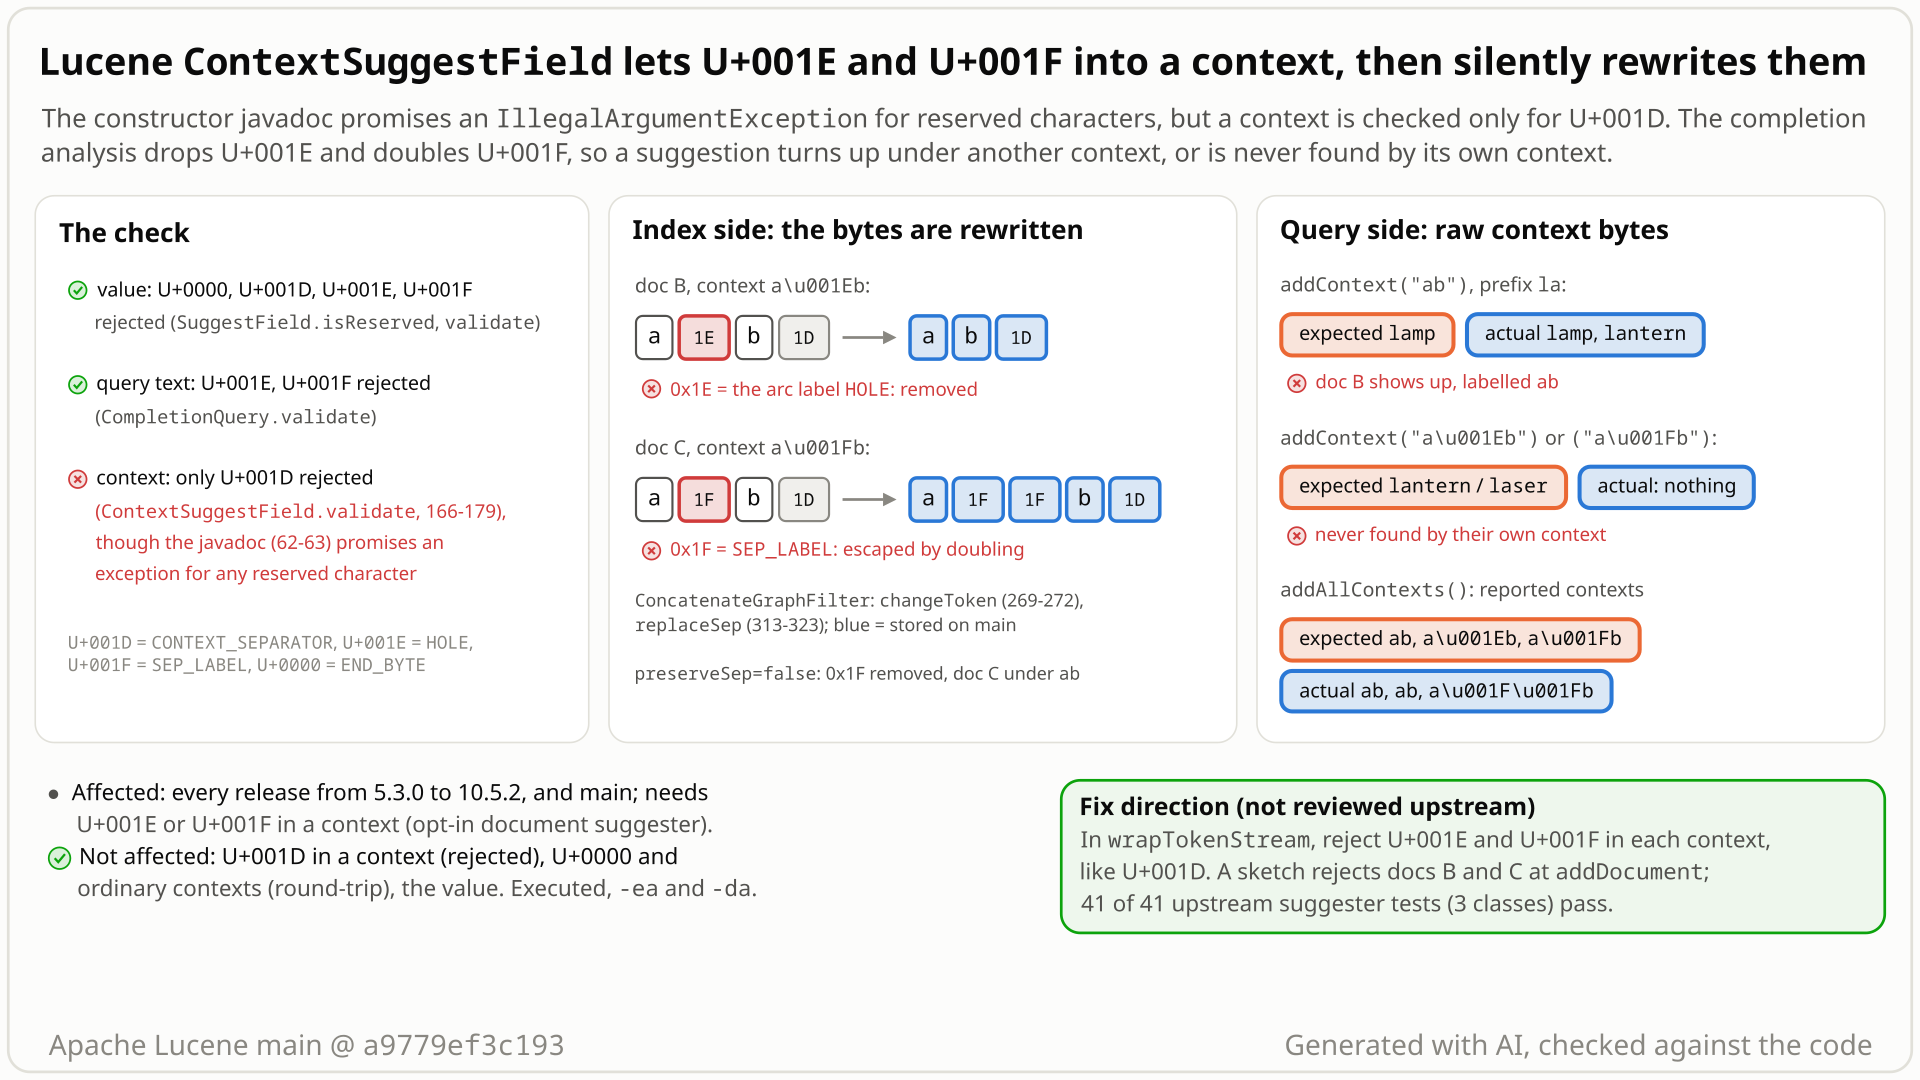
ab, a<1E>b and a<1F>b: which reserved character each input position checks, how the completion analysis rewrites the context bytes (U+001E dropped, U+001F doubled), and what the context queries then return. Select the still to open it at full size. Generated with AI, checked against the code.- You index two suggestions with
ContextSuggestField:sugg0under contextabandsugg1under contexta<1E>b(the three characters a, U+001E, b). - The constructor documents an
IllegalArgumentException"if value or contexts contains any reserved characters", so you expectaddDocumentto throw, as it does for a context with U+001D. It does not: both documents are indexed. - A prefix query
suggwith the exact contextabshould return 1 hit,sugg0. It returns 2,sugg0andsugg1, both labelledab. The exact contexta<1E>breturns 0 hits instead of 1. - Why: the context is analysed together with the value, and that analysis drops a U+001E byte (it marks a hole) and doubles a U+001F byte (an escape), while
ContextQuerymatches the raw characters. - So a context
a<1F>bnever matches its own exact query (0 hits) and is reported asa<1F><1F>b; withpreserveSep=falseit merges intoablike U+001E. Same with assertions off, no error anywhere.
Users of the document suggester (ContextSuggestField with ContextQuery) whose context strings can contain U+001E or U+001F, for example contexts taken from imported data or from document fields. Exact-context filtering then silently returns a suggestion under the wrong context, or never finds it. Opt-in and experimental; ordinary context labels are unaffected.
Mechanism, terms and numbers599 words
The ContextSuggestField constructor documents "@throws IllegalArgumentException ... if value or contexts contains any reserved characters". For contexts it checks only CONTEXT_SEPARATOR U+001D, although the same module treats U+001E (HOLE_CHARACTER) and U+001F (SEP_LABEL) as reserved in the suggestion value and in completion query text. The context is indexed as the first token of the completion token stream, so ConcatenateGraphFilter rewrites it: a U+001E byte becomes an epsilon and a U+001F byte is doubled (or removed with preserveSep=false). ContextQuery keys a query context by its raw bytes. So a suggestion indexed under a<1E>b is stored under ab, an exact ContextQuery for ab returns it and labels it ab, and the exact query for a<1E>b returns nothing; a context a<1F>b never matches its own exact query and is reported as a<1F><1F>b. No error, with assertions on and off, in every release since the class appeared in 5.3.0 (LUCENE-6459, 2015). Rejecting the two characters in contexts, like U+001D, fixes it; U+0000 works in contexts and must stay allowed.
- Document suggester:
SuggestField/ContextSuggestFieldindex a weighted suggestion with a completion postings format;PrefixCompletionQueryand friends look suggestions up throughSuggestIndexSearcher.ContextQuerywraps such a query to filter or boost by context, a string attached to the suggestion (for example a category).addContext("ab")"Adds an exact context";addAllContexts()matches every context. - The internal characters: U+001D is
ContextSuggestField.CONTEXT_SEPARATOR(ends the context), U+001E isCompletionAnalyzer.HOLE_CHARACTER(=TokenStreamToAutomaton.HOLE, marks a removed token), U+001F isConcatenateGraphFilter.SEP_LABEL(=TokenStreamToAutomaton.POS_SEP, between tokens).a<1E>bbelow means the three characters a, U+001E, b.
- The constructor promises "@throws IllegalArgumentException ... if value or contexts contains any reserved characters" (
ContextSuggestField.java:62-63). wrapTokenStreamrunsvalidate()on each context, including contexts injected throughcontexts()(:73-76,:80-83), so the check happens ataddDocument.validate()rejects onlyCONTEXT_SEPARATOR(:166-179).- Elsewhere in the module U+001E and U+001F are the reserved characters:
SuggestField.isReservedfor the value (SuggestField.java:140-149, also U+0000),CompletionQuery.validatefor query text ("this character is reserved",CompletionQuery.java:141-154), and the analyzing suggesters (AnalyzingSuggester.java:469,:686,:690). PrefixTokenFilteremits the context plus U+001D as one token ahead of the value (ContextSuggestField.java:138-157), andConcatenateGraphFilterconcatenates the stream. Every token byte becomes an automaton label (TokenStreamToAutomaton.java:197-206), so a literal 0x1E or 0x1F byte cannot be told apart from the HOLE and POS_SEP labels.replaceSepturns every HOLE label into an epsilon (ConcatenateGraphFilter.java:313-323; its comment: "if that's somehow a problem we can always map HOLE to a dedicated byte (and escape it in the input)"), andEscapingTokenStreamToAutomatondoubles every 0x1F byte (:253-281); withpreserveSep=false0x1F labels become epsilons instead (:234-240,:305-312).ContextQuery.addContextalso checks only U+001D and keys the query context by its raw bytes (ContextQuery.java:124-144); the exact-match automaton is built from them (:228-250), and the reported context is decoded from the indexed path (:308-331). Index and query side disagree.
| indexed contexts | query | expected | actual |
|---|---|---|---|
a<1E>b, a<1F>b | addDocument | IllegalArgumentException | accepted |
ab, a<1E>b | exact ab / exact a<1E>b | [sugg0:ab] / [sugg1:a<1E>b] | [sugg0:ab, sugg1:ab] / [] |
a<1F>b | exact a<1F>b / all contexts | [sugg0:a<1F>b] / [sugg0:a<1F>b] | [] / [sugg0:a<1F><1F>b] |
ab, a<1F>b, preserveSep=false | exact ab / exact a<1F>b | [sugg0:ab] / [sugg1:a<1F>b] | [sugg0:ab, sugg1:ab] / [] |
controls: ab / axb; a U+001D context; U+001E or U+001F in the value | round-trip; rejected; rejected | as expected |
A U+0000 context round-trips correctly, so only U+001E and U+001F are affected.
Exposure and likelihood340 words
- Who is exposed. Applications that use the document suggester (
ContextSuggestFieldwith a completion postings format, queried throughContextQuery) and whose context strings can contain U+001E or U+001F: contexts built from imported data or composite keys that use these characters as delimiters, or taken from document fields through acontexts()override (LUCENE-6702 added that hook to "get context values from another field in a document"). Ordinary category, locale or tenant labels normally do not contain them. - What goes wrong. Silent wrong results, no error, with assertions on and off: an exact-context filter returns a suggestion indexed under a different context string and labels it with the wrong context, or a suggestion can never be found by its own context. In the tested cases, ordinary contexts, values, weights, and exact, prefix and all-contexts queries without these characters behaved normally, and the index stayed readable and queryable (no
CheckIndexrun). - The same cause reaches other context features (a caveat probe on main, assertions on and off): boosts follow the stored bytes (with
addContext("ab", 1)andaddContext("a<1E>b", 100)thea<1E>bsuggestion of weight 9 scores 9, not 900, labelledab); non-exact (prefix) query contexts match the rewritten bytes (addContext("a<1F>", 1, false)finds thea<1F>bsuggestion and reportsa<1F><1F>b); a context made only of U+001E becomes the empty context, reported asnulland found by an exact query for""; and the raw contextsabanda<1E>bon one document collapse into one (all contexts returns one hit, not two). - Default vs opt-in. The document suggester is an optional module and both classes are
@lucene.experimental; within it the trigger needs no setting (preserveSep=falseonly turns the U+001F case from "unreachable" into "merged"). - Scale and versions. Deterministic, one document is enough. Every release from 5.3.0 to 10.5.2, and main.
- Persistence. A fix stops new occurrences; contexts already indexed in the rewritten form stay that way until the documents are reindexed.
- How likely. Rare: it needs control characters in context strings, and the documented searches found no prior report.
The test shows that a ContextSuggestField context containing U+001E is accepted and merged into another context: a suggestion indexed under a<U+001E>b is returned, labelled ab, by an exact ContextQuery.addContext("ab").
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.document;

import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.MockAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestContextSuggestFieldHoleCharContext extends LuceneTestCase {

  public void testHoleCharContextIsNotMergedIntoAnotherContext() throws Exception {
    Analyzer analyzer = new MockAnalyzer(random());
    IndexWriterConfig iwc = new IndexWriterConfig(analyzer);
    iwc.setCodec(TestUtil.alwaysPostingsFormat(new Completion104PostingsFormat()));
    try (Directory dir = newDirectory();
        IndexWriter iw = new IndexWriter(dir, iwc)) {
      String[] contexts = {"ab", "a\u001Eb"};
      for (int i = 0; i < contexts.length; i++) {
        Document doc = new Document();
        doc.add(new ContextSuggestField("suggest", "s" + i, 2 - i, contexts[i]));
        try {
          iw.addDocument(doc);
        } catch (IllegalArgumentException documentedRejectionOfReservedChar) {
          return;
        }
      }
      try (DirectoryReader reader = DirectoryReader.open(iw)) {
        ContextQuery query =
            new ContextQuery(new PrefixCompletionQuery(analyzer, new Term("suggest", "s")));
        query.addContext("ab");
        List<String> keys = new ArrayList<>();
        for (TopSuggestDocs.SuggestScoreDoc hit :
            new SuggestIndexSearcher(reader).suggest(query, 10, false).scoreLookupDocs()) {
          keys.add(hit.key + "@" + hit.context);
        }
        // expected: "a\u001Eb" rejected (@throws) or only [s0@ab]; actual: [s0@ab, s1@ab]
        assertEquals(List.of("s0@ab"), keys);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-522/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/suggest/build/libs/lucene-suggest-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.suggest.document.TestContextSuggestFieldHoleCharContext
- Expected vs actual
- Expected
addDocumentto reject the reserved character (the constructor's @throws) or the exactabquery to return only[s0@ab]; actual[s0@ab, s1@ab], with-eaand-da.
More files, environment, full output35 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[s0@ab]> but was:<[s0@ab, s1@ab]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.suggest.document.TestContextSuggestFieldHoleCharContext.testHoleCharContextIsNotMergedIntoAnotherContext(TestContextSuggestFieldHoleCharContext.java:60)- The constructor's
@throwsclause names contexts: "if value or contexts contains any reserved characters". - The commit that added the class rejects exactly U+001E and U+001F as reserved in the suggestion value and in completion query text.
- No test or discussion allows them in a context, and an accepted context should at least not turn into a different, existing one.
The full argument242 words
- The javadoc. The
@throwsclause names contexts (ContextSuggestField.java:62-63), in the class's first version (be4d58c7740, LUCENE-6459). - The same commit reserves exactly these characters in the raw suggestion value and in completion query text:
SuggestField.isReservedfor the value andCompletionQuery.validate("this character is reserved") for query text;TestSuggestField#testReservedCharsasserts that the value rejects[0x1f],[0x1e]and[0x0](TestSuggestField.java:101-124). - The analysis comment.
replaceSep's comment notes that a removed hole will also match an empty-string token, and that "if that's somehow a problem we can always map HOLE to a dedicated byte (and escape it in the input)" (ConcatenateGraphFilter.java:316-322). Nothing escapes a literal 0x1E in the input, so a context byte 0x1E is removed exactly like a real hole. For the raw value and query text the callers avoid this by rejecting the character; for contexts nobody does. - Tests and history. The only context test,
TestContextSuggestField#testReservedChars(TestContextSuggestField.java:66-103), checks just[0x1d]; no upstream test puts U+001E or U+001F in a context, to allow or to forbid it. No comment on LUCENE-6459 (24 on JIRA, 23 on GitHub) or on the later issues that changed the class discusses reserved characters in contexts, and there is no "won't fix". - Not a normalisation. If the characters were allowed, the context would at least have to behave as a context; instead the raw string does not find its own document, and a different, already existing context does.
The devil's-advocate check285 words
The checkers built the strongest case for "intended": for contexts "reserved" may mean only U+001D. Both validation sites (ContextSuggestField.validate, ContextQuery.addContext) and the only context test check just that character; U+0000, reserved in the value, works in a context, so the reserved set depends on position; so does analyzer output: U+001E or U+001F produced by the application's analyzer in a suggestion value is accepted and round-trips, and contexts bypass the application's analyzer (PrefixTokenFilter adds them after it); the code is unchanged since 2015; both classes are @lucene.experimental; and the input is rare.
Why it fails: nothing documents that a context may silently change, and the API takes any CharSequence. An exact ContextQuery returning a different context breaks the class's stated purpose, "filtering by specified contexts" (ContextQuery.java:42-44). A position-dependent reserved set can explain why U+0000 is harmless in a context, and analyzer output round-trips because the query text goes through the same analysis as the value, so both sides are rewritten alike; a context is rewritten on the index side only, while ContextQuery keys the raw bytes, so it cannot round-trip. Neither explains why U+001E and U+001F, which the same commit reserves in the raw value and in query text, should silently corrupt a context. Rarity and @lucene.experimental are about severity, not intent. Every checker rejected the case; the cross-model reviews rated it weak. A later cross-model fact check also rated it weak overall, but "moderate" for U+001F alone: the analysis escapes U+001F on purpose by doubling it, and an exact query for the doubled form finds the entry; it still fails the raw exact match, changes the reported label, and with preserveSep=false becomes the same merge as U+001E.
Recommended A. Reject U+001E and U+001F in contexts, like U+001D (ContextSuggestField.validate)
Reject U+001E and U+001F in contexts with the existing "is a reserved character" check, at addDocument like U+001D, and keep U+0000 allowed. Validated: the new tests pass, as do all 240 suggest-module tests and check. Optionally reject them in ContextQuery.addContext too, as CompletionQuery already does for query text.
+import org.apache.lucene.analysis.miscellaneous.ConcatenateGraphFilter;
 ...
   private void validate(final CharSequence value) {
     for (int i = 0; i < value.length(); i++) {
-      if (CONTEXT_SEPARATOR == value.charAt(i)) {
+      char c = value.charAt(i);
+      // contexts go through the same completion analysis as the value, which drops HOLE_CHARACTER
+      // and escapes SEP_LABEL, so both are reserved in contexts too (the value is already checked
+      // for them by SuggestField)
+      if (c == CONTEXT_SEPARATOR
+          || c == CompletionAnalyzer.HOLE_CHARACTER
+          || c == ConcatenateGraphFilter.SEP_LABEL) {
         throw new IllegalArgumentException(
             "Illegal value ["
All options and trade-offs4 options · 637 words
Options A and B were applied in a scratch worktree of main a9779ef3c193 and run through gradle with assertions on and off; options C and D were not run.
A. Reject U+001E and U+001F in contexts, like U+001D (ContextSuggestField.validate) (validated by the checks) (recommended)
Extend ContextSuggestField.validate() (ContextSuggestField.java:166-179), which wrapTokenStream already runs on every context, to reject CompletionAnalyzer.HOLE_CHARACTER and ConcatenateGraphFilter.SEP_LABEL as well; +8/-1 lines with the import.
Where it fires. At addDocument, exactly like the U+001D check, so contexts injected through contexts() are covered; the message is the existing "... UTF-16 codepoint [0x1e] at position 1 is a reserved character". The constructor's own validate(value) call is unaffected: SuggestField already rejects both characters in the value.
Timing vs the @throws clause. The clause is on the constructor, but option A, like today's U+001D check, rejects contexts only when the field is analysed (wrapTokenStream, at addDocument), which keeps contexts injected through contexts() covered. A literal reading of the contract would also check the constructor's contexts in the constructor; that is a possible addition (not run).
Not U+0000. It round-trips in contexts, and downstream engines prefix contexts with (char) typeId starting at 0.
+import org.apache.lucene.analysis.miscellaneous.ConcatenateGraphFilter;
 ...
   private void validate(final CharSequence value) {
     for (int i = 0; i < value.length(); i++) {
-      if (CONTEXT_SEPARATOR == value.charAt(i)) {
+      char c = value.charAt(i);
+      // contexts go through the same completion analysis as the value, which drops HOLE_CHARACTER
+      // and escapes SEP_LABEL, so both are reserved in contexts too (the value is already checked
+      // for them by SuggestField)
+      if (c == CONTEXT_SEPARATOR
+          || c == CompletionAnalyzer.HOLE_CHARACTER
+          || c == ConcatenateGraphFilter.SEP_LABEL) {
         throw new IllegalArgumentException(
             "Illegal value ["
Trade-offs
- Applications that index such contexts today get an
IllegalArgumentExceptioninstead of a silent merge; say so in the release note. - Contexts already indexed in the rewritten form are not repaired until reindexed.
- No API-surface change (no signature changes), but an intentional behaviour change: input that is accepted today throws. Two extra comparisons per context character.
What the checks validated
- All
org.apache.lucene.search.suggest.document.*suites with the new test: stock 62 tests, 4 failed (the new ones); with the fix 62 of 62, assertions on and off. - All of
:lucene:suggest:testwith assertions on: 32 classes, 240 tests, 7 skipped, 0 failures. :lucene:suggest:check -x testpasses (google-java-format, ecjLint, forbiddenApis).- Through the repro harness: the new test 4 of 4 pass with the fix shadowed on
a9779ef3c193. Earlier, onea57360912ed, the finder's equivalent fix passed the finder's repro and, together with two sibling fix sketches, 136 upstream tests in 11 classes.
The same three-character test in ContextQuery.addContext (ContextQuery.java:128-139), +5/-1 lines. Mirrors CompletionQuery.validate, which already rejects them in query text. Validated together with A: 62 of 62 document tests (assertions on and off), 240 module tests, check -x test passes.
Trade-offs
A query context containing them now throws instead of matching nothing (exact) or the rewritten bytes (prefix), which can surface as an error where applications pass user input as query contexts; it also stops the undocumented exact query for the doubled a<1F><1F>b form that finds an old U+001F context.
Escape U+001F and map U+001E to a dedicated, escaped byte consistently on the index and the query side (for HOLE, this is what the replaceSep comment anticipates).
Trade-offs
Larger: it changes the indexed bytes of these contexts and needs the same escaping in ContextQuery's automaton and in the reported context, for characters that no report found by the searches asks to support.
Say in the javadoc that contexts must not contain U+001E or U+001F.
Trade-offs
The silent merge stays, and the @throws clause would still promise an exception.
By code reading, search engines that build category contexts from document field values pass them to ContextSuggestField (behind a one-character type prefix) without checking for control characters, so they inherit the silent merge; with the fix such documents fail at indexing instead.
A bounded-exhaustive matrix put each reserved completion character (U+0000, U+001D, U+001E, U+001F) at each input position of the document suggester and checked the documented outcome: rejected, or else round-trips. 18 of 20 cells behaved; the two wrong ones were contexts with U+001E and U+001F. Reading the context check gave the cause.
The method in full167 words
- Method (semi-formal): a bounded-exhaustive reject/accept matrix on the stock main jar, in the hunt's unit on completion-suggester indexing, with assertions on and off: every reserved character (U+0000, U+001D, U+001E, U+001F) at every input position (the
SuggestFieldvalue, theContextSuggestFieldvalue, a context, and the analysis output of either value), 20 cells. - Oracle. Each cell must either be rejected, as the javadoc documents, or round-trip: the suggestion is found by its own context and by no neighbouring context, and is reported with the context it was given.
- Signal. 18 cells behaved as documented (rejected, or a round trip, including a U+0000 context); the only 2 wrong cells were a context with U+001E (merged into the neighbouring context) and a context with U+001F (unreachable by its exact context). The hypothesis came from modelling the context path of the finder's suggester-level reference.
- Root cause by reading
ContextSuggestField.validate(),ConcatenateGraphFilterandContextQuery.addContext; the finder then wrote the public-API JUnit and a fix sketch, and independent checkers followed (see "Independent checks").
No prior report found (searched 2026-10-26, re-checked 2026-10-28: about 100 tool queries and 154 direct searches over GitHub, JIRA, the Lucene lists and the web, plus all open PRs). Closest: a downstream issue about U+001D, which is rejected correctly.
Searches5 searches
Plausible hits were read; none describes this bug. Keyword search only: a report that only describes the symptom could be missed; GitHub's search rate limit was exhausted, so manual queries went through GraphQL; private lists cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (three runs) | 2026-10-26 | 56 mailing-list queries (dev@, java-user@, issues@, commits@), 14 JIRA-archive, 22 GitHub issue/PR, 5 commit and 5 downstream queries, over class names, the error text, the character names and the analysis identifiers | no report; the medium hits are the issues that built the code |
| GitHub (GraphQL search) | 2026-10-26 | 154 queries over apache/lucene, apache/lucene-solr, apache/lucenenet, apache/solr and two downstream search engines (u001e, u001f, "unit separator", SEP_LABEL, HOLE_CHARACTER, "is a reserved character", "category context", class names, the suggest label); the changed files of all 408 open apache/lucene PRs | 314 items triaged, no report; no open PR touches ContextSuggestField, ContextQuery, SuggestField or their test; #16911 (decommissioning branch_10x) deletes ConcatenateGraphFilter.java there with every other file |
| JIRA, history and the web | 2026-10-26 | descriptions and comments of LUCENE-5030, -6339, -6459, -6515, -6702, -6858, -8332 and -9018; git log -S on the full history; 11 web queries | no report; the only discussion of these characters is about suggester values (LUCENE-5030) |
| Re-check | 2026-10-28 | GitHub search for open PRs and issues on ContextSuggestField, ContextQuery and the characters; changed files of the PRs opened since 2026-10-26 | nothing new |
| Closest items (read) | 2026-10-26 | full threads | a downstream engine's 2018 issue (its (char) typeId context prefix reached U+001D, which is rejected correctly; capped downstream); #6094 / LUCENE-5030 and #7400 / LUCENE-6339 (the characters reserved in suggester input and values); #7518 / LUCENE-6459 (the introducing change); #9335 / LUCENE-8288 (open, a different query-side defect) |
Present since ContextSuggestField was added by LUCENE-6459 (be4d58c7740b, 2015-05-28), first released in 5.3.0. The bug shows on all 103 releases from 5.3.0 to 10.5.2 and on main. Not fixed upstream.
Versions tested5 rows
Introduced by LUCENE-6459 (now #7518), "add common suggest API for document based NRT suggester", patch by @areek, committed by @mikemccand: trunk be4d58c7740b (2015-05-28) and its branch_5x copy 380bb29f3959 the same day (SVN era, no PR). It created the class with the "reserved characters" javadoc and the U+001D-only check, and in the same commit SuggestField.isReserved and CompletionQuery.validate, which reject U+001E and U+001F. CHANGES lists it under 5.3.0.
Not a regression. Later commits on the file (LUCENE-6515, LUCENE-6702 which moved the check into wrapTokenStream, a license-header move (LUCENE-7013), LUCENE-6858, LUCENE-8332 which moved the analysis to ConcatenateGraphFilter, a reformat, #11942, #15573) never changed which characters are checked.
Not fixed upstream. At a9779ef3c193 (upstream main on 2026-10-26), branch_10x and branch_10_6 both checks still look only for U+001D; no open PR proposes a fix: none touches ContextSuggestField, ContextQuery, SuggestField or their test, and the only one touching ConcatenateGraphFilter.java is #16911, an unrelated branch-decommission PR that deletes every file on branch_10x (re-checked 2026-10-28).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | new test 4 of 4 fail through gradle and the repro harness (assertions on and off) |
| 10.5.2, 9.12.3 | affected | new test 4 of 4 fail (assertions on, and off in the fact check); the finder's and the reproducer's JUnit fail |
| 5.3.0 ... 10.5.2 (all 103 releases) | affected | release-portable probe: U+001E/U+001F contexts accepted and rewritten, controls pass (118 usable runs; also with -da on 5.3.0, 7.7.3, 8.11.4, 9.12.3 and 10.5.2) |
| 5.2.1 | API absent | no ContextSuggestField, ContextQuery or CompletionQuery; the probe does not compile |
fix A on main a9779ef3c193 | not affected | 62 of 62 document tests and all 240 module tests pass; check -x test passes |
An independent reproducer (own 7-test suite), a works-as-designed review by a reviewer from another model family, an intended-behaviour devil's advocate, an adjudication and a credibility audit all judged it real; the reproducer, the devil's advocate, the adjudication and the audit re-ran it. A read-only refute review said "not real" only because it could not run code.
Checks and verdicts412 words
Every verdict below that re-ran a repro did so on main ea57360912ed, whose suggest and analysis code is identical to a9779ef3c193; the reading-only cross-model reviews were followed by a separate re-run of the repro (fails). This doc's own fix validation ran on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model refute review | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: it could run no command, so it could not vote real. It agreed with the root cause, found the inputs within the contract, rated the intended-behaviour case weak, and noted that U+0000 is also accepted in contexts (the matrix shows it round-trips). A separate run re-ran the repro: fails 3 of 3. |
| Independent reproducer | real | Own public-API suite written from the claim only: 5 of 7 fail on main, 10.5.2 and 9.12.3, assertions on and off; both controls (a U+001D context rejected; ab / axb round-trip) pass. Added the preserveSep=false merge; a U+0000 context round-trips. Its first run was vacuous (wrong completion format) and was discarded. |
| Works-as-designed review | real (medium) | The same OpenAI GPT-5.6 reviewer with an intended-behaviour lens, reading only: the "reserved means only U+001D for contexts" reading does not explain the broken round trip. A separate observation test, run on main with assertions on and off, printed the merge (idx[ab,a<1E>b] q=ab -> [d0:ab, d1:ab]). |
| Intended-behaviour devil's advocate | real (medium-high) | Built the strongest "intended" case and rejected it; its probe of the current behaviour passes 5 of 5 on main (assertions on and off) and 10.5.2; it re-ran the finder's repro (fails 3 of 3) and corrected the first release to 5.3.0. |
| Adjudication | confirmed (high) | Re-ran the reproducer's suite with a new seed (7 run, 5 failed, assertions on and off) and the finder's repro (3 of 3 fail). Maintainers may prefer documenting the limit; a complete fix may also reject the characters in ContextQuery.addContext. |
| Credibility audit | keep | Re-ran both JUnits with fresh seeds (3 of 3 and 5 of 7 fail); kept the impact as silent wrong results of an opt-in, experimental API with rare input. |
| Fix validation (this doc) | fix A passes | Gradle in a scratch worktree of a9779ef3c193: stock 4 of 62 document tests fail (the new ones); with fix A 0 of 62, the whole module 240 tests, 0 failed, check -x test passes; the same with A and B together. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 439 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,621 words
- Registry title
- ContextSuggestField accepts contexts that contain U+001E or U+001F although its javadoc promises an IllegalArgumentException for reserved characters; the completion analysis then drops U+001E (a suggestion indexed under context 'a<U+001E>b' is stored as, returned for and labelled with the exact context 'ab') and doubles U+001F (context 'a<U+001F>b' never matches its own exact query and is reported as 'a<U+001F><U+001F>b')
- Area
- suggest / document (NRT) suggester (ContextSuggestField context validation; the context then passes through ConcatenateGraphFilter's SEP_LABEL escaping and HOLE removal)
- Priority
- Low, rank 490: ContextSuggestField silently mangles contexts containing U+001E or U+001F despite the documented exception, only for control-character contexts, so it follows its ConcatenateGraphFilter sibling LFV-517.
- Impact class
- silent wrong results
- Impact note
- Applications that use the opt-in document suggester (ContextSuggestField with a completion postings format) on any release from 5.3.0 through 10.5.2 or on main, and whose context strings can contain the ASCII control characters U+001E or U+001F (for example contexts taken from document data through a contexts() override or built by a downstream engine from field values), get no IllegalArgumentException at construction or at addDocument; instead a context with U+001E is silently merged into the context without it (an exact ContextQuery for 'ab' also returns, and labels as 'ab', a suggestion indexed under 'a<U+001E>b'), and a context with U+001F can never be matched by its exact context and is reported doubled (with preserveSep=false U+001F is removed instead and merges like U+001E); no scale and no other non-default setting is needed, the class is @lucene.experimental, and a fix cannot repair contexts that were already indexed in the rewritten form.
- Summary
- You index one suggestion under context 'ab' and another under context 'a<U+001E>b' with ContextSuggestField, and expect an IllegalArgumentException, because the constructor javadoc says it throws one 'if value or contexts contains any reserved characters' and U+001E and U+001F are exactly the characters that SuggestField and CompletionQuery reject as reserved (or, at the least, a context that round-trips). Instead both documents are indexed: ContextQuery.addContext("ab") returns both and reports both with context 'ab', addContext("a<U+001E>b") returns nothing, and a context 'a<U+001F>b' is also accepted, its exact query returns nothing and addAllContexts() reports it as 'a<U+001F><U+001F>b'. The cause: ContextSuggestField.validate checks a context only for U+001D (CONTEXT_SEPARATOR); the context then goes through ConcatenateGraphFilter, which turns a U+001E byte into an epsilon and escapes U+001F by doubling it, while ContextQuery builds its automaton from the raw characters, so the index side and the query side disagree.
- Introduced
- be4d58c7740bea4e797eb1acff6355eb260e7c93 (LUCENE-6459 'add common suggest API for document based NRT suggester', patch by Areek Zillur (@areek), committed by Mike McCandless (@mikemccand), trunk svn r1682158, SVN era with no pull request; review on JIRA LUCENE-6459, now apache/lucene#7518), released through the branch_5x copy 380bb29f39595de1c3947075296d1d0a36f02fd8 (r1682170, the same day; the commit in 5.3.0-5.5.5) [read: git blame and git log -S in the full-history clone; exec: 5.2.1 has no ContextSuggestField and the probe does not compile there, 5.3.0 shows the bug]. The commit created ContextSuggestField with the 'reserved characters' @throws javadoc and a validate() that rejects only CONTEXT_SEPARATOR U+001D, and in the same commit added SuggestField.isReserved (U+001F, U+001E, U+0000) for values and CompletionQuery.validate, which rejects U+001E and U+001F in query text as 'reserved'; so the defect is as old as the API, not a regression. Later commits kept the U+001D-only check: cecebbc7506 (LUCENE-6515), f8ae631751a (LUCENE-6702, moved the context check into wrapTokenStream), 4e2d9deff4a (LUCENE-6858), f9f5e837450 / 9b61121ffb6 (LUCENE-8332, analysis moved to ConcatenateGraphFilter), 2cbf261032d (LUCENE-9570 reformat), 135f3fab412 (#11942), 378ca8d1bbf (#15573, javadoc markup) (2015-05-28 (be4d58c7740 on trunk and 380bb29f395 on branch_5x))
- First affected version
- 5.3.0 [exec] (tag 2015-08-20, the first release with ContextSuggestField: the portable public-API probe shows the bug with -ea and -da, and a 5.x port of the finder's JUnit fails 3 of 3 with the same messages as on main); 5.2.1 has no ContextSuggestField, ContextQuery or CompletionQuery, so the probe does not compile [exec]. Correction to the finder's first take ('since 5.2'), as the intended-behaviour check, the adjudication and the history step found (CHANGES lists LUCENE-6459 under 5.3.0)
- Affected versions
- every release from 5.3.0 through 10.5.2 (all 103 releases on Maven Central) and main ea57360912ed; not fixed upstream (upstream main a9779ef3c19, branch_10x and branch_10_6 read on 2026-10-26: validate() and ContextQuery.addContext still check only U+001D; no open PR touches the files). [exec: the portable probe (controls: U+001E/U+001F rejected in the value, U+001D rejected in a context, ordinary contexts round-trip) gives identical claim and control results in all 118 usable runs, -ea on every release and -da on 5.3.0, 7.7.3, 8.11.4, 9.12.3, 10.5.2 and main; the finder's JUnit fails 3 of 3 on 9.12.3, 10.5.2 and main; the independent reproduction's JUnit fails 5 of 7 (both controls pass) on 9.12.3, 10.5.2 and main with -ea and -da; with the fix shadowed the probe passes on main]. Caveats: probe v1 picked an absent completion format on 10.3.0-10.3.2 (a probe error), so those three ran with probe v2, which agrees with v1 wherever both ran; 8.8.2-8.11.3 have no tag in the history clone but were executed; the preserveSep=false variant (U+001F removed, merging into 'ab') holds from 5.4.0 on, because in 5.3.x context queries on a CompletionAnalyzer index return nothing at all (the separate, fixed LUCENE-6858); all runs on Linux aarch64 with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record, verdict new): three scripted prior-report searches (56 mailing-list queries over dev@, java-user@, issues@ and commits@, 14 JIRA-archive (plus the remainder of 2 truncated ones, fetched by hand), 22 GitHub issue/PR, 5 commit and 5 downstream queries; 0 errors), 154 manual GitHub GraphQL searches over apache/lucene, apache/lucene-solr, apache/lucenenet, apache/solr, elastic/elasticsearch and opensearch-project/OpenSearch (314 distinct items triaged), the description and comments of LUCENE-5030, -6339, -6459, -6515, -6702, -6858, -8332 and -9018, 11 web queries, the local full history, and the changed files of all 408 open apache/lucene PRs (none touches ContextSuggestField.java, ContextQuery.java, SuggestField.java or TestContextSuggestField.java); the finder's and the intended-behaviour check's earlier scripted prior-report searches (the intended-behaviour check: 133 hits, 0 high) found nothing either. Closest items, not reports of this bug: elastic/elasticsearch#32710 (2018, a downstream engine's (char) typeId context prefix reached U+001D at 30 contexts and was correctly rejected; fixed downstream by capping context mappings, #32741 / PR #38675); #6094 (LUCENE-5030, 2013, the analyzing suggesters reserve 0x1E and 0x1F) and #7400 (LUCENE-6339, U+001F rejected in the value); elastic/elasticsearch#48341 / PR #48445 and a 2020 forum thread (reserved characters in the suggestion value or query text, not contexts); #7518 (LUCENE-6459, the introducing change; none of its JIRA or GitHub comments discusses reserved characters in contexts), #7760 (LUCENE-6702), #7916 (LUCENE-6858), #7573 (LUCENE-6515), #9379 (LUCENE-8332), #10061 (LUCENE-9018); same classes, different defects: #9335 (LUCENE-8288, open, regex '.' assertion), #9334 (LUCENE-8287), #14169 (performance), SOLR-9968 (Solr's infix-suggester context filter parsing). Not fixed upstream.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree (removed afterwards): the new 4-test class with allorg.apache.lucene.search.suggest.document.*suites, assertions on and off (stock: 4 of 62 fail; with the fix: 0), the fix alone and with the query-side option against all of:lucene:suggest:testandcheck -x test. The new test through the repro harness on 9.12.3, 10.5.2 and main (-ea,-da, and with the fix shadowed); the hunt's release-portable probe on all 103 releases from 5.3.0 to 10.5.2 and on main. The hunt itself ran on mainea57360912ed, whose suggest and analysis code is identical. A caveat probe (boosts, prefix query contexts, a context made only of U+001E, two contexts on one document) on main with assertions on and off: every observation as stated. OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextSuggestField.java:55-64 (at ea57360912ed) (constructor javadoc; '@throws IllegalArgumentException ... if value or contexts contains any reserved characters' :62-63), :44 (@lucene.experimental), :78-83 (wrapTokenStream validates each context, loop :81-83), :166-179 (validate: rejects only CONTEXT_SEPARATOR U+001D, message 'is a reserved character')lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestField.java:140-149 (at ea57360912ed) (isReserved: SEP_LABEL U+001F, HOLE_CHARACTER U+001E, END_BYTE U+0000, for the value)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionQuery.java:141-152 (at ea57360912ed) (validate: 'Term text cannot contain HOLE character U+001E; this character is reserved' and the same for U+001F)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:42-44 (at ea57360912ed) (class javadoc: 'boosting and/or filtering by specified contexts'), :71 (@lucene.experimental), :124-144 (addContext checks only U+001D and builds the context key from the raw bytes, Util.toIntsRef(new BytesRef(context)))lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java:253-281 (at ea57360912ed) (EscapingTokenStreamToAutomaton.changeToken doubles the SEP_LABEL byte), :313-324 (replaceSep turns every HOLE transition into an epsilon; comment 'if that's somehow a problem we can always map HOLE to a dedicated byte (and escape it in the input)')
- The finding in 30 seconds
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextSuggestField.java:44, :49, :55-64, :73-76, :78-103 (loop :80-83), :138-157, :166-179 @ a9779ef3c193lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestField.java:75-76, :140-149; lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionQuery.java:63, :141-154; lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionAnalyzer.java:44 @ a9779ef3c193lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:469, :686, :690 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java:59, :226-251 (:234-240), :253-281, :285-333 (:305-312, :313-323) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:98, :101, :176, :197-206 @ a9779ef3c193lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:42-44, :110-113, :124-144, :228-250, :285-331 @ a9779ef3c193lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestContextSuggestField.java:105-156 (testTokenStream: context, U+001D, SEP_LABEL, value) @ a9779ef3c193
- Who is affected
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:311-317 (empty context reported as null); lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextSuggestField.java:70 (HashSet of raw contexts) @ a9779ef3c193lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextSuggestField.java:44, :73-76; lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:71 @ a9779ef3c193
- Why it looks unintended
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextSuggestField.java:62-63, :166-179; lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:42-44, :124-139 @ a9779ef3c193lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestContextSuggestField.java:66-103; lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestSuggestField.java:101-124; lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestContextQuery.java:535 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java:313-323 (comment :316-322) @ a9779ef3c193
- Suggested fix
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextSuggestField.java:166-179; lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:124-144; lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java:316-322 (the replaceSep comment) @ a9779ef3c193
- History
lucene/CHANGES.txt:10233, :10242-10246 @ a9779ef3c193
- TestContextSuggestFieldHoleCharContext.java (JUnit test):
repro/LFV-522/src/org/apache/lucene/search/suggest/document/TestContextSuggestFieldHoleCharContext.java(64 lines)
assets/LFV-522/bug.png(439 KB)