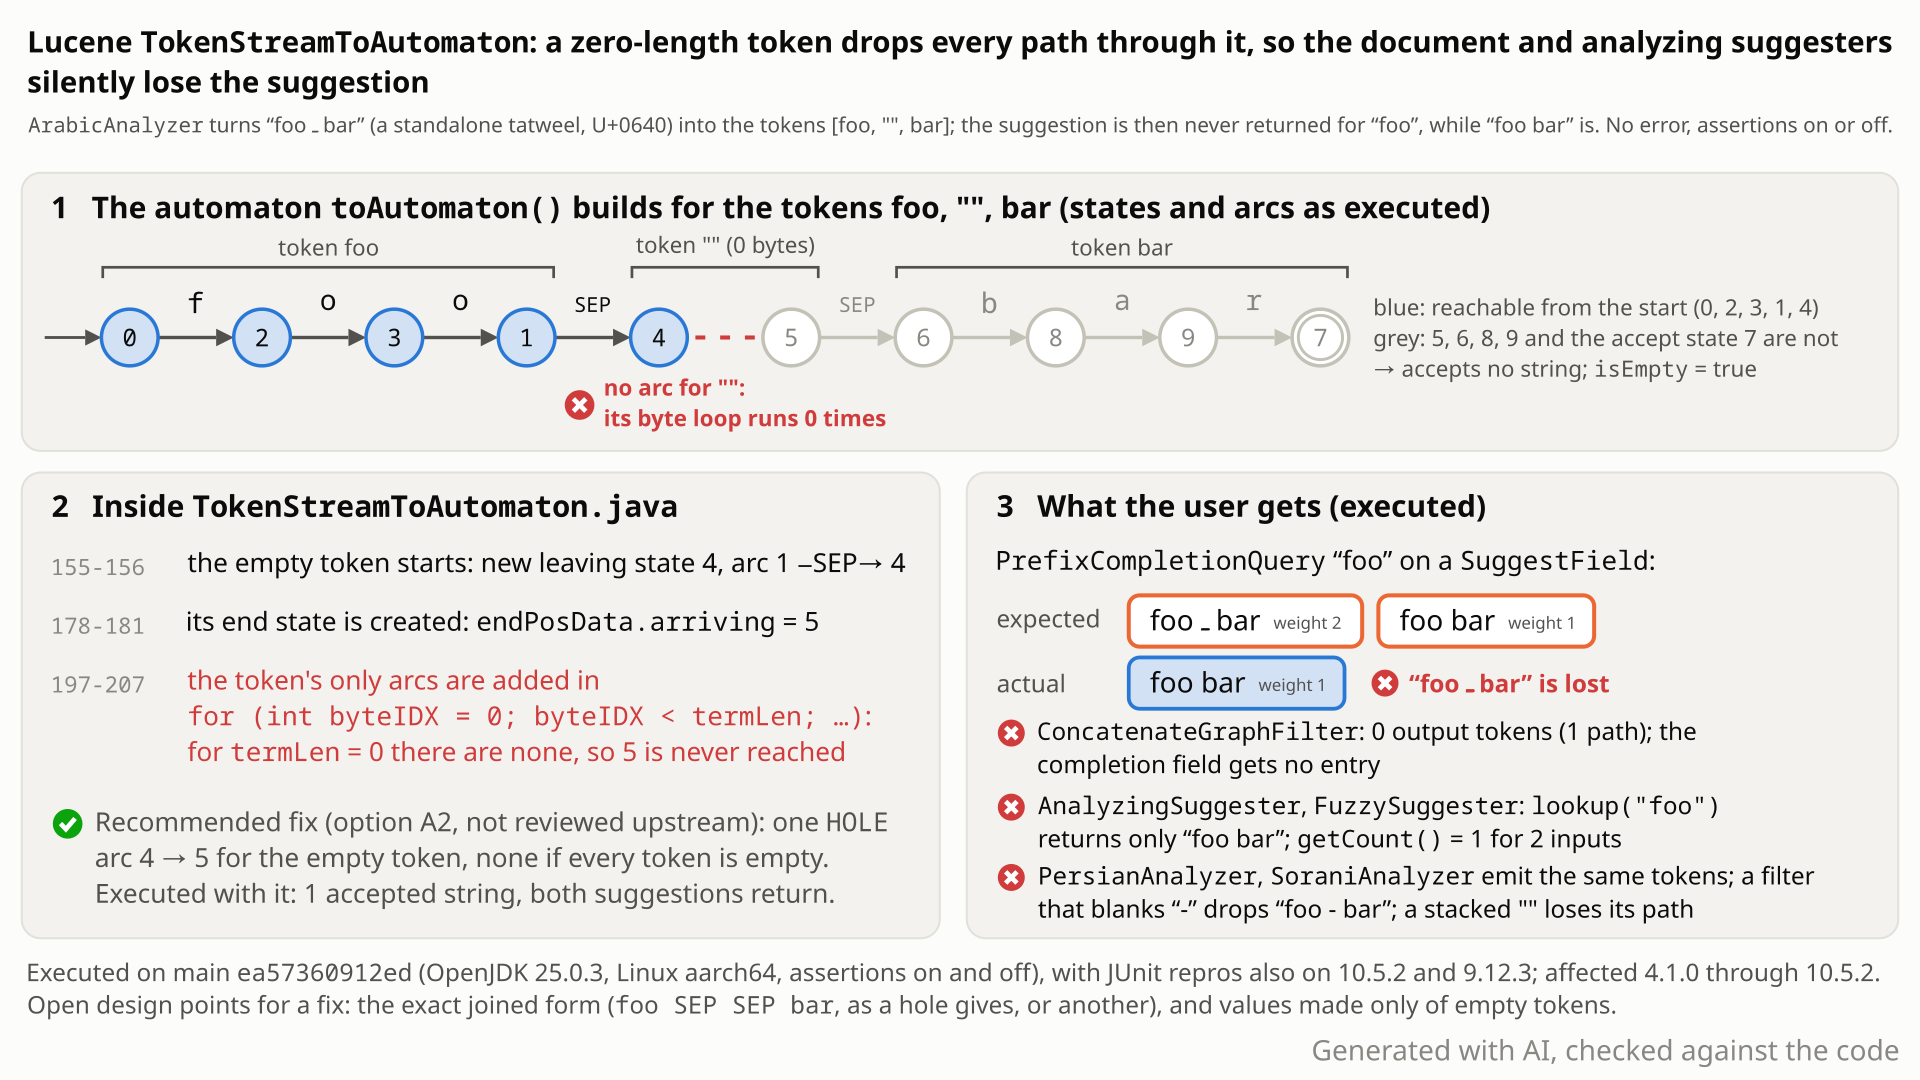
Completion suggesters turn each value's tokens into an automaton, one arc per byte. A token with no bytes gets no arc, so every path through it is cut: the value gets no suggestion entry, and a lookup key with such a token matches nothing.
- Index two suggestions with the stock
ArabicAnalyzer: "foo bar" (weight 1) and "foo ـ bar" (weight 2; the middle character is a standalone tatweel, U+0640). The analyzer turns them into the tokens [foo, bar] and [foo, "", bar]. - Ask for the prefix "foo":
PrefixCompletionQueryon aSuggestField, orlookup("foo")onAnalyzingSuggesterorFuzzySuggester. You expect both suggestions, [foo ـ bar, foo bar]. - You get [foo bar]. The suggester turns a value's tokens into an automaton with one arc per byte. The empty token has 0 bytes, so no arc reaches the state after it, and the automaton for "foo ـ bar" accepts no string at all.
- So
ConcatenateGraphFilteremits 0 tokens for a token graph with exactly one path, the document gets no completion entry, andAnalyzingSuggestercounts 1 entry for 2 inputs. The document and its other fields are indexed; only the suggestion entry is missing. Nothing throws, with assertions on or off. - Not only Arabic: a chain that strips punctuation turns "-" into "", so "Spider Man - Homecoming" never comes back for "spider". In a test set of 84 suggestions, all 45 that contain a standalone tatweel got no entry: the 42 that mix it with words should have one (the 3 made only of tatweels get none even with the recommended fix).
Applications using SuggestField/CompletionAnalyzer, AnalyzingSuggester, FuzzySuggester or ConcatenateGraphFilter, for values whose analysis has an empty token: a standalone tatweel under the stock Arabic, Persian or Sorani analyzer, or a filter that blanks a token, such as punctuation stripping. Deterministic and silent for every value whose only path runs through the empty token; index size plays no part; other entries are unaffected.
Mechanism, terms and numbers691 words
TokenStreamToAutomaton turns a token graph into an automaton whose labels are each token's bytes, with a separator (POS_SEP) between tokens. For each token it creates the state where the token ends and adds one arc per byte, the last one into that state. A token whose term is empty has no bytes, so no arc is added, the end state is never reached, and every path through the token is lost. Stock analysis emits such tokens on purpose: ArabicAnalyzer, PersianAnalyzer and SoraniAnalyzer turn a standalone tatweel (U+0640) into "", and PatternReplaceFilter can blank a punctuation-only token. Everything built on the class then drops the value without an error (the other suggesters, such as the infix and FST lookups, do not use it): ConcatenateGraphFilter emits no token although it promises "one output token for every path", the document suggester (SuggestField, CompletionAnalyzer) indexes no entry, and AnalyzingSuggester and FuzzySuggester skip the input. With ArabicAnalyzer, the suggestions "foo bar" and "foo ـ bar" and the prefix "foo" give only [foo bar]; a lookup that contains a standalone tatweel returns nothing. A stacked empty token loses only its own path. The loop has had no zero-length case since the class was written in 2012: all 120 release tags from 4.1.0 to 10.5.2 in the history clone have it, the 21 releases executed fail, and so does main.
- Empty token: a token whose term has zero characters,
"". Lucene allows them, and some stock filters produce them on purpose: the Arabic, Persian and Sorani normalizers delete the tatweel (U+0640), a typographic stretching mark, so a tatweel standing alone between spaces becomes"";PatternReplaceFiltercan blank a token such as-. TokenStreamToAutomaton: turns the tokens of one value into an automaton, a graph of states joined by arcs, one arc per byte of each token, with a separator arc (SEP) between tokens and aHOLEarc where a position is missing (a removed stop word). Each path from the start to an accept state spells one way to read the value.- Its users:
ConcatenateGraphFilterjoins every path into one token; the document suggester (SuggestField,CompletionAnalyzer) indexes those joined tokens;AnalyzingSuggesterandFuzzySuggesterindex the automaton's strings directly. The other suggesters (AnalyzingInfixSuggester,BlendedInfixSuggester,FreeTextSuggester,FSTCompletionLookup,WFSTCompletionLookup) do not use it.
- For every token, the state where the token ends is created first (
TokenStreamToAutomaton.java:178-181). - The token's arcs are added only inside
for (int byteIDX = 0; byteIDX < termLen; byteIDX++)(:197-207); the last arc ends in that state. - For an empty token
termLenis 0, the loop runs zero times, and nothing joins the state where the token starts to the state where it ends. Everything after it hangs off an unreachable state: forfoo,"",barthe automaton accepts no string. - With no strings,
ConcatenateGraphFilteremits no token, the completion field gets no entry, and the analyzing suggesters get no input. If the empty token is stacked on a non-empty one at the same position, only its own path is lost.
| what you do | expected | got |
|---|---|---|
TokenStreamToAutomaton on a, "", b | 1 path | 0 |
the same with a, {y | ""}, b | 2 paths | 1 |
ConcatenateGraphFilter on a, "", b | 1 token | 0, for each of the 5 separators tried and both position settings |
SuggestField "foo bar" and "foo ـ bar", ArabicAnalyzer, prefix "foo" | 2 | 1 (foo bar) |
AnalyzingSuggester / FuzzySuggester, same inputs | 2 | 1; getCount() 1 for 2 inputs |
whitespace + lowercase + patternReplace stripping punctuation: "Spider Man - Homecoming", lookup "spider" | 2 | 1 |
84 suggestions (all 1-3 word sequences of foo, bar, baz, ـ), AnalyzingSuggester | 81 (84 minus the 3 made only of tatweels, which get none even with the fix) | 39: the 42 that mix a tatweel with words are lost |
| query side, same 84: lookup "foo ـ" | 20 (with the fix) | 0 ("foo" gives 13) |
| controls: a non-empty middle token, a hole | kept | kept |
Exposure and likelihood343 words
- Entry points. The document suggester (
SuggestField,ContextSuggestField,CompletionAnalyzer,PrefixCompletionQueryand its siblings),AnalyzingSuggester,FuzzySuggester, andConcatenateGraphFilter(or itsconcatenateGraphfactory) in any analysis chain. - What it takes. A value, or a lookup key, whose analysis contains a token with an empty term that the paths must cross (an empty token stacked next to a non-empty one loses only its own path). Stock prebuilt analyzers:
ArabicAnalyzer,PersianAnalyzerandSoraniAnalyzeron a standalone tatweel. Custom chains: a filter that can blank a token with noLengthFilterafter it, for examplePatternReplaceFilterstripping punctuation under a whitespace tokenizer (its javadoc warns it "may produce Tokens whose text is the empty string"), orKeywordTokenizer+TrimFilteron blanks. - Opt-in. The completion suggesters and
ConcatenateGraphFilterare features an application chooses (the document suggester also needs a completion postings format), andTokenStreamToAutomaton,ConcatenateGraphFilterand the suggester classes are marked experimental (the analyzers andPatternReplaceFilterare not). Within such an application the trigger is ordinary text. - Deterministic and silent. Every value whose only path runs through an empty token is lost on the first try, with assertions on or off; no exception, no log line. The automaton is built from the value's own tokens, so index size plays no part. In the security probe the document and its other fields were indexed, CheckIndex was clean and other entries were unaffected.
- Both sides. At index time the value never becomes a suggestion (the document is indexed, its completion entry is not); at lookup time a key with a standalone tatweel ("foo ـ") returns nothing.
- Not affected.
AnalyzingInfixSuggester,BlendedInfixSuggester,FreeTextSuggester,FSTCompletionLookupandWFSTCompletionLookupdo not useTokenStreamToAutomatonorConcatenateGraphFilter. - How often. A standalone tatweel is uncommon in titles and names (it normally sits inside words); a punctuation-stripping chain hits ordinary text such as "Spider Man - Homecoming" every time. Nobody has reported it since 4.1.0, so the registry rates it rare (a judgement, not a measurement).
- Downstream. Search servers build completion features on these classes; that path was not executed.
The test shows that a zero-length token (ArabicAnalyzer turns the standalone tatweel in foo ـ bar into foo, "", bar) makes TokenStreamToAutomaton drop the path through it, so ConcatenateGraphFilter emits nothing.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.ar.ArabicAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestConcatenateGraphFilterEmptyToken extends LuceneTestCase {

  public void testPathThroughEmptyTokenIsKept() throws Exception {
    // ArabicAnalyzer turns the standalone tatweel (U+0640) into an empty token: foo, "", bar
    try (Analyzer analyzer = new ArabicAnalyzer();
        TokenStream ts = new ConcatenateGraphFilter(analyzer.tokenStream("f", "foo ـ bar"))) {
      ts.reset();
      int tokens = 0;
      while (ts.incrementToken()) {
        tokens++;
      }
      ts.end();
      assertEquals("output tokens for the one path foo, \"\", bar", 1, tokens);
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-523/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestConcatenateGraphFilterEmptyToken
- Expected vs actual
- Expected one output token for the one path; actual none (
expected:<1> but was:<0>), with-eaand-da.
More files, environment, full output42 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: output tokens for the one path foo, "", bar expected:<1> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.analysis.miscellaneous.TestConcatenateGraphFilterEmptyToken.testPathThroughEmptyTokenIsKept(TestConcatenateGraphFilterEmptyToken.java:36)ConcatenateGraphFilterpromises "one output token for every path"; foo → "" → bar has one path and gets none.- The authors' own 2012 comment says two adjacent separators also match an empty-string token; on our reading, its path was meant to survive.
- Empty tokens are intended: Lucene's Sorani test asserts that a standalone U+0640 normalizes to "".
The full argument317 words
ConcatenateGraphFilterjavadoc (ConcatenateGraphFilter.java:40-41): "Concatenates/Joins every incoming token with a separator into one output token for every path through the token stream (which is a graph)."TokenStreamToAutomatonjavadoc (:31-33): the labels are the token's bytes, and "Between tokens we insert POS_SEP and for holes we insert HOLE." Read literally,a,"",bgivesa SEP SEP b, not an empty language; the javadoc does not mention empty tokens, so this is a reading, not an explicit rule.- The authors' comment in
replaceSep(AnalyzingSuggester.java:295-301, added with the trunk commit of the class,f2f91bae46c; the copy atConcatenateGraphFilter.java:316-322came later throughCompletionTokenStream, LUCENE-6339, and LUCENE-8332): removing a hole leaves "two SEP tokens next to each other ... Note that it will also match an empty-string token". Our reading, an inference: it assumes the empty token's path is there. preservePositionIncrementsjavadoc (ConcatenateGraphFilter.java:103-105): "Whether to add an empty token for missing positions. The effect is a consecutive SEP_LABEL."- Empty terms are legal:
TestSoraniNormalizationFilterassertscheckOneTerm(a, "\u0640", "")(:85);PatternReplaceFilter's javadoc warns it may produce empty tokens; LUCENE-3529 and LUCENE-4880 madeIndexWriterandMemoryIndexaccept empty terms. Being legal to index does not by itself mean every experimental graph consumer promises to handle them; the case rests on theConcatenateGraphFilterpromise and on the absence of any exclusion. - Upstream tests: one randomized test,
TestFlattenGraphFilter(:702), asserts that this class's output for its graphs has no dead states (not a stated invariant, but dead states are not expected output); the empty-token automaton has them.TestGraphTokenizersandTestConcatenateGraphFiltercover holes and an empty stream, never a zero-length token, and no test pins today's behaviour. - History: the loop never had a zero-length case (LUCENE-3842, 2012); the 66 JIRA comments of that issue discuss holes and separators only, and no won't-fix or by-design discussion was found.
The devil's-advocate check218 words
Strongest case for "intended": the classes that build and consume the automaton are experimental; PatternReplaceFilter warns about empty tokens, so users should add LengthFilter(min=1); some components reject empty tokens; AnalyzingSuggester documents that "Lookups with the empty string return no results", SuggestField rejects an empty value, and an empty stream yields no output by design. And an empty term has no byte for an arc, so encoding it as a HOLE conflates a real token with a missing position; nobody has reported the behaviour.
Why it fails: experimental allows API changes, not silent loss of entries; no javadoc of these classes asks for non-empty tokens, and the authors' comment, on our reading, expects the empty token to survive; the prebuilt Arabic, Persian and Sorani analyzers have no option for an extra filter (wrapping them works, but nothing tells users to); the empty-input rules cover an empty value, stream or lookup, not a non-empty value with one empty token inside; and an upstream test treats dead states as a failure for its graphs. The encoding point is about how to keep the path, not whether to keep it. Every checker concluded "not intended". The exact joined form (a SEP SEP b or a SEP b) is a design choice for the maintainers; the path must not vanish.
Recommended Connect an empty token like a hole, unless every token is empty (recommended of the two tested shapes)
Recommended of the two tested shapes: connect a zero-length token like a hole (one HOLE arc to its end state), only when the stream also has a non-empty token, so an all-empty lookup still matches nothing. +20 lines; the new tests and the core analysis, analysis-common and suggest suites pass. Limit: an all-empty ContextSuggestField value gets an entry.
All options and trade-offs6 options · 1,258 words
Both arc-based options were run through gradle in a scratch worktree at ea57360912ed; the others are untested design alternatives. Every command is in the fix folder's commands.txt.
Connect an empty token like a hole, unless every token is empty (recommended of the two tested shapes) (validated by the checks)
optionA2-hole-arc-unless-all-empty.diff, TokenStreamToAutomaton.java only, +20 lines (counting an IntArrayList import and two blank lines). Each empty token's start and end states are recorded; after the loop they get the one HOLE arc a hole gets, if the stream had any non-empty token. ConcatenateGraphFilter and AnalyzingSuggester (so also FuzzySuggester) turn HOLE into an epsilon, so a, "", b is joined as a SEP SEP b, the form the replaceSep comment and the preservePositionIncrements javadoc describe; direct callers of toAutomaton, such as the test framework's assertGraphStrings, see the raw HOLE label. A stream of only empty tokens keeps today's automaton (it accepts nothing), so a lookup key made only of empty tokens still matches nothing, like an empty key, and for SuggestField, AnalyzingSuggester and FuzzySuggester a value made only of tatweels still gets no entry. Automaton.Builder accepts transitions in any order.
    // (from, to) state pairs of zero-length tokens, connected at the end:
    final IntArrayList emptyTokens = new IntArrayList();
    boolean sawNonEmptyToken = false;
    while (in.incrementToken()) {
      ...
      if (termLen == 0) {
        emptyTokens.add(state);
        emptyTokens.add(endPosData.arriving);
      } else {
        sawNonEmptyToken = true;
      }
      ...
    }
    in.end();

    if (sawNonEmptyToken) {
      // A zero-length token has no bytes, but it still spans its position(s): connect it like a
      // hole so the paths through it are kept (consumers remove HOLE, leaving two adjacent
      // separators). A stream of only zero-length tokens accepts nothing, like an empty stream.
      for (int i = 0; i < emptyTokens.size(); i += 2) {
        builder.addTransition(emptyTokens.get(i), emptyTokens.get(i + 1), HOLE);
      }
    }
Trade-offs
ContextSuggestField: the all-empty exception looks at the whole stream, andContextSuggestFieldputs a non-empty context-prefix token in front of the value. So with this fix aContextSuggestFieldvalue made only of tatweels gets an entry with an empty key (stock gets none), and a match-allContextQueryreturns it (executed by the fact check). The guard test checks only the lookup side. Any non-empty token, even one stacked alternative, turns the exception off.- An empty token and a removed (hole) token become the same in the automaton when
preservePositionIncrementsis true; with false a hole collapses toa SEP bwhile this fix still givesa SEP SEP b. The exact form is the maintainers' choice. - A prefix lookup "foo" returns "foo ـ bar", but the exact lookup "foo bar" does not match it, as with a stop-word hole.
- Edges: a stream whose only position holds a non-empty token and a stacked empty one also accepts the empty string (no stock analyzer was seen producing that); an empty token with
positionLength > 1gets oneHOLEarc across its span (untested). - Not reviewed by a committer.
What the checks validated
- The doc's test plus 3 guard tests for lookups made only of empty tokens (
AnalyzingSuggester,PrefixCompletionQuery,ContextQuery): 9 tests, 0 failures, with-Ptests.asserts=trueand=false. TestGraphTokenizerswith 3 new tests: 26 tests, 0 failures; coreorg.apache.lucene.analysis.*: 21 classes, 171 tests, 0 failures (assertions on, the core module's default for this seed).- The whole suggest module: 32 classes, 245 tests (236 upstream + 9 new), 0 failures, with assertions off (2026-10-26, the seed's default) and on (the fact check's
-Ptests.asserts=truere-run). The whole analysis-common module: 339 classes, 1,909 tests, 0 failures, likewise off and on (it includes the graph-string tests ofTestSynonymGraphFilterandTestWordDelimiterGraphFilter, which use this class).TestRandomChains: 2 tests, 0 failures (assertions off). :lucene:core:check :lucene:suggest:check -x test(google-java-format, ecjLint, forbiddenApis) passes.- Harness with the fix shadowed in: the finder's test 3 of 3 (including the joined token
a SEP SEP b), an independent reproducer's 10 of 10, and the follow-up's security probe: in 620 lookups every stock result set is a subset of the fix's, 0ContextQueryerrors, a lone-tatweel lookup returns nothing, 81 of 84 inputs get an entry.
Inside the loop, if (termLen == 0) builder.addTransition(state, endPosData.arriving, HOLE);. It fixes every bug test, and no upstream test fails (suggest 245 tests, analysis-common 1,909, TestRandomChains).
      if (termLen == 0) {
        // A zero-length token still spans its position(s): connect it like a hole so that the paths
        // through it are kept (consumers remove HOLE, so it reads as an empty element between two SEPs).
        builder.addTransition(state, endPosData.arriving, HOLE);
      }
Trade-offs
A value or lookup made only of empty tokens becomes the empty string: a lookup for a lone tatweel returns every suggestion (AnalyzingSuggester 2 of 2 instead of 0, PrefixCompletionQuery 1 of 1), against the documented "Lookups with the empty string return no results". With assertions off a ContextQuery returns 2 of 2, including an entry made only of a tatweel; with assertions on that lookup fails with an AssertionError at ContextQuery.java:319.
What the checks validated
The 6 bug tests, the finder's 3 and the reproducer's 10 pass. The 3 guard tests fail through gradle with assertions off and through the harness with assertions on and off; testOnlyEmptyTokens fails (assertions on). The suggest, analysis-common and TestRandomChains suites ran with assertions off (the seed's default).
Treat a zero-length token like a removed token with preservePositionIncrements=false, so "foo ـ bar" matches the lookup "foo bar".
Trade-offs
More code (merge the token's start and end states, or an epsilon), and an empty token then behaves differently from a hole, against the preservePositionIncrements javadoc. Untested.
Wrap the stream in ConcatenateGraphFilter and the analyzing suggesters with a filter that drops empty tokens and carries their position increment, as LengthFilter does.
Trade-offs
For an empty token alone at its position it gives the recommended fix's result for those consumers; for a stacked one (position increment 0) the filter removes the alternative, while the recommended fix keeps it as a HOLE path. TokenStreamToAutomaton stays wrong for its other callers (for example the test framework's assertGraphStrings), and three places change instead of one. Untested.
Either toAutomaton throws on a zero-length term, so the loss becomes loud, or the empty token gets its own label instead of HOLE, so consumers can tell it from a missing position.
Trade-offs
Rejecting makes values that index silently today fail at index time; a new label needs every consumer of the automaton to handle it. Untested; listed because the cross-model fact check suggested presenting it.
Workaround in every affected release: drop empty tokens before the suggester (validated by the checks)
In a CustomAnalyzer, add the length filter with min=1; around a prebuilt analyzer, an AnalyzerWrapper whose wrapComponents appends new LengthFilter(tokenStream, 1, Integer.MAX_VALUE). LengthFilter turns the removed token into a hole, so the value is joined as foo SEP SEP bar, the same form as the recommended fix for an empty token alone at its position (a stacked empty token is simply removed).
Trade-offs
Each application has to know about it; nothing in the suggester documentation says it is needed.
What the checks validated
On stock main, ArabicAnalyzer wrapped this way returns [foo ـ bar, foo bar] from both AnalyzingSuggester and SuggestField (2 tests, 0 failures).
Bounded-exhaustive translation validation: a checker compared the real ConcatenateGraphFilter and TokenStreamToAutomaton with an independent reference of the documented join semantics over every token graph of up to 3 positions (1,041,120 checks). Paths through an empty token went missing; a suggester-level checker and a survey of stock analyzers then found the tatweel trigger.
The method in full240 words
Method: bounded-exhaustive translation validation (a hunt unit, completion suggester indexing, 2026-10-26, main ea57360912ed). No model checker, SMT solver or prover was involved.
- The finder (an AI tool) wrote an independent reference of the documented join semantics: one output token for every path, separators between tokens, holes for missing positions.
- Its checker (
ConcatGraphTV.java) ran the real classes against it over every token graph of up to 3 positions, each a hole or 1-2 distinct stacked tokens from an 8-token alphabet that includes the empty token (every token with position length 1; graphs made only of holes skipped), with trailing holes on and off, 5 separators and bothpreservePositionIncrementssettings: 1,041,120 checks. The run reported 889,575 mismatches in all, sorted into classes; the class "missing paths through an empty token" (245,958 checks) is this bug, and the other classes (separator escaping, non-ASCII separators, the expansion limit and an unclassified rest) are separate questions, not part of this report. - A suggester-level checker (
SuggestTV.java), with a token mapped to"", found 7,915 mismatching (query x configuration) checks out of 13,440, each missing one or more results and none returning an extra one; a survey of stock analyzers found that the Arabic, Persian and Sorani analyzers emit an empty token for a standalone tatweel. - Then a public-API JUnit, a cross-model review, independent verifiers, an adjudication, a 66-run release sweep, a prior-report search and a security screen (see Independent checks).
No prior report found: about 241 tool queries, 59 GitHub searches and 9 web searches over issues, PRs, commits, JIRA, the mailing lists and downstream projects, plus the changed files of all 408 open PRs (2026-10-26). Upstream main still has the 2020 version of the file, and no open PR touches it.
Searches4 searches
None of the searched issues, PRs, commits, JIRA entries, list threads or downstream reports describes a zero-length token cutting paths in TokenStreamToAutomaton, ConcatenateGraphFilter emitting nothing for it, or suggestions lost this way. The two earlier defect fixes the class's history shows concern holes (LUCENE-8344, 2018; commit e64111c6545, 2017). Word-based searches show what was found, not that no report exists anywhere.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | a scripted prior-report search in five runs (about 241 queries in all, with GitHub, JIRA, list and web sources), 31 direct GitHub searches: class names, 'empty token', 'zero-length token', tatweel, kashida, U+0640, replaceSep, POS_SEP, the suggester classes with 'empty' | no report; nearest #9391 / LUCENE-8344 (trailing position increment), commit e64111c6545 (holes freed too early), #4915 / LUCENE-3842 (the introducing change, no zero-length discussion), #9379, #9370, #10061 (ConcatenateGraphFilter), #7518 and #9334 (empty value rejected, empty query returns nothing: intended) |
| Open PRs | 2026-10-26 | the changed files of all 408 open apache/lucene PRs; re-checked with a PR search for TokenStreamToAutomaton | none touches TokenStreamToAutomaton.java; #16911 (deletes branch_10x) is the only one touching ConcatenateGraphFilter |
| JIRA archive and mailing lists | 2026-10-26 | the migrated LUCENE JIRA, dev@, java-user@, issues@ and commits@ (including the exact phrases 'empty token' and 'zero-length token') | no report; java-user threads only confirm that empty tokens are legal and that TrimFilter + LengthFilter removes them |
| Downstream and web | 2026-10-26 | 28 GitHub searches on Elasticsearch, OpenSearch, Solr, lucene-solr and Lucene.NET; 9 web searches; two Q&A pages checked later through their public feeds (one saved feed was a 'page not found' page; the fact check fetched it again) | no report; Elasticsearch #46445, #31738, #25664, #30286 are missing completion suggestions from other causes |
Present since the class was written for LUCENE-3842 (2012) and first released in 4.1.0; the loop never changed. Fails on all 21 releases tried from 4.1.0 to 10.5.2 and on main. Silent everywhere except 4.10.x and 5.1-5.2, where unrelated changes made it throw. Not fixed upstream.
Versions tested9 rows
Introduced by LUCENE-3842 "add AnalyzingSuggester" (@mikemccand, issue #4915): written on the feature branch in 9d7873ff5a6 (2012-09-15), committed to trunk as f2f91bae46c and merged to branch_4x as 0c89e05d765 (2012-09-28). The trunk commit added the replaceSep comment (in AnalyzingSuggester) that, on our reading, expects an empty-string token to read as two separators. Later edits to the loop (LUCENE-5030, LUCENE-5752, LUCENE-6653, the LUCENE-9570 reformat) added no zero-length case. Not a regression.
Consumers are affected from their own first release: AnalyzingSuggester and FuzzySuggester 4.1.0, the document suggester 5.1.0 (LUCENE-6339), ConcatenateGraphFilter 7.4.0 (LUCENE-8332). On 4.10.x and 5.1-5.2 the same lost path made an unrelated automaton change throw IllegalStateException: from state (0) already had transitions added; LUCENE-5963 and LUCENE-6365 made it silent again. No issue links that exception to empty tokens. On upstream main the file's last change is the 2020 reformat.
| Version or commit | Verdict | Result |
|---|---|---|
| 4.0.0 | no API | TokenStreamToAutomaton, AnalyzingSuggester and FuzzySuggester do not exist (compile error) |
| 4.1.0 | first affected | the automaton for a, "", b accepts 0 strings; both suggesters return only "foo bar"; one added arc fixes it |
| 4.5.1, 4.9.1 | affected | silent drop |
| 4.10.0, 4.10.4 | throws | core path lost; AnalyzingSuggester/FuzzySuggester.build() throws IllegalStateException |
| 5.0.0 | affected | silent drop |
| 5.1.0, 5.2.1 | throws | suggesters drop the entry silently; consuming CompletionAnalyzer's stream throws IllegalStateException |
| 5.3.0 to 10.5.2 (13 releases run: 5.3.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.4.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2) | affected | silent: 0 completion tokens, suggestion lost; ConcatenateGraphFilter emits 0 tokens from 7.4.0 on; the doc's test fails 6 of 6 on 10.5.2 |
| main ea57360912ed | affected | the doc's test fails 6 of 6 through gradle with -Ptests.asserts=true and =false and through the harness with -ea and -da; upstream main a95c754ee003 still has the 2020 version of the file |
| main with the recommended fix | not affected | the doc's test and guards 9 of 9; core analysis 171 tests pass (assertions on), and suggest 245 and analysis-common 1,909 with assertions on and off |
An independent reproducer, a devil's advocate and an adjudication said real; an OpenAI GPT-5.6 reviewer (reading only) agreed on the root cause, said real in most of its lenses and "not real" in one only because it could not run code. This doc's test and both arc-based fixes were run through gradle.
Checks and verdicts436 words
All checks ran on main ea57360912ed unless noted; the GPT-5.6 reviews read code only. Assertion modes: the harness runs used -ea and -da; the 2026-10-26 gradle runs used the seed's default (off for the suggest and analysis-common modules, on for core), and the 2026-10-27 fact check re-ran them with an explicit -Ptests.asserts=true.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit) | candidate | The 3-test JUnit fails 3 of 3 on main, 10.5.2 and 9.12.3; a main() variant fails on 9.0.0, 8.11.4, 7.7.3 and 6.6.6; with the fix sketch it passes. |
| Cross-model review (OpenAI GPT-5.6, reading only) | root cause real; intended behaviour real; refute not real (procedural) | It agreed on the root cause, found the inputs in contract and the works-as-designed case weak; the refute-lens review votes not real when it cannot run code. A separate run re-ran the finder's test: fail 3 of 3, pass with the fix. |
| Independent reproducer | real | Its own 10-test JUnit fails its 7 bug tests on main, 10.5.2 and 9.12.3 (the 3 controls pass), including the stacked path, FuzzySuggester, the document suggester and a PatternReplace chain; 10 of 10 with the fix. |
| Devil's advocate | real | Built the strongest intended readings (misuse, acknowledged corner case, empty-input rules, experimental API) and showed why each fails; its probe recorded dead states, no output for any separator, and a stacked path lost. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's test with a fresh seed (7 of 10 fail, assertions on and off), the finder's (3 of 3) and the independent reproduction's with the fix (10 of 10 pass). |
| Follow-up and registry re-runs | reproduced | The 66-run release sweep, the security probe (620 lookups, only lost results), and re-runs with fresh seeds on main and 10.5.2. |
| This doc's test and fix validation | reproduced; fix validated | The new 6-test JUnit fails 6 of 6 through gradle (assertions on and off, fact-check re-run) and through the harness on main and 10.5.2; the recommended fix passes it, 3 guard tests, 3 new core tests and the core analysis, suggest and analysis-common suites. |
| Fact checks of this doc (2026-10-27) | bug confirmed; wording fixed | An independent fact check and a cross-model one (OpenAI GPT-5.6, reading only) confirmed the bug and the mechanism and found wording and provenance errors: the assertion mode of the gradle runs, a cited run of an earlier draft, the fix's ContextSuggestField limit, the scope of the affected suggesters, and the unit of the checker's count. All are fixed here; the fact check re-ran the test and the fix's suites with assertions on. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 492 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,505 words
- Registry title
- A zero-length token makes TokenStreamToAutomaton drop every path through it, so ConcatenateGraphFilter emits nothing and the document suggester, AnalyzingSuggester and FuzzySuggester silently lose that suggestion (stock trigger: a standalone tatweel U+0640 with ArabicAnalyzer, PersianAnalyzer or SoraniAnalyzer)
- Area
- analysis / TokenStreamToAutomaton (core), reached through ConcatenateGraphFilter (analysis-common) and the completion suggesters (suggest: NRT document suggester, AnalyzingSuggester, FuzzySuggester)
- Priority
- Low, rank 270: Needs a zero-length token in a completion-suggester value, for example a standalone tatweel, an uncommon input.
- Impact class
- silent wrong results
- Impact note
- Hits applications that use a completion suggester (the NRT document suggester through SuggestField or CompletionAnalyzer, AnalyzingSuggester or FuzzySuggester) or ConcatenateGraphFilter directly, and only for values whose analysis contains a zero-length token, which the stock ArabicAnalyzer, PersianAnalyzer and SoraniAnalyzer emit for a standalone tatweel and custom chains emit when a filter such as PatternReplaceFilter blanks a punctuation-only token: that suggestion is silently never indexed or never returned (a stacked empty token loses only its own alternative path), with -ea and -da, no scale needed and no exception.
- Summary
- You index the suggestion 'foo ـ bar' (a standalone Arabic tatweel between two words) with ArabicAnalyzer into a SuggestField, or build an AnalyzingSuggester or FuzzySuggester from it, and expect a lookup for 'foo' to return it next to 'foo bar', because ArabicAnalyzer turns the tatweel into an ordinary empty token and ConcatenateGraphFilter promises one output token for every path through the token graph. Instead TokenStreamToAutomaton adds a token's transitions only inside its per-byte loop, which never runs for a zero-length token, so the token's end state is unreachable: ConcatenateGraphFilter emits nothing, the document suggester indexes no entry for the value and the analyzing suggesters skip the input, so the suggestion never comes back. A stacked empty token loses only its own alternative path; nothing throws, with assertions on or off.
- Introduced
- f2f91bae46cbc4a883324521767e4701fbbbc14a (LUCENE-3842 'add AnalyzingSuggester', mikemccand, svn r1391683 on trunk; the class was first written on the feature branch lucene3842 in 9d7873ff5a6 (r1385125, 2012-09-15) and reached branch_4x as the merge 0c89e05d765 (r1391686); JIRA patch workflow, no PR; issue #4915) [read: git log --follow and git blame in the history clone; git blame on main still attributes the loop skeleton (TokenStreamToAutomaton.java:174-175, 178, 181-182, 206-207) to it, and none of the later commits that touched the loop (LUCENE-5030, LUCENE-5752, LUCENE-6653, the LUCENE-9570 reformat) added a zero-length case]. Not a regression (2012-09-28 (trunk and branch_4x commits; the feature-branch commit is from 2012-09-15))
- First affected version
- 4.1.0 [exec] (the first release with TokenStreamToAutomaton, AnalyzingSuggester and FuzzySuggester; 4.0.0 does not have them [exec: compile error]). Later consumers are affected from their own first release: the NRT document suggester from 5.1.0 and ConcatenateGraphFilter from 7.4.0 [exec]
- Affected versions
- 4.1.0 through 10.5.2 (the last release before 10.6.0; the latest 9.x is 9.12.3) and main ea57360912ed. [exec] per-era main() probes fail on 4.1.0, 4.5.1, 4.9.1, 4.10.0, 4.10.4, 5.0.0, 5.1.0, 5.2.1, 5.3.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.4.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (4.1.0, 4.10.4, 10.5.2 and main also with -da), with every control (a non-empty middle token) passing; on 4.1.0 one added arc for the empty token (shadowed) makes the probe pass; the ConcatenateGraphFilter probe fails on 7.4.0, 8.11.4, 9.12.3, 10.5.2 and main; the finder's JUnit fails 3 of 3 on 9.12.3, 10.5.2 and main (-ea, -da); the independent reproduction's JUnit fails 7 of 10 on 9.12.3, 10.5.2 and main (-ea, -da). The visible symptom differs in two windows for reasons unrelated to this bug: on 4.10.0-4.10.4 AnalyzingSuggester/FuzzySuggester.build() throws IllegalStateException 'from state (0) already had transitions added', and on 5.1.0-5.2.1 consuming the document suggester's analysis chain throws the same exception [exec; mechanism read: LUCENE-5752, then LUCENE-5963 and LUCENE-6365]; every other release loses the suggestion silently. [read] all 120 release tags from 4.1.0 to 10.5.2 in the history clone have the per-term loop with no zero-length case (8.8.2-8.11.4 are not tagged there; 8.11.4 was executed). Not fixed upstream: upstream main ffa9d816eeb4 has a byte-identical TokenStreamToAutomaton.java, its last change on main and the 10.x branches is the 2020 reformat, and no open PR touches it [read, 2026-10-26]. Executed only on aarch64 Linux with JDK 25 (plain Java logic)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record, verdict new; plus the finder's and the intended-behaviour check's searches): a scripted prior-report search in five runs (24 + 38 + 60 + 66 + 53 queries) over apache/lucene GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists (including the exact phrases 'empty token', 'zero-length token' and 'empty tokens'), the JIRA archive and the web; 31 GitHub GraphQL searches on apache/lucene (class names, 'empty token', tatweel, kashida, U+0640, replaceSep, POS_SEP, the suggester classes with 'empty') and 28 on Elasticsearch, OpenSearch, Solr, lucene-solr and Lucene.NET; 9 web searches; the changed files of all 408 open apache/lucene PRs; the file's commit history on main and the 10.x branches; local git history (-S 'termLen == 0': none). Related, not this bug: #9391/LUCENE-8344 (closed, 2018: trailing position increment with preservePositionIncrements=false; the last functional change to the class), commit e64111c6545 (2017: holes freed too early), #4915/LUCENE-3842 (closed: introduced the class and the replaceSep comment; its discussion never mentions zero-length tokens), #9379/LUCENE-8332 and #9370/LUCENE-8323 (ConcatenateGraphFilter created), #10061/LUCENE-9018 (custom separator; holds the preservePositionIncrements 'empty token' javadoc), #6094/LUCENE-5030, #7025/LUCENE-5963, #7400/LUCENE-6339 (other changes to the same code), #7518/LUCENE-6459 (SuggestField rejects an empty value), #9334/LUCENE-8287 and commit beb163c9160 (empty query automata, intended), #9570, #9465, #3479, #2049 (empty tokens in other components), Elasticsearch #46445, #31738, #25664, #30286 (missing completion suggestions for other causes), #16911 (open PR that deletes branch_10x; the only open PR touching ConcatenateGraphFilter). Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
ea57360912ed(commit of 2026-10-24; tested 2026-10-26, re-checked 2026-10-27), seed DEADBEEF: the doc's test through gradle with-Ptests.asserts=trueand=false(the fact check's re-run; the 2026-10-26 gradle runs used the seed's default, assertions off) and through a standalone JUnit harness with-eaand-da; the doc's test also on the 10.5.2 release jars; per-version probes on 21 releases from 4.1.0 to 10.5.2 (4.0.0 does not have the class).
- Finding record
lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:30-36 (at ea57360912ed) (class javadoc: transition labels are the token's UTF-8 bytes or code points; 'Between tokens we insert POS_SEP and for holes we insert HOLE' at :33; @lucene.experimental), :174-181 (the token's end position and its arriving state are created), :195 (state = posData.leaving), :197-206 (the only transitions for a token, inside 'for (int byteIDX = 0; byteIDX < termLen; byteIDX++)': zero iterations when termLen == 0)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java:39-46 (at ea57360912ed) (class javadoc: 'one output token for every path through the token stream (which is a graph)'; @lucene.experimental), :100-105 (preservePositionIncrements: 'Whether to add an empty token for missing positions. The effect is a consecutive SEP_LABEL'), :221-235 (toAutomaton through TokenStreamToAutomaton), :312-324 (replaceSep: removing a HOLE leaves two SEPs, 'Note that it will also match an empty-string token')lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:95 (at ea57360912ed) (documented limitation: lookups with the empty string return no results), :268-301 (replaceSep with the same HOLE comment), :317-318 and :406 (TokenStreamToAutomaton use)lucene/analysis/common/src/test/org/apache/lucene/analysis/ckb/TestSoraniNormalizationFilter.java:85 (at ea57360912ed) (checkOneTerm(a, "\u0640", ""): a standalone tatweel normalizes to the empty term by design); lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicNormalizer.java:48, :81 (TATWEEL removed); lucene/analysis/common/src/java/org/apache/lucene/analysis/pattern/PatternReplaceFilter.java:32 ('may produce Tokens whose text is the empty string')
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:30-36 (class javadoc), :155-156 (SEP arc), :174-181 (end state created), :195-207 (the per-byte loop, the only arcs of a token), :244-255 (accept states)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java:39-46 (one output token for every path), :226-250 and :285-333 (toAutomaton, replaceSep)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestField.java:104, :114-120; CompletionTokenStream.java:59-60; CompletionAnalyzer.java:149-152 (the document suggester goes through ConcatenateGraphFilter)lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:406, :415-419 (build enumerates the finite strings of each input's automaton)lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingInfixSuggester.java, BlendedInfixSuggester.java, FreeTextSuggester.java; fst/FSTCompletionLookup.java, WFSTCompletionLookup.java (no use of TokenStreamToAutomaton or ConcatenateGraphFilter)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicNormalizer.java:48, :81; ckb/SoraniNormalizer.java:55, :108 (TATWEEL deleted); ar/ArabicAnalyzer.java:132-142 (no LengthFilter)lucene/analysis/common/src/java/org/apache/lucene/analysis/pattern/PatternReplaceFilter.java:31-32lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilterFactory.java:47 (SPI name concatenateGraph)lucene/suggest/build.gradle (suggest depends on core and analysis-common)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java:40-41, :103-105, :316-322lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:30-36lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:95, :295-301lucene/analysis/common/src/test/org/apache/lucene/analysis/ckb/TestSoraniNormalizationFilter.java:85lucene/analysis/common/src/test/org/apache/lucene/analysis/core/TestFlattenGraphFilter.java:702lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestConcatenateGraphFilter.java:163-167 (testEmpty: an empty stream)lucene/CHANGES.txt:17012 (LUCENE-3529), :14115 (LUCENE-4880)
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java:103-105, :313-323; lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:95, :292-302; lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:271-299 (addHoles, HOLE arc :291)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextSuggestField.java:78-101, :137-152 (context-prefix token); lucene/core/src/java/org/apache/lucene/analysis/FilteringTokenFilter.java:49-60; lucene/test-framework/src/java/org/apache/lucene/tests/analysis/BaseTokenStreamTestCase.java:1595-1610
- TestConcatenateGraphFilterEmptyToken.java (JUnit test):
repro/LFV-523/src/org/apache/lucene/analysis/miscellaneous/TestConcatenateGraphFilterEmptyToken.java(39 lines)
A picture of the automaton for the tokens foo, "", bar with the state numbers of an executed run on main, the three code locations, and what the user gets; made in parallel with this doc.
assets/LFV-523/bug.png(492 KB)