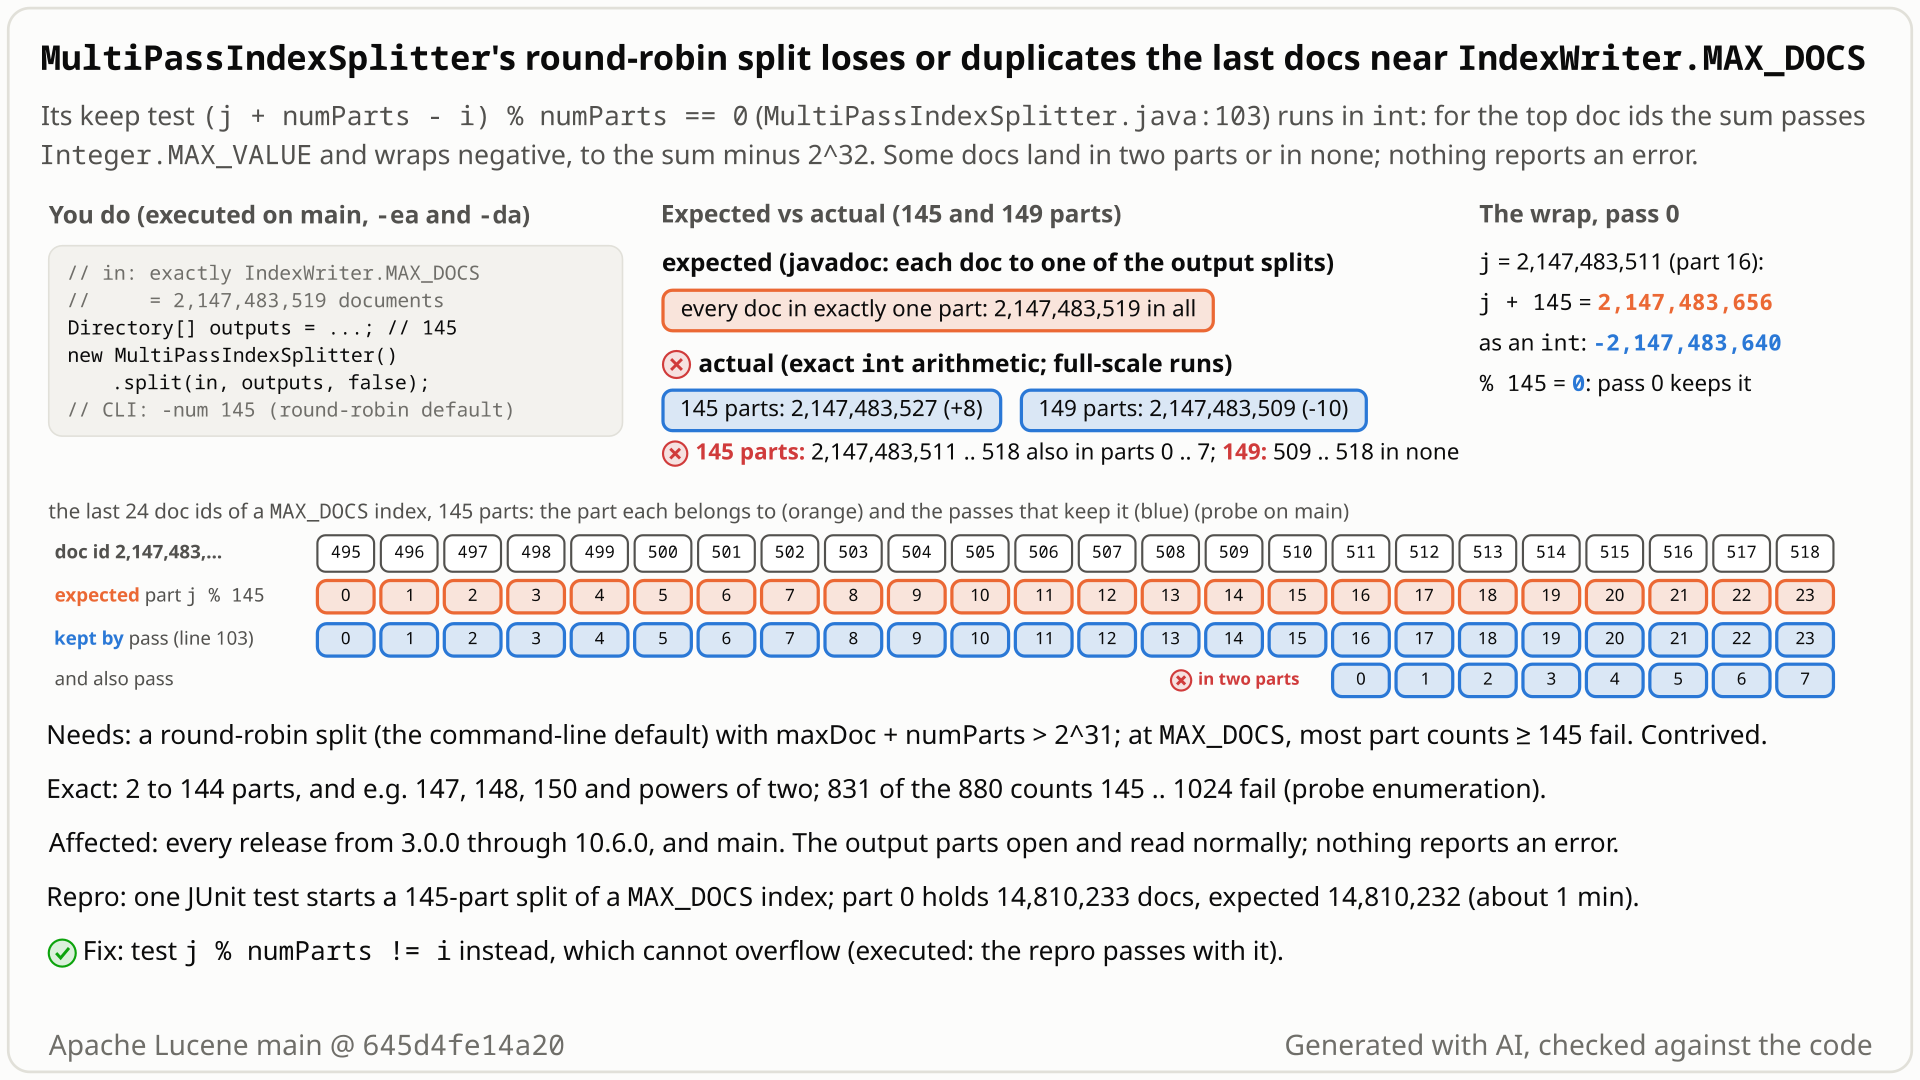
MultiPassIndexSplitter makes one pass over the input per output part. In round-robin mode, pass i keeps document j only when (j + numParts - i) % numParts == 0, computed in int. For the last doc ids of an index near IndexWriter.MAX_DOCS the sum passes Integer.MAX_VALUE, wraps negative, and the test picks the wrong documents.
MultiPassIndexSplitterin lucene/misc copies one index into N new indexes, the parts. It is an offline tool: callsplit(reader, outputs, seq)or run it from the command line with-out <dir> -num <N> [-seq] <input>.- It makes one pass per part: it hides every document that does not belong to part i and copies the rest into part i with
IndexWriter.addIndexes. - Round-robin mode, the command line's default, sends document j to part
j % N: with 3 parts, documents 0, 3, 6 go to part 0, documents 1, 4, 7 to part 1, and so on.-seqsplits into contiguous id ranges instead.
- Build an index of exactly
IndexWriter.MAX_DOCS= 2,147,483,519 documents, the documented hard limit, and split it withMultiPassIndexSplitterinto 145 parts in round-robin mode, the tool's default. - You expect every document in exactly one part: document j goes to part
j % 145, so part 0 gets 14,810,232 documents and the 145 parts add up to 2,147,483,519. - Pass i keeps document j when
(j + 145 - i) % 145 == 0, computed inint. For j = 2,147,483,511 in pass 0, j + 145 = 2,147,483,656 passesInteger.MAX_VALUEand wraps to -2,147,483,640, a multiple of 145: part 0 keeps it. Its real part, 16, keeps it too. - Result: documents 2,147,483,511 to 2,147,483,518 are each in two parts (parts 0 to 7 hold one extra), 2,147,483,527 in total. With 149 parts, documents 2,147,483,509 to 2,147,483,518 are in no part. No exception, no warning.
- It needs
maxDoc + numParts > 2^31(necessary, not sufficient): atMAX_DOCS, 145 is the smallest failing part count and 831 of the 880 counts from 145 to 1024 fail. The fixj % numParts != icannot overflow.
Only users of the opt-in lucene/misc MultiPassIndexSplitter in round-robin mode (its default) whose input's maxDoc, deleted documents included, plus the part count exceeds 2^31: at MAX_DOCS, one of the failing part counts of 145 or more. The parts open and read normally; only their document counts show it.
Mechanism, terms and numbers719 words
MultiPassIndexSplitter (lucene/misc) splits an index into N parts by reading it once per part. In round-robin mode, the command line's default, pass i keeps document j only when (j + numParts - i) % numParts == 0 (MultiPassIndexSplitter.java:103), the intended j % numParts == i. The sum is an int. For an index of IndexWriter.MAX_DOCS = 2,147,483,519 documents and 145 parts, the sum passes Integer.MAX_VALUE for the last doc ids, wraps negative (the int value is the sum minus 2^32), and because 2^32 mod 145 = 16, pass i also keeps the overflowing documents of part i + 16.
The result is silent: with 145 parts, documents 2,147,483,511 to 2,147,483,518 are each copied into two parts (2,147,483,527 documents in total); with 149 parts, 10 documents are in no part; with 1000 parts, 296 (by exact enumeration). The parts open and read normally. The input must have maxDoc + numParts > 2^31 (deleted documents count), so it takes an index at the document limit and a large part count, which is why the priority is low. The line dates from the class's first commit (LUCENE-1959, 2009) and is in every release from 3.0.0 to 10.6.0; j % numParts != i fixes it.
- Inputs.
split()checks onlyoutputs.length >= 2andin.numDocs() >= 2(:71-76);numParts = outputs.length(:77), andmaxDoc = input.maxDoc()(:82) counts deleted documents too. The command line parses-numwith no upper bound (:138), rejects only values below 2 (:163-165), and is round-robin unless-seqis given (:127,:133). - One pass per part. For each part i (
:84),undeleteAll()(:85) resets a private live-docs bit set from the source's own live docs (:244-258). - The keep test (
:100-107), all inint:
   for (int j = 0; j < maxDoc; j++) {
     if ((j + numParts - i) % numParts != 0) {   // :103
       input.deleteDocument(j);
     }
   }
(j + numParts - i) % numParts == 0 is a non-negative way to write j % numParts == i, and it is right only while the sum fits in an int.
- The wrap. When
j + numParts - i >= 2^31, theintvalue is the sum minus 2^32 (negative, so Java's%gives a negative or zero remainder). The remainder is zero, and j kept, exactly whenj - iis congruent to 2^32 modulo numParts. For 145 parts, 2^32 mod 145 = 16, so pass i keeps the overflowing documents of part i + 16. - Copy.
addIndexescopies the documents left live into part i (:108-114). Each part is a normal index that opens and reads normally (CheckIndexwas not run); only which documents it holds is wrong.
MAX_DOCS = Integer.MAX_VALUE - 128= 2,147,483,519 (IndexWriter.java:201-208), so doc ids run from 0 to 2,147,483,518.- 145 parts, j = 2,147,483,511 (j % 145 = 16). Pass 0: j + 145 = 2,147,483,656 wraps to -2,147,483,640 = -145 x 14,810,232, remainder 0, kept. Pass 16: j + 129 = 2,147,483,640 fits, remainder 0, kept. The document is in parts 0 and 16.
- Over all passes: documents 2,147,483,511 to 2,147,483,518 are each in two parts (parts 0 to 7 hold one extra; parts 16 to 23 hold them too), 2,147,483,527 documents in total (+8).
- 149 parts: documents 2,147,483,509 to 2,147,483,518 are in no part (2,147,483,509 in total, -10). 1000 parts: 296 documents in no part (enumeration).
- When it happens. Some pass overflows only if
maxDoc + numParts > 2^31; that is necessary, not sufficient. AtMAX_DOCSthat takes at least 130 parts; 130 to 144 happen to come out right, 145 is the smallest count that fails, and 831 of the 880 counts from 145 to 1024 fail. The other 49 are exact, for example 147, 148, 150, 153 and every power of two (2^32 mod 2^k = 0). The smallest input that fails with 145 parts has 2,147,483,512 documents; with 1000 parts, 2,147,483,001. - Not affected: sequential mode (
-seq,:86-99), whose bounds never exceedmaxDoc; an SMT model proved it exact for 2, 3, 7, 64, 129 and 130 parts.
Exposure and likelihood306 words
- Who can be hit. Users of the lucene/misc
MultiPassIndexSplitter(an opt-in, offline index tool) in round-robin mode, its default, on an input whosemaxDoc(deleted documents included) is within aboutnumParts - 129documents ofMAX_DOCS, with a part count that fails, and only if the affected documents near the top are live: a document already deleted in the source stays deleted in every part. An index that has reached the document limit is exactly one someone may want to split, but usually into far fewer parts. - Silent. The parts open and read normally: the independent reproducer opened every part and read the last documents' doc values. A few documents are missing from the output or appear in two parts, and the only sign is that the parts' document counts do not add up to the input's (
CheckIndexwas not run on the parts). - Scale. The input has two billion documents and the tool reads it once per part: the recorded full splits took about 75 to 111 minutes each (the finder's, of empty documents, 75 to 78 minutes; the independent reproducer's and the adjudication's, of documents empty except for doc values on the last 64, 93 to 111 minutes). The minimal test stops after part 0.
- Older releases reach further. Before
MAX_DOCSthere was no document ceiling belowInteger.MAX_VALUE, so small part counts can fail too. Executed on 3.0.0 only: an input of 2,147,483,645 documents (the largest the 3.0.0 runs could split) gives one document too many with 6 parts and 5 too few with 10 parts; 3.1 to 4.9.0 were not executed. SinceMAX_DOCSarrived (LUCENE-5843, 4.9.1 and 4.10.0), only part counts of 145 or more can fail. - Likelihood: contrived. It needs an index at the document limit and a large, unlucky part count; no public report of it was found.
One JUnit test on Lucene's public API plus the standard test framework: an index of exactly IndexWriter.MAX_DOCS empty documents, split round-robin into 145 parts. Outputs 1 to 144 are one closed directory, so the split stops after writing part 0, and the test checks part 0's document count. Deterministic and single-threaded; it needs a 4 GB test heap.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.misc.index;

import java.util.Arrays;
import org.apache.lucene.codecs.Codec;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.CodecReader;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.AlreadyClosedException;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestMultiPassIndexSplitterRoundRobinOverflow extends LuceneTestCase {

  public void testPart0OfMaxDocsIndex() throws Exception {
    Codec.setDefault(TestUtil.getDefaultCodec());
    Directory blockDir = new ByteBuffersDirectory();
    try (IndexWriter w = new IndexWriter(blockDir, new IndexWriterConfig())) {
      for (int i = 0; i < IndexWriter.MAX_DOCS / 257; i++) {
        w.addDocument(new Document());
      }
      w.forceMerge(1);
    }
    Directory input = new ByteBuffersDirectory();
    try (DirectoryReader block = DirectoryReader.open(blockDir);
        IndexWriter w = new IndexWriter(input, new IndexWriterConfig())) {
      CodecReader[] copies = new CodecReader[257];
      Arrays.fill(copies, (CodecReader) block.leaves().get(0).reader());
      w.addIndexes(copies);
    }

    Directory part0 = new ByteBuffersDirectory();
    Directory stopAfterPart0 = new ByteBuffersDirectory();
    stopAfterPart0.close();
    Directory[] outputs = new Directory[145];
    Arrays.fill(outputs, stopAfterPart0);
    outputs[0] = part0;
    try (DirectoryReader in = DirectoryReader.open(input)) {
      expectThrows(
          AlreadyClosedException.class,
          () -> new MultiPassIndexSplitter().split(in, outputs, false));
    }
    try (DirectoryReader p = DirectoryReader.open(part0)) {
      // MAX_DOCS = 257 * 8,355,967 docs; part 0 must hold exactly the 14,810,232 ids j with j % 145 == 0
      assertEquals("numDocs of round-robin part 0 of 145", 14_810_232, p.numDocs());
    }
  }
}
cd $LUCENE   # an apache/lucene checkout at 645d4fe14a20
cp $REPRO/TestMultiPassIndexSplitterRoundRobinOverflow.java lucene/misc/src/test/org/apache/lucene/misc/index/
./gradlew :lucene:misc:test --tests org.apache.lucene.misc.index.TestMultiPassIndexSplitterRoundRobinOverflow -Ptests.heapsize=4g
# assertions off fails the same way: add -Ptests.asserts=false
- Expected
- Part 0 holds the 14,810,232 documents j with j % 145 == 0, and the test passes.
- Observed
numDocs of round-robin part 0 of 145 expected:<14810232> but was:<14810233>, with assertions on and off: doc 2,147,483,511 of part 16 is in part 0 too.
More files, environment, full output389 words
- Input. Exactly
MAX_DOCS= 2,147,483,519 = 257 x 8,355,967 empty documents: one force-merged segment of 8,355,967addDocumentcalls (no document blocks), added 257 times withaddIndexes(CodecReader...), all inByteBuffersDirectory. - Why only part 0.
outputs[1..144]are one already-closedByteBuffersDirectory.split()writes and closes part 0, then theIndexWriterfor part 1 throwsAlreadyClosedException, which the test expects. Part 0 is complete at that point; this saves 144 more passes over two billion documents. The full 145-part split was run separately (sum 2,147,483,527). - Codec pinned.
split()builds its ownIndexWriterConfig, so the test setsCodec.setDefault(TestUtil.getDefaultCodec())(the test framework restores the default after the class). Two seeds give the same failure. - Cost. A 4 GB heap (a 256 MB live-docs bit set plus merge doc maps). About 1 minute with a plain JUnit runner and about 3 minutes under gradle, whose test JVM runs with C1 only.
- Formatting.
./gradlew tidy(google-java-format) only wraps the long comment above the assertion. - What it asserts. Only part 0's count: 14,810,232 = the number of ids j with j % 145 == 0 (0, 145, ..., 2,147,483,495). It gets one more, because doc 2,147,483,511 of part 16 is copied there too.
split()only clears live-doc bits, so the extra document can only be one that belongs to another part. - As the regression test: the same test. It fails on stock and passes with the fix. Its scale matches the
@Monstertests, likeTestIndexWriterMaxDocs(which run only with-Ptests.monster=true), and it needs-Ptests.heapsize=4g.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the same failure on the 10.6.0 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
# gradle, main 645d4fe14a20, seed DEADBEEF (the same with -Ptests.asserts=false)
TestMultiPassIndexSplitterRoundRobinOverflow > testPart0OfMaxDocsIndex FAILED
    java.lang.AssertionError: numDocs of round-robin part 0 of 145 expected:<14810232> but was:<14810233>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:FD70867819D80048]:0)
        at junit@4.13.2/org.junit.Assert.fail(Assert.java:89)
        at junit@4.13.2/org.junit.Assert.failNotEquals(Assert.java:835)
        at junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:647)
        at org.apache.lucene.misc.index.TestMultiPassIndexSplitterRoundRobinOverflow.testPart0OfMaxDocsIndex(TestMultiPassIndexSplitterRoundRobinOverflow.java:64)
  2> Writing part 1 ...

# the full 145-part split (the independent reproducer's own test, main ea57360912ed, -da, re-run by the adjudication)
java.lang.AssertionError: round-robin split is not a partition of the input: 8 bad parts,
  sum of parts' numDocs=2147483527 vs input numDocs=2147483519;
  first problems: [part 0: numDocs=14810233 expected=14810232;
  last-64 docs held=[2147483495, 2147483511] expected=[2147483495], part 1: ...

# full splits on the main jars (-da): sums of the parts' numDocs
144 parts: 2,147,483,519 (exact) 145 parts: 2,147,483,527 (+8) 149 parts: 2,147,483,509 (-10)- The javadoc says round-robin assigns each source id "to one of the output splits".
- Upstream
testSplitRRspot-checks thej % numPartsmapping, and a lost-seqdocument was fixed as a bug before the class was committed. - The input is legal:
MAX_DOCSis the documented hard limit, upstream tests build such indexes, and nothing bounds the part count.
The full argument270 words
- The contract.
split()javadoc: "If false, source document id-s will be assigned in a deterministic round-robin fashion to one of the output splits." (MultiPassIndexSplitter.java:65-67). Class javadoc: "This tool splits input index into multiple equal parts." (:43). The 3.0.0 CHANGES entry: "MultiPassIndexSplitter can split any index into any number of output parts, at the cost of doing multiple passes over the input index." - The test.
TestMultiPassIndexSplitter.testSplitRRsplits an 11-document index (the last one deleted) into 3 parts and asserts, for each part k, that its first document is document k, that it holds at most 4 documents, and that it lacks an id of another part (part 0 lacks 1, part 1 lacks 0, part 2 lacks 0 and 1): spot checks of thej % numParts == imapping. - History. The expression came with the class (LUCENE-1959, 2009) and was never changed. In that review, a reviewer reported "If we have 13 docs ... and numParts=3, 12th doc is missing with -seq mode", and the
i < numParts - 1guard (:95) was added before the commit: a lost document was treated as a bug. Overflow and size limits were never discussed. - Legal input.
MAX_DOCSis the "Hard limit on the maximum number of documents that may be added to the index" (IndexWriter.java:201-208);TestIndexWriterMaxDocs.testExactlyAtTrueLimit(@Monster) builds such an index. Neithersplit()nor-numbounds the part count. - Precedent. CHANGES records fixes of
intoverflows at extreme but legal scale, for example LUCENE-10678 (a BKD tree with more than 4 billion points), LUCENE-8221 (MoreLikeThis.setMaxDocFreqPct) and LUCENE-6409 (LongBitSet.ensureCapacity).
The devil's-advocate check118 words
The strongest case for "not worth calling a bug" (the intended-behaviour devil's advocate, a cross-model review and the adjudication): the scale is unrealistic, the tool is an expensive misc utility that reads the input once per part, and the class javadoc's NOTE already says it "can easily break up" document blocks added with addDocuments.
Why it fails: scale argues for a low priority, not for intent; the NOTE is about blocks being spread over different parts, which round-robin does by design, not about documents being lost or duplicated, and the repro adds documents one at a time with addDocument; nothing documents a size or part-count limit; and the fix costs nothing. Verdict: not intended, low impact.
Recommended Test j % numParts != i
Test j % numParts != i instead of (j + numParts - i) % numParts != 0. For every legal i and j it is the same test, it cannot overflow, and it costs the same. With this one-line change the repro passes with assertions on and off, and the misc module's tests and static checks pass.
         for (int j = 0; j < maxDoc; j++) {
-          if ((j + numParts - i) % numParts != 0) {
+          if (j % numParts != i) { // j + numParts - i overflows int for j near IndexWriter.MAX_DOCS
             input.deleteDocument(j);
           }
         }
All options and trade-offs4 options · 429 words
One fix was run through gradle in a scratch worktree of 645d4fe14a20 (OpenJDK 25.0.3, seed DEADBEEF); it is the hunt's candidate fix, unchanged. The other options are described, not run.
In the round-robin loop of split() (MultiPassIndexSplitter.java:103). The comment is optional.
         for (int j = 0; j < maxDoc; j++) {
-          if ((j + numParts - i) % numParts != 0) {
+          if (j % numParts != i) { // j + numParts - i overflows int for j near IndexWriter.MAX_DOCS
             input.deleteDocument(j);
           }
         }
Trade-offs
- For
0 <= jand0 <= i < numPartsboth tests keep the same documents, andj % numPartsstays in[0, numParts), so nothing can overflow. - Same cost: one remainder per document per pass. No behaviour change below the overflow window.
What the checks validated
- Stock: the repro fails with assertions on and off.
- Fix: the repro passes with assertions on and off.
- Closest suite
TestMultiPassIndexSplitter(testSplitRR,testSplitSeq): 2 tests, 0 failures. - The whole misc test suite with the repro in place: 24 classes, 317 tests, 0 failures, 9 skipped (seed DEADBEEF).
:lucene:misc:check -x testpasses with the fix and the repro tidied by./gradlew :lucene:misc:tidy, which only wraps the repro's long comment line; the fix needed no reformatting. Untidied, the check fails on that comment line alone.- Earlier: the independent reproducer's full 145-part split with the fix shadowed is exact, the minimal test passes with the fix shadowed (assertions on and off), and every enumeration finds the fixed test exact for all part counts from 2 to 1024.
if ((j + (long) numParts - i) % numParts != 0).
Trade-offs
Also correct and overflow-free, and keeps the original shape, but it is less obvious than j % numParts != i and hides why the cast is needed.
Throw when maxDoc + numParts > 2^31.
Trade-offs
Refuses valid splits that the one-line fix handles.
Start from an empty bit set and set j = i, i + numParts, ... instead of clearing every other document.
Trade-offs
Faster, but j += numParts can itself overflow near MAX_DOCS unless j is a long, and it must set a bit only where the source document is live, to keep the source's own deletions; a bigger change for a tool whose run time is dominated by addIndexes.
No call of the tool was found in the major downstream search servers; anyone who splits a near-full index with it can check that the parts' document counts add up to the input's.
Semi-formal: an AI tool modelled both split modes in exact Java int arithmetic with the Z3 SMT solver, which proved small part counts correct but timed out at 129 and 130 parts. It then enumerated the expression over the overflow window and found 145 as the first failing part count; a full-size split of the stock code confirmed it.
The method in full239 words
Method: semi-formal (the first counterexample came from an exact enumeration of the transcribed expression, not from the solver). Hunt unit on the misc reorder and split tools, 2026-10-26, main ea57360912ed.
- Model. A Z3 4.12 bit-vector model of both split modes in exact Java
intsemantics, with a vacuity mutant (the-seqmode without its last-part rule, which the solver must and did catch). It proved "no document lost" and "no document duplicated" for sequential mode at 2, 3, 7, 64, 129 and 130 parts and for round-robin at 2, 3, 7 and 64 parts, and returned unknown for round-robin at 129 and 130 parts (120 s timeouts). - Enumeration. Over the window where
j + numParts - ican overflow, the AI tool evaluated the transcribed test exactly in Javaintarithmetic for every part count from 2 to 1024 atmaxDoc = MAX_DOCS: 145 is the first failing count, and 831 counts fail. Later checks repeated it independently, in Java and in closed form, with the same result. - Full scale. A full split of a
MAX_DOCS-document index on the stock main jars (on a separate arm64 host): 145 parts +8, 149 parts -10, 144 parts exact. - Then: an independent reproducer wrote its own JUnit from the claim alone and failed it on main (
-eaand-da), 10.5.2 and 9.12.3; an adjudication re-ran it with a new seed; a fourth audit re-ran a full-scale split.
No prior report: 78 search-tool queries over GitHub issues, PRs and commits, the JIRA archive, seven Lucene mailing lists, downstream projects and the web on 2026-10-26, re-checked on GitHub on 2026-10-31. Not fixed upstream.
Searches4 searches
Closest items, context only: LUCENE-1959 / #3034 (added the class; its only correctness fix was the -seq lost-document bug, 2009); LUCENE-3626 / #4700 (per-segment rework; the round-robin test was untouched); LUCENE-5982 (the splitters should take the write lock, open); open PRs #14996 and #13951 (touch the file, not the test); a 2010 java-user thread "Question to the writer of MultiPassIndexSplitter" (about speed). Limits: keyword search; list search starts in 2010-03, so 2009 traffic is covered through the LUCENE-1959 thread, read in full; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | search-tool queries on the class, the expression, round-robin, overflow and MAX_DOCS terms; changed-file scans of all 408 open PRs and of PRs #1 to #16908 | no report; the closest items are listed above |
| JIRA archive and mailing lists (dev@, java-user@, issues@, commits@, solr-user@, general@, java-dev@) | 2026-10-26 | search-tool queries; the LUCENE-1959 thread read in full | no report; the 2010 java-user thread is about speed |
| Downstream projects and web | 2026-10-26 | issue and code search in the major downstream search servers; web queries | no report; no call of the tool found |
| GitHub re-check | 2026-10-31 | MultiPassIndexSplitter (14 issues, latest update 2022), "IndexSplitter overflow", "round-robin split numParts", "splitter MAX_DOCS", issues created since 2026-10-25, open PRs naming the class | nothing new; line 103 unchanged on upstream main 2f424fd428da, branch_11x and branch_10_6 |
Introduced with the class itself by LUCENE-1959 (commit 7d0d4ecc44c, 2009-10-13) and first released in 3.0.0; every release since, up to 10.6.0 and main, has the same line. Before 4.9.1 and 4.10.0 there was no document ceiling below Integer.MAX_VALUE, so even 6 or 10 parts can fail (run on 3.0.0).
Versions tested6 rows
- Introduced by
7d0d4ecc44c6acb60ac3cc0dbf9dc2c18d7497de"LUCENE-1959 Add MultiPassIndexSplitter." (svn r824798, 2009-10-13; JIRA LUCENE-1959 "Index Splitter", mirrored as #3034; pre-GitHub, no PR).git blame -w -M -Cattributes lines 100-107 to it, and with git's default rename detectiongit log -Son the expression returns only it (with--no-renamesit also lists the three commits that moved the file, none of which changes the line). - Never changed. The line is byte-identical at all 133 release tags from 3.0.0 to 10.5.2 and at the 10.6.0 tag; the same
intbytecode (iadd,isub,irem) is insplit()of 16 sampled release jars from 3.0.0 to 10.5.2. Releases between 3.0.0 and 9.12.3 were checked by source and bytecode, not executed. - Reach by era. Before 4.9.1 there was no document ceiling below
Integer.MAX_VALUE, so small part counts can fail too (executed on 3.0.0 only; 3.1 to 4.9.0 not run); from 4.9.1 and 4.10.0 on,MAX_DOCS = 2^31 - 129(LUCENE-5843) leaves only part counts of 145 or more.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails, assertions on and off (gradle and the standalone runner) |
| 10.6.0 | affected | the minimal test fails (assertions off) |
main ea57360912ed, 10.5.2, 9.12.3 | affected | the full 145-part split: +8, parts 0 to 7 each hold one extra document (main with -ea and -da) |
| 3.0.0 | first affected | +8 at 2,147,483,519 documents and 145 parts; at 2,147,483,645 documents, +1 with 6 parts and -5 with 10 parts (a 3.x port of the same oracle) |
| 2.9.0, 2.9.4 | before the class | the class does not exist |
fix (j % numParts != i) | not affected | the minimal test passes; the full 145-part split is exact |
Confirmed with high confidence by the adjudication after an independent reproducer, an intended-behaviour devil's advocate and read-only reviews by another model family (OpenAI GPT-5.6); a fourth audit's own full-scale run and this doc's gradle runs agree.
Checks and verdicts296 words
Every executed check ran on main ea57360912ed or 645d4fe14a20 (identical splitter and IndexWriter code) or on release jars. The cross-model reviews could only read code.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Z3 model and exact enumeration (first failing 145); full splits on the stock main jars: 145 parts +8, 149 parts -10, 144 parts exact. |
| intended-lens review (OpenAI GPT-5.6, read-only) | real, medium | Worked the 2,147,483,511 example by hand; fix judged correct; the intended argument weak. |
| Independent reproducer | real, high | Own full-scale JUnit written from the claim: fails on main (-ea and -da), 10.5.2 and 9.12.3 with parts 0 to 7 holding one extra document each; controls pass (4,194,304 documents, 144 parts, the fix). |
| Refute review (OpenAI GPT-5.6, read-only) | not real, low (procedural) | Could not run Java, so its verdict is procedural; it agreed on root cause, contract, legal inputs and fix. A separate run of the Java enumeration matches. |
| Intended-behaviour devil's advocate | real | Ran the exact expression in Java and a closed-form derivation; read the LUCENE-1959 thread, tests and CHANGES; found no by-design statement. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test with a new seed at full scale (5,577 s): the same 8 bad parts and sum 2,147,483,527. |
| credibility audit | keep | Own full-scale split stopped after part 8: parts 0 to 7 hold one extra document each, part 8 exact. |
| repro minimisation | one test | The one-test repro: fails on 645d4fe14a20 with -ea and -da, passes with the fix shadowed. |
| this doc (2026-10-31) | real, fix validated | The minimal test through gradle on 645d4fe14a20 (fails, assertions on and off) and on the 10.6.0 jars (fails); the fix through gradle: repro, closest suite, the misc test suite and :lucene:misc:check (see Suggested fix). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 522 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,270 words
- Registry title
- MultiPassIndexSplitter's round-robin split loses or duplicates the last few documents of an index at about IndexWriter.MAX_DOCS for most part counts of 145 or more, because its int test (j + numParts - i) % numParts overflows
- Area
- misc / index tools (MultiPassIndexSplitter.split, round-robin mode)
- Priority
- Low, rank 979: MultiPassIndexSplitter round-robin splits lose or duplicate the last documents only near IndexWriter.MAX_DOCS with 145 or more parts, extreme-scale and contrived.
- Impact class
- data corruption
- Impact note
- Only operators who run the lucene/misc MultiPassIndexSplitter tool in its default round-robin mode (command line, or split(in, outputs, false)) on an input whose maxDoc, deleted documents included, is within about numParts - 129 documents of IndexWriter.MAX_DOCS (at least 2,147,483,512 for 145 parts), with a part count that fails (smallest 145; 831 of the 880 values 145..1024; powers of two and e.g. 147, 148, 150 are exact), are hit: the output parts are valid indexes, but a few of the highest doc ids are copied into two parts or into none, with no error (145 parts: 8 duplicated; 149 parts: 10 lost; 1000 parts: 296 lost by enumeration), in every release since 3.0.0, with -ea and -da.
- Summary
- You split an index of IndexWriter.MAX_DOCS (2,147,483,519) documents with MultiPassIndexSplitter in round-robin mode, the command-line default, into 145 parts, and expect every document in exactly one part (part i gets the documents whose id j has j % numParts == i), as the split javadoc says: ids are 'assigned in a deterministic round-robin fashion to one of the output splits'. Instead the parts hold 2,147,483,527 documents in total: documents 2,147,483,511..518 belong to parts 16..23 but are also copied into parts 0..7, and with 149 parts documents 2,147,483,509..518 end up in no part at all; nothing reports an error. The cause is the keep test (j + numParts - i) % numParts == 0 at MultiPassIndexSplitter.java:103, computed in int: for the top doc ids j + numParts - i wraps negative and Java's % keeps the sign, while the equivalent j % numParts == i cannot overflow.
- Introduced
- 7d0d4ecc44c6acb60ac3cc0dbf9dc2c18d7497de (svn r824798, 'LUCENE-1959 Add MultiPassIndexSplitter.'; JIRA LUCENE-1959 'Index Splitter', mirrored as apache/lucene#3034; pre-GitHub, no PR) [read: git blame -w -M -C on main attributes MultiPassIndexSplitter.java:100-107 to it, and git log -S on the expression over the file's four historical paths returns only it; the faulty line is part of the class's first version and no later commit changed it] (2009-10-13)
- First affected version
- 3.0.0 (2009-11-25, the first release with the class) [exec: a 3.x port of the repro at 2,147,483,519 docs and 145 parts gives the same +8 as main; at 2,147,483,645 docs, 6 parts give +1 and 10 parts -5, 5 parts are exact]; not affected: 2.9.x and earlier, where the class does not exist [exec: class lookup on the 2.9.0 and 2.9.4 jars; 2.9.1 and 2.9.2 by source]
- Affected versions
- every release from 3.0.0 to 10.6.0, plus main ea57360912ed and 645d4fe14a20; never fixed (line 103 unchanged on upstream main f4cc6ac2097c, branch_10x and branch_10_6 on 2026-10-26). [exec] main (-ea and -da), 10.5.2 (-da) and 9.12.3 (-da) with the verifier's JUnit at MAX_DOCS and 145 parts: +8 each, identical parts and ids; 3.0.0 (-da) with a 3.x port: +8 at 2,147,483,519 docs and 145 parts, +1 (-ea and -da) and -5 at 2,147,483,645 docs with 6 and 10 parts; the minimal test (part 0 of 145 holds 14,810,233 documents, expected 14,810,232) fails on the 10.6.0 release jars (SHA-1 checked, -da) and through gradle on main 645d4fe14a20 (-ea and -da) [exec 2026-10-31]. [read] the source line is byte-identical at all 133 release tags 3.0.0..10.5.2 of the release-tag clone, and the same int bytecode (iadd, isub, irem) is in split() of the released misc jars of 3.0.0, 3.0.3, 3.6.2, 4.0.0, 4.9.0, 4.10.0, 5.5.5, 6.6.6, 7.7.3, 8.0.0, 8.8.2, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2; releases between 3.0.0 and 9.12.3 were not executed. Reach by era: 3.0.0-4.9.0 accept inputs up to Integer.MAX_VALUE docs, so small part counts fail too near 2^31 (the largest input 3.0.0 could split on this JVM was 2,147,483,645 docs); from 4.9.1/4.10.0 on, IndexWriter.MAX_DOCS = 2^31 - 129 (LUCENE-5843) leaves only part counts of 145 or more
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (2026-10-26, read-only; verdict new): scripted prior-report searches with 78 queries (GitHub issues, PRs and commits on apache/lucene; Elasticsearch, OpenSearch and Solr; the dev@, java-user@, issues@, commits@, solr-user@, general@ and java-dev@ lists; the JIRA archive; the web) and 33 hits read and classified, plus changed-file scans of all 408 open PRs and of PRs #1-#16908. Related, not this bug: LUCENE-1959 / #3034 (added the class; its only correctness fix was a -seq mode lost-last-document bug in 2009), LUCENE-3626 / #4700 (per-segment rework, round-robin test untouched), open PRs #14996 and #13951 (touch the file, not the test), and the 2010 java-user thread 'Question to the writer of MultiPassIndexSplitter' (about speed). Not fixed upstream (line 103 unchanged on main f4cc6ac2097c, branch_10x and branch_10_6).
- Lucene commit tested
- main
645d4fe14a20(the minimal test through gradle with assertions on and off, and with a standalone JUnit runner); the 10.6.0 release jars (the minimal test, assertions off); mainea57360912ed, 10.5.2 and 9.12.3 with the independent reproducer's full 145-part split; 3.0.0 with a 3.x port of the same oracle; the recommended fix through gradle in a scratch worktree of645d4fe14a20. All runs on Linux aarch64 with OpenJDK 25.0.3. Line 103 is unchanged on upstream main2f424fd428da(2026-10-30),branch_11x,branch_10_6and the 10.6.0 tag.
- Finding record
lucene/misc/src/java/org/apache/lucene/misc/index/MultiPassIndexSplitter.java:42-56 (at ea57360912ed) (class javadoc: 'splits input index into multiple equal parts'; Note 2, one read of the input per part; NOTE, document blocks can be broken up), :60-69 (split javadoc; :65-67 'source document id-s will be assigned in a deterministic round-robin fashion to one of the output splits'), :71-73 (only outputs.length >= 2 is checked), :82 (maxDoc = input.maxDoc()), :101-107 (round-robin loop; :103 'if ((j + numParts - i) % numParts != 0)' in int), :127 (command line: 'default is round-robin'), :138 (-num parsed with no upper bound)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:201-208 (at ea57360912ed) (MAX_DOCS = Integer.MAX_VALUE - 128, the hard limit) and lucene/core/src/java/org/apache/lucene/index/BaseCompositeReader.java:82-106 (composite maxDoc bounded by MAX_DOCS); upstream @Monster TestIndexWriterMaxDocs builds indexes of exactly MAX_DOCS docs (cited by the cross-model review and the intended-behaviour check)lucene/misc/src/test/org/apache/lucene/misc/index/TestMultiPassIndexSplitter.java (at ea57360912ed) testSplitRR (11 docs, 3 parts: asserts the j % numParts mapping)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/misc/src/java/org/apache/lucene/misc/index/MultiPassIndexSplitter.java:42-56, 60-69, 70-117 (split; :103 the keep test), 119-165 (command line: :127 usage, :133 seq = false, :138 -num, :163-165), 244-262 (FakeDeleteLeafIndexReader.undeleteAll, deleteDocument)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:201-208 (MAX_DOCS)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/misc/src/java/org/apache/lucene/misc/index/MultiPassIndexSplitter.java:42-56 (class javadoc and NOTE), :60-69 (split javadoc), :95 (the -seq guard)a Lucene main checkout (645d4fe14a20) lucene/misc/src/test/org/apache/lucene/misc/index/TestMultiPassIndexSplitter.java:68-104 (testSplitRR)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:201-208; lucene/core/src/test/org/apache/lucene/index/TestIndexWriterMaxDocs.java:46-48 (@Monster testExactlyAtTrueLimit)a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:4034 (LUCENE-10678), :7456 (LUCENE-8221), :10842 (LUCENE-6409)
- Prior reports
a Lucene clone: git show origin/main, origin/branch_11x, origin/branch_10_6, releases/lucene/10.6.0 : lucene/misc/src/java/org/apache/lucene/misc/index/MultiPassIndexSplitter.java line 103
- TestMultiPassIndexSplitterRoundRobinOverflow.java (one test):
repro/LFV-531/TestMultiPassIndexSplitterRoundRobinOverflow.java(67 lines)
assets/LFV-531/bug.png(522 KB)