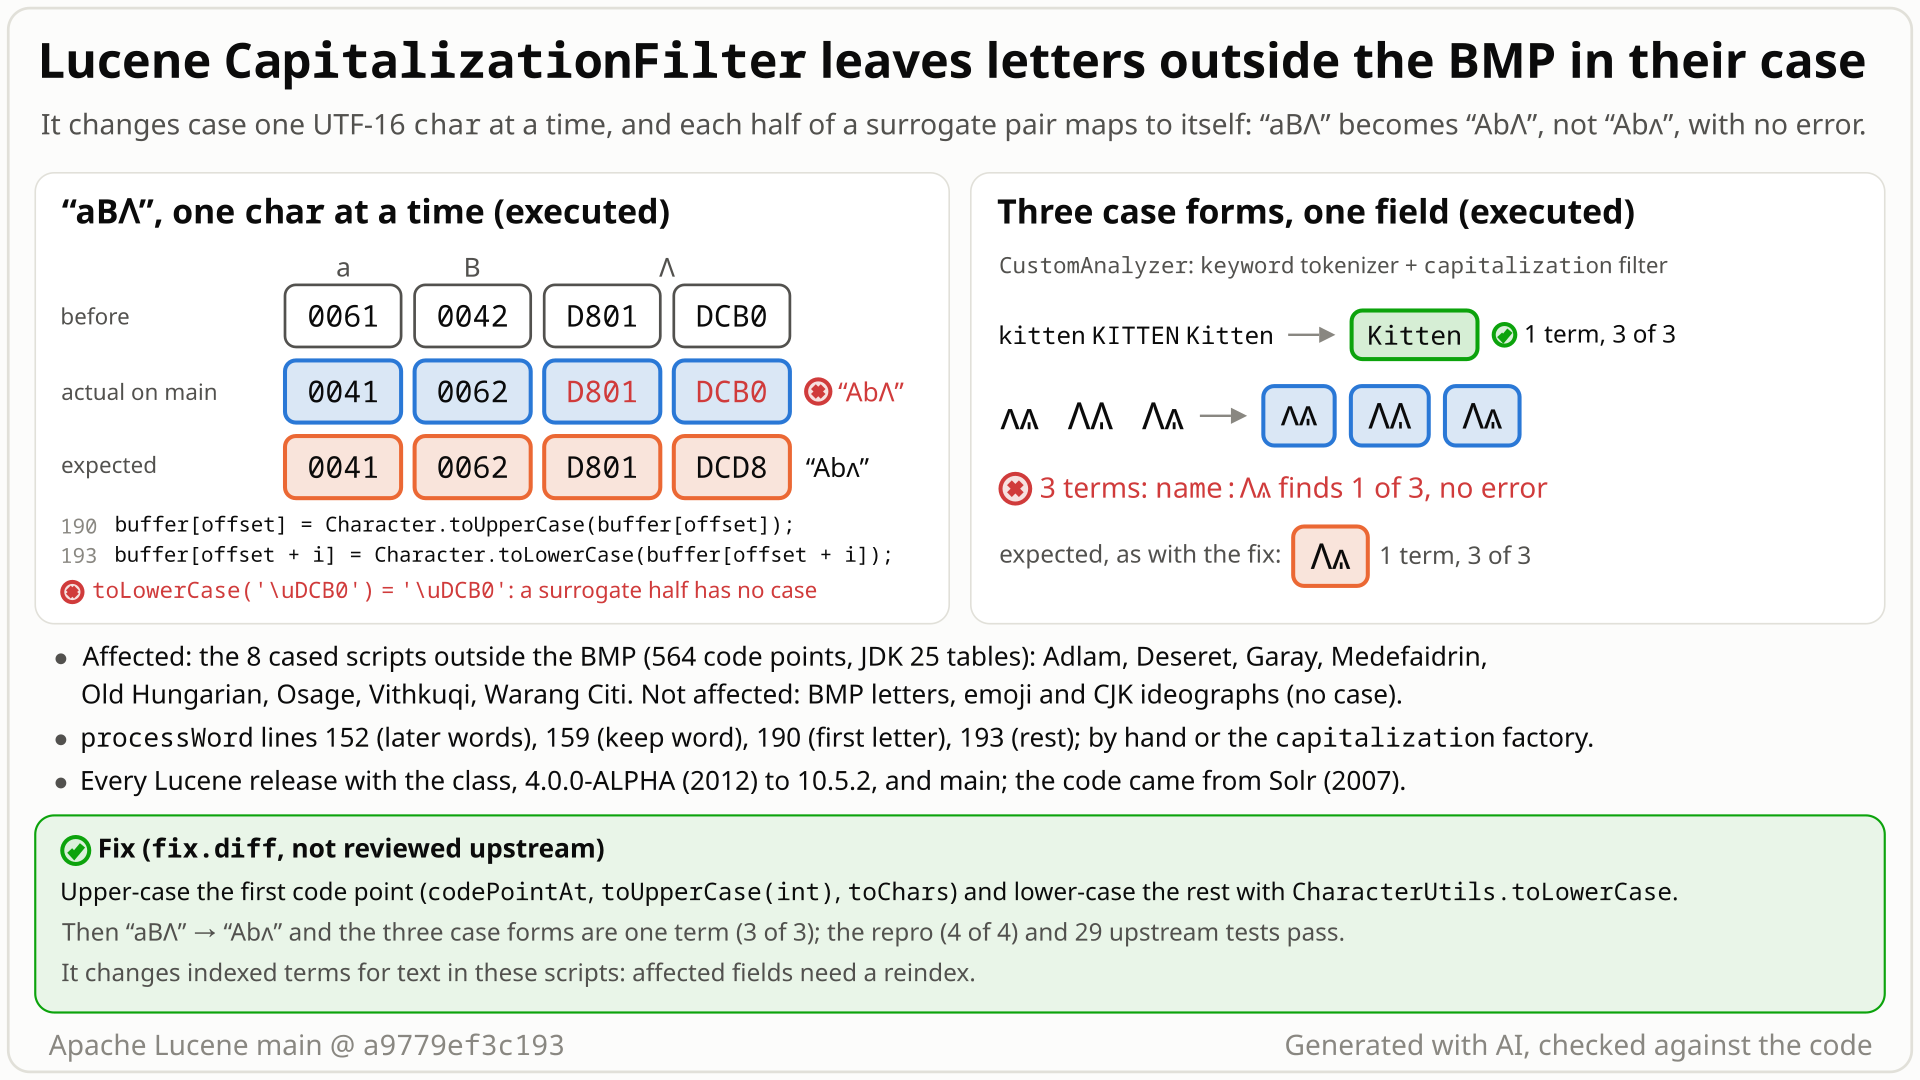
processWord changes case with Character.toUpperCase(char) and toLowerCase(char), one 16-bit char at a time (CapitalizationFilter.java:152, :159, :190, :193). A letter outside the BMP is two chars; each half alone has no case and comes back unchanged. LowerCaseFilter and UpperCaseFilter map whole code points.
- Java stores text as 16-bit
charvalues. Most letters of everyday text, Latin, Greek and Cyrillic included, fit in one char: they are in the Basic Multilingual Plane (BMP). - Letters above U+FFFF, such as those of Adlam, Osage and Deseret, take two chars, a surrogate pair: the Adlam small alif U+1E922 is U+D83A U+DD22.
- A surrogate alone is not a letter.
Character.toUpperCase(char)returns U+D83A unchanged;Character.toUpperCase(int)on the whole code point U+1E922 returns the capital U+1E900.
- You analyse a field with
KeywordTokenizer+CapitalizationFilter(default settings), documented to "make the first letter capital and the rest lower case", and index four values:PARIS,paris, and the Adlam letters alif + daali in capitals (U+1E900 U+1E901) and in small letters (U+1E922 U+1E923). - You expect 2 terms,
Parisand U+1E900 U+1E923 (capital alif, small daali), and a query for either Adlam spelling to find both Adlam documents. - You get 3 terms:
Paris, U+1E900 U+1E901 and U+1E922 U+1E923. The queryparisfinds 2 documents; the query U+1E922 U+1E923 finds 1. - Why: each Adlam letter is two Java chars, a surrogate pair. The filter passes each char alone to
Character.toUpperCaseortoLowerCase; half of a pair has no case and comes back unchanged. BMP letters in the same token are mapped:aB+ Osage U+104B0 givesAb+ U+104B0, notAb+ U+104D8. - No exception in any run, and the terms stay valid UTF-16. Every path of the filter does it: the first letter, the rest of the word, later words (
onlyFirstWord, on by default) and keep words withforceFirstLetter.
Any chain with CapitalizationFilter or the capitalization factory (schemas, CustomAnalyzer). It needs text in one of eight cased scripts outside the BMP, such as Adlam (a living script for Fulani) or Osage; there it happens every time: case variants stay separate terms and facet values (with a case-sensitive keep list, some merge into a kept word instead).
Mechanism, terms and numbers624 words
The javadoc of CapitalizationFilter says "It will make the first letter capital and the rest lower case" (CapitalizationFilter.java:26-28). Its processWord changes case with Character.toUpperCase(char) and Character.toLowerCase(char), one UTF-16 char at a time (:152, :159, :190, :193). Letters outside the Basic Multilingual Plane (BMP) are stored as two chars, a surrogate pair, and each half alone has no case, so the 564 cased code points of Adlam, Deseret, Garay, Medefaidrin, Old Hungarian, Osage, Vithkuqi and Warang Citi are never capitalized and never lower-cased, while BMP letters in the same token are. In a field analysed with KeywordTokenizer + CapitalizationFilter, PARIS and paris become one term, Paris, but the Adlam letters alif + daali in capitals and in small letters stay two terms, neither capitalized, and a query for one spelling finds 1 of the 2 documents. No run threw, and the output is valid UTF-16 of the same length. The char-wise lines come from the Solr original (2007-2008), were moved into Lucene unchanged in 2010 and are in every release since 4.0.0-ALPHA; mapping code points, as LowerCaseFilter and UpperCaseFilter do, fixes it.
- UTF-16 char: Java stores text as 16-bit
charvalues. Most letters fit in one char: they are in the Basic Multilingual Plane (BMP). - Supplementary character: a code point above U+FFFF, stored as two chars, a surrogate pair. The Adlam small alif U+1E922 is U+D83A U+DD22. A surrogate alone is not a letter and has no case.
- Code-point case mapping:
Character.toUpperCase(int)andtoLowerCase(int)map a whole code point (U+1E922 to U+1E900). Thecharoverloads cannot: the JDK documents that they "cannot handle supplementary characters".
incrementTokensplits the term into words at chars<= ' 'and.and callsprocessWordon each word, editing the term buffer in place (CapitalizationFilter.java:102-143).processWord(:145-196) maps case with thecharoverloads at four places::152, every char of a later word whenonlyFirstWordis true (the default);:159, the first char of a keep word withforceFirstLetter;:190,buffer[offset] = Character.toUpperCase(buffer[offset]);, the first letter;:193, every other char of the word, lower-cased.- For a surrogate both overloads return the char unchanged (all 2,048 surrogate units checked), so a supplementary letter keeps its case. BMP letters in the same word are mapped.
- The code-point helpers exist next door:
CharacterUtils.toLowerCaseandtoUpperCase(CharacterUtils.java:54-70,:105-113), used byLowerCaseFilter(:38) andUpperCaseFilter(:48). This filter's own case-insensitive keep set compares per code point too (CharArrayMap.java:231-290).
input (one token, KeywordTokenizer) | expected | stock filter | path |
|---|---|---|---|
| U+1E922 U+1E923 (Adlam, small) | U+1E900 U+1E923 | U+1E922 U+1E923 | first letter: high half :190, low half :193 |
| U+1E900 U+1E901 (Adlam, capitals) | U+1E900 U+1E923 | U+1E900 U+1E901 | rest of the word, :193 |
aB U+104B0 (Osage capital A) | Ab U+104D8 | Ab U+104B0 | rest of the word, :193 |
hEy space U+10400 U+10401 (Deseret capitals) | Hey space U+10428 U+10429 | Hey space U+10400 U+10401 | later word, :152 |
keep word U+10428 x, forceFirstLetter | U+10400 x | U+10428 x | keep word, :159 |
kiTTEN, hEy yOU (controls) | Kitten, Hey you | Kitten, Hey you | BMP |
In an index (KeywordTokenizer + CapitalizationFilter, four documents PARIS, paris, U+1E900 U+1E901, U+1E922 U+1E923): expected terms [Paris, U+1E900 U+1E923], actual [Paris, U+1E900 U+1E901, U+1E922 U+1E923]; the query paris finds 2 documents, the query U+1E922 U+1E923 finds 1 instead of 2.
The supplementary code points with a case mapping (JDK 25 tables): 564 in eight scripts, Adlam 68, Deseret 80, Garay 44, Medefaidrin 64, Old Hungarian 102, Osage 72, Vithkuqi 70, Warang Citi 64. Emoji and CJK ideographs have no case and are not affected.
Exposure and likelihood356 words
- Who is exposed. Chains built with the constructors, the
capitalizationfactory in aCustomAnalyzer(reached with the stockstandard,whitespaceandkeywordtokenizers: 9 of 9 cases unmapped, whilelowercasein the same pipeline lower-cases the capitals) or a schema field type like the factory's javadoc example. Every path that changes case is affected (the default settings,onlyFirstWord=falseand a keep word withforceFirstLetterwere run). The filter is opt-in and in no stock analyzer. - What it takes. Text in Adlam (a living script for Fulani), Osage, or historic or rarely used Deseret, Old Hungarian, Warang Citi, Medefaidrin, Vithkuqi or Garay.
- What changes for the user. Usually, case variants of such words stay separate terms (3 instead of 2 in the repro), separate facet values, and a query in one case misses the other (1 hit instead of 2). The capitalized display form the filter exists for is never produced for them. In one configuration the opposite also happens: with a case-sensitive keep list and
forceFirstLetter, the stock filter turns[a, U+10400]into the kept word[A, U+10400]instead of[A, U+10428], merging case variants that the fixed filter keeps apart (35 stock terms in that configuration of the security probe, none in the other four). - What does not happen. In a bounded probe over 7,380 tokens and 5 configurations, assertions on and off: no exception, no change in term length, valid UTF-16; the filter keeps no state across tokens or documents.
- Scale. Deterministic, with assertions on or off. The result depends only on the token text and the settings, so index size should not matter; only small indexes were run.
- JDK dependence. Deseret (Unicode 3.1) shows it on every JDK Lucene supported; Adlam and Osage need Unicode 9.0 tables, which first came with JDK 11 (JDK 9 and 10 have Unicode 8.0; JDK 11 has Unicode 10.0, JEP 327). Only JDK 25 was run for the repro; a JDK 11 sanity run maps Adlam and Osage too.
- How likely. Rare: the documented searches found no public report since Solr 1.3.0 (2008), and it needs those scripts in a field with this filter.
The test shows that CapitalizationFilter does not capitalize a first letter outside the BMP: the Adlam word U+1E922 U+1E923 goes through KeywordTokenizer + CapitalizationFilter unchanged.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import java.io.StringReader;
import java.util.List;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.KeywordTokenizer;
import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestCapitalizationFilterSupplementary extends LuceneTestCase {

  public void testCapitalizesFirstLetterOutsideBmp() throws Exception {
    Tokenizer tokenizer = new KeywordTokenizer();
    tokenizer.setReader(new StringReader(new String(new int[] {0x1E922, 0x1E923}, 0, 2)));
    try (TokenStream ts = new CapitalizationFilter(tokenizer)) {
      CharTermAttribute term = ts.addAttribute(CharTermAttribute.class);
      ts.reset();
      ts.incrementToken();
      // expected U+1E900 U+1E923 (Adlam capital first letter), actual U+1E922 U+1E923 (unchanged)
      assertEquals(
          List.of("1e900", "1e923"),
          term.toString().codePoints().mapToObj(Integer::toHexString).toList());
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-533/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestCapitalizationFilterSupplementary
- Expected vs actual
- Expected U+1E900 U+1E923 (capital first letter); actual U+1E922 U+1E923 (
expected:<[1e900, 1e923]> but was:<[1e922, 1e923]>), with-eaand-da.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[1e900, 1e923]> but was:<[1e922, 1e923]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.miscellaneous.TestCapitalizationFilterSupplementary.testCapitalizesFirstLetterOutsideBmp(TestCapitalizationFilterSupplementary.java:37)- The javadoc promises "the first letter capital and the rest lower case", with no BMP limit; the JDK says the
charoverloads "cannot handle supplementary characters". LowerCaseFilter,UpperCaseFilterand this filter's own keep set work per code point; tests require it for Deseret.- The same defect was fixed in
LowerCaseFilter(LUCENE-2069) and, as bugs, inTruncateTokenFilter(#15900) andDecimalDigitFilter(LUCENE-6914).
The full argument263 words
- Contract. "A filter to apply normal capitalization rules to Tokens. It will make the first letter capital and the rest lower case." (
CapitalizationFilter.java:26-28). No script, BMP or UTF-16-unit limit in the class or the factory javadoc. Where Lucene means UTF-16 units it says so:LengthFilter.java:26, "Length is calculated as the number of UTF-16 code units". - The API used cannot do it. The JDK javadoc of
Character.toUpperCase(char)andtoLowerCase(char): "This method cannot handle supplementary characters. To support all Unicode characters, including supplementary characters, use the toUpperCase(int) method." - Siblings and their tests.
TestAnalyzers.testLowerCaseFilterandtestUpperCaseFilter("handles entire unicode range correctly") require Deseret to be mapped (TestAnalyzers.java:135-169). The filter's ownkeepIgnoreCaseset folds case per code point. - Policy before the class moved in.
CHANGES.txt:17927-17928(3.1.0): "LUCENE-2069: Added Unicode 4 support to LowerCaseFilter. Due to the switch to Java 5, supplementary characters are now lowercased correctly." That commit (2009) is an ancestor of the 2010 move of this class into Lucene, which copied the char loop verbatim. - Same defect class treated as a bug.
CHANGES.txt:1198-1200(10.5.0 Bug Fixes): "GITHUB#15899, GITHUB#15900: Improve TruncateTokenFilter to truncate on codepoints not chars and no longer produce half surrogates"; on #15899 uschindler wrote "We modified all other similar filters in the past (like ngrams), they all work correctly".CHANGES.txt:8852: "LUCENE-6914: Fixed DecimalDigitFilter in case of supplementary code points." - Nothing presents it as a choice. No test, javadoc, CHANGES or MIGRATE entry, commit message or JIRA discussion (SOLR-248, SOLR-468 and LUCENE-2413, read in full) marks the char loop as BMP-only.
TestCapitalizationFilter.testRandomStringchecks token-stream consistency, not case.
The devil's-advocate check187 words
The strongest case for "intended" (the intended-behaviour check and the cross-model reviewer): a legacy, display-oriented char-buffer filter from Solr 1.3 ("useful to build nice looking facet parameters"), never updated, whose fix changes indexed output; on #15900 uschindler argued at one point that half surrogates from char-based truncation are "expected", "exactly the same like if you use String#substring(n,m)" (earlier in the same thread, uschindler had called that filter "somehow broken in general"), and both LUCENE-2069 and #15900 kept a legacy path.
Why it fails: nothing documents a BMP limit; the JDK documents the overloads used as unable to do the job; the sibling case filters and this filter's own keep set work per code point; on #15900 rmuir wrote "Nobody expects that behavior and doing this based on codepoints is a better api" (before the "expected" remark), and that fix shipped under Bug Fixes. Every verifier who assessed the argument rated it weak (the intended-behaviour check: no intended argument survives). What survives is the narrow reach and the reindex cost: reasons for low priority and a CHANGES note, perhaps a legacy option, not for keeping the behaviour.
Recommended A: map code points, as LowerCaseFilter and UpperCaseFilter do
Map code points, as LowerCaseFilter does: CharacterUtils.toLowerCase for the rest and later words, Character.toUpperCase(int) on the first code point (+11/-9 lines). The repro passes with assertions on and off; the whole analysis-common test task (1,913 tests, assertions on) and lint pass; lone surrogates stay unchanged. Indexed terms change for these scripts: mention reindexing.
All options and trade-offs3 options · 636 words
One fix, the finder's patch, was rebuilt and validated in a scratch worktree at a9779ef3c193; it applies unchanged.
A: map code points, as LowerCaseFilter and UpperCaseFilter do (validated by the checks) (recommended)
Replace the two char loops with CharacterUtils.toLowerCase(buffer, from, to) and the two first-letter statements with a small helper that reads the first code point, upper-cases it with Character.toUpperCase(int) and writes it back with Character.toChars. All three paths of processWord are covered.
--- a/lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/CapitalizationFilter.java
+++ b/lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/CapitalizationFilter.java
@@ -19,6 +19,7 @@
 import java.io.IOException;
 import java.util.Collection;
 import org.apache.lucene.analysis.CharArraySet;
+import org.apache.lucene.analysis.CharacterUtils;
 import org.apache.lucene.analysis.TokenFilter;
 import org.apache.lucene.analysis.TokenStream;
 import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
@@ -148,15 +149,13 @@
     }

     if (onlyFirstWord && wordCount > 0) {
-      for (int i = 0; i < length; i++) {
-        buffer[offset + i] = Character.toLowerCase(buffer[offset + i]);
-      }
+      CharacterUtils.toLowerCase(buffer, offset, offset + length);
       return;
     }

     if (keep != null && keep.contains(buffer, offset, length)) {
       if (wordCount == 0 && forceFirstLetter) {
-        buffer[offset] = Character.toUpperCase(buffer[offset]);
+        upperCaseFirstCodePoint(buffer, offset, length);
       }
       return;
     }
@@ -187,11 +186,14 @@
     /*char[] chars = w.toCharArray();
     StringBuilder word = new StringBuilder( w.length() );
     word.append( Character.toUpperCase( chars[0] ) );*/
-    buffer[offset] = Character.toUpperCase(buffer[offset]);
-
-    for (int i = 1; i < length; i++) {
-      buffer[offset + i] = Character.toLowerCase(buffer[offset + i]);
-    }
+    int firstLen = upperCaseFirstCodePoint(buffer, offset, length);
+    CharacterUtils.toLowerCase(buffer, offset + firstLen, offset + length);
     // return word.toString();
   }
+
+  /** Upper-cases the first code point of the word; returns its length in chars. */
+  private static int upperCaseFirstCodePoint(char[] buffer, int offset, int length) {
+    int cp = Character.codePointAt(buffer, offset, offset + length);
+    return Character.toChars(Character.toUpperCase(cp), buffer, offset);
+  }
 }
Trade-offs
- Output changes only for supplementary letters; BMP text gives the same chars as before. Indexes built with this filter need reindexing for exact consistency, so a CHANGES note should say so.
- The in-place edit relies on case mapping keeping each code point's UTF-16 length; that holds for all 1,112,064 non-surrogate code points with JDK 25, and
CharacterUtils.toLowerCase(used byLowerCaseFilter) relies on the same. - With a case-sensitive keep list, the stock filter maps
[a, U+10400]onto a kept word[A, U+10400]; the fixed filter keeps them apart ([A, U+10428]). Worth one sentence in the PR.
What the checks validated
- Stock main: the paste-ready test fails 3 of 4, assertions on and off; the 29 upstream
TestCapitalizationFilter*tests pass. - With fix A,
TestCapitalizationFilter*: 3 classes, 33 tests, 0 failures, assertions on and off. - With fix A, the whole
:lucene:analysis:common:testtask: 340 classes, 1,913 tests, 0 failures, 18 skipped (skips not examined). ecjLintMain,ecjLintTest,checkGoogleJavaFormat,forbiddenApisMainandforbiddenApisTestof the module pass.- The standalone runner with the fixed class shadowed: 4 of 4 on main,
-eaand-da; earlier, the finder's test (4 of 4) and the 29 upstream tests onea57360912ed. - Malformed UTF-16: all 137,257 strings of 0-6 chars over {
a,B, space,., U+D801, U+DCB0, U+DCD8} (128,166 with an unpaired surrogate) through the stock and the fixed filter, three configurations,-eaand-da: no exception, the same length, lone surrogates unchanged, and without a valid pair the fixed output equals the stock output.
Keep the char-wise path behind an option, as #15900 did for TruncateTokenFilter ("new factory parameters available to configure legacy prefix chars and new codepoint behaviour") or LUCENE-2069 did with a Version argument.
Trade-offs
More API surface for 564 code points; only worth it if maintainers want old terms to stay exactly as they are without reindexing.
A javadoc note that only BMP letters change case.
Trade-offs
Cheap, but contradicts LowerCaseFilter, UpperCaseFilter, the filter's own keep set and the project's past fixes.
Search servers built on Lucene that expose the factory in a schema, as its javadoc example text_cptlztn does, inherit the behaviour.
Semi-formal. A bounded-exhaustive comparison ran the stock filter against a per-code-point reference written from its javadoc, on every token of up to 4 code points over a, B, space and two Deseret letters, with both onlyFirstWord settings: 836 of 1,414 checks differed, each at a supplementary letter. A public-API JUnit then confirmed it on the stock jar.
The method in full179 words
Method: bounded-exhaustive translation validation (the hunt's semi-formal tier). The finder wrote two references for CapitalizationFilter from its javadoc, one that maps case per char and one per code point, and compared the stock filter with them:
- with the per-char reference, on every token of up to 5 chars over {a, B, space, '.', U+0131} under 1,440 parameter combinations (7,874,496 checks): the mismatches found the sibling word-boundary bug (LFV-535);
- with the per-code-point reference, on every token of up to 4 code points over {a, B, space, U+10428, U+10400}, with the default parameters and with
onlyFirstWord=false, restricted to checks (a token with oneonlyFirstWordsetting) where the per-char reference agrees, so the sibling bug is excluded: 836 of 1,414 checks differ, each at a supplementary letter; 880 of all 1,562 checks (781 tokens x 2 settings) still differ after the sibling's fix.
A public-API JUnit on the stock main jar then confirmed it (found 2026-10-26). The same reference was used to find and to check, so the exhaustive count is not independent evidence; the verifiers wrote their own tests.
No prior report found: four scripted prior-report search runs (GitHub, JIRA, the Lucene and old Solr lists, the web), 64 GitHub and 16 JIRA searches and the files of all 408 open PRs (2026-10-26), and a GitHub re-check on 2026-10-28. Nearest: #2763, the 2009 policy for supplementary characters in char-based code, which never names this class. Not fixed upstream.
Searches5 searches
The documented searches found no issue, PR, review, commit message, JIRA entry, mailing-list thread or web page that reports that CapitalizationFilter maps case per char or leaves supplementary letters unchanged. Every CapitalizationFilter issue on record is about other behaviour: SOLR-248 (origin), SOLR-468 (keep semantics), SOLR-1317 (NPE), SOLR-1320 and SOLR-1342 (term-buffer length), SOLR-1660 (maxWordCount crash) and LUCENE-5559 = #6621 (argument validation). Context and precedent: #2763 (LUCENE-1689, the 2009 umbrella; it names only Lucene classes, and this class was in Solr until 2010), #3145 (LUCENE-2069, LowerCaseFilter), #6433 (LUCENE-5369, UpperCaseFilter), #7972 (LUCENE-6914) and #15899 / #15900 (TruncateTokenFilter). If you read the 2009 umbrella as covering every char-based class, the label becomes "known". LFV-685 (IrishLowerCaseFilter) has the same pattern with a different fix site.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), downstream repositories | 2026-10-26 | the scripted prior-report search, the finder's run (45 queries) and the follow-up's (58: GitHub 20, commits 3, downstream 2, lists 20, JIRA 4, web 9), plus 64 GraphQL issue and PR searches over apache/lucene, apache/solr, Elasticsearch, OpenSearch, Lucene.NET and all of GitHub | no report; only #6621 and #6108 mention the class (in the body or comments), neither about this |
| Open PRs | 2026-10-26 | the changed files of all 408 open apache/lucene PRs | only #16911 (decommission branch_10x) lists the file; not a fix |
| JIRA archive and mailing lists | 2026-10-26 | 16 JQL searches over SOLR and LUCENE, 19 issues read in full; dev@, java-user@, issues@, commits@, solr-user@, solr-dev@, general@ and java-dev@ (two more tool runs, 24 queries on the old Solr lists) | no report; a 2010 solr-user thread about '.' splitting words belongs to the sibling LFV-535 |
| Web | 2026-10-26 | 9 general web searches (titles and snippets) | no report; one 2011 Q&A page, 'Solr CapitalizationFilterFactory not working', could not be opened |
| GitHub re-check | 2026-10-28 | read-only searches for CapitalizationFilter and capitalization issues and PRs, the file lists of the 15 open PRs created since 2026-10-26, and the commits on the file | nothing new (of the 15 new open PRs only #16911, the branch_10x decommission, touches the file: it deletes it there; not a fix); the file's last upstream commit is from 2020-12-28 (LUCENE-9570, formatting) |
As old as the code: char-wise since the Solr original 777e0c81608 (SOLR-248, 2007); the current lines are from ac58a1a4dd4 (SOLR-468, 2008), moved into Lucene unchanged by 8f71031ac88 (LUCENE-2413, 2010). First Lucene release 4.0.0-ALPHA; never changed since, and every release tested reproduces it.
Versions tested9 rows
Introduced by 777e0c81608 (Solr, SOLR-248, svn r556196, 2007-07-14, "SOLR-248 -- Added CapitalizationFilterFactory"), whose first letter, rest-of-word and keep-word paths were already char-wise; only the later-words path used String.toLowerCase(), which maps code points. ac58a1a4dd4 (SOLR-468, svn r630572, 2008-02-24) rewrote processWord to edit the char[] in place, which produced the four statements on main and made the later-words path char-wise too. 8f71031ac88 (LUCENE-2413 = #3488, svn r957162, 2010-06-23, "consolidate remaining solr tokenstreams into modules/analysis") copied it into Lucene verbatim. svn era, no pull request. Later commits only changed the path, argument validation (LUCENE-5559), an import (LUCENE-7318), licence headers, two javadoc doclint fixes (bab0b463371, 376256316b0) and formatting (LUCENE-9570). All 133 release-tag versions of the file (Solr 1.3.0-3.6.2, Lucene 4.0.0-ALPHA-10.5.2) have the four char-wise statements. The history clone has no tags for 8.8.2-8.11.4, so the release jars were checked too: in the 129 release jars 4.0.0 to 10.5.1 of the hunt's jar cache (SHA-1 checked) the bytecode of processWord calls Character.toUpperCase(char) twice and Character.toLowerCase(char) twice, and no code-point overload. Not a regression: LowerCaseFilter already mapped code points (LUCENE-2069, 2009) when the class moved in. Upstream main 645d4fe14a20, branch_10x and branch_10_6 have the same file blob as the tested commit (2026-10-28).
| Version or commit | Verdict | Result |
|---|---|---|
| Lucene 3.6.2 | no class | ClassNotFoundException: the Lucene class does not exist before 4.0.0-ALPHA |
| Solr 1.3.0 | Solr's class | none of 4 supplementary cases (Adlam x2, Osage, Deseret) mapped; BMP control OK |
| 4.0.0-ALPHA, 4.0.0 | affected | a release-portable main(): 3 of 3 supplementary cases wrong, control OK |
| 8.11.4 | affected | the same main(): the same 3 cases wrong |
| 4.0.0 to 10.5.1 (129 release jars) | bytecode | javap -c of processWord: 2 x toUpperCase(char), 2 x toLowerCase(char), no code-point call, in every release jar, 8.8.2-8.11.4 included |
| 9.12.3, 10.5.2 | affected | this doc's test: 4 run, 3 failed (-da), the same messages as main; the hunt's and the independent reproduction's tests fail too |
main ea57360912ed | affected | the hunt's test 3 of 4 and the independent reproduction's 5 of 7 fail, -ea and -da |
main a9779ef3c193 | affected | this doc's test: 3 of 4 fail through gradle and the JUnit runner, -ea and -da |
| main + fix A | fix | 33 of 33 (gradle, -ea and -da); whole analysis-common module 1,913 tests, 0 failures (-ea) |
The finder, an independent reproducer, an intended-behaviour devil's advocate, the adjudication and a credibility audit all ran code and said real. A reviewer from another model family (OpenAI GPT-5.6) could only read, not run: real once, and once not real for that procedural reason alone. This doc wrote a new test and validated the fix through gradle.
Checks and verdicts327 words
The hunt's checks ran on main ea57360912ed, this doc's on a9779ef3c193; the filter and its factory are byte-identical in both. Every run used JDK 25.0.3.
| Check | Verdict | What it found |
|---|---|---|
| finder: exhaustive check and JUnit | 836 of 1,414 checks wrong | All at a supplementary letter. The JUnit fails 3 of 4 on main (-ea, -da), 10.5.2 and 9.12.3; with the fix 4 of 4 pass, and the 29 upstream tests pass. |
| cross-model reviewer, intended lens (OpenAI GPT-5.6) | real, medium | Reading only (it could not start Java); intended argument weak; a separate re-run of the repro failed 3 of 4. |
| Independent reproducer | real | Own 7-test JUnit with Deseret letters fails 5 of 7 on main (-ea, -da), 10.5.2 and 9.12.3; oracle and BMP controls pass; it also covers the onlyFirstWord and keep-word paths. |
| Cross-model reviewer, refute lens (OpenAI GPT-5.6) | not real, low (procedural) | Could not execute; agreed on the root cause and the contract, rated the intended argument weak and noted "Static evidence strongly favors a real defect"; a separate re-run failed 3 of 4. |
| Intended-behaviour devil's advocate | real; no intended argument survives | Reached it through CustomAnalyzer with the stock standard, whitespace and keyword tokenizers: 9 of 9 cases unmapped, while 'lowercase' maps them (-ea, -da). |
| adjudication | confirmed, high | New seed: the independent reproduction's test 5 of 7 fail (-ea and -da), the finder's 3 of 4. |
| registry re-run and credibility audit | keep | 3 of 4 fail with -ea and -da, 4 of 4 pass with the fix; the audit re-ran with a fresh seed and advises a low-priority correctness fix. |
| this doc | confirmed; fix validated | New format-clean test fails 3 of 4 through gradle (-ea, -da) and the runner (main, 10.5.2, 9.12.3); with the fix it passes, as do the whole analysis-common test task (assertions on) and the module's lint, format and forbidden-API checks; the fix also holds on malformed UTF-16. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 443 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,364 words
- Registry title
- CapitalizationFilter changes case one UTF-16 char at a time, so cased letters outside the BMP (Adlam, Osage, Deseret and five other scripts) are neither capitalized nor lower-cased, while BMP letters in the same token are
- Area
- analysis-common / miscellaneous (CapitalizationFilter case mapping)
- Priority
- Low, rank 528: CapitalizationFilter ignores case for supplementary-plane cased scripts such as Adlam and Osage, a tiny share of text in a niche filter.
- Impact class
- silent wrong results
- Impact note
- Hits applications that put the opt-in CapitalizationFilter (directly, or by its 'capitalization' factory name in a schema or CustomAnalyzer) on a field that holds text in one of the eight cased scripts encoded outside the BMP (Adlam, Osage, Deseret, Old Hungarian, Warang Citi, Medefaidrin, Vithkuqi, Garay): every such letter that should change case keeps its case, on every release since 4.0.0-ALPHA, deterministically with -ea and -da and at any scale, so case variants of one word stay separate terms and facet values and a query in the other case misses; the output stays valid UTF-16, nothing is thrown or corrupted, and BMP text, emoji and CJK ideographs are not affected.
- Summary
- You add CapitalizationFilter, documented to 'make the first letter capital and the rest lower case', and give it a word in a cased script outside the BMP, for example the Adlam word U+1E922 U+1E923 (two small letters), and expect U+1E900 U+1E923 (capital first letter). Instead every supplementary letter keeps its case: U+1E922 U+1E923 comes out unchanged, U+1E900 U+1E901 is not lower-cased to U+1E900 U+1E923, and 'aB' followed by the Osage capital U+104B0 gives 'Ab' + U+104B0, because processWord applies Character.toUpperCase(char) and toLowerCase(char) to single UTF-16 units and a surrogate unit maps to itself. BMP letters in the same token are mapped, nothing is thrown, and the onlyFirstWord and keep-word forceFirstLetter paths behave the same way.
- Introduced
- 777e0c81608b331e766c9d283778186e8fb4c7ab (Solr, JIRA SOLR-248, svn r556196; the first version of the filter, with char-wise first-letter, rest-of-word and keep-word case mapping); the four statements now on main come from ac58a1a4dd4b (SOLR-468, svn r630572, the in-place char[] rewrite, which also made the onlyFirstWord later-words path char-wise) and were copied verbatim into Lucene by 8f71031ac88e (LUCENE-2413 = #3488, svn r957162) [read: git blame -w -C -C -M of main lines 152, 159, 190 and 193 and per-commit diffs in the full-history clone]; svn era, no pull request; never changed since (later commits touched only the path, argument validation, an import, license headers and formatting) (2007-07-14 (Solr origin; current line form 2008-02-24; moved into Lucene 2010-06-23))
- First affected version
- 4.0.0-ALPHA [exec] (the first Lucene release with the class, 2012-06-29; first GA release 4.0.0 [exec]); the same code shipped earlier as Solr's own class from Solr 1.3.0 [exec]; Lucene 3.6.2 has no such class [exec: ClassNotFoundException]
- Affected versions
- every Lucene release before 10.6.0 with the class, 4.0.0-ALPHA through 10.5.2, and main ea57360912ed: JUnit fails on main (-ea and -da), 10.5.2 and 9.12.3 [exec, finder and the independent reproduction], and a release-portable main() fails on 8.11.4, 4.0.0 [exec, finder] and 4.0.0-ALPHA and Solr 1.3.0 [exec, follow-up history check]; the four char-wise statements are unchanged in all 133 release-tag file versions scanned (Solr 1.3.0-3.6.2, Lucene 4.0.0-ALPHA-10.5.2) [read]; not fixed upstream: upstream main ffa9d816eeb4 has a byte-identical file and branch_10x, branch_10_6 and branch_10_5 have the same lines [read, 2026-10-26]; unaffected: Lucene before 4.0.0-ALPHA (no class) [exec on 3.6.2]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, the prior-report record verdict new, all read-only: the finder's scripted prior-report search (45 queries) and the follow-up's (58 queries over GitHub issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web, every source finished), two more scripted prior-report searches over the ASF and old Solr lists (24 queries on solr-user@, solr-dev@, general@ and java-dev@), 64 GitHub GraphQL issue and PR searches (apache/lucene, apache/solr, Elasticsearch, OpenSearch, Lucene.NET and all of GitHub), 16 JQL searches with 19 SOLR and LUCENE issues read in full, the file lists of all 408 open apache/lucene PRs, the solr.apache.org lists, full-history git searches and 9 web searches; gap: Q&A sites only through web search, and one 2011 Q&A page titled 'Solr CapitalizationFilterFactory not working' could not be opened); every CapitalizationFilter issue on record (SOLR-248, SOLR-468, SOLR-1317, SOLR-1320, SOLR-1342, SOLR-1660, LUCENE-5559 = #6621) is about other behaviour; related prior items, context and precedent only: #2763 (LUCENE-1689, the 2009 umbrella 'supplementary character handling', which set the policy that char-based analysis code must handle supplementary characters; it names only Lucene classes, and CapitalizationFilter was a Solr class until 2010), #3145 (LUCENE-2069, the same defect fixed in LowerCaseFilter), #6433 (LUCENE-5369, UpperCaseFilter maps per code point), #3144, #3259 and #3170 (LUCENE-2068, -2183, -2094), SOLR-1593, #7972 and #8417 (LUCENE-6914, LUCENE-7363, DecimalDigitFilter), #6106 (LUCENE-5042), #15899 and #15900 (TruncateTokenFilter on code points, 10.5.0 Bug Fixes; in #15899 uschindler wrote that all other similar filters work correctly), #3488 (LUCENE-2413, moved the class into Lucene); not fixed upstream: upstream main ffa9d816eeb4 has a byte-identical file and no open PR changes it (#16911, the branch_10x decommission, deletes it on that branch only and is not a fix). Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
a9779ef3c193(gradle in a scratch worktree, assertions on and off, and the standalone JUnit runner); the release jars 10.5.2 and 9.12.3 (this doc's test); mainea57360912ed, 8.11.4, 4.0.0, 4.0.0-ALPHA and Solr 1.3.0 (the hunt's tests and the history probe); the fix on main (gradle: theTestCapitalizationFilter*classes and the whole:lucene:analysis:common:testtask, plus the module's lint, format and forbidden-API checks). JDK 25.0.3 on Linux aarch64 only.
- Finding record
a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/CapitalizationFilter.java:26-31 (class javadoc: 'It will make the first letter capital and the rest lower case'; 'nice looking facet parameters'), :145-196 (processWord), :152, :159, :190, :193 (Character.toLowerCase(char) / toUpperCase(char) on single UTF-16 units), :107 and :116 (termAtt.length(), in UTF-16 units, compared with maxTokenLength)a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/CapitalizationFilterFactory.java (factory javadoc, no BMP or code-unit limit; no normalize() override)a Lucene main checkout lucene/analysis/common/src/test/org/apache/lucene/analysis/core/TestAnalyzers.java:136-166 (LowerCaseFilter and UpperCaseFilter must map Deseret letters)a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/LengthFilter.java:26 ('Length is calculated as the number of UTF-16 code units'); lucene/analysis/common/src/java/org/apache/lucene/analysis/ga/IrishLowerCaseFilter.java:55 (side observation, char overload, not executed)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/CapitalizationFilter.java:26-31 (javadoc), :102-143 (incrementToken), :145-196 (processWord; char overloads at :152, :159, :190, :193)lucene/core/src/java/org/apache/lucene/analysis/CharacterUtils.java:54-70, :105-113; lucene/core/src/java/org/apache/lucene/analysis/LowerCaseFilter.java:38; lucene/analysis/common/src/java/org/apache/lucene/analysis/core/UpperCaseFilter.java:48lucene/core/src/java/org/apache/lucene/analysis/CharArrayMap.java:231-290 (code-point case folding of the keep set)JDK 25 src.zip java.base/java/lang/Character.java:11210-11213 (toLowerCase(char)), :11270-11273 (toUpperCase(char)): 'cannot handle supplementary characters'
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/CapitalizationFilterFactory.java:49-58 (schema example), :65 (SPI name)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/CapitalizationFilter.java:26-31lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/CapitalizationFilterFactory.java:28-61 (factory javadoc)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/LengthFilter.java:26JDK 25 src.zip java.base/java/lang/Character.java:11210-11213, :11270-11273lucene/analysis/common/src/test/org/apache/lucene/analysis/core/TestAnalyzers.java:135-169lucene/core/src/java/org/apache/lucene/analysis/CharArrayMap.java:231-290lucene/CHANGES.txt:17927-17928 (3.1.0, LUCENE-2069), :1198-1200 (10.5.0 Bug Fixes, GITHUB#15899/#15900), :8852 (LUCENE-6914)
- Suggested fix
lucene/CHANGES.txt:1198-1200 (#15900 legacy parameters), :17927-17931 (LUCENE-2069 Version argument)
- Prior reports
gh api repos/apache/lucene/commits?path=.../CapitalizationFilter.java; gh search issues/prs --repo apache/lucene CapitalizationFilter; gh pr list --search created:>=2026-10-26 (read-only, 2026-10-28)
- History
gh api repos/apache/lucene/contents/.../CapitalizationFilter.java?ref=645d4fe14a20, branch_10x, branch_10_6: blob 08b46c3191e5 (= a9779ef3c193) (read-only, 2026-10-28)
- Diagrams
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/CapitalizationFilter.java:27-28, :30, :120-134, :145-196 (:152, :159, :190, :193)
- TestCapitalizationFilterSupplementary.java (JUnit test):
repro/LFV-533/src/org/apache/lucene/analysis/miscellaneous/TestCapitalizationFilterSupplementary.java(42 lines)
A step-by-step picture made from an executed probe on main a9779ef3c193 (stock jars and the fixed class, assertions on and off); every value drawn comes from that probe and the source at that commit. It uses the Osage example (left to right, BMP and supplementary letters in one token) rather than the Adlam one of the repro; the defect is the same for all eight scripts. The PNG is the final summary frame.
assets/LFV-533/bug.png(443 KB)