The taxonomy stores each label as UTF-8, where an unpaired surrogate becomes U+FFFD, but the writer cache compares the label's Java string. After 11 cache misses a writer session reloads its cache from the index under the stored text and then trusts it as complete, so the original label misses its own entry and is indexed again.
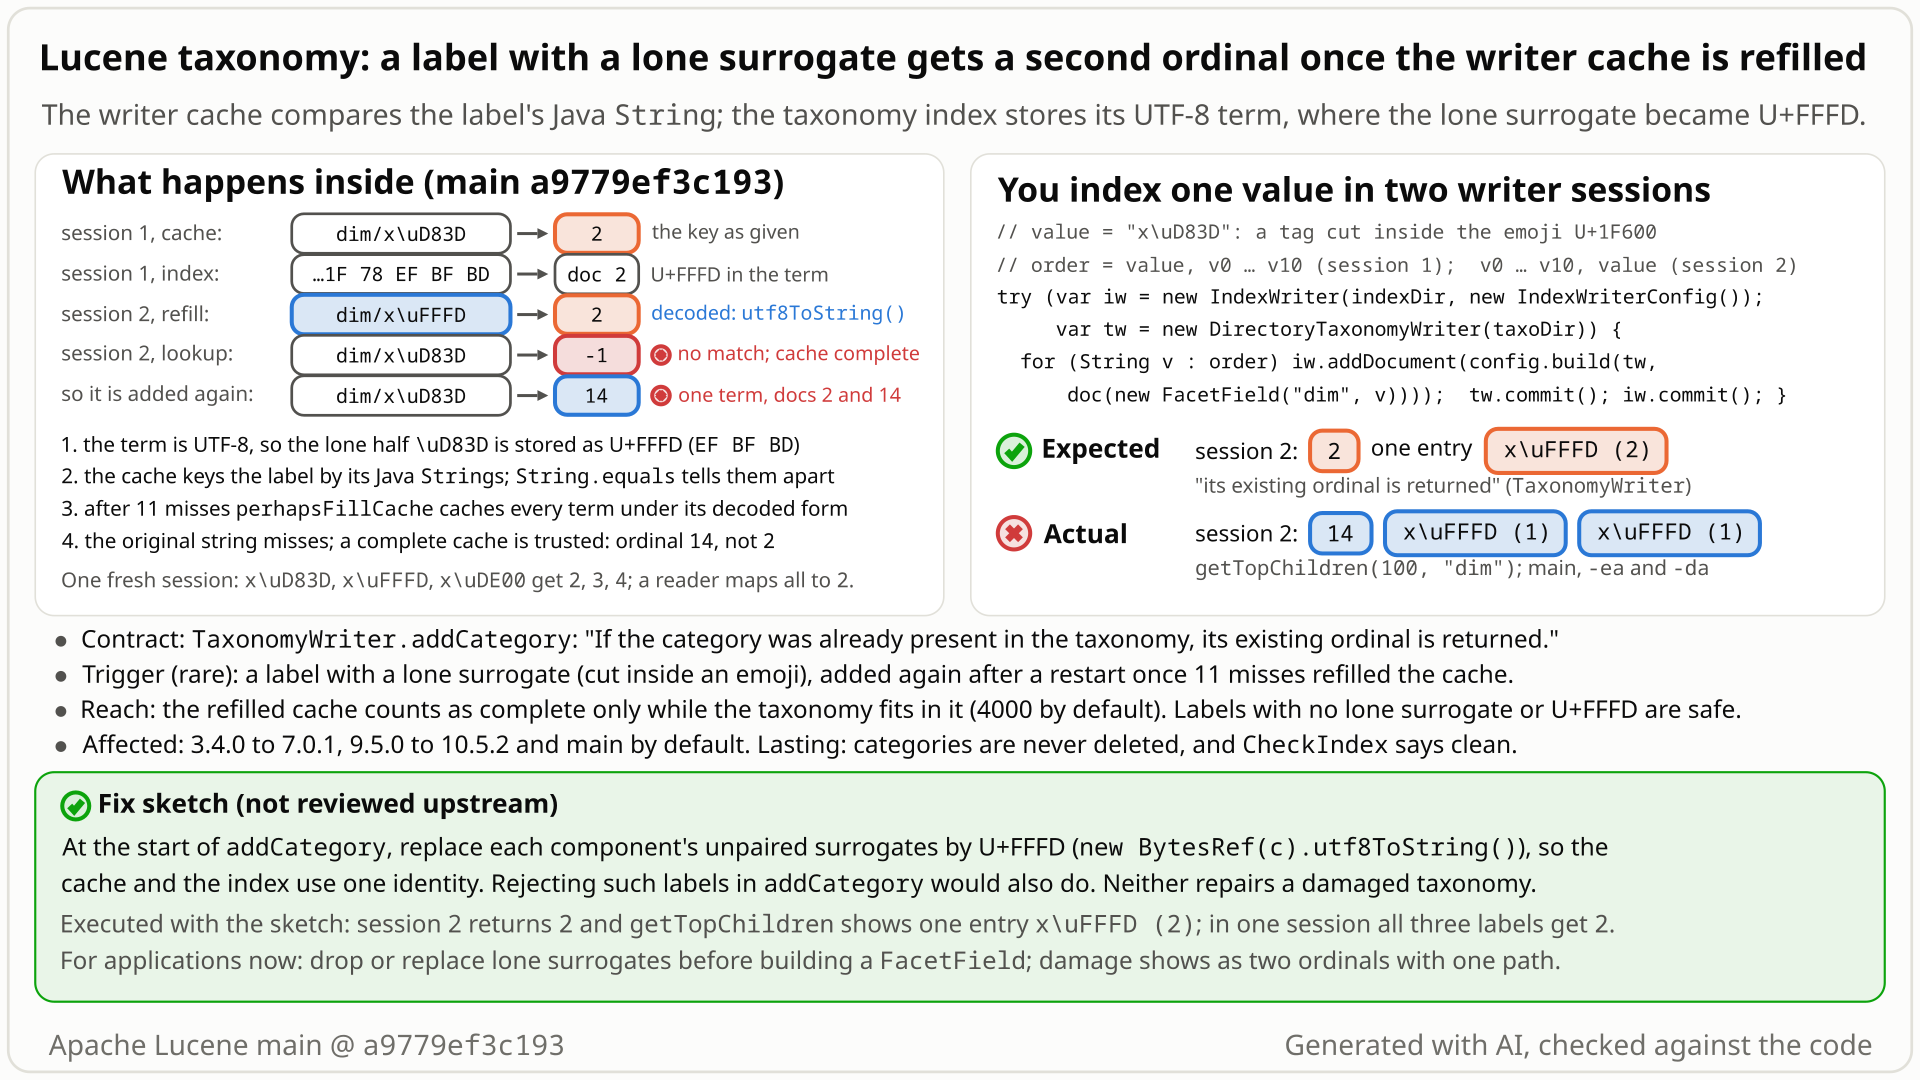
- You index a facet value cut inside an emoji:
"x😀".substring(0, 2)is"x\uD83D", anxplus a lone half. The taxonomy stores labels as UTF-8, where the lone half becomes U+FFFD, so category 2 is stored asdim/x�. Valuesv0tov10get ordinals 3 to 13. - You restart and index
v0tov10again, then the cut value. The new writer's cache starts empty; after 11 misses (v0tov10) it loads all 14 categories from the index, keyed by their stored text, and from then on trusts the cache as complete. - You expect
x\uD83Dto get its existing ordinal 2 back, and one facet entryx� (2). - Instead
x\uD83Ddoes not equal the cachedx�, the complete cache says "new", and the writer indexes the label again as ordinal 14.getTopChildrenshowsx� (1)twice, andgetSpecificValuecounts 1 of the 2 documents. - It lasts: commit stores two categories with one path,
CheckIndexcalls the taxonomy clean, each later session can add another copy, and once both copies sit in one taxonomy segment,TaxonomyMergeUtils.mergekeeps the value for only 1 of 2 documents (or throwsEOFException).
Applications that use taxonomy facets with the default writer and cache and whose labels can keep half an emoji: tags cut by char count, decoded JSON \uD83D escapes. From 9.5.0 the taxonomy must still fit in the 4,000-entry cache. Rare but silent and lasting; labels with neither an unpaired surrogate nor U+FFFD, search hits and drill-down are unaffected.
Mechanism, terms and numbers826 words
A facet label can contain an unpaired surrogate, for example a tag cut by String.substring in the middle of an emoji ("x😀".substring(0, 2) is "x\uD83D"). The taxonomy index stores each category as UTF-8, and UTF-8 encoding replaces the unpaired surrogate with U+FFFD, as IndexWriter.addDocument documents. DirectoryTaxonomyWriter's cache, however, compares the label's Java strings. When a writer session fills its cache from the index (by default after 11 cache misses), the cached key is the stored form x�, the original x\uD83D misses, and because the cache now counts as complete the writer indexes the label again: ordinal 14 instead of 2. commit() persists two category documents for one taxonomy term, facet counts for the value split into two entries with the same label, label lookups see only the first copy, every later session can add one more copy, and once both copies sit in one taxonomy segment (after later sessions merge the taxonomy's segments, or when both are made in one session) a TaxonomyMergeUtils.merge drops the value from documents on the duplicate (or throws EOFException with DiskOrdinalMap). CheckIndex calls the taxonomy clean. It affects the default configuration in 9.5.0 to 10.5.2 and main (and 3.4.0 to 7.0.1); from 9.5.0 the cross-session case needs a taxonomy that fits in the 4,000-entry cache. Labels with neither an unpaired surrogate nor U+FFFD are never affected; a well-formed label containing U+FFFD can get a second ordinal only when an ill-formed label with the same stored form is also added.
- Taxonomy and ordinal. Taxonomy facets store each label, such as
dim/v0, once in a side index, as one document whose doc ID is the label's ordinal; main-index documents store ordinals, and counts are kept per ordinal. Categories are never deleted (TaxonomyReader.java:33-35). - Unpaired surrogate. Java strings are UTF-16; an emoji such as 😀 (U+1F600) takes two chars, a surrogate pair. Cutting by char count can keep only the first half:
"x😀".substring(0, 2)is"x\uD83D". UTF-8 has no encoding for a lone half, so Lucene writes U+FFFD (bytesEF BF BD) instead: "the invalid characters are silently replaced with the Unicode replacement character U+FFFD" (IndexWriter.java:1483-1485;UnicodeUtil.java:231-235). - Writer cache.
DirectoryTaxonomyWriterremembers label -> ordinal in a cache, by defaultLruTaxonomyWriterCache(4000)keyed by theFacetLabel, whoseequalscompares Java strings (DirectoryTaxonomyWriter.java:89,:273-276;NameIntCacheLRU.java:71-74;FacetLabel.java:122-139).
addCategoryasks the cache first (DirectoryTaxonomyWriter.java:385); on a missfindCategoryeither trusts the cache, when it counts as complete (:326-329), or looks the label up in the index by its UTF-8 term (:354-357).- In a reopened taxonomy the cache starts empty and incomplete. After
cacheMissesUntilFill = 11misses (:101,:331),perhapsFillCachereads every term into the cache undernew FacetLabel(FacetsConfig.stringToPath(t.utf8ToString())), the U+FFFD form (:633), and setscacheIsComplete = !aborted(:652); it aborts only when the cache is full (:626,:640). x\uD83Ddoes not equal the cachedx�, the complete cache answers "absent", andaddCategoryDocumentwrites a second document for the same term (:397,:452-482), against the writer's own comment "Since we guarantee uniqueness of categories, each term has exactly one document" (:628-632).- A new taxonomy starts with a complete cache (
:181-182), so in one fresh sessionx\uD83D,x�andx\uDE00get ordinals 2, 3 and 4, while a reader resolves all three to 2 (DirectoryTaxonomyReader.java:299-306, the first document of the term). This holds while the cache stays complete: once aputevicts entries (at 4,000 by default),addToCachesetscacheIsComplete = false(:484-492) and later labels are looked up in the index again. - Readers list both copies as children (
x� (1)twice); lookups of the duplicated path (getOrdinal,getSpecificValue,getTopChildren(dim, path)) see only the first copy, while a unique child's full path below the second copy still resolves; drill-down uses path terms and matches both documents. addTaxonomymaps only the first document of each term per segment (DirectoryTaxonomyWriter.java:717-721), thoughOrdinalMapexpects one mapping per document (:743-746). Once both copies share a taxonomy segment,MemoryOrdinalMapleaves the second at 0, the root (:770-784), so that document loses its value in the merged index;DiskOrdinalMapthrowsEOFException.
Default writer, cache and FacetsConfig; session 1 indexes dim/x\uD83D (ordinal 2) and dim/v0 to dim/v10 (3 to 13); session 2 indexes the same 12 values. After the 11th miss the cache holds all 14 categories and counts as complete; dim/x\uD83D then gets ordinal 14, the term dim + 1F 78 EF BF BD has documents 2 and 14, getTopChildren(100, "dim") gives value=24 childCount=13 with x� (1) twice, getSpecificValue("dim", "x\uD83D") is 1, drill-down matches 2 documents and CheckIndex reports the taxonomy clean. With the normalizing fix: ordinal 2, one entry x� (2). Same with assertions on and off.
Exposure and likelihood440 words
- Who is exposed. Taxonomy-facet users with the default
DirectoryTaxonomyWriterand cache (defaultIndexWriterConfig, codec andDirectory) whose labels can keep an unpaired surrogate: a tag or category cut by char count inside an emoji, or a decoded JSON\uD83Descape (executed with one parser only, jackson-core 2.17.1, whose byte and char parsers both keep the lone\uD83D). Nothing in the facet API rejects such a label:FacetField.verifyLabelchecks null and empty (FacetField.java:64-73),FacetLabel.checkComponentsnull, empty and length (FacetLabel.java:81-100). - When. From 9.5.0: the same label again in a later writer session after 11 cache misses in that session (any 11 labels not yet cached), while the taxonomy fits in the 4,000-entry cache: with 11 or 3,990 filler labels (taxonomies of 14 and 3,993 categories before the re-add) the label is duplicated, with 4,100 or 20,000 (4,103 and 20,003 categories) it is not. Or two labels with the same stored form in a new taxonomy or after a fill, while the cache is complete. In 3.4.0 to 7.0.1 the default cache never reports full, so by code reading any taxonomy size is affected.
- Effect. Split and duplicated facet entries for the value; lookups of that label see only the first copy; one more copy per affected session (6 sessions gave 6 copies); once both copies sit in one taxonomy segment,
TaxonomyMergeUtilsmerges drop the value from documents or throwEOFException(while they sit in different segments, a merge into a new taxonomy joins them). All of it is committed, andCheckIndexcalls the taxonomy clean. - Not affected. Labels with neither an unpaired surrogate nor U+FFFD: a bounded-exhaustive check of 66,822 short labels found that only the 58,080 ill-formed ones change on the way to the index and no two well-formed labels share a term. A well-formed label containing U+FFFD can still be hit next to an ill-formed label of the same stored form: in one session
x\uD83Dgets 2 and the well-formedx�gets 3, which the reader resolves to 2. Search hits and drill-down stay correct, andSortedSetDocValuesFacetFieldgives one entry for the same value across two sessions. - Scale and likelihood. No scale needed (15 categories). Rare: every case needs a label with an unpaired surrogate; the same-label case also needs a later session after the fill and, from 9.5.0, a taxonomy that fits in the cache, while two different labels with one stored form collide even in one fresh session. No public report was found in the searches described below.
- Repair. Neither fix repairs existing duplicates; that takes rebuilding the taxonomy and re-indexing. Damage shows as two taxonomy ordinals with the same path.
The test shows that DirectoryTaxonomyWriter.addCategory gives a label with an unpaired surrogate (dim/"x\uD83D") a second ordinal in a later writer session once that session has filled its cache from the index (the stored term is x + U+FFFD).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.facet.taxonomy.directory;

import org.apache.lucene.facet.taxonomy.FacetLabel;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestTaxonomyUnpairedSurrogateLabel extends LuceneTestCase {

  public void testSameLabelKeepsOrdinalAfterCacheFill() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      FacetLabel label = new FacetLabel("dim", "x\uD83D");
      int first;
      try (DirectoryTaxonomyWriter tw = new DirectoryTaxonomyWriter(dir)) {
        first = tw.addCategory(label);
      }
      try (DirectoryTaxonomyWriter tw = new DirectoryTaxonomyWriter(dir)) {
        // with the label's own lookup, 11 misses (the default) fill the cache from the index
        for (int i = 0; i < 10; i++) {
          tw.addCategory(new FacetLabel("v" + i));
        }
        assertEquals("ordinal of the same label in a later session", first, tw.addCategory(label));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-541/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/facet/build/libs/lucene-facet-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.facet.taxonomy.directory.TestTaxonomyUnpairedSurrogateLabel
# the module(s) facet also need their third-party runtime jars
- Expected vs actual
- Expected, per
TaxonomyWriter.addCategory("If the category was already present in the taxonomy, its existing ordinal is returned"):2. Actual:expected:<2> but was:<13>.
More files, environment, full output42 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: ordinal of the same label in a later session expected:<2> but was:<13>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.facet.taxonomy.directory.TestTaxonomyUnpairedSurrogateLabel.testSameLabelKeepsOrdinalAfterCacheFill(TestTaxonomyUnpairedSurrogateLabel.java:38)TaxonomyWriter.addCategory: "If the category was already present in the taxonomy, its existing ordinal is returned." The same label gets 2, then 14.- The writer's own invariant "each term has exactly one document" breaks, though
IndexWriterdocuments storing such strings as U+FFFD. - One ordinal or two depends only on a hidden 11-miss cache heuristic; the 7.1.0-9.4.2 default cache gave one.
The full argument247 words
- Contract.
TaxonomyWriter.java:52-53: "addCategory() adds a category with a given path name to the taxonomy, and returns its ordinal. If the category was already present in the taxonomy, its existing ordinal is returned." The writer-only test breaks it with one unchanged label. - The writer's invariants. "Since we guarantee uniqueness of categories, each term has exactly one document" (
DirectoryTaxonomyWriter.java:628-632); "if the term was found, we know it has exactly one document" (:366). The defaultLRU_STRINGcache is "always correct" as opposed toLRU_HASHED, where a hash collision means "your document will get an incorrect facet" (LruTaxonomyWriterCache.java:28-41); that promise is about exact label keys, not about agreeing with the index's UTF-8 form. - Core semantics.
IndexWriter.java:1483-1485documents that malformed surrogate pairs are accepted and stored as U+FFFD (LUCENE-510), andTestIndexWriterUnicode.testInvalidUTF16asserts it. So the index's identity of such a label is its replaced form; taxonomy drill-down and SSDV facets already behave that way. - Tests.
TestTaxonomyCombined.testWriterTwice2andtestWriterTwice3assert that re-added categories keep their ordinals across writer sessions and across the cache fill. Facet tests draw labels from generators that make only valid UTF-16, so no test uses an unpaired surrogate. - History. 7.1.0 to 9.4.2 defaulted to
UTF8TaxonomyWriterCache(LUCENE-7975), keyed by the same UTF-8 bytes as the index, and did not show the bug. #12093 / #12092 replaced it because of a ThreadLocal leak (#12000); neither discusses label identity. LUCENE-7891 (#8942), a cache-key bug that gave documents wrong facets, was fixed as a bug.
The devil's-advocate check217 words
Strongest case (the devil's-advocate checker; a cross-model reviewer rated it moderate): a string with an unpaired surrogate is not Unicode text, BytesRef(CharSequence) says "This must be well-formed unicode text, with no unpaired surrogates" (BytesRef.java:74-79), FacetLabel is @lucene.internal and the writer @lucene.experimental, and in the review of PR #15900 (for the related #15899) one committer first called half surrogates from char truncation expected, something callers must be prepared for (the merged #15900, in 10.5.0, then added code-point truncation and deprecated the char-only constructor): garbage in, garbage out.
What to concede: Lucene could reasonably reject such labels, or only document that labels must be well-formed UTF-16; normalizing is one consistent choice, not the only one, and for the one-session pair (x\uD83D vs x�) merging them into one category is a policy choice. Why it fails as a defence of today's behaviour: the BytesRef precondition binds the writer's own internal call, while the user goes through the public FacetField API, which accepts the label; IndexWriter documents accepting such text; and the failure is self-inconsistent: the same unchanged label gets one ordinal or two depending only on whether a hidden cache heuristic has fired, and the writer breaks its own uniqueness invariant. Garbage in would justify an exception, not a silently duplicated category. Verdict: a defect.
Recommended Normalize the label to its indexed form in addCategory
Normalize the label to its stored form at the start of addCategory: replace each unpaired surrogate with U+FFFD, so cache and index agree (+44 lines). The new test passes 6 of 6 and the facet module's 312 tests pass, assertions on and off. Rejecting such labels instead also passes. Neither repairs existing duplicates.
categoryPath = toIndexedForm(categoryPath); // in addCategory, right after ensureOpen()
private static String replaceUnpairedSurrogates(String s) {
  char[] chars = null;
  for (int i = 0; i < s.length(); i++) {
    char c = s.charAt(i);
    if (Character.isHighSurrogate(c) && i + 1 < s.length() && Character.isLowSurrogate(s.charAt(i + 1))) {
      i++; // a well-formed pair
    } else if (Character.isSurrogate(c)) {
      if (chars == null) chars = s.toCharArray();
      chars[i] = (char) UnicodeUtil.UNI_REPLACEMENT_CHAR;
    }
  }
  return chars == null ? s : new String(chars);
}
All options and trade-offs4 options · 627 words
Options A and B were built and validated with gradle in a scratch worktree; C and D were not run. Until a fix lands, applications can replace unpaired surrogates with U+FFFD (the form the index stores anyway) or reject such labels before building a FacetField, and truncate labels by code point rather than by char.
One file, DirectoryTaxonomyWriter.java: addCategory first maps the label through toIndexedForm, which copies the components only if one changes and replaces every unpaired surrogate by U+FFFD, exactly as UTF-8 encoding does. Cache and index then share one identity. The logic is the finder's sketch, with an explicit replacement instead of a round trip through BytesRef(CharSequence), whose javadoc forbids unpaired surrogates.
categoryPath = toIndexedForm(categoryPath); // in addCategory, right after ensureOpen()
private static String replaceUnpairedSurrogates(String s) {
  char[] chars = null;
  for (int i = 0; i < s.length(); i++) {
    char c = s.charAt(i);
    if (Character.isHighSurrogate(c) && i + 1 < s.length() && Character.isLowSurrogate(s.charAt(i + 1))) {
      i++; // a well-formed pair
    } else if (Character.isSurrogate(c)) {
      if (chars == null) chars = s.toCharArray();
      chars[i] = (char) UnicodeUtil.UNI_REPLACEMENT_CHAR;
    }
  }
  return chars == null ? s : new String(chars);
}
Trade-offs
- Semantics:
x\uD83D,x\uDE00andx�become one category, as the reader, drill-down, SSDV facets and the 7.1.0 to 9.4.2 default cache already treat them;enrichOrdinalDocumentreceives the normalized label. - Cost: an extra scan of the label's chars on every
addCategorycall, cache hits included; an allocation only for labels that change. Not benchmarked. - Scope: a subclass that calls the protected
findCategorywith a raw label is not covered (it could normalize there too). Existing duplicates are not repaired.
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, JDK 25: the new test fails 4 of 6 on stock and passes 6 of 6 with the fix, assertions on and off; withTestDirectoryTaxonomyWriter,TestTaxonomyCombined,TestAddTaxonomy,TestConcurrentFacetedIndexingandTestDirectoryTaxonomyReader: 66 tests, 0 failures (3 nightly tests skipped). - The whole facet module: 40 suites, 312 tests (306 upstream + 6 new), 0 failures, assertions on (7 skipped) and off (8 skipped);
:lucene:facet:check -x test(google-java-format, ecjLint, forbiddenApis) passes. - Standalone runner with the patched class: the new test (on and off), the finder's JUnit (3 of 3), the independent reproducer's (5 of 5) and the follow-up's 13-test probe, merge cases included, pass.
Throw IllegalArgumentException in addCategory when a component has an unpaired surrogate (+23 lines in DirectoryTaxonomyWriter.java).
Trade-offs
A behaviour change: documents with such labels now fail in FacetsConfig.build, so applications that index them today must clean labels first. Matches BytesRef's precondition and the first view in the #15900 review (half surrogates from char truncation are the caller's concern). Rejecting in FacetField or FacetLabel instead would also hit SSDV facets and reader-side lookups, which work today (not run).
What the checks validated
The new test passes 6 of 6, the 66 closest-suite tests and the whole facet module (312 tests, assertions on) pass, and check -x test passes. The finder's JUnit fails 1 of 3 with it: its facet test does not expect the exception.
Normalize inside the LRU cache's key (for example NameIntCacheLRU.key). Not run.
Trade-offs
Fixes only the built-in cache; a custom TaxonomyWriterCache would still disagree with the index.
Map each document of a term to the new ordinal (DirectoryTaxonomyWriter.java:717-721), so merging a damaged taxonomy repairs it instead of dropping values or throwing EOFException. Not run.
Trade-offs
Does not prevent the duplicate; helps taxonomies already damaged.
Read-only code searches of Elasticsearch, OpenSearch and Solr found no direct use of DirectoryTaxonomyWriter (indirect or plugin use is not ruled out), so the known exposure is custom applications that build taxonomy facets from user-supplied text such as tags.
Code reading of the writer's cache fill while modelling the taxonomy writer cache in TLA+; the model treats labels as atoms and did not witness it. A bounded-exhaustive check of label-to-term round trips then showed which labels change, and the finder reduced it to a JUnit on the stock jars.
The method in full156 words
Method: code reading, then a bounded-exhaustive check (the study's "non-formal" tier), in a hunt unit on concurrent adds to the taxonomy writer.
- While writing a TLA+ model of
DirectoryTaxonomyWriter's cache, the finder readperhapsFillCacheand saw that the refilled keys come from decoded index terms. The model treats labels as atoms, so it cannot and did not witness this bug. - A bounded-exhaustive check on the stock jar enumerated all 66,822 labels of 1-2 components of 1-3 chars over {
a, U+D83D, U+DE00, U+FFFD, U+001F, U+001E}: label -> term -> label changes exactly the 58,080 ill-formed labels, and no two well-formed labels share a term. It characterizes the lossy mapping, not the duplicate ordinal itself. - The finder then wrote a JUnit on the stock jars (facet counts through the public
FacetFieldAPI), and an independent reproducer, reviewers from another model family (OpenAI GPT-5.6, reading only), a devil's advocate, an adjudication and an audit checked it.
No prior report found (2026-10-26): GitHub issues and PRs, JIRA, four mailing lists, downstream projects, the web and all 409 open PRs. #12092 / #12093 changed the default cache without discussing label identity; #15899 shows the same U+FFFD collapse in a token filter.
Searches3 searches
Verdict new. The nearest items changed the default cache, fixed other cache-key bugs, or show the same U+FFFD collapse elsewhere; none describes a taxonomy label getting two ordinals.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories; the web | 2026-10-26 | two runs of a scripted prior-report search (78 queries, then 24 list and JIRA queries), the finder's and the devil's advocate's runs (43 and 32), about 38 manual GitHub searches | no report; related #12092, #12093, #12000, #12013, #9024 (LUCENE-7975), #8942 (LUCENE-7891), #9427 (LUCENE-8380), #15899 / #15900, #1588 (LUCENE-510) |
| JIRA archive, dev@, java-user@, issues@, commits@ | 2026-10-26 | the tool's list and JIRA queries plus 39 direct list and 7 JQL searches; nine JIRA issues read | no report |
| Open apache/lucene PRs and git history | 2026-10-26 | all 409 open PRs with their changed files; git log -S surrogate and -S FFFD over the facet module | #16847 and #12862 touch the files but not label identity; no facet commit ever mentions surrogates or U+FFFD |
Present since the facet module (3.4.0, LUCENE-3079, 2011). Masked by accident in 7.1.0 by a UTF-8-keyed default cache (LUCENE-7975) and exposed again in 9.5.0 when #12093 restored a string-keyed default. Affects 9.5.0 to 10.5.2 and main by default; never fixed.
Versions tested5 rows
Origin: LUCENE-3079 "add faceting module" (d4e1a420d52 on branch_3x, trunk port 4291f52c70d, 2011-06-29): the cache keyed by label chars, refilled from decoded index terms and then marked complete. Masked in 7.1.0 by LUCENE-7975 (6cee162e195 / a9fb4ddf80f, 2017-10-03), a speed and memory change whose UTF8TaxonomyWriterCache keyed by the same UTF-8 bytes as the index. Exposed again in 9.5.0 by #12093 "Deprecate support for UTF8TaxonomyWriterCache" (9d6173148d7, 2023-01-18) and on main by #12092 (dc33ade76d3, first released in 10.0.0), which made LruTaxonomyWriterCache(4000) the default because of a ThreadLocal leak. In 3.x the on-disk lookup also compared Java strings, so the duplicate appeared without a fill. Not fixed: DirectoryTaxonomyWriter.java is the same blob in 10.0.0, 10.5.2 and a9779ef3c193.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test fails 4 of 6 (gradle and standalone, assertions on and off); passes 6 of 6 with either fix |
| 9.5.0, 9.12.3, 10.5.2 | affected | default cache: the finder's test fails 3 of 3; 10.5.2 also this doc's test, 4 of 6 |
| 7.1.0, 8.11.4, 9.4.2 | explicit LRU cache only | pass with the default UTF-8-keyed cache; with an explicit LruTaxonomyWriterCache(4000), 8.11.4 and 9.4.2 fail (7.1.0 not run that way) |
| 3.4.0, 4.0.0, 4.6.1, 4.7.0, 7.0.1 | affected | default cache (char-keyed): fail. 4.7.0 ran the finder's test; 4.6.1 a CategoryPath port of its two writer checks; 4.0.0 and 3.4.0 main() ports (3.4.0 has LuceneTaxonomyWriter, whose reader returns -1 for the label); 3.4.0 fails even without a cache fill |
normalizing fix (scratch worktree at a9779ef3c193) | not affected | 6 of 6; facet module 312 tests, 0 failures |
Confirmed by an independent reproducer, a devil's advocate, an adjudication and an audit; a reviewer from another model family (OpenAI GPT-5.6, reading only) called it real. The refute-lens review said "not real" with low confidence, procedurally, because it could not run code. This doc's test and both fixes were re-run with gradle on main.
Checks and verdicts280 words
Each executing check ran its own or the finder's test on the stock jars; the controls pass everywhere.
| Check | Verdict | What it found |
|---|---|---|
| independent reproducer | real | Own 5-test JUnit from the claim alone: 3 fail on main (assertions on and off), 10.5.2, 9.12.3 and 9.5.0; 9.4.2 and the fix pass; a well-formed pair and a re-add before the fill keep their ordinals. |
| cross-model review, refute lens | not real, low (procedural) | Read the code only and could not reproduce; agreed on the root cause and that the inputs are in contract. Its objection (internal FacetLabel, BytesRef precondition) led to the facet-count test through the public FacetField API. |
| cross-model review, intended lens | real, medium; intended argument weak | Read the code only; root cause agrees, the fix fixes it. A separate run re-ran the finder's JUnit (3 of 3 fail) and the fix (3 of 3 pass). |
| devil's advocate | real; not intended | Every not-a-bug argument fails on documented core semantics; controls (SSDV facets, a well-formed pair, drill-down) pass; reach probe: with 11 and 3,990 filler labels the label is duplicated, with 4,100 and 20,000 it is not. |
| adjudication | confirmed, high | Re-ran the independent reproduction's JUnit on main with assertions on and off: 3 of 5 fail, controls pass. |
| registry re-runs and audit | keep | Fresh seeds on main: the finder's JUnit fails 3 of 3 with assertions on and off; class data corruption kept. |
| this doc's runs | reproduced; two fixes validated | New 6-test JUnit: 4 fail on main (gradle and standalone) and 10.5.2, assertions on and off; the normalizing and the rejecting fix each pass it and the facet module. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 583 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,578 words
- Registry title
- DirectoryTaxonomyWriter indexes a facet label that contains an unpaired surrogate a second time, under a new ordinal, once its writer cache has been filled from the taxonomy index, because the cache compares the label's Java string while the index stores its UTF-8 term with the surrogate replaced by U+FFFD; the taxonomy then holds two categories with one path and facet counts for that value are split
- Area
- facet / taxonomy writer (DirectoryTaxonomyWriter category identity: writer cache key vs taxonomy index term, perhapsFillCache)
- Priority
- Low, rank 332: Default taxonomy writer, but only malformed labels with an unpaired surrogate reach it, and maintainers may prefer to reject such labels.
- Impact class
- data corruption
- Impact note
- Applications that index taxonomy facets with the default DirectoryTaxonomyWriter and writer cache (LruTaxonomyWriterCache(4000) from 9.5.0, Cl2oTaxonomyWriterCache in 3.4.0-7.0.1; in 7.1.0-9.4.2 only with an explicitly configured LruTaxonomyWriterCache), default IndexWriterConfig, codec and Directory, -ea and -da, are hit when a facet label contains an unpaired surrogate (a value cut inside an emoji, or a decoded JSON \uD83D escape) and is added again in a later writer session after that session has filled its cache from the index (by default after 11 cache misses) while the taxonomy still fits in the cache (from 9.5.0: 11 and 3,990 categories duplicate, 4,100 and 20,000 do not), or when two labels with the same stored form are added while the cache counts as complete: commit() persists a second category document for one taxonomy term (CheckIndex calls it clean, categories are never deleted), facet counts for that value are split across two entries with the same label, lookups by label resolve only to the first copy, and a later TaxonomyMergeUtils.merge drops the value from the documents on the duplicate (MemoryOrdinalMap) or throws EOFException (DiskOrdinalMap); no scale is needed, search hits and drill-down stay correct, and well-formed labels are never affected.
- Summary
- You add a facet value with an unpaired surrogate, for example FacetField("dim", "x\uD83D") built from a string cut inside an emoji, in one writer session and the same value again in a later session, with the default DirectoryTaxonomyWriter; you expect the existing ordinal back, as TaxonomyWriter.addCategory promises, and one facet entry with count 2. Instead, once the second session has filled its cache from the index (after 11 new categories by default), the cached key is the stored form "x\uFFFD", the original string misses, the writer trusts its now complete cache and indexes the label again (ordinal 14 instead of 2), so the facet result shows x\uFFFD (1) twice. The duplicate stays in the taxonomy for good; within one fresh session the writer likewise gives "x\uD83D" and "x\uFFFD" ordinals 2 and 3, although the taxonomy reader resolves both to 2.
- Introduced
- d4e1a420d52 (LUCENE-3079 'add faceting module', branch_3x; trunk port 4291f52c70d the same day; JIRA, no PR) [read: git blame on main traces cache.get(categoryPath) (DirectoryTaxonomyWriter.java:385) and the perhapsFillCache loop (:625-635) to it; later commits only reworked the logic (LUCENE-4061 1db88a8665d, LUCENE-5339 5edc798fda3); exec: 3.4.0, the first release with the facet module, fails]. The default configuration was masked in 7.1.0-9.4.2 by LUCENE-7975 (6cee162e195 on branch_7x, a9fb4ddf80f on master; default UTF8TaxonomyWriterCache keyed by the U+FFFD-replaced UTF-8 bytes; incidental, its discussion is about speed and memory) and exposed again by #12093 'Deprecate support for UTF8TaxonomyWriterCache' (9d6173148d7, branch_9x, first released in 9.5.0; main twin #12092 dc33ade76d3, first released in 10.0.0; default LruTaxonomyWriterCache(4000) keyed by FacetLabel; motivated by the ThreadLocal leak #12000, no discussion of label identity) [read: git log -S defaultTaxonomyWriterCache, git tag --contains; exec: 7.0.1 fails, 7.1.0 and 9.4.2 pass, 9.5.0 fails]. So 9.5.0 is a regression of the default configuration, not the origin (2011-06-29 (LUCENE-3079); default configuration masked 2017-10-03 (LUCENE-7975, 7.1.0) and exposed again 2023-01-18 (#12093 / #12092, 9.5.0))
- First affected version
- 3.4.0 [exec] (the first release with the facet module; 3.3 has none)
- Affected versions
- Default configuration: 3.4.0-7.0.1 and 9.5.0-10.5.2 and main ea57360912ed; 7.1.0-9.4.2 only with an explicitly configured LruTaxonomyWriterCache. [exec] the finder's JUnit (or a faithful port for the older APIs) fails on 3.4.0, 4.0.0, 4.6.1, 4.7.0, 7.0.1, 9.5.0, 9.12.3, 10.5.2 and main (-ea and -da); passes with the default cache on 7.1.0, 8.11.4 and 9.4.2 (also 8.11.2 and 9.0.0 with the earlier 2-test version); fails with an explicit LruTaxonomyWriterCache(4000) on 7.0.1, 8.11.4 and 9.4.2 (and 8.11.2); the independent reproduction's JUnit fails on main, 10.5.2, 9.12.3 and 9.5.0 and passes on 9.4.2. [read] the other releases from git tag --contains and unchanged code. 3.x is wider: its on-disk lookup and reader compare Java strings, so the duplicate appears without a cache fill and the reader returns -1 for the ill-formed label (3.4.0 no-fill control fails; 4.0.0 and 4.6.1 no-fill controls pass). Reach by era [read, not executed at scale]: Cl2oTaxonomyWriterCache.isFull() is always false, so in 3.4.0-7.0.1 the cross-session duplicate should occur at any taxonomy size; from 9.5.0 only while the taxonomy fits in the 4000-entry cache (the intended-behaviour check reach probe, executed). Not fixed upstream: no commit on the affected files after ea57360912ed. All runs on aarch64 Linux with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record verdict new): scripted prior-report search d1 (78 queries: 30 GitHub issue/PR, 3 commit, 5 downstream (Elasticsearch, OpenSearch, Solr), 28 mailing-list over dev@, java-user@, issues@ and commits@, 6 JIRA, 6 web; 365 distinct hits, 0 high) and run d2 (24 list and JIRA queries, 351 hits, 0 high), plus the finder's run (43 queries, 95 hits) and the intended-behaviour check's (32 queries, 248 hits), all four scanned for facet/taxonomy together with surrogate/U+FFFD/replacement character (0 hits); about 30 manual GitHub searches; all 409 open apache/lucene PRs (only #16847 and #12862 touch the affected files; diffs read, neither changes label identity); upstream commits on the affected files after ea57360912ed: none; git log -S 'surrogate' and -S 'FFFD' over the facet module's history: no commit ever; CHANGES.txt and MIGRATE.md. Related, not reports: #12092 / #12093 (made the default cache key labels by Java string in 9.5.0; no identity discussion), #12013 / #12000 (the ThreadLocal leak behind them), #9024 LUCENE-7975 (the UTF-8-keyed default, 7.1), #8942 LUCENE-7891 (a different cache-key identity bug, LRU_HASHED hash collisions), #9427 LUCENE-8380 (an offset bug in the removed UTF-8 cache), #15899 / #15900 (the same U+FFFD collapse mechanism in TruncateTokenFilter, fixed in 10.5.0; taxonomy not mentioned), #1588 LUCENE-510 (introduced the documented U+FFFD replacement). Not fixed upstream.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) with gradle in a scratch worktree and with the standalone JUnit runner, assertions on and off; the 10.5.2 release jars (this doc's test). The hunt, the independent checks and the registry re-runs ran on mainea57360912ed, whose facet module and the core files involved are byte-identical, and the follow-up's history runs on 3.4.0, 4.0.0, 4.6.1, 4.7.0, 7.0.1, 7.1.0, 8.11.4, 9.4.2, 9.5.0, 9.12.3 and 10.5.2. Both fix options were validated in the scratch worktree: the new test, the closest suites (66 tests) and the whole facet module (312 tests), plus the module's format, ecjLint and forbiddenApis checks.
- Finding record
lucene/facet/src/java/org/apache/lucene/facet/taxonomy/directory/DirectoryTaxonomyWriter.java:89 (DEFAULT_CACHE_SIZE = 4000), :101 (cacheMissesUntilFill = 11), :181-182 (a new taxonomy starts with cacheIsComplete = true), :273-276 (default LruTaxonomyWriterCache), :323-350 (findCategory returns the cache answer when the cache is complete), :354-357 (term lookup by new BytesRef(pathToString(...))), :380-401 (addCategory: cache.get(categoryPath)), :457-463 (addCategoryDocument stores the UTF-8 form), :603-662 (perhapsFillCache: keys from t.utf8ToString(), 'each term has exactly one document', cacheIsComplete = !aborted) at ea57360912edlucene/facet/src/java/org/apache/lucene/facet/taxonomy/writercache/NameIntCacheLRU.java:71-74 (key = the FacetLabel) and LruTaxonomyWriterCache.java:41 (LRU_STRING 'this is always correct') at ea57360912edlucene/facet/src/java/org/apache/lucene/facet/taxonomy/TaxonomyWriter.java:52-53 ('If the category was already present in the taxonomy, its existing ordinal is returned.'); FacetField.java:64-73 (verifyLabel: null or empty only); FacetLabel.java:81-99 (checkComponents: null, empty, length only) at ea57360912edlucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1483-1485 (malformed surrogate pairs 'silently replaced with the Unicode replacement character U+FFFD'); lucene/core/src/java/org/apache/lucene/util/BytesRef.java:74-77 (BytesRef(CharSequence) 'must be well-formed unicode text, with no unpaired surrogates') at ea57360912ed
- The finding in 30 seconds
a Lucene main checkout (a9779ef3c193) lucene/facet/src/java/org/apache/lucene/facet/taxonomy/directory/DirectoryTaxonomyWriter.java:89, :101, :181-182, :273-276, :326-329, :331, :354-357, :385, :397, :452-482, :604-662, :717-721, :743-746, :770-784a Lucene main checkout (a9779ef3c193) lucene/facet/src/java/org/apache/lucene/facet/taxonomy/writercache/NameIntCacheLRU.java:71-74; FacetLabel.java:122-139; TaxonomyReader.java:33-35; directory/DirectoryTaxonomyReader.java:299-306a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1483-1485; util/UnicodeUtil.java:231-235a Lucene main checkout (a9779ef3c193) DirectoryTaxonomyWriter.java:484-492 (addToCache: an eviction sets cacheIsComplete = false); writercache/LruTaxonomyWriterCache.java:74-75 (isFull)
- Who is affected
a Lucene main checkout (a9779ef3c193) lucene/facet/src/java/org/apache/lucene/facet/FacetField.java:64-73; taxonomy/FacetLabel.java:81-100
- Why it looks unintended
a Lucene main checkout (a9779ef3c193) lucene/facet/src/java/org/apache/lucene/facet/taxonomy/TaxonomyWriter.java:52-53; directory/DirectoryTaxonomyWriter.java:366, :628-632; writercache/LruTaxonomyWriterCache.java:41a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1483-1485; util/BytesRef.java:74-79; core test TestIndexWriterUnicode.java:245a Lucene main checkout (a9779ef3c193) lucene/facet/src/test/org/apache/lucene/facet/taxonomy/TestTaxonomyCombined.java:190-242github.com/apache/lucene/pull/15900 conversation (2026-04-02T08:28Z: half surrogates from char truncation "expected"); merged as b858e81d1be (first tag 10.5.0), TruncateTokenFilter.truncateAfterCodePoints, deprecated char-only constructor
- History
a Lucene clone (git tag --contains 9d6173148d7: 9.5.0; dc33ade76d3: 10.0.0; DirectoryTaxonomyWriter.java blob bd4934fbb04 in 10.0.0, 10.5.2, a9779ef3c193)
- TestTaxonomyUnpairedSurrogateLabel.java (JUnit test):
repro/LFV-541/src/org/apache/lucene/facet/taxonomy/directory/TestTaxonomyUnpairedSurrogateLabel.java(42 lines)
A step-by-step picture made in parallel with this doc from an executed probe of the same two-session scenario on main a9779ef3c193 (stock and with the normalizing fix, assertions on and off).
assets/LFV-541/bug.png(583 KB)