A filter that removes tokens records the positions it skipped at the end of the stream, in end(), so the next value of the field starts after them. ConditionalTokenFilter loses that number when the last token went through its wrapped filters.
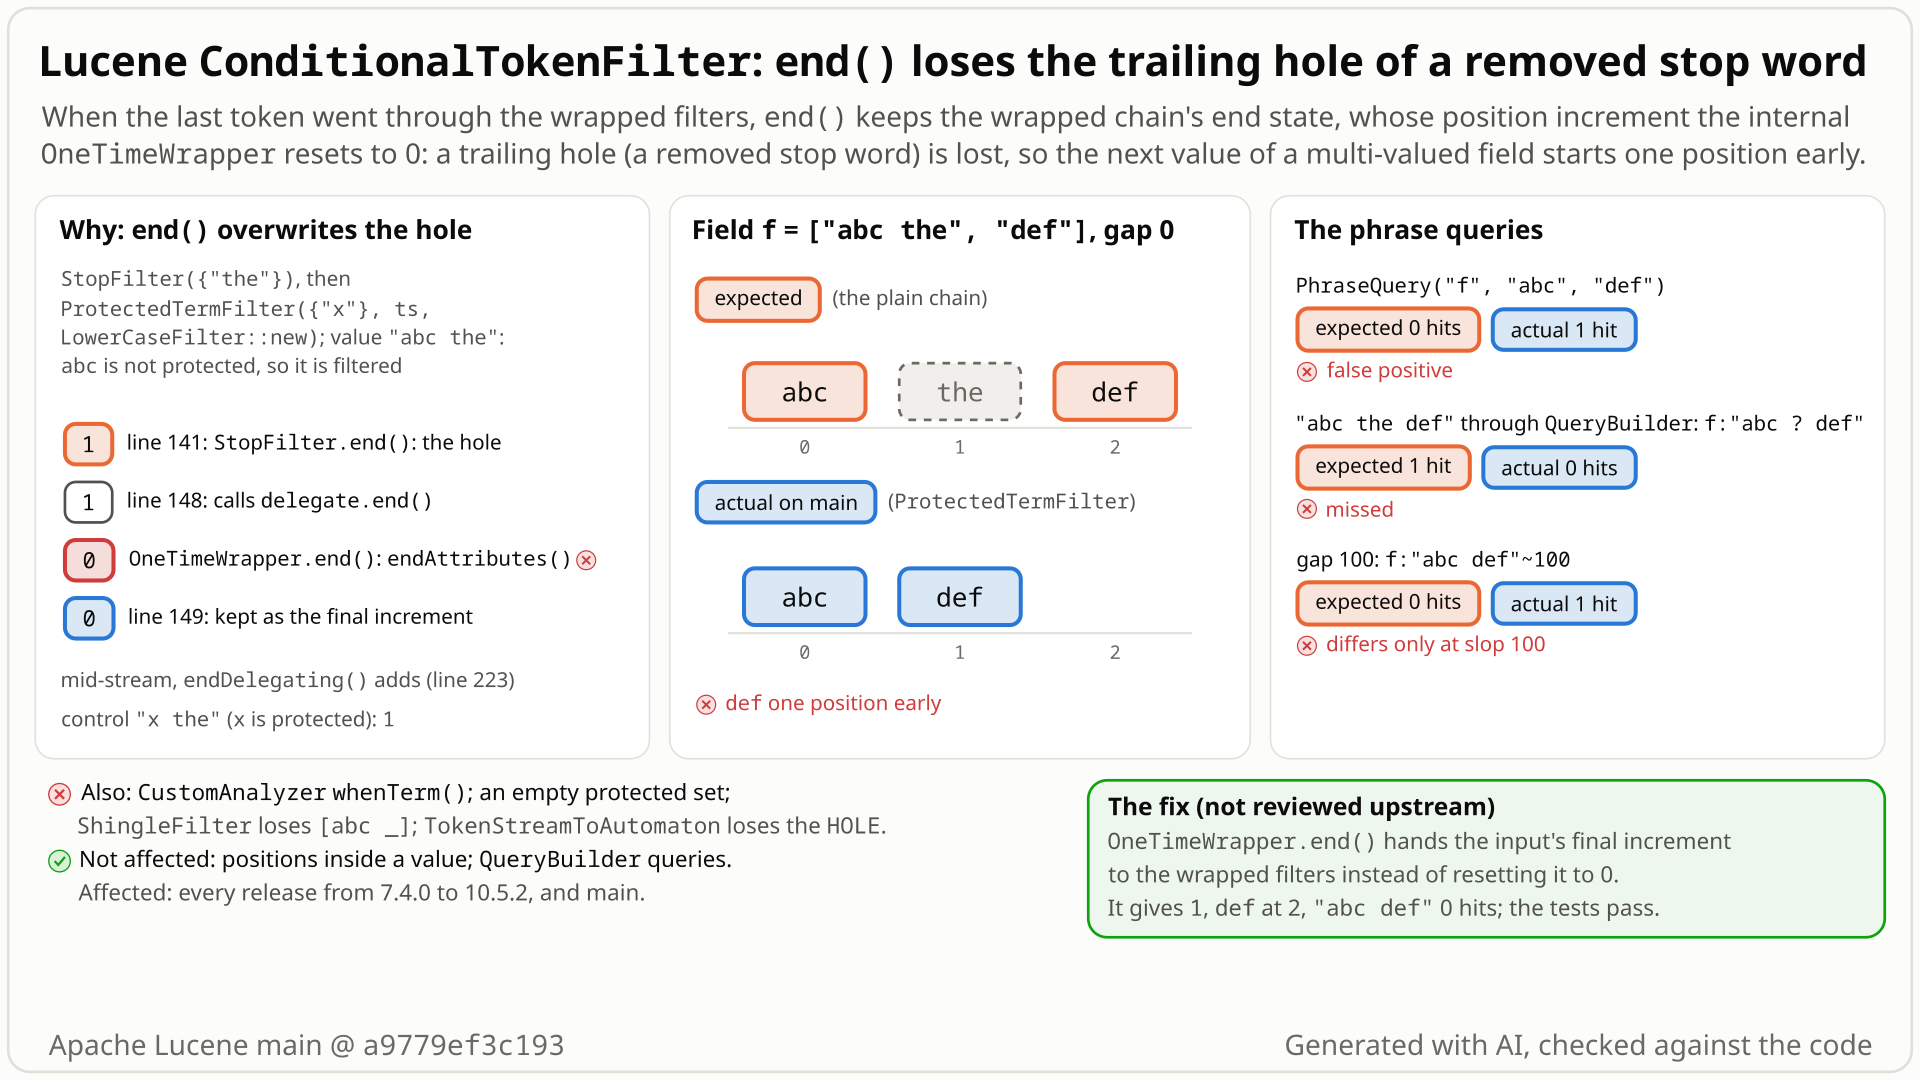
end() overwrites the hole, the positions of the field values abc the and def with and without the condition, and what the phrase queries then match. Select the still to open it at full size. Generated with AI, checked against the code.- You analyse text with
WhitespaceTokenizer, thenStopFilter({"the"}), then aProtectedTermFilteraroundLowerCaseFilter(or theCustomAnalyzerchainstop,whenTerm(...),lowercase,endwhen()).ABC thegives the tokenabc; the removedtheleaves a hole of 1 position at the end. - You expect
end()to report that hole as a final position increment of 1, as the same chain without the condition does, and asProtectedTermFilterdoes when the last word is protected (x the: 1). - You get 0 whenever the last token went through
LowerCaseFilter, which never touches positions. Even a condition around a filter that does nothing (in -> in) gives 0;abc the thegives 0 instead of 2. - With Lucene's default position increment gap of 0, the field values
abc theanddefputdefat position 1 instead of 2, andPhraseQuery("f", "abc", "def")finds the document: 1 hit instead of 0. - Why: the wrapped filters read from an internal stream whose
end()imitates a tokenizer and resets the increment to 0, andend()keeps their result instead of adding the input's increment. In the middle of the stream the class does add it.
Users of ProtectedTermFilter (or its protectedTerm factory), CustomAnalyzer when()/whenTerm(), or another ConditionalTokenFilter placed after a StopFilter. Values ending in a removed word shift the next value of a multi-valued field, so cross-value phrase queries over- or under-match; token automata and downstream shingles lose the hole too. Opt-in, deterministic, any index size.
Mechanism, terms and numbers816 words
A StopFilter that removes a value's last word records the gap in end(): abc the gives the token abc and a final position increment of 1, so the next value of the same field starts one position later. Put a ConditionalTokenFilter after it (ProtectedTermFilter, or a CustomAnalyzer when()/whenTerm() branch) and that 1 becomes 0 whenever the last token went through the wrapped filters, even when they never touch positions (LowerCaseFilter, or in -> in). The cause: end() keeps the wrapped chain's end state, and that chain ends on the internal OneTimeWrapper, whose end() imitates a tokenizer, resets the increment to 0 and restores only the final offset. In the middle of the stream the same class adds the wrapped filters' end increment instead. With the default gap of 0, the multi-valued field ['abc the', 'def'] indexes def at position 1 instead of 2 and the phrase "abc def" matches (1 hit instead of 0); TokenStreamToAutomaton and a downstream ShingleFilter lose the trailing hole too. It fails on all ten versions run, from 7.4.0 (2018, the class's first release) to 10.5.2 and main, and the file's history shows no release in between with a different end-of-stream path. Handing the input's final increment to the wrapped filters (a few lines in the class) fixes it; the recommended fix also covers a related end-of-stream case (a removed stacked last token adds a position), and the analysis module's tests and TestRandomChains pass with it.
- Trailing hole:
StopFilteronabc theemitsabcand, inend(), a final position increment of 1 for the removedthe(FilteringTokenFilter.java:72-75;TokenStream.java:152-154). - Conditional filter:
ConditionalTokenFiltersends each token through some wrapped filters only ifshouldFilter()is true.ProtectedTermFilterdoes that for every token that is not in its protected set (ProtectedTermFilter.java:51-54);CustomAnalyzer'swhen()andwhenTerm()build one. - Who reads the final increment:
IndexingChainadds it to the field position before the next value of the same field (IndexingChain.java:2105-2109, then the gap at:2122; the default gap is 0,Analyzer.java:296-311).TokenStreamToAutomatonturns it into trailing HOLE arcs (TokenStreamToAutomaton.java:212-239),ShingleFilterinto trailing filler shingles (:379-382).
- The wrapped filters are built on an internal stream,
OneTimeWrapper, over the same attributes as the input (ConditionalTokenFilter.java:119). OneTimeWrapper.end()"imitate[s] Tokenizer.end()": it callsendAttributes(), which sets the position increment to 0 (PackedTokenAttributeImpl.java:183-186, the default implementation), and puts back only the final offset (:84-95).ConditionalTokenFilter.end()first captures the input's end state (increment 1), then, if the last token was filtered, callsdelegate.end()and keeps that state (:139-151). The 1 is overwritten with 0, not added.- In the middle of the stream,
endDelegating()adds the wrapped filters' end increment to the next token's own increment (:213-230, the addition at:223). So holes in the middle survive, and so does a trailing hole the wrapped filters make themselves; the trailing hole of the input is lost, and only when the last token was filtered. - Related, the other way round. A stacked token (increment 0) that goes to the wrapped filters is handed to them with an increment of 1 (
:56-60); mid-stream the class takes that 1 back (:188-192,:224-227), at the end of the stream it does not. So when the wrapped filters remove a stacked last token, aStopFilteramong them reports one position too many: tokensx/1,a/0, a condition only foraaroundStopFilter({"a"})give a final increment of 1 instead of 0; also with public API only (SynonymGraphFilterx->akeeping the original, thenProtectedTermFilter({a}, StopFilter({"x"}))). Found by the cross-model fact check of this doc and executed on main; the recommended fix covers it.
input and chain (after StopFilter({"the"})) | plain chain | conditional |
|---|---|---|
abc the, condition always true around in -> in | 1 | 0 |
ABC the, ProtectedTermFilter({x}, LowerCaseFilter) | 1 | 0 |
ABC the, ProtectedTermFilter(empty set, LowerCaseFilter) | 1 | 0 |
x the, same, last token protected | 1 | 1 |
abc the the, in -> in | 2 | 0 |
abc a the, condition around StopFilter({"a"}) | 2 | 1 |
abc the def (hole in the middle) | def +2, end 0 | def +2, end 0 |
ShingleFilter(2,2) after ProtectedTermFilter(empty set, LowerCaseFilter), abc the | abc, abc _ | abc |
"Plain chain" is the same chain without the condition. The hunt's verifiers also executed TokenStreamToAutomaton on abc the (abc instead of abc + POS_SEP + HOLE) and 200,000 trailing stop words (0 instead of 200,000).
Only the position increment and the final offset were examined: OneTimeWrapper.end() resets every attribute and puts back only the offset, so a custom attribute with its own end-of-stream state would not reach the wrapped filters either (not tested; no fix here changes that).
Exposure and likelihood413 words
- Who is exposed. Applications that put a
ConditionalTokenFilterbehind a filter that leaves a trailing hole (typicallyStopFilter):ProtectedTermFilter/ProtectedTermFilterFactory(SPI nameprotectedTerm),CustomAnalyzerwhen()/whenTerm()branches, andConditionalTokenFilterFactorysubclasses. No stock Lucene analyzer uses the class, so it is opt-in. - What it takes. A value that ends in a removed token right after a token that went through the wrapped filters; for
ProtectedTermFilter, any value ending in a stop word whose previous word is not protected. - What changes. The next value of a multi-valued field starts one position early per lost hole. With the default gap 0, a cross-value phrase query over-matches (
"abc def": 1 hit instead of 0) or misses (the phrase built forabc the def,f:"abc ? def", no longer matches the valuesabc the|def); both directions executed withPhraseQuery. Span and interval queries read the same positions, so they can do the same (by code reading; not run). - Token automata and shingles.
TokenStreamToAutomatonwith its default settings and aShingleFilterinside or after the condition lose the trailing hole, also on a single value (so a shingle field's terms change). What a suggester sees depends on its settings:AnalyzingSuggesterturns onfinalOffsetGapAsHole(AnalyzingSuggester.java:317-321), which can hide a single lost hole such asabc the's. No suggester was run end to end. - What does not change. For a chain where nothing inside or after the condition reads the final increment (
LowerCaseFilter,in -> in): terms, offsets and positions inside a value (executed), and, by code reading, a single-valued field's index content, since the final increment only moves where a next value starts. Also: the queriesQueryBuilderandIntervals.analyzedTextbuild,MemoryIndex, andCheckIndex(clean). With a gap of 100, as common search servers configure, a cross-value phrase result changes only at slop 100 for one lost hole and 100-101 for two (executed over slops 0-250). - Not assessed end to end. Other readers of the final increment, such as
FreeTextSuggester.lookup()and highlighters that re-analyse multi-valued fields. - Scale and versions. Deterministic, any index size, no error. Fails on every version run (ten, from 7.4.0 to 10.5.2, and main); by the file's history every release in between is affected too.
- How likely. Rare: the wrong number is common, but it shows only with a small gap and a cross-value positional query, or a shingle or suggester consumer; nobody has reported it since 2018.
The test shows that ConditionalTokenFilter.end() drops its input's trailing hole (a removed trailing stop word) when the last token went through the wrapped filters, even when the wrapped filter is the identity in -> in.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import java.io.IOException;
import java.io.StringReader;
import java.util.List;
import org.apache.lucene.analysis.CharArraySet;
import org.apache.lucene.analysis.StopFilter;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestConditionalTokenFilterEndPositionIncrement extends BaseTokenStreamTestCase {

  public void testTrailingHoleKeptThroughIdentityDelegate() throws IOException {
    Tokenizer tokenizer = new WhitespaceTokenizer();
    tokenizer.setReader(new StringReader("abc the"));
    TokenStream stop = new StopFilter(tokenizer, new CharArraySet(List.of("the"), false));
    TokenStream ts =
        new ConditionalTokenFilter(stop, in -> in) {
          @Override
          protected boolean shouldFilter() {
            return true;
          }
        };
    // expected final position increment 1 (the removed "the", as StopFilter alone reports); was 0
    assertTokenStreamContents(
        ts, new String[] {"abc"}, null, null, null, null, null, null, 1, null, true, null);
  }
}
# in a copy of this finding's repro folder (repro/LFV-542/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestConditionalTokenFilterEndPositionIncrement
- Expected vs actual
- Expected the final position increment 1 that
StopFilterreports forabc the; actual 0 (finalPosInc expected:<1> but was:<0>), with-eaand-da.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: finalPosInc expected:<1> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:436)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:544)
org.apache.lucene.analysis.miscellaneous.TestConditionalTokenFilterEndPositionIncrement.testTrailingHoleKeptThroughIdentityDelegate(TestConditionalTokenFilterEndPositionIncrement.java:43)TokenStream#endnames stop-filter holes as what the final increment carries; components "must put accurate values" at the end of the field.- A condition around a do-nothing filter, or a
ProtectedTermFilterprotecting nothing, turns 1 into 0; with the last word protected it stays 1. - Mid-stream the class adds the wrapped filters' end increment; only this branch drops it.
The full argument335 words
- The contract.
TokenStream#end: "any skipped positions (such as those removed by a stopfilter) can be applied to the position increment" (TokenStream.java:152-154). The core analysis package docs, "End of Input Cleanup": components "must put accurate values into the token attributes to reflect the situation at the end of the field" (package-info.java:276-281). LUCENE-3849 madeend()carry the increment "so we can handle trailing holes" (lucene/CHANGES.txt:13337-13340). - The class's own promise. "If it returns false, then the wrapped filter(s) will be skipped" (
ConditionalTokenFilter.java:31-33);CustomAnalyzer.when(): the conditional filters "will only be used if the current token matches the condition" (CustomAnalyzer.java:463-465). So a condition aroundin -> inshould change nothing, andProtectedTermFilterwith nothing protected should equal its wrapped filter. Only the final increment differs (1 vs 0). - It flips with the last token. The same chain gives 1 when the last token is protected and 0 when it is not, although
LowerCaseFilternever touches positions. - The class adds mid-stream (
endDelegating(),:223); the end of the stream has no such addition. - Stated intent, kept mid-stream only. The LUCENE-8360 report (#9407, 2018) says the bug was found through this class, "which calls end() on its delegate when it reaches a token that shouldn't have the delegate applied to it, so that things like position increments and position length are preserved". That is the mid-stream path (
endDelegating()), which keeps the promise by adding; the end of the stream, where this bug is, does not. LUCENE-8376/8371 (7.5.0 Bug Fixes) already treated wrongend()propagation in this class as a bug, and fixedFixedShingleFilter, which "did not set position increment in end()" (lucene/CHANGES.txt:7198-7200). - Nothing pins the current value. No upstream test asserts a final increment on any conditional path;
testEndPropagationasserts final offsets only (18 and 20,TestConditionalTokenFilter.java:174-197). The generic check that would have caught it (LUCENE-8361, #9408) was never committed. With fix B the 44 tests of the four closest suites pass.
The devil's-advocate check214 words
The checkers built the strongest case for "intended": (a) TokenStream#end says skipped positions "can" be applied, not "must"; (b) OneTimeWrapper imitates Tokenizer.end() on purpose, and the package docs say "The base method TokenStream#end() sets PositionIncrement to 0, which is required" (package-info.java:283-284); (c) the wrapped chain's end state wins on purpose when the last token was filtered, and testEndPropagation pins that (final offset 18 instead of 20); (d) nobody has reported it since 7.4.0, although TestRandomChains wraps random filters in conditions.
Why it fails: (a) the same package docs require accurate values at the end of the field, and the class javadoc promises that the wrapped filters are skipped or applied, not that the stream's end changes. (b) The "0, which is required" sentence is the base method's starting value; each filter then adds its own, as FilteringTokenFilter.end() does. A tokenizer has nothing upstream; OneTimeWrapper does, and it passes the input's final offset on but not its increment. (c) In testEndPropagation the wrapped filter saw the input's real final offset and changed it; it never sees the input's increment, so "the wrapped chain wins" becomes "the input's hole is erased". (d) Nothing checks the final increment on these paths. The adjudication names (a) as the main risk. Every checker rejected the works-as-designed case.
Recommended B+. Fix B, plus taking back the extra position of a removed stacked last token
Let the wrapped filters see the input's real end: once the input is exhausted, OneTimeWrapper.end() keeps the input's final position increment instead of 0, and end() no longer re-captures endState. Fix B+ also takes back the extra position of a removed stacked last token. The new tests, all analysis-module tests, TestRandomChains and check pass.
All options and trade-offs4 options · 1,458 words
Fixes A, B and B+ were applied in scratch worktrees of main a9779ef3c193 and run through gradle with assertions on and off. A probe ran 21 chains, 8 plain and 13 conditional (two of them controls in which the wrapped filters never see the last token: x the with x protected, and the alone): stock main differs from the plain chain in 8 of the 13 conditional runs, fix A in 1, fixes B and B+ in none, the hunt's sketch in 2. A second probe covers the related stacked last token: of its 9 conditional runs, stock main differs in 4, fixes A and B in 5, fix B+ in none.
B+. Fix B, plus taking back the extra position of a removed stacked last token (validated by the checks) (recommended)
Fix B (next option) for the reported bug. For the related case: a stacked token (increment 0) that goes to the wrapped filters is handed to them with an increment of 1 (ConditionalTokenFilter.java:56-60); mid-stream the class takes it back (:188-192, :224-227), at the end of the stream it did not. When adjustPosition is still set at the end, end() now takes the extra position back after delegate.end(); Math.max(0, ...) keeps the increment from going negative. +13/-2 lines, 7 of the added lines are comments.
New output. The 21-chain probe prints the same lines as with fix B: all 13 conditional runs equal their plain chain. The stacked-token probe: all 9 conditional runs equal their plain chain (x/1 a/0 ends with 0; with an input trailing hole 1; the public-API SynonymGraphFilter chain 0; a repeated end() 0 and 0), assertions on and off.
     public void end() throws IOException {
-      // imitate Tokenizer.end() call - endAttributes, set final offset
+      // imitate the end() of our input: ... once the input is exhausted, its final position increment
+      int finalPosInc = 0;
       if (exhausted) {
         ...
         endOffset = offsetAtt.endOffset();
+        finalPosInc = posIncAtt.getPositionIncrement();
       }
       endAttributes();
       offsetAtt.setOffset(endOffset, endOffset);
+      posIncAtt.setPositionIncrement(finalPosInc);
     }
   ...
     if (lastTokenFiltered) {
       this.delegate.end();
-      endState = captureState();
+      if (adjustPosition) {
+        // the last token was stacked (increment 0), went to the wrapped filters with an increment
+        // of 1 and they emitted nothing for it: take that position back, as endDelegating() does
+        posIncAtt.setPositionIncrement(Math.max(0, posIncAtt.getPositionIncrement() - 1));
+      }
     }
Trade-offs
- Those of fix B, plus: like the mid-stream code, it assumes the wrapped filters counted the increment of 1 they were handed for the stacked token, as
FilteringTokenFilterdoes; a wrapped filter that drops a token without counting its increment would now report one position fewer at the end (never below 0). - It changes the final increment only when a stacked last token went to the wrapped filters and they emitted nothing for it. The stacked-token test uses the test framework's
CannedTokenStream; the probe'sSynonymGraphFilterchain shows the same with public API only.
What the checks validated
- The 5 new tests, the 2 stacked-token tests and the closest upstream suites pass with assertions on and off: 51 of 51 (
TestConditionalTokenFilter12,TestProtectedTermFilter1,TestProtectedTermFilterFactory5,TestCustomAnalyzer26); with fix B the 2 stacked-token tests fail, on stock main 1 of them. - All of
:lucene:analysis:common:testwith assertions on and-Ptests.iters=4: 341 classes, 7,661 test runs, 69 skipped, 0 failures. TestRandomChains(which wraps random filters in conditional filters), 2 methods x 4 iterations: 8 runs, 0 failures.:lucene:analysis:common:check -x testpasses (google-java-format, ecjLint, forbiddenApis).- Through the repro harness: the new test 5 of 5, the finder's JUnit 5 of 5, the independent reproducer's 8 of 8 and the stacked-token test 2 of 2 (assertions on and off) pass.
B. OneTimeWrapper.end() hands the input's final position increment to the wrapped filters (validated by the checks)
When the input is exhausted, OneTimeWrapper.end() (ConditionalTokenFilter.java:84-95) keeps the input's final position increment instead of resetting it to 0; mid-stream (endDelegating(), input not exhausted) it still reports 0, so the additive path is unchanged. end() keeps the wrapped filters' state as before, which now includes the input's hole plus anything they add, and no longer re-captures endState after delegate.end() (:149), so endState stays the input's end state and a repeated end() returns the same value. +7/-2 lines, 4 of the added lines are comments.
New output. All 13 conditional chain runs of the probe equal their plain chain: abc the 1, abc the the 2, abc a the 2, the hole in the middle unchanged, a ShingleFilter after or inside the condition gives abc, abc _, and a repeated end() gives 2 and 2.
     public void end() throws IOException {
-      // imitate Tokenizer.end() call - endAttributes, set final offset
+      // imitate the end() of our input: ... once the input is exhausted, its final position increment
+      int finalPosInc = 0;
       if (exhausted) {
         ...
         endOffset = offsetAtt.endOffset();
+        finalPosInc = posIncAtt.getPositionIncrement();
       }
       endAttributes();
       offsetAtt.setOffset(endOffset, endOffset);
+      posIncAtt.setPositionIncrement(finalPosInc);
     }
   ...
     if (lastTokenFiltered) {
       this.delegate.end();
-      endState = captureState();
     }
Trade-offs
- Not covered: the related stacked last token stays wrong (
x/1a/0: 1 instead of 0), and with an input trailing hole after it fix B gives 2 instead of 1, a value stock main gets right by accident; the stacked-token test fails 2 of 2 with fix B (gradle and the harness). - The wrapped filters now see at the end of the stream what they see without the condition; one that reads the final increment (
ShingleFilter,FlattenGraphFilter) acts on the input's trailing hole as in a plain chain. - Indexed positions change only after a value whose last token was filtered and that ends in a hole; an existing index keeps the old positions until reindexed. No benchmark was run (one int read and write per
end()).
What the checks validated
- The 5 new tests and the closest upstream suites pass with assertions on and off: 49 of 49 (
TestConditionalTokenFilter12,TestProtectedTermFilter1,TestProtectedTermFilterFactory5,TestCustomAnalyzer26); stock: the 5 new tests fail. - All of
:lucene:analysis:common:testwith assertions on and-Ptests.iters=4: 340 classes, 7,653 test runs, 69 skipped, 0 failures. TestRandomChains(which wraps random filters in conditional filters), 2 methods x 4 iterations: 8 runs, 0 failures.:lucene:analysis:common:check -x testpasses (google-java-format, ecjLint, forbiddenApis).- Through the repro harness: the finder's JUnit 5 of 5 and the independent reproducer's 8 of 8 pass.
- The module-wide and
TestRandomChainsruns above used an earlier revision of the new test (same assertions; it differed only in the phrase assertion's message and thewhenTermpredicate); the fact check re-ran both with the final revision and a new seed (FC542B01): 340 classes, 7,653 runs and 8 runs, 0 failures. - Not covered: the related stacked-token case; its 2 tests fail with fix B (gradle and the harness).
A. Add the input's final increment after delegate.end() in ConditionalTokenFilter.end() (validated by the checks)
Read the input's final increment before delegate.end(), add it to what the wrapped filters report, and drop the re-capture of endState (+5/-1, 3 comment lines). This is the hunt's sketch plus the re-capture fix.
Trade-offs
Smaller, and keeps the "imitate Tokenizer.end()" design, but the wrapped filters still see 0 at the end: a ShingleFilter inside the condition gives abc (end 1) instead of abc, abc _. The other 12 conditional runs of the probe equal the plain chain. Like fix B, it does not cover the stacked last token (1 instead of 0; 2 instead of 1 with an input trailing hole).
What the checks validated
- The 5 new tests and the 4 closest suites pass with assertions on and off (49 of 49; with the final test revision, this doc's run with assertions on and the fact check's also with them off); all of
:lucene:analysis:common:test(-Ptests.iters=4: 340 classes, 7,653 runs, 0 failures) andTestRandomChains(8 runs, 0 failures) pass; the finder's and the reproducer's JUnit pass shadowed. check -x test: this doc's run failed only on an ecjLint error in the earlier revision of the new test (.whenTerm(t -> true), an unused lambda parameter), not on fix A; the fact check re-ran it with fix A and the final test revision, and it passes.
Option A without dropping endState = captureState().
Trade-offs
Passes the new test (5 of 5) and, in the hunt, the 44 tests of the four closest suites, but a second end() call adds the input's increment again: a condition around StopFilter({"a"}) on abc a the gives 2, then 3. A second end() is outside the TokenStream contract, so this is robustness, not a reachable bug; the checkers flagged it as the sketch's open point.
Search servers that build token filters on this class (the condition and multiplexer filters of Elasticsearch and OpenSearch, by code reading only) likely inherit the shift; their text fields usually use a gap of 100, where only slop 100 sees one lost hole (100-101 two).
Code reading: while checking how the n-gram filters report the end of the stream, a finder read ConditionalTokenFilter.end() and saw it replace the input's final increment instead of adding to it. A probe and a public-API JUnit confirmed it; independent checkers followed.
The method in full103 words
- Method (non-formal): code reading in the hunt's unit on analysis filters against semantic references, while modelling the
end()contract of the n-gram filters; the LUCENE-8360 report says that bug was found throughConditionalTokenFilter, which pointed the finder at this class. It was outside the unit's planned file list (same module and contract), and the unit's exhaustive harness did not find it. - Confirmation. An executed probe, then a public-API JUnit (
WhitespaceTokenizer,StopFilter,ProtectedTermFilter,CustomAnalyzer.whenTerm,IndexWriter) that fails on main, 10.5.2 and 9.12.3, and a release-portablemain()that fails from 7.4.0 on. Independent checkers followed (see "Independent checks").
No prior report found (searched 2026-10-26, about 155 queries over GitHub issues, PRs and commits, JIRA, the Lucene and Solr lists, downstream trackers and the web, plus all 407 open PRs; re-checked 2026-10-28). Closest: LUCENE-8376/8371 (2018), which changed only which end() state is used.
Searches4 searches
No hit describes this bug. LUCENE-8361 (#9408, open since 2018) proposes a generic check that would probably have caught it, but names no ConditionalTokenFilter defect and was never committed. Keyword search only; part of the GitHub REST quota ran out (covered by GraphQL), three generic web queries were not run, and private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (three runs) | 2026-10-26 | 104 + 51 queries: apache/lucene issues, PRs and commits, Elasticsearch, OpenSearch and Solr repositories, dev@, java-user@, issues@, commits@, the JIRA archive, the web | no report |
| GitHub (REST and GraphQL) | 2026-10-26; re-checked 2026-10-28 | class and method names (ConditionalTokenFilter, ProtectedTermFilter, OneTimeWrapper, lastTokenFiltered, whenTerm) and symptom phrasings in apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch and apache/solr; the changed files of all 407 open apache/lucene PRs | no report; no open PR touches ConditionalTokenFilter.java, ProtectedTermFilter.java or CustomAnalyzer.java |
| ASF JIRA (LUCENE, SOLR) and lists.apache.org | 2026-10-26 | REST searches for the class names; dev@, java-user@, issues@, solr-user@, users@ and dev@solr | no report; TestRandomChains offset failures, usage threads and release logistics only |
| Closest items (read in full) | 2026-10-26 | comment threads | #9320 / LUCENE-8273 (introduced the class; end() test checks offsets only), #9423 / LUCENE-8376 and #9418 / LUCENE-8371 (moved where lastTokenFiltered is set), #9407 / LUCENE-8360 (n-gram filters; states the intent), #9408 / LUCENE-8361 (generic check, never committed), #4922 / LUCENE-3849, elastic/elasticsearch #31958 and #74176 |
Introduced by b1ee23c525a (LUCENE-8273, "Fix end() and posInc handling", 2018-05-18) and first released in 7.4.0. Fails on all ten versions run, 7.4.0 to 10.5.2, and on main; the file's history covers the releases in between. Not fixed upstream. The related stacked-token case was run on main only.
Versions tested8 rows
Introduced by b1ee23c525a (master, 2018-05-18, "LUCENE-8273: Fix end() and posInc handling"; identical branch_7x copy 443bd2ac526), committed from a JIRA patch while fixing TestRandomChains failures. It made OneTimeWrapper.end() call endAttributes() and restore only the final offset. The class itself (1ce3ebadbd6, 2018-05-11) and the next version (2225d0e464e) kept the hole; neither shipped.
Later commits 0c0fce3e98c (end-state capture, including the re-capture after delegate.end()), 4ea9d2ea8cb and ab2fec1642b (mid-stream increments), f835d249977 (LUCENE-8376/8371, 7.5.0) and the 2020 reformat all lose the hole (single-class bisect on the 7.4.0 jars, not a full build of each commit).
Not fixed upstream. Upstream main c5ab3e57b9ba (2026-10-28) last changed the file on 2020-12-28 (formatting only); the file is byte-identical in 9.0.0, 9.12.3, 10.5.2 and main.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | new test 5 of 5 fail through gradle (assertions on and off) and the repro harness |
| 10.5.2, 9.12.3 | affected | new test 5 of 5 fail; the finder's JUnit 3 of 5 and the reproducer's 5 of 8 fail |
| 7.4.0, 7.5.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 10.0.0 | affected | release-portable main(): final increment 0 instead of 1; its 2 controls give 1 |
| 7.3.1 | no such class | the API does not exist (compile error) |
1ce3ebadbd6 (class added), 2225d0e464e | bisect, unreleased | final increment 1 |
b1ee23c525a (introducing) and every later version of the file | bisect | final increment 0 |
fix B+ (recommended) on main a9779ef3c193 | not affected | 51 of 51 tests of the six classes (assertions on and off), all module tests and TestRandomChains pass; the stacked-token case fixed too |
fix B on main a9779ef3c193 | reported bug only | 49 of 49 tests of the five suites, all module tests and TestRandomChains pass; the 2 stacked-token tests fail |
An independent reproducer (own 8-test JUnit), a works-as-designed review by a reviewer from another model family, an intended-behaviour devil's advocate, an adjudication and a credibility audit all judged it real and re-ran it on main. A read-only refute review said "not real" only because it could not run code.
Checks and verdicts447 words
Every verdict below that re-ran a repro did so on main ea57360912ed, whose analysis module is identical to a9779ef3c193; the reading-only cross-model reviews were followed by a separate re-run of the repro (fails). This doc's own test and fix validation ran on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model refute review | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: it could run no command, so it could not vote real. It agreed with the root cause and that the inputs are legal, and found the intended-behaviour case unconvincing. A separate run re-ran the repro: 3 of 5 fail. |
| Independent reproducer | real | Own public-API JUnit written from the claim: 5 of 8 fail on main with assertions on and off, on 10.5.2 and on 9.12.3, including the phrase hit ([0,1,1] instead of [0,2,0]) and the lost TokenStreamToAutomaton hole; 3 controls pass; 8 of 8 with the hunt's sketch. |
| Works-as-designed review | real (high) | The same reviewer family with an intended-behaviour lens, reading only: rated the case that the wrapped chain's end state is authoritative by design as moderate and rejected it. A separate run ran its probe: 2 of 4 fail on main and 10.5.2, 4 of 4 pass with the sketch. |
| Intended-behaviour devil's advocate | real (high) | Built the strongest works-as-designed case and rejected it; own probe fails 4 of 10 on main (-ea, -da) and 10.5.2 (identity delegate, nothing protected, holes from both sides, the phrase), 10 of 10 with the sketch. |
| Adjudication | confirmed (high) | Re-ran the reproducer's JUnit with assertions on and off (5 of 8 fail) and the finder's (3 of 5). |
| Credibility audit | keep | Own probe fails 3 of 5 on main with assertions on and off; added the downstream ShingleFilter result ([abc] instead of [abc] [abc _]); score kept. |
| Fix validation (this doc) | fix B passes | Gradle in a scratch worktree of a9779ef3c193: stock 5 of 49 tests fail; fix B 0 of 49 (assertions on and off), all module tests and TestRandomChains pass, check -x test passes; the probe shows fix B matches the plain chain in all 13 conditional runs. |
| Fact checks of this doc | corrections applied | Fact checks (one by the reviewer from another model family, reading only) and a diagram check. All points were valid; they fixed counts, citations, a cut quote and several overclaims, and the cross-model one found the related stacked-token case, which was then executed (stock 1 of 2 tests fail, fixes A and B 2 of 2) and covered by the recommended fix B+. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 405 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,578 words
- Registry title
- ConditionalTokenFilter (ProtectedTermFilter, CustomAnalyzer when()/whenTerm()) reports a final position increment of 0 when the last token went through the wrapped filters, so a trailing hole from upstream (such as a removed trailing stop word) is lost and the next value of a multi-valued field starts one position too early (since 7.4.0)
- Area
- analysis / common miscellaneous (ConditionalTokenFilter#end and OneTimeWrapper#end: final position increment on the delegate branch)
- Priority
- Low, rank 487: ConditionalTokenFilter loses a trailing hole the same way as LFV-354 and LFV-532 in a less used filter.
- Impact class
- silent wrong results
- Impact note
- Applications that put a ConditionalTokenFilter (ProtectedTermFilter or its factory, a CustomAnalyzer when()/whenTerm() branch, or a downstream wrapper built on the class) behind a filter that leaves a trailing hole (typically StopFilter) are hit whenever a value ends in a removed word right after a token that went through the wrapped filters (for ProtectedTermFilter, any token that is not protected): end() reports 0 instead of the hole, so in a multi-valued field the next value starts one position early per lost hole and phrase, span and interval queries across the two values over-match or miss (executed with Lucene's default gap 0; with a gap of 100 only slop of 100 or more is affected), and TokenStreamToAutomaton loses the trailing hole (executed at the automaton level; a downstream ShingleFilter by code reading); positions inside one value, single-valued fields, the query side and the index structure are unaffected (CheckIndex clean); deterministic, ordinary scale, -ea and -da, every release from 7.4.0 to 10.5.2 and main.
- Summary
- You analyse 'abc the' with WhitespaceTokenizer, a StopFilter that removes 'the', and a ProtectedTermFilter that wraps a LowerCaseFilter (or the CustomAnalyzer equivalent whenTerm(...).addTokenFilter("lowercase").endwhen()), and expect end() to report the removed stop word as a final position increment of 1, as the same chain does without the condition and as the class itself does when the last token is protected ('x the' gives 1). Instead it reports 0 whenever the last token went through the wrapped filter, although LowerCaseFilter never touches positions: end() keeps the wrapped chain's end state, and the internal wrapper that feeds that chain resets the increment to 0. In a multi-valued field ['abc the', 'def'] with the default gap 0, 'def' is then indexed at position 1 instead of 2, so the PhraseQuery "abc def" matches the document (1 hit) where the plain chain gives 0 (executed).
- Introduced
- b1ee23c525a64017242148bca43111168fe1be3a (master, 'LUCENE-8273: Fix end() and posInc handling', by GitHub romseygeek; LUCENE-8273 = apache/lucene#9320, JIRA patch workflow, no PR), shipped in 7.4.0 through the identical branch_7x copy 443bd2ac526a40079e9028a5e7d8ad2f24ca6a4b (same ConditionalTokenFilter.java blob): it made OneTimeWrapper.end() 'imitate Tokenizer.end() call - endAttributes, set final offset', so the position increment becomes 0 and only the final offset is restored, while ConditionalTokenFilter.end() keeps the delegate's end state when lastTokenFiltered [exec bisect: ConditionalTokenFilter.java of each commit compiled with --shadow-src on the 7.4.0 jars: the class-adding commit 1ce3ebadbd6 (2018-05-11) and the parent 2225d0e464e keep the hole (final increment 1); b1ee23c525a and every later version of the file (0c0fce3e98c, 4ea9d2ea8cb, ab2fec1642b, f835d249977 = LUCENE-8376/8371, 8ef6a0da568 reformat) lose it] [read: git blame of 'endAttributes();' in OneTimeWrapper.end() and git log -G 'endAttributes\(\)' give only b1ee23c525a]. The two hole-keeping versions existed for one week on master and branch_7x and never shipped; b1ee23c525a was written to fix other end() problems found by TestRandomChains, so the hole loss is a side effect of that fix (2018-05-18)
- First affected version
- 7.4.0 [exec] (the first release with ConditionalTokenFilter, ProtectedTermFilter and CustomAnalyzer when()/whenTerm(); 7.3.1 does not have the API [exec: compile error]); no release ever had the correct behaviour
- Affected versions
- every release before 10.6.0 that has the class: 7.4.0, 7.5.0, 7.6.0, 7.7.0-7.7.3, 8.0.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.5.2 and main ea57360912ed; not fixed. [exec] the release-portable main() (final increment 0 through a pass-through delegate; its 2 controls give 1) fails on 7.4.0, 7.5.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main; the finder's JUnit fails 3 of 5 on main (-ea and -da), 10.5.2 and 9.12.3; the independent reproduction's JUnit fails 5 of 8 on main (-ea and -da), 10.5.2 and 9.12.3; the intended-behaviour check's probe fails 4 of 10 on main (-ea and -da) and 10.5.2. [read] git tag --contains on the history clone lists 58 release tags from 7.4.0 to 10.5.2 (8.8.2, 8.9.0 and 8.10-8.11 are untagged there; 8.11.4 was executed); ConditionalTokenFilter.java is byte-identical in 9.0.0, 9.12.3, 10.5.2 and main; upstream main a95c754ee003 (read 2026-10-26) last changed the file on 2020-12-28 (formatting only) and no open PR touches it. Executed only on aarch64 Linux with JDK 25 (plain Java logic)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record, verdict new; plus the finder's scripted prior-report search and the intended-behaviour check's searches): two follow-up scripted prior-report searches (104 queries over apache/lucene GitHub issues, PRs and commits, Elasticsearch, OpenSearch and Solr repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web) on top of the finder's run (51 queries); direct GitHub REST and GraphQL searches in apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch and apache/solr; ASF JIRA (LUCENE, SOLR); lists.apache.org including the Solr lists; full comment threads of LUCENE-8273, 8371, 8376, 8360 and 8361; and the changed files of all 407 open apache/lucene PRs. Related, not this bug: #9320/LUCENE-8273 (closed, introduced the class; its end() fixes concern offsets and branch choice, and the end() test that landed asserts final offsets only), #9423/LUCENE-8376 and #9418/LUCENE-8371 (closed, 7.5.0, commit f835d249977 changed only where lastTokenFiltered is set; the bug reproduces on 8.0.0 to main), #9407/LUCENE-8360 (closed, n-gram end() increments, other fix site; states the intent to preserve position increments), #9408/LUCENE-8361 (open since 2018, a generic summed-increment check for TestRandomChains, never committed, names no ConditionalTokenFilter defect), #4922/LUCENE-3849 (the end() trailing-hole contract), #9391/LUCENE-8344, #9696/LUCENE-8650 and #16577 (same symptom family in other classes), elastic/elasticsearch#31958 and #74176 (the downstream 'condition' filter; no end() or position discussion). Not fixed upstream: upstream main a95c754ee003 still has the overwrite; no open PR touches ConditionalTokenFilter.java, ProtectedTermFilter.java or CustomAnalyzer.java (only #13390 touches TestConditionalTokenFilter, constructor calls).
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree: the new 5-test class withTestConditionalTokenFilter,TestProtectedTermFilter,TestProtectedTermFilterFactoryandTestCustomAnalyzer, assertions on and off (stock: 5 of 49 fail; fixes A and B: 0), fixes A and B with all of:lucene:analysis:common:test(-Ptests.iters=4: 7,653 test runs, 0 failures) andTestRandomChains(8 runs, 0 failures), fix B withcheck -x test(fix A's passed in the fact check's re-run); the recommended fix B+ the same way, with a 2-test class for the related stacked-token case (51 of 51 tests with assertions on and off, 7,661 module test runs, 8 TestRandomChains runs,check -x test); the worktrees were removed afterwards. The new test through the repro harness on 9.12.3, 10.5.2 and main (-ea,-da); a 21-chain probe and a stacked-token probe on stock main and with each fix variant; the hunt's release-portablemain()on 7.4.0 to 10.5.2 and its single-class bisect on the 7.4.0 jars (hunt commitea57360912ed, whose analysis module is identical); OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConditionalTokenFilter.java:84-95 (at ea57360912ed) (OneTimeWrapper.end(): 'imitate Tokenizer.end() call - endAttributes, set final offset'; input.end() is captured, then endAttributes() resets the position increment to 0 and only the final offset is restored), :139-151 (end(): the input's end state is captured, then replaced by delegate.end()'s when lastTokenFiltered), :213-230 (endDelegating: mid-stream, the delegate's end increment is ADDED to the buffered token's increment)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ProtectedTermFilter.java:51-54 (at ea57360912ed) (shouldFilter() is true for every token that is not protected)lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:152-154 (at ea57360912ed) (end(): 'any skipped positions (such as those removed by a stopfilter) can be applied to the position increment'); lucene/core/src/java/org/apache/lucene/analysis/package-info.java:274-284 ('End of Input Cleanup': components 'must put accurate values' at the end of the field); lucene/core/src/java/org/apache/lucene/analysis/FilteringTokenFilter.java:72-75 (StopFilter's end() adds the skipped positions)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2050-2054 (at ea57360912ed) (the final increment is added to the field position after stream.end()), :2066-2068 (position increment gap before the next value); lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:212-225 (trailing holes from the end() increment)lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestConditionalTokenFilter.java (at ea57360912ed) testEndPropagation (asserts final offsets 20 and 18 only, CannedTokenStream with final increment 0); grep of non-test sources: only ProtectedTermFilter(Factory), ConditionalTokenFilterFactory and CustomAnalyzer use the class (no stock analyzer)lucene/CHANGES.txt:7182-7184 (at ea57360912ed) (LUCENE-8376/LUCENE-8371, 7.5.0 Bug Fixes: 'ConditionalTokenFilter.end() would not propagate correctly if the last token in the stream was subsequently dropped'), :7482 (LUCENE-8360), :6912 (LUCENE-8650), :13321 (LUCENE-3849)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConditionalTokenFilter.java:84-95, :119, :139-151, :178, :202, :213-230 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ProtectedTermFilter.java:51-54 @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:152-154; lucene/core/src/java/org/apache/lucene/analysis/FilteringTokenFilter.java:72-75; lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:81-83 (default attribute factory); lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/PackedTokenAttributeImpl.java:183-186 @ a9779ef3c193lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2105-2109, :2122; lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:296-311; lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:212-239; lucene/analysis/common/src/java/org/apache/lucene/analysis/shingle/ShingleFilter.java:379-382 @ a9779ef3c193
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ProtectedTermFilterFactory.java:86 (NAME) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:84-95, :463-466, :544-564 @ a9779ef3c193lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:317-321; lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:474-535; lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:212-239 @ a9779ef3c193
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:152-154; lucene/core/src/java/org/apache/lucene/analysis/package-info.java:274-284 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConditionalTokenFilter.java:28-34, :213-230 @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:460-466 @ a9779ef3c193lucene/CHANGES.txt:7198-7200 (LUCENE-8376/8371), :13337-13340 (LUCENE-3849) @ a9779ef3c193lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestConditionalTokenFilter.java:174-197 @ a9779ef3c193
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConditionalTokenFilter.java:56-60, :84-95, :139-151, :188-192, :213-230 @ a9779ef3c193
- TestConditionalTokenFilterEndPositionIncrement.java (JUnit test):
repro/LFV-542/src/org/apache/lucene/analysis/miscellaneous/TestConditionalTokenFilterEndPositionIncrement.java(46 lines)
assets/LFV-542/bug.png(405 KB)