- A synonyms file holds one rule per line:
couch, sofamakes the words equivalent,i-pod => ipodmaps one side to the other. - The parser trims each term and runs it through an analyzer. A term that leaves no word is an error, and one bad line rejects the whole file.
- The class javadoc lists, as rule 1 of the format: "Blank lines and lines starting with '#' are comments."
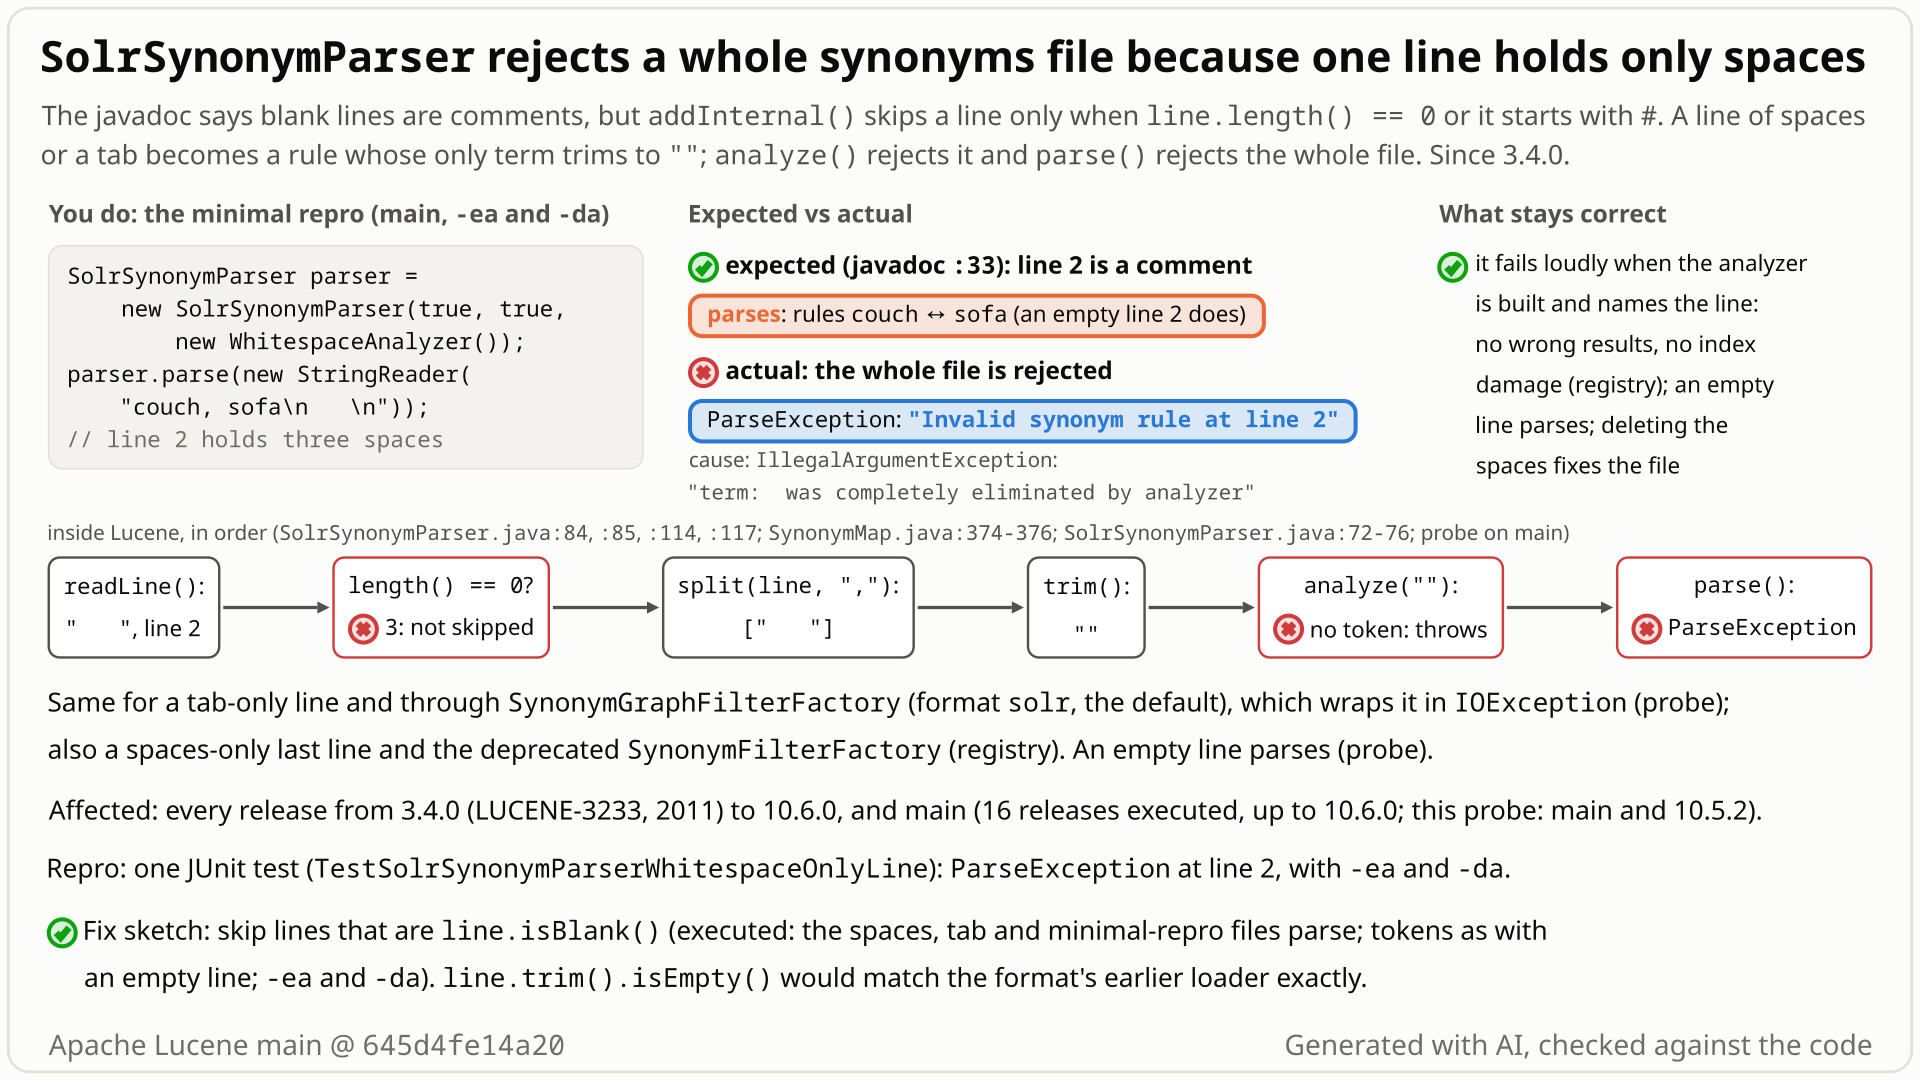
- Write a synonyms file of three lines:
couch, sofa, a line of three spaces, andbig, large. Load it withSolrSynonymParser, or withSynonymGraphFilterFactory, whose default format is this one. - You expect line 2 to be skipped: the javadoc says "Blank lines and lines starting with '#' are comments." With an empty line 2 the file loads and gives 2 rules.
- Instead the parser skips a line only when its length is 0. Line 2 has length 3, so it is read as a rule; its single term trims to an empty string, and the analyzer turns that into no word at all.
- The whole file is rejected:
ParseException: Invalid synonym rule at line 2, caused byterm: was completely eliminated by analyzer(the factory reportsIOException: Error parsing synonyms file:). The analyzer cannot be built until the spaces are deleted.
Anyone who loads Solr-format synonyms, the default format of SynonymGraphFilterFactory and the deprecated SynonymFilterFactory (also through CustomAnalyzer), or calls SolrSynonymParser directly, from a file with a line of only spaces or tabs, for example left by an editor. Through the factories it fails loudly when the analyzer is built and names the line; no wrong results.
Mechanism, terms and numbers484 words
SolrSynonymParser, the default parser of SynonymGraphFilterFactory and SynonymFilterFactory, documents that "Blank lines and lines starting with '#' are comments", but it skips a line only when it has zero length. A line of only spaces or tabs is parsed as a rule whose single term trims to the empty string; the analyzer leaves nothing of it, and the whole file is rejected with ParseException: Invalid synonym rule at line N (the factories wrap it in IOException: Error parsing synonyms file:). Through the factories it fails loudly when the analyzer is built and names the line; nothing goes silently wrong. The pre-3.4 Solr loader of the same format, and Lucene's WordlistLoader today, skip such lines. Every release from 3.4.0 to 10.6.0 and main is affected; the fix is one line.
SolrSynonymParser: reads the Solr synonyms format into aSynonymMapforSynonymGraphFilter.SynonymGraphFilterFactoryand the deprecatedSynonymFilterFactoryuse it whenformatis missing orsolr(the default), and analyze rule terms with aWhitespaceTokenizerunless a tokenizer or analyzer is configured.- Blank line: the javadoc does not define it. Lucene's
WordlistLoaderuses the word for lines that are empty aftertrim(), and so did the Solr loader that read this format before 3.4.
addInternalskips a line only ifline.length() == 0 || line.charAt(0) == '#'(SolrSynonymParser.java:85-86, comment "ignore empty lines and comments").- For the line
" ",split(line, "=>")gives one side, so it takes the equivalent-synonyms branch;split(line, ",")gives[" "], andanalyze(unescape(...).trim(), ...)analyzes""(:90-91,:114-117). SynonymMap.Parser.analyzethrowsIllegalArgumentException("term: was completely eliminated by analyzer")when no characters are left (SynonymMap.java:374-377), or "analyzed to a zero-length token" for a tokenizer that emits one empty token (:349-352). In the hunt's security probe the line was rejected in all 48 combinations ofWhitespaceAnalyzer,StandardAnalyzer,KeywordAnalyzer,SimpleAnalyzer, expand on/off and six blank forms. Only an analyzer that emits a non-empty token for empty input accepts such a line (executed with a custom one).parse()turns it intoParseException("Invalid synonym rule at line 2")(:72-76); the factories wrap that inIOException("Error parsing synonyms file:")(SynonymGraphFilterFactory.java:162-163,SynonymFilterFactory.java:165-166). Through the factories no map is built, so every rule in the file is lost. A direct caller that catches theParseExceptionand callsbuild()anyway gets only the rules before the line (executed).
| synonyms file | expected | actual |
|---|---|---|
couch, sofa / (empty line) / big, large | parses | parses (control) |
couch, sofa / (three spaces) / big, large | parses | ParseException: Invalid synonym rule at line 2 |
couch, sofa / a tab / big, large | parses | rejected the same way |
tv, television / car, auto / one space, no final newline | parses | rejected the same way |
the same files through SynonymGraphFilterFactory or CustomAnalyzer | analyzer builds | IOException: Error parsing synonyms file: |
Exposure and likelihood180 words
- Who is hit. Callers of
SolrSynonymParser.parse, and users ofSynonymGraphFilterFactoryorSynonymFilterFactorywith the default format, directly or throughCustomAnalyzerand configurations that name the factories. Such a line is easy to produce: an auto-indented separator line, whitespace left on an otherwise empty line, a last line holding a space (trailing whitespace after a rule is harmless: every term is trimmed). - Default vs opt-in. The synonym filter is in no stock
Analyzer; within it, the bug needs only defaults (formatsolr).SolrSynonymParserandSynonymGraphFilterFactorycarry@lucene.experimental. - Scale. None: one whitespace-only line anywhere in the file.
- Visibility. Loud and early: through the factories the analyzer is not built, the error names the line, and nothing is indexed or searched with a partial map (only a direct caller that ignores the exception and builds anyway could get one). The message is misleading: an "invalid synonym rule" with an empty
term:for a line that holds no rule. - Severity. Low: a wrong error; through the factories no wrong results and no index damage; deleting the whitespace works around it.
One JUnit test, public API only: parse "couch, sofa\n \n" (a rule, then a line of three spaces) with new SolrSynonymParser(true, true, new WhitespaceAnalyzer()); it must not throw. No randomness, single thread, the same result with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.synonym;

import java.io.StringReader;
import java.text.ParseException;
import org.apache.lucene.analysis.core.WhitespaceAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSolrSynonymParserWhitespaceOnlyLine extends LuceneTestCase {

  public void testSpacesOnlyLineIsBlank() throws Exception {
    try (WhitespaceAnalyzer analyzer = new WhitespaceAnalyzer()) {
      SolrSynonymParser parser = new SolrSynonymParser(true, true, analyzer);
      try {
        parser.parse(new StringReader("couch, sofa\n   \n"));
      } catch (ParseException e) {
        // class javadoc: "Blank lines and lines starting with '#' are comments."
        throw new AssertionError(
            "expected: line 2 (three spaces) is skipped as blank; actual: " + e + " <- " + e.getCause(),
            e);
      }
    }
  }
}
cp TestSolrSynonymParserWhitespaceOnlyLine.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.synonym.TestSolrSynonymParserWhitespaceOnlyLine -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
- Expected
parseskips line 2 (three spaces) as a blank line and returns normally.- Observed
ParseException: Invalid synonym rule at line 2, caused byterm: was completely eliminated by analyzer; the same with assertions off.
More files, environment, full output210 words
parse() alone shows the bug (it throws before build()), so no map or token stream is needed. WhitespaceAnalyzer matches the factories' default tokenizer for rule terms. The try/catch only turns the ParseException into an AssertionError that states expected vs actual.
Also fails with seed 5EED1234 (5 of 5) and on the 10.6.0 release jars with assertions on and off; passes with either fix.
As the regression test: the same test, for example as a new method in TestSolrSynonymParser.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also fails on 10.6.0, 10.5.2, 9.12.3 and every release back to 3.4.0 |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (pure string handling; the platform does not matter) |
cp TestSolrSynonymParserWhitespaceOnlyLine.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.synonym.TestSolrSynonymParserWhitespaceOnlyLine -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
# gradle, main 645d4fe14a20, seed DEADBEEF (assertions on; the same with -Ptests.asserts=false)
TestSolrSynonymParserWhitespaceOnlyLine > testSpacesOnlyLineIsBlank FAILED
    java.lang.AssertionError: expected: line 2 (three spaces) is skipped as blank; actual: java.text.ParseException: Invalid synonym rule at line 2 <- java.lang.IllegalArgumentException: term:  was completely eliminated by analyzer
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:1FA61A41CFDB32CB]:0)
        at org.apache.lucene.analysis.synonym.TestSolrSynonymParserWhitespaceOnlyLine.testSpacesOnlyLineIsBlank(TestSolrSynonymParserWhitespaceOnlyLine.java:34)

        Caused by:
        java.text.ParseException: Invalid synonym rule at line 2
            at org.apache.lucene.analysis.synonym.SolrSynonymParser.parse(SolrSynonymParser.java:74)
            at org.apache.lucene.analysis.synonym.TestSolrSynonymParserWhitespaceOnlyLine.testSpacesOnlyLineIsBlank(TestSolrSynonymParserWhitespaceOnlyLine.java:30)

            Caused by:
            java.lang.IllegalArgumentException: term:  was completely eliminated by analyzer
                at org.apache.lucene.analysis.synonym.SynonymMap$Parser.analyze(SynonymMap.java:375)
                at org.apache.lucene.analysis.synonym.SolrSynonymParser.addInternal(SolrSynonymParser.java:117)
at org.apache.lucene.analysis.synonym.SolrSynonymParser.parse(SolrSynonymParser.java:71)- Javadoc: "Blank lines ... are comments." Lucene's
WordlistLoaderalso treats a line of spaces as blank: it trims, then skips it. - The pre-3.4 Solr loader of this format skipped such lines; the 3.4 rewrite dropped that silently.
- Such a line holds no rule and fails under every analyzer tried, so skipping it changes no file that parses today with them.
The full argument216 words
- Javadoc (
SolrSynonymParser.java:33): "Blank lines and lines starting with '#' are comments." - Lucene's own word for it.
WordlistLoader"adds every non-blank line ... (omitting leading and trailing whitespace)" and doesword = word.trim(); // skip blank lines(WordlistLoader.java:43-44,:56-58; also:107,:123-124,:294,:307-308).TestWordlistLoader.testGetLinesfeeds a line holding one space and expects it skipped. GITHUB#12291, "Skip blank lines from stopwords list", is listed under Bug Fixes in 9.7.0. - The format's previous loader. Solr's
SolrResourceLoader.getLines, which read synonyms files before 3.4, didif (word.startsWith("#")) continue;, thenword=word.trim();, then// skip blank lines. LUCENE-3233 createdSolrSynonymParserto parse "the existing solr synonyms format"; its thread lists the known differences as "deduping rules, lowercasing" and never mentions blank lines. In the 4.0.0 jar the kept pre-3.4 loader (luceneMatchVersion=LUCENE_33) accepts the file, whileLUCENE_34andLUCENE_40reject it. - No test asserts the rejection: no test in the analysis-common module uses a whitespace-only line either way.
- No file that parses today with the analyzers tried changes: with them such a line is rejected in every combination tried. Only an analyzer that emits a token for empty input lets it parse (executed with a custom one); for it, the fix would drop a one-term rule.
The devil's-advocate check189 words
The strongest case for "intended" (an intended-behaviour devil's advocate, and a reviewer from another model family, OpenAI GPT-5.6, who rated it "moderate"): the inline comment says "ignore empty lines" (:86); the comment check is literal too, so # x is a rule; the parser is strict on purpose, and upstream tests require a ParseException when the analyzer removes a term (TestSolrSynonymParser.testInvalidAnalyzesToNothingOutput / Input, inputs a => 1 and 1 => a); the class is @lucene.experimental; the behaviour is 15 years old and the error names the line.
Why it fails: those strictness tests use lines that hold a rule whose real term the analyzer removes; a whitespace-only line holds no rule, and the "term" in the error is an empty string the user never wrote. The inline comment is the only support for the narrow reading, while the public javadoc, Lucene's other line loaders and this format's own previous loader all skip trimmed-empty lines, and nothing records a decision to narrow it. These points bear on severity and on the "bug or improvement" label, not on whether the code matches the documented format.
Recommended Skip lines that are empty after trim()
Skip lines that are empty after trim(): change line.length() == 0 to line.trim().isEmpty() in SolrSynonymParser.addInternal, the rule the pre-3.4 loader and WordlistLoader use. One line; the repro passes with assertions on and off, all 121 synonym-package tests pass, and the module's static checks pass.
-      if (line.length() == 0 || line.charAt(0) == '#') {
-        continue; // ignore empty lines and comments
+      if (line.trim().isEmpty() || line.charAt(0) == '#') {
+        continue; // ignore blank lines and comments
       }
All options and trade-offs3 options · 629 words
Two one-line fixes in SolrSynonymParser.addInternal (SolrSynonymParser.java:85-86); both were run through gradle in a scratch worktree of 645d4fe14a20.
Matches the pre-3.4 Solr loader and WordlistLoader exactly.
-      if (line.length() == 0 || line.charAt(0) == '#') {
-        continue; // ignore empty lines and comments
+      if (line.trim().isEmpty() || line.charAt(0) == '#') {
+        continue; // ignore blank lines and comments
       }
Trade-offs
Skips exactly the lines whose single term the parser would trim to the empty string (it uses the same trim() on every term, :99, :105, :117); with the analyzers tried every such line fails today, so no file that parses today with them changes meaning (an analyzer that emits a token for empty input is the one exception). No public API signature changes; it is a leniency change: files rejected today are accepted. Indented comment lines ( # x) stay rules, as before, and so do lines of only Unicode spaces that trim() keeps, such as U+3000 (rejected today with WhitespaceAnalyzer, and still rejected). Cost: one trim() per line at load time.
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20: without the fix the repro fails with assertions on and off. - With the fix: it passes with assertions on and off (
-Ptests.asserts=false). - Closest suites: every test class in
org.apache.lucene.analysis.synonym(includingword2vec) with the repro: 12 classes, 121 tests, 0 failures, 0 skipped. ./gradlew :lucene:analysis:common:check -x test(google-java-format, ecj lint, forbidden APIs, generated-file checksums) passes with the fix and the repro in place, once./gradlew tidyhas wrapped the repro's long message line; before that, the format check failed only on that test line. The full test suite was not run.
The same condition with String.isBlank().
-      if (line.length() == 0 || line.charAt(0) == '#') {
+      if (line.isBlank() || line.charAt(0) == '#') {
Trade-offs
A different set of lines, not just a broader one: trim() removes every character up to U+0020, while isBlank() uses Character.isWhitespace. So B also skips lines of Unicode whitespace that trim() keeps (U+2003, U+3000), but still rejects lines of control characters that trim() removes and that are not whitespace (U+0001). Executed on the main jars (couch, sofa / X / big, large): a U+0001 line is rejected today, parses with A and is still rejected with B. A U+3000 or U+2003 line is rejected today with WhitespaceAnalyzer and parses with B; with KeywordAnalyzer it parses today as a one-term rule that adds no mapping with expand on and maps the term to itself with expand off (3 words). B skips it, so with expand off the self-mapping is lost (2 words). B therefore changes how a file that parses today is read, in a small way; A matches the old loader exactly and is the safer choice (the adjudication rated either fix safe before this difference was found).
What the checks validated
Gradle in the same scratch worktree: the repro and TestSolrSynonymParser pass with assertions on (11 tests, 0 failures); the other suites and the static checks were not run through gradle for this option (the fact check later ran the repro with it through gradle with assertions off: pass). Earlier, shadowed into the stock main jars, the four earlier test classes (21 tests) and the 10 upstream TestSolrSynonymParser tests pass, and the minimal repro passes with assertions on and off.
Would also turn indented # x lines into comments.
Trade-offs
A different change: it alters how files that parse today are read (an indented # line is a rule today, and was in the pre-3.4 loader too). Not tried.
Elasticsearch's synonym filters parse rules with a subclass of SolrSynonymParser (by code reading), so their users get the same error unless they enable its lenient mode, which drops the failing rule instead.
Semi-formal: a bounded-exhaustive check compared the parser on 253,130 small synonym files (1,012,520 parse-and-build checks) with a reference written from the javadoc, with 0 mismatches. Writing that reference forced a decision on what "blank line" means, so whitespace-only lines were tested on their own, and they are rejected.
The method in full112 words
Method: semi-formal (bounded-exhaustive translation validation). The harness enumerated synonym files of 1-3 rules, with expand and dedup on and off, parsed and built each with SolrSynonymParser and SynonymMap.Builder, decoded the resulting FST rule set and compared it exactly with a reference implementation of the javadoc's rules: 253,130 files, 1,012,520 checks, 0 mismatches; two deliberately broken reference variants are caught, so the check is not vacuous. The reference had to say what a blank line is, so whitespace-only lines were checked as their own class, and a public-API JUnit test then showed the rejection on the stock main jars (2 of 3 tests fail: spaces-only and tab-only line; the empty-line control passes).
No prior report found in GitHub issues, PRs and commits, open PRs, the JIRA archive, the Lucene and Solr lists, downstream trackers, forums or the web (2026-10-26, refreshed 2026-11-01); not fixed upstream.
Searches5 searches
Closest items, none a report of this bug: a 2019 Elastic forum thread (topic 183596) with the same error, where a team member guessed "this might be a blank line or something in your file" while the user's real cause was quoted rules (nobody tested a whitespace-only line); #12291 / #12299 (2023, blank lines in WordlistLoader stopword files, a precedent for the fix); #10073 / LUCENE-9030, #7460 / LUCENE-6400, LUCENE-5219 and SOLR-3235 (other synonym-parser changes); Elasticsearch #30968, #31224, #40077, #29426, #36433 (the same error from stop filters, an ICU rule and position increments).
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene and apache/lucene-solr issues and PRs (incl. the migrated JIRA issues) and commits | 2026-10-26; refreshed 2026-11-01 | a scripted prior-report search (16 issue/PR queries with the top hits' comments, 3 commit queries) plus 17 own queries; full-history git log -S / --follow on the check; refresh: gh search for SolrSynonymParser, "synonym whitespace line" and open synonym PRs | no report; the check dates from LUCENE-3233 and never changed |
| Open PRs | 2026-10-26 | changed files of all 407 open apache/lucene PRs | none changes the check |
| JIRA archive (LUCENE, SOLR) and mailing lists | 2026-10-26 | 4 + 18 JQL queries, the full LUCENE-3233, LUCENE-5219 and LUCENE-6400 threads; 20 + 14 lists.apache.org queries over the Lucene and Solr lists | no report; a 2013 solr-user thread with the same error from a trailing comma |
| Downstream trackers, Stack Overflow, forums, web | 2026-10-26 | 13 Elasticsearch, OpenSearch and Solr tracker queries; Stack Overflow full-text search; the Elastic and OpenSearch forum search; 12 web queries | the same error from other causes; one forum guess about a blank line (near miss) |
| Upstream main | 2026-11-01 | file contents of SolrSynonymParser.java at 2f424fd428da (2026-10-30) | still if (line.length() == 0 || line.charAt(0) == '#') { at line 85 |
There since SolrSynonymParser was created in LUCENE-3233 (commit 015ecfa0a02, 2011-07-11), first released in 3.4.0. Every release from 3.4.0 to 10.6.0 and main fails; the pre-3.4 Solr loader accepted such files.
Versions tested7 rows
Introduced by LUCENE-3233 (rmuir): trunk commit 015ecfa0a02 (2011-07-11), branch_3x backport a52015db05f (same day); no PR (the issue was migrated as #4306). git blame and git log -L on the check return only this commit, and git log -S finds the javadoc sentence and the empty-term error first in it. Not a later regression: the class has behaved this way since it was written; relative to the format's previous Solr loader it is a narrowing at 3.4.
Reach by version: in 3.x the factory lived in Solr; Lucene's SynonymFilterFactory exists from 4.0.0-beta and SynonymGraphFilterFactory from 6.4.0, both defaulting to this parser. Up to 4.10.4 a factory with luceneMatchVersion below 3.4 used the old loader, which accepts such files; it is gone from 5.0.0.
By reading: all 128 release tags 3.4.0..10.5.2 in the history clone carry the identical check; upstream main still has it.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal repro fails with assertions on and off (standalone and gradle); passes with either fix |
| 10.6.0 | affected | minimal repro fails with assertions on and off |
| 10.5.2, 9.12.3 | affected | the hunt's, the independent reproduction's and the intended-behaviour check's JUnit tests fail; the history probe fails |
| 10.0.0, 9.0.0, 8.11.4, 7.7.3, 6.6.6, 5.5.5, 5.0.0, 4.10.4, 4.5.0, 4.4.0, 4.0.0, 3.6.2 | affected | history probe: spaces-only and tab-only line rejected, empty-line control parses |
| 3.4.0 | first affected | history probe fails the same way |
| 4.0.0, luceneMatchVersion LUCENE_33 | pre-3.4 loader | the kept old loader accepts the file |
| 3.3.0 | class absent | no SolrSynonymParser |
Confirmed with high confidence: the finder's test, an independent reproducer, a factory test, an intended-behaviour devil's advocate and an adjudication all reproduce it; the reproducer, the devil's advocate and the adjudication call it real. A reviewer from another model family, unable to run code, agreed on the root cause.
Checks and verdicts334 words
Nobody found it intended; all agree it is low severity: a loud, line-numbered error at analyzer build time.
| Check | Verdict | What it found |
|---|---|---|
| finder (bounded-exhaustive check + JUnit) | candidate | 0 mismatches over 1,012,520 checks of the javadoc's rules; the whitespace-only class fails 2 of 3 tests on main (assertions on and off), 10.5.2 and 9.12.3; passes with line.isBlank(). |
| cross-model review (OpenAI GPT-5.6, reading-only, lenses) | refute: not real, low (procedural); intended: real, medium | Could not run code; agreed on the root cause and the legality of the input; rated the intended-behaviour argument weak (refute) and moderate (intended). Separate re-runs failed 2 of 3. |
| separate factory test | reproduced | Fails 4 of 7 on main (assertions on and off) and 10.5.2: spaces line, tab line, one-space last line, deprecated factory; 3 controls pass; 7 of 7 with the fix. |
| Independent reproducer | real | Own public-API test (same filter output as the file without the line) fails 4 of 5 on main (on and off), 10.5.2 and 9.12.3; 5 of 5 with the fix. |
| Intended-behaviour devil's advocate | real | The narrow reading rests only on the inline comment; factory-path test fails 3 of 6 on main, 10.5.2 and 9.12.3; 6 of 6 with the fix. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test with a fresh seed: fails 4 of 5 with assertions on and off, passes 5 of 5 with the fix. |
| minimal repro and this doc | verified | The one-test repro fails on main (two seeds, on and off) and on 10.6.0; both fixes pass through gradle. |
| fact checks of this doc (independent, and cross-model OpenAI GPT-5.6) | bug, repro and history correct; wording corrected | The independent fact check re-ran the repro (standalone and gradle) and fix A: fails on main with assertions on and off, passes with the fix. Both checks asked for narrower wording on the fix B comparison, the partial-map and custom-analyzer cases and a few counts; this version has those corrections. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 485 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,309 words
- Registry title
- SolrSynonymParser rejects a whole synonyms file because one line holds only spaces or tabs, although its javadoc says blank lines are comments (ParseException 'Invalid synonym rule at line N', every release since 3.4.0)
- Area
- analysis-common / synonym (SolrSynonymParser; SynonymGraphFilterFactory and SynonymFilterFactory, format solr)
- Priority
- Low, rank 1057: A synonyms file with a whitespace-only line fails loudly at analyzer build time naming the line.
- Impact class
- wrong error
- Impact note
- Anyone who loads a Solr-format synonyms file (SolrSynonymParser.parse directly, or SynonymGraphFilterFactory / SynonymFilterFactory with the default format 'solr', for example through CustomAnalyzer) that contains a line of only spaces or tabs, including a spaces-only last line, gets a ParseException 'Invalid synonym rule at line N' (wrapped by the factories in IOException 'Error parsing synonyms file:'), caused by 'term: was completely eliminated by analyzer', so the analyzer cannot be built until the whitespace is deleted; it fails loudly at analyzer-build time with no wrong results, no index damage and no scale needed, with -ea and -da, on every release from 3.4.0 to 10.6.0 and main.
- Summary
- You load a synonyms file such as 'couch, sofa', then a line holding three spaces or a tab, then 'big, large', and expect it to parse, because the SolrSynonymParser javadoc says 'Blank lines and lines starting with '#' are comments'. Instead the whole file is rejected with ParseException 'Invalid synonym rule at line 2': the parser skips a line only when it has zero length (or starts with '#'), so the whitespace-only line is parsed as a rule whose single term trims to the empty string, which the analyzer step rejects. A truly empty line parses fine, and so did whitespace-only lines in the Solr loader this format came from before 3.4.
- Introduced
- 015ecfa0a0255f053682bb2436b2b8dec5cb8283 (LUCENE-3233 'improve ram/perf of SynonymFilter, add wordnet parsing, nuke contrib/wordnet', trunk r1145158, @rmuir; branch_3x backport a52015db05f, r1145178; no pull request, the issue was migrated as apache/lucene#4306) [read: git blame and git log -L on the check at SolrSynonymParser.java:85 return only this commit, and git log -S finds the javadoc sentence and the 'was completely eliminated by analyzer' error first in it; exec: 3.3.0 has no SolrSynonymParser, 3.4.0 fails, and in the 4.0.0 jar the kept pre-3.4 loader (luceneMatchVersion=LUCENE_33) accepts the file while LUCENE_34 and LUCENE_40 (SolrSynonymParser) reject it]. Not a later regression: the class has rejected such lines since it was written; relative to the format's previous loader (Solr's SolrResourceLoader.getLines: trim, then skip empty) it is a narrowing at 3.4 (2011-07-11)
- First affected version
- 3.4.0 (released 2011-09-14, the first release with SolrSynonymParser) [exec]; first 4.x release 4.0.0-alpha [read], 4.0.0 [exec]
- Affected versions
- every release from 3.4.0 through 10.6.0, and main ea57360912ed and 645d4fe14a20; [exec] the minimal repro fails on main 645d4fe14a20 and on the 10.6.0 release jars (SHA-1 checked against Maven Central), -ea and -da (2026-11-01); the version-portable main() probe fails (spaces-only and tab-only line rejected, empty-line control parses) on 3.4.0, 3.6.2, 4.0.0, 4.4.0, 4.5.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da), and passes on main with the one-line fix shadowed; the finder's JUnit fails 2 of 3 on main (-ea, -da), 10.5.2 and 9.12.3; the independent reproduction's JUnit fails 4 of 5 on main (-ea, -da), 10.5.2 and 9.12.3; the intended-behaviour check's factory-path JUnit fails 3 of 6 on main (-ea, -da), 10.5.2 and 9.12.3; [read] all 128 release tags 3.4.0..10.5.2 in the history clone carry the identical check (the 8.8.2..8.11.4 tags are not in the clone; 8.11.4 was executed), and upstream main still has it (GitHub contents API, 2026-10-26). From 3.4 to 4.10.4 a factory with luceneMatchVersion < 3.4 used the old loader, which accepts such files; that loader is gone from 5.0.0. aarch64 with JDK 25 only (pure string handling)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (2026-10-26, read-only): a scripted prior-report search (16 apache/lucene GitHub issue and PR queries with the comments of the top 20 hits read, 3 commit queries, 20 list queries, 4 JIRA queries, 6 web queries) plus own searches: 14 more apache/lucene and 3 apache/lucene-solr issue/PR queries, full-history git log -S/--follow on the check, the changed files of all 407 open apache/lucene PRs, 18 JQL queries on the LUCENE and SOLR JIRA archive with the full LUCENE-3233, LUCENE-5219 and LUCENE-6400 threads scanned, 14 lists.apache.org queries over the Lucene and Solr lists, 13 Elasticsearch, OpenSearch and Solr tracker queries, Stack Overflow, the Elastic and OpenSearch forums and 12 general web queries. Nothing reports or discusses SolrSynonymParser rejecting a whitespace-only line. Closest items, all different: a 2019 Elastic forum thread with the same error where a team member guessed 'this might be a blank line or something in your file' (the real cause was quoted rules); #12291/#12299 (blank lines in WordlistLoader stopword files, fixed in 2023, precedent for the fix); #10073/LUCENE-9030, #7460/LUCENE-6400, LUCENE-5219, SOLR-3235 and downstream reports of the same error from other inputs (trailing comma, stop words, tokenizers). Not fixed on upstream main (line 85 unchanged); no open PR touches the logic (#16911 only deletes branch_10x). Search limits: GitHub full-text search matches phrases loosely, and the forums were searched only through their own search endpoints plus a web engine. Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
645d4fe14a20(the minimal repro with assertions on and off, standalone and through gradle; both fixes through gradle); mainea57360912ed(the hunt's, the reproducers' and the adjudication's tests; the synonym package is identical in both commits); the release jars 10.6.0 (minimal repro, assertions on and off), 10.5.2 and 9.12.3 (the hunt's JUnit tests); and a version-portable probe on 3.3.0 (class absent), 3.4.0, 3.6.2, 4.0.0, 4.4.0, 4.5.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SolrSynonymParser.java:29-33 (at ea57360912ed) (class javadoc rule 1: 'Blank lines and lines starting with '#' are comments.'), :57 (@lucene.experimental), :68-79 (parse: IllegalArgumentException rethrown as ParseException 'Invalid synonym rule at line N', reader closed), :85-86 (skip test 'line.length() == 0 || line.charAt(0) == '#'', comment 'ignore empty lines and comments'), :114-117 (alternatives split on ',' and analyze(unescape(...).trim()))lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymMap.java:374-377 (at ea57360912ed) (Parser.analyze throws 'term: ... was completely eliminated by analyzer' when nothing is left)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymGraphFilterFactory.java:71 (at ea57360912ed) (SolrSynonymParser is the default format), :155 (format null or 'solr' selects it), :163 (IOException 'Error parsing synonyms file:'); SynonymFilterFactory.java:78 (@Deprecated), :158, :166 (same)lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:43, (at ea57360912ed) :57, :107, :124, :294, :308 ('non-blank' lines with whitespace trimmed; '// skip blank lines' after trim)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SolrSynonymParser.java:33, :68-80, :82-139, :141-170 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymMap.java:341-379 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymGraphFilterFactory.java:71, :135-163, :191-193; SynonymFilterFactory.java:78, :158-166, :195 (at 645d4fe14a20)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SynonymGraphFilterFactory.java:71-72, :155-156; SynonymFilterFactory.java:72, :78; SolrSynonymParser.java:57 (at 645d4fe14a20)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SolrSynonymParser.java:33, :57, :85-86 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:43-44, :56-58, :107, :123-124, :294, :307-308 (at 645d4fe14a20)lucene/core/src/test/org/apache/lucene/analysis/TestWordlistLoader.java:86-96; lucene/CHANGES.txt:3570 (9.7.0 Bug Fixes, GITHUB#12291) (at 645d4fe14a20)lucene/analysis/common/src/test/org/apache/lucene/analysis/synonym/TestSolrSynonymParser.java:84-108 (at 645d4fe14a20)
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/SolrSynonymParser.java:85-86, :99, :105, :117 (at 645d4fe14a20)
- History
GitHub API GETs 2026-11-01: commits on SolrSynonymParser.java (last change #15681, 2026-02-11), contents at main 2f424fd428da
- TestSolrSynonymParserWhitespaceOnlyLine.java (JUnit, one test):
repro/LFV-548/src/org/apache/lucene/analysis/synonym/TestSolrSynonymParserWhitespaceOnlyLine.java(39 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the executed minimal repro.
assets/LFV-548/bug.png(485 KB)