Query parsers cannot run the full analyzer on a partial word such as м’яс* (it would be stemmed), so they call Analyzer.normalize(), which must return "the representation that it would have in the index". An analyzer supplies that through two hooks, one for char filters and one for token filters; this one implements neither.
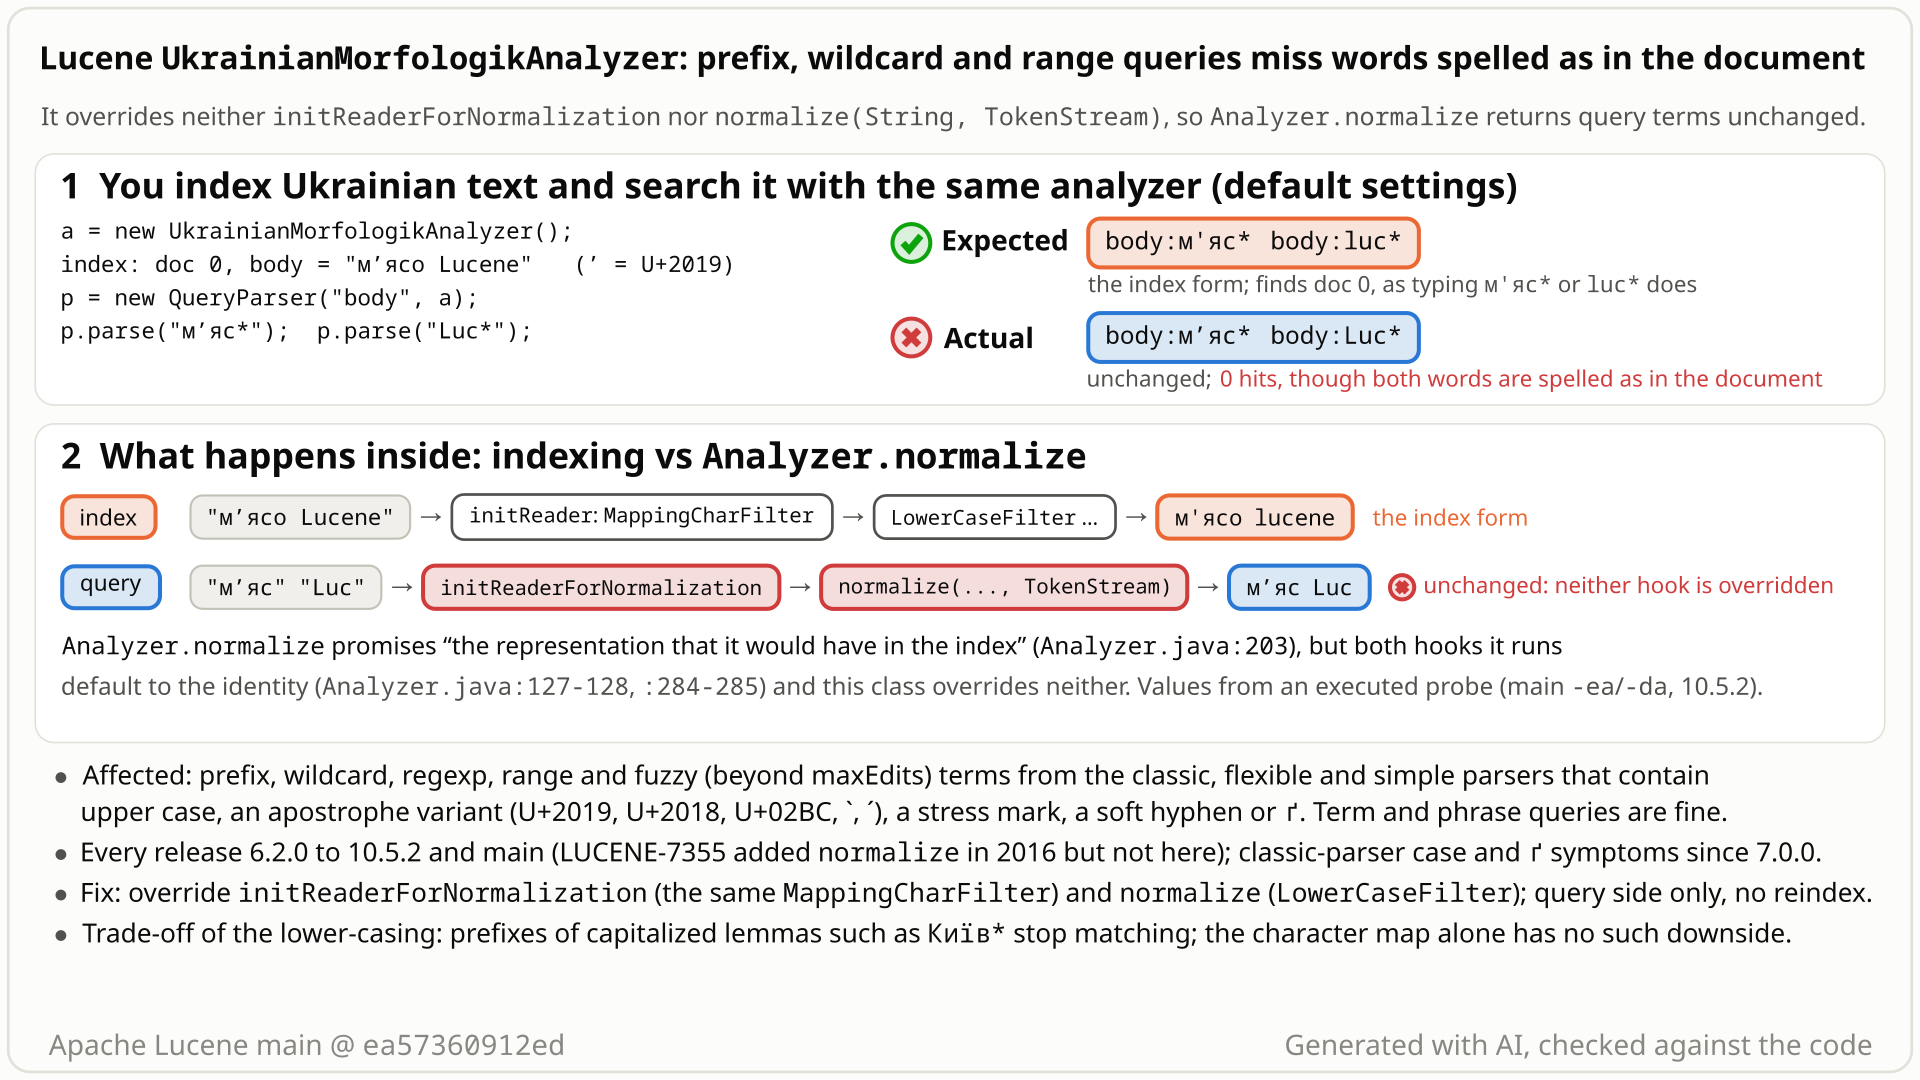
м’ясо Lucene is indexed as м'ясо lucene, while the query terms м’яс and Luc pass through both normalization hooks unchanged, so the parsed queries find 0 hits. Select the still to open it at full size. Generated with AI, checked against the code.- Index the text
м’ясо Lucene(typographic apostrophe U+2019) withnew UkrainianMorfologikAnalyzer(). The analyzer stores the termsм'ясо(plain apostrophe) andlucene(lower case). - Search with the classic
QueryParserand the same analyzer forм’яс*orLuc*, typed exactly as in the document. You expect 1 hit, asм'яс*andluc*get. - You get 0 hits, with no error. A prefix is a partial word, so the parser does not run the full analyzer on it (stemming would break it); it asks
Analyzer.normalize()for the term's index form instead. - This analyzer overrides neither of the two hooks behind
normalize(), so the term comes back unchanged:normalize("Lucene")isLucene, the prefix staysм’яс, and no indexed term starts with either. - The same happens for prefix, wildcard, regexp and range terms that keep a typographic apostrophe, a stress mark, a soft hyphen or
ґ(no indexed term contains one), and for those with a capital letter when the word is indexed in lower case (every word the dictionary does not know, and every lower-case lemma); a capitalised term still finds a capitalised dictionary lemma (Київ*findsКиїв). Term and phrase queries and the index are fine; fuzzy misses only beyond its edit distance (Lucene~1finds the document,LUCENE~2does not).
Applications that index Ukrainian text with the stock analyzer (two downstream search servers' Ukrainian plugins construct it unchanged) and accept prefix, wildcard, regexp, range or fuzzy syntax. Default settings; no scale needed. Ordinary spelling triggers it: the apostrophe inside м’ясо or п’ять, or a capital on a lower-cased word. Hits silently go missing.
Mechanism, terms and numbers674 words
UkrainianMorfologikAnalyzer normalizes every word before it is indexed: its initReader maps the apostrophe variants U+2019, U+2018, U+02BC, backtick and U+00B4 to ', removes the stress mark U+0301 and the soft hyphen U+00AD and maps ґ to г, and its chain lower-cases before the dictionary lemmatizer. So м’ясо Lucene is indexed as м'ясо and lucene. For prefix, wildcard, regexp, range and fuzzy terms the classic and flexible query parsers call Analyzer#normalize (the simple parser for prefix and fuzzy terms), documented to return "the representation that it would have in the index". The class overrides neither initReaderForNormalization nor normalize(String, TokenStream), and both default to the identity, so normalize("Lucene") returns Lucene and the parsed queries м’яс*, Luc*, Luce?e and [Lucene TO Lucene] find nothing, while м'яс* and luc* find the document. Term and phrase queries and the index are unaffected. LUCENE-7355 created normalize in 2016 and added overrides to 42 named stock analyzers (plus CustomAnalyzer), but skipped this class, committed a week before the change was authored: Analyzer#normalize is wrong in every release from 6.2.0 to 10.5.2 and main, and the classic parser's upper-case symptom starts in 7.0.0. Two overrides fix it on the query side, without reindexing. The character-mapping one has no side effect; the lower-casing one makes prefixes and ranges of capitalised dictionary lemmas such as Київ* stop matching and lower-cases regexp escapes (\D to \d), as every stock analyzer that lower-cases in normalize already does.
- Analyzer chain: the steps that turn text into indexed terms. This analyzer's chain is a
MappingCharFilter(initReader), thenStandardTokenizer->LowerCaseFilter->StopFilter-> (SetKeywordMarkerFilter) ->MorfologikFilter, the dictionary lemmatizer (UkrainianMorfologikAnalyzer.java:151-154,:165-177). NORMALIZER_MAP(:47-64): U+2019, U+2018, U+02BC, backtick and U+00B4 to'; U+0301 (stress mark) and U+00AD (soft hyphen) removed;ґ/Ґtoг/Г.- Multi-term query: prefix (
Luc*), wildcard (Luce?e), regexp (/Luc.*/), range ([a TO b]) and fuzzy (Lucene~1). Their term is a pattern or a partial word, so the parsers do not tokenize or stem it. Analyzer#normalize(field, text)(Analyzer.java:202-213): "Normalize a string down to the representation that it would have in the index. ... This method uses initReaderForNormalization ... to apply necessary character-level normalization and then normalize(String, TokenStream) in order to apply the normalizing token filters." Both hooks default to the identity (:122-129,:279-286).
- Indexing runs
initReaderandcreateComponents:м’ясо Lucenebecomes the termsм'ясоandlucene. - The parsers send multi-term terms through
normalize: classicQueryParserBase.java:550,:556(range),:646,:656(wildcard),:683(regexp),:712(prefix),:729(fuzzy); simpleSimpleQueryParser.java:573,:605; flexibleWildcardQueryNodeProcessor.java:66,:76,TermRangeQueryNodeProcessor.java:138-139,FuzzyQueryNodeProcessor.java:59,RegexpQueryNodeProcessor.java:43. - The class overrides only
initReaderandcreateComponents, sonormalizereturns its input:м’яс*staysbody:м’яс*,Luc*staysbody:Luc*. - No indexed term can contain a mapped character: every pass-through token goes through the char filter, and an exhaustive scan of all 3,485,758 entries of the bundled dictionary found none in any lemma or form. Pass-through tokens are lower-cased; a dictionary word is replaced by one or more lemmas, some capitalised. So the unchanged
м’ясandLuccannot match; a capitalised term matches only a capitalised lemma (Київ*findsКиїв).
The repro's numbers (classic QueryParser, one document м’ясо Lucene; the fuzzy row comes from the security probe's seven-document index, document Lucene)
| query | parsed as | expected | actual |
|---|---|---|---|
м'яс*, luc*, Lucene (controls) | body:м'яс*, body:luc*, body:lucene | 1 each | 1 each |
м’яс* | body:м’яс* | 1 | 0 |
Luc*, Luce?e, [Lucene TO Lucene] | unchanged | 1 each | 0 each |
Lucene~1 / LUCENE~2 (fuzzy) | unchanged | 1 / 1 | 1 / 0 |
normalize itself, with each word's indexed form checked first: Lucene -> Lucene (index lucene), м’ясо -> м’ясо (index м'ясо), м'я\u0301со -> unchanged (index м'ясо), сек\u00ADрет -> unchanged (index секрет), ґрунт -> ґрунт (index грунт).
Exposure and likelihood344 words
- Who is exposed. Applications that index with the stock
UkrainianMorfologikAnalyzerand pass multi-term syntax through the classic, flexible or simple query parser, or callAnalyzer#normalizethemselves. By code reading only, the analysis-ukrainian plugins of two downstream search servers (Elasticsearch and OpenSearch) construct the stock class unchanged; their query paths were not tested. - Default or opt-in. Default constructor, default parser settings, default
IndexWriterConfig, one document. The opt-in is the language analyzer itself (the optionalanalysis-morfologikmodule, Ukrainian-language indexes) and multi-term syntax. - Triggers. A prefix, wildcard, regexp or range term that keeps one of the five apostrophe forms the analyzer maps (U+2019, U+2018, U+02BC, backtick, U+00B4), a stress mark, a soft hyphen or
ґ(no indexed term contains one), or that has an upper-case letter where the word is indexed in lower case (every pass-through word and every lower-case lemma). A capitalised term still matches a capitalised dictionary lemma (stockКиїв*,Гет*,Чайков*: 1 hit each). The apostrophe sits inside common words (м’ясо,п’ять,сім’я);ґis a letter of the alphabet, so a correctly spelledґрунт*cannot matchгрунт. - Scale (measured on synthetic strings). A scan over every 1- and 2-character string of a 110-character multilingual alphabet plus random 3- and 4-character strings: of the 14,854 strings that index as one token (lemmatization almost entirely switched off),
normalizedisagreed with the indexed token on 7,983: 7,979 indexed as the lower-cased, mapped input and 4 as the capitalised lemmaГб, so every disagreement is a case or mapped-character difference. All 4,786 disagreeing strings checked were missed by classic, flexible and flexible multi-field prefix, wildcard, regexp and range queries and by simple-parser prefix queries; fuzzy still found 3,606. All 5,246 agreeing strings were found. - What you see. Fewer hits, no error. Term and phrase queries and the index are unaffected; for ranges an upper-case bound compares in the wrong representation and can also admit extra terms.
- No workaround inside the class. It is
final, so users cannot subclass it; anAnalyzerWrapperworks (Suggested fix, option E).
UkrainianMorfologikAnalyzer.normalize skips the apostrophe mapping its initReader applies, so normalize("f", "м’ясо") (with U+2019) differs from the indexed term.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.uk;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestUkrainianAnalyzerNormalizeApostrophe extends LuceneTestCase {

  public void testNormalizeMapsTypographicApostrophe() throws Exception {
    try (Analyzer a = new UkrainianMorfologikAnalyzer()) {
      // initReader maps U+2019 to ' so the index holds м'ясо; normalize must return the same term
      assertEquals("м'ясо", a.normalize("f", "м\u2019ясо").utf8ToString());
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-557/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/analysis/morfologik/build/libs/lucene-analysis-morfologik-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.uk.TestUkrainianAnalyzerNormalizeApostrophe
# the module(s) analysis-morfologik also need their third-party runtime jars
- Expected vs actual
- Expected "м'ясо" (the term the index holds), actual "м’ясо" (input unchanged):
expected:<м[']ясо> but was:<м[’]ясо>.
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<м[']ясо> but was:<м[’]ясо>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.uk.TestUkrainianAnalyzerNormalizeApostrophe.testNormalizeMapsTypographicApostrophe(TestUkrainianAnalyzerNormalizeApostrophe.java:27)Analyzer.normalizepromises "the representation that it would have in the index", char filters included (Analyzer.java:203-211).- LUCENE-7355 gave 42 named stock analyzers
normalizeoverrides and skipped this one; the Russian, Polish, Thai and Japanese analyzers have one. - No indexed term contains a mapped character, so keeping one can only miss. The class is final.
The full argument311 words
- Contract.
Analyzer#normalize: "Normalize a string down to the representation that it would have in the index", applying "necessary character-level normalization" throughinitReaderForNormalization(Analyzer.java:203,:209-211), which is "typically a subset of the CharFilters that are applied in initReader" (:280-282). The class's char map is namedNORMALIZER_MAP(UkrainianMorfologikAnalyzer.java:47). TheAnalyzerclass javadoc example keeps the normalization filter innormalizeand drops only the stemming filter (Analyzer.java:45-60). - MIGRATE.txt (LUCENE-7355, 7.0): "CommonQueryParserConfiguration.setLowerCaseExpandedTerms removed ... This option has been removed as expanded terms are now normalized through Analyzer#normalize."
- Siblings.
RussianAnalyzerandPolishAnalyzeroverridenormalizewithLowerCaseFilter;ThaiAnalyzerandJapaneseAnalyzeralso overrideinitReaderForNormalizationwith their char filters. This is the only stock search analyzer whose chain lower-cases and char-maps and that overrides neither hook. Two analyzers follow the convention only in part:JapaneseCompletionAnalyzerlower-cases at index time but overrides onlyinitReaderForNormalization(JapaneseCompletionAnalyzer.java:52,:62), andPersianAnalyzerchar-filters ininitReader(PersianAnalyzer.java:158-160) withoutinitReaderForNormalization, which the devil's advocate judged a tokenization aid (ZWNJ to space). - History. The class was committed on 2016-06-21 (LUCENE-7287); LUCENE-7355 (authored 2016-06-28, committed 2016-07-12) added overrides to 42 named stock analyzers (plus
CustomAnalyzer, the test framework'sMockAnalyzerand Solr'sTokenizerChain) and not to it, and no commit since has. On LUCENE-7355 its author described the design as applying "all normalization filters (lowercasing, ascii folding, etc.) but not transformations (stop word removal, stemming, etc.)". LUCENE-7841 addedґ->гbecause "the search will benefit". LUCENE-7429, the same omission inDelegatingAnalyzerWrapper, was fixed as a bug; LUCENE-8022 was resolved Invalid because the analyzer must overridenormalize, and here that analyzer is Lucene's own and final. - Tests. No upstream test asserts identity normalization;
checkRandomData(throughcheckAnalysisConsistency) only checks thatnormalizedoes not throw ("TODO: what can we do besides testing that the above method does not throw?").
The devil's-advocate check340 words
The strongest "intended" case (an intended-lens reviewer from another model family rated it moderate; the devil's advocate and the refute review weak; a later cross-model fact check moderate overall, weak for the character mapping, moderate for the lower-casing): the identity defaults are documented and optional; the classic parser's javadoc still says prefix and wildcard terms "will not go through the default Analyzer, however, since normal Analyzers are unlikely to work properly with wildcard templates" (QueryParserBase.java:610-612, :695-697; :666-668 says the same for regexps with "regular expression templates"); 265,482 of the 3,485,758 dictionary entries (7.6%) have a lemma with an upper-case letter (proper nouns such as Київ, also all-caps forms), so a lower-casing normalize makes Київ* stop matching; the dictionary replaces a word with one or more lemmas (MorfologikFilter.java:121-135), so for dictionary words no single string is "the representation that it would have in the index"; and a lower-casing normalize also lower-cases regexp escapes and range bounds.
Why it fails: optional defaults let arbitrary analyzers skip the hooks; they do not say a stock analyzer that lower-cases and char-maps should, and every other such stock analyzer got at least one of the two overrides. The parser javadoc is outdated rather than a statement of intent: it still describes the removed lowercaseExpandedTerms setting ("Depending on settings, ... may be lower-cased automatically") and does not mention that the same methods call getAnalyzer().normalize(...) (:683, :712); MIGRATE.txt says expanded terms "are now normalized through Analyzer#normalize". Its "will not go through the default Analyzer" is still true of the full chain. The capitalised-lemma and one-to-many points concern only the lower-casing half: normalize can be exact only for pass-through words, and those are lower-cased; in the history probe's classic-parser runs the capitalised-lemma match exists only since 7.0.0 (the 6.x classic parser lower-cased the terms and missed Київ* too). The regexp-escape effect is what StandardAnalyzer already does on main (/\D+/ becomes /\d+/). The character-mapping half has no trade-off at all: no indexed term can contain a mapped character.
Recommended Override only initReaderForNormalization (+5 lines): no side effect, the suggested first step
Lead with an override that has no side effect: initReaderForNormalization returning new MappingCharFilter(NORMALIZER_MAP, reader) (+5 lines, query side only, no reindex) fixes the apostrophe, stress-mark, soft-hyphen and ґ misses. Offer normalize returning new LowerCaseFilter(in) for discussion: it fixes Luc*, but capitalised lemmas (Київ*) stop matching and regexp escapes get lower-cased.
+  @Override
+  protected Reader initReaderForNormalization(String fieldName, Reader reader) {
+    return new MappingCharFilter(NORMALIZER_MAP, reader);
+  }
All options and trade-offs5 options · 1,178 words
Suggested route: lead with option B and offer option A's lower-casing for discussion (the adjudication's advice and the cross-model fact check's); proposing A in one change with its trade-offs stated is the other route. Option A was validated in a scratch worktree at ea57360912ed (removed afterwards); option B through gradle (the repro, and the whole module in the fact checker's run) and the runner; the option-B variant of testNormalize through the runner; option E on main through the runner. The trade-off tables come from two classic-parser probes run against stock, A and B.
Override initReaderForNormalization and normalize (+10 lines): the complete fix for lower-cased words, with trade-offs (validated by the checks)
initReaderForNormalization reuses the existing NORMALIZER_MAP; normalize applies LowerCaseFilter, as RussianAnalyzer and PolishAnalyzer do. Query side only: indexing does not call these hooks. The code below is the whole file, which git apply applies to ea57360912ed. fix-with-test.diff adds testNormalize to TestUkrainianAnalyzer (the PR shape for this route). Add a CHANGES entry under Bug Fixes, and fix the outdated QueryParserBase javadoc in the same change (option C).
diff --git a/lucene/analysis/morfologik/src/java/org/apache/lucene/analysis/uk/UkrainianMorfologikAnalyzer.java b/lucene/analysis/morfologik/src/java/org/apache/lucene/analysis/uk/UkrainianMorfologikAnalyzer.java
index 3915d264d7f..c3b8468b666 100644
--- a/lucene/analysis/morfologik/src/java/org/apache/lucene/analysis/uk/UkrainianMorfologikAnalyzer.java
+++ b/lucene/analysis/morfologik/src/java/org/apache/lucene/analysis/uk/UkrainianMorfologikAnalyzer.java
@@ -153,6 +153,16 @@ public final class UkrainianMorfologikAnalyzer extends StopwordAnalyzerBase {
     return new MappingCharFilter(NORMALIZER_MAP, reader);
   }

+  @Override
+  protected Reader initReaderForNormalization(String fieldName, Reader reader) {
+    return new MappingCharFilter(NORMALIZER_MAP, reader);
+  }
+
+  @Override
+  protected TokenStream normalize(String fieldName, TokenStream in) {
+    return new LowerCaseFilter(in);
+  }
+
   /**
    * Creates a {@link org.apache.lucene.analysis.Analyzer.TokenStreamComponents} which tokenizes all
    * the text in the provided {@link Reader}.
Trade-offs
Prefixes of capitalised dictionary lemmas stop matching, because the index holds them capitalised and the query term is now lower-cased (classic parser; documents м’ясо Lucene, Київ, Цих Чайковського і Ґете.):
| query | stock | option A | option B |
|---|---|---|---|
м’яс* | 0 | 1 | 1 |
Luc*, Luce?e, [Lucene TO Lucene] | 0 each | 1 each | 0 each |
Київ* (lemma Київ) | 1 | 0 | 1 |
Гет* (lemma Гете) | 1 | 0 | 1 |
Ґет* | 0 | 0 | 1 |
Чайков* (lemma Чайковський) | 1 | 0 | 1 |
київ* | 0 | 0 | 0 |
A prefix typed in lower case (київ*) finds nothing on stock, A or B; in the history probe's classic-parser runs the capitalised-lemma match exists only since 7.0.0 (the 6.x classic parser lower-cased the terms). 265,482 of the 3,485,758 dictionary entries (7.6%) have a lemma with an upper-case letter. SOLR-11835 (2018) says the dictionary holds proper names in lower case since 6.6; on main the analyzer emits capitalised lemmas (testCapsTokenStream asserts Чайковське, Чайковський and Гете; the probes show Київ), so reconcile the two before describing the side effect. Cost: one MappingCharFilter and one LowerCaseFilter over one query term; nothing at index time.
The whole regexp is lower-cased, escapes included, so \D, \S, \W become \d, \s, \w (the opposite classes) and [^L] becomes [^l]; a range bound on a capitalised lemma stops matching. StandardAnalyzer, whose normalize already lower-cases, does the same to regexps today; with its lower-cased index the range still matches (parsed query and hits; the probe also indexes the document 2026):
| query | stock | option A | option B | StandardAnalyzer (control) |
|---|---|---|---|---|
/\D+/ | /\D+/ 3 | /\d+/ 1 | /\D+/ 3 | /\d+/ 1 |
/\S+/ | /\S+/ 4 | /\s+/ 0 | /\S+/ 4 | /\s+/ 0 |
/\W+/ | /\W+/ 3 | /\w+/ 2 | /\W+/ 3 | /\w+/ 2 |
/[^L]ucene/ | /[^L]ucene/ 1 | /[^l]ucene/ 0 | /[^L]ucene/ 1 | /[^l]ucene/ 0 |
[Київ TO Київ] | 1 | [київ TO київ] 0 | 1 | [київ TO київ] 1 |
The regexp and range cases are in no repro or security-probe test; they come only from this measurement probe. The lower-casing half also turns a deny prefix written with a capitalised lemma (*:* -Київ*) into a no-op, so prefix rules on this field stay best effort either way.
What the checks validated
- Scratch worktree at
ea57360912ed: the repro passes with assertions on and off (it fails on stock);TestUkrainianAnalyzer8 tests (9 withtestNormalize), the wholeanalysis-morfologiksuite (21 tests with the repro, 22 withtestNormalize, assertions on and off) and:lucene:analysis:morfologik:check(google-java-format, ecj, forbidden APIs) pass.testNormalizefails on stock at its first assertion. - As a shadow source on main: the parser-level test 2 of 2, the independent reproducer's test 4 of 4, the intended-lens probe 2 of 2, the security probe 17 of 17. Back-ported to 7.0.0 every history-probe group passes; on 6.2.0 and 6.6.6 the normalize and simple-parser groups.
Override only initReaderForNormalization (+5 lines): no side effect, the suggested first step (validated by the checks) (recommended)
The character-mapping half alone: initReaderForNormalization returning new MappingCharFilter(NORMALIZER_MAP, reader). The snippet shows the added lines.
+  @Override
+  protected Reader initReaderForNormalization(String fieldName, Reader reader) {
+    return new MappingCharFilter(NORMALIZER_MAP, reader);
+  }
Trade-offs
No side effect: no indexed term contains a mapped character, so nothing that matches today stops matching; Ґет* starts to find Гете; regexps and ranges keep their stock behaviour (option A's tables). Upper-case terms (Luc*, Luce?e, [Lucene TO Lucene]) still miss lower-cased words; the lower-casing can follow as a separate, discussed change.
What the checks validated
The repro then fails only on the upper-case entries ([Lucene -> Lucene (index holds lucene)], [Luc* -> body:Luc* hits=0]), through gradle and the runner; the fact checker's gradle run of the whole module with option B: 21 tests, 2 failures, only those repro entries, the 19 existing module tests pass. A test change for this route (testNormalize without its upper-case assertion, 5 assertions) passes git apply --check; through the runner TestUkrainianAnalyzer with it fails 1 of 9 on stock (м’ясо keeps U+2019) and passes 9 of 9 with option B and with option A, assertions on and off. It was not run through gradle check (it is the checked testukrainiananalyzer-test.diff minus one assertion line, with a shorter javadoc line). Trade-off columns B in option A's tables.
QueryParserBase.java:610-612, :666-668, :695-697 still say that, "depending on settings", the term "may be lower-cased automatically" (the lowercaseExpandedTerms setting removed in 7.0) and that it "will not go through the default Analyzer" (still true of the full chain); they do not say that the term goes through Analyzer#normalize. Documentation only; goes with A or B. Not built.
Would remove the capitalised-lemma trade-off of option A.
Trade-offs
Changes the indexed terms (reindex), breaks the upstream assertion testCapsTokenStream (Чайковське, Чайковський, Гете) and changes term queries. Not run.
Wrap the stock analyzer in an AnalyzerWrapper whose wrapReaderForNormalization applies a copy of the nine-entry map (the original is private) and whose wrapTokenStreamForNormalization applies LowerCaseFilter; use it for indexing and parsing (indexing is unchanged).
Trade-offs
Same capitalised-lemma trade-off as option A; the copied map must be kept in sync by hand.
What the checks validated
On main with the classic parser: stock м’яс*, Luc*, Luce?e find 0; with the wrapper they, lucene and the phrase "м’ясо Lucene" find the document (1 each).
Why: a term that keeps a mapped character never equals an indexed term, and a capitalised term misses every lower-cased word (only capitalised lemmas such as Київ match), so a NOT rule written that way excludes nothing (*:* -Секрет* still returns секрет). Only the rule's author causes it. Out of scope of SECURITY.md; no known exploit.
An AI finder ran a bounded-exhaustive metamorphic scan on the stock main jars: Analyzer.normalize(w) must equal the single token indexing produces for w, over all short strings of a multilingual alphabet. The Ukrainian analyzer disagreed on 7,983 of 14,854; every checked disagreeing string was missed by every non-fuzzy parser path. Code reading found the missing overrides.
The method in full296 words
Method: bounded-exhaustive metamorphic testing, a hunt unit (analyzer normalize consistency), 2026-10-26 (the hunt's "semi-formal" tier).
- Inputs: 20,207 strings, every 1- and 2-character string over an explicit 110-code-point multilingual alphabet plus random 3- and 4-character strings (fixed seed).
- Relation N1: for every stock analyzer and every input
wthat indexes as exactly one full-span token,Analyzer.normalize(f, w)equals that token.UkrainianMorfologikAnalyzerdisagreed on 7,983 of 14,854 compared strings with lemmatization (almost entirely) switched off through the stem exclusion set (7,971 of 14,838 with the default constructor); the disagreements are case and mapped-character differences (7,979 indexed as the lower-cased, mapped input, 4 as the capitalised lemmaГб; the fact checker's re-run). - Relation N2 (parser reachability): each string, indexed alone, must be found by its own prefix, wildcard, regexp, range and fuzzy query through the classic, flexible, flexible multi-field and simple parsers. All 4,786 checked disagreeing strings were missed by every non-fuzzy path; fuzzy found 3,606; all 5,246 agreeing strings were found.
- Then: a public-API JUnit; a review by an independent reviewer from another model family (OpenAI GPT-5.6, read-only: "not real, low", procedural, because it could not run its own test; it agreed with the root cause); an independent reproducer; an intended-behaviour review by the same model family (read-only: real, medium); a devil's advocate (with an exhaustive scan of the bundled dictionary); an adjudication; a history sweep; a prior-report search; a security assessment; a registry re-run; an audit. Neither reviewer from the other model family ran code; separate runs re-ran the finder's test, which failed.
- Afterwards: a fact check of the brief and this doc (it re-ran the repro, the fix variants and the probes) and a read-only fact check by the other model family corrected overstatements about upper-case terms and added the regexp and range trade-offs.
No prior report: 90 tool and 36 manual queries over GitHub issues, PRs and commits, JIRA, four mailing lists, downstream repositories and the web, plus the changed files of all 407 open PRs (2026-10-26). Closest: LUCENE-7429, the same omission in DelegatingAnalyzerWrapper, fixed as a bug.
Searches5 searches
32 hits read, none this bug. Limits: keyword search only; forums only through general web search; private security@ reports are invisible. Hunt sibling: LFV-534 (SerbianAnalyzer.normalize omits SerbianNormalizationFilter), the same bug class from the same hunt with a different fix site.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | a scripted prior-report search (26 issue and PR queries, 4 commit queries) and manual queries, including two all-of-GitHub class-name searches; the changed files of all 407 open PRs | no report; #8342 (adds the class), #8409 (adds normalize), #8892 and #8836 (widened the map in initReader only) never discuss multi-term queries; the only open PR touching the file (#16911) deletes branch_10x |
| Related items (read) | 2026-10-26 | full-text regex scans of 12 JIRA and 13 GitHub issues | #8482 (LUCENE-7429, DelegatingAnalyzerWrapper skipped by LUCENE-7355, fixed as a bug); #9070 (LUCENE-8022, a user's analyzer without normalize, Invalid); #9234, #8657, #9141 (CustomAnalyzer and factory normalization, other classes); #8489 (wildcard tokenization) |
| JIRA archive (LUCENE, SOLR) | 2026-10-26 | 10 tool and 6 manual JQL queries | no report; SOLR-11835 (dictionary proper names, relevant to the fix trade-off) |
| Mailing lists | 2026-10-26 | 40 tool queries over dev@, java-user@, issues@, commits@; a manual "Ukrainian" search over six lists (356 mails, every subject read) | no thread about multi-term queries with this analyzer |
| Downstream and web | 2026-10-26 | 4 tool and 8 manual downstream-repository queries; 6 tool and 9 manual web queries (one in Ukrainian) | generic wildcard-normalization items in other code only |
Missing since LUCENE-7355 created Analyzer#normalize (authored 2016-06-28, committed 2016-07-12, first released in 6.2.0) and added overrides to 42 named stock analyzers, skipping this one, committed a week before the change was authored. The classic-parser upper-case and ґ symptoms start in 7.0.0. Executed on 6.2.0, 6.6.6, 7.0.0, 8.11.4, 9.12.3, 10.5.2 and main.
Versions tested7 rows
Introduced by the omission in LUCENE-7355 (GitHub #8409, "Leverage MultiTermAwareComponent in query parsers"; JIRA patch, by jpountz; commit subject "Add Analyzer#normalize() and use it in query parsers"): 7c2e7a0fb80 on branch_6x (first released in 6.2.0) and e92a38af90d on master (first released in 7.0.0), both authored 2016-06-28 and committed 2016-07-12. The analyzer came with LUCENE-7287 (#8342), 6ef174f5273 / 4a71e03a32f, 2016-06-21, with the char filter and LowerCaseFilter from the start. git log --all -G 'normalize|initReaderForNormalization' on the file returns nothing.
The master commit also removed the parsers' lowercaseExpandedTerms (MIGRATE.txt), which exposed the upper-case half in the classic parser from 7.0.0. LUCENE-7785 (2017-04-19) and LUCENE-7841 (effd3766e7f, 2017-05-25) widened the map in initReader only; the ґ mapping first shipped in 7.0.0.
| Version or commit | Verdict | Result |
|---|---|---|
main ea57360912ed | affected | fails with -ea and -da, through gradle and the runner |
upstream main ffa9d816eeb4, a95c754ee003 | read | same code on 2026-10-26 (the fact checker's read), not fixed |
| 10.5.2, 9.12.3 | affected | fail (release jars; 10.5.2 with -ea and -da, 9.12.3 with -ea) |
| 8.11.4, 7.0.0 | affected | every probe group fails; the back-ported fix passes on 7.0.0 |
| 6.6.6, 6.2.0 | first affected (6.2.0) | normalize and simple-parser prefix fail; the classic parser lower-cased expanded terms itself, so Luc* matches, and did not analyze prefix terms, so the classic м’яс* miss there is a 6.x parser limitation; the back-ported fix makes the normalize and simple-parser groups pass |
| 6.1.0 | last unaffected | neither the class nor Analyzer#normalize exists (compile error) |
| the other 75 release tags 6.2.1 to 10.5.1 | read | the file lower-cases and char-maps and has no override (8.8.2 to 8.11.3 inferred) |
An independent reproducer, a devil's advocate, an adjudication and an intended-lens reviewer from another model family say real; a refute-lens review by that family said "not real" only because it could not run code. The adjudication, a registry re-run, an audit and this doc's gradle run all saw it fail on stock and pass with the fix.
Checks and verdicts535 words
Neither cross-model reviewer ran code of its own; every executed check was run by the hunt's own AI tools and runner.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit) | candidate | N1/N2 scans; the parser-level JUnit fails 2 of 2 on main (-ea, -da), 10.5.2 and 9.12.3; the fix passes, and TestUkrainianAnalyzer 8 of 8 with it. |
| review (OpenAI GPT-5.6, read-only) | not real (low), procedural | Could not write or run a test; agreed with the root cause, judged the inputs in contract, rated the intended case weak. A separate run re-ran the JUnit: fails 2 of 2. |
| Independent reproducer | real | Own JUnit: 3 of 4 fail on main (-ea, -da), 10.5.2, 9.12.3, the RussianAnalyzer control passes; own fix 4 of 4; cross-version runs 6.2.0 to main; the trade-off probe. |
| Intended-lens review (OpenAI GPT-5.6, read-only) | real (medium); intended case moderate, rejected | Root cause agreed, fix judged correct (static). A separate probe fails 1 of 2 on main and passes with the fix. |
| Devil's advocate | real | Built and refuted the intended case; scanned all 3,485,758 dictionary entries (none with a mapped character; 7.6% capitalised lemmas). |
| Adjudication | confirmed, high | Re-ran the independent reproduction's JUnit (seed 5EED1234: 3 of 4 fail; 4 of 4 with the fix) and the finder's with -da (2 of 2 fail). |
| Security assessment | out of scope of SECURITY.md | Security probe: 13 of 17 fail on main (-ea, -da) and 10.5.2 (deny rules that exclude nothing, three over-matching allow rules); 17 of 17 with the fix. |
| Registry re-run and audit | keep | Fresh seeds: the finder's JUnit fails 2 of 2 (-ea, -da), the independent reproduction's fails 3 of 4 (-da, main and 10.5.2) and passes 4 of 4 with the fix. |
| This doc's fix validation | reproduced; fix validated | Gradle in a scratch worktree: the new module repro fails on stock (asserts on and off); with the fix it, TestUkrainianAnalyzer, the whole module suite and check pass; 10.5.2 and 9.12.3 jars fail through the runner. |
| Fact check of the brief and this doc | bug confirmed; 2 wording errors, fixed | Re-ran the gradle repro (2 of 2 fail, assertions on and off), the runner on main, 10.5.2 and 9.12.3, the fix variants, the module check, the trade-off, security and workaround probes, and the N1 scan; every number matched. Its two errors (an overstatement about capital letters; a truncated patch block) and its minor findings are fixed. |
| Cross-model fact check (OpenAI GPT-5.6, read-only) | core bug real; 7 errors, 12 overclaims, 6 missing caveats, fixed | Found the same capital-letter overstatement, the missing regexp and range trade-offs of the lower-casing half (now executed) and counter-precedents; advised leading with option B. Every item is fixed or answered. |
| Correction to the registry row | registry wording to update | The registry row's impact, likelihood and security notes still say upper-case terms always miss ("whenever the query term has an upper-case letter", "misses deterministically", "excludes nothing when its term has an upper-case letter"). As this doc now says, that holds for mapped characters, and for capital letters only against lower-cased words: capitalised dictionary lemmas such as Київ still match. The row is outside this step's files. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 463 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,632 words
- Registry title
- UkrainianMorfologikAnalyzer overrides neither normalize() nor initReaderForNormalization, so prefix, wildcard, regexp, range and fuzzy terms from the query parsers skip its lower-casing and its apostrophe, stress-mark, soft-hyphen and ґ mapping and miss words spelled exactly as in the document
- Area
- analysis-morfologik / language analyzers (UkrainianMorfologikAnalyzer normalization: Analyzer#normalize and initReaderForNormalization, used by the query parsers for multi-term queries)
- Priority
- Medium, rank 120: The stock Ukrainian analyzer skips its normalization for every multi-term query, so ordinary capitalised or apostrophe words miss silently.
- Impact class
- silent wrong results
- Impact note
- Every application that indexes text with the stock UkrainianMorfologikAnalyzer and accepts prefix, wildcard, regexp, range or fuzzy syntax through Lucene's classic, flexible or simple query parser (or calls Analyzer.normalize itself) silently gets too few hits, and for ranges sometimes extra terms, whenever the query term has an upper-case letter, a typographic apostrophe (U+2019, U+02BC, U+2018, backtick, U+00B4), a stress mark (U+0301), a soft hyphen (U+00AD) or ґ, because the index holds only the lower-cased, mapped form; term and phrase queries and the indexed data are unaffected, no setting or scale is needed, every release from 6.2.0 to 10.5.2 and main has it (the classic-parser case symptom from 7.0.0), and by code reading two downstream search servers' Ukrainian analysis plugins expose the stock class unchanged.
- Summary
- You index Ukrainian text with UkrainianMorfologikAnalyzer, which maps typographic apostrophes to ', removes stress marks and soft hyphens, maps ґ to г and lower-cases every token before lemmatizing, so the document 'м’ясо Lucene' is stored as the terms м'ясо and lucene. A prefix, wildcard, regexp, range or fuzzy query built by a query parser sends its term through Analyzer.normalize, documented to return 'the representation that it would have in the index', but this analyzer overrides neither normalize(String, TokenStream) nor initReaderForNormalization, so normalize returns the text unchanged. As a result 'м’яс*', 'Luc*', 'Luce?e' and '[Lucene TO Lucene]' find nothing while "м'яс*" and 'luc*' find the document, and normalize("Lucene") returns 'Lucene' although the index holds 'lucene'.
- Introduced
- 7c2e7a0fb80a5bf733cf710aee6cbf01d02629eb on branch_6x (first released in 6.2.0) and its master twin e92a38af90d12e51390b4307ccbe0c24ac7b6b4e (first released in 7.0.0): LUCENE-7355 'Add Analyzer#normalize() and use it in query parsers' (GitHub issue apache/lucene#8409, JIRA patch, no PR), which created Analyzer#normalize, normalize(String, TokenStream) and initReaderForNormalization and added overrides to 42 stock analyzers but not to UkrainianMorfologikAnalyzer, which the parent of both commits already contains [read: the two diffs; git log --all -G 'normalize|initReaderForNormalization' on the file returns nothing, so no branch ever had either override]. The analyzer came one week earlier with LUCENE-7287 (6ef174f5273 on master / 4a71e03a32f on branch_6x, 2016-06-21, apache/lucene#8342), with the MappingCharFilter in initReader and the LowerCaseFilter from the start. The master commit also removed the parsers' lowercaseExpandedTerms (MIGRATE.txt), which exposed the case half in the classic parser from 7.0.0; LUCENE-7785 (2017-04-19) and LUCENE-7841 (effd3766e7f, 2017-05-25) later widened the map in initReader only (2016-06-28 (LUCENE-7355, both branches; the analyzer itself 2016-06-21))
- First affected version
- 6.2.0 [exec] (Analyzer.normalize and the simple parser's prefix query fail; with the back-ported two-method fix they pass on 6.2.0 and 6.6.6); the classic-parser case symptom and the ґ symptom start in 7.0.0 [exec] (6.x classic parsers lower-cased expanded terms themselves, and the ґ mapping first shipped in 7.0.0); 6.1.0 has neither the class nor Analyzer.normalize [exec, compile error]
- Affected versions
- Every release 6.2.0 to 10.5.2 and main ea57360912ed. [exec] the follow-up's portable history probe (-ea, seed DEADBEEF) on 6.2.0, 6.6.6, 7.0.0, 8.11.4, 9.12.3, 10.5.2 and main, every control passing; the finder's JUnit (2 of 2 fail) on main (-ea and -da), 10.5.2 and 9.12.3; the independent reproduction's JUnit (3 of 4 fail, its control passes) on main (-ea and -da), 10.5.2 and 9.12.3, and the independent reproduction's cross-version runs on 6.2.0, 6.6.6, 7.0.0 and 8.11.4; the fix back-ported to 7.0.0 makes every bug group pass, and back-ported to 6.2.0 and 6.6.6 the normalize and simple-parser groups. [read] the other 75 release tags 6.2.1 to 10.5.1 in the history clone (the file lower-cases and char-maps and has no normalization override); 8.8.2 to 8.11.3 inferred (not tagged in the history clone, between 8.8.1 [read] and 8.11.4 [exec]). In 6.x the classic parser's apostrophe miss is a limitation of the 6.x parser (the fix does not change it there), not this bug. Upstream apache/lucene main ffa9d816eeb4 (2026-10-26) is unchanged [read]. Not affected: 6.1.0 (API absent) [exec]. Not executed: x86
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record verdict new): a scripted prior-report search (26 GitHub issue and PR queries on apache/lucene, 4 commit, 4 downstream-repository, 40 mailing-list queries over dev@, java-user@, issues@ and commits@, 10 JIRA-archive queries, 6 web queries) plus the finder's earlier run; 36 manual queries (GitHub search including two all-of-GitHub class-name searches, 6 JQL queries over LUCENE and SOLR, a 'Ukrainian' search over six lists with 356 mails whose subjects were all read, 8 downstream-repository queries, 9 web searches, one in Ukrainian); full-text regex scans of 12 JIRA and 13 GitHub issues; the changed-file lists of all 407 open PRs; git history. 32 hits read, none the same bug. The issues that created or changed this analyzer's normalization (#8342 LUCENE-7287, #8836 LUCENE-7785, #8892 LUCENE-7841) and #8409 (LUCENE-7355) never mention normalize() or multi-term queries for this class. Related, not reports: #8482 (LUCENE-7429, DelegatingAnalyzerWrapper skipped by LUCENE-7355, fixed as a bug), #9070 (LUCENE-8022, a user's own analyzer without normalize, resolved Invalid: the analyzer must override normalize), #9234, #8657 and #9141 (CustomAnalyzer and factory normalization bugs, other classes), #8489 (open, wildcard tokenization); downstream generic wildcard items elastic/elasticsearch#84191, #43759 and #121281 and opensearch-project/OpenSearch#20843 (ASCII-only case folding in that engine's own wildcard field) are other code. Not fixed: upstream main ffa9d816eeb4 (2026-10-26) still has only initReader; the only open PR that touches the file (#16911) deletes branch_10x. Gaps: keyword search; forums reached only through general web search; private reports not visible. Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
ea57360912ed(commit of 2026-10-24; tested 2026-10-26): the repro through gradle in a scratch worktree (stock fails with assertions on and off; with the two-override fix it passes, and so doTestUkrainianAnalyzer, the wholeanalysis-morfologiktest suite with assertions on and off and:lucene:analysis:morfologik:check; the worktree was removed afterwards) and through the standalone JUnit runner on main (-ea,-da) and on the Maven Central jars of 10.5.2 (-ea,-da) and 9.12.3 (-ea) (fail), and on main with the fix as shadow source (pass); the follow-up's portable probe on 6.2.0, 6.6.6, 7.0.0 and 8.11.4 (fail) and 6.1.0 (class absent); upstream mainffa9d816eeb4read on 2026-10-26 anda95c754ee003(same code, not fixed); the regexp and range trade-off probe and the option-B variant oftestNormalizethrough the runner on main (2026-10-26). The fix was validated on main only (plus the follow-up's back-ports to 6.2.0, 6.6.6 and 7.0.0).
- Finding record
lucene/analysis/morfologik/src/java/org/apache/lucene/analysis/uk/UkrainianMorfologikAnalyzer.java:38-43 (at ea57360912ed) (class javadoc '@since 6.2.0', final class), :47-64 (NORMALIZER_MAP: U+2019, U+2018, U+02BC, backtick, U+00B4 to ', U+0301 and U+00AD removed, ґ/Ґ to г/Г), :151-154 (initReader: MappingCharFilter), :165-177 (createComponents: StandardTokenizer -> LowerCaseFilter -> StopFilter -> [SetKeywordMarkerFilter] -> MorfologikFilter); no normalize or initReaderForNormalization overridelucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:122-129 (at ea57360912ed) (normalize(String, TokenStream) default returns the stream as-is), :202-213 (normalize(String, String): 'the representation that it would have in the index', applies 'necessary character-level normalization' through initReaderForNormalization), :279-286 (initReaderForNormalization: 'typically a subset of the CharFilters that are applied in initReader', default returns the reader unchanged)lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:550, (at ea57360912ed) :556 (range bounds), :646, :656 (wildcard chunks), :683 (regexp), :712 (prefix), :729 (fuzzy) call Analyzer.normalize; :610-612, :666-668, :695-697 (stale javadoc 'will not go through the default Analyzer'); lucene/queryparser/src/java/org/apache/lucene/queryparser/simple/SimpleQueryParser.java:573 (fuzzy), :605 (prefix); the flexible WildcardQueryNodeProcessor, TermRangeQueryNodeProcessor, FuzzyQueryNodeProcessor and RegexpQueryNodeProcessor (follow-up the security record sources)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionAnalyzer.java:48-64 (at ea57360912ed) and lucene/demo/src/java/org/apache/lucene/demo/knn/DemoEmbeddings.java:41-51 (grep over src/java trees: the other analyzers whose chain lower-cases without a normalize(String, TokenStream) override)https://github.com/apache/lucene/issues/8409 (LUCENE-7355, introduces Analyzer#normalize), https://github.com/apache/lucene/issues/8342 (LUCENE-7287, the analyzer), https://github.com/apache/lucene/issues/8892 (LUCENE-7841, ґ to г 'the search will benefit'), https://github.com/apache/lucene/issues/8482 (LUCENE-7429, precedent fixed as a bug), https://github.com/apache/lucene/issues/9070 (LUCENE-8022, the analyzer must override normalize)
- The finding in 30 seconds
Lucene main ea57360912ed: lucene/analysis/morfologik/src/java/org/apache/lucene/analysis/uk/UkrainianMorfologikAnalyzer.java:43 (public final class), :47-64 (NORMALIZER_MAP), :151-154 (initReader), :165-177 (createComponents); no normalize or initReaderForNormalization overrideLucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:122-129, :202-213, :279-286Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:550, :556, :646, :656, :683, :712, :729; lucene/queryparser/src/java/org/apache/lucene/queryparser/simple/SimpleQueryParser.java:573, :605; lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/processors/WildcardQueryNodeProcessor.java:66, :76, TermRangeQueryNodeProcessor.java:138-139, FuzzyQueryNodeProcessor.java:59, RegexpQueryNodeProcessor.java:43
- Who is affected
Lucene main ea57360912ed: lucene/analysis/morfologik/src/java/org/apache/lucene/analysis/uk/UkrainianMorfologikAnalyzer.java:43, :47-64
- Why it looks unintended
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:45-60, :122-129, :202-213, :279-286Lucene main ea57360912ed: lucene/analysis/morfologik/src/java/org/apache/lucene/analysis/uk/UkrainianMorfologikAnalyzer.java:47-64Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:610-612, :666-668, :695-697, :683, :712Lucene main ea57360912ed: lucene/analysis/common/src/java/org/apache/lucene/analysis/ru/RussianAnalyzer.java:119-121; lucene/analysis/stempel/src/java/org/apache/lucene/analysis/pl/PolishAnalyzer.java:145-147; lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:112-128; lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseAnalyzer.java:120-133Lucene main ea57360912ed: lucene/test-framework/src/java/org/apache/lucene/tests/analysis/BaseTokenStreamTestCase.java:1478-1479Lucene main ea57360912ed: lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionAnalyzer.java:52, :62; lucene/analysis/common/src/java/org/apache/lucene/analysis/fa/PersianAnalyzer.java:147-149, :158-160; lucene/analysis/morfologik/src/java/org/apache/lucene/analysis/morfologik/MorfologikFilter.java:121-135
- Suggested fix
Lucene main ea57360912ed: lucene/analysis/morfologik/src/test/org/apache/lucene/analysis/uk/TestUkrainianAnalyzer.java:64-69 (testCapsTokenStream)Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/analysis/AnalyzerWrapper.java:90, :114 (wrapTokenStreamForNormalization, wrapReaderForNormalization)
- TestUkrainianAnalyzerNormalizeApostrophe.java (JUnit test):
repro/LFV-557/src/org/apache/lucene/analysis/uk/TestUkrainianAnalyzerNormalizeApostrophe.java(30 lines)
A light, step-by-step picture of the finder's example (one document м’ясо Lucene, the classic parser, м’яс* and Luc*), made in parallel with this doc. Every value on screen comes from an executed probe on main ea57360912ed (assertions on and off, and with the fix shadowed) and 10.5.2, or from the code; the PNG is the summary card.
assets/LFV-557/bug.png(463 KB)