A boosted MoreLikeThis query cannot be built when one of its selected terms scores exactly 0.
MoreLikeThis.like(...)turns a text or a stored document into a query that finds similar documents. It scores each term as tf × idf, keeps the bestmaxQueryTerms(default 25) and ORs them asTermQueryclauses.- The idf comes from a
TFIDFSimilarity: the defaultClassicSimilarity, whose idf is at least 1, or one the application passes to the constructor or tosetSimilarity. - With
setBoost(true)(off by default) each clause is wrapped in aBoostQueryscaled by its term's score, so more interesting terms count more.
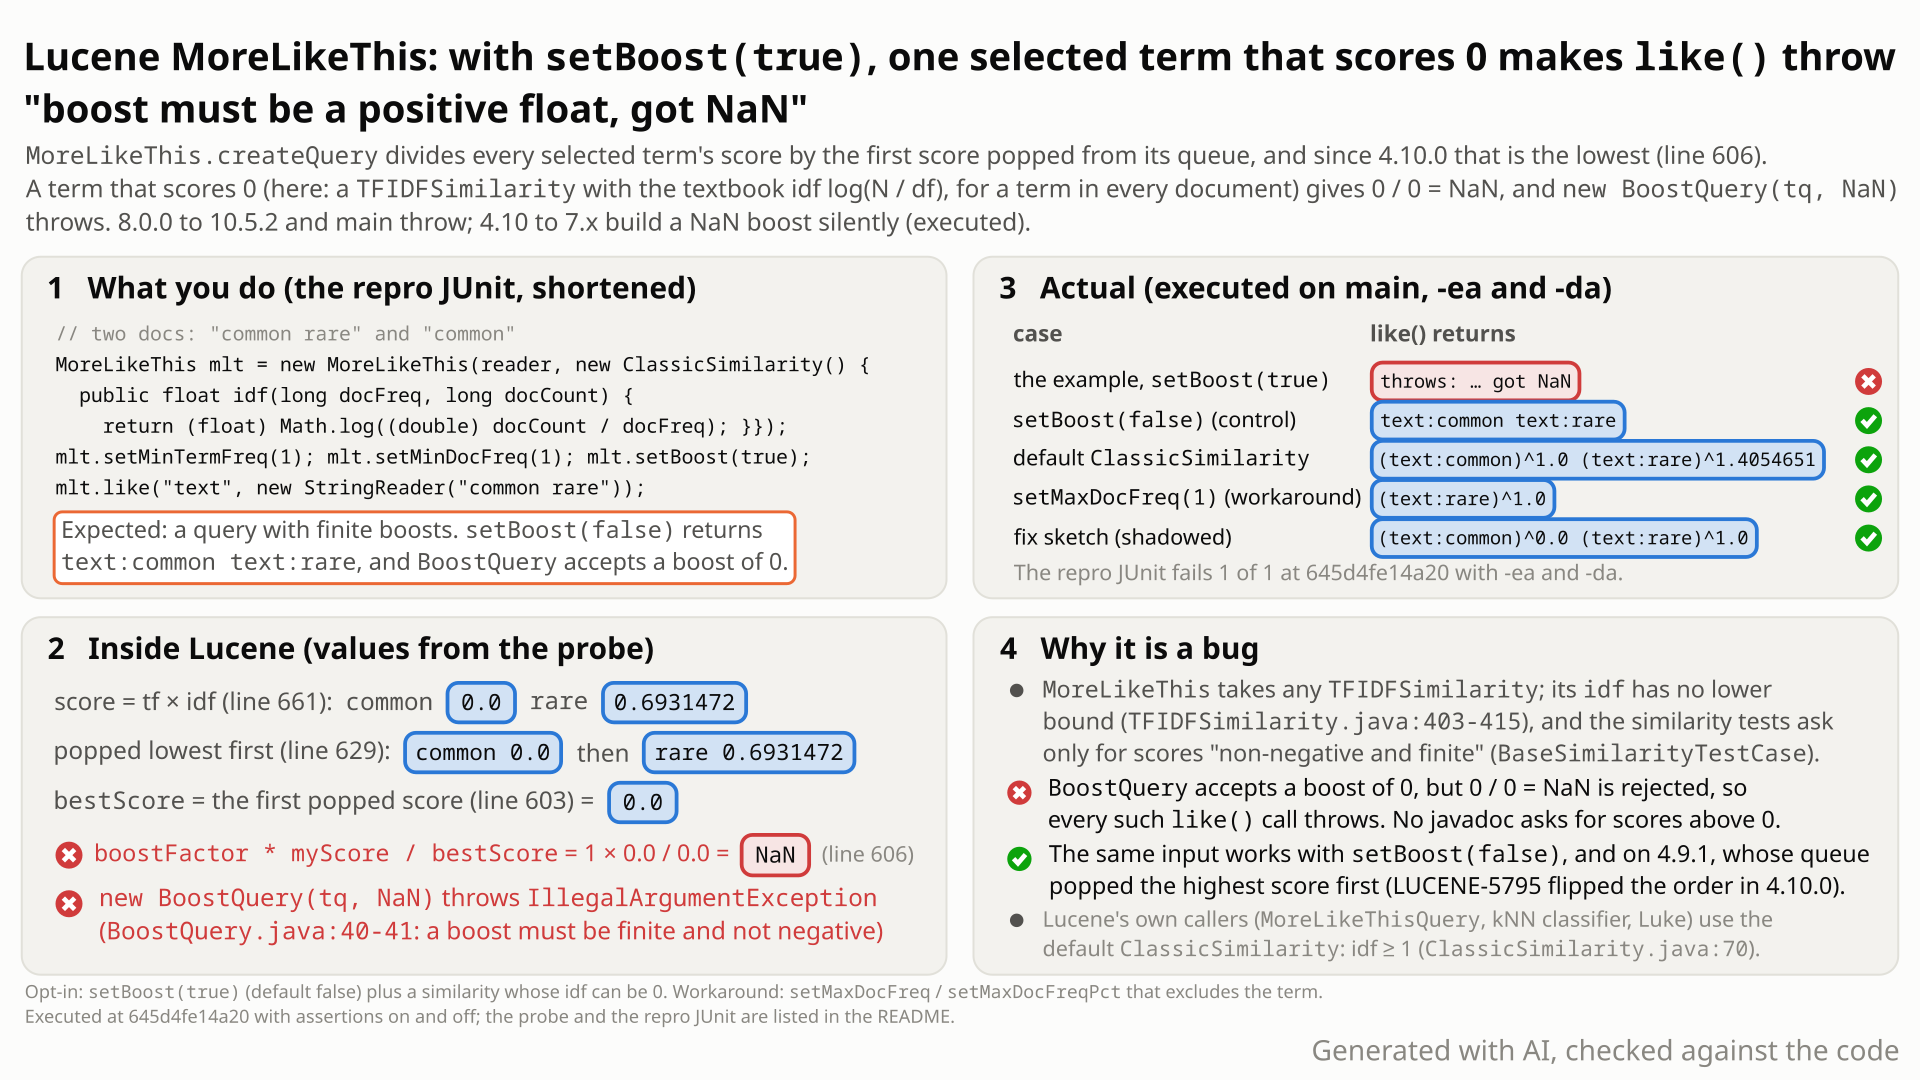
common scores 0 and pops first from the lowest-first queue, so it becomes the divisor and its boost is 0/0 = NaN, which BoostQuery rejects. Select the still to open it at full size. Generated with AI, checked against the code.- Index two documents,
common rareandcommon. GiveMoreLikeThisaTFIDFSimilaritywith the textbook idflog(docCount/docFreq):commonis in both documents, so its idf is log(2/2) = 0;raregets log(2/1) = 0.69. - Call
like("text", "common rare")withsetBoost(true). You expect each term boosted by its score, for example(text:common)^0.0 (text:rare)^1.0. Without boosting the same call returnstext:common text:rare. - You get
IllegalArgumentException: boost must be a positive float, got NaN, with assertions on and off. - Why: the selected terms sit in a queue that pops the lowest score first, and
createQuerykeeps that first score asbestScore. Each boost isscore / bestScore, socommongets 0/0 = NaN (andrarewould get 0.69/0 = Infinity). - Before 4.10 the queue popped the highest score first and this input worked. From 4.10 to 7.x the query is built silently with NaN and Infinity boosts; since 8.0
BoostQueryrejects them.
Applications that call MoreLikeThis directly with the opt-in setBoost(true) and their own TFIDFSimilarity whose idf can be 0, on 4.10.0 to 10.6.0 and main. Each like() fails while a zero-score term is among the selected terms. The default ClassicSimilarity (idf at least 1) and Lucene's own callers never hit it.
Mechanism, terms and numbers528 words
MoreLikeThis with the opt-in setBoost(true) weights each clause of the query it builds by its term's score divided by bestScore, the score of the first term it pops from its queue. Since LUCENE-5795 (4.10.0) that queue pops the lowest score first, so the divisor is the lowest selected score. A term that scores exactly 0, which a custom TFIDFSimilarity such as the textbook idf log(N/df) gives a term found in every document, makes the first boost 0/0 = NaN: like() throws IllegalArgumentException: boost must be a positive float, got NaN on 8.0.0 through 10.6.0 and main, with assertions on and off, and 4.10 to 7.x silently build NaN and Infinity boosts. The default ClassicSimilarity (idf at least 1) never gives 0, so Lucene's own callers are not affected.
All lines are in lucene/queries/src/java/org/apache/lucene/queries/mlt/MoreLikeThis.java at 645d4fe14a20.
createQueue(:624-677) scores each candidate term astf * similarity.idf(docFreq, numDocs)(:660-661) and keeps the bestmin(maxQueryTerms, #terms)inPriorityQueue.usingComparator(limit, FloatComparator.comparing(st -> st.score))(:628-629). Lucene'sPriorityQueuekeeps the least element on top, sopop()returns the lowest score first.createQuery(:593-616) pops the terms one by one. WithsetBoost(true)it stores the first popped score asbestScore(:596,:602-604) and wraps each clause innew BoostQuery(tq, boostFactor * myScore / bestScore)(:606). So every score is divided by the lowest selected score.- If that lowest score is 0, the first boost is
0 / 0 = NaN(and every later positive term would getscore / 0 = +Infinity). - The
BoostQueryconstructor rejects a boost that is not finite or is negative (BoostQuery.java:40-41; 0 is accepted), solike()throwsIllegalArgumentException: boost must be a positive float, got NaNbefore any search runs.
Every like() overload ends in createQuery: like(int) (:555-563), like(Map) (:569-576) and like(String, Reader...) (:584-590); the first and the last were executed.
A new term replaces the queue's lowest entry only if it scores strictly higher (:669), so a 0-score term stays selected while fewer than maxQueryTerms (default 25) other terms score above 0. With a zero-idf similarity, 1, 23 or 24 positive-score terms plus the zero-score term throw; with 25 or 30 the zero-score term drops out and the query builds.
ClassicSimilarity.idf is log((docCount + 1) / (docFreq + 1)) + 1 (ClassicSimilarity.java:69-70), and MoreLikeThis passes ir.getDocCount(fieldName) (:634), which counts deleted documents just as docFreq does, so idf is at least 1. Even with 99 of 100 documents deleted and not merged, the stock similarity builds finite boosts (executed on main and 8.11.4). This relies on getDocCount: MoreLikeThis falls back to ir.numDocs() (live documents only) when it returns -1 (:635-637), which the standard readers never do (LeafReader.getDocCount is final and returns the field's Terms.getDocCount() or 0, and Terms.getDocCount() documents no -1). Before 8.3.0 MoreLikeThis always passed ir.numDocs(), so on 4.10 to 8.2 this argument does not hold: there the stock idf could go below 0 with many unmerged deletes (a separate, historical issue).
Exposure and likelihood310 words
- Who is hit. Direct
MoreLikeThisusers who turn onsetBoost(true)(DEFAULT_BOOST = false,MoreLikeThis.java:190) and pass their ownTFIDFSimilarity(constructor:300orsetSimilarity:309) whose idf can be exactly 0: the textbooklog(N/df), or a clamped Robertson-Sparck Jones idfmax(0, log((N - df + 0.5) / (df + 0.5)))(both executed). Any like text that contains a term found in every document of the field, plus fewer than 25 other scoring terms, fails: ordinary short input, not crafted input. - Who is not.
ClassicSimilarityandSweetSpotSimilarity(which does not override idf). Lucene's own callers usenew MoreLikeThis(reader), that isClassicSimilarity:MoreLikeThisQuery(:61), the classification module's kNN classifiers (which do callsetBoost(true)) and Luke. - Default vs opt-in. Both triggers are opt-in. Nothing else is needed: the repro uses
new IndexWriterConfig()and two documents and creates noIndexSearcher(the exception comes from building the query). It ran under the test framework's randomized codec (CheapBastard in the gradle runs) and failed on every seed tried. - Effect. On 8.0 and later one request fails loudly, with a message that blames a boost the caller never set. No state damage: the reader, searcher and
MoreLikeThiskeep working. On 4.10 to 7.x (out of support) the boosts are silently NaN and Infinity: on 7.7.3 with assertions off a search with that query returned the right total hit count but a top list with a placeholder (doc 2147483647, score -Infinity) and doc 1 with score NaN, while the real hit doc 0 was missing. - Workaround.
setMaxDocFreq(...)orsetMaxDocFreqPct(...)so a term in every document is never selected,setBoost(false), or a similarity whose idf stays above 0. - How likely. Rare: no report was found in the recorded searches, although the code has been this way since 4.10.0 (2014). The failure is deterministic: the same input fails every time.
One JUnit class for lucene/queries/src/test/org/apache/lucene/queries/mlt/, one method, public API: two documents, a ClassicSimilarity subclass with idf log(docCount/docFreq), setBoost(true) and one like() call. Deterministic and single-threaded; it fails with assertions on and off and is also the suggested regression test.
package org.apache.lucene.queries.mlt;

import java.io.StringReader;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.similarities.ClassicSimilarity;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestMoreLikeThisBoostZeroScore extends LuceneTestCase {

  public void testBoostWithZeroIdfTerm() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      for (String text : new String[] {"common rare", "common"}) {
        Document doc = new Document();
        doc.add(new TextField("text", text, Field.Store.NO));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        MoreLikeThis mlt =
            new MoreLikeThis(
                reader,
                new ClassicSimilarity() {
                  @Override
                  public float idf(long docFreq, long docCount) {
                    return (float) Math.log((double) docCount / docFreq); // 0 for "common"
                  }
                });
        mlt.setAnalyzer(new StandardAnalyzer());
        mlt.setFieldNames(new String[] {"text"});
        mlt.setMinTermFreq(1);
        mlt.setMinDocFreq(1);
        mlt.setBoost(true);
        try {
          mlt.like("text", new StringReader("common rare"));
        } catch (IllegalArgumentException e) {
          throw new AssertionError("expected a query with finite boosts, got " + e, e);
        }
      }
    }
  }
}
cp $REPRO/TestMoreLikeThisBoostZeroScore.java $LUCENE/lucene/queries/src/test/org/apache/lucene/queries/mlt/
cd $LUCENE && ./gradlew :lucene:queries:test --tests org.apache.lucene.queries.mlt.TestMoreLikeThisBoostZeroScore -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same failure)
- Expected
like()returns a query with finite boosts, for example(text:common)^0.0 (text:rare)^1.0(what the recommended fix returns).- Observed
IllegalArgumentException: boost must be a positive float, got NaNfromMoreLikeThis.createQuery(MoreLikeThis.java:606), with assertions on and off.
More files, environment, full output275 words
The test indexes common rare and common into a ByteBuffersDirectory with new IndexWriterConfig() (under the test framework the codec is randomized; the gradle runs used CheapBastard), so idf(common) = log(2/2) = 0 and idf(rare) = log(2/1) = 0.69, and calls like("text", new StringReader("common rare")) with StandardAnalyzer, setMinTermFreq(1), setMinDocFreq(1) and setBoost(true). The IllegalArgumentException is rethrown as an AssertionError that states expected versus actual. Nothing in the test uses random(); it failed on 10 of 10 derived seeds with assertions on and off. It also fails on the 10.6.0 release jars. On releases before 9.0 the test-framework package differs (org.apache.lucene.util.LuceneTestCase); before 8.0 there is no exception to catch, and the boost is NaN instead. The file has no license header: add the standard ASF header before submitting it as the regression test (that shifts the test line numbers in the output below; the license check was not run).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also fails on 10.6.0 (release jars); 4.9.1 is the last release that passes |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
TestMoreLikeThisBoostZeroScore > testBoostWithZeroIdfTerm FAILED
    java.lang.AssertionError: expected a query with finite boosts, got java.lang.IllegalArgumentException: boost must be a positive float, got NaN
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:9D2BA54E4B4AEA09]:0)
        at org.apache.lucene.queries.mlt.TestMoreLikeThisBoostZeroScore.testBoostWithZeroIdfTerm(TestMoreLikeThisBoostZeroScore.java:44)

        Caused by:
        java.lang.IllegalArgumentException: boost must be a positive float, got NaN
            at org.apache.lucene.core@11.0.0-SNAPSHOT/org.apache.lucene.search.BoostQuery.<init>(BoostQuery.java:41)
            at org.apache.lucene.queries.mlt.MoreLikeThis.createQuery(MoreLikeThis.java:606)
            at org.apache.lucene.queries.mlt.MoreLikeThis.like(MoreLikeThis.java:589)
            at org.apache.lucene.queries.mlt.TestMoreLikeThisBoostZeroScore.testBoostWithZeroIdfTerm(TestMoreLikeThisBoostZeroScore.java:42)

1 test completed, 1 failed

# the same with -Ptests.asserts=false; with the recommended fix the test passes

# the query each setting builds for the same input (a printing probe, not the repro)
stock, setBoost(false): text:common text:rare
stock, setBoost(true):  threw java.lang.IllegalArgumentException: boost must be a positive float, got NaN
fix, setBoost(true): (text:common)^0.0 (text:rare)^1.0- Nothing asks for a positive idf:
TFIDFSimilarity.idfsets no lower bound, and Lucene's similarity tests check only that scores are "non-negative and finite". BoostQueryaccepts a boost of 0; the same call works withsetBoost(false)and on 4.9.1.- The lowest-score divisor is a side effect of a 2014 speed-up (LUCENE-5795) that never discussed boosts.
The full argument298 words
- Nothing asks for a positive score.
MoreLikeThis(IndexReader, TFIDFSimilarity)andsetSimilaritytake anyTFIDFSimilaritywith no precondition (MoreLikeThis.java:300-311).TFIDFSimilarity.idfsets no lower bound: "Terms that occur in fewer documents are better indicators of topic, so implementations of this method usually return larger values for rare terms, and smaller values for common terms." (TFIDFSimilarity.java:408-409). Lucene's base similarity test suite checks that scores are "non-negative and finite" (BaseSimilarityTestCase.java:256, checked at:387-389): a test-framework expectation rather than an API contract, and it allows 0.setBoost's javadoc only says: Sets whether to boost terms in query based on "score" or not (MoreLikeThis.java:422). - 0 is a legal boost and a legal score.
BoostQueryaccepts 0 (BoostQuery.java:40). In a verifier's test the same zero-idf similarity scores a 4-document index normally throughIndexSearcher.search: aTermQueryon the ubiquitous term returns all 4 documents with score 0.0. - The same input works without boosting, and worked before 4.10.
setBoost(false)returnstext:common text:rare. 4.9.1 passes the same test: its queue popped the highest score first (lessThanreturnedfa > fb), so the divisor was the highest score and a zero-score term got boost 0. - The change of divisor was a side effect. LUCENE-5795 (#6857, "More Like This: ensures selection of best terms is indeed O(n)") flipped the queue to ascending order for its bounded top-N selection and kept "first popped =
bestScore". Its 4.10.0 CHANGES entry sits under Optimizations: "MoreLikeThisQuery now only collects the top N terms instead of collecting all terms from the like text when building the query." (lucene/CHANGES.txt:11949-11951). The issue's 9 comments never mention boosts. - No test covers it. The upstream
TestMoreLikeThisuses only the defaultClassicSimilarity, so no boosted test sees a score of 0.
The devil's-advocate check162 words
The strongest case for "works as designed" (from the verifiers, the cross-model reviews, the adjudication and the cross-model fact check): setBoost is off by default; TFIDFSimilarity is an expert API; every in-tree similarity has idf at least 1; setMaxDocFreq avoids it; and since 8.0 it fails fast instead of returning wrong results, so it is a misconfiguration. MoreLikeThis is a heuristic term selector, and a maintainer may prefer to reject negative or non-finite similarity scores explicitly rather than turn them into a boost (the recommended fix maps negative and NaN scores to 0 and still throws on +Infinity).
Why it fails: nothing documents that boosted MoreLikeThis needs strictly positive scores; the textbook idf gives 0 for a term in every document; BoostQuery itself accepts 0; the identical call works with boosting off and worked in 4.9.1; and the exception reports an internal 0/0, not a bad argument. These points lower the impact; none makes the exception intended. Verdict: not intended, a defect.
Recommended A: normalise by the lowest positive score; a zero-score term gets boost 0 (validated)
Normalise by the lowest positive score and give a zero-score term boost 0 (+6/-4 lines in createQuery); all-positive selections keep their boosts. With it the repro passes, and so do TestMoreLikeThis and the classification module's tests, with assertions on and off.
       if (boost) {
-        if (bestScore == -1) {
-          bestScore = (scoreTerm.score);
-        }
         float myScore = (scoreTerm.score);
-        tq = new BoostQuery(tq, boostFactor * myScore / bestScore);
+        // q pops the lowest score first: normalise by the lowest POSITIVE score, so that a term
+        // whose score is 0 (a TFIDFSimilarity idf may be 0) gets boost 0 instead of 0/0 = NaN
+        if (bestScore == -1 && myScore > 0) {
+          bestScore = myScore;
+        }
+        tq = new BoostQuery(tq, myScore > 0 ? boostFactor * myScore / bestScore : 0f);
       }
All options and trade-offs3 options · 669 words
One fix was built and validated with gradle on 645d4fe14a20; the alternatives come from the study's verifiers and the adjudication. What a zero-score term should get (boost 0, or no clause) is the maintainers' choice: the defect is the NaN and the exception. LFV-571 (at the boolean clause limit the same loop keeps the lowest-scoring terms) is a sibling: both come from LUCENE-5795's queue flip, and their fixes touch the same lines.
Take bestScore from the first popped term whose score is above 0, and give a term with score 0 the boost 0. The first popped score of an all-positive selection is positive, so it becomes bestScore exactly as today and no existing boost changes (code reading). An all-zero selection gives every clause boost 0. The zero-score clause stays, so by code reading the boosted query matches the same documents as the unboosted one (not executed); scores, and so ranking and top-N results, differ, as with any boosting.
       if (boost) {
-        if (bestScore == -1) {
-          bestScore = (scoreTerm.score);
-        }
         float myScore = (scoreTerm.score);
-        tq = new BoostQuery(tq, boostFactor * myScore / bestScore);
+        // q pops the lowest score first: normalise by the lowest POSITIVE score, so that a term
+        // whose score is 0 (a TFIDFSimilarity idf may be 0) gets boost 0 instead of 0/0 = NaN
+        if (bestScore == -1 && myScore > 0) {
+          bestScore = myScore;
+        }
+        tq = new BoostQuery(tq, myScore > 0 ? boostFactor * myScore / bestScore : 0f);
       }
Trade-offs
A negative or NaN score from a broken custom similarity also becomes boost 0 instead of an error. If the maintainers want such scores rejected, add an explicit check with a message that names the similarity. The fix covers finite, non-negative scores: a +Infinity score still gives an infinite or NaN boost (Infinity / Infinity), so BoostQuery still throws, as today (code reading).
What the checks validated
- Gradle in a scratch worktree of
645d4fe14a20(removed after the runs): stock, the repro fails with assertions on and off; with the fix,--tests 'org.apache.lucene.queries.mlt.*'(the repro and the upstreamTestMoreLikeThis: 12 tests, 0 failures, 1@AwaitsFixskipped) passes with assertions on and off, the whole:lucene:classification:test(12 classes, 43 tests, 0 failures, 1 skipped; its kNN classifiers run boosted MoreLikeThis withClassicSimilarity) passes with assertions on, and:lucene:queries:checkGoogleJavaFormatpasses. The classification module with assertions off was run by the page's fact check, in a fresh scratch worktree of645d4fe14a20with the fix: 12 classes, 43 tests, 0 failures, 1 skipped. - A printing probe shows the fixed query for the repro's input:
(text:common)^0.0 (text:rare)^1.0. - Earlier checks: the study's fix check (the repro and the upstream
TestMoreLikeThis, 11 run, 0 failed), the verifiers' tests and the adjudication's re-run pass with it; the standalone runner passes the repro with it on645d4fe14a20(-ea,-da).
Restore the pre-4.10 normaliser: drain the queue, divide every score by the highest one, and give boost 0 when that is 0.
Trade-offs
Changes the boost of every existing boosted query: positive scores would get boosts in (0, boostFactor] instead of starting at boostFactor (a zero score gets 0 under the guard). For example scores 1 and 2 give boosts 1 and 2 today and 0.5 and 1 then. An all-zero selection still needs the guard, and the loop must read the highest score before it builds the first clause.
Skip the clause of a term whose score is 0, since it adds nothing to the score.
Trade-offs
The boosted query then matches fewer documents than the unboosted one (in the repro, the document that contains only common no longer matches), and an all-zero selection gives an empty query.
Solr's MoreLikeThis handler and parser let users turn boosting on but always use ClassicSimilarity, so they cannot hit it (code read), while Elasticsearch's and OpenSearch's own XMoreLikeThis copies divide by the first popped score the same way and would not get a Lucene fix.
AI tools checked MoreLikeThis against a reference model written from its javadoc (118,800 bounded-random checks). Every boosted query turned out to be normalised by the lowest selected score; a probe with a zero-idf similarity then threw, and the case was reduced to a two-document JUnit.
The method in full132 words
Method: semi-formal (a hypothesis formed while modelling, then witnessed by a tool).
- An AI finder wrote a reference implementation of
MoreLikeThisterm selection and query construction from its javadoc and compared it with the real queries jar in bounded-random translation validation (118,800 checks, seed DEADBEEF). Observation O1: all 8,242 boosted checks were normalised by the lowest selected score, not the highest. - A small selection model (
create_query: best = first popped) showed that the divisor can be a zero minimum. A scratch probe with a zero-idf similarity threw on main, and the finder wrote a public-API JUnit, later reduced to the two-document test. - So the tool pointed at the lowest-score divisor; the zero-score trigger was then reasoned out and confirmed by execution. It is not a blind discovery by a tool.
No prior report found (2026-10-26: 203 logged queries over GitHub issues, PRs and commits, the JIRA archive, four mailing lists and the web; all 406 open PRs checked), and a 2026-10-30 GitHub search found 0 apache/lucene issues or PRs mentioning MoreLikeThis updated since 2026-10-26. Not fixed upstream.
Searches5 searches
No report of NaN or infinite MoreLikeThis boosts, of this exception from MoreLikeThis, or of the lowest-score divisor was found. The closest items explain the code, not the bug: LUCENE-5795 introduced the divisor without discussing boosts, and an unmerged 2017 refactor renamed bestScore to minScore and kept the division with no zero guard. Upstream main 716d6f216f52 (2026-10-29) changes no file under mlt/ and not BoostQuery.java.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive; Elasticsearch, OpenSearch, Solr, Lucene.NET, RavenDB) | 2026-10-26 | the scripted prior-report search (70 queries) and 94 read-only GitHub GraphQL searches: NaN, Infinity, the exception text, bestScore, boostFactor, normalise, zero and negative idf, BM25, the issue numbers, file paths, stack frames | no report |
| Related items (read in full) | 2026-10-26 | 34 items: bodies, all comments, PR diffs | only related: #6857 / LUCENE-5795 (the origin), apache/lucene-solr#191 (unmerged refactor, same divisor as minScore), #9373 / LUCENE-8326 (unmerged PRs, same divisor), #9044 / LUCENE-7996 (the BoostQuery check), #10608 / LUCENE-9568 (the same exception text from FuzzyTermsEnum, another cause) |
| Open PRs | 2026-10-26 | changed-file lists of all 406 open apache/lucene PRs | #940 (tf) and #16847 (long doc ids) touch MoreLikeThis.java, neither changes createQuery |
| Mailing lists, JIRA, web | 2026-10-26 | dev@, java-user@, issues@, commits@ (20 queries); JIRA LUCENE and SOLR (12 JQL, 8 issues read) and Hibernate Search (4 JQL); 15 web queries | no report; a 2007 java-user question about setBoost predates the bug |
| Re-check for this page | 2026-10-30 (twice) | upstream main vs 645d4fe14a20; GitHub search API: apache/lucene issues and PRs mentioning MoreLikeThis updated since 2026-10-26, and the exception text with MoreLikeThis, with positive controls (MoreLikeThis alone: 49 hits; the exception text alone: 1, #10608) | 0 and 0 hits; MoreLikeThis.java unchanged upstream |
Introduced in 4.10.0 by LUCENE-5795 (173a44e67c7, 2014-07-10), which flipped the term queue to lowest-first. 4.10 to 7.x build NaN boosts silently; since 8.0.0 (LUCENE-7996's BoostQuery check) like() throws. Executed: 4.9.1 passes; every tested release from 4.10.0 to 10.6.0 and main fails.
Versions tested5 rows
Introduced by LUCENE-5795 (now #6857) "More Like This: ensures selection of best terms is indeed O(n)", patch by Alex Ksikes, committed by Simon Willnauer on 2014-07-10 as 173a44e67c7 (trunk, the line main descends from) and 1427d574d3d (branch_4x backport); a JIRA patch, no pull request. It changed the queue's lessThan from fa > fb (highest popped first) to a.score < b.score (lowest first) and kept createQuery's "first popped = bestScore". Symptom change: LUCENE-7996 (#9044, a8a63464e7d, 2017-12-06, first released in 8.0.0) made BoostQuery reject non-finite boosts. Later edits kept the arithmetic: LUCENE-6590 (5.4.0, setBoost became BoostQuery) and #14761 (a7704f5242d, 2025-06-18, main only, PriorityQueue.usingComparator with the same ascending order).
Caveat: 4.9.1 is not fully safe. When every selected term scores 0 the divisor is 0 under either queue order; that all-zero probe fails on 4.9.1 and 4.10.0. LUCENE-5795 widened it to any selection that contains a zero-score term.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 (unreleased 11.0) | fails loudly | IllegalArgumentException, -ea and -da, gradle and standalone |
| 10.6.0 | fails loudly | IllegalArgumentException, -ea and -da (release jars) |
| 8.0.0, 8.11.4, 9.12.3, 10.5.2 | fails loudly | IllegalArgumentException (10.5.2 with -ea and -da) |
| 4.10.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3 | silent NaN boost | the query is built with a NaN boost, no exception (version-specific test variants) |
| 4.9.1 | not affected | passes: finite boosts (an all-zero selection still gives NaN) |
The finder, an independent reproducer, an intended-behaviour devil's advocate, the adjudication and this page's gradle runs all reproduce it. Cross-model reviews (OpenAI GPT-5.6) could run nothing: some said real, the others "not real" for procedure alone, with code evidence that supports real.
Checks and verdicts453 words
Every check that executed code voted real. The only dissent is procedural: a cross-model refute review that could not run Java voted not real on procedure only at low confidence while its cited code evidence supported real; a separate re-run of the repro failed as claimed. Nothing ran on x86 (nothing here is architecture-specific).
| Check | Verdict | What it found |
|---|---|---|
| Finder (finder) | candidate | Translation validation found the lowest-score divisor (8,242 of 8,242 boosted checks); its JUnit fails on main (-ea, -da), 10.5.2, 9.12.3, 8.11.4, 7.7.3, 6.6.6 and 4.10.4 and passes on 4.9.1. |
| Cross-model review, intended lens (OpenAI GPT-5.6) | real, medium | Read-only: it could run nothing; root cause agreed. A separate run re-ran the repro: fails. |
| Cross-model review, refute lens (OpenAI GPT-5.6) | not real, low (procedural) | Read-only: it could not run Java, so it voted not real on procedure only; its cited code evidence supports real. |
| Independent reproducer | real | Own JUnit written from the claim (3 documents, like(Reader) and like(docNum), a boost-off control): 2 of 3 fail on main (-ea, -da), 10.5.2 and 9.12.3; all pass with the fix. |
| Cross-model review, root-cause lens (OpenAI GPT-5.6) | real, medium | Read-only; root cause agreed. A separate probe fails 2 of 3 on main and passes 3 of 3 with the fix; the fix keeps the upstream TestMoreLikeThis green (11 of 11). |
| Intended-behaviour devil's advocate | real (high that it is not intended; low impact) | Built and rejected the "expert API, opt-in, fail-fast" case; its test fails 2 of 5 on main and 10.5.2 (textbook and clamped RSJ idf); 3 controls pass. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test (2 of 3 fail, -ea and -da, two seeds) and the finder's (fails); the independent reproduction's test with the fix passes. |
| Minimal repro | verified | Fails on main 645d4fe14a20 (-ea, -da) and on 10 of 10 derived seeds; passes with the fix shadowed. |
| Registry re-runs and credibility audit | keep | The finder's JUnit on the earlier main ea57360912ed (same MoreLikeThis.java) fails 1 of 1 with -ea and -da at seed DEADBEEF, and again at a new seed 5EED0004. |
| This page's runs | reproduced; fix validated | Gradle on main: the repro fails with -ea and -da; with the fix, the mlt tests and the classification module pass. 10.6.0 fails with -ea and -da. |
| Fact checks of this page | substantively correct; small errors fixed | A checker re-ran the gradle repro in a fresh scratch worktree (fails, -ea and -da), the fix with the mlt tests and the classification module (both modes), and the standalone runner on main and 10.6.0; the diagram checker re-ran the diagram probe (-da, stock and fix); a cross-model checker (OpenAI GPT-5.6) reviewed it read-only. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 614 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,335 words
- Registry title
- MoreLikeThis with setBoost(true) divides every term's score by the lowest selected score, so a selected term that scores 0 (a TFIDFSimilarity whose idf is 0, such as the textbook log(N/df) for a term in every document) makes like() throw 'boost must be a positive float, got NaN' (8.0 and later) or build NaN and Infinity boosts (4.10 to 7.x)
- Area
- queries / MoreLikeThis boosted query construction (MoreLikeThis.createQuery boost normalisation)
- Priority
- Low, rank 631: MoreLikeThis like() throws only with opt-in setBoost(true) plus a custom TFIDFSimilarity whose idf can be 0, never with stock similarities, the same rare-config loud profile as LFV-393.
- Impact class
- crash
- Impact note
- Direct MoreLikeThis users who turn on the opt-in setBoost(true) (default false) and pass their own TFIDFSimilarity whose idf can be exactly 0 (constructor or setSimilarity) get IllegalArgumentException from every like(...) call on 8.0.0 through 10.6.0 and main whenever a zero-score term is among the selected terms (it stays selected while fewer than maxQueryTerms, default 25, other terms score above 0), with -ea and -da, the default codec and searcher and no scale; 4.10 to 7.x (out of support) build NaN and Infinity boosts silently instead; it is one failed call with no state damage, and the stock ClassicSimilarity has idf >= 1, so MoreLikeThisQuery, the classification module, Luke and (by code reading) Solr's MLT handler and parser never hit it.
- Summary
- You enable boosting on MoreLikeThis (setBoost(true)) with a custom TFIDFSimilarity whose idf is 0 for a term that is in every document, as the textbook idf log(N/df) is, and call like(...) on text that contains that term and a rarer one. You expect a query with finite, non-negative boosts: the same call works with setBoost(false), and BoostQuery accepts a boost of 0. Instead createQuery divides each term's score by the first score popped from its ascending queue, which is the lowest selected score (0 here), so the zero-score term's boost is 0/0 = NaN and like() throws IllegalArgumentException 'boost must be a positive float, got NaN' on 8.0 and later, or builds the query with NaN and Infinity boosts on 4.10 to 7.x.
- Introduced
- 173a44e67c7c3c1a9ffbe7259ea8b45f1f53b015 (trunk, svn r1609474; the line main descends from, shipped from 6.0.0 on) and its branch_4x backport 1427d574d3dae460d638b8d6584116baf4756214 (svn r1609493, shipped in 4.10.0 and 5.x): LUCENE-5795 'More Like This: ensures selection of best terms is indeed O(n)' (now apache/lucene#6857; a JIRA patch committed by s1monw; SVN era, no pull request; CHANGES 4.10.0 'Optimizations') [read: git history clone; exec: 4.9.1 passes, 4.10.0 fails]. It flipped the term queue from highest-first (FreqQ.lessThan 'fa > fb') to ascending ('a.score < b.score') but kept createQuery's 'first popped term = bestScore' normaliser, so the divisor became the lowest selected score; the issue thread (9 comments) never mentions boosts. Symptom change: LUCENE-7996 (a8a63464e7da, 2017-12-06, first released in 8.0.0) made the BoostQuery constructor reject non-finite boosts, so the NaN became an exception. Later edits kept the arithmetic: LUCENE-6590 (962313b83ba / fb2a8aaac40, 5.4.0, setBoost -> BoostQuery) and #14761 (a7704f5242d, 2025-06-18, main only, FreqQ -> PriorityQueue.usingComparator, same ascending order) (2014-07-10)
- First affected version
- 4.10.0 [exec: silent NaN boost; 4.9.1 passes]; IllegalArgumentException from 8.0.0 [exec] (first release with the LUCENE-7996 BoostQuery check). Caveat: when every selected term scores 0, 4.9.1 already gave 0/0 [exec, all-zero probe]; LUCENE-5795 widened that to any selection containing a zero-score term
- Affected versions
- every release from 4.10.0 through 10.6.0 and main ea57360912ed [exec: 4.10.0, 4.10.4, 5.5.5, 6.6.6 and 7.7.3 build the query with a NaN boost silently (version-specific test variants); 8.0.0, 8.11.4, 9.12.3, 10.5.2 (-ea and -da), 10.6.0 (release jars, -ea and -da) and main (-ea and -da) throw IllegalArgumentException]; not affected for a mixed zero/positive selection: 4.9.1 [exec], which still fails for an all-zero selection [exec]; not fixed upstream [read, 2026-10-26: upstream main a95c754ee003, branch_10x 657014b3c579 and branch_10_6 4ae946e5a9b9 still have the unguarded division; of the 406 open PRs only #940 and #16847 touch MoreLikeThis.java, and neither changes createQuery]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only, the prior-report record verdict new: 203 logged queries: 26 GitHub REST issue/PR, 3 commit, 2 downstream-repo, 23 mailing-list (dev@, java-user@, issues@, commits@), 24 JIRA (LUCENE, SOLR), 4 Hibernate Search JIRA, 15 web, 94 read-only GitHub GraphQL searches (apache/lucene, Elasticsearch, OpenSearch, Solr, Lucene.NET, RavenDB, global) and 12 other checks (item reads, open PRs, upstream heads, history); 34 items read in full; every one of the 406 open apache/lucene PRs checked for MoreLikeThis.java; the finder's earlier scripted prior-report search agrees); 18 hits assessed, none the same bug. Nearest: #6857 / LUCENE-5795 (the introducing change; its thread never discusses boosts); apache/lucene-solr#191 (unmerged 2017 LUCENE-7498 refactor that renamed bestScore to minScore and kept the division without a zero guard); #9373 / LUCENE-8326 (unmerged PRs keep the first-popped divisor); #9044 / LUCENE-7996 (added BoostQuery's check, the 8.0 symptom change); #10608 / LUCENE-9568 (same exception text from FuzzyTermsEnum, different cause); open PRs #940 (tf) and #16847 (long doc ids) touch MoreLikeThis.java but not createQuery. Elasticsearch's and OpenSearch's forked XMoreLikeThis have the same normalisation code (default ClassicSimilarity); no downstream report found. Not fixed upstream (main a95c754ee003, branch_10x 657014b3c579, branch_10_6 4ae946e5a9b9 [read])
- Lucene commit tested
- main
645d4fe14a20(2026-10-28;MoreLikeThis.javais unchanged on upstream main716d6f216f52, 2026-10-29): the repro through gradle in a scratch worktree, stock with assertions on and off, and with the recommended fix together with themlttests and the classification module (the worktree was removed after the runs); a standalone runner on main (-ea,-da, 10 of 10 derived seeds) and on the 10.6.0 release jars (-ea,-da); the study's version runs from 4.9.1 to 10.5.2; the independent tests of the finder, verifiers and the adjudication. JDK OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/queries/src/java/org/apache/lucene/queries/mlt/MoreLikeThis.java:184-190 (at ea57360912ed) (DEFAULT_BOOST javadoc 'Boost terms in query based on score', default false), :300-311 (MoreLikeThis(IndexReader, TFIDFSimilarity) and setSimilarity, no precondition), :422-429 (setBoost javadoc 'boost terms in query based on "score"'), :593-616 (createQuery: bestScore = score of the first popped term at :602-604; new BoostQuery(tq, boostFactor * myScore / bestScore) at :606), :627-629 (createQueue: PriorityQueue.usingComparator(limit, FloatComparator.comparing(st -> st.score)), lowest score on top), :660-672 (score = tf * similarity.idf(docFreq, numDocs); a term replaces the queue minimum only if strictly higher)lucene/core/src/java/org/apache/lucene/search/BoostQuery.java:38-44 (at ea57360912ed) (rejects a boost that is not finite or is negative; 0 is accepted)lucene/core/src/java/org/apache/lucene/search/similarities/TFIDFSimilarity.java:403-415 (at ea57360912ed) (idf javadoc: 'usually return larger values for rare terms, and smaller values for common terms'; no lower bound)lucene/test-framework/src/java/org/apache/lucene/tests/search/similarities/BaseSimilarityTestCase.java:256, (at ea57360912ed) :386-390 (similarity contract: 'scores are non-negative and finite')lucene/CHANGES.txt:11916-11918 (at ea57360912ed) (LUCENE-5795 entry under 4.10.0: 'MoreLikeThisQuery now only collects the top N terms'; nothing about boosts)
- The finding in 30 seconds
lucene/queries/src/java/org/apache/lucene/queries/mlt/MoreLikeThis.java:555-563, (at 645d4fe14a20) :569-576, :584-590, :593-616 (:596, :602-604, :606), :624-677 (:628-629, :634, :660-661, :669)lucene/core/src/java/org/apache/lucene/search/BoostQuery.java:38-44; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/similarities/ClassicSimilarity.java:69-70lucene/core/src/java/org/apache/lucene/index/LeafReader.java:117-123; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/Terms.java:117-121; MoreLikeThis.java:634-637; release tags 8.2.0 (MoreLikeThis passes ir.numDocs()) and 8.3.0 (ir.getDocCount(fieldName), LUCENE-8984)
- Who is affected
Lucene main 645d4fe14a20 MoreLikeThis.java:190, :300, :309; MoreLikeThisQuery.java:61; lucene/classification/src/java/org/apache/lucene/classification/KNearestNeighborClassifier.java:104, :160; lucene/classification/src/java/org/apache/lucene/classification/document/KNearestNeighborDocumentClassifier.java:134; lucene/luke/src/java/org/apache/lucene/luke/models/search/SearchImpl.java:254
- Why it looks unintended
Lucene main 645d4fe14a20 MoreLikeThis.java:300-311, :422-427; lucene/core/src/java/org/apache/lucene/search/similarities/TFIDFSimilarity.java:403-415; lucene/test-framework/src/java/org/apache/lucene/tests/search/similarities/BaseSimilarityTestCase.java:256, :387-389; BoostQuery.java:40; lucene/CHANGES.txt:11929 (Optimizations), :11949-11951; lucene/queries/src/test/org/apache/lucene/queries/mlt/TestMoreLikeThis.java (no Similarity reference)
- TestMoreLikeThisBoostZeroScore.java (JUnit for Lucene's build):
repro/LFV-559/src/org/apache/lucene/queries/mlt/TestMoreLikeThisBoostZeroScore.java(49 lines)
Made in parallel with this page: a four-panel summary card (PNG), built from the code at that commit and from probe runs on the stock jars and with the fix. The card's version line names 8.0.0 to 10.5.2 and main; 10.6.0 was run for this page and fails the same way.
assets/LFV-559/bug.png(614 KB)