A function query's Weight keeps one small map, the context, for the whole search, and all slices of an executor search use it. scale() fills in its min/max entry lazily, during the search, from whichever slice thread gets there first.
FunctionQuery(modulelucene/queries) scores every document with a function built fromValueSources, for examplesum(scale(num, 0, 1), query(body:w0)).scale(num, 0, 1)maps a field's values onto the range 0..1 using the min and max over the whole index;query()uses another query's score.- When the search starts,
createWeightmakes one context map (anIdentityHashMap) and each source may store per-search data in it:query()stores its Weight, and the map always holds "searcher". For each segment,getValuesthen reads that data. new IndexSearcher(reader, executor)groups the segments into slices that run on different threads. They all use the same Weight, so the same map.
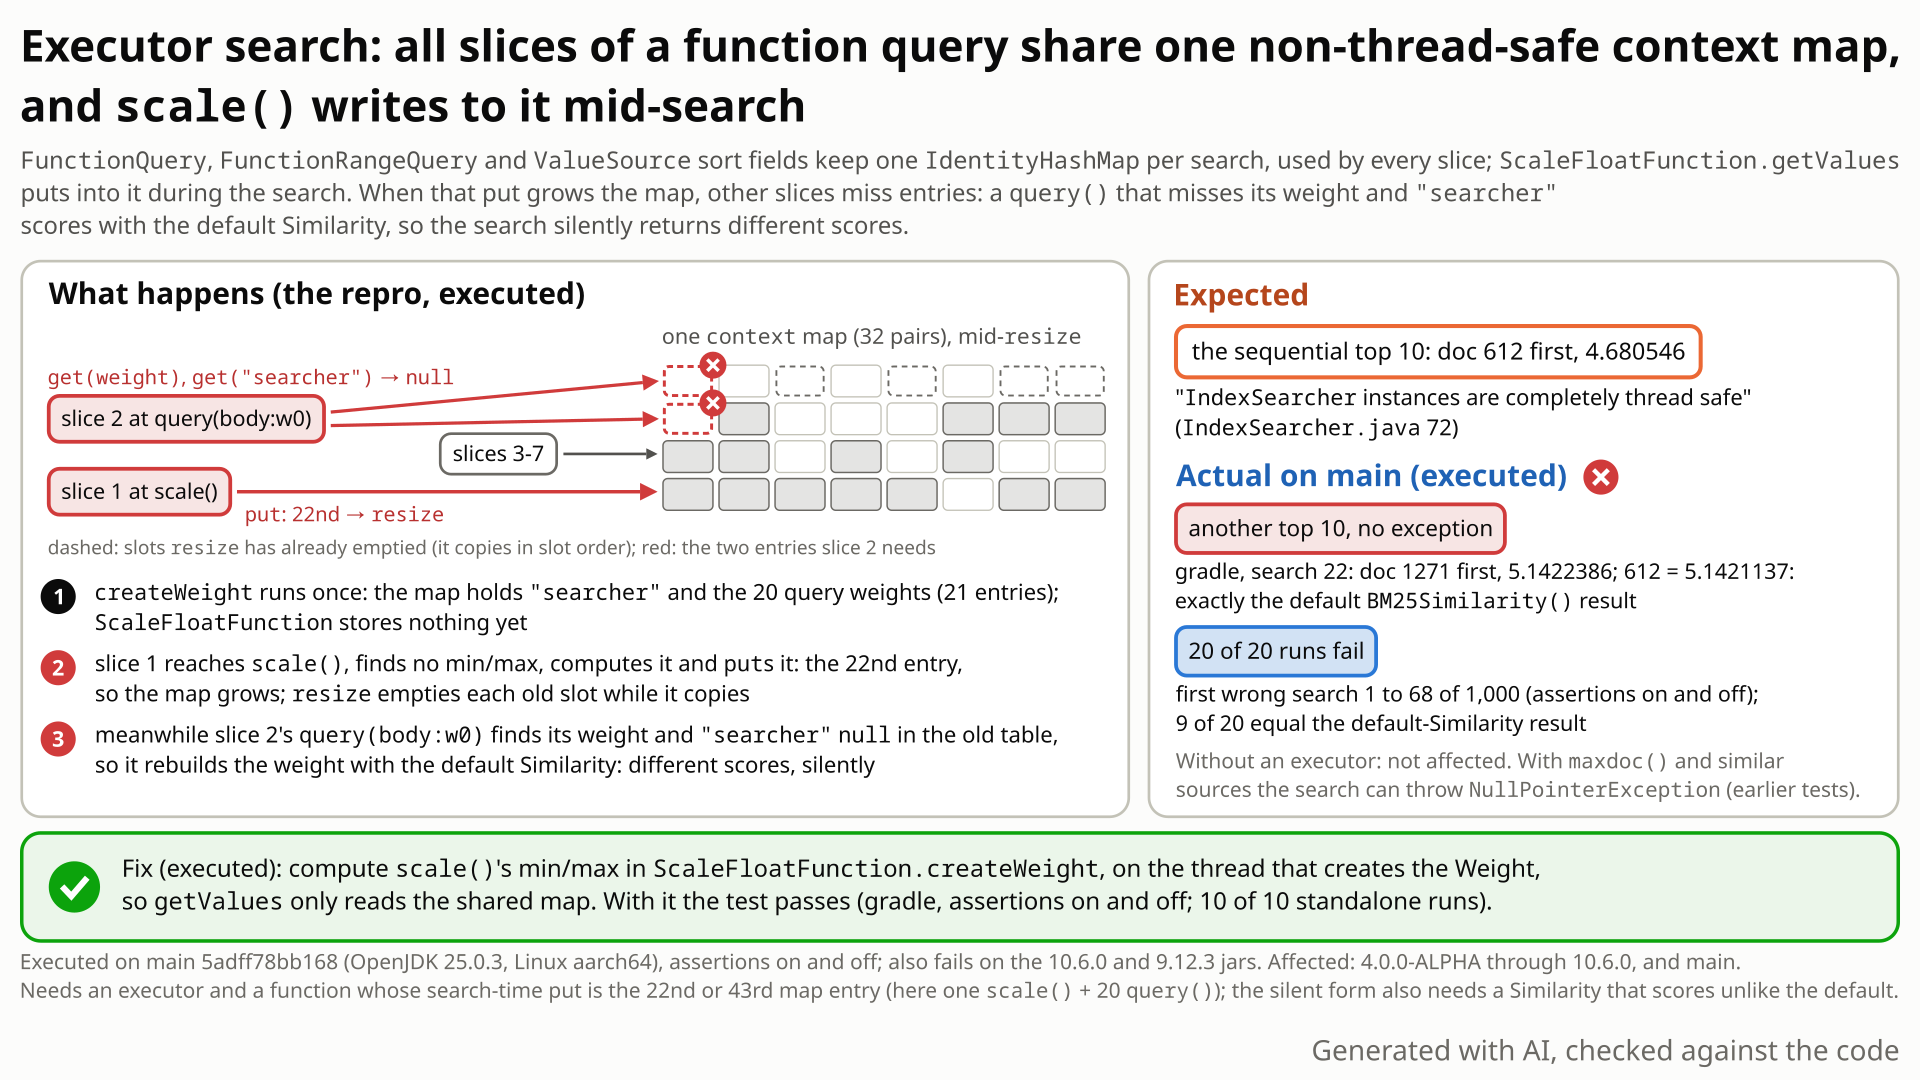
createWeight; scale() adds the 22nd from a slice thread during the search, the map copies itself into a bigger table, and meanwhile another slice's query() finds its weight and "searcher" missing and scores with the default Similarity. Select the still to open it at full size. Generated with AI, checked against the code.- Index 1,600 small documents in 32 segments. Search
FunctionQuery(sum(scale(num, 0, 1), query(body:w0), ..., query(body:w19)))for the top 10 withBM25Similarity(1.8, 0.3)onnew IndexSearcher(reader, executor): 8 threads, 7 slices. - You expect what the same search gives without an executor, every time: doc 612 first with score 4.680546.
IndexSearcheris documented as completely thread safe. - Instead, within the first 70 of 1,000 searches, one returns other scores and another order, with no error. In the gradle run doc 1271 is first with 5.1422386 and doc 612 has 5.1421137: exactly what the default
BM25Similarity()gives, so the configured Similarity was silently dropped. - Why: the query's Weight has one context map for all slices. After
createWeightit holds 21 entries ("searcher" and 20query()weights).scale()adds the 22nd from a slice thread during the search; the 22nd entry makes the map copy itself into a bigger table, and meanwhile other slices find "searcher" and their weights missing. Aquery()that misses both its weight and "searcher" then rebuilds its weight on a new searcher with the default Similarity. - Functions that also use
maxdoc(),idf(),docfreq(),norm()ortf()can crash instead:NullPointerException("searcher" is null; seen in earlier tests). With 10query()sources the map never grows, and all 5 control runs were right. Every release since 4.0.0-ALPHA (2012) is affected.
Applications that search with an executor (opt-in) and use FunctionQuery, FunctionRangeQuery or a ValueSource sort whose function has scale() plus about 20 query(), totaltermfreq() or sumtotaltermfreq() sources, so that scale()'s entry is the map's 22nd or 43rd (or a later growth point). Searchers without an executor are unaffected, and a 10-source function passed every control run. Every release since 4.0.0-ALPHA.
Mechanism, terms and numbers694 words
FunctionQuery, FunctionRangeQuery and ValueSource sort fields create one context map per search (ValueSource.newContext, an IdentityHashMap documented as "non-threadsafe") and hand it to every slice of an executor search. ScaleFloatFunction stores nothing in createWeight; it computes the whole-index min/max on first use in getValues and puts it into that shared map from a slice thread. When that put makes the map grow (the 22nd, 43rd or a later growth point), the other slices can briefly find entries missing: a query() that misses both its weight and "searcher" rebuilds it with the default Similarity, so a searcher whose Similarity scores differently silently gets different scores and top hits, and sources that need "searcher" (maxdoc(), idf(), ...) throw NullPointerException. In the repro (1,600 documents, 7 slices, sum(scale(num), 20 x query()), BM25Similarity(1.8, 0.3)), 20 of 20 runs return a different top 10 within the first 70 searches. Every release since 4.0.0-ALPHA is affected; the fix computes the scale in createWeight.
// ValueSource.java
/** Returns a new non-threadsafe context map. */                                 // :73
public static Map<Object, Object> newContext(IndexSearcher searcher) {
  Map<Object, Object> context = new IdentityHashMap<>();                         // :75, default capacity 32
  context.put("searcher", searcher);                                             // :76
// FunctionQuery.FunctionWeight: one context per Weight, shared by every slice
this.context = ValueSource.newContext(searcher);                                 // :70
func.createWeight(context, searcher);                                            // :71, query() puts its weight (QueryValueSource.java:85)
vals = func.getValues(weight.context, context);                                  // :116, AllScorer, on each slice thread

// valuesource/ScaleFloatFunction.java
ScaleInfo scaleInfo = (ScaleInfo) context.get(ScaleFloatFunction.this);          // :106
if (scaleInfo == null) scaleInfo = createScaleInfo(context, readerContext);      // :107-109, during the search
context.put(ScaleFloatFunction.this, scaleInfo);                                 // :98, a write to the shared map
public void createWeight(...) { source.createWeight(context, searcher); }        // :148-151, nothing stored

// valuesource/QueryValueSource.java, QueryDocValues constructor
Weight w = fcontext == null ? null : (Weight) fcontext.get(vs);                  // :114, may read null
weightSearcher = (IndexSearcher) fcontext.get("searcher");                       // :120, may read null
if (weightSearcher == null) weightSearcher = new IndexSearcher(ReaderUtil.getTopLevelContext(readerContext)); // :121-122, default SimilarityFunctionRangeQueryshares its map the same way (FunctionRangeQuery.java:148-149,:154,:170), and so does a sort byValueSource.getSortField(ValueSource.java:379-382,:434).- After
createWeightthe map in the repro holds 21 entries: "searcher" and the 20query()weights. The JDK'sIdentityHashMapgrows its table when an entry would make3 * sizeexceed the table length, so at the 22nd entry for the default capacity 32 (table length 64), then at the 43rd, the 86th and so on, as the table doubles (JDK 25IdentityHashMap.java:160,:456). resizecopies the entries one by one into a new array, nulling each old slot as it goes (:489-501), and only then publishes the new table (:502). Ageton the old table that meets a nulled slot returnsnull(:337-349). By reading the code, two slices that resize at the same time could also drop entries for the rest of the search (not observed directly).- A missing "searcher" makes
MaxDocValueSourcethrow (MaxDocValueSource.java:49-50; the same read inDocFreqValueSource.java:60,IDFValueSource.java:51,NormValueSource.java:66,TFValueSource.java:54). Aquery()that misses both its weight and "searcher" rebuilds its weight with the default Similarity and puts it back into the shared map (QueryValueSource.java:125, then:85), where later leaves of the same search find it; a weight lost again on the way throwsNullPointerException: ... because "this.weight" is null(QueryValueSource.java:150). ScaleFloatFunctionis the only built-inValueSourcethat writes the context outsidecreateWeight(thequery()fallback above callscreateWeightduring a search only after an entry went missing).asDoubleValuesSourceis not affected: it makes a new context per leaf (ValueSource.java:200).
1,600 documents in 32 segments (default slicing: 7 slices), an 8-thread executor, sum(scale(num, 0, 1), query(body:w0..w19)), BM25Similarity(1.8, 0.3), top 10. Sequential: 612=4.680546 1271=4.6782455 1303=4.6594014 .... The executor search differed within the first 70 of 1,000 searches in 20 of 20 runs (10 with assertions on, 10 off); in 9 of them the wrong top 10 equals, value for value, the sequential result with the default BM25Similarity(): 1271=5.1422386 612=5.1421137 1303=5.1220636 .... Other runs mix the two Similarities term by term.
Exposure and likelihood276 words
- Who is exposed. Applications that use
IndexSearcher(IndexReader, Executor)and run aFunctionQuery,FunctionRangeQueryorValueSourcesort whose function containsscale()and enough context-storing sources (query(),totaltermfreq(),sumtotaltermfreq(); "searcher" counts once) thatscale()'s entry is the 22nd or 43rd (or a later growth point) of the map: about 20 such sources with onescale(), or 41. - Nearby sizes. With several
scale()calls the window widens. With 19query()sources (the put is then the 21st entry, below the growth point) one of five runs also failed, at search 597 of 1,000; that failure was not instrumented and its cause is open. - What they see. With a Similarity that scores differently from the default
BM25Similarity(), silently different scores and top hits (no exception; this doc's test, 20 of 20 runs). Withmaxdoc(),idf(),docfreq(),norm()ortf()in the function, a failed search (earlier tests):NullPointerException: Cannot invoke "org.apache.lucene.search.IndexSearcher.getIndexReader()" because "searcher" is null. With the default Similarity, no run showed different scores (5 runs of this function), but one threw. - Contained. Only the triggering search is affected; other searches on the same searcher and executor were unaffected (0 of about 17,000 in a probe), nothing is cached and the index is not touched.
- Not affected. Searchers without an executor; in the controls, a 10-source function (5 of 5 runs pass all 1,000 searches);
asDoubleValuesSource. - How likely. Narrow: it takes an executor and a function sized to a growth point, and the searches found no report of it since 4.0.0-ALPHA (2012). But a deployment whose ranking function sits at a growth point fails in most runs.
One JUnit test in lucene/queries: 1,600 documents in 32 segments, an 8-thread executor, sum(scale(num), 20 x query(body:wN)) with BM25Similarity(1.8, 0.3). It compares up to 1,000 executor searches with one sequential search. Concurrency is the bug, so it is probabilistic: 20 of 20 runs failed, at search 1 to 68.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queries.function;

import java.util.ArrayList;
import java.util.List;
import java.util.Random;
import java.util.concurrent.ExecutorService;
import java.util.concurrent.Executors;
import java.util.concurrent.TimeUnit;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.NoMergePolicy;
import org.apache.lucene.index.Term;
import org.apache.lucene.queries.function.valuesource.LongFieldSource;
import org.apache.lucene.queries.function.valuesource.QueryValueSource;
import org.apache.lucene.queries.function.valuesource.ScaleFloatFunction;
import org.apache.lucene.queries.function.valuesource.SumFloatFunction;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.ScoreDoc;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.search.similarities.BM25Similarity;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.NamedThreadFactory;

public class TestScaleFunctionWithExecutor extends LuceneTestCase {

  public void testExecutorSearchMatchesSequentialSearch() throws Exception {
    Random r = new Random(7);
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriterConfig iwc = new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE);
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        for (int segment = 0; segment < 32; segment++) { // 32 segments: 7 slices
          for (int d = 0; d < 50; d++) {
            StringBuilder body = new StringBuilder();
            for (int k = 0, n = 1 + r.nextInt(6); k < n; k++) {
              body.append(" w").append(r.nextInt(24));
            }
            Document doc = new Document();
            doc.add(new TextField("body", body.toString(), Field.Store.NO));
            doc.add(new NumericDocValuesField("num", r.nextInt(1000)));
            w.addDocument(doc);
          }
          w.flush();
        }
      }
      // sum(scale(num, 0, 1), query(body:w0), ..., query(body:w19)): after createWeight the shared
      // context map holds 21 entries ("searcher" and 20 query weights), so the entry scale() puts
      // during the search is the 22nd, and an IdentityHashMap grows when its 22nd entry is added
      List<ValueSource> sources = new ArrayList<>();
      sources.add(new ScaleFloatFunction(new LongFieldSource("num"), 0, 1));
      for (int i = 0; i < 20; i++) {
        sources.add(new QueryValueSource(new TermQuery(new Term("body", "w" + i)), 0f));
      }
      Query query = new FunctionQuery(new SumFloatFunction(sources.toArray(new ValueSource[0])));

      ExecutorService executor = Executors.newFixedThreadPool(8, new NamedThreadFactory("scale"));
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher sequential = new IndexSearcher(reader);
        IndexSearcher concurrent = new IndexSearcher(reader, executor);
        sequential.setSimilarity(new BM25Similarity(1.8f, 0.3f)); // not the default k1 and b
        concurrent.setSimilarity(new BM25Similarity(1.8f, 0.3f));
        String expected = topHits(sequential, query);
        for (int i = 0; i < 1000; i++) {
          assertEquals("search " + i, expected, topHits(concurrent, query));
        }
      } finally {
        executor.shutdown();
        assertTrue(executor.awaitTermination(1, TimeUnit.MINUTES));
      }
    }
  }

  private static String topHits(IndexSearcher searcher, Query query) throws Exception {
    StringBuilder sb = new StringBuilder();
    for (ScoreDoc sd : searcher.search(query, 10).scoreDocs) {
      sb.append(sd.doc).append('=').append(sd.score).append(' ');
    }
    return sb.toString();
  }
}
cd $LUCENE
cp $REPRO/TestScaleFunctionWithExecutor.java lucene/queries/src/test/org/apache/lucene/queries/function/
./gradlew :lucene:queries:test --tests org.apache.lucene.queries.function.TestScaleFunctionWithExecutor -Ptests.seed=DEADBEEF
# assertions off fails the same way: add -Ptests.asserts=false
- Expected
- Every executor search returns the sequential top 10:
612=4.680546 1271=4.6782455 1303=4.6594014 .... - Observed
ComparisonFailure: search 22 expected:<[612=4.680546 1271=4.6782455 ...]> but was:<[1271=5.1422386 612=5.1421137 ...]>(gradle, seedDEADBEEF, assertions off).
More files, environment, full output351 words
One test method, public API only; it sits next to the other function-query tests. The index and the function are fixed (new Random(7)); the test framework still randomizes the codec. It stops at the first executor search whose top 10 differs from the sequential one.
Regression test: this same test. It passes with the fix (gradle, assertions on and off; 10 of 10 standalone runs) and passes :lucene:queries:check -x test. It covers FunctionQuery and the silent-score form only: the FunctionRangeQuery, sort-field and maxdoc() NullPointerException forms rest on the earlier tests (see Independent checks).
Hit rate: on a 32-core aarch64 machine, 20 of 20 standalone runs fail (seeds 5CA1E001..5CA1E010, assertions on and off), the first wrong search between search 1 and search 68; gradle fails too, although in this run Lucene's gradle setup made the test JVM report 1 CPU (it adds -XX:ActiveProcessorCount=1 outside CI when default vectorization is off); the 8 executor threads still run in parallel. On a machine with few cores the race may need more searches to show.
Controls (5 runs each, assertions on; the two source-count controls change one line, the default-Similarity control both setSimilarity lines): 10 query() sources: 5 of 5 pass. 19 sources: 4 of 5 pass, one failed at search 597 (not instrumented; the cause is open). Default BM25Similarity(): no different scores in these 5 runs, but 1 of 5 threw NullPointerException ... "this.weight" is null.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT); the same test also fails on the 10.6.0 and 9.12.3 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64, 32 CPUs |
TestScaleFunctionWithExecutor > testExecutorSearchMatchesSequentialSearch FAILED
    org.junit.ComparisonFailure: search 22 expected:<[612=4.680546 1271=4.6782455 1303=4.6594014 24=4.650218 1480=4.630164 309=4.6299486 764=4.6039133 348=4.5888166 1060=4.5771465 1527=4.524094] > but was:<[1271=5.1422386 612=5.1421137 1303=5.1220636 24=5.108552 1480=5.0892344 309=5.0861616 764=5.069854 348=5.0580726 1060=5.035736 1527=4.9915533] >
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:AD787DCA0434352F]:0)
        at app/junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:117)
        at app//org.apache.lucene.queries.function.TestScaleFunctionWithExecutor.testExecutorSearchMatchesSequentialSearch(TestScaleFunctionWithExecutor.java:87)
:lucene:queries:test (FAILURE): 1 test, 1  failure

# assertions on (same seed): search 11 returned a mixed result, 1271=5.1422386 612=4.9920917 1060=4.9601364 ...
# supporting probe, sequential only, same index and function:
#   BM25Similarity(1.8, 0.3): 612=4.680546 1271=4.6782455 1303=4.6594014 ...
# BM25Similarity() : 1271=5.1422386 612=5.1421137 1303=5.1220636 ...IndexSearcherinstances "are completely thread safe" (IndexSearcher.java:71-75); nothing says function queries need a searcher without an executor.ValueSource's convention: sources store weight info increateWeight, andgetValuesretrieves it (ValueSource.java:66-68);scale()writes ingetValues.- Lucene's own Weight code shares the map, not the user, and the wrong scores are exactly the default Similarity's.
The full argument177 words
- Contract.
IndexSearcherinstances "are completely thread safe, meaning multiple threads can call any of its methods, concurrently" (IndexSearcher.java:71-75); the executor constructor "Runs searches for each segment separately, using the provided Executor" (:194). Nothing says function queries need a searcher without an executor. - ValueSource's convention. "Implementations should propagate createWeight to sub-ValueSources which can optionally store weight info in the context. The context object will be passed to getValues() where this info can be retrieved." (
ValueSource.java:66-68).ScaleFloatFunctionstores nothing increateWeight(:148-151) and writes ingetValues(:98,:106-109). - Who shares the map.
FunctionWeight,FunctionRangeWeightandValueSourceSortFieldhand the one map to every slice; the user never sees it. - Tests.
TestValueSourcessearches throughnewSearcher(reader)(TestValueSources.java:201), which randomly adds an executor (LuceneTestCaseParent.java:2563-2583,:2641-2675); itstestScale(:593) passes because its functions are small. - Effect. The configured Similarity is silently replaced by the default one for some or all of the terms of a search; that is not a documented trade-off of concurrent search.
The devil's-advocate check118 words
Strongest case for "intended": newContext is documented "Returns a new non-threadsafe context map" (ValueSource.java:73); FunctionQuery (FunctionQuery.java:38) and the executor constructor (IndexSearcher.java:199) are @lucene.experimental; and 20 query() sources is an unusual function.
Why it fails: that javadoc warns whoever shares the map, and the sharing is Lucene's own Weight code; experimental status does not make silently different scores acceptable; no limit on function size is documented, and the failures appear at or next to the map's growth points (21 or 42 entries before scale()), not at some size where things degrade. The intended-behaviour verifier and reviews by another model family (OpenAI GPT-5.6, reading-only) rejected this argument. Verdict: not intended, a defect.
Recommended A: compute the scale in createWeight
Compute the scale in ScaleFloatFunction.createWeight, so getValues only reads the shared map (one import, one parameter type, five lines). Validated: the repro passes with assertions on and off, the 112 function-query tests and the whole lucene/queries suite (513 tests) pass, and :lucene:queries:check -x test passes.
private ScaleInfo createScaleInfo(Map<Object, Object> context, IndexReaderContext readerContext)
    throws IOException { /* unchanged body */ }

@Override
public void createWeight(Map<Object, Object> context, IndexSearcher searcher) throws IOException {
  source.createWeight(context, searcher);
  // The slices of a concurrent search share this context, so compute the scale now: getValues
  // must only read the context, never write to it.
  if (context.get(ScaleFloatFunction.this) == null) {
    createScaleInfo(context, searcher.getTopReaderContext());
  }
}
All options and trade-offs3 options · 544 words
Fix A was validated with gradle in a scratch worktree of 5adff78bb168; B was checked earlier with the changed class compiled over the jars in standalone runs; C was not run. A fixes scale(); B also covers custom ValueSources that write the context from getValues. They combine well.
ScaleFloatFunction.createWeight computes the min/max right after source.createWeight, on the thread that creates the Weight, and stores it in the context; getValues then only reads it. createScaleInfo takes an IndexReaderContext instead of a LeafReaderContext, so it can be called with searcher.getTopReaderContext(); ReaderUtil.getTopLevelContext walks to the same root as the stock lazy path, so the min/max is unchanged. The lazy path stays for callers that never call createWeight (asDoubleValuesSource, one context per leaf).
private ScaleInfo createScaleInfo(Map<Object, Object> context, IndexReaderContext readerContext)
    throws IOException { /* unchanged body */ }

@Override
public void createWeight(Map<Object, Object> context, IndexSearcher searcher) throws IOException {
  source.createWeight(context, searcher);
  // The slices of a concurrent search share this context, so compute the scale now: getValues
  // must only read the context, never write to it.
  if (context.get(ScaleFloatFunction.this) == null) {
    createScaleInfo(context, searcher.getTopReaderContext());
  }
}
Trade-offs
- Fixes
scale()only: a customValueSourcethat writes the context ingetValuesstays unsafe (see B). - The whole-index scan moves into
createWeight: it runs once, on the calling thread, before the slices start (today each slice that misses the entry may scan in parallel), and it also runs when no scorer is ever pulled.TotalTermFreqValueSource.createWeightalready loops over all leaves (TotalTermFreqValueSource.java:65-71), an in-tree precedent for the eager scan. - No targeted test yet covers a nested
scale()or theFunctionRangeQueryand sort-field entry points; the runs cover this test and the existing suites only.
What the checks validated
- The repro passes with assertions on and off; with the fixed class compiled over the jars in standalone runs, 10 of 10 runs pass (5 on, 5 off).
- All 15 classes under
org.apache.lucene.queries.function, 112 tests includingTestValueSources.testScaleand the repro, pass; the whole:lucene:queries:test, 513 tests, 5 skipped, passes. :lucene:queries:check -x testpasses (google-java-format, ecj lint, forbidden APIs) with the fix and the new test.
ValueSource.newContext returns Collections.synchronizedMap(new IdentityHashMap<>()). This covers every writer, custom sources included.
Map<Object, Object> context = Collections.synchronizedMap(new IdentityHashMap<>());Trade-offs
- A lock on each context access (per leaf and source, not per document).
- Slices may still compute the scale twice (harmless, same value).
- A caller-supplied map, for example in
GroupingSearch(ValueSource, Map), is not covered.
What the checks validated
Checked earlier with a replaced ValueSource on main ea57360912ed: the independent reproducer's four tests pass with assertions on and off, 0 of 20 + 0 of 20 runs fail on a 64-vCPU host, and the same replacement passes on 4.0.0. Not run through gradle.
Copy the context per slice or leaf after createWeight. Not recommended alone: with the lazy scale() each copy would rescan the whole index. Only useful together with A.
Trade-offs
One small map copy per leaf; needs A to avoid repeated scans.
What the checks validated
Not run.
For downstream servers that turn client function syntax into these classes and search with an executor: a client can only break its own search (an error or a wrong ranking); other searches were unaffected.
Semi-formal: a bytecode scan of Lucene's search-time classes found that scale() is the only built-in function source that writes to the per-search context outside createWeight. A bounded-exhaustive model of the JDK's IdentityHashMap growth rule then predicted which function sizes make that write grow the map, and directed runs failed at or next to those sizes.
The method in full182 words
Method: semi-formal (2026-10-26, main ea57360912ed).
- A bytecode scan (an abstract interpretation of the class files with a per-basic-block symbolic operand stack that resolves the receiver of every field write and collection mutation) covered 689 subtypes of
Weight,Query,ValueSource,Similarityand other search-time types in 17 jars. It flaggedScaleFloatFunction.createScaleInfoas the only built-inValueSourcemethod that puts into the per-search context map outsidecreateWeight. Code reading showed thatFunctionWeighthands that map to every slice. - A differential test of executor and sequential searches passed for small functions, so a bounded-exhaustive model of the real JDK growth rule enumerated every pair of entries before the search (up to 120) and puts during the search (up to 8): 968 cases, 108 of them grow the map during the search.
- Directed experiments and sweeps on a 64-vCPU host then failed at the predicted growth points (20 and 41 padding sources: 5 of 5 runs each; none at 18, 19, 21, 22 and 42 in the independent reproducer's sweep; one throw in five runs at 40, next to the second).
No report of this defect found (re-checked 2026-11-04). Related, not a report: in the review of #15574 (grouping test code) a reviewer and the author noted that a shared ValueSource context is not thread-safe when a source writes it in getValues(); it names none of the affected classes and reports no failure.
Searches5 searches
Re-checked 2026-11-03 in two independent passes and again on 2026-11-04: the searches found no Lucene issue, PR, JIRA entry, list thread or commit, and nothing outside Lucene, that describes this defect. The items below are related but about different defects or sites.
- #15574 (FirstPassGroupingCollectorManager, merged 2026-06-02): review comments on
TestGrouping.java(2026-04-20, 2026-05-19, 2026-05-20). A reviewer noted that if all per-slice collectors share one ValueSource context map "it needs to handle concurrency"; the author replied that some ValueSources "may write the context in getValues() so it's not thread-safe" and kept one map per collector in that test. It is about grouping test code, names none ofFunctionQuery,FunctionRangeQuery, the sort field orScaleFloatFunction, does not say that Lucene's own Weights share the map, and reports no failure; no issue or fix followed. It states the hazard in general, and a maintainer may read it as an earlier acknowledgement of that general hazard; it does not report this defect. - SOLR-5524 (2013, fixed): a single-threaded
scale()context-key collision (aClassCastException); same map, different defect. - #6399 (LUCENE-5335) and #7294 (LUCENE-6232): about the map's generic type.
- SOLR-13350 (2019): a general remark to review Solr's Weights for thread safety; no function-query finding. OpenSearch#10079: a similar race in that project's own script code.
- Side note (read, not executed):
GroupingSearch(ValueSource, Map)hands one caller-supplied context to every per-sliceValueSourceGroupSelectorsince #15936 and #16247, the same hazard at another site.
Caveat: keyword search (first page per GitHub query); private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive), downstream projects, dev@, java-user@, issues@, commits@, JIRA | 2026-11-04 | scripted prior-report search, 51 queries (16 GitHub, 3 commit, 2 downstream, 20 list, 4 JIRA; 6 web queries planned), 367 distinct hits | the closest hits are history and unrelated function-query items (#3905, #3957, #8653, #9951, #5107, the SOLR-5524 commit, #3652) |
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive), downstream projects, dev@, java-user@, issues@, commits@, JIRA | 2026-11-04 (later) | scripted prior-report search, a wider spec of 51 queries (16 GitHub, 3 commit, 2 downstream, 20 list, 4 JIRA; 6 web queries planned), 652 distinct hits | the closest hits are history and unrelated items (#3905, LUCENE-2883, #2704, #7294, the SOLR-5524 commit mail) |
| GitHub (manual, read-only) | 2026-11-04 | ScaleFloatFunction; FunctionQuery and ValueSource items created since 2026-10-20; "ValueSource context concurrency"; newContext ValueSource; "non-threadsafe context"; commits on the five affected files since 2026-10-01 | nothing new: #5428 (unrelated), #15574 (related), no new items, no commits; upstream main f72004515ec2 |
| the web | 2026-11-04 | two general web searches (ScaleFloatFunction concurrent NPE; FunctionQuery executor ValueSource context) | nothing on this defect |
| GitHub, JIRA (LUCENE and SOLR), Solr, OpenSearch, Elasticsearch and Lucene.NET, the lists, the web, git history, the changed files of all 406 open PRs | 2026-10-26 | 223 logged queries, six scripted prior-report search runs | the related #15574 review remark only |
In Lucene since the function queries moved into the queries module (a993ae90323, LUCENE-3249, 2011); first released in 4.0.0-ALPHA; the code pattern has not changed since. Executed on 14 releases from 4.0.0-ALPHA to 10.6.0 and on main: affected each time. 3.6.x has no such API.
Versions tested7 rows
Introduced into Lucene by a993ae90323 (2011-06-28, LUCENE-3249 = #4322 "Moved FunctionQuery impls to new Queries module", Christopher John Male), with b3f0ae9b7a0 the day before (LUCENE-3240 = #4313: FunctionQuery, ValueSource and newContext). The search-time put came with that move from Solr code, where 8b241d92303 (2011-01-08, LUCENE-2831 = #3905, Yonik Seeley) made scale() cache its min/max in the shared context from getValues; the executor search with one shared Weight is from 87274d00ac1 (2011-01-05, LUCENE-2837 = #3911). svn era, no PR. FunctionRangeQuery shares its map the same way since it was added (13f8ab93a97, LUCENE-6720, 5.4.0). SOLR-5524 (4.7.0) changed only the context key. The bug's code pattern (one context per Weight shared by the slices, "searcher" in the map, the lazy put from getValues, nothing stored in createWeight) is present at all 123 release tags from 4.0.0-ALPHA to 10.5.2 in the history clone, although the code itself changed over time (for example the context key in 4.7.0); the five affected files are identical in 10.6.0 and main 5adff78bb168; upstream main f72004515ec2 (2026-11-03) has no later commit on them.
| Version or commit | Verdict | Result |
|---|---|---|
| 3.6.0, 3.6.2 | before | no context-map function API (API probe) |
| 4.0.0-ALPHA | first: 4.0.0-ALPHA | history probe fails, assertions on and off |
| 4.0.0 | affected | history probe fails; a synchronized-map replacement passes |
| 4.10.4 - 8.11.4 | affected | history probe fails on 4.10.4, 5.4.0, 5.5.5, 6.6.6, 7.7.3, 8.0.0 and 8.11.4; the finder's test fails on 8.11.4 |
| 9.0.0 - 10.5.2 | affected | history probe fails on 9.0.0, 9.12.3, 10.0.0 and 10.5.2; this doc's test fails on 9.12.3 |
| 10.6.0 | affected | this doc's test fails, assertions on and off |
main 5adff78bb168 | affected | this doc's test fails through gradle, assertions on and off; passes with fix A |
An independent reproducer, an intended-behaviour verifier, the adjudication and reviews by another model family (OpenAI GPT-5.6, reading-only) all rated it real; the adjudication confirmed it with high confidence. Re-runs on main e1faeba08bde and this doc's runs on 5adff78bb168 still fail.
Checks and verdicts298 words
Neither review by another model family executed Java (both were reading-only); separate runs re-ran the finder's and the controls' tests, and those failed on stock and passed with the fix. A fourth independent re-check (2026-10-26) re-ran the finder's test and lowered the likelihood to contrived, because the silent-score form also needs a non-default Similarity.
| Check | Verdict | What it found |
|---|---|---|
| finder | found | Three-method JUnit (FunctionQuery, FunctionRangeQuery, a BM25Similarity(1.8, 0.3) case) fails 3 of 3 on main (assertions on and off), 10.5.2, 9.12.3 and 8.11.4; 20 of 20 runs on a 64-vCPU host; 0 of 20 with the fix. |
| cross-model review before the claim (OpenAI GPT-5.6, reading-only) | real (high) | Root cause and fix correct, not intended; its open points (sort-field path, 4.0 lower bound) were later executed. |
| independent reproducer | real | Own four-test JUnit, including the ValueSource sort-field path, fails 4 of 4 on main (on and off), 10.5.2 and 9.12.3; the padding sweep fails at the growth points (and once next to one); the synchronized-map control and the fix pass. |
| cross-model review, root-cause lens (OpenAI GPT-5.6, reading-only) | real (high) | Intended argument weak; root cause, fix and inputs agreed; first wrong step ScaleFloatFunction.java:98. |
| intended-behaviour verifier | real | Rejected the "non-threadsafe javadoc", "legacy API", "@lucene.experimental" and "function too large" arguments; re-ran the finder's test (fails). |
| adjudication | confirmed (high) | Re-ran the reproducer's and the finder's tests on main (fail) and the synchronized-map control (passes 4 of 4); no duplicate. |
re-run on main e1faeba08bde | still reproduces | The finder's test fails 3 of 3 with assertions on and off (2026-11-02). |
this doc's runs on 5adff78bb168 | reproduces | The one-test repro fails 20 of 20 runs and through gradle; passes with fix A (gradle and 10 of 10 standalone runs). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 533 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,398 words
- Registry title
- FunctionQuery, FunctionRangeQuery and ValueSource sort fields share one non-thread-safe context map across the slices of an executor search, and scale() (ScaleFloatFunction) writes to it during the search, so when that write grows the map the search throws NullPointerException or silently returns different scores
- Area
- queries / function queries (ValueSource context map under concurrent search)
- Priority
- Low, rank 700: With an executor search a FunctionQuery whose scale() grows the shared context map throws a NullPointerException or, with a non-default Similarity, silently gives different scores; the trigger is contrived, so it goes with the concurrent-search crash row LFV-125.
- Impact class
- silent wrong results
- Impact note
- Applications that search through an IndexSearcher with an executor (opt-in; in Solr, for example, a node executor plus multiThreaded=true [read]) with a FunctionQuery, FunctionRangeQuery or ValueSource sort whose function contains scale() and enough context-storing sources (query(), totaltermfreq(), sumtotaltermfreq(); about 20 with one scale()) that a search-time scale() put is the 22nd or 43rd entry of the shared IdentityHashMap (or close to it, through concurrent duplicate puts) are hit: the search fails with NullPointerException ('"searcher" is null') or, on a searcher with a non-default Similarity, silently returns different scores and top hits (20 of 20 runs of the one-test repro, 2026-11-04); in the controls a 10-source function passed 5 of 5 runs and a 19-source one failed once in 5, searchers without an executor and the asDoubleValuesSource adapter [read] are not affected, and no scale is needed.
- Summary
- You search with a FunctionQuery (or FunctionRangeQuery, or a sort by ValueSource.getSortField) whose function uses scale() together with about twenty context-storing sources such as query(), on an IndexSearcher built with an executor, and expect the same hits and scores as on a searcher without one, because IndexSearcher is documented as completely thread safe. Instead all slices share the Weight's one IdentityHashMap context (documented 'non-threadsafe'), ScaleFloatFunction.getValues puts its min/max entry into it from the slice threads, and when that put resizes the map other slices miss entries such as "searcher". The search then throws NullPointerException, or, on a searcher with a non-default Similarity, QueryValueSource silently rebuilds its weight with the default Similarity and the scores and top hits change.
- Introduced
- a993ae9032337ca8d5b2c7a4d58bf41a6f5053f5 (2011-06-28, svn r1140906, LUCENE-3249 = #4322 'Moved FunctionQuery impls to new Queries Module': brings ScaleFloatFunction with its lazy getValues-time put, QueryValueSource and MaxDocValueSource into Lucene's queries module) with its companion b3f0ae9b7a0d9e58b1e38d9b48fe6cb3cfbd4e5a (2011-06-27, r1140379, LUCENE-3240 = #4313: FunctionQuery with one context per FunctionWeight, and ValueSource.newContext, an IdentityHashMap documented 'non-threadsafe') [read: history clone; exec: 4.0.0-ALPHA fails, 3.6.x has no such API]. Code origin, all first released in 4.0.0-ALPHA: the search-time put comes from Solr's ScaleFloatFunction in 8b241d9230380b75157ad396c74ca1498f287666 (2011-01-08, LUCENE-2831 = #3905), the shared-Weight executor search from 87274d00ac17cbee79da2b162f8f169abdd61cd7 (2011-01-05, LUCENE-2837 = #3911), the context map from 1eb4697977563fa26562e5973cc9c06796ba3aa3 (2009-09-17, SOLR-1432, Solr code); the context key changed later (SOLR-5524, 4.7.0) without changing the lazy put. Pre-GitHub (svn), no PR. (2011-06-28 (move into Lucene; companion 2011-06-27; the search-time put itself dates from 2011-01-08 in Solr code))
- First affected version
- 4.0.0-ALPHA [exec: fails -ea and -da; first GA release 4.0.0, also executed: fails]; FunctionRangeQuery from 5.4.0, where the class first appears [exec]; not affected: 3.6.2 and earlier, where the API does not exist [exec: API probe on 3.6.0 and 3.6.2]
- Affected versions
- Every release from 4.0.0-ALPHA through 10.6.0, plus main (ea57360912ed, 5adff78bb168); [exec, 2026-11-04] the one-test repro fails on the released 10.6.0 (-ea and -da) and 9.12.3 jars and on main 5adff78bb168 (-ea and -da). [exec] fail: 4.0.0-ALPHA, 4.0.0, 4.10.4, 5.4.0, 5.5.5, 6.6.6, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (history probe, public API, 300 searches per case; 26 of 26 stock JVM runs failed, every control without scale() passed; -da also on 4.0.0-ALPHA, 4.0.0, 8.11.4, 9.12.3, 10.5.2 and main); the finder's JUnit fails on main (-ea, -da), 10.5.2, 9.12.3 and 8.11.4; the independent reproduction's JUnit on main (-ea, -da), 10.5.2 and 9.12.3; separate runs on main (-ea, -da), 10.5.2 and 9.12.3. [read] the other release tags have the same code (code-identity check over 123 of 123 tags 4.0.0-alpha..10.5.2 in the history clone; the 8.9.0-8.11.x tags are not in the clone, 8.11.4 was executed). Not fixed upstream: no commit and no open PR changes this code (prior-report search, 2026-10-26).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal; also reached by exhaustive check, code reading
- Upstream and prior reports
- no report of this defect found; one related item (searched 2026-10-26, read-only, by the finder, the intended-behaviour check and a follow-up search: 223 logged queries, six scripted prior-report searches over apache/lucene issues and PRs, commits, downstream repositories (apache/solr, OpenSearch, Elasticsearch, lucenenet), dev@, java-user@, issues@, commits@, builds@ and the Solr lists, the LUCENE and SOLR JIRA archives (16 extra JQL queries) and the web; the changed-file lists of all 406 open apache/lucene PRs; git history of the affected classes; 27 hits assessed). Related: in the review of apache/lucene#15574 (FirstPassGroupingCollectorManager, merged 2026-06-02; comments of 2026-04-20, 2026-05-19 and 2026-05-20 on TestGrouping.java) a reviewer noted that if all per-slice collectors share one ValueSource context map 'it needs to handle concurrency', and the author replied that other ValueSources 'may write the context in getValues() so it's not thread-safe' and kept one map per collector in the test; it names none of the affected classes, does not say that Lucene's own Weights share the map, reports no failure, and no issue or fix followed. Context only: SOLR-5524 (2013, a single-threaded ScaleFloatFunction context-key collision, fixed), #6399 (LUCENE-5335) and #7294 (LUCENE-6232) about the map's type, SOLR-13350 (a 2019 remark to audit Solr's Weights for thread safety), OpenSearch#10079 (an analogous bug in OpenSearch's own expression script). Not fixed: no commit changes this code and no open PR touches it (open #14775 edits ValueSource.java without changing the context).
- Lucene commit tested
- main
5adff78bb168(12.0.0-SNAPSHOT), 2026-11-04: the one-test repro through gradle in a scratch worktree, stock (fails, assertions on and off) and with fix A (passes; the 112 tests underorg.apache.lucene.queries.function, the wholelucene/queriessuite with 513 tests, and:lucene:queries:check -x test); the standalone JUnit runner on main (20 of 20 runs fail; three controls), on the 10.6.0 and 9.12.3 release jars (fails), and with fix A applied (10 of 10 pass). Earlier records: the finder's and the verifiers' tests on mainea57360912ed(the function-query sources andIndexSearcher.javaare identical), a history probe on 13 releases from 4.0.0-ALPHA to 10.5.2, and a re-run on maine1faeba08bde(2026-11-02).
- Finding record
a Lucene main checkout @ ea57360912ed: lucene/queries/src/java/org/apache/lucene/queries/function/ValueSource.java:66-71 (createWeight javadoc: store in createWeight, retrieve in getValues), :73-77 (newContext: 'Returns a new non-threadsafe context map', IdentityHashMap with "searcher"), :198-203 (asDoubleValuesSource: new context per getValues call), :373-383 (ValueSourceSortField.rewrite: one context for the rewritten sort), :434 (comparator doSetNextReader calls getValues(fcontext, ...)); FunctionQuery.java:70-71 (one context per FunctionWeight), :116 (AllScorer: func.getValues(weight.context, leaf)); FunctionRangeQuery.java:148-149, 154, 170 (FunctionRangeWeight vsContext), :177 (isCacheable); valuesource/ScaleFloatFunction.java:60-99 (createScaleInfo, put at :98), :106-108 (getValues: lazy createScaleInfo), :149-150 (createWeight only delegates); valuesource/QueryValueSource.java:81-86 (createWeight puts its weight), :113-128 (QueryDocValues fallback: new IndexSearcher with the default Similarity when "searcher" is missing); valuesource/MaxDocValueSource.java:49-50, DocFreqValueSource.java:60, IDFValueSource.java:51, NormValueSource.java:66, TFValueSource.java:54 (dereference context.get("searcher")); valuesource/SumTotalTermFreqValueSource.java:66, TotalTermFreqValueSource.java:73 (other createWeight puts); lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:68-75 ('completely thread safe'), :194 (executor constructor: 'Runs searches for each segment separately')
- The finding in 30 seconds
lucene/queries/src/java/org/apache/lucene/queries/function/ValueSource.java:66-68, (at 5adff78bb168) :73-78, :200, :379-382, :434lucene/queries/src/java/org/apache/lucene/queries/function/FunctionQuery.java:70-71, (at 5adff78bb168) :116; FunctionRangeQuery.java:148-149, :154, :170lucene/queries/src/java/org/apache/lucene/queries/function/valuesource/ScaleFloatFunction.java:61-100, (at 5adff78bb168) :98, :106-109, :148-151; valuesource/QueryValueSource.java:85, :114-127, :150; valuesource/MaxDocValueSource.java:49-50OpenJDK 25.0.3 src.zip java.base/java/util/IdentityHashMap.java:160, :337-349, :435-465, :473-504
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:71-75, (at 5adff78bb168) :194, :199lucene/queries/src/java/org/apache/lucene/queries/function/ValueSource.java:66-68, (at 5adff78bb168) :73; FunctionQuery.java:38; valuesource/ScaleFloatFunction.java:98, :106-109, :148-151lucene/queries/src/test/org/apache/lucene/queries/function/TestValueSources.java:201, (at 5adff78bb168) :593; lucene/test-framework/src/java/org/apache/lucene/tests/util/LuceneTestCaseParent.java:2563-2583, :2641-2675
- History
a Lucene clone: git diff releases/lucene/10.6.0 5adff78bb168 (affected files identical)
- Diagrams
lucene/queries/src/java/org/apache/lucene/queries/function/FunctionQuery.java:70-71, (at 5adff78bb168) :116; valuesource/ScaleFloatFunction.java:98, :106-109; valuesource/QueryValueSource.java:114-127OpenJDK 25.0.3 java/util/IdentityHashMap.java:456, :489-502
- TestScaleFunctionWithExecutor.java (one test, lucene/queries):
repro/LFV-567/src/org/apache/lucene/queries/function/TestScaleFunctionWithExecutor.java(103 lines)
A picture of the shared context map and the growth during the search, built from the code at 5adff78bb168 and this doc's one test and its executed runs; the PNG is the summary still.
assets/LFV-567/bug.png(533 KB)