Two parts of one decision ask different codec objects: the merge asks the writer's, the "already merged?" check asks the one the segment was loaded with.
- A segment can be stored as one compound file (
.cfs) or as separate files. On main, whether a merged segment is compound is decided by the codec'sCompoundFormat: compound files on or off, a size threshold of 64 MB (65,536 docs forLogDocMergePolicy), and a maximum size. Each codec instance has its own copy of these settings. (A newly flushed segment followsIndexWriterConfig.getUseCompoundFile()instead, default true.) - When a writer opens an index, every segment read from the commit gets the codec named there, looked up with
Codec.forName: one shared instance per name (by default alsoCodec.getDefault(), unlessCodec.setDefaultinstalled another), with default settings unless someone changed it. - Before
forceMerge(1)rewrites a lone segment,MergePolicy.isMergedchecks whether it already has no deletions and "matches the current compound file setting". If it does, the segment is kept.
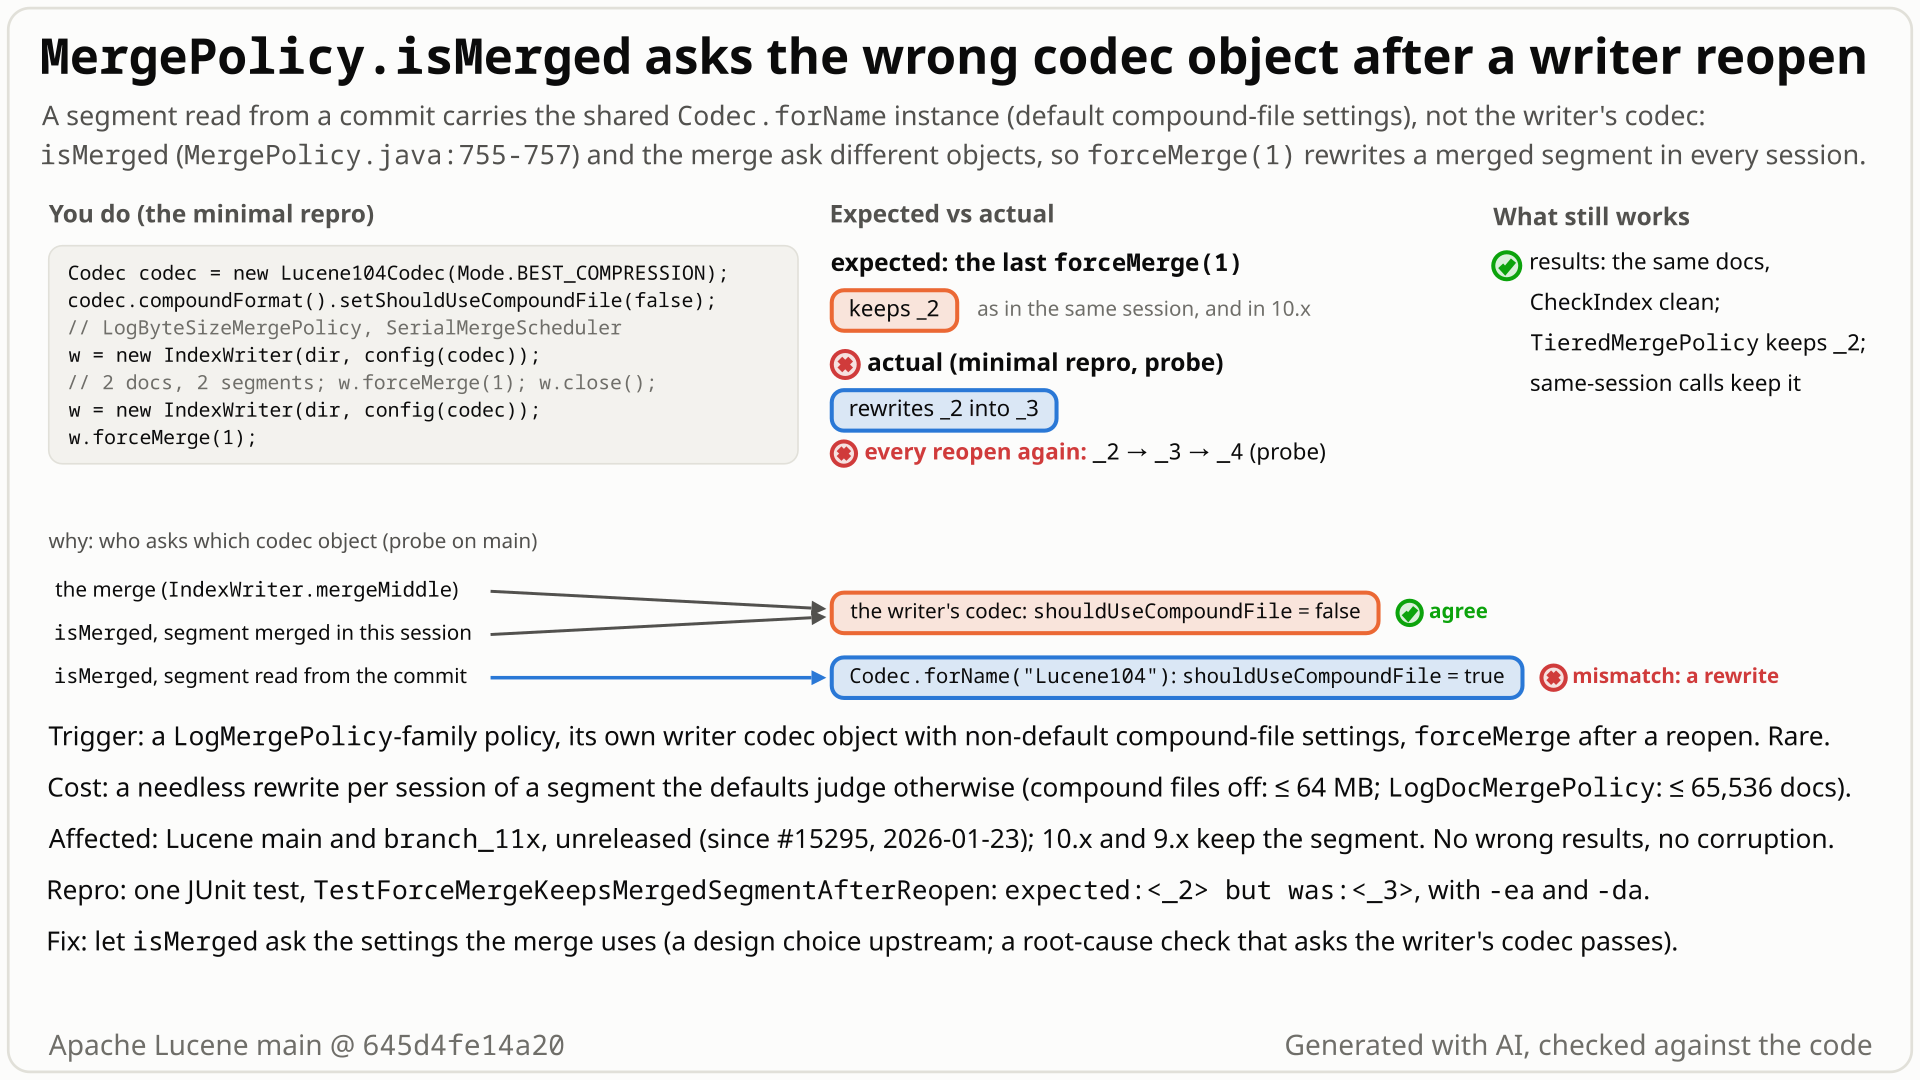
isMerged ask, in the first writer session and after a reopen. After a reopen isMerged asks the shared Codec.forName object with default settings, so the merged segment _2 is rewritten into _3. Select the still to open it at full size. Generated with AI, checked against the code.- Give the writer its own codec,
new Lucene104Codec(BEST_COMPRESSION), turn compound files off on it as MIGRATE.md shows, and useLogByteSizeMergePolicy. Add 2 documents in 2 segments (flushed as compound files: a flush followsIndexWriterConfig.getUseCompoundFile(), not the codec) andforceMerge(1): you get one non-compound segment,_2. Close the writer. - Reopen the writer with the same config and call
forceMerge(1)again. You expect_2to be kept: one segment, no deletions, non-compound as configured. 10.x keeps it with the equivalent settings. - Instead
_2is rewritten into_3. The reopened writer judges_2by the sharedCodec.forName("Lucene104")instance, whose default settings say a segment up to 64 MB (this one is 773 bytes) should be compound, so_2looks unmerged. - The rewrite is written with the writer's codec, so
_3is non-compound again, and the firstforceMerge(1)of the next session rewrites it into_4: one needless rewrite per writer session that force-merges. Content, deletions and CheckIndex stay the same; only I/O is wasted.
Unreleased: on main and branch_11x. It takes all four: a LogMergePolicy-family policy (the default TieredMergePolicy never reaches the check), your own codec instance, non-default compound settings on it, and forceMerge after a reopen. Cost: one silent rewrite per session of segments up to 64 MB (or 65,536 docs with LogDocMergePolicy), more with raised thresholds.
Mechanism, terms and numbers691 words
Since #15295 the compound-file settings (setShouldUseCompoundFile, the doc and byte thresholds, the maximum compound segment size) are fields of each CompoundFormat instance, and Lucene104Codec holds one per codec instance. MIGRATE.md tells users to set them on iwc.getCodec().compoundFormat().
A merge decides the compound flag of its new segment with the writer's codec. MergePolicy.isMerged, which decides whether a lone segment needs a forced merge at all, asks the codec the segment carries. For a segment the writer merged in this session that is the writer's codec; for a segment read from a commit it is Codec.forName(name), the shared SPI instance, whose settings are the defaults unless someone changed that instance. So a writer with its own codec instance and non-default compound settings sees its merged segment as "not merged" after every reopen, and the next forceMerge rewrites it through LogMergePolicy.findForcedMerges. The rewrite uses the writer's codec again, so this repeats once in every writer session that force-merges. No result changes; it costs I/O. It is on main and branch_11x only, unreleased.
| who asks | codec asked | settings it sees |
|---|---|---|
the merge (IndexWriter.mergeMiddle; also addIndexes(CodecReader...)) | the merged segment's codec, which IndexWriter builds from config.getCodec() | the writer's |
isMerged, for a segment merged in this session | the writer's codec (same reason) | the writer's: kept |
isMerged, for a segment read from a commit | Codec.forName(name) | the shared instance's (the defaults unless changed): rewritten |
isMerged ends with info.info.getCodec().compoundFormat().useCompoundFile(size(info, mergeContext), this) == info.info.getUseCompoundFile() (MergePolicy.java:756-757). The settings are per-instance fields (CompoundFormat.java:48-57), and Lucene104Codec creates one CompoundFormat per instance (Lucene104Codec.java:75, 157-159). A merged segment gets config.getCodec() (IndexWriter.java:5334) and the merge asks it (IndexWriter.java:5683-5691). A segment read from a commit gets Codec.forName (SegmentInfos.java:407, 423, 561-564), which returns the cached SPI instance (Codec.java:118-119), by default the same object as Codec.getDefault() (Codec.java:59; Codec.setDefault at :141-153 can install another). Segments loaded at an older commit through IndexWriterConfig.setIndexCommit and segments copied by addIndexes(Directory...) also carry the Codec.forName instance (IndexWriter.java:1083-1103, 3130; read, not executed); a writer opened from an NRT reader instead clones that reader's in-memory segment infos (IndexWriter.java:1049-1053) and may keep an earlier writer's codec objects (read, not executed). The isMerged javadoc is partly stale: the body no longer checks its "same dir as the writer" part.
- The rewrite is written with the writer's codec, so the new segment has the writer's compound flag again. In the same session it carries the writer's codec and is kept, so one
forceMergecall cannot loop; after the next reopen it carries the shared instance again (a reopen alone rewrites nothing; the firstforceMerge(1)after it does). Executed: exactly 1 rewrite per writer session over 5forceMerge(1)calls, in 3 sessions and 3 configurations. - A writer that uses the default codec (with no
Codec.setDefaultcall) shares one object with the segments it reads, so nothing goes wrong. Neither does an own instance left at the default settings. LogMergePolicy.findForcedMergesasksisMergedfor a lone original segment (LogMergePolicy.java:181-203, 352, 379; also:241, 257, 289for size-limited and multi-segment forced merges, read only). The defaultTieredMergePolicyfirst drops every segment that is not insegmentsToMerge(TieredMergePolicy.java:775-777) and then reports a lone remaining segment as already merged before it asks (:836-843), so itsisMergedcall is never reached. Background merges andforceMergeDeletesnever askisMerged.
With such a policy, a lone segment without deletions is rewritten when the writer codec's compound decision for its size differs from that of the shared Codec.forName instance as it currently is (the defaults unless changed):
setShouldUseCompoundFile(false)(the MIGRATE.md recipe): segments the defaults would make compound, up to 64 MB with byte-size policies or 65,536 docs withLogDocMergePolicy. Measured over 3 sessions: a 60,000-docLogDocMergePolicysegment rewritten every time; a 70,000-doc one and an 80.4 MBLogByteSizeMergePolicysegment kept.- Raised thresholds:
setCfsThresholdDocSize(100000)with a 70,000-doc compound segment, rewritten after a reopen;setCfsThresholdByteSize(1 GB)with an 80.4 MB compound segment, rewritten in all 3 sessions.
Exposure and likelihood256 words
- Who is hit. Applications on Lucene main (11.0.0-SNAPSHOT) that use
LogByteSizeMergePolicy,LogDocMergePolicyor a subclass, give the writer a codec instance other than the oneCodec.forNamereturns (new Lucene104Codec(Mode), any per-field subclass, an instance installed withCodec.setDefault(...), or a separately constructed instance of a custom codec registered through SPI; executed only with the first and withTestUtil.getDefaultCodec(false)), set compound-file settings on it whose answer differs from the shared instance's for the segment's size, and callforceMergeafter reopening the writer. - Default configuration is not hit: the default
TieredMergePolicynever reaches itsisMergedcall (it drops segments outsidesegmentsToMergefirst), and the default codec, with noCodec.setDefaultcall, is the same object the segments are read with. - Cost: one needless rewrite of an already merged segment per writer session that calls
forceMerge, with the transient disk space of any forced merge. Small under the MIGRATE.md recipe (segments up to 64 MB, or 65,536 docs withLogDocMergePolicy); large segments only with raised thresholds (an 80.4 MB segment was rewritten in every session under a 1 GB threshold). The runs counted rewrites and checked content; they did not measure bytes written, I/O time, commit or fsync churn, or effects on open readers and caches. - Silent: nothing logs it; live documents, stored values, doc values, deletions and CheckIndex are unchanged by the rewrite.
- Not released yet: it is on main and
branch_11x(created from main on 2026-10-29); 10.6.0, earlier releases andbranch_10xare not affected, so it can be fixed before 11.0.0 ships.
One JUnit method on the public API: an own Lucene104Codec(BEST_COMPRESSION) with compound files off, LogByteSizeMergePolicy, SerialMergeScheduler and 2 empty documents in a ByteBuffersDirectory. It merges to one segment, reopens the writer and force-merges again. It fails with assertions on and off, for every seed tried.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.io.IOException;
import org.apache.lucene.codecs.Codec;
import org.apache.lucene.codecs.lucene104.Lucene104Codec;
import org.apache.lucene.document.Document;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestForceMergeKeepsMergedSegmentAfterReopen extends LuceneTestCase {

  private static IndexWriterConfig config(Codec codec) {
    return new IndexWriterConfig()
        .setCodec(codec)
        .setMergePolicy(new LogByteSizeMergePolicy())
        .setMergeScheduler(new SerialMergeScheduler());
  }

  public void testForceMergeOfMergedIndexAfterReopen() throws IOException {
    Codec codec = new Lucene104Codec(Lucene104Codec.Mode.BEST_COMPRESSION);
    codec.compoundFormat().setShouldUseCompoundFile(false); // as MIGRATE.md shows
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, config(codec))) {
        w.addDocument(new Document());
        w.flush();
        w.addDocument(new Document());
        w.forceMerge(1);
      }
      String merged = SegmentInfos.readLatestCommit(dir).info(0).info.name;
      try (IndexWriter w = new IndexWriter(dir, config(codec))) {
        w.forceMerge(1);
      }
      // expected: the already merged segment is kept; actual: it is rewritten into a new segment
      assertEquals(
          "segment after forceMerge(1)",
          merged,
          SegmentInfos.readLatestCommit(dir).info(0).info.name);
    }
  }
}
cp $REPRO/TestForceMergeKeepsMergedSegmentAfterReopen.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestForceMergeKeepsMergedSegmentAfterReopen -Ptests.seed=DEADBEEF -Ptests.asserts=true
# same failure with -Ptests.asserts=false
# recorded runs: ./gradlew --no-daemon --offline, in a detached scratch worktree of 645d4fe14a20
- Expected
- The already merged segment
_2is kept by theforceMerge(1)after the reopen. - Observed
segment after forceMerge(1) expected:<_[2]> but was:<_[3]>: the segment was rewritten.
More files, environment, full output186 words
The test sits in org.apache.lucene.index by upstream convention but uses nothing package-private. It builds IndexWriterConfig directly (no randomized writer settings) and is single-threaded. Session 1 flushes _0 and _1 and merges them into the non-compound _2; session 2 opens a new writer with the same codec instance and calls forceMerge(1) on the single merged segment. The same test is the suggested regression test; it passes with the fix below and passes the core format and lint checks as written.
Not asserted here (shown by the verification runs): one rewrite per writer session, the opposite direction (a raised doc threshold rewrites a 70,000-doc compound segment), and that TieredMergePolicy keeps the segment.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; also fails on a9779ef3c193, ea57360912ed and the introducing 6643a5dbe1ed; with the fix: passes |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
# stock main 645d4fe14a20, seed DEADBEEF (same with -Ptests.asserts=false)
TestForceMergeKeepsMergedSegmentAfterReopen > testForceMergeOfMergedIndexAfterReopen FAILED
    org.junit.ComparisonFailure: segment after forceMerge(1) expected:<_[2]> but was:<_[3]>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:6AE676CFFF132E72]:0)
        at app//org.junit.Assert.assertEquals(Assert.java:117)
        at app//org.apache.lucene.index.TestForceMergeKeepsMergedSegmentAfterReopen.testForceMergeOfMergedIndexAfterReopen(TestForceMergeKeepsMergedSegmentAfterReopen.java:51)
1 test completed, 1 failed

# with the recommended fix: BUILD SUCCESSFUL, 1 test, 0 failures (assertions on and off)isMergedcalls a segment merged when it "matches the current compound file setting"; MIGRATE.md says to set that oniwc.getCodec().- The merge asks the writer's codec, the check the segment's: the same segment is "merged" in one session, "not merged" after a reopen.
- A regression from #15295: before it both asked the writer's merge policy; 10.x keeps the segment.
The full argument269 words
- Documented intent. The
isMergedjavadoc (since LUCENE-5038, 2013; partly stale, as the body no longer checks the "same dir" part): "Returns true if this single info is already fully merged (has no pending deletes, is in the same dir as the writer, and matches the current compound file setting" (MergePolicy.java:746-749). On main the only place to configure that setting is the codec, and MIGRATE.md's recipe isCompoundFormat cfs = iwc.getCodec().compoundFormat(); cfs.setShouldUseCompoundFile(false);(MIGRATE.md:322-324).LiveIndexWriterConfig.setUseCompoundFilepoints toCompoundFormatfor merges. - One decision, two answers. The merge uses the writer's codec;
isMergeduses the segment's. Executed: a secondforceMerge(1)in the same session keeps the segment, and the first one after a reopen rewrites it. - Regression. Before #15295 all three compound-file decisions asked the writer's merge policy, so they always agreed; 10.5.2 and 9.12.3 keep the segment with the equivalent merge-policy settings (executed).
- Upstream uses private instances itself.
TestUtil.getDefaultCodec(boolean)sets compound settings on a freshLucene104Codec, andnewIndexWriterConfigrandomizes them on the config's codec; with that helper andLogDocMergePolicythe bug reproduces (segments_4,_5,_6over 3 sessions). - Precedents fixed as bugs: #15616 (compound settings lost through a different
CompoundFormatinstance), LUCENE-5481 / #6544 (forceMergeran an unneeded merge on a merged segment), LUCENE-9905 / #176 (a merge used the SPI default instead of configured format parameters). - No upstream test asserts whether
forceMergekeeps an already merged single segment after a writer reopen. Tests do reopen writers with per-codec compound settings, for exampleTestDeletionPolicy(TestDeletionPolicy.java:333, 353, 357-359), but only to merge an index of more than one segment (:342-348).
The devil's-advocate check174 words
The strongest case for "intended": forceMerge promises only "at most n segments" and leaves the choice to the merge policy; MergePolicy and CompoundFormat are @lucene.experimental; a segment's codec is the codec that wrote it, so asking it is self-consistent; Lucene104Codec(Mode) documents its options for "newly flushed/merged segments"; the MIGRATE.md recipe works with the default codec; since LUCENE-8330 the segment's codec is the only codec isMerged can reach; and in an index whose segments use several codecs, a maintainer may prefer to judge each segment by its own codec.
Why it fails: nothing documents that the settings work only on the named instance, and setting them there changes every writer in the JVM; compression-mode and per-field codecs are necessarily separate instances; the merge itself uses the writer's codec, so asking the segment's codec does not answer "would a merge change this segment?"; the outcome flips across a reopen with an identical config; and 10.x behaves as expected. The checkers who built this case rated it moderate and weak to moderate, and both rejected it.
Recommended Give isMerged the writer's CompoundFormat through MergeContext
Let isMerged ask the same CompoundFormat the merge uses: a default method MergeContext#getCompoundFormat() (null keeps today's fallback), implemented by IndexWriter as config.getCodec().compoundFormat() and delegated by CachingMergeContext. Validated on the runs listed, not as broad compatibility proof: the repro passes, and all 1,396 core index tests and the lint checks pass.
// MergePolicy.MergeContext
default CompoundFormat getCompoundFormat() {
  return null; // unknown: isMerged falls back to the segment's codec
}
// IndexWriter (CachingMergeContext delegates to it)
public CompoundFormat getCompoundFormat() {
  return config.getCodec().compoundFormat();
}
// MergePolicy.isMerged
CompoundFormat cf = mergeContext.getCompoundFormat();
if (cf == null) cf = info.info.getCodec().compoundFormat();
return delCount == 0
    && cf.useCompoundFile(size(info, mergeContext), this) == info.info.getUseCompoundFile();
All options and trade-offs4 options · 581 words
One option was built and validated in a scratch checkout of main 645d4fe14a20. A clean fix needs a design choice, because MergeContext exposes no codec and MergePolicy has had no writer access since LUCENE-8330; the other options come from the verifiers and the adjudication.
Give isMerged the writer's CompoundFormat through MergeContext (validated by the checks) (recommended)
+35/-1 in three files of lucene/core. A default method MergeContext#getCompoundFormat() returns null (unknown); IndexWriter overrides it with config.getCodec().compoundFormat(); CachingMergeContext, which wraps the writer for findForcedMerges, delegates; isMerged asks it and falls back to the segment's codec when it is null. The check then asks exactly what the merge asks, so "merged" means "a merge would not change the compound flag". Writers on the default codec (with no Codec.setDefault call), and own Lucene104Codec instances with default settings, should see no change (the executed controls). Indexes whose segments use several codecs, and custom-named codecs, were not checked and need a compatibility review.
// MergePolicy.MergeContext
default CompoundFormat getCompoundFormat() {
  return null; // unknown: isMerged falls back to the segment's codec
}
// IndexWriter (CachingMergeContext delegates to it)
public CompoundFormat getCompoundFormat() {
  return config.getCodec().compoundFormat();
}
// MergePolicy.isMerged
CompoundFormat cf = mergeContext.getCompoundFormat();
if (cf == null) cf = info.info.getCodec().compoundFormat();
return delCount == 0
    && cf.useCompoundFile(size(info, mergeContext), this) == info.info.getUseCompoundFile();
Trade-offs
- A new experimental method on the public
MergeContextinterface, and so a publicIndexWriter#getCompoundFormat(). - A
MergeContextimplemented outside Lucene keeps today's behaviour until it overrides the method; any wrapper must delegate it.
What the checks validated
- Stock
645d4fe14a20: the repro fails with assertions on and off. With the fix: it passes both ways. - 19 merge-related core suites (
TestLogMergePolicy,TestTieredMergePolicy,TestIndexWriterMergePolicy,TestCachingMergeContext,TestIndexWriterForceMerge,TestSizeBoundedForceMerge,TestForceMergeForever,TestMergePolicy,TestFilterMergePolicy,TestNoMergePolicy,TestUpgradeIndexMergePolicy,TestTemporalMergePolicy*,TestSoftDeletesRetentionMergePolicy,TestOneMergeWrappingMergePolicy,TestThreadedForceMerge,TestMergeCarryOverFromDisk,TestAddIndexes, the repro): 158 tests (7 skipped), 0 failures, assertions on and off. - All core
org.apache.lucene.index.*tests: 215 suites, 1,396 tests (56 skipped), 0 failures, assertions on and off. checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMain,forbiddenApisTestandrenderJavadocof:lucene:corepass.- The independent reproduction's 4-test JUnit, including the opposite direction (raised doc threshold,
LogDocMergePolicy, 70,000-doc compound segment), passes 4 of 4 with the three fixed classes, assertions on and off; it fails 2 of 4 on stock. - Not run: other modules, the full core suite, x86,
MergeContextimplementations outside Lucene, mixed-codec indexes.
If the context is the IndexWriter, or the package-private CachingMergeContext around it, ask w.getConfig().getCodec().
Trade-offs
Makes the repro pass (it was used as the root-cause check), but relies on instanceof against a package-private class and silently changes nothing for any other context. Not proposed.
For example onto IndexWriterConfig, where the merge and isMerged can both read them.
Trade-offs
Removes this bug class and the JVM-wide mutation of the default codec that the MIGRATE.md recipe causes with the default codec, but reverses part of #15295's API shortly before 11.0. Not run.
A javadoc and MIGRATE.md change only.
Trade-offs
A workaround, not a fix: it changes every writer in the JVM, and a writer with its own instance (a compression mode, a per-field subclass) would have to keep the same settings on its own instance and on the shared one, which is global and fragile. Not recommended.
An open Elasticsearch to-do for Lucene 11 plans to put per-index compound-file settings on the index codec's CompoundFormat, and that server uses LogByteSizeMergePolicy for time-based data, so its force-merges would likely meet this rewrite (not verified).
While mapping which code answers each merge-policy hook, the hunt read the three calls of CompoundFormat.useCompoundFile. A class-file call-site scan confirmed that the two in IndexWriter ask the merged segment's codec, the writer's, while MergePolicy.isMerged asks the existing segment's. A public-API JUnit then reproduced the rewrite.
The method in full138 words
Method: semi-formal (code reading witnessed by a tool, then an executed test). A hunt unit built a census of merge-policy hooks: for each hook, which code answers it. Reading the compound-file decisions raised the hypothesis; the unit's class-file call-site scanner (written on the JDK class-file API) listed the three calls of CompoundFormat#useCompoundFile and the codec each one asks: the two IndexWriter sites (mergeMiddle, addIndexesReaderMerge) ask the merged segment's codec, and MergePolicy#isMerged asks the existing segment's SegmentInfo#getCodec.
A public-API JUnit then showed the rewrite after a reopen on stock main, with two controls (the Codec.forName instance with the same settings; an own instance with default settings) that pass, and a shadow isMerged that asks the writer's codec made it pass. Independent checkers reproduced it with their own tests; the minimal one-method test above came last.
No prior report: GitHub issues and PRs, all open PRs, commits, the JIRA archive, four mailing lists and downstream projects were searched on 2026-10-26 and re-checked on 2026-10-31. The closest item, #15616, fixed a related loss of compound settings through another CompoundFormat instance in test code.
Searches5 searches
Verdict new. #15616 (with #15615 and #15673, merged 2026-01-29) is the closest: a backward-codecs test codec returned a new CompoundFormat per call, so its settings were lost, and a committer warned in general terms about mutable setter state on codec components. Same design hazard, but different code, trigger and fix site, and nothing about segments read from disk, isMerged or a reopen.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | the scripted prior-report search (24 issue/PR and 3 commit queries) plus manual GraphQL searches: class and method names (isMerged, CompoundFormat, setShouldUseCompoundFile), symptom phrases, date-bounded compound/CFS/forceMerge queries | no report; related: #15616, #15615, #15673; the origin #15295 and design issue #14959 (no review comment on codec instance scope); #15691 (the MIGRATE.md recipe) |
| Open PRs (apache/lucene) | 2026-10-26 | all 406 open PRs listed with their files; those touching MergePolicy, LogMergePolicy, CompoundFormat, SegmentInfos, Lucene104Codec or Codec diffed | #16571 and #16847 touch MergePolicy but keep isMerged unchanged |
| Mailing lists and JIRA archive | 2026-10-26 | 20 queries over dev@, java-user@, issues@ and commits@, filtered to posts after 2026-01-23; 4 JIRA-archive queries | no report; issues@/commits@ hits mirror the GitHub items; old compound-file issues only |
| Downstream projects and the web | 2026-10-26 | Elasticsearch, Solr and luceneutil repositories (Lucene 11 branches read directly); 6 web queries | elastic/elasticsearch#163164 plans per-index compound settings on its own codec instance (no mention of isMerged); general forceMerge pages only |
| GitHub re-check | 2026-10-31 | issues and PRs mentioning "compound" created since 2026-10-25; issues mentioning isMerged | none new; an issue search for isMerged returns only #6544 (LUCENE-5481, 2014, a different cause, fixed); with PRs included it also returns the open PR #16571, which keeps isMerged unchanged (fact check, 2026-11-01) |
Introduced on main by #15295 (6643a5dbe1ed, merged 2026-01-23), which moved the compound-file settings onto CompoundFormat instances and made isMerged ask the segment's codec. It is also on branch_11x, created from main on 2026-10-29. No release has it; 10.6.0 and branch_10x keep the old check.
Versions tested8 rows
Introduced by 6643a5dbe1ed "Switching to a fixed CFS threshold (#15295)", by Shubham Sharma, merged by stefanvodita on 2026-01-23, closing design issue #14959 (CHANGES 11.0.0, API Changes; author, merger and issue link from the PR page, as the commit body is empty). Before it, isMerged ended with useCompoundFile(infos, info, mergeContext) == info.info.getUseCompoundFile(), the writer's merge-policy settings; after it, info.info.getCodec().compoundFormat().useCompoundFile(...).
The repro's API (CompoundFormat setters) did not exist before the commit, so older code ran a counterpart probe with the settings on the merge policy, plus a vacuity check that sees a rewrite when one is due. Not fixed upstream: main 2f424fd428da (2026-10-30) still has the line, and branch_11x 603af870375 (2026-10-29) has it too.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails, assertions on and off; passes with the fix |
main a9779ef3c193, ea57360912ed | affected | the finder's and verifiers' tests fail, assertions on and off |
branch_11x 603af870375 | read | created from main on 2026-10-29 (#16929); same isMerged line (MergePolicy.java:756) and the CompoundFormat setters |
6643a5dbe1ed (#15295) | bisect | the candidate test fails with the same message as on main |
parent d455fefc6b63 | bisect | counterpart probe passes; its vacuity check sees a due rewrite |
| 10.6.0 | read | old isMerged line, no CompoundFormat setters |
branch_10x and branch_10_6 snapshots | not affected | counterpart probe passes; branch_10x was emptied on 2026-10-29 (#16911), its last code commit 657014b3c57 keeps the old line |
| 10.5.2, 10.4.0, 10.3.2, 9.12.3 | not affected | counterpart probe passes |
Independent Claude reproducers and an adjudication confirmed it with their own tests; read-only reviews by OpenAI GPT-5.6 agreed on the root cause (one procedural "not real" because it could not run Java); a credibility audit re-ran it with new seeds; the fix was validated on 645d4fe14a20.
Checks and verdicts296 words
Every executing check ran on Linux aarch64 with OpenJDK 25.0.3, with assertions on and off where stated.
| Check | Verdict | What it found |
|---|---|---|
| Finder (JUnit, controls, root-cause shadow) | candidate | Fails on main and ea57360, assertions on and off, 20 of 20 iterations; controls (the Codec.forName instance; an own instance with default settings) pass; a shadow isMerged asking the writer's codec passes. |
| Refute review (OpenAI GPT-5.6, read-only) | not real, low (procedural) | Could not run Java, so its "not real" is procedural; agreed on the root cause, inputs in contract, intended case moderate. Its suggested control was added and passes; a separate re-run of the finder's repro fails. |
| The independent reproduction | real | Own 4-test JUnit fails 2 of 4; added the opposite direction (raised doc threshold); a reach probe narrowed the cost; counterparts pass on 10.5.2 and 9.12.3. |
| Intended-behaviour review (OpenAI GPT-5.6, read-only) | real, medium | Intended case moderate, rejected. The reviewer ran no Java; its variant with TestUtil.getDefaultCodec(false) and LogDocMergePolicy, run separately, fails over 3 sessions (_4, _5, _6); its TieredMergePolicy control passes. |
| Devil's advocate | real, medium-high | Intended case weak to moderate; re-ran the repro (fails) and the 10.5.2 counterpart (passes); found no upstream test asserting either behaviour. |
| Adjudication | confirmed, high; minor | Re-ran the independent reproduction's JUnit with a new seed (2 of 4 fail, both ways) and with the root-cause shadow (4 of 4 pass). |
| Credibility audit | keep | Re-ran the finder's and the independent reproduction's JUnits with new seeds: fail as before; impact already honest. |
| Minimal repro and fix validation | fails on 645d4fe14a20; fix passes | The one-method test fails with assertions on and off; the recommended fix passes it, the merge-policy suites, all core index tests and lint. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 487 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,236 words
- Registry title
- MergePolicy.isMerged checks a segment read from disk against the codec instance it was loaded with (the shared Codec.forName instance, with default compound-file settings) instead of the writer's codec, so forceMerge(1) with a LogMergePolicy rewrites an already merged segment after every writer reopen
- Area
- index / merge policy compound-file check (MergePolicy.isMerged vs CompoundFormat settings)
- Priority
- Low, rank 1014: Unreleased: forceMerge(1) under LogMergePolicy with a custom codec instance needlessly rewrites a merged segment once per session, performance only.
- Impact class
- minor
- Impact note
- Main and branch_11x only (unreleased, since #15295): applications that use a LogMergePolicy-family policy (LogByteSizeMergePolicy, LogDocMergePolicy; the default TieredMergePolicy is not affected for an original single segment), give the writer its own codec instance (for example new Lucene104Codec(Mode) or a per-field codec subclass, anything other than the instance Codec.forName returns) and configure compound-file settings on it as MIGRATE.md shows pay one needless rewrite of an already merged segment per writer session on forceMerge(1), but only for segments whose compound-file decision under those settings differs from the default one (with setShouldUseCompoundFile(false): segments up to 64 MB, or up to 65,536 docs with LogDocMergePolicy; larger segments only with raised thresholds, executed for an 80 MB segment under a 1 GB threshold); no wrong results, no corruption, no scale needed.
- Summary
- You give IndexWriter its own codec instance, for example new Lucene104Codec(Mode.BEST_COMPRESSION), turn compound files off on it as MIGRATE.md says (iwc.getCodec().compoundFormat().setShouldUseCompoundFile(false)), use a LogByteSizeMergePolicy and force-merge the index to one segment. You expect a later forceMerge(1) to leave that already merged segment alone, as it does in the same writer session and as 10.x does with the equivalent merge-policy settings. Instead, after the writer is closed and reopened, MergePolicy.isMerged asks the codec instance the segment was read with (the shared Codec.forName instance, whose settings are the defaults), decides the non-compound segment should have been compound, and forceMerge(1) rewrites it (_3 becomes _4); the merge itself uses the writer's codec and writes a non-compound segment again, so the same rewrite happens in every later writer session.
- Introduced
- 6643a5dbe1ed (6643a5dbe1ed6d3a4b933c90beed60cfe44b5992, GITHUB#15295 'Switching to a fixed CFS threshold' by shubhamsrkdev, merged to main by stefanvodita 2026-01-23, closes #14959): it moved the compound-file settings from the merge policy into per-instance CompoundFormat fields and changed the last check of MergePolicy.isMerged from the writer's merge-policy settings (useCompoundFile(infos, info, mergeContext) of this policy) to info.info.getCodec().compoundFormat(), while the merge itself asks the merged segment's codec, which IndexWriter builds with config.getCodec() [read: git blame of MergePolicy.java:756-757, git show 6643a5dbe1ed] [exec: the parent d455fefc6b63 passes the pre-change counterpart probe with -ea and -da, and 6643a5dbe1ed fails the candidate JUnit with -ea and -da] (2026-01-23)
- First affected version
- unreleased (main and branch_11x, 11.0.0-SNAPSHOT since 6643a5dbe1ed; branch_11x 603af870375, created from main on 2026-10-29 by #16929, contains it [read]; it would first ship in 11.0.0 unless fixed; #15295 is not in branch_10x or branch_10_6 and no release tag contains it)
- Affected versions
- main 11.0.0-SNAPSHOT at 6643a5dbe1ed (introducing), ea57360912ed and a9779ef3c193 [exec: the candidate JUnit fails (3 tests run, 1 failed) with -ea and -da]; the commits in between [read: none touches isMerged or CompoundFormat]; upstream main a95c754ee003 (2026-10-26) [read: the two newer commits do not touch merge policies or compound files]; branch_11x 603af870375 (created from main on 2026-10-29, #16929) [read: contains 6643a5dbe1ed, same isMerged line at MergePolicy.java:756]. Not affected [exec, counterpart probe with the same scenario and the settings on the merge policy, the API of those versions, including a vacuity check that sees a rewrite when one is due; the candidate JUnit does not compile there because the CompoundFormat setters do not exist]: the parent d455fefc6b63, branch_10x 10.7.0-SNAPSHOT, branch_10_6 10.6.0-SNAPSHOT, 10.5.2, 10.4.0, 10.3.2 and 9.12.3. Not executed: x86.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, read-only; verdict new): a scripted prior-report search with 59 queries (24 GitHub issue and PR, 3 commit, 2 downstream, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA-archive, 6 web), manual GitHub GraphQL searches on apache/lucene and on Elasticsearch, OpenSearch, Solr and luceneutil, all 406 open apache/lucene PRs listed with their files and those touching MergePolicy, LogMergePolicy, CompoundFormat, SegmentInfos, Lucene104Codec or Codec diffed, lists.apache.org filtered to posts after 2026-01-23, and the git history of the touched files. Related, not this bug: #15616 and #15615 (merged 2026-01-29: a backward-codecs test codec returned a new CompoundFormat per call, so its settings were lost; in that PR a committer, mikemccand, warned in general terms against mutable setter state on codec writer components; nothing about segments read from disk, read-side codec instances or isMerged), the origin #15295 and design issue #14959 (no review comment discusses codec instance scope), #15691 (the MIGRATE.md recipe, no scope caveat), elastic/elasticsearch#163164 (open downstream to-do that plans per-index compound-file settings on its own codec instance, with LogByteSizeMergePolicy for time-based data; it does not mention isMerged or rewrites), and as precedents #6544 (LUCENE-5481, the same symptom from a different cause, fixed 2014) and #176 (LUCENE-9905, configured format parameters ignored in favour of the SPI default, fixed 2021). Not fixed upstream; open PRs #16571 and #16847 keep isMerged unchanged. Gaps: keyword search only; inline review comments were read directly only for the items listed above; private security reports are not visible.
- Lucene commit tested
- main
645d4fe14a20(minimal repro, fix validation),a9779ef3c193andea57360912ed(verification), the introducing commit6643a5dbe1edand its parentd455fefc6b63; counterpart probes with the settings on the merge policy on thebranch_10xandbranch_10_6snapshots, 10.5.2, 10.4.0, 10.3.2 and 9.12.3; 10.6.0 by reading.
- Finding record
lucene/core/src/java/org/apache/lucene/index/MergePolicy.java :746-749 (isMerged javadoc 'matches the current compound file setting'), :750-758 (info.info.getCodec().compoundFormat().useCompoundFile(size(info, mergeContext), this) == info.info.getUseCompoundFile())lucene/core/src/java/org/apache/lucene/index/SegmentInfos.java :561-564 (readCodec: Codec.forName(name)); codecs/Codec.java :118-119 (forName: Holder.getLoader().lookup(name)); codecs/CompoundFormat.java :47-58 (per-instance settings, shouldUseCompoundFile = true), :163-180 (useCompoundFile); codecs/lucene104/Lucene104Codec.java :75, :157-159 (one CompoundFormat per codec instance)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java :5334 (merged SegmentInfo built with config.getCodec()), :5683-5691 (merge-side compound decision through the merged segment's codec); index/LogMergePolicy.java :181-203, :378-384 ('There is only one segment already, and it is merged'); index/TieredMergePolicy.java :836-843 (an original single segment is 'already merged' before isMerged is asked)lucene/MIGRATE.md :290-327 ('APIs for configuring compound file creation thresholds have been updated and moved'; recipe 'CompoundFormat cfs = iwc.getCodec().compoundFormat(); cfs.setShouldUseCompoundFile(false);')
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/MergePolicy.java:746-758lucene/core/src/java/org/apache/lucene/codecs/CompoundFormat.java:48-57, 163-180; codecs/lucene104/Lucene104Codec.java:75, 157-159lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:5329-5340, 5683-5691, 3608-3617; index/SegmentInfos.java:407, 423, 561-564; codecs/Codec.java:59, 118-119; util/NamedSPILoader.java:102-104; codecs/Codec.java:141-153; index/IndexWriter.java:1049-1053, 1083-1103, 3130, 3525, 3536; index/DocumentsWriterPerThread.java:643-653lucene/core/src/java/org/apache/lucene/index/LogMergePolicy.java:181-203, 241, 257, 289, 352, 379; index/TieredMergePolicy.java:775-777, 836-843lucene/MIGRATE.md:290-327
- Who is affected
lucene/core/src/java/org/apache/lucene/index/TieredMergePolicy.java:836-843lucene/core/src/java/org/apache/lucene/index/TieredMergePolicy.java:775-777; index/IndexWriter.java:2161-2201 (forceMerge free-space note); codecs/Codec.java:141-153
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/MergePolicy.java:746-749; index/LiveIndexWriterConfig.java:373-381; codecs/lucene104/Lucene104Codec.java:112-116lucene/MIGRATE.md:290-327lucene/test-framework/src/java/org/apache/lucene/tests/util/TestUtil.java:1338-1342; LuceneTestCaseParent.java:1697lucene/core/src/test/org/apache/lucene/index/TestDeletionPolicy.java:333-359 (per-codec compound settings and a reopen, multi-segment only)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:2473-2484 (findForcedMerges gets a CachingMergeContext)
- History
a Lucene clone: releases/lucene/10.6.0 (MergePolicy.java:797, no CompoundFormat setters); origin/main 2f424fd428da (MergePolicy.java:756-757 unchanged)
- TestForceMergeKeepsMergedSegmentAfterReopen.java (one test method, public API):
repro/LFV-572/src/org/apache/lucene/index/TestForceMergeKeepsMergedSegmentAfterReopen.java(57 lines)
Made in parallel with this doc, from the code at 645d4fe14a20 and an executed trace of the repro scenario.
assets/LFV-572/bug.png(487 KB)