Since #16734, addBatch gives a DENSE vector column to the vectors writer in one addDenseValues call. The HNSW and scalar-quantized writers forward it to the flat writer they wrap and count the new vectors only if the call returns, assuming the flat writer keeps all of the batch or none. The default addDenseValues keeps a prefix.
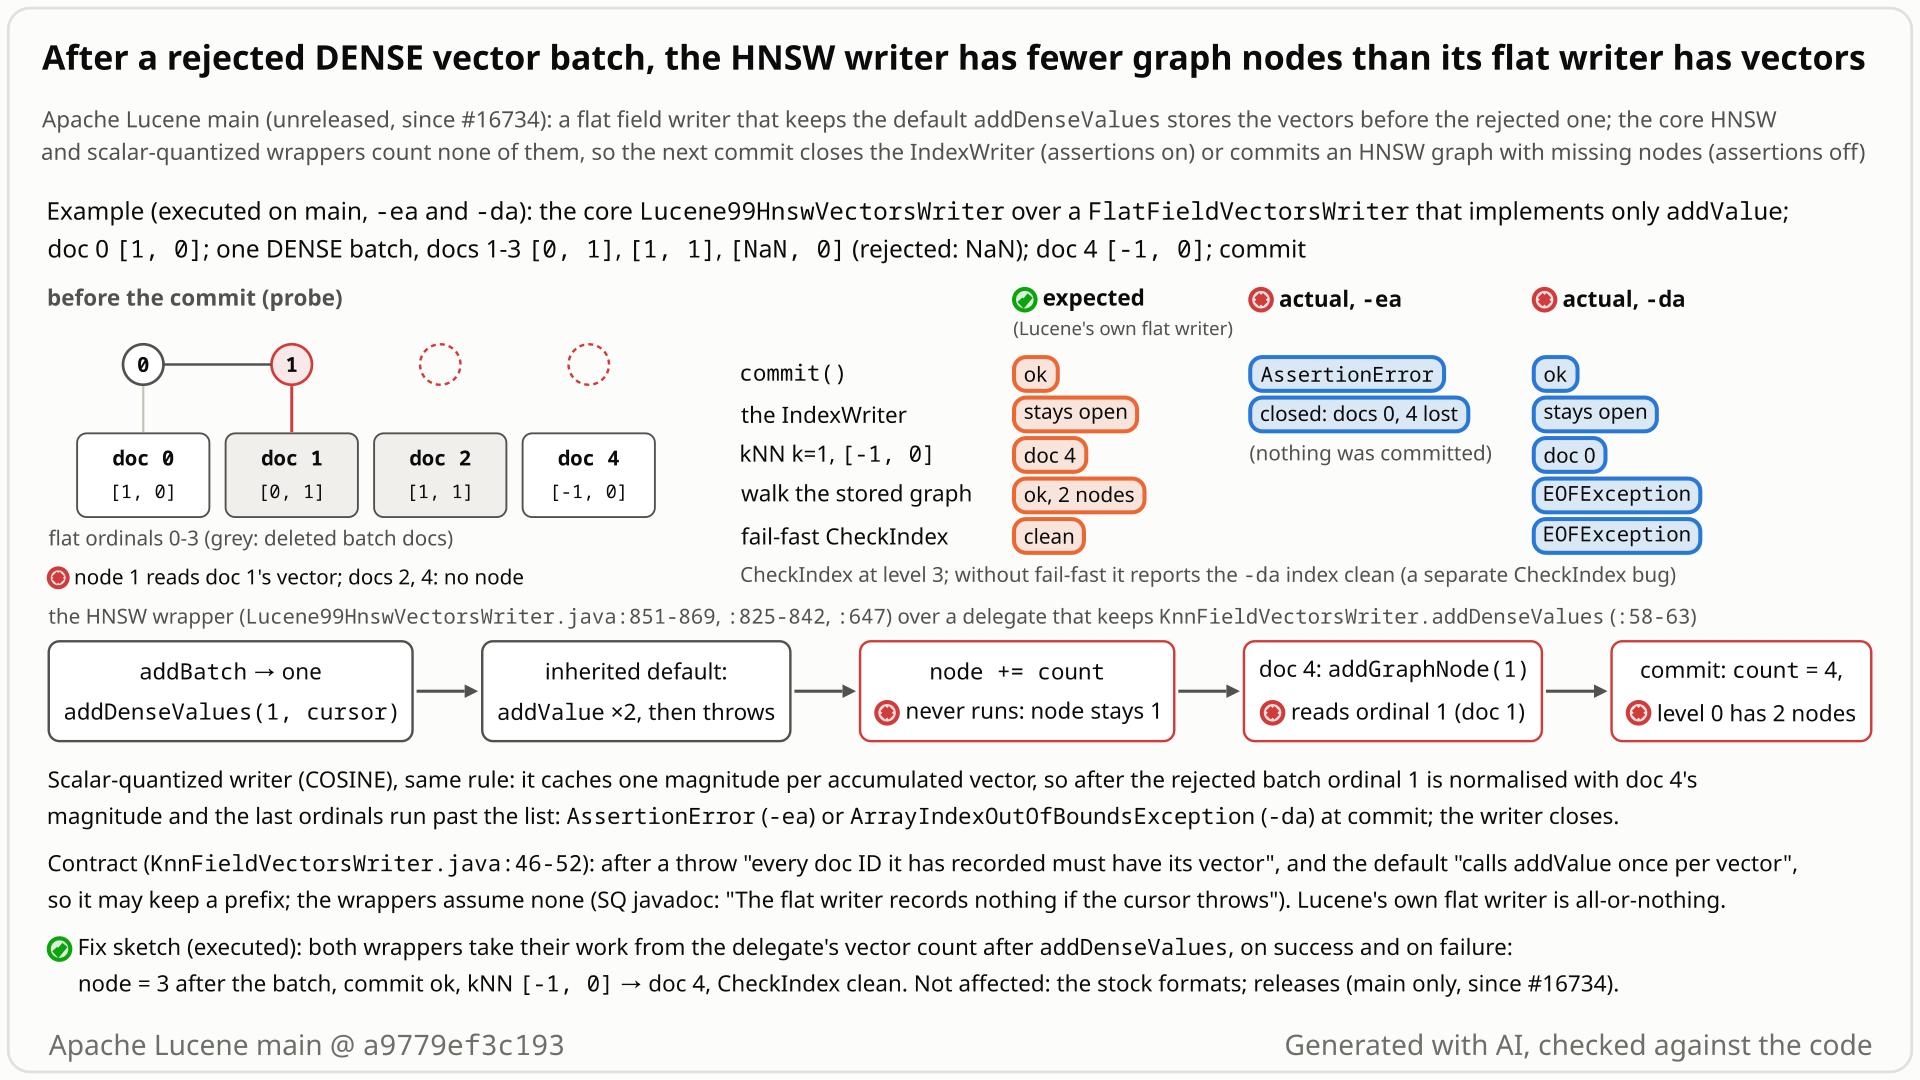
- Plug your own per-field vector storage into the stock HNSW writer through the public
Lucene99FlatVectorsWriter(state, scorer, strategyFactory)constructor, as upstream'sTestKnnVectorsFormatCustomWriterdoes; like that test's writer, it does not overrideaddDenseValues. Index doc 0 =[1, 0]. - Call
addBatchwith a DENSE column of 3 vectors:[0, 1],[1, 1],[NaN, 0]. Lucene rejects the third; docs 1-3 are deleted and the writer stays open. But the defaultaddDenseValueshas already stored the first two: the flat writer holds 3 vectors, while the HNSW writer still counts 1. - Add doc 4 =
[-1, 0]and commit. You expect a clean commit with 2 searchable documents, as with the same rows in a SPARSE column or with the stock format. - Instead the HNSW writer, still counting 1, adds graph node 1, which is vector 1: deleted doc 1's
[0, 1]. Doc 4's vector, stored as vector 3, never enters the graph. The commit throwsAssertionError: Level 0 expects to have all nodesand the writer closes, losing every uncommitted document. - With assertions off the commit succeeds and writes a graph with 2 nodes for 4 vectors: a kNN query for doc 4's own vector returns doc 0, and CheckIndex at level 3 (fail-fast) throws
EOFException. With the default threshold, 1,000 documents, a rejected 4-vector batch and 10 more, all 1,010 kNN queries throwEOFException.
Main only, unreleased (it would ship in 11.0.0), and only with a non-default vectors format: your own per-field storage or flat writer under the core HNSW or scalar-quantized writer, as in upstream's own test. It also needs the experimental addBatch with DENSE vector columns and a batch whose second or later vector is rejected. Stock formats are not affected.
Mechanism, terms and numbers955 words
Since #16734, IndexWriter#addBatch hands a DENSE vector column to the field's vectors writer in one addDenseValues call, through a cursor that validates each vector as it is consumed. The core HNSW and scalar-quantized writers forward that call to the flat field writer they wrap and update their own state only if it returns normally, assuming the flat writer stores all of the batch or none of it. Lucene's own flat writer does; the default addDenseValues, which every other flat field writer inherits, stores one vector at a time. So when Lucene rejects vector k >= 1 of a batch (NaN or infinite, a zero vector with COSINE, a wrong length, or a cursor that throws), such a flat writer keeps vectors 0..k-1 while the wrapper counts none, and stays k vectors behind. With assertions on, the next commit fails and closes the IndexWriter; with them off, the HNSW writer commits a graph with fewer nodes than vectors, on which kNN search returns wrong documents or throws and fail-fast CheckIndex fails, and the COSINE scalar-quantized writer fails at commit or commits a segment in which kNN finds nothing. It needs a non-default vectors format, such as upstream's own TestKnnVectorsFormatCustomWriter composition, and the experimental addBatch; the stock formats are not affected. Main only, unreleased.
- DENSE vector column.
IndexWriter#addBatch(experimental) indexes a batch column by column. Since #16734 a column declared DENSE (one vector per document) goes to the field's vectors writer in a singleaddDenseValues(firstDocID, cursor)call (IndexingChain.java:1318-1369). The cursor checks each vector as it hands it out (ValidatingVectorValuesCursor.java:141-147); a bad one throws, the batch's documents are deleted, and the writer stays open. - Flat field writer. Buffers the raw vectors of one field until flush. The HNSW writer and the scalar-quantized (SQ) writer wrap one: the HNSW writer adds a graph node per vector, the SQ writer adds each vector to the centroid sums and, for COSINE, caches its length (magnitude).
- The default
addDenseValues(KnnFieldVectorsWriter.java:58-63) callsaddValueonce per vector. Lucene's own flat writer overrides it all-or-nothing (Lucene99FlatVectorsWriter.java:507-531); any other flat field writer, for example one plugged in through the publicstrategyFactoryconstructor (:87-105, since 10.5.0), inherits the default.
- The HNSW writer forwards the batch first,
flatFieldVectorsWriter.addDenseValues(firstDocID, values)(Lucene99HnswVectorsWriter.java:857), and only after it returns advances its node counter and adds graph nodes (:858-868). The SQ writer accumulates the new vectors only after the delegate returns (Lucene104ScalarQuantizedVectorsWriter.java:750-757); its javadoc says "The flat writer records nothing if the cursor throws, so neither does this writer" (:745-748). - With the default, a batch rejected at vector k leaves vectors 0..k-1 in the flat writer, which the contract allows: "every doc ID it has recorded must have its vector" (
KnnFieldVectorsWriter.java:46-48). The wrapper counted none of them: it is now k vectors behind. - HNSW. The next
addValuestores the vector in the flat writer and callsaddGraphNode(node)with the wrapper's counter (:839). The graph scores ordinals against the flat writer's vectors (:797-801), so it inserts the vector of a deleted batch document, and the new vector, k ordinals further, gets no node. The graph ends with fewer nodes than vectors. - Flush, assertions on.
writeMetaassertsnodesOnLevel.size() == count : "Level 0 expects to have all nodes"(:647, count from the flat writer,:272). The exception is tragic: the writer closes and drops everything not committed. - Flush, assertions off. The short graph is written. The reader sizes level 0 by the vector count (
Lucene99HnswVectorsReader.java:589-591) and seeks without bounds checks (:603-604), so reading a missing node, or an upper-level node whose offsets the missing ones shift, throwsEOFException; a query that meets only existing nodes returns a wrong document. - SQ, COSINE. The prefix has no cached magnitude, so at flush
scaleToUnitLengthdivides each later ordinal by another vector's magnitude (:828-833) and the last ordinals read past the list: anAssertionErrorin the quantizer (assertions on); with assertions offFloatArrayList.getchecks the index only by assertion (FloatArrayList.java:130-135), so it throwsArrayIndexOutOfBoundsExceptionpast its backing array or returns a never-written 0 (a division by zero, by reading), after which kNN finds no document of the segment. For EUCLIDEAN and DOT_PRODUCT only the centroid is biased (by reading; not tested).
Before #16734 every vector of a column went through the wrapper's own addValue, so wrapper and flat writer moved together; the same scenario passes on the parent commit (NaN / zero and wrong-length triggers) and, with a wrong-length rejected vector, on 10.5.0 and 10.5.2 (10.5.x does not reject NaN or zero vectors).
| case | assertions on | assertions off |
|---|---|---|
| HNSW, threshold 0: doc 0, rejected 3-doc batch (NaN), doc 4 | commit throws Level 0 expects to have all nodes; writer closed | commit ok (a graph with 2 nodes for 4 vectors); kNN for doc 4's vector returns doc 0; CheckIndex level 3 fail-fast: EOFException; without fail-fast: clean |
| HNSW, default threshold: 1,000 docs, rejected 4-doc batch (+Infinity), 10 docs | same assertion; writer closed | commit ok; 1,010 of 1,010 kNN queries throw EOFException; CheckIndex level 3 fails with and without fail-fast |
SQ, COSINE: doc [2, 0], rejected batch (zero vector), 2 docs | AssertionError in OptimizedScalarQuantizer.scalarQuantize:189; writer closed | ArrayIndexOutOfBoundsException: Index 4 out of bounds for length 4; writer closed |
SQ, COSINE: doc [1, 0], rejected batch (zero vector), doc [-1, 0.5] | AssertionError; writer closed | commit ok; kNN for either live document's vector returns no hit; CheckIndex level 3 clean |
| the same rows as a SPARSE column, or the stock formats | clean | clean |
Exposure and likelihood519 words
- Who is hit. Applications on main that (1) use a vectors format in which the core HNSW writer or the core scalar-quantized writer wraps a flat field writer that does not override
addDenseValues: their own per-field storage through the publicLucene99FlatVectorsWriter(state, scorer, strategyFactory)constructor (#16053, released in 10.5.0; upstream'sTestKnnVectorsFormatCustomWriterbuilds exactly this,:84-96), or their ownFlatVectorsWriterunder the public writer constructors; every field writer written for 10.5 inherits the default without any change; (2) index vectors through the experimentaladdBatch(orupdateDocuments(Term|Query, ColumnBatch)) with a DENSEVectorColumn; (3) send a batch in which a vector after the first is rejected (NaN or infinite, a zero vector with COSINE, a wrong length) or whose cursor throws. A NaN embedding or a zero vector is an ordinary data accident. - Not affected. The stock core formats: their flat writer is all-or-nothing (controls pass; the hunt's bounded sweep found 0 mismatches for the stock HNSW stack in 5,562 scenarios per mode; its few stock HNSW + SQ and stock SQ mismatches are all the separate LFV-047). The shipped sandbox Dedup formats have the composition and reproduce it (outside the hunt's scope).
- Scale. None beyond a segment that ends up with an HNSW graph: with the default tiny-segment threshold, more than
100 * ln(n)vectors, about 650 (Lucene99HnswVectorsWriter.java:716-722); a probe with upstream's composition failed after 1,000 documents, and after 3 documents followed by enough to build the graph later, and passed a 600-document segment that never builds a graph. WithtinySegmentsThreshold <= 0any size fails. The COSINE SQ case has no size threshold. - Assertions on (tests, many development setups): the next flush or commit throws, the IndexWriter closes with a tragic exception, and every document added since the last commit is lost.
- Assertions off (production): HNSW commits a graph that lacks the field's last vectors; kNN returns wrong documents or throws
EOFException(all 1,010 queries in the 1,000-document probe). COSINE SQ throws at commit and closes the writer, or commits a segment in which kNN finds no document. The damage stays until the segment is replaced (for example by reindexing); whether a later merge repairs or spreads it was not tested. - Hard to see. CheckIndex checks vectors only at level 2 or higher (
CheckIndex.java:1114-1144), which is not its default (level 0 in code unlesssetLevelis called, level 1 on the command line). At level 3 without fail-fast it reports the HNSW graph error of the small threshold-0 case but calls the index clean (LFV-561); in the 1,000-document case its vector search also fails and it reports the index broken. The COSINE SQ segment with no kNN hits passed CheckIndex at level 3 either way. - Why the suites miss it.
BaseKnnVectorsFormatTestCasenever callsaddBatch, soTestKnnVectorsFormatCustomWriternever reachesaddDenseValues; theaddBatchtests use the stock formats only. - Downstream. A codec that builds the core HNSW writer over its own flat field writer, written before
addDenseValuesexisted, inherits the default; one such downstream format was found by read-only code reading. No downstream product is known to send DENSE vector columns throughaddBatchtoday.
after IndexWriter#addBatch rejects the third vector of a DENSE vector batch, the stock HNSW writer is out of step with a flat field writer that keeps the default addDenseValues, so the next commit fails or writes a broken graph.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene99;

import java.io.IOException;
import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.codecs.KnnVectorsFormat;
import org.apache.lucene.codecs.KnnVectorsReader;
import org.apache.lucene.codecs.KnnVectorsWriter;
import org.apache.lucene.codecs.hnsw.FlatFieldVectorsWriter;
import org.apache.lucene.codecs.hnsw.FlatVectorScorerUtil;
import org.apache.lucene.codecs.hnsw.FlatVectorsScorer;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.KnnFloatVectorField;
import org.apache.lucene.document.column.Column;
import org.apache.lucene.document.column.ColumnBatch;
import org.apache.lucene.document.column.ObjectTupleCursor;
import org.apache.lucene.document.column.VectorColumn;
import org.apache.lucene.document.column.VectorValuesCursor;
import org.apache.lucene.index.CheckIndex;
import org.apache.lucene.index.DocsWithFieldSet;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.NoMergePolicy;
import org.apache.lucene.index.SegmentReadState;
import org.apache.lucene.index.SegmentWriteState;
import org.apache.lucene.index.VectorSimilarityFunction;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestDenseBatchHnswOverDefaultDelegate extends LuceneTestCase {

  /** Per-field vector storage that keeps the default addDenseValues (one addValue per vector). */
  private static final class ListFieldVectorsWriter extends FlatFieldVectorsWriter<float[]> {
    private final List<float[]> vectors = new ArrayList<>();
    private final DocsWithFieldSet docs = new DocsWithFieldSet();
    private boolean finished;

    @Override
    public void addValue(int docID, float[] vector) {
      vectors.add(vector.clone());
      docs.add(docID);
    }

    @Override
    public float[] copyValue(float[] vector) {
      return vector.clone();
    }

    @Override
    public List<float[]> getVectors() {
      return vectors;
    }

    @Override
    public DocsWithFieldSet getDocsWithFieldSet() {
      return docs;
    }

    @Override
    public void finish() {
      finished = true;
    }

    @Override
    public boolean isFinished() {
      return finished;
    }

    @Override
    public long ramBytesUsed() {
      return 0;
    }
  }

  /** The stock HNSW writer over that storage, building the graph from the first vector. */
  private static final class ListHnswFormat extends KnnVectorsFormat {
    ListHnswFormat() {
      super("Lucene99HnswVectorsFormat");
    }

    @Override
    public KnnVectorsWriter fieldsWriter(SegmentWriteState state) throws IOException {
      FlatVectorsScorer scorer = FlatVectorScorerUtil.getLucene99FlatVectorsScorer();
      return new Lucene99HnswVectorsWriter(
          state,
          16,
          100,
          new Lucene99FlatVectorsFormat(scorer),
          new Lucene99FlatVectorsWriter(state, scorer, fi -> new ListFieldVectorsWriter()),
          1,
          null,
          0);
    }

    @Override
    public KnnVectorsReader fieldsReader(SegmentReadState state) throws IOException {
      return new Lucene99HnswVectorsFormat().fieldsReader(state);
    }

    @Override
    public int getMaxDimensions(String fieldName) {
      return 1024;
    }
  }

  public void testCommitAfterRejectedDenseBatch() throws Exception {
    FieldType type = KnnFloatVectorField.createFieldType(2, VectorSimilarityFunction.EUCLIDEAN);
    float[][] rows = {{0, 1}, {1, 1}, {Float.NaN, 0}};
    VectorColumn<float[]> column =
        new VectorColumn<>("v", type, Column.Density.DENSE) {
          @Override
          public ObjectTupleCursor<float[]> tuples() {
            throw new UnsupportedOperationException();
          }

          @Override
          public VectorValuesCursor<float[]> values() {
            return new VectorValuesCursor<>(rows.length, 2) {
              int i;

              @Override
              public float[] next() {
                return rows[i++];
              }
            };
          }
        };
    ColumnBatch batch =
        new ColumnBatch() {
          @Override
          public int numDocs() {
            return rows.length;
          }

          @Override
          public Iterable<Column> columns() {
            return List.of(column);
          }
        };
    IndexWriterConfig iwc =
        new IndexWriterConfig()
            .setCodec(TestUtil.alwaysKnnVectorsFormat(new ListHnswFormat()))
            .setMergePolicy(NoMergePolicy.INSTANCE);
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        w.addDocument(List.of(new KnnFloatVectorField("v", new float[] {1, 0}, type)));
        expectThrows(IllegalArgumentException.class, () -> w.addBatch(batch));
        w.addDocument(List.of(new KnnFloatVectorField("v", new float[] {-1, 0}, type)));
        // expected no error; actual: "Level 0 expects to have all nodes" (-ea), EOF in CheckIndex (-da)
        w.commit();
      }
      TestUtil.checkIndex(dir, CheckIndex.Level.MIN_LEVEL_FOR_SLOW_CHECKS, true, false, null);
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-579/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.codecs.lucene99.TestDenseBatchHnswOverDefaultDelegate
- Expected vs actual
- Expected: commit succeeds and CheckIndex is clean; actual:
AssertionError: Level 0 expects to have all nodesat commit (-ea),EOFExceptionreading the HNSW graph in CheckIndex (-da).
More files, environment, full output43 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: Level 0 expects to have all nodes
       org.apache.lucene.codecs.lucene99.Lucene99HnswVectorsWriter.writeMeta(Lucene99HnswVectorsWriter.java:647)
       org.apache.lucene.codecs.lucene99.Lucene99HnswVectorsWriter.writeField(Lucene99HnswVectorsWriter.java:268)
       org.apache.lucene.codecs.lucene99.Lucene99HnswVectorsWriter.flush(Lucene99HnswVectorsWriter.java:224)
       org.apache.lucene.codecs.perfield.PerFieldKnnVectorsFormat$FieldsWriter.flush(PerFieldKnnVectorsFormat.java:126)
       org.apache.lucene.index.VectorValuesConsumer.flush(VectorValuesConsumer.java:76)
       org.apache.lucene.index.IndexingChain.flush(IndexingChain.java:336)
       org.apache.lucene.index.DocumentsWriterPerThread.flush(DocumentsWriterPerThread.java:492)
       org.apache.lucene.index.DocumentsWriter.doFlush(DocumentsWriter.java:541)
       org.apache.lucene.index.DocumentsWriter.maybeFlush(DocumentsWriter.java:496)
[...]- The
addDenseValuescontract allows a partial batch: "every doc ID it has recorded must have its vector"; its default records one vector at a time. - Upstream's
testDenseVectorValidationFailureRecoversmakes a rejected DENSE vector batch non-fatal and checks that "the vectors writer was left consistent". - Upstream's
TestKnnVectorsFormatCustomWriterbuilds this composition: a field writer withoutaddDenseValuesunder the stock HNSW writer.
The full argument338 words
- The contract allows a partial batch. "The cursor may throw while it is being consumed ... In that case the documents of the whole batch are marked as deleted, but the writer must remain in a consistent state: every doc ID it has recorded must have its vector" (
KnnFieldVectorsWriter.java:46-48). The default records a prefix by construction (:58-63), and overriding is an optimisation: "Override for a more efficient bulk path" (:52-53). No javadoc,CHANGES.txtorMIGRATE.mdentry says a wrapped delegate must be all-or-nothing. - The duty binds the wrappers too. Both wrappers override
addDenseValues, so they must stay consistent; their own flush code needs one graph node per vector (:647) and one cached magnitude per ordinal (:828-829). - Recovery is tested upstream.
TestColumnBatchIndexing.testDenseVectorValidationFailureRecovers(:886-922) rejects a DENSE batch with NaN at position 2 and continues in the same segment: "the failed batch stays in the same segment as the recovery batch, so flush checks that the vectors writer was left consistent". It uses the stock format. #16708 added these rejections; they do not abort the writer. - The composition is a released extension point. 10.5.0 CHANGES (GITHUB#16053): a field-writer creation strategy "to allow different formats to change how vectors are stored in memory"; its test exists to "ensure that the use of a different, custom strategy does not break any existing invariants". That test's writer keeps the default
addDenseValuesunder the stock HNSW writer. - The review asked for this to be safe. In #16734 jimczi asked that "The HNSW and scalar quantized field writers would also need to forward to their flat delegate" and that "the writer should only record doc IDs after
fillreturns"; mayya-sharipova added both. Nobody discussed a delegate that keeps the default; there is no by-design statement. - The other paths are consistent. The same rows as a SPARSE column, and the pre-#16734 form on the parent commit (both triggers) and on 10.5.0 and 10.5.2 (a wrong-length trigger; 10.5.x accepts NaN and zero vectors), pass.
The devil's-advocate check232 words
The strongest case for "intended" (an intended-behaviour checker and a cross-model refute review): the SQ writer's javadoc states the all-or-nothing assumption on purpose; the base javadoc tells wrappers to forward, which reads as expecting every delegate to override; every API involved is @lucene.experimental; a batch that fails part-way is caller error; and a committer could declare that delegates must be all-or-nothing.
Why it fails: the SQ sentence sits on a package-private nested class and records an assumption that holds for one delegate only, against the base-class default that every other flat field writer inherits, while the public constructors accept any flat writer. The "should forward" sentence is about reaching the delegate's fast path; the same javadoc calls overriding optional. "Experimental" allows the API to change, not a core writer to close the IndexWriter or commit a malformed graph, and upstream's own test builds the composition. The rejection is Lucene's own non-aborting validation, and a caller cursor that throws does the same. If upstream decides delegates must be all-or-nothing, the default and the "every doc ID it has recorded" wording would need to change, or a stronger precondition be documented for delegates wrapped by these writers: either way the wrappers and the default disagree today. The refute reviewer agreed with the root cause and rated the intended case weak; its "not real" was procedural (it could not run code). Verdict: not intended.
Recommended Let the wrappers index exactly what the flat writer holds (validated)
Let both wrappers count what the flat writer actually holds after addDenseValues, on success and on failure: the HNSW writer adds graph nodes for [firstNode, flat size), then rethrows; the SQ writer accumulates [firstOrd, flat size) in a finally. The test then passes 4 of 4 with assertions on and off, and all 8,893 tests of :lucene:core:test pass.
All options and trade-offs4 options · 1,019 words
One fix was built and validated (option A, from the hunt); the others are alternatives upstream may prefer, not tested.
In Lucene99HnswVectorsWriter.FieldWriter.addDenseValues, catch the delegate's exception, add graph nodes (or create the graph) for [firstNode, flat writer size), then rethrow, keeping the cursor's exception primary and suppressing any failure of the catch-up into it. In Lucene104ScalarQuantizedVectorsWriter.FieldWriter.addDenseValues, accumulate [firstOrd, vectors.size()) in a finally. +37/-13 lines in two files; the stock flat writer's bulk path is unchanged.
diff --git a/lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104ScalarQuantizedVectorsWriter.java b/lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104ScalarQuantizedVectorsWriter.java
index 322585e7fc4..62b93c4a77a 100644
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104ScalarQuantizedVectorsWriter.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104ScalarQuantizedVectorsWriter.java
@@ -749,10 +749,14 @@ public class Lucene104ScalarQuantizedVectorsWriter extends FlatVectorsWriter {
     @Override
     public void addDenseValues(int firstDocID, VectorValuesCursor<T> values) throws IOException {
       final int firstOrd = getVectors().size();
-      flatFieldVectorsWriter.addDenseValues(firstDocID, values);
-      final List<T> vectors = getVectors();
-      for (int ord = firstOrd; ord < vectors.size(); ord++) {
-        accumulate(vectors.get(ord));
+      try {
+        flatFieldVectorsWriter.addDenseValues(firstDocID, values);
+      } finally {
+        // the delegate may have recorded a prefix of the batch before the cursor threw
+        final List<T> vectors = getVectors();
+        for (int ord = firstOrd; ord < vectors.size(); ord++) {
+          accumulate(vectors.get(ord));
+        }
       }
     }

diff --git a/lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99HnswVectorsWriter.java b/lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99HnswVectorsWriter.java
index 3287674b25a..898c5dabbc3 100644
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99HnswVectorsWriter.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99HnswVectorsWriter.java
@@ -854,17 +854,37 @@ public final class Lucene99HnswVectorsWriter extends KnnVectorsWriter {
       if (count == 0) {
         return;
       }
-      flatFieldVectorsWriter.addDenseValues(firstDocID, values);
       final int firstNode = node;
-      node += count;
-      lastDocID = firstDocID + count - 1;
-      if (hnswGraphBuilder != null) {
-        for (int ord = firstNode; ord < node; ord++) {
-          hnswGraphBuilder.addGraphNode(ord);
+      Throwable failure = null;
+      try {
+        flatFieldVectorsWriter.addDenseValues(firstDocID, values);
+      } catch (Throwable t) {
+        failure = t;
+      }
+      // The delegate may have recorded a prefix of the batch before the cursor threw (the default
+      // addDenseValues adds one vector at a time): index exactly the vectors it holds.
+      final int added = flatFieldVectorsWriter.getVectors().size() - firstNode;
+      if (added > 0) {
+        node += added;
+        lastDocID = firstDocID + added - 1;
+        try {
+          if (hnswGraphBuilder != null) {
+            for (int ord = firstNode; ord < node; ord++) {
+              hnswGraphBuilder.addGraphNode(ord);
+            }
+          } else if (shouldCreateGraph(graphThreshold, node)) {
+            initializeGraphBuilder();
+            replayBufferedVectors();
+          }
+        } catch (Throwable t) {
+          if (failure == null) {
+            throw t;
+          }
+          failure.addSuppressed(t); // keep the cursor's exception as the primary one
         }
-      } else if (shouldCreateGraph(graphThreshold, node)) {
-        initializeGraphBuilder();
-        replayBufferedVectors();
+      }
+      if (failure != null) {
+        throw IOUtils.rethrowAlways(failure);
       }
     }
Trade-offs
- For: fixes every delegate that keeps a consecutive prefix of the batch (the default does), including flat field writers written for 10.5 and downstream ones, with no change to them, provided the catch-up itself succeeds; the rejected batch's recorded vectors stay in the segment as deleted documents, exactly as on the SPARSE path.
- Against: the wrappers rely on
getVectors().size()being the flat writer's vector count (true for everyFlatFieldVectorsWriter; it is also whatreplayBufferedVectorsuses); catchingThrowablemeans the catch-up also runs after anError, then rethrows it; in the SQ part an exception fromaccumulatein thefinallywould replace the cursor's exception (unlikely: only accepted vectors are accumulated);lastDocID = firstDocID + added - 1assumes the recorded vectors belong to the batch's firstaddeddocuments, which the public contract does not state. - Not done: a regression test for BYTE and FLOAT16 fields (the hunt's sweep shows HNSW mismatches there too; the JUnit uses float32), benchmarks (by reading, the success path gains no per-vector work: a try block and one size query per batch), x86.
What the checks validated
Through gradle in a scratch worktree of a9779ef3c193, JDK 25.0.3, ./gradlew --no-daemon, seed DEADBEEF unless stated:
| run | stock | with the fix |
|---|---|---|
| the paste-ready JUnit, assertions on / off | 4 tests, 3 failures (each) | 4 tests, 0 failures (each) |
| the same at seeds A0D17004, 5EEDD1A6, 7A11E5ED | - | 4 tests, 0 failures (each) |
18 closest classes (codecs.lucene99.* incl. upstream TestKnnVectorsFormatCustomWriter, the three Lucene104 SQ suites, document.column.*, TestColumnBatchIndexing incl. testDenseVectorValidationFailureRecovers, TestKnnGraph), assertions on / off | - | 527 tests, 0 failures, 13 skipped (each) |
| sandbox Dedup format suites | - | 139 tests, 0 failures, 6 skipped |
:lucene:core codecs.*, index.*Knn*, index.*Vector*, search.*Knn*, util.hnsw.* | - | 2,042 tests, 0 failures, 125 skipped |
all of :lucene:core:test | - | 749 classes (with the new test), 8,893 tests, 0 failures, 322 skipped |
:lucene:core:check -x test with the test file | passes | passes |
Also: the kNN probe with the fix compiled onto the main jars (all cases clean, assertions on and off, 3 seeds); in the hunt, the finder's JUnit 4 of 4 and its sandbox variant 3 of 3, the independent reproducer's 5 of 5, and a separate randomized harness run with the fix (3,586 builds, assertions on) has 0 custom-strategy mismatches; the cross-model reviewer ran upstream TestKnnVectorsFormatCustomWriter with the fix (57 tests pass).
Consume and copy the whole batch before the first addValue, so a cursor that throws leaves any writer that keeps the default unchanged.
Trade-offs
Fixes every wrapper at once, but the default cannot allocate a T itself: copying through copyValue breaks writers whose copyValue is unsupported, including upstream's own PagedFieldVectorsWriter (TestKnnVectorsFormatCustomWriter.java:179-185) and both wrappers; next() may reuse its array, so a copy is required; the batch is held twice in memory. Untested.
Change the addDenseValues and wrapper javadocs only.
Trade-offs
No code change, but every existing strategy and downstream flat writer stays broken until it overrides addDenseValues, and the "every doc ID it has recorded" sentence and the per-vector default would contradict the rule. Untested.
Drop the two overrides, so the default calls the wrapper's own addValue per vector, as before #16734.
Trade-offs
Keeps wrapper and delegate in step per vector, as before #16734, but the stock flat writer's bulk path is never reached, which the #16734 review explicitly asked for. Untested.
Not a security issue (it needs an application-built codec composition and the experimental addBatch), but a downstream service with such a codec that indexes untrusted vectors in DENSE batches could see one bad vector close its shared IndexWriter or commit a graph on which kNN search returns wrong documents or throws.
Semi-formal. While modelling the vectors-writer stack in Z3 (a batch whose cursor throws at position k), the finder noticed from the code that the wrappers assume an all-or-nothing flat writer; the model then produced 4-operation counterexamples. A bounded-exhaustive harness on the real jars and a public-API JUnit confirmed it.
The method in full254 words
Method: Z3 bounded model checking of the vectors-writer stack, then a bounded-exhaustive differential harness (the study's "semi-formal" tier: the first signal came from reading the code while modelling).
- The hunt unit targeted the code new in #16734. Its Z3 model (
dense_vector_commit.py, extending an earlier unit's dense-commit model) coversaddValue/addDenseValueswith a cursor that throws at position k. With the stock all-or-nothing flat writer, its four invariants hold to depth 4 and an inductive invariant is proved for unbounded counts; with a delegate that keeps the defaultaddDenseValues, the HNSW node counter, the graph ordinals and the SQ magnitudes invariants are violated by 4-operation witnesses (the bounded model checking unrolls exactly 4 operations), and a 1-step counterexample to induction exists. - A bounded-exhaustive harness on the real jars compared DENSE against SPARSE against
addDocumentover batch sizes 1 to 6, every failure position, 4 failure kinds, 3 encodings, 3 similarities, 3 thresholds and index sort on and off: 944 to 1,415 mismatches per mode for the custom-strategy HNSW stacks, 146 to 242 for SQ, 0 for the stock HNSW stack. In a separate randomized run with the fix (3,586 builds, assertions on) the custom-strategy mismatches drop to 0. The stock HNSW + SQ and stock SQ stacks show a few mismatches per mode, all the separate LFV-047. - The finder then wrote a public-API JUnit (2 of 4 fail, 25 of 25 iterations, with assertions on and off). This doc's JUnit is a compact rewrite of it with the default-threshold case added.
No prior report found (searched 2026-10-26, re-checked 2026-10-27): 96 automated queries over GitHub, commits, mailing lists, the JIRA archive and the web, 26 manual GitHub searches, every open PR's file list, a full-text scan of recent PRs and issues, and the introducing PR's review in full. The code is new.
Searches5 searches
No report of this defect was found. The closest material is the introducing PR's own review, which asked for the forwarding but never discussed a delegate that keeps the default.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene), commits, downstream repositories, web | 2026-10-26 | a scripted prior-report search: 40 issue/PR, 6 commit, 5 downstream and 7 web queries on the class and method names (addDenseValues, VectorValuesCursor, ValidatingVectorValuesCursor, replayBufferedVectors, scaleToUnitLength), keywords and the symptom strings; 26 manual gh searches; the finder's and a checker's own runs (39 and 33 queries) | only the column-API PRs: #16734 (introducing), #16708 / #16732, #16053, #15979, #15990 / #16066; none describes the defect |
| Open PRs and recent activity | 2026-10-26 | the changed-file lists of all 406 open PRs; a full-text scan of 151 closed or merged PRs, 406 open PRs and 94 issues updated since 2026-09-20 | #16731 (open, sandbox) replaces the core HNSW writer in the Dedup formats, so it would probably remove only the sandbox manifestation; it does not mention the bug |
| Review threads | 2026-10-26 | #16734, #16708, #16053, #16062, #15990 and #16219 read in full | #16734: forwarding and recording after fill discussed; delegates that keep the default not discussed |
| Mailing lists and JIRA archive | 2026-10-26 | 32 queries over dev@, java-user@, issues@ and commits@; 6 JIRA-archive queries | no report; the dev@ column-API thread covers scope and performance |
| GitHub, re-check | 2026-10-27 | search for addDenseValues; commits on the three affected files | only #16734 and #15990; no commit after a9779ef3c193 on the files |
Introduced by #16734 (a9779ef3c193, merged 2026-10-26), which added addDenseValues with its per-vector default and the two wrapper overrides. Unreleased: main only (CHANGES lists it under 11.0.0). The parent commit passes the same scenario through the API it has; 10.5.0 and 10.5.2 pass it with a wrong-length rejected vector (they do not reject NaN or zero vectors).
Versions tested6 rows
Introduced by #16734 "Add bulk vector path to columnar addBatch" (@mayya-sharipova; merged 2026-10-26 as a9779ef3c193). git blame attributes every defective line to it; inside the PR, the wrapper overrides came from PR commit e5f1df0c6a7 (2026-10-01), added after the review asked for the forwarding (read, not built). Older preconditions, harmless on their own: the column API (#15990, 10.5.0), the strategyFactory constructor (#16053, 10.5.0), the non-aborting NaN / zero-vector rejection (#16708; on main, branch_10x and branch_10_6, CHANGES: 10.6.0, released 2026-10-29).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's JUnit 3 of 4 fail through gradle, assertions on and off; the finder's 2 of 4 (25 of 25 iterations); a wrong-length trigger fails the same |
upstream main a95c754ee003 | read | same code: no later commit touches the three files (re-checked 2026-10-27) |
parent f4cc6ac2097c (local build) | not affected | the repro does not compile (no VectorValuesCursor); the same composition and rejected batch through the API it has pass 4 of 4, assertions on and off |
previous hunt main ea57360912ed, 10.5.2, 10.5.0 | not affected | does not compile; the pre-#16734 form passes 4 of 4, assertions on and off, with a wrong-length rejected vector (10.5.x does not reject NaN or zero vectors) |
| 9.12.3 | n/a | no columnar API |
| main + fix (option A) | not affected | this doc's JUnit 4 of 4 pass, assertions on and off; the closest and wider suites pass |
A cross-model reviewer (OpenAI GPT-5.6) reproduced it and agreed on the root cause and the fix; an independent reproducer, an intended-behaviour checker and an adjudication each re-ran it on main with assertions on and off (adjudication: confirmed, high). A refute review by the same model family returned a procedural "not real": it could not run code.
Checks and verdicts336 words
Every check that could run code reproduced the bug on main a9779ef3c193 with assertions on and off.
| Check | Verdict | What it found |
|---|---|---|
| cross-model review | real, high | An independent reviewer from another model family (OpenAI GPT-5.6) with code execution reproduced both repros and its own cursor-throw variant, agreed on the root cause, and found that the fix fixes it while upstream TestKnnVectorsFormatCustomWriter passes with it (57 tests); it asked that catch-up failures not mask the cursor exception (addressed). |
| independent reproducer | real | Own JUnit from the claim: 3 of 5 fail with assertions on and off (including the default threshold after 1,000 documents), controls pass, HNSW 40 of 40 over 20 seeds; the fix passes 5 of 5; the pre-#16734 form passes on the previous main. |
| cross-model refute review | not real (procedural) | Its first run targeted an older main without the code; its corrected run could not execute anything. On substance: root cause agrees, inputs in contract, intended-behaviour case weak. Separate re-runs reproduced (2 of 4 fail). |
| intended-behaviour checker | real (not intended: high; reach: moderate) | Built the strongest "intended" case and refuted it; its probe with upstream's 7-argument constructor and the default threshold fails 3 of 4 cases, including a caller cursor that throws with no Lucene validation, and passes a segment too small for a graph. |
| adjudication | confirmed, high | Re-ran the independent reproducer's JUnit with assertions on and off (3 of 5 fail each, controls pass); duplicate of nothing. |
| this doc's validation | reproduced; fix validated | This doc's JUnit (a compact rewrite of the finder's, with the default-threshold case added) fails 3 of 4 through gradle on a fresh stock worktree with assertions on and off and passes 4 of 4 with the fix; with the fix, 527 closest tests, 139 sandbox Dedup tests and all 8,893 tests of :lucene:core:test pass. A kNN probe found that every query of the 1,000-document segment throws EOFException, and that the COSINE SQ segment with no hits passes CheckIndex. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 540 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,667 words
- Registry title
- When IndexWriter#addBatch rejects a vector part-way through a DENSE vector column, the core HNSW and scalar-quantized vectors writers fall out of step with a flat field writer that keeps the default addDenseValues (new in #16734): the next commit closes the IndexWriter, or with assertions off commits a corrupt HNSW graph or misaligned COSINE quantization state
- Area
- codecs / vectors writers (Lucene99HnswVectorsWriter and Lucene104ScalarQuantizedVectorsWriter field writers over a flat field writer; columnar addBatch DENSE vector bulk path)
- Priority
- Low, rank 305: Main-only (not in 10.6.0), and it needs the experimental addBatch with a non-stock flat field writer under the core vector writers.
- Impact class
- data corruption
- Impact note
- Hits only unreleased main (since a9779ef3c193, #16734), and there only applications that index vectors through the experimental IndexWriter#addBatch with a DENSE VectorColumn into a non-default vectors format in which the core Lucene99HnswVectorsWriter or Lucene104ScalarQuantizedVectorsWriter wraps a flat field writer that keeps the default addDenseValues (their own per-field storage through the public Lucene99FlatVectorsWriter strategyFactory constructor, the composition of upstream's own TestKnnVectorsFormatCustomWriter, or their own FlatVectorsWriter), when a batch is rejected at position 1 or later (a NaN or infinite value, a zero vector with COSINE, a wrong length, or a cursor that throws); the stock core formats are not affected, and no scale is needed beyond a segment large enough to build an HNSW graph (about 650 vectors at the default tiny-segment threshold, any size with the threshold <= 0).
- Summary
- You index vectors with IndexWriter#addBatch and a DENSE VectorColumn into an HNSW or scalar-quantized format whose per-field flat storage is your own FlatFieldVectorsWriter (plugged in through the public Lucene99FlatVectorsWriter strategyFactory constructor, without overriding addDenseValues), and Lucene rejects the third vector of a 3-document batch (NaN, or a zero vector with COSINE). You expect what the addDenseValues javadoc and Lucene's own recovery test promise: the batch's documents are deleted, the writer stays open and consistent, and the next commit writes a readable, searchable segment. Instead the flat writer has kept the batch's first two vectors while the HNSW wrapper added no graph nodes for them (and the scalar-quantized wrapper no centroid sums or COSINE magnitudes), so with assertions on the next commit fails ('Level 0 expects to have all nodes', or an assertion in the quantizer) and closes the writer, losing every uncommitted document, and with assertions off it commits an HNSW graph that cannot be read back (EOFException, CheckIndex at level 2 or more fails, a kNN query for a document's own vector returns another document), or the COSINE quantized writer throws ArrayIndexOutOfBoundsException at commit or commits NaN codes so that kNN finds no document of the segment.
- Introduced
- a9779ef3c1939fcd8aaab1b9485f036311797a1d (apache/lucene#16734 'Add bulk vector path to columnar addBatch', by mayya-sharipova, merged to main 2026-10-26) [exec: the repro fails on a9779ef3c193 with -ea and -da; on the parent f4cc6ac2097c (local build) it does not compile (VectorValuesCursor absent), and the same composition and rejected batch through the pre-#16734 API (a DENSE column with tuples(), one addValue per document) pass 4 of 4 with -ea and -da; read: git blame at a9779ef3c193 attributes KnnFieldVectorsWriter.java:40-63, Lucene99HnswVectorsWriter.java:845-869, Lucene104ScalarQuantizedVectorsWriter.java:739-757, Lucene99FlatVectorsWriter.java:504-531 and IndexingChain.java:1318-1368 to this commit]. Inside the PR, the two wrapper overrides came from PR commit e5f1df0c6a7 (2026-10-01), added after a reviewer (jimczi) asked that the HNSW and scalar-quantized field writers forward to their flat delegate [read: PR commits through the GitHub API, not built] (2026-10-26 (merged; commit date 2026-10-26 -0400))
- First affected version
- unreleased (main only, 11.0.0-SNAPSHOT since a9779ef3c193; CHANGES.txt lists #16734 under 11.0.0, so it would first ship in 11.0.0 unless fixed or backported first; not on branch_10x, branch_10_6 or branch_10_5) [exec on main; read for the branches]
- Affected versions
- main a9779ef3c193 [exec: finder JUnit 2 of 4 fail with -ea and -da (25 of 25 iterations each), the independent reproduction JUnit 3 of 5, also with a wrong-length vector as the trigger; controls pass]; upstream main a95c754ee003 (2026-10-26) [read: no later commit touches KnnFieldVectorsWriter.java, Lucene99HnswVectorsWriter.java or Lucene104ScalarQuantizedVectorsWriter.java]. Not affected: the parent f4cc6ac2097c, the previous hunt main ea57360912ed, 10.5.0 and 10.5.2 [exec: the repro does not compile; the same composition and rejected batch through the API those versions have pass 4 of 4 with -ea and -da]; 9.12.3 and older [exec: compile error, no columnar API]; branch_10x, branch_10_6 and branch_10_5 [read through the GitHub API 2026-10-26: KnnFieldVectorsWriter.java has no addDenseValues there]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3, code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only; follow-up prior-report record verdict new): a scripted prior-report search with 96 queries (40 GitHub issue and PR, 6 commit, 5 downstream-repository, 32 mailing-list over dev@, java-user@, issues@ and commits@, 6 JIRA-archive, 7 web), 26 manual gh searches on apache/lucene, all of GitHub and downstream repositories, the changed-file lists of all 406 open apache/lucene PRs, a full-text GraphQL scan of the title, body, comments and reviews of 151 closed or merged PRs, all 406 open PRs and 94 issues updated since 2026-09-20, and the review threads of #16734, #16708, #16053, #16062, #15990 and #16219 read in full; plus the finder's and the intended-behaviour check's own scripted prior-report searches (12 and 33 queries). Related, none of them a report of this bug: #16734 (the introducing PR, merged 2026-10-26: a reviewer asked for the wrapper forwarding and that writers 'only record doc IDs after fill returns'; nobody raised a delegate that keeps the default per-vector addDenseValues); open #16731 (sandbox: replaces the core HNSW writer in the Dedup formats, so it would probably remove only the sandbox manifestation, by code reading; it does not mention the bug and does not touch the core wrappers); #16708 / #16732 (the non-aborting validation that rejects the batch); #16053 (the strategyFactory constructor and TestKnnVectorsFormatCustomWriter); #15979 (the sandbox Dedup formats); #15990 / #16066 (the column API); #15540 (invalid vectors accepted until merge, different root cause).apache.org may lag by hours
- Lucene commit tested
- main
a9779ef3c193(2026-10-26, the introducing commit): the paste-ready JUnit through gradle on a fresh stock worktree with assertions on and off (3 bug tests fail, the control passes) and with the hunt's fix applied (4 of 4 pass with assertions on and off, and at 3 more seeds), the closest suites with the fix (18 closest classes, 527 tests, 0 failures, assertions on and off; the sandbox Dedup suites, 139 tests; the core codecs, kNN and HNSW tests, 2,042 tests; all of:lucene:core:test, 8,893 tests, 0 failures),:lucene:core:check -x test; a kNN probe on the main jars and with the fix, assertions on and off, seeds DEADBEEF, A0D17004 and 5EEDD1A6; the finder's, the independent reproducer's, the intended-behaviour checker's and the adjudication's JUnits on main; the parentf4cc6ac2097c(local build), the previous hunt mainea57360912ed, 10.5.0, 10.5.2 and 9.12.3 with the API each version has. Upstream maina95c754ee003was read, not run: no later commit touches the affected files (re-checked 2026-10-27).
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/KnnFieldVectorsWriter.java:40-63 (at a9779ef3c193) (addDenseValues contract: 'The cursor may throw while it is being consumed ... the writer must remain in a consistent state: every doc ID it has recorded must have its vector ... record doc IDs and vectors only after fill has returned'; 'The default implementation calls addValue once per vector. Override for a more efficient bulk path. A writer that wraps another field writer should forward this method to it'; @lucene.experimental; default body loops addValue(firstDocID + i, values.next()))lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99HnswVectorsWriter.java:845-869 (at a9779ef3c193) (FieldWriter.addDenseValues: flatFieldVectorsWriter.addDenseValues first; node, lastDocID and addGraphNode or initializeGraphBuilder/replayBufferedVectors only after it returns), :647 (writeMeta: assert nodesOnLevel.size() == count 'Level 0 expects to have all nodes'), :107 and :128 (public constructors taking any FlatVectorsWriter)lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104ScalarQuantizedVectorsWriter.java:739-757 (at a9779ef3c193) (FieldWriter.addDenseValues javadoc 'The flat writer records nothing if the cursor throws, so neither does this writer'; accumulate only after the delegate returns), :822-834 (scaleToUnitLength: magnitudes.get(ord)), :86 (public constructor)lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99FlatVectorsWriter.java:87-105 (at a9779ef3c193) (public strategyFactory constructor: any FlatFieldVectorsWriter per field), :504-531 (DefaultFieldWriter.addDenseValues: fills a temporary batch, records vectors and doc IDs only after every fill returned, so the stock writer is all-or-nothing)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1318-1369 (at a9779ef3c193) (processDenseVectorColumn: one addDenseValues call with a ValidatingVectorValuesCursor that checks each vector as it is consumed)lucene/core/src/test/org/apache/lucene/index/TestColumnBatchIndexing.java:886-922 (at a9779ef3c193) (testDenseVectorValidationFailureRecovers: a rejected DENSE vector batch is non-aborting; 'flush checks that the vectors writer was left consistent'; stock formats only)lucene/core/src/test/org/apache/lucene/codecs/lucene99/TestKnnVectorsFormatCustomWriter.java:43-113 (at a9779ef3c193) (upstream test: paged FlatFieldVectorsWriter strategy without an addDenseValues override, wrapped in the stock Lucene99HnswVectorsWriter)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1535-1537 (at a9779ef3c193) (addBatch, @lucene.experimental); lucene/CHANGES.txt:219-221 (GITHUB#16734 under 11.0.0)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/KnnFieldVectorsWriter.java:40-63 (at a9779ef3c193) (contract, default)lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99HnswVectorsWriter.java:272, (at a9779ef3c193) :647, :797-801, :825-844, :851-869lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104ScalarQuantizedVectorsWriter.java:745-757, (at a9779ef3c193) :791-804, :828-833; lucene/core/src/java/org/apache/lucene/internal/hppc/FloatArrayList.java:130-135lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99FlatVectorsWriter.java:87-105, (at a9779ef3c193) :507-531lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99HnswVectorsReader.java:589-591, (at a9779ef3c193) :603-604lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1318-1369; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/document/column/ValidatingVectorValuesCursor.java:141-147
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99FlatVectorsWriter.java:87-105; (at a9779ef3c193) lucene/core/src/test/org/apache/lucene/codecs/lucene99/TestKnnVectorsFormatCustomWriter.java:84-96, :113-185lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1528-1573 (at a9779ef3c193) (addBatch, updateDocuments(Term|Query, ColumnBatch), @lucene.experimental; updateBatch is private, :1575); lucene/CHANGES.txt:219-221 (GITHUB#16734 under 11.0.0), :885-887 (GITHUB#16053 under 10.5.0)lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99HnswVectorsWriter.java:716-722; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/util/hnsw/HnswGraphSearcher.java:56-58lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:1114-1144, (at a9779ef3c193) :499-508, :4673, :4742-4748 (levels); lucene/test-framework/src/java/org/apache/lucene/tests/index/BaseKnnVectorsFormatTestCase.java (no addBatch)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/KnnFieldVectorsWriter.java:46-63 (at a9779ef3c193)lucene/core/src/test/org/apache/lucene/index/TestColumnBatchIndexing.java:886-922 (at a9779ef3c193)lucene/core/src/test/org/apache/lucene/codecs/lucene99/TestKnnVectorsFormatCustomWriter.java:43-113; (at a9779ef3c193) lucene/CHANGES.txt:885-887
- Suggested fix
lucene/core/src/test/org/apache/lucene/codecs/lucene99/TestKnnVectorsFormatCustomWriter.java:179-185 (at a9779ef3c193) (copyValue unsupported)
- History
lucene/CHANGES.txt:219-221 (at a9779ef3c193) (#16734 under 11.0.0), :446, :504-507, :527-529 (#15979/#16506 and #16708 under 10.6.0)
- TestDenseBatchHnswOverDefaultDelegate.java (JUnit test):
repro/LFV-579/src/org/apache/lucene/codecs/lucene99/TestDenseBatchHnswOverDefaultDelegate.java(173 lines)
The diagrams follow the repro's numbers (doc 0, the rejected batch [0, 1], [1, 1], [NaN, 0], doc 4), re-run by a small diagram probe on main that reads the wrapper's and the flat writer's state after every step; see the diagram directory's notes for the scene list and the source of each value.
assets/LFV-579/bug.png(540 KB)