A stop filter removes words but keeps their positions as holes, so one of the best is one, two holes, best. At the end of the input those holes are reported in the final position increment. SuggestStopFilter drops them there, and the suggester's query then has too few holes.
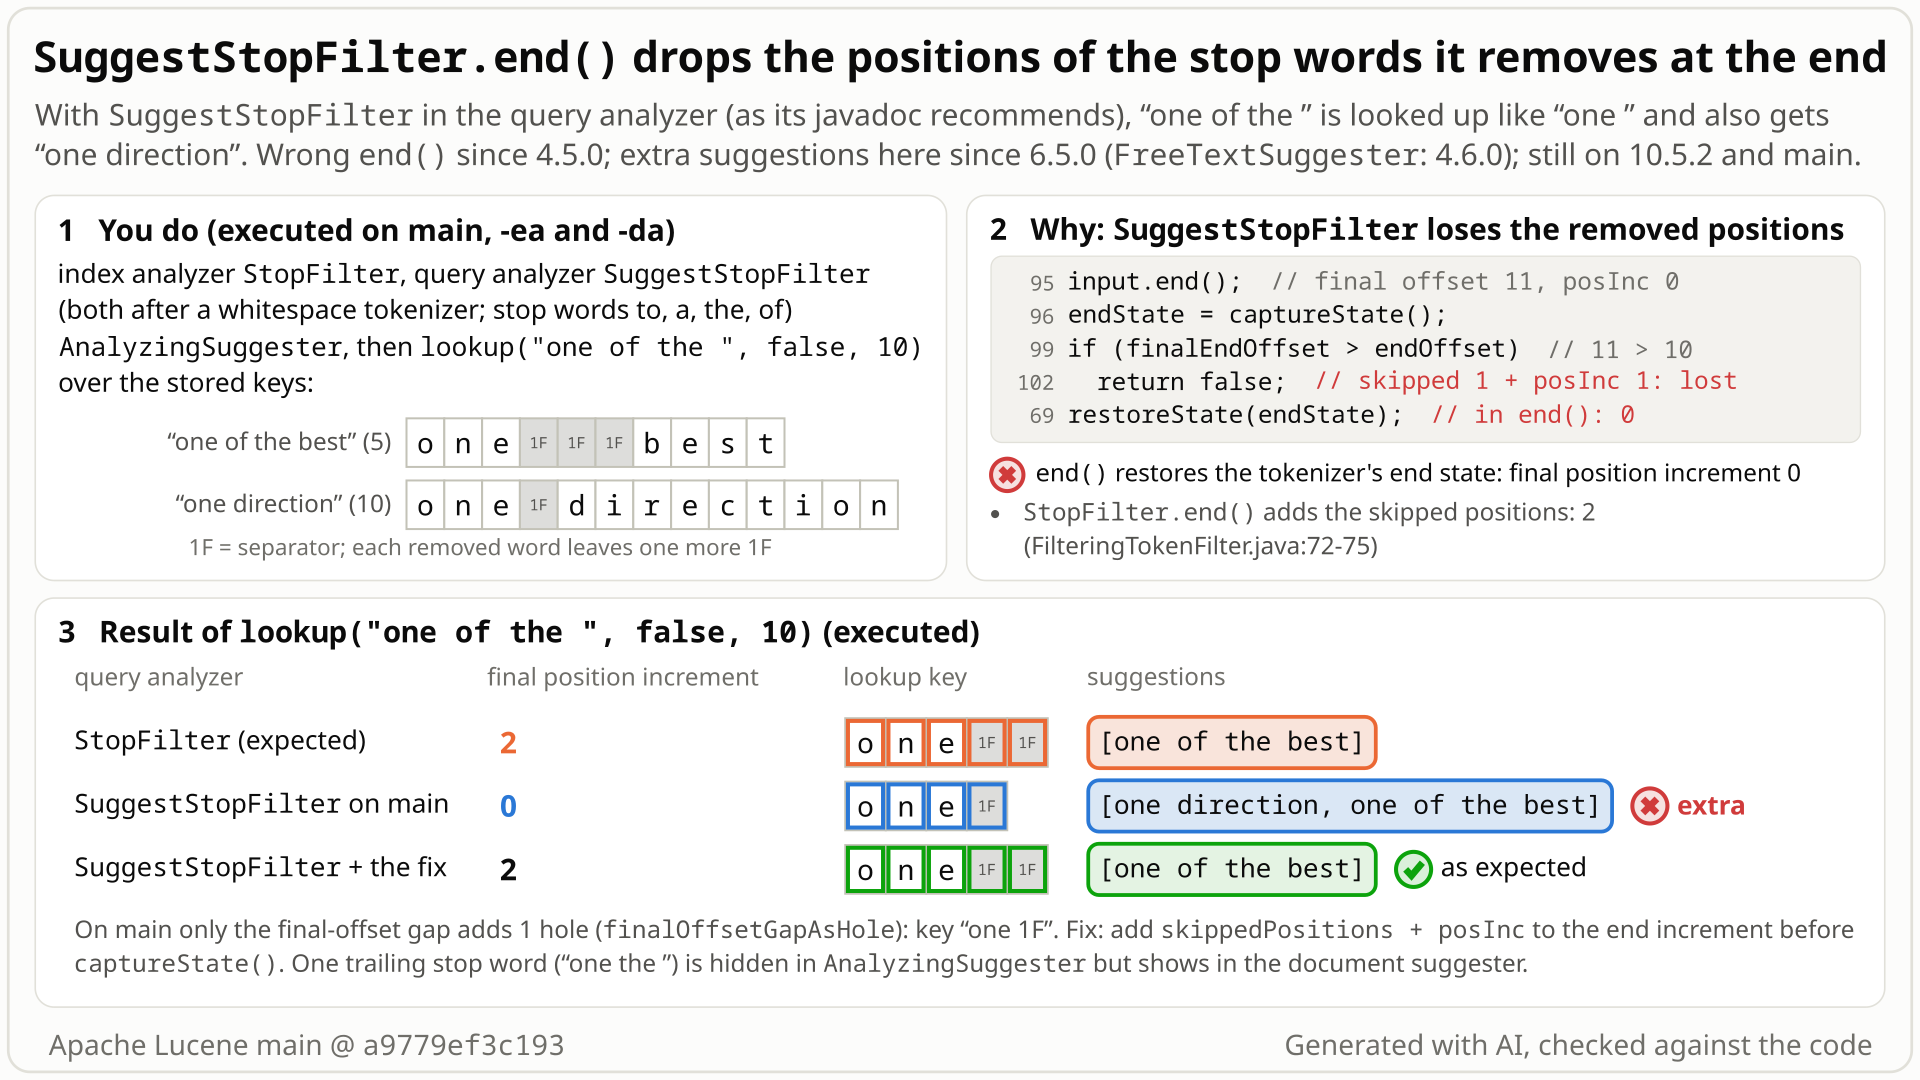
one of the example step by step: each removed word should leave a hole; StopFilter reports two at the end, SuggestStopFilter reports none, so the query one plus one separator also matches one direction. Select the still to open it at full size. Generated with AI, checked against the code.- You build an
AnalyzingSuggesterover two entries,one direction(weight 10) andone of the best(weight 5). The index analyzer removes the stop wordsto a the ofwithStopFilter, the query analyzer withSuggestStopFilter, as the class javadoc recommends. - The user types
one of thewith a space afterthe, so both stop words are finished. Both filters keep onlyone, and each removed word should leave a hole:StopFilterreports 2 removed positions at the end of the input (final position increment 2).SuggestStopFilterreports 0. - You expect
[one of the best], which the same suggester returns with aStopFilterquery analyzer: the query meansone, then two skipped words, then whatever comes next. - Instead you get
[one direction, one of the best], with no error. With 0 removed positions the suggester sees onlyoneand a space, so every entry that starts withonematches.go to a thereports 0 instead of 3 the same way. - With one finished stop word (
one the) theAnalyzingSuggesteradds one hole by itself, because the final offset lies past the end of the last kept word (finalOffsetGapAsHole), which happens to be right; the document suggester (PrefixCompletionQuery) does not, so thereone thealready matches likeone.
Applications with SuggestStopFilter in a suggester's query analyzer (directly or as the suggestStop factory), as its javadoc recommends. Lookups ending in finished stop words can get extra suggestions: with two or more such words in AnalyzingSuggester and FuzzySuggester, with one in the document suggester and FreeTextSuggester. No error; it clears once a non-stop word is typed.
Mechanism, terms and numbers905 words
SuggestStopFilter is the query-side stop filter for autocomplete. Its javadoc defines it as "Like StopFilter except it will not remove the last token if that token was not followed by some token separator" and recommends StopFilter in the index analyzer with this class in the query analyzer of the analyzing suggesters. When the typed text ends in stop words followed by a separator, such as one of the , it removes them like StopFilter, but its end() reports the input's own final position increment, 0, instead of adding the positions it removed; StopFilter reports 2. Terms, position increments, offsets and the final offset are identical. The suggesters turn that final increment into trailing holes of the lookup automaton, so with too few holes the lookup matches more entries: AnalyzingSuggester.lookup("one of the ") returns [one direction, one of the best] where a StopFilter query analyzer returns [one of the best]. AnalyzingSuggester and FuzzySuggester show it with two or more removed trailing stop words, the document suggester and FreeTextSuggester with one. In a bounded probe the result was always the result for the same text without its trailing stop words; in exactFirst mode (AnalyzingSuggester, FuzzySuggester) one entry whose text equals the typed text is dropped (with assertions on, the lookup throws an AssertionError). The end value has been wrong since 4.5.0 (LUCENE-3849); it has changed FreeTextSuggester results since that suggester's first release, 4.6.0, and the other suggesters' since 6.5.0 (LUCENE-7619). With a small fix (+6/-2 lines in SuggestStopFilter) the whole suggest test task has 0 failures.
- Position increment: each token says how many positions it moved on from the previous one. A removed stop word leaves a hole: in
go to school,schoolhas increment 2. - Final position increment: after the last token,
TokenStream#end()reports the positions skipped at the end of the input: "any skipped positions (such as those removed by a stopfilter) can be applied to the position increment" (TokenStream.java:152-154).StopFilterdoes this (FilteringTokenFilter.java:72-75):go to a theends with final increment 3. - SuggestStopFilter: "Like StopFilter except it will not remove the last token if that token was not followed by some token separator" (
SuggestStopFilter.java:29-37). It keeps an unfinished last word (find the), so that a queryacan still suggestapple(LUCENE-5165 CHANGES entry). - Lookup automaton:
AnalyzingSuggesterturns the analyzed query into an automaton and matches it as a prefix of the analyzed entries. Each hole becomes an extra separator (AnalyzingSuggester.java:268-307); trailing holes come from the final position increment (TokenStreamToAutomaton.java:212-241).
// incrementToken(): the last token is a stop word and the input has no more tokens
clearAttributes();
input.end();
endState = captureState();                 // :96  the input's end state: final posInc 0
int finalEndOffset = offsetAtt.endOffset();
if (finalEndOffset > endOffset) {
  // OK there was a token separator after the stopword, so it was a stopword
  return false;                            // :102 skippedPositions and this word's posInc are lost
}

// end()                                      :61-71
if (endState == null) { super.end(); } else { restoreState(endState); }

// StopFilter, through FilteringTokenFilter.end()   :72-75
super.end();
posIncrAtt.setPositionIncrement(posIncrAtt.getPositionIncrement() + skippedPositions);- For
one of the,oneis returned.ofis skipped (skippedPositions = 1).theis a stop word and the last token, so the filter callsinput.end()and captures that state: final increment 0, final offset 11. - The final offset is past the end of
the(10), sothewas finished and is removed. The filter returns false without addingskippedPositions(1) orthe's own increment (1).end()restores the captured state: final increment 0.StopFiltergives 2. - The index side stores
one of the bestasone, three separators,best(one separator per position step), andone directionasone, one separator,direction. TheStopFilterqueryone of theisoneplus two separators: a prefix of the first entry only. TheSuggestStopFilterquery isoneplus one separator: a prefix of both. AnalyzingSuggesterandFuzzySuggestercallsetFinalOffsetGapAsHole(true)(AnalyzingSuggester.java:317-322): a final increment of 0 becomes 1 hole when the final offset lies past the end of the last token (TokenStreamToAutomaton.java:214-216; here 11 against 3, the gapof the). That is right for one removed word and too few for two or more. The document suggester builds its automaton without that setting (ConcatenateGraphFilter.java:233-244), so there one removed word already matters.
Mid-stream the class does the bookkeeping: go to a the school gives school increment 4, which the upstream TestSuggestStopFilter.testMultipleStopWords asserts. Only the end-of-input branch drops it.
input (whitespace tokenizer, stop words to a the of) | StopFilter final posInc | SuggestStopFilter final posInc |
|---|---|---|
go the | 1 | 0 |
one of the | 2 | 0 |
go to a the | 3 | 0 |
go to school (control) | 0 | 0 |
AnalyzingSuggester, index analyzer StopFilter, entries one direction (10), one of the best (5) | lookup("one of the ") |
|---|---|
query analyzer StopFilter (control) | [one of the best] |
query analyzer SuggestStopFilter (main) | [one direction, one of the best] |
query analyzer SuggestStopFilter with the fix | [one of the best] |
An exhaustive comparison with StopFilter over 11,718 inputs (every sequence of 0-5 words over go to a the school, 3 endings) found 4,686 differences, all in the final position increment only; 0 with the fix (compared: terms, position increments, offsets, final offset and final position increment).
Exposure and likelihood546 words
- Who. Users of
SuggestStopFilterin the query analyzer ofAnalyzingSuggester,FuzzySuggester, the document suggester (PrefixCompletionQuery,FuzzyCompletionQuery) orFreeTextSuggester, directly or throughSuggestStopFilterFactory(SPI namesuggestStop). It is opt-in: no Lucene analyzer uses the class by default. The suggester defaults (exactFirst, preserved separators and position increments) are the configuration shown.preservePositionIncrements=falsedoes not hide it but reverses it: the buggy lookup then misses single-token entries that aStopFilterquery analyzer matches (AnalyzingSuggesterwith entriesone direction,one of the best,oneplus:[one direction, one of the best]instead of[one direction, one of the best, oneplus]).AnalyzingInfixSuggesteris not affected. - Trigger. Ordinary typing: text that ends in removed stop words followed by a space, such as
one of the.AnalyzingSuggesterandFuzzySuggesterneed two or more such words (with one, their own trailing-space hole happens to be right); the document suggester needs one (one thematches likeone), and so doesFreeTextSuggester, which reads the end increment itself (FreeTextSuggester.java:474-541):one ofreturns the next-word predictions afteronewhere aStopFilterquery analyzer returns none. - Effect. Extra suggestions. In a bounded probe (6 words, 3 of them stop words, texts of 1 to 4 words: 1,434 entries, 3,108 queries, 777 ending in removed stop words) the result with the bug always equals the result for the same text without its trailing stop words, 0 mismatches. Not every such query changes: 270 of the 777 differ from the fixed filter in
AnalyzingSuggesterand inFuzzySuggester, 528 (prefix) and 513 (fuzzy) in the document suggester; inFreeTextSuggester657 of 2,868 queries differ. Contexts and document filters still apply to every hit. - One entry can be lost. In exactFirst mode, an entry whose text equals the typed text, trailing space included (entry
one of the, queryone of the), is dropped with assertions off: the probe'sAnalyzingSuggesterreturns[one of the best, one direction, one the end], whereStopFilterand the fix return[one of the , one of the best, one the end]. With assertions on the lookup throws anAssertionErroratAnalyzingSuggester.java:808.FuzzySuggester, which inherits that code, does the same. - Index time (not the documented setup). In an index analyzer the lost increment moves the next value of a multi-valued field one position earlier:
foo the|barwith gap 0 putsbarat position 1 instead of 2, so the phrase"foo bar"matches. - How likely. Plausible: in that setup such a lookup can be broadened, and the extra entries are the suggestions for the shorter text; they go away once a word that is not a stop word is typed. No report was found in the searches performed. No scale is needed.
- Workaround. None that keeps the class's purpose:
preservePositionIncrements=falsedoes not help (above) and ignores every hole; aStopFilterquery analyzer is right forone of thebut removes an unfinished last word (find the), the caseSuggestStopFilterexists for. A filter after it cannot repair the value (the count of removed trailing words stays insideincrementToken()), and the class isfinal(SuggestStopFilter.java:38); an application would need its own copy of the class with the fix.
The test shows that SuggestStopFilter removes the separator-terminated trailing stop words of "one of the " but its end() leaves their positions out of the final position increment.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.analyzing;

import java.io.StringReader;
import org.apache.lucene.analysis.StopFilter;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.tokenattributes.PositionIncrementAttribute;
import org.apache.lucene.tests.analysis.MockTokenizer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSuggestStopFilterTrailingHoles extends LuceneTestCase {

  public void testEndCountsRemovedTrailingStopWords() throws Exception {
    Tokenizer tokenizer = new MockTokenizer(MockTokenizer.WHITESPACE, true);
    tokenizer.setReader(new StringReader("one of the "));
    TokenStream ts = new SuggestStopFilter(tokenizer, StopFilter.makeStopSet("of", "the"));
    PositionIncrementAttribute posInc = ts.addAttribute(PositionIncrementAttribute.class);
    ts.reset();
    while (ts.incrementToken()) {}
    ts.end();
    // expected 2 (StopFilter counts the removed "of" and "the" in end()); actual 0
    assertEquals(2, posInc.getPositionIncrement());
    ts.close();
  }
}
# in a copy of this finding's repro folder (repro/LFV-583/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/suggest/build/libs/lucene-suggest-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.suggest.analyzing.TestSuggestStopFilterTrailingHoles
- Expected vs actual
- Expected: 2, as
StopFilterreports on the same input (the class is documented as "Like StopFilter"). Actual:expected:<2> but was:<0>(-ea and -da).
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<2> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
       org.junit.Assert.assertEquals(Assert.java:633)
org.apache.lucene.search.suggest.analyzing.TestSuggestStopFilterTrailingHoles.testEndCountsRemovedTrailingStopWords(TestSuggestStopFilterTrailingHoles.java:38)- Documented as
StopFilterwith one exception, an unfinished last word;StopFilterreports the removed trailing positions inend(), and a test asserts it. - LUCENE-3849 made
end()carry trailing holes; its commit added the skipped positions there forStopFilterand for the plainTokenFilterMockTokenFilter, not here. - No test, CHANGES entry or recorded decision was found for the current value.
The full argument241 words
- One documented exception. "Like StopFilter except it will not remove the last token if that token was not followed by some token separator" (
SuggestStopFilter.java:29-34). The LUCENE-5165 CHANGES entry says the same: a stop word "at the very end of the lookup query, and without any trailing token characters, will be preserved" (CHANGES.txt:13275-13280). StopFilterreports the positions, and a test pins it.FilteringTokenFilter.end()addsskippedPositions(:72-75);TestStopFilter.testEndStopwordasserts final increment 1 fortest of(TestStopFilter.java:172-189).end()is the channel.TokenStream#end: skipped positions "can be applied to the position increment" (TokenStream.java:152-154). LUCENE-3849: "TokenStreams now set the position increment in end(), so we can handle trailing holes" (CHANGES.txt:13337-13340). Its issue text (#4922) says "subclasses of FilteringTokenFilter (e.g. stopfilter) should do: super.end(); posIncAtt += skippedPositions;"; this class is a plainTokenFilter, but the commit made the same change in the test framework'sMockTokenFilter, also a plainTokenFilter. Before the commit the committer wrote "I agree this bug is bad. It can also affects suggesters".- The class already does it mid-stream (
SuggestStopFilter.java:92, :114;testMultipleStopWordsasserts +4), and the suggesters read the end increment:FreeTextSuggestersince its first release, 4.6.0 (FreeTextSuggester.java:474-541), the analyzing suggesters since LUCENE-7619 (6.5.0). - No test covers it.
testEndIsStopWord(go to) andtestMultipleStopWordsEnd2(go to a the) use theassertTokenStreamContentsoverload that passesfinalPosInc = null(TestSuggestStopFilter.java:47-64, 123-140).
The devil's-advocate check223 words
Strongest case (an intended-behaviour checker and a reviewer from another model family, OpenAI GPT-5.6; rated moderate): TokenStream#end says skipped positions "can" be applied, not "must". The author of the class rewrote SuggestStopFilter.end() in the LUCENE-3849 commit itself, six days after adding the class, and did not add them. The upstream trailing-stop tests leave the final increment unchecked, and TestAnalyzingSuggester strips trailing holes from its oracle because "TokenStream.end() does not tell us any trailing holes, yet ... there is an issue open for this" (TestAnalyzingSuggester.java:900-902).
Why it fails: the class's only documented difference from StopFilter does not apply to text that ends in a separator. LUCENE-3849's issue text asks FilteringTokenFilter subclasses such as StopFilter to add skippedPositions in end(), and the same commit did so for FilteringTokenFilter and for the test framework's MockTokenFilter, a plain TokenFilter like this class. When it landed, no suggester read the end increment yet: FreeTextSuggester, which does, was added six weeks later (4.6.0), and TokenStreamToAutomaton looked only at the final offset until LUCENE-7619 (6.5.0). The indexer reads it too, but an index analyzer is not where the class is documented to go. No record of a decision about the value was found. The TestAnalyzingSuggester comment dates from 2012, before LUCENE-3849, and concerns that test's own filter: it names a known gap, not a design.
Recommended A. Add the removed positions before capturing the end state (recommended)
On the branch that removes a finished last stop word, add skippedPositions + posInc to the final position increment before capturing the end state (+6/-2 in SuggestStopFilter.java). With two finalPosInc asserts added to TestSuggestStopFilter, the whole :lucene:suggest test task (240 tests, 7 upstream skips) has 0 failures, the repro tests included, with assertions on and off.
All options and trade-offs3 options · 759 words
Fix A and fix B were built and run in a scratch worktree at a9779ef3c193 with the whole :lucene:suggest:test task (the two repro classes and the new asserts included); both give StopFilter's end state. Either fix also makes FreeTextSuggester follow StopFilter for such text. Both are behaviour-changing bug fixes: suggestion lists for such text change. The sibling end() bugs in other classes (LFV-354, LFV-542, LFV-532, LFV-488) have their own fix sites.
On the branch where the last stop word is followed by a separator, add skippedPositions + posInc to the input's final increment and only then capture endState; the unfinished-last-word branch captures it unchanged. end() stays as it is. The patch below plus two finalPosInc asserts in the existing TestSuggestStopFilter trailing-stop tests is fix-with-test.diff.
           clearAttributes();
           input.end();
-          endState = captureState();
           int finalEndOffset = offsetAtt.endOffset();
           assert finalEndOffset >= endOffset;
           if (finalEndOffset > endOffset) {
             // OK there was a token separator after the
-            // stopword, so it was a stopword
+            // stopword, so it was a stopword; like StopFilter,
+            // report the removed trailing positions in end()
+            posIncAtt.setPositionIncrement(
+                posIncAtt.getPositionIncrement() + skippedPositions + posInc);
+            endState = captureState();
             return false;
           } else {
+            endState = captureState();
             // No token separator after final token that
             // looked like a stop-word; don't filter it:
             restoreState(sav);
Trade-offs
- Smallest change: the stored end state itself is right, so any consumer that calls
end()seesStopFilter's value. - Changes suggestions only for text that ends in removed stop words and a separator; those now match
StopFilter.FreeTextSuggesterresults for such text change the same way (one ofgives[]instead of the bigrams afterone). - With
preservePositionIncrements=falsethe change goes the other way: such a lookup then matches like aStopFilterquery analyzer, which also includes single-token entries that start with the kept word (oneplusforone of the). - For very long runs of trailing stop words the lookup automaton grows like
StopFilter's (40,004 states for 20,000 stop words instead of 6; single runs, not a benchmark); bounding query length is the application's job (SECURITY.md line 38).
What the checks validated
- Gradle on
a9779ef3c193, seed DEADBEEF:fix-with-test.diffplus the two repro classes, all of:lucene:suggest:test: 33 classes, 240 tests, 0 failures, 7 skipped (upstream@Ignoreand@Nightly), with assertions on and off (an independent fact check repeated both). That is 236 upstream tests (e.g.TestAnalyzingSuggester23,TestFuzzySuggester14,TestAnalyzingInfixSuggester23,TestFreeTextSuggester11,TestPrefixCompletionQuery9) plus the 4 repro tests. :lucene:suggest:ecjLintMain,ecjLintTestandcheckGoogleJavaFormatpass withfix-with-test.diff.- With the standalone runner (fix as a shadow class): the finder's and the reproducer's tests pass, 46 tests of the four closest classes pass, and the exhaustive differential against
StopFiltergives 11,718 of 11,718 equal.
Keep the capture where it is; store skippedPositions + posInc in a field on the separator branch, reset it in reset(), and add it after restoreState(endState) in end() (+5 lines).
   private State endState;
+  // positions of the stop words removed at the end of the input, reported in end() like StopFilter
+  private int trailingSkippedPositions;
   ...
     endState = null;
+    trailingSkippedPositions = 0;
   ...
       restoreState(endState);
+      posIncAtt.setPositionIncrement(posIncAtt.getPositionIncrement() + trailingSkippedPositions);
   ...
             // stopword, so it was a stopword
+            trailingSkippedPositions = skippedPositions + posInc;
             return false;
Trade-offs
Same result as A and reads like FilteringTokenFilter.end(), which adds its count after super.end(); one more field to reset.
What the checks validated
- Gradle on
a9779ef3c193, seed DEADBEEF, with the same test asserts and repro classes: all of:lucene:suggest:testpasses with assertions on (33 classes, 240 tests, 0 failures, 7 skipped);ecjLintMain,ecjLintTestandcheckGoogleJavaFormatpass. With assertions off (run by an independent fact check): 33 classes, 240 tests, 0 failures, 7 skipped.
Pass finalPosInc in the two existing trailing-stop tests of TestSuggestStopFilter: 1 for go to (testEndIsStopWord) and 3 for go to a the (testMultipleStopWordsEnd2), with the assertTokenStreamContents overload that takes it. The finder's JUnit adds the suggester-level case.
Trade-offs
Pins the value at the filter level; the suggester-visible effect needs the repro's lookup test.
What the checks validated
- On stock main the two asserts fail (
finalPosInc expected:<1> but was:<0>,expected:<3> but was:<0>; 2 of 6TestSuggestStopFiltertests); with fix A or fix B they pass.
By code reading only, Elasticsearch and OpenSearch build a SuggestStopFilter for their stop token filter with remove_trailing: false, and Solr documents SuggestStopFilterFactory for suggester query analyzers; nothing was run downstream and no downstream report was found.
Semi-formal: a bounded-exhaustive sweep compared the end() positions and offsets of 434 selected token-filter configurations with a reference built from their input plus the positions they removed (6.78 million analyses), and flagged SuggestStopFilter. A differential test against StopFilter over 11,718 inputs isolated the final position increment; it was reduced to a public-API JUnit.
The method in full190 words
- Sweep (bounded-exhaustive translation validation of the stock jars). 434 selected component configurations (the token filters registered through SPI with their defaults, except 27 that need parameters or resources, plus parameter grids for the buffering and token-removing filters), behind 3 upstream chains, on 5,208 texts each (6.78 million analyses). The reference for each run is the end() state of the same chain without the component, plus the positions the component removed; it compares terms, position increments and lengths, offsets, and the final position increment and offset, not every attribute. Every
suggestStopconfiguration with a matching stop word list showed final-position mismatches. - Differential against the documented equivalence. Every sequence of 0-5 words over
go to a the schoolwith 3 endings (11,718 inputs) throughStopFilterandSuggestStopFilter: 4,686 mismatches, all of one shape (only the final position increment differs; terms, position increments, offsets and the final offset equal; other attributes not compared); 0 with the fix (non-vacuous). - Reduction. Code reading found the separator branch in
incrementToken; the finder wrote the public-API JUnit with theAnalyzingSuggesterlookup and ran it on main, 10.5.2 and 9.12.3, and amain()probe on 8.11.4.
No prior report found (142 logged queries plus about 40 manual GitHub searches, the JIRA archive, the mailing lists and downstream trackers, 2026-10-26). Nearest: LUCENE-3849 (#4922), whose commit fixed StopFilter's end() and missed this class, and LUCENE-5165 (#6229), which added the class.
Searches5 searches
Registry verdict new. None of the items reports that SuggestStopFilter.end() omits the removed trailing positions or the extra suggestions. Same family in other classes, each filed and fixed separately: LUCENE-5180 (#6244, ShingleFilter), LUCENE-8360 (NGramTokenFilter), LUCENE-8371 (#9418, FixedShingleFilter), LUCENE-8650 (#9696, ConcatenatingTokenStream) and #16577 (FixedShingleFilter). Also read and different: #9391 (LUCENE-8344, TokenStreamToAutomaton with preservePositionIncrements=false), #4915 (LUCENE-3842, the analyzing suggester).
| Where | When | How | Found |
|---|---|---|---|
| GitHub apache/lucene issues, PRs and commits | 2026-10-26 | three scripted prior-report searches (class-focused and symptom-focused, 142 queries in total) and about 40 manual gh searches (SuggestStopFilter and its factory, trailing stop words or holes in suggesters, TokenStreamToAutomaton trailing, final position increment, skippedPositions, finalOffsetGapAsHole); the file's history on main, branch_10x, branch_10_5 and branch_9x | no report; nearest #4922, #6229, #9391, #4915 |
| Open PRs | 2026-10-26 | the changed files of all 406 open apache/lucene PRs | none touches SuggestStopFilter or its test |
| Downstream (Elasticsearch, OpenSearch, Solr, Lucene.NET) | 2026-10-26 | issue searches, remove_trailing, code search for reach | no report; Elasticsearch and OpenSearch map remove_trailing=false to SuggestStopFilter (code reading) |
| Mailing lists and JIRA | 2026-10-26 | java-user@, dev@, issues@, commits@, general@, solr-user@, users@solr; JIRA text ~ SuggestStopFilter (5 results) | no report; a 2017 java-user@ thread is usage advice |
| Web | 2026-10-26 | 7 web queries | no report |
Introduced by LUCENE-3849 (2013-08-20: e005a580e9f on branch_4x, shipped in 4.5.0; trunk twin 2a5421ca685), which made end() report trailing holes and missed this class. Visible in FreeTextSuggester since 4.6.0 and in the analyzing and document suggesters since 6.5.0 (LUCENE-7619). Every release checked from 4.5.0 to 10.5.2 and main; not fixed upstream.
Versions tested7 rows
Introduced by LUCENE-3849 (apache/lucene#4922), committed by Michael McCandless on 2013-08-20 as "LUCENE-3849: end() now sets position increment, so any trailing holes are counted": e005a580e9f on branch_4x (shipped in 4.5.0) and 2a5421ca685 on trunk (first released in 6.0.0). The commit gave FilteringTokenFilter.end() the skipped positions and changed SuggestStopFilter to capture its end state right after input.end(), without them. Commit isolation on 4.4.0 jars with shadowed sources: before it both filters agree, after it they differ exactly as in 4.5.0. The class itself (LUCENE-5165, #6229) was added six days earlier.
Visible in FreeTextSuggester since 4.6.0: LUCENE-5214 added it (branch_4x 9494be7ec2a, 2013-10-02; first release 4.6.0), and from its first version its lookup reads the end increment. lookup("one of ") returns [] with a StopFilter query analyzer and [one_, onedirection, oneone] with SuggestStopFilter on 4.6.0, 4.10.4, 5.0.0, 5.5.5, 6.4.2, 6.5.0 and main.
Visible in AnalyzingSuggester, FuzzySuggester and the document suggester since 6.5.0: LUCENE-7619 (#8670; branch_6x 4e4ec082caa, 2017-01-17) made TokenStreamToAutomaton turn the end increment into trailing holes. On 6.4.2 even a StopFilter query analyzer returns [one direction, one of the best] from AnalyzingSuggester; from 6.5.0 on StopFilter narrows it and SuggestStopFilter does not. FuzzySuggester and the document suggester use the same TokenStreamToAutomaton; their effect was run on main only.
Not fixed upstream: since 2013 the file has had only non-functional commits (license header, imports, a 2021 reformat); in the full-history clone all 114 release tags from 4.5.0 to 10.5.2 contain one of the two LUCENE-3849 commits. The clone has no tag for 7.4.1, 7.5.1, 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0 to 8.11.3 and 8.11.4; 8.11.4 was run from its release jars and is affected.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | 4 of 4 repro tests fail (gradle and runner, assertions on and off) |
| 6.5.0, 6.6.6, 7.7.3, 8.11.4, 9.12.3, 10.5.2 | affected | end() 3/0, 1/0, 2/0 against StopFilter, and the extra AnalyzingSuggester suggestion (portable probes; FreeTextSuggester also on 6.5.0; the JUnit repro also fails on 9.12.3 and 10.5.2) |
| 4.6.0, 4.10.4, 5.0.0, 5.5.5, 6.4.2 | FreeTextSuggester | FreeTextSuggester lookup("one of "): [] with StopFilter, [one_, onedirection, oneone] with SuggestStopFilter (fact check); the wrong end() value (probed on 4.10.4, 5.5.5, 6.4.2); AnalyzingSuggester unchanged on 6.4.2 (same list for both filters; 4.x and 5.x analyzing lookup not run) |
| 4.5.0 | end() only | the same wrong end() value; no FreeTextSuggester yet, analyzing lookup not run |
4.4.0 + SuggestStopFilter before LUCENE-3849 vs + the LUCENE-3849 files | bisect | before: both filters agree (1/1); after: 3/0, 1/0, 2/0 as in 4.5.0 |
| 4.4.0 and earlier | no such class | the release has no SuggestStopFilter |
| main + fix A or fix B | not affected | all 240 tests of :lucene:suggest run with 0 failures (7 upstream skips), the 4 repro tests and the 2 new asserts included (fix A and fix B, assertions on and off) |
The finder, an independent reproducer, an intended-behaviour checker and an adjudication each ran tests on main: all said real. Reviews from another model family (OpenAI GPT-5.6) read the code; one agreed, one returned a procedural 'not real' because it could not run code. An audit kept it; this doc's gradle runs reproduced it and validated two fixes.
Checks and verdicts522 words
Every check executed code on main except the cross-model reviews, which only read code; separate runs re-ran the finder's test (fails on main; the intended-lens stage also passed it with the fix). The intended-lens review read main ea57360912ed, where these files are identical.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Sweep and exhaustive differential (4,686 of 11,718 differ, 0 with the fix); JUnit fails 2 of 2 on main (-ea, -da), 10.5.2 and 9.12.3; main() probe fails on 8.11.4; with the fix 46 upstream suggest tests pass. |
| refute review (OpenAI GPT-5.6, reading only) | procedural "not real", low | Could not run code; its own notes call the verdict 'not a substantive refutation'; root cause agrees, inputs in contract, intended argument moderate. A separate re-run of the finder's test failed 2 of 2. |
| independent reproducer | real | Own JUnit written from the claim fails 2 of 2 on main (-ea, -da), 10.5.2 and 9.12.3; controls agree; the same fix passes it, and 46 upstream suggest tests pass with and without the fix. Noted that the raw end() difference already happens with one stop word. |
| intended-lens review (OpenAI GPT-5.6, reading only) | real, high | 'Intended' argument moderate and rejected; root cause agrees, inputs in contract. Separate runs: the finder's test fails with -ea and -da and passes with the fix. |
| intended-behaviour checker | real, medium-high | Built the strongest intended case and refuted it (StopFilter equivalence, LUCENE-3849 issue text, the 2012 test comment); re-ran the repro on main (-ea, -da) and 10.5.2; TestAnalyzingInfixSuggester 23 of 23 pass with the fix; dated the suggester symptom to 6.5.0. |
| adjudication | confirmed, high | Re-ran the reproducer's JUnit at seed 5EED1234 (fails 2 of 2 with -ea and -da, passes with the fix); duplicate of nothing. |
| security screen | none, high | Probe over 3,108 queries on four suggester paths: the result with the bug equals the result for the text without its trailing stop words (0 mismatches); contexts and filters hold; found the exactFirst edge case and the one-word trigger on the document suggester. |
| credibility audit | keep | Re-ran the finder's test at seed C0FFEE42 (fails 2 of 2, -ea and -da); own probe confirms the one-word and preservePositionIncrements=false cases show no difference in AnalyzingSuggester; FuzzySuggester differs only on the larger probe dictionary. |
| this doc's gradle runs | reproduced; fixes A and B pass the module | Scratch worktree at a9779ef3c193, seed DEADBEEF: stock main fails the two repro classes 4 of 4 with assertions on and off, and the two new TestSuggestStopFilter asserts 2 of 6; with fix A (assertions on and off) or fix B (on) all 240 tests of :lucene:suggest pass. |
| fact checks of this doc (one by a reviewer from another model family, OpenAI GPT-5.6, reading only) | bug confirmed; text corrected | Both re-confirmed the bug, mechanism and fixes (the first re-ran gradle: 4 of 4 fail on main, fixes A and B pass the module with assertions on and off). Corrected here: FreeTextSuggester shows it since 4.6.0, the paste-ready command now sets -Ptests.asserts=true, preservePositionIncrements=false does not mask it, the release-tag coverage, and several wordings. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 466 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,275 words
- Registry title
- SuggestStopFilter.end() leaves out the positions of the stop words it removes at the end of the input (StopFilter counts them), so a suggester with SuggestStopFilter in its query analyzer returns extra suggestions for text that ends in removed stop words and a space (two or more stop words for AnalyzingSuggester and FuzzySuggester, one for the document suggester; wrong end() since 4.5.0, visible in suggesters since 6.5.0)
- Area
- suggest / SuggestStopFilter (query analysis of the analyzing and document suggesters)
- Priority
- Low, rank 440: SuggestStopFilter's wrong end() broadens as-you-type suggestions in its recommended setup on everyday input, but it affects suggestion quality only and clears at the next typed word.
- Impact class
- silent wrong results
- Impact note
- Applications that put SuggestStopFilter in a suggester's query analyzer (directly, through the suggestStop factory, or, by code reading, through a downstream stop filter with remove_trailing=false), which is the setup its javadoc recommends next to a StopFilter index analyzer, get a broader suggestion list whenever the typed text ends in removed stop words followed by a separator: two or more stop words for AnalyzingSuggester and FuzzySuggester (one is hidden by finalOffsetGapAsHole), one for the document suggester (PrefixCompletionQuery and FuzzyCompletionQuery); the extra entries are exactly the suggestions for the text without those stop words, except that in exactFirst mode an entry whose text equals the typed text, trailing space included, is dropped (or, with -ea, the lookup throws an AssertionError); AnalyzingInfixSuggester is not affected, preservePositionIncrements=false masks it, and no scale is needed. Low severity: suggestion quality only.
- Summary
- You build an AnalyzingSuggester over 'one direction' and 'one of the best' with a StopFilter index analyzer and a SuggestStopFilter query analyzer, as the SuggestStopFilter javadoc recommends, and look up 'one of the ' (the user has typed 'the' and a space). You expect what a StopFilter query analyzer gives, [one of the best], because the class is documented as 'Like StopFilter' except that it keeps an unterminated last stop word, and StopFilter adds the positions of removed trailing stop words to the final position increment in end(). Instead SuggestStopFilter.end() reports the input's own final increment (0 instead of 2), so the lookup automaton has too few trailing holes and the lookup also returns 'one direction'; the tokens and the final offset are correct.
- Introduced
- e005a580e9f856e1cdebc3bf3230768911c7105c (branch_4x, svn r1515909, LUCENE-3849 'position increments should be implemented by TokenStream.end()', apache/lucene#4922, committed by mikemccand; the commit that shipped in 4.5.0) and its trunk twin 2a5421ca685b7341bbead24975cd218cbcaf34f7 (svn r1515887, first released in 6.0.0; git blame on main credits it with the SuggestStopFilter lines). Both capture endState right after input.end() and restore it in end() without adding skippedPositions or the removed last stop word's increment, while the same commit made FilteringTokenFilter.end() (StopFilter) add skippedPositions [exec: 4.4.0 jars plus SuggestStopFilter at d5e99b1b959 (just before) agree with StopFilter; 4.4.0 jars plus the four files at e005a580e9f differ like 4.5.0]. The suggester-visible symptom starts with LUCENE-7619 (branch_6x 4e4ec082caa, trunk 637915b890d), which made TokenStreamToAutomaton turn the end() position increment into trailing holes [exec: 6.4.2 gives the same suggestions as a StopFilter query analyzer, 6.5.0 differs] (2013-08-20 (wrong end() increment, LUCENE-3849); 2017-01-17 (visible in suggesters, LUCENE-7619))
- First affected version
- 4.5.0 (wrong end() increment) [exec]; 6.5.0 for the suggester-visible extra suggestions [exec]
- Affected versions
- Every release from 4.5.0 to 10.5.2 (114 release tags) and main a9779ef3c193 (unreleased 11.0) [read: git tag --contains]. Executed: wrong end() increment on 4.5.0, 4.10.4, 5.5.5, 6.4.2, 6.5.0, 6.6.6, 7.7.3, 8.11.4, 9.12.3, 10.5.2 and main [exec]; extra suggestions on 6.5.0, 6.6.6, 7.7.3, 8.11.4, 9.12.3, 10.5.2 and main, not on 6.4.2 [exec]; JUnit fails on 9.12.3 and 10.5.2 (-ea) and on main (-ea and -da) [exec]. Not affected: 4.4.0 and earlier (no SuggestStopFilter) [exec, read]. Not fixed upstream: SuggestStopFilter.java has had only non-functional changes since 2013 (last a 2021 reformat) on main, branch_10x and branch_10_5 [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only; follow-up prior-report record verdict new): three scripted prior-report searches (142 queries over GitHub issues, PRs and commits, downstream repositories, dev@, java-user@, issues@ and commits@, the JIRA archive and 7 web queries), about 40 manual gh searches on apache/lucene, the changed files of all 406 open PRs, the commit history of SuggestStopFilter.java on main, branch_10x, branch_10_5 and branch_9x, and lists.apache.org including solr-user@. Closest prior art, none of it this bug: #4922 LUCENE-3849 (defines the end() trailing-hole contract; its commit edited SuggestStopFilter.end() without the skipped positions; never mentions SuggestStopFilter), #6229 LUCENE-5165 (adds the class; discusses only the unterminated last token), #9391 LUCENE-8344 (TokenStreamToAutomaton with preservePositionIncrements=false, other fix site), #4915 LUCENE-3842 (design history). Same family in other classes, each filed and fixed separately: LUCENE-5180 #6244, LUCENE-8360, LUCENE-8371 #9418, LUCENE-8650 #9696, #16577. Caveat: the GitHub search API rate-limited twice; blocked queries were retried or duplicated completed ones
- Lucene commit tested
- main
a9779ef3c193(gradle in a scratch worktree, assertions on and off, and the standalone JUnit runner with several seeds); the release jars 4.5.0, 4.10.4, 5.5.5, 6.4.2, 6.5.0, 6.6.6, 7.7.3, 8.11.4, 9.12.3 and 10.5.2; 4.4.0 with the class shadowed just before and just after LUCENE-3849 (commit isolation); theFreeTextSuggesterlookup on 4.6.0, 4.10.4, 5.0.0, 5.5.5, 6.4.2, 6.5.0 and main (fact check); fixes A and B with the whole:lucene:suggest:testtask (assertions on and off). JDK 25.0.3, Linux aarch64.
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/SuggestStopFilter.java:29-37 (at a9779ef3c193) (class javadoc: 'Like StopFilter except it will not remove the last token if that token was not followed by some token separator'; StopFilter in the indexAnalyzer, this class in the queryAnalyzer of the analyzing suggesters), :61-71 (end() restores endState only), :73-118 (incrementToken: skippedPositions carried mid-stream; on the separator branch clearAttributes(); input.end(); endState = captureState(); return false, without the skipped positions)lucene/core/src/java/org/apache/lucene/analysis/FilteringTokenFilter.java:70-75 (at a9779ef3c193) (StopFilter's end(): super.end() then posInc + skippedPositions)lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:152-154 (at a9779ef3c193) ('any skipped positions (such as those removed by a stopfilter) can be applied to the position increment')lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:212-241 (at a9779ef3c193) (end() posInc becomes trailing HOLE arcs; finalOffsetGapAsHole maps 0 to 1 when the final offset passes the last token)lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:317-322 (at a9779ef3c193) (setFinalOffsetGapAsHole(true)), :800-810 (exactFirst: assert results.size() == 1 on a same-surface-form path)
- The finding in 30 seconds
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/SuggestStopFilter.java:29-37 (at a9779ef3c193) (class javadoc), :61-71 (end()), :73-118 (incrementToken; :83 skippedPositions, :92 mid-stream, :94-102 separator branch, :114)lucene/core/src/java/org/apache/lucene/analysis/FilteringTokenFilter.java:72-75; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:152-154lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:212-241 (at a9779ef3c193) (trailing holes; :214-216 finalOffsetGapAsHole), :271-299 (addHoles)lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:268-307 (at a9779ef3c193) (replaceSep: HOLE becomes epsilon, POS_SEP becomes SEP_LABEL), :317-322 (setFinalOffsetGapAsHole(true))lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java:233-244; (at a9779ef3c193) lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestSuggestStopFilter.java:85-102 (testMultipleStopWords, +4)
- Who is affected
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/SuggestStopFilterFactory.java:73 (at a9779ef3c193) (NAME = suggestStop); AnalyzingSuggester.java:180-192 (default options), :799-811 (exactFirst, assert at :808)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/PrefixCompletionQuery.java:73-76; (at a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenateGraphFilter.java:233-244lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:474-541 (at a9779ef3c193) (end(), endPosInc, hole-only predictions skipped); SuggestStopFilter.java:38 (public final class), :83-102; lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:214-218 (preservePositionIncrements=false drops a positive end increment, finalOffsetGapAsHole still adds 1)
- Why it looks unintended
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/SuggestStopFilter.java:29-37, (at a9779ef3c193) :92, :114lucene/core/src/java/org/apache/lucene/analysis/FilteringTokenFilter.java:72-75; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:152-154; lucene/core/src/test/org/apache/lucene/analysis/TestStopFilter.java:172-189lucene/CHANGES.txt:13275-13280 (at a9779ef3c193) (LUCENE-5165), :13337-13340 (LUCENE-3849), :8407-8410 (LUCENE-7619)lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestSuggestStopFilter.java:47-64, (at a9779ef3c193) :85-102, :123-140; lucene/test-framework/src/java/org/apache/lucene/tests/analysis/BaseTokenStreamTestCase.java:474-528 (the overload these tests use delegates with finalPosInc null at :522); lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestAnalyzingSuggester.java:900-902
- Suggested fix
SECURITY.md line 38
- TestSuggestStopFilterTrailingHoles.java (JUnit test):
repro/LFV-583/src/org/apache/lucene/search/suggest/analyzing/TestSuggestStopFilterTrailingHoles.java(41 lines)
A step-by-step picture of the repro's example, made in parallel with this doc.
assets/LFV-583/bug.png(466 KB)