When a word of a quoted phrase has a single-word synonym, QueryBuilder builds a MultiPhraseQuery through a method that never reads token boosts, so every boost of the phrase is lost. Plain phrases and phrases with multi-word synonyms keep them.
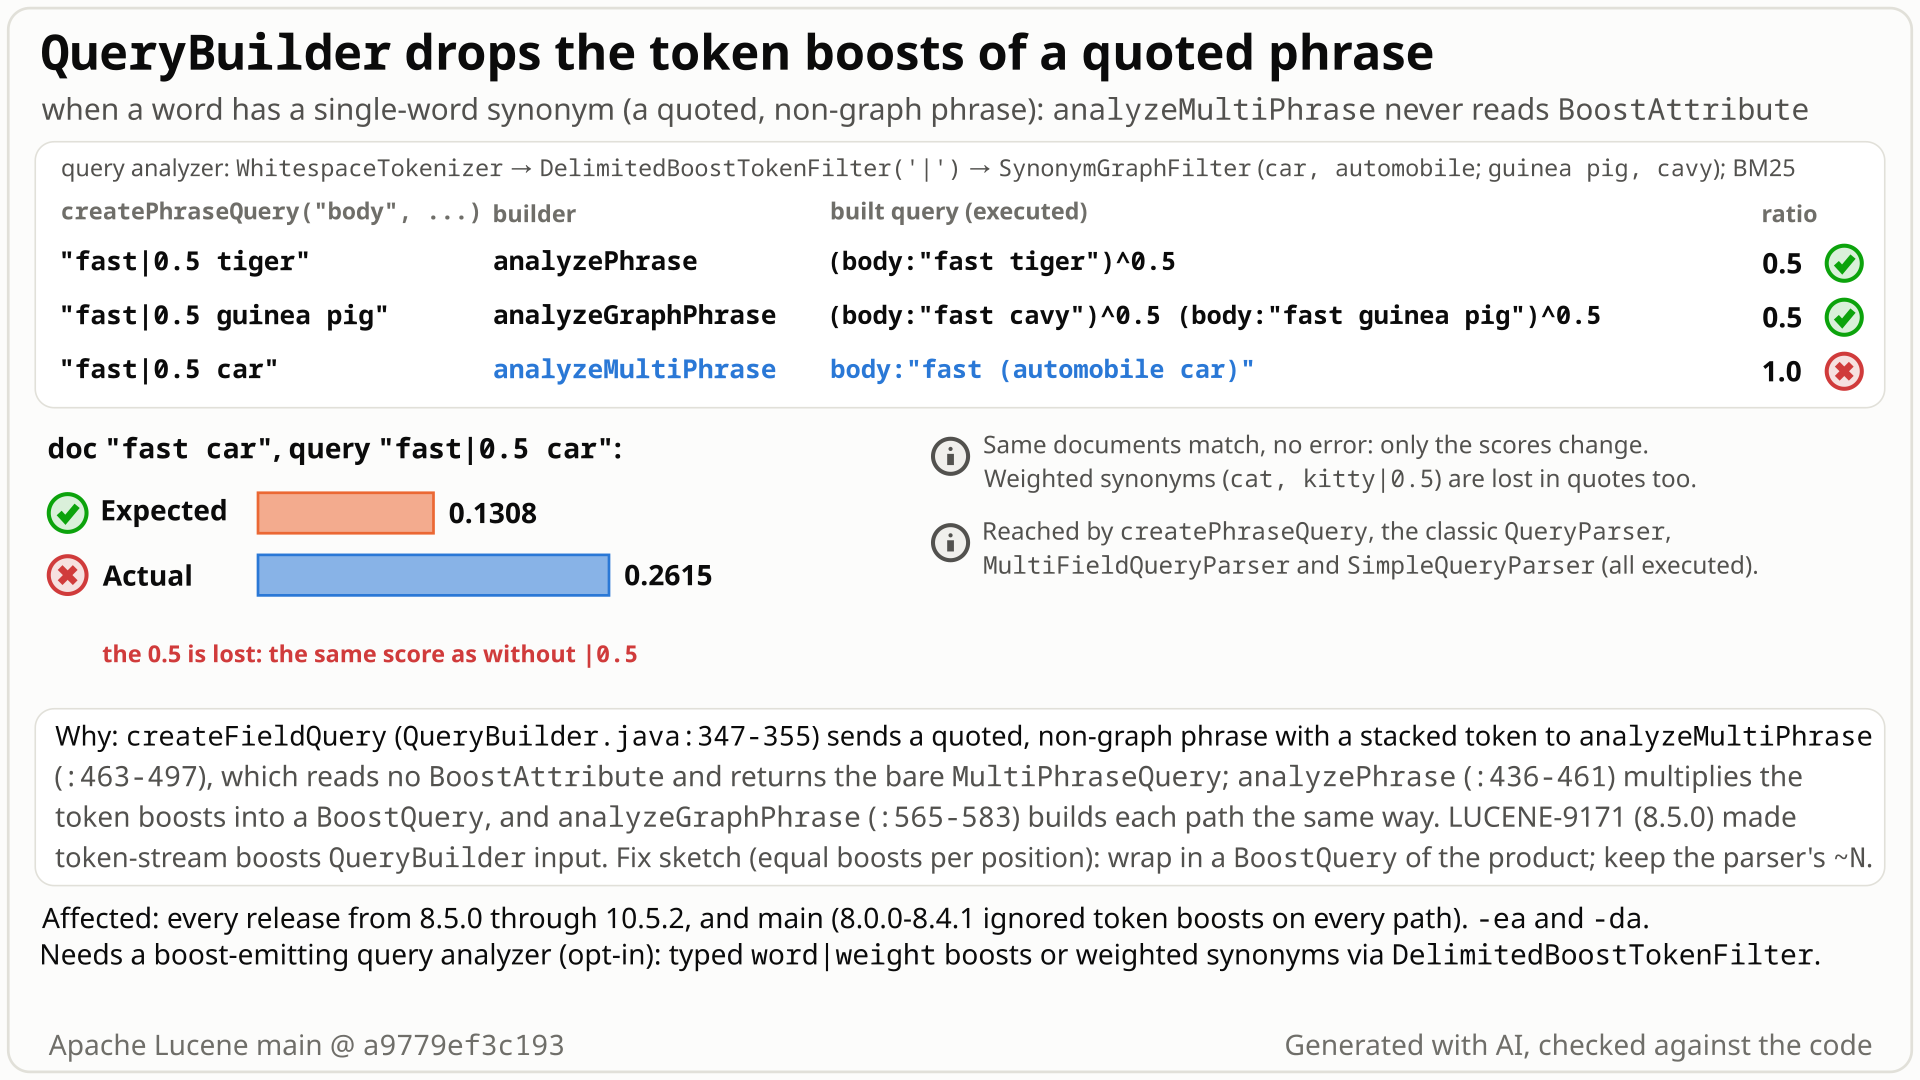
fast in three quoted phrases: the plain phrase and the multi-word-synonym phrase keep it, the phrase where car has the single-word synonym automobile loses it and scores 0.2615 instead of 0.1308. Select the still to open it at full size. Generated with AI, checked against the code.- Your query analyzer turns
word|weightinto a token boost (the stockDelimitedBoostTokenFilter) and knows the synonymcar, automobile. You search the quoted phrase"fast|0.5 car"withQueryBuilder.createPhraseQueryor the classicQueryParser. - You expect half the score of
"fast car", as without a synonym:"fast|0.5 tiger"becomes(body:"fast tiger")^0.5and scores 0.1308 instead of 0.2615. - Instead
carhas a stacked synonym, soQueryBuilderbuilds aMultiPhraseQueryinanalyzeMultiPhrase, which never reads the boost:body:"fast (automobile car)"scores 0.2615, as if you had typed no boost. - Weighted synonyms are lost the same way: with
cat, kitty|0.5the unquotedcat foodranks the documentkitty foodlower (0.2867 vs 0.3979), but the quoted"cat food"scores both 0.7130. - No error, and the matching documents do not change. Every release from 8.5.0 to 10.6.0 (10.6.0 by reading) and main is affected.
Applications whose query analyzer emits token boosts through the stock DelimitedBoostTokenFilter (weighted synonyms, or typed word|weight) and that build phrases with QueryBuilder or the classic, multi-field or simple query parser. Every quoted phrase in which a word has a single-word synonym is hit, deterministically. Ranking only; the boosting analyzer is opt-in.
Mechanism, terms and numbers739 words
Since 8.5.0 (LUCENE-9171) QueryBuilder reads the BoostAttribute of query tokens, which the stock DelimitedBoostTokenFilter sets from word|weight input, so typed boosts and weighted synonyms such as cat, kitty|0.5 reach the parsed query. For a phrase it multiplies the token boosts: "fast|0.5 tiger" becomes (body:"fast tiger")^0.5, and a phrase with a multi-word synonym becomes one boosted query per path. But when a quoted phrase analyzes to more than one position with a stacked token (a word with a single-word synonym) and no token graph (no multi-word synonym), createFieldQuery builds a MultiPhraseQuery in analyzeMultiPhrase, which never reads BoostAttribute, and every boost of the phrase is silently dropped: "fast|0.5 car" with car, automobile becomes the unboosted body:"fast (automobile car)" and scores 0.2615 instead of 0.1308, and with cat, kitty|0.5 the quoted "cat food" scores kitty food the same as cat food (0.7130 both), although the unquoted query ranks it lower. The classic QueryParser shows the same. The bug changes no match set (a boost only scales scores); only scores and ranking are wrong. Every release from 8.5.0 to 10.6.0 (10.6.0 by reading) and main; the boost-emitting query analyzer is an opt-in choice. A 28-line fix (boost the MultiPhraseQuery like analyzePhrase does, and let the classic parser's explicit-slop rewrite look inside the BoostQuery) fixes the lost boost; the closest suites pass, and only the weighted-synonym test still fails, which this fix leaves to an expansion or a javadoc note by design.
- Token boost: a weight attached to one query token through
BoostAttribute. The stockDelimitedBoostTokenFilter(SPI namedelimitedBoost) sets it fromword|weightand strips the suffix:fast|0.5becomes the tokenfastwith boost 0.5. With a synonym file such ascat, kitty|0.5placed before it in the chain, it gives weighted synonyms. - Single-word synonym:
car, automobileaddsautomobileat the same position ascar(position increment 0, a stacked token). A multi-word synonym such asguinea pig, cavymakes a token graph instead. - QueryBuilder: turns analyzed query text into a
Query. The classicQueryParser,MultiFieldQueryParserandSimpleQueryParserbuild their queries through it. For a quoted phrase it picks one of three builders:analyzePhrase(no stacked token),analyzeGraphPhrase(a token graph) oranalyzeMultiPhrase(a stacked token and no graph).
createFieldQuerymarkshasSynonymswhen a token has position increment 0 and sends a quoted, non-graph phrase with such a token toanalyzeMultiPhrase, any other quoted, non-graph phrase toanalyzePhrase(QueryBuilder.java:347-355).analyzePhrasemultiplies the token boosts,phraseBoost *= boostAtt.getBoost(), and returnsnew BoostQuery(query, phraseBoost)when the product is not 1 (:436-461).analyzeGraphPhrasesends each path of the graph back throughcreateFieldQuery, so a path of several tokens is built byanalyzePhraseand keeps its product, and a one-token path is built byanalyzeTerm, which reads the boost too (:565-583).analyzeMultiPhrasecollects the terms of each position into aMultiPhraseQueryand returns it as is; it never adds or readsBoostAttribute(:463-497). Every otheranalyze*method reads it, directly or (foranalyzeGraphPhrase) through the builders it calls.- So whether a boost survives depends on the builder: in practice, on whether some word of the phrase has a single-word synonym (and none a multi-word one). Two cases: (a) a boost on a word without a synonym is lost because another word has one, the clear-cut case; (b) weighted single-word synonyms are ignored inside quotes, weaker because
MultiPhraseQueryhas no per-term weights. - A boost only scales scores, so the matched documents are the same: on 14,376 multi-phrase-path queries (main with and without assertions, 10.5.2) the match sets never differed and 6,461 scores did (executed).
Stock WhitespaceTokenizer, DelimitedBoostTokenFilter and SynonymGraphFilter, BM25, small indexes:
- No synonym:
"fast tiger"givesbody:"fast tiger", score 0.2615;"fast|0.5 tiger"gives(body:"fast tiger")^0.5, score 0.1308. - Multi-word synonym
guinea pig, cavy:"fast|0.5 guinea pig"gives(body:"fast cavy")^0.5 (body:"fast guinea pig")^0.5, half the score of the unboosted phrase. - Single-word synonym
car, automobile:"fast|0.5 car"givesbody:"fast (automobile car)", score 0.2615 (expected 0.1308). - Weighted synonym
cat, kitty|0.5, unquotedcat food:Synonym(body:cat body:kitty^0.5) body:food,cat food0.3979 andkitty food0.2867. - Quoted
"cat food":body:"(kitty cat) food", both documents 0.7130. - Classic
QueryParserwithtv => television|0.9:"tv food"gives(body:"television food")^0.9, but"tv car"givesbody:"television (automobile car)", without the 0.9.
Exposure and likelihood199 words
- Who. Users of
QueryBuilder.createPhraseQuery, of quoted phrases in the classicQueryParser(executed) and inMultiFieldQueryParserandSimpleQueryParser(executed by the fact check), or ofautoGeneratePhraseQueries, whose query-time analyzer sets token boosts. The only stock token-stream producer ofBoostAttributeisDelimitedBoostTokenFilter: weighted synonyms from the synonym file, or user-typedword|weightwhen the tokenizer keeps the delimiter. - When. Every quoted (or auto-generated) phrase that analyzes to more than one position with a stacked token and no token graph (in practice: some word has a single-word synonym and none a multi-word one), deterministically. A single-word synonym such as
car, automobileis an ordinary synonym-file entry. - Effect. Silent wrong scores and ranking: the phrase's typed boosts and synonym weights are ignored. The matched documents are unchanged, so filters, deny rules and counts built from such a query are not affected; an application that drops hits below a score threshold can still show a different result list. No error.
- Default vs opt-in. Default writer, codec, similarity, searcher and parsers; the boost-emitting query analyzer is an opt-in choice.
- Scale. None needed: one document and one phrase show it.
- In practice a low-severity ranking defect; the searches found no report since 8.5.0 (2020).
The test shows that QueryBuilder.createPhraseQuery drops the token boost of a phrase once one of its words has a single-word synonym: "fast|0.5 car" with the synonym car -> automobile builds an unboosted MultiPhraseQuery, while "fast|0.5 tiger" gives (body:"fast tiger")^0.5.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.util;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.boost.DelimitedBoostTokenFilter;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.analysis.synonym.SynonymGraphFilter;
import org.apache.lucene.analysis.synonym.SynonymMap;
import org.apache.lucene.search.BoostQuery;
import org.apache.lucene.search.Query;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestQueryBuilderMultiPhraseBoost extends LuceneTestCase {

  public void testPhraseBoostKeptWhenAWordHasASynonym() throws Exception {
    SynonymMap.Builder synonyms = new SynonymMap.Builder();
    synonyms.add(new CharsRef("car"), new CharsRef("automobile"), true);
    SynonymMap map = synonyms.build();
    Analyzer analyzer =
        new Analyzer() {
          @Override
          protected TokenStreamComponents createComponents(String fieldName) {
            Tokenizer tokenizer = new WhitespaceTokenizer();
            return new TokenStreamComponents(
                tokenizer,
                new SynonymGraphFilter(new DelimitedBoostTokenFilter(tokenizer, '|'), map, true));
          }
        };
    Query q = new QueryBuilder(analyzer).createPhraseQuery("body", "fast|0.5 car");
    // "fast|0.5 tiger" gives (body:"fast tiger")^0.5; expected boost 0.5 here too, got 1.0
    assertEquals(q.toString(), 0.5f, q instanceof BoostQuery bq ? bq.getBoost() : 1f, 0f);
  }
}
# in a copy of this finding's repro folder (repro/LFV-584/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.util.TestQueryBuilderMultiPhraseBoost
- Expected vs actual
- Expected boost 0.5; actual 1.0 (
body:"fast (automobile car)" expected:<0.5> but was:<1.0>), with-eaand-da.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: body:"fast (automobile car)" expected:<0.5> but was:<1.0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:577)
org.apache.lucene.util.TestQueryBuilderMultiPhraseBoost.testPhraseBoostKeptWhenAWordHasASynonym(TestQueryBuilderMultiPhraseBoost.java:47)- LUCENE-9171 (8.5.0) made
QueryBuilderapply token boosts to parsed queries; plain and graph phrases multiply them. - The boost on
fastis kept in"fast tiger"and"fast guinea pig"but dropped in"fast car", only becausecarhas a single-word synonym. - The change that added the feature skipped only
analyzeMultiPhrase; no test, doc or discussion calls that a choice.
The full argument238 words
- The contract. CHANGES 8.5.0, LUCENE-9171: "QueryBuilder can now use BoostAttributes on input token streams to selectively boost particular terms or synonyms in parsed queries" (
CHANGES.txt:5948-5949). - QueryBuilder's own rule.
analyzePhrasemultiplies the token boosts and graph phrases keep them per path; the same boosted token is honoured or dropped depending only on whether an unrelated word has a single-word synonym ("tv food"keeps^0.9,"tv car"drops it, executed through the classic parser). - The feature author meant phrases. In the review of apache/lucene-solr#357, a reviewer (romseygeek) wrote "we need to combine boosts together somehow; currently your phrase boost is just the boost of the last term in the phrase", and the author (alessandrobenedetti) answered "I implemented a simple multiplicative boost ... it's also compatible in not synonym cases, if the user needs a boost per token in phrase and span queries".
MultiPhraseQueryis never mentioned in that PR, in LUCENE-9171 (#10211) or in SOLR-12238. - History: an omission. Commit
663611c99c7addedBoostAttributehandling toanalyzeTerm,analyzeBoolean,analyzeMultiBoolean,analyzePhrase,analyzeGraphBooleanandcreateSpanQuery, but not to the olderanalyzeMultiPhrase(2013/2015), which has had no boost-related change since. - Tests. The only upstream test of token-stream boosts through
QueryBuilder,TestQueryBuilder#testTokenStreamBoosts, coverscreateBooleanQueryonly (TestDelimitedBoostTokenFiltertests the filter's own output); no test asserts the unboostedMultiPhraseQuery. - Legal trigger. Public API, the stock
DelimitedBoostTokenFilterandSynonymGraphFilterin the documented order, the classic parser.
The devil's-advocate check481 words
The strongest case for "intended" (the works-as-designed reviewer, the intended-behaviour checker, the adjudication, and a committer's own words): BoostAttribute is @lucene.internal and its javadoc says it is "intended to be added only by the TermsEnum to itself in its constructor and consumed by the MultiTermQuery.RewriteMethod". A committer, rmuir, restated this in 2023 in the review of #12169 (the Word2VecSynonymFilter): "BoostAttribute is not for use in tokenstreams. it is for multitermquery." (review comment 1116841545, 2023-02-24); "This is wrong, wrong wrong. Remove any use of boostattribute outside of MultiTermQuery. It documents not to do this." (review comment 1121546026, 2023-03-01); "It is really important that this only be used by fuzzyquery, it is only for multitermquery. That's why it is documented as such." (issue comment 1467945170, 2023-03-14). The filter merged without setting it, and its author's follow-up, open #12433, proposes a separate token-stream boost attribute next to a renamed MultiTermQuery one. Further, createPhraseQuery's javadoc lists the query types it returns and promises nothing about boosts; the CHANGES entry only says "can now use"; LUCENE-9171 was scoped to term and synonym queries (a reviewer suggested to "leave the graph queries alone for the moment, as boosting there is more complex"); and MultiPhraseQuery cannot weight alternatives. So a maintainer may well answer that token streams should not set this attribute at all. A 2011 proposal, LUCENE-3130 (#4203), already said the multi-term synonym phrase case would need a decision ("possibly just punt for now").
Why it fails: the javadoc conflicts with the shipped feature. LUCENE-9171 made token-stream boosts documented QueryBuilder input (the CHANGES 8.5.0 entry), with a public SPI filter and a reference-guide recipe, and QueryBuilder still reads the attribute on every other path at a9779ef3c193. rmuir's statements argue against the feature as a whole, not for dropping boosts on one path only: while the feature ships, a boost kept on one path and dropped on another is a bug; if the maintainers would rather retire or move token-stream boosts (the direction of #12433), the report can point to that decision. The author stated the multiplicative rule is for "a boost per token in phrase and span queries", and the final commit applied it to plain and graph phrases despite the "leave graph alone" remark. No doc, test or discussion records the multi-phrase omission as a choice. For case (a) a BoostQuery around the MultiPhraseQuery expresses the rule exactly, so "MultiPhraseQuery cannot weight alternatives" does not apply. LUCENE-3130 predates the code by nine years and describes no implemented behaviour. For (b) the case for "intended" is stronger (the cross-model fact check rates it moderate): MultiPhraseQuery cannot weight alternatives, and taking the largest, averaging, expanding or rejecting differing weights are all different policies. Verdict: not intended. High confidence for (a); (b) may be treated upstream as an enhancement or a documentation note, so file (a) as the bug and offer (b) as fix-or-document.
Recommended Boost the MultiPhraseQuery by the product of the token boosts, and keep the explicit slop (validated)
Boost the MultiPhraseQuery like analyzePhrase does, by the product over positions of each position's largest token boost (+19/-2 in QueryBuilder), and let the classic parser apply an explicit ~N inside the BoostQuery (+9 in QueryParserBase). The lost boost is fixed and the closest suites pass, except the weighted-synonym test: weighted single-word synonyms inside quotes stay unweighted.
BoostAttribute boostAtt = stream.addAttribute(BoostAttribute.class);
float phraseBoost = DEFAULT_BOOST;
float positionBoost = Float.NEGATIVE_INFINITY;
// ... at each new position, after mpqb.add(...):
  phraseBoost *= positionBoost;
  positionBoost = Float.NEGATIVE_INFINITY;
// ... for every token:
  positionBoost = Math.max(positionBoost, boostAtt.getBoost());
// after the loop:
phraseBoost *= positionBoost;
Query query = mpqb.build();
return phraseBoost == DEFAULT_BOOST ? query : new BoostQuery(query, phraseBoost);
All options and trade-offs4 options · 1,121 words
One fix was applied in a scratch worktree at a9779ef3c193 and run through gradle; the hunt's expansion sketch was run by shadowing and through gradle; the other options were not run. Lead the PR with case (a); offer (b) as expansion or documentation.
Boost the MultiPhraseQuery by the product of the token boosts, and keep the explicit slop (validated) (recommended)
Part A, QueryBuilder.analyzeMultiPhrase: read BoostAttribute; each position contributes the largest boost of its stacked terms; the phrase boost is the product over positions; wrap the MultiPhraseQuery in a BoostQuery when it is not 1. When the terms at each position share one boost (typed boosts on words without synonyms, unweighted synonyms), this is exactly analyzePhrase's rule. Part B, QueryParserBase.getFieldQuery(String, String, int): the classic parser re-applies an explicit ~N only to a bare PhraseQuery or MultiPhraseQuery (QueryParserBase.java:420-432), so once part A wraps the phrase, "fast|0.5 car"~3 would lose the ~3 that stock keeps; part B adds a BoostQuery branch that applies the slop to the wrapped phrase, as MultiFieldQueryParser.applySlop has done since 9.6.0 (#12196). Part B also fixes an older, separate gap: a boosted plain phrase such as "fast|0.5 tiger"~3 loses its ~3 on stock (tracked separately in this hunt's list as the classic parser's explicit-slop bug). A maintainer may want part B as its own commit or issue. If that bug's own fix (pass the explicit slop into the analysis) lands first, part B is not needed. A PR also needs a CHANGES entry.
BoostAttribute boostAtt = stream.addAttribute(BoostAttribute.class);
float phraseBoost = DEFAULT_BOOST;
float positionBoost = Float.NEGATIVE_INFINITY;
// ... at each new position, after mpqb.add(...):
  phraseBoost *= positionBoost;
  positionBoost = Float.NEGATIVE_INFINITY;
// ... for every token:
  positionBoost = Math.max(positionBoost, boostAtt.getBoost());
// after the loop:
phraseBoost *= positionBoost;
Query query = mpqb.build();
return phraseBoost == DEFAULT_BOOST ? query : new BoostQuery(query, phraseBoost);
Trade-offs
- Match-neutral (a
BoostQueryonly scales scores) and cheap: one float per position, no extra clauses. No benchmark was run. It still changes the query object: its shape,toString,equals(so query-cache identity) and explanations; and a zero product gives a^0.0query, whichBoostQuery.rewriteturns into a constant-score one (BoostQuery.java:92-94). - Leaves (b): when the terms at one position carry different boosts, the largest counts, so
"cat food"withkitty|0.5still scores both documents 0.7130 (executed). The same holds for a typed boost on the word that has the synonym, when the boost filter runs before the synonym filter: the injected synonym gets the default boost 1, so"fast car|0.5"stays unboosted (executed). The chosen boost is at least the boost of every combination of alternatives; taking the largest is one policy among several (averaging, the exact expansion below, rejecting differing weights), and a maintainer may prefer another. - Behaviour change by design: boosted phrases with a single-word synonym score differently after the upgrade; part B also makes
"fast|0.5 tiger"~3keep its~3. - Zero, negative and non-finite token boosts on a word without a synonym now behave as on the plain-phrase path (executed):
fast|0gives^0.0,fast|-1andfast|NaNthrowIllegalArgumentExceptionfromBoostQuery, where stock silently drops them. On the word with the synonym (boost filter first) the largest boost of the position counts, so the synonym's default 1 hides a zero or negative boost:"fast car|0"and"fast car|-1"stay unboosted, where"fast tiger|0"gives^0.0and"fast tiger|-1"throws;"fast car|NaN"and"fast car|Infinity"still throw (executed).
What the checks validated
- Stock main
a9779ef3c193: core 1 of 3 fail (both controls pass), analysis-common 2 of 2, queryparser 3 of 3, with assertions on and off. - With the fix, assertions on and off: core 3 of 3 and queryparser 3 of 3 pass; analysis-common: case (a) passes, case (b) still fails, as designed.
- Closest suites with the fix (seed
DEADBEEF):TestQueryBuilder26 tests and the repro's 3, 0 failures; the analysis-commonboostandsynonympackages, 13 classes, 124 tests, 1 failure (case (b)); the wholelucene/queryparsermodule, 31 classes, 536 tests, 0 failures (1 test skipped by@Ignoreupstream); the UnifiedHighlighter tests, 7 classes, 439 tests, 0 failures. tidychanges nothing;ecjLint,checkGoogleJavaFormatandrenderJavadocoflucene/coreandlucene/queryparserpass; the diff applies cleanly toa9779ef3c193.- Probe on the main jars with the fix shadowed in:
"fast|0.5 car"gives(body:"fast (automobile car)")^0.5and 0.1308; the classic parser gives(body:"fast (automobile car)"~3)^0.5for"fast|0.5 car"~3. - Not run: other modules' suites, Solr, benchmarks.
Exact weights: expand into one boosted phrase per combination when the boosts at a position differ (the hunt's sketch) (validated by the checks)
Uniform positions as above; when the terms at a position carry different boosts, build a BooleanQuery of one boosted PhraseQuery per combination of alternatives, as analyzeGraphPhrase does per path. This also fixes (b): "cat food" with kitty|0.5 becomes (body:"kitty food")^0.5 body:"cat food" and scores cat food 0.3979 and kitty food 0.1990, the order of the unquoted query (executed).
Trade-offs
- The query grows with the product of the alternatives: 10 weighted words give 1,024 clauses, and 11 or more throw
TooManyClausesat the default limit, where the phrase parses today (executed). - With slop above 0 it matched a strict superset of today's documents in 14 of 4,809 probe cases; the three printed ones are sloppy and each repeats a term across positions (executed).
- The classic parser's explicit slop is lost for such phrases even with part B, because the result is a
BooleanQuery:"cat food"~3gives(body:"kitty food")^0.5 body:"cat food", where stock keeps~3(executed). The same gap exists today for graph phrases.
What the checks validated
Shadowed onto the main jars: the hunt's repro passes and upstream TestQueryBuilder passes 26 of 26. Through gradle with part B, assertions on: the doc's three tests pass (8 of 8, case (b) included), TestQueryBuilder 26 of 26, the analysis-common boost and synonym packages 124 of 124, and the whole lucene/queryparser module 536 tests with 0 failures.
Add to the createPhraseQuery (or analyzeMultiPhrase) javadoc that the terms stacked at one position of a phrase share one weight, so weighted single-word synonyms are not weighted inside quotes.
Trade-offs
Documentation only; pairs with the recommended fix and leaves (b) as a known limitation.
Set the parser's phrase slop to the explicit ~N around the analysis in getFieldQuery(String, String, int) and restore it afterwards, so QueryBuilder builds every phrase shape with the right slop. This is the fix proposed for the classic parser's explicit-slop bug tracked separately in this hunt's list.
Trade-offs
Also covers graph phrases and the expansion option; it changes two pinned TestQueryParser assertions, according to that bug's validation.
Downstream, Solr's standard and edismax parsers inherit this method unchanged and the Solr Reference Guide documents the weighted-synonym chain, while Elasticsearch's match query overrides it (both read in their source, not run).
A bounded-exhaustive check ran the real QueryBuilder against an independent reference model on every well-formed token stream of up to 3 tokens (position increments 0-2, position lengths 1-2, boosts 0.5, 1 and 2): 739,080 checks. No phrase built as a MultiPhraseQuery from boosted tokens kept its boosts (35,244 flagged checks); JUnit tests with stock filters confirmed it.
The method in full240 words
Method: bounded-exhaustive translation validation on the real jar (semi-formal tier), in a hunt unit on QueryBuilder reference semantics.
- Scope C: every well-formed token stream of at most 3 tokens over {a, b, c} (19,458 of 106,956 enumerated; the other 87,498 are ill-formed graphs and were skipped) with position increments 0-2, position lengths 1-2 and
BoostAttributevalues {0.5, 1, 2}, run through everyQueryBuilderentry point (Boolean, minimum-should-match and phrase queries at several slops) on the stock main jar and compared, structurally and by the matched documents, with an independent reference model: 739,080 checks in about 10 s. - A structural boost check flagged every
createPhraseQueryresult that is aMultiPhraseQuerywhile some token carries a boost other than 1: 35,244 checks at slop 0 (26,820 + 8,424), class MULTIPHRASE-BOOST-DROPPED. The check is structural, so it also counts streams whose boosts multiply to 1, where nothing is lost. Plain phrases, and graph phrases without a hole inside a multi-word synonym, kept their boosts. The run's other classes are not this bug: boosts or matches lost around a hole inside a multi-word synonym (the known upstream #9185 family) and anIllegalArgumentExceptionfromSynonymQuery, registered separately as LFV-588. - Then public-API JUnit tests on the stock jar with
SynonymGraphFilterandDelimitedBoostTokenFilterconfirmed it by scores. Found 2026-10-26 on maina9779ef3c193; then checked by an independent reproducer, an intended-behaviour devil's advocate, reading-only reviews by a model from another family (OpenAI GPT-5.6) and an adjudication.
No prior report found (2026-10-26: 89 tool queries, 39 manual GitHub and 13 JIRA searches, the mailing lists, the web, and all 406 open PRs). Closest: LUCENE-9171 and its PR, which added the feature without discussing this path, and LUCENE-3130 (2011), a proposal that predates the code.
Searches5 searches
Verdict new: 172 distinct tool hits over the two runs (41 and 167), 0 of high overlap, none the same bug. LUCENE-9171 (#10211) and apache/lucene-solr#357 introduced the feature and never mention analyzeMultiPhrase; LUCENE-3130 (#4203, open since 2011) said the multi-term synonym phrase case would need a decision ("possibly just punt for now"), nine years before the code, and does not cover a boost lost on a word without synonyms. Related, not this bug: #12169 (the Word2VecSynonymFilter PR, where a committer objected to any use of BoostAttribute in token streams; no phrase case; see the devil's advocate above), open #12433 (proposes a separate token-stream boost attribute and renames the MultiTermQuery one, QueryBuilder included; does not touch analyzeMultiPhrase), LUCENE-8943 / #9986 (MultiPhraseQuery IDF, not boosts). None of the open PRs that touch the files changes analyzeMultiPhrase. Keyword search cannot prove absence.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; Elasticsearch, OpenSearch and Solr repositories; dev@, java-user@, issues@ and commits@; the LUCENE JIRA archive | 2026-10-26 | the hunt's prior-report tool in two runs: the finder's (35 queries, 41 hits) and the follow-up's (54 queries, 167 hits) | 172 distinct hits, 0 of high overlap in either run; the introducing feature only |
| GitHub issues and PRs (apache/lucene, apache/lucene-solr, apache/solr, Elasticsearch, OpenSearch) | 2026-10-26 | 39 manual searches and 4 code searches | no report |
| Open apache/lucene PRs | 2026-10-26 | changed files of all 406 open PRs | #12295, #12433, #14262, #14716, #16851 and #16911 touch the files (#16911 only because it deletes branch_10x's files); none changes analyzeMultiPhrase |
| JIRA (SOLR, LUCENE) | 2026-10-26 | 13 manual JQL queries; SOLR-12238 (32 comments) and LUCENE-3130, -8652, -9823, -9283 read | no report |
| Mailing lists and the web | 2026-10-26 | java-user@, dev@, users@solr, solr-user@; 8 web searches; the Solr Reference Guide's weighted-synonym section | no report; the guide documents no phrase limitation |
Introduced in 8.5.0 by 663611c99c7 (LUCENE-9171 / SOLR-12238, merged 2020-02-24), which added token boosts to every QueryBuilder path except analyzeMultiPhrase. Executed: 8.0.0-8.4.1 ignore token boosts everywhere, so they are not affected; all 52 releases from 8.5.0 to 10.5.2 and main are.
Versions tested6 rows
Introduced by 663611c99c7 "[SOLR-12238] Synonym Queries boost (#357)" (apache/lucene-solr#357; SOLR-12238 and LUCENE-9171 = apache/lucene#10211), merged to master on 2020-02-24 and backported to branch_8x as 2752d50dd1d the same day; first released in 8.5.0. It made QueryBuilder read BoostAttribute in analyzeTerm, analyzeBoolean, analyzeMultiBoolean, analyzeGraphBoolean and createSpanQuery, made the analyzePhrase boost the product of the token boosts, and added DelimitedBoostTokenFilter. analyzeMultiPhrase dates from LUCENE-5261 (2013) and LUCENE-6401 (2015); git log -L shows 8 commits on it in total (6 after LUCENE-6401), none about boosts. Found by reading the history (git log -S, git log -L), not a bisect; the release sweep agrees.
On 8.x graph phrases were span queries (LUCENE-9207, which made them one boosted PhraseQuery per path, is 9.0-only), so the hunt's second test stops at its graph-phrase sanity check there; the portable test covers that case. Unfixed: upstream main a95c754ee00, branch_10_6 and branch_10x have the same analyzeMultiPhrase (read, 2026-10-26); re-checked on 2026-10-28 on upstream main 20ced71c1e6 (2026-10-27) and both branches: the method is byte-identical, and neither QueryBuilder.java nor QueryParserBase.java changed since a9779ef3c193.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the doc's tests via gradle: core 1 of 3, analysis-common 2 of 2, queryparser 3 of 3 fail, assertions on and off; the hunt's and the reproducer's tests fail too |
| 10.0.0 to 10.5.2 (12 releases) | affected | portable test: both controls pass, both bug tests fail; the hunt's test fails 2 of 2 on 10.0.0 and 10.5.2 |
| 9.0.0 to 9.12.3 (21 releases) | affected | portable test: same pattern; the hunt's test fails 2 of 2 on 9.0.0, 9.1.0 and 9.12.3 |
| 8.5.0 to 8.11.4 (19 releases) | first affected | portable test: same pattern and the same scores (0.2615 for "fast|0.5 car", 0.7130 both for "cat food") |
| 8.0.0 to 8.4.1 | not affected | QueryBuilder ignores token boosts on every path (both controls fail), so nothing is inconsistent |
recommended fix on a9779ef3c193 | fix | case (a) fixed (core 3 of 3, queryparser 3 of 3); case (b) left as designed |
An independent reproducer (3 of 5 fail, 2 controls pass), an intended-behaviour devil's advocate and a classic-parser test from the works-as-designed review reproduced it. Reading-only reviews by a model from another family (OpenAI GPT-5.6) agreed on the root cause. An adjudication confirmed it, and this doc's gradle runs reproduce it on a9779ef3c193.
Checks and verdicts431 words
Every executing check wrote or re-ran its own test on stock main; every control passed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Exhaustive check (739,080 cases); JUnit 2 of 2 fail with assertions on and off, on 10.5.2, 9.12.3, 9.0.0 and 8.5.0 (there test 2 stops at a sanity check); the fix sketch passes, with upstream TestQueryBuilder 26 of 26. |
| independent reproducer | real | Own test from the claim only (score ratio of boosted to unboosted query): 3 of 5 fail on main (assertions on and off), 10.5.2 and 9.12.3; both controls pass; the classic parser too. A diagnostic patch fixes case (a) and, as expected, not (b). |
| cross-model reviews (refute, intended) | not real (low, procedural); real (medium) | An independent reviewer from another model family (OpenAI GPT-5.6) reviewed by reading only, since it could not run Java. The refute lens called the report "technically credible" and agreed on the root cause; the intended lens rated the works-as-designed case moderate but outweighed by the sibling paths. A separate classic-parser test fails 1 of 1 ("tiger story" with tiger, tigre|0.9 gives f:"(tigre tiger) story"); a separate run re-ran the repro: 2 of 2 fail. |
| intended-behaviour devil's advocate | real (high for (a), medium overall) | Built the strongest intended case (@lucene.internal attribute, javadoc silence, scope of LUCENE-9171) and showed why it fails; read the introducing PR review; its reachability test through the classic parser and the SPI chain fails on main and 10.5.2. |
| adjudication | confirmed (high) | Re-ran the reproducer's test without assertions: 3 of 5 fail, controls pass. |
| Follow-up and registry re-runs | still reproduces | History on 60 releases plus main; a security probe (0 match-set differences in 14,376 queries); registry and audit re-runs on a9779ef3c193: the hunt's test 2 of 2 and the reproducer's 3 of 5 fail. |
| fact checks of this doc | reproduced; wording fixed | An independent fact check re-ran the doc's gradle commands on a clean a9779ef3c193 tree (stock and with the fix, assertions on and off) and its own probe: every query and score matched. It and a reading-only cross-model fact check (OpenAI GPT-5.6) found wording errors (a stale-javadoc claim, a commit count, scope and precision points), all fixed or answered; a diagram check found no errors. |
| this doc's gradle runs | reproduced; fix validated | Scratch worktree at a9779ef3c193, gradle: stock, the three tests fail (6 of 8 test methods; the 2 controls pass) with assertions on and off; with the fix, case (a) passes and the closest suites pass, (b) is left as designed. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 481 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,338 words
- Registry title
- QueryBuilder drops every token boost (BoostAttribute) from a quoted phrase as soon as one of its words has a single-word synonym, so typed word|weight boosts and weighted-synonym weights are silently ignored there, while plain phrases, graph phrases and unquoted queries keep them
- Area
- core / util QueryBuilder phrase building with token boosts (analyzeMultiPhrase; BoostAttribute from DelimitedBoostTokenFilter and weighted synonyms; reached through the classic, multi-field and simple query parsers)
- Priority
- Low, rank 374: Ranking-only, and only behind an opt-in boost-emitting query analyzer.
- Impact class
- silent wrong results
- Impact note
- Applications whose query-time analyzer emits token boosts through DelimitedBoostTokenFilter (weighted synonyms such as 'cat, kitty|0.5', the recipe in the Solr Reference Guide, or user-typed word|weight boosts) and that build phrases through QueryBuilder (createPhraseQuery, or quoted phrases in the classic QueryParser [exec], MultiFieldQueryParser and SimpleQueryParser [read], or autoGeneratePhraseQueries) get, for every phrase in which some word has a single-word synonym, an unboosted MultiPhraseQuery with no error: the same documents match, but the scores ignore all of the phrase's boosts; default writer, codec, similarity and searcher, but the boost-emitting analyzer is an opt-in choice; no scale needed; every release from 8.5.0 through 10.6.0 (10.6.0 by reading) and main.
- Summary
- You give a phrase a token boost, for example "fast|0.5 car" through DelimitedBoostTokenFilter, or use weighted synonyms such as 'cat, kitty|0.5', and expect the quoted phrase to keep the boost the way QueryBuilder's other paths do: "fast|0.5 tiger" becomes (body:"fast tiger")^0.5, and a multi-word weighted synonym gives one boosted phrase per path. But as soon as one word of the phrase has a single-word synonym ('car, automobile'), QueryBuilder builds a MultiPhraseQuery in analyzeMultiPhrase, which never reads BoostAttribute: "fast|0.5 car" becomes the unboosted body:"fast (automobile car)" (score 0.2615 instead of 0.1308), and the quoted "cat food" scores 'kitty food' the same as 'cat food' (0.7130 both), although the unquoted query ranks it lower. The matching documents are unchanged; only scores and ranking are wrong, and there is no error.
- Introduced
- 663611c99c7d48dd31d53ea17644fcecd5e0fad7 '[SOLR-12238] Synonym Queries boost (#357)' (apache/lucene-solr#357; SOLR-12238 and LUCENE-9171 = apache/lucene#10211; branch_8x backport 2752d50dd1dc) [read: git log -S BoostAttribute and git log -L on analyzeMultiPhrase, not a bisect; consistent with the executed release sweep: 8.4.1 not affected, 8.5.0 affected]. The commit added BoostAttribute handling to analyzeTerm, analyzeBoolean, analyzeMultiBoolean, analyzePhrase (phrase boost = product of the token boosts), analyzeGraphBoolean and createSpanQuery, but not to analyzeMultiPhrase, which dates from LUCENE-5261 (57f38e67d65, 2013) and LUCENE-6401 (3b8ea7b2e78, 2015) and has had no boost-related change since (2020-02-24)
- First affected version
- 8.5.0 [exec] (8.0.0 through 8.4.1 are not affected [exec]: QueryBuilder ignored BoostAttribute on every path then, so nothing was inconsistent; earlier releases [read])
- Affected versions
- 8.5.0 through 10.6.0 (10.6.0 by reading) and main [exec: all 52 releases from 8.5.0 to 10.5.2 (19 on 8.x, 21 on 9.x, 12 on 10.x) and main a9779ef3c193 fail the portable 5-test JUnit with both controls passing; the finder's registered repro fails on 8.5.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da; on 8.x its second test stops at a graph-phrase sanity assertion because 8.x builds span queries for graph phrases, and the portable test covers that manifestation there); the independent reproduction's repro fails on main, 10.5.2 and 9.12.3, the intended-behaviour check's on main and 10.5.2]. Upstream main a95c754ee00, branch_10_6 and branch_10x [read: analyzeMultiPhrase unchanged, reads no BoostAttribute]. Not affected: 8.0.0 to 8.4.1 [exec]. All runs on JDK 25, not each release's own JDK.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only; follow-up prior-report record verdict new): a scripted prior-report search in two runs (the finder's 35 queries; the follow-up's 54: 16 GitHub issue and PR, 3 commit, 5 downstream, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 LUCENE JIRA; 167 distinct hits, 0 high overlap), 39 manual GitHub issue and PR searches (28 in apache/lucene, 11 in elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr and apache/lucene-solr), 4 downstream code searches, 13 manual JQL queries over SOLR and LUCENE (SOLR-12238 read in full, 32 comments), manual searches of the java-user@, dev@, users@solr and solr-user@ archives, 8 web searches, and the changed-file lists of all 406 open apache/lucene PRs (#12295, #12433, #14262, #14716 and #16851 touch the files; none changes analyzeMultiPhrase); plus the independent reproduction's, the intended-behaviour check's and the adjudication's own searches (0 hits). Related, none a report of this bug: LUCENE-9171 (#10211) and apache/lucene-solr#357, the feature that introduced it (analyzeMultiPhrase never discussed); LUCENE-3130 (#4203, open since 2011), a pre-feature proposal whose description says the multi-term synonym phrase case would need a decision, 'possibly just punt for now'; #12169 (a committer's design objection to BoostAttribute outside MultiTermQuery, no phrase case); open #12433 (renames the attribute in QueryBuilder, does not touch analyzeMultiPhrase); LUCENE-8943 (#9986, MultiPhraseQuery IDF, not boosts). Gaps: GitHub search does not index PR diffs (closed unmerged PRs not scanned by file); GitHub's search rate limit was reached and rate-limited queries were re-run; one Stack Overflow how-to question could not be fetched
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): the doc's three public-API tests through gradle in a scratch worktree, stock and with the fix, assertions on and off, plusTestQueryBuilder, the analysis-common boost and synonym packages, the wholelucene/queryparsermodule and the UnifiedHighlighter tests with the fix (2026-10-28); probes on the main jars with each fix shadowed in. Hunt runs on maina9779ef3c193, the 10.5.2 and 9.12.3 jars and a portable test on 60 releases from 8.0.0 (8.5.0 to 10.5.2 affected, 8.0.0 to 8.4.1 not).
- Finding record
lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:347-355 (at a9779ef3c193) (createFieldQuery: a quoted, non-graph stream with a stacked token goes to analyzeMultiPhrase, otherwise to analyzePhrase)lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:436-461 (at a9779ef3c193) (analyzePhrase: reads BoostAttribute, phraseBoost *= each token's boost, returns BoostQuery(PhraseQuery, product) when it is not 1)lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:463-497 (at a9779ef3c193) (analyzeMultiPhrase: no BoostAttribute is added or read; returns the bare MultiPhraseQuery)lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:565-583 (at a9779ef3c193) (analyzeGraphPhrase: one phrase per path through createFieldQuery, so each path keeps its tokens' boosts)lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:100-135 (at a9779ef3c193) (createPhraseQuery javadoc: lists the returned query types only, says nothing about boosts)lucene/core/src/java/org/apache/lucene/search/BoostAttribute.java:31-34 (at a9779ef3c193) (javadoc 'intended to be added only by the TermsEnum'; @lucene.internal; stale since LUCENE-9171 made token-stream boosts QueryBuilder input)lucene/CHANGES.txt:5908 (at a9779ef3c193) and :5948 (8.5.0, LUCENE-9171: 'QueryBuilder can now use BoostAttributes on input token streams to selectively boost particular terms or synonyms in parsed queries')upstream: apache/lucene#10211 (LUCENE-9171), apache/lucene-solr#357 review comments discussion_r376473778 and discussion_r376513280, apache/lucene#4203 (LUCENE-3130) description, read-only
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:311-355 (createFieldQuery: hasSynonyms, routing to analyzeMultiPhrase or analyzePhrase); :436-461 (analyzePhrase); :463-497 (analyzeMultiPhrase); :565-583 (analyzeGraphPhrase); :371-434 (analyzeTerm, analyzeBoolean, analyzeMultiBoolean read BoostAttribute)lucene/analysis/common/src/java/org/apache/lucene/analysis/boost/DelimitedBoostTokenFilter.java:27-64
- Who is affected
lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:61, 405-411 (extends QueryBuilder; newFieldQuery calls createFieldQuery); simple/SimpleQueryParser.java:101 (extends QueryBuilder)
- Why it looks unintended
lucene/CHANGES.txt:5908, 5948-5949 (LUCENE-9171)lucene/core/src/java/org/apache/lucene/search/BoostAttribute.java:31-34; lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:111-135 (createPhraseQuery javadoc)lucene/core/src/test/org/apache/lucene/util/TestQueryBuilder.java:551-605 (MockBoostTokenFilter, testTokenStreamBoosts: createBooleanQuery only)apache/lucene#12169 review comments 1116841545 (2023-02-24) and 1121546026 (2023-03-01) and issue comment 1467945170 (2023-03-14), all by rmuir; #12433 (open) file list and diff; read-only GitHub API, 2026-10-28lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/ (no BoostAttribute; grep)lucene/analysis/common/src/test/org/apache/lucene/analysis/boost/TestDelimitedBoostTokenFilter.java (testBoosts: the filter's own output)
- Suggested fix
lucene/core/src/java/org/apache/lucene/search/BoostQuery.java:57, 75-94, 110 (equals, rewrite of a zero boost, toString)lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:420-432; lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/MultiFieldQueryParser.java:110-130 (applySlop unwraps BoostQuery)
- History
lucene/CHANGES.txt:5908, 5948-5949
- TestQueryBuilderMultiPhraseBoost.java (JUnit test):
repro/LFV-584/src/org/apache/lucene/util/TestQueryBuilderMultiPhraseBoost.java(49 lines)
Made in parallel with this doc from a probe on main a9779ef3c193 (assertions on and off, 10.5.2, and with the hunt's fix sketch shadowed in); the values on screen come from the probe's log. Its analyzer puts the boost filter before the synonym filter, like the doc's stock-filter test for case (a). The PNG is the final summary frame.
assets/LFV-584/bug.png(481 KB)