highlight(topDocs, q1, q2) runs one MatchRegionRetriever per query, and each loads from stored fields only the fields its own query touches. A document keeps the field values of the first query only; later queries add match ranges but no values, and only fields with values are formatted.
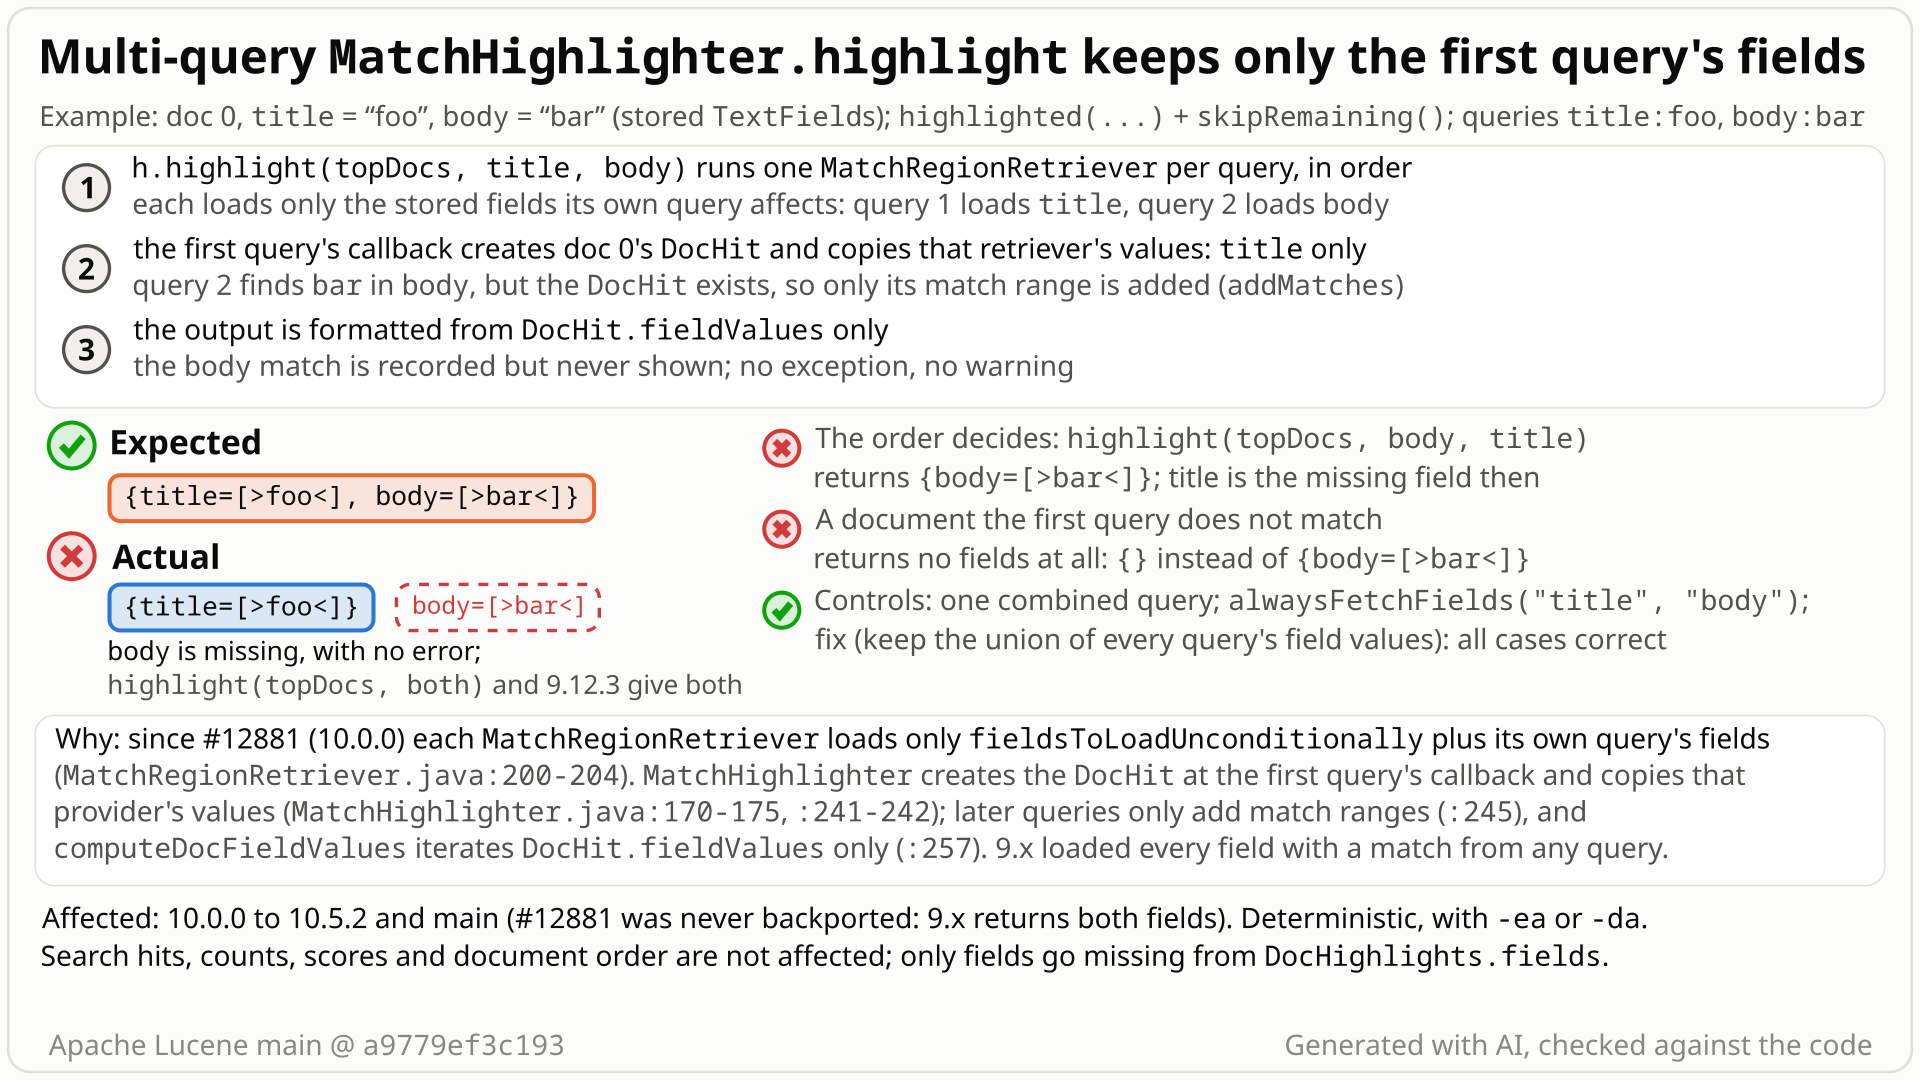
title: foo and body: bar, the combined query that highlights both fields, then the two queries with one retriever each, the first query's values copied into the document, the body match that is not kept, and the swapped order. Select the still to open it at full size. Generated with AI, checked against the code.- You index one document with two stored text fields,
title: fooandbody: bar, and searchtitle:foo OR body:bar: 1 hit. - You highlight the hit with
MatchHighlighter, passing the two clauses as separate queries,highlight(topDocs, title:foo, body:bar), so that each query can get its own markers, as the class's own test does. - You expect both fields, exactly as the combined query gives them:
{title=[>foo<], body=[>bar<]}. Lucene 9.x returns that for the separate queries too. - Instead you get
{title=[>foo<]}, with no error; with the queries swapped,{body=[>bar<]}. With a second document{title: baz, body: bar}in the index, that document comes back with no fields at all:{}. - Why: each query loads from stored fields only the fields it touches, and each document keeps only the first query's values. The second query loads
bodyand findsbar, but that value is dropped, sobodyis never formatted.
Applications that pass two or more queries on different fields to MatchHighlighter.highlight(TopDocs, Query...), such as a title clause and a body clause with their own markers. Default settings, any index size, deterministic. Hidden for always-fetched fields. Hits, counts and scores are unaffected. Rare: the package is little used.
Mechanism, terms and numbers610 words
MatchHighlighter.highlight(TopDocs, Query...) highlights several queries over the same hits, for example the title and body clauses of a search, so that each query can get its own markers. It runs one MatchRegionRetriever per query (9.x did too); since 10.0.0 each retriever loads from stored fields only the always-fetched fields plus the fields its own query touches. Each document's DocHit is created by the first query's callback and copies that query's field values only; later queries add their match ranges but not their values, and the output is built from the values alone. So a field that only the second or a later query matches is silently missing from DocHighlights.fields (unless it is always fetched or the first query also touches it), the result depends on the order of the queries, and a document that the first query does not match can come back with no fields. Hits, counts and scores are unaffected. 9.x loaded every field that any query matched. Introduced by #12881 (755de5aae33, 2023-12-07), first released in 10.0.0, unfixed through 10.6.0 (10.6.0 by reading) and main; the fix keeps the union of the values every query loaded (+12/-1).
MatchHighlighter: the highlighter of thematchhighlightpackage, built on the Matches API.highlight(TopDocs, Query...)returns oneDocHighlightsper hit, a map from field name to formatted values, built by a chain of field highlighters such asFieldValueHighlighters.highlighted(...)(format a field that has matches) andskipRemaining()(omit the rest).- Several queries at once: you pass the clauses of the search query separately,
highlight(topDocs, q1, q2); every match range remembers its query (QueryOffsetRange.query), so a custom formatter can give each query its own markers. The class's own test does this with the sub-clauses of its search query. MatchRegionRetriever: runs one query over the hits, reads each hit's stored fields and computes the match ranges per field. It hands each document to a callback together with aFieldValueProvider, the field values it loaded.
highlightbuilds one retriever per query, withfieldsToLoadUnconditionally = fieldsAlwaysReturned::contains(MatchHighlighter.java:211,:224-231); 9.x had the same loop.- Each retriever loads a stored field only if it is always-fetched or one of the fields its own query visits (
MatchRegionRetriever.java:180-192,:200-204). It reads the stored document of every hit, matched or not (:357-376), and calls the callback for each (:382-388). - The first query's callback finds no
DocHityet and creates one,new DocHit(docId, fieldValueProvider)(MatchHighlighter.java:240-244); the constructor copies that provider's fields (:170-175). - Every callback then calls
docHit.addMatches(q, hits)(:245,:177-184): later queries add their ranges, and their providers' values are dropped. computeDocFieldValuesiteratesdocHit.fieldValuesonly (:257).body's ranges frombody:barsit inmatchRanges, butbodyhas no values, so no field highlighter is ever asked about it.
Before #12881 (9.x), DocHit loaded the document once, after all queries, with a visitor that accepted matchRanges.containsKey(field) || needsField.test(field): every field that any query matched.
Doc 0 {title: foo, body: bar}, doc 1 {title: baz, body: bar}, queries title:foo and body:bar, the stock highlighted then skipRemaining chain:
| call | doc 0 | doc 1 | fields |
|---|---|---|---|
highlight(topDocs, title:foo OR body:bar) | {body=[>bar<], title=[>foo<]} | {body=[>bar<]} | 3 of 3 |
highlight(topDocs, title:foo, body:bar) | {title=[>foo<]} | {} | 1 of 3 |
highlight(topDocs, body:bar, title:foo) | {body=[>bar<]} | {body=[>bar<]} | 2 of 3 |
An executed probe drove the second query's own retriever: for doc 0 it reports loaded=[body] and hits={body=[[from=0, to=3]]}. The second query loads the field and finds the match; MatchHighlighter keeps the match range but drops the loaded value, so the range is never used.
Exposure and likelihood350 words
- Who. Applications that call
MatchHighlighter.highlight(TopDocs, Query...)with two or more queries that touch different fields, for example the title and body clauses of the search query passed separately to tell their markers apart (the pattern of the class's own test). Fields with offsets in postings and positions-only fields are both hit (executed). - Default vs opt-in.
MatchHighlighteritself is opt-in; nothing else needs a non-default setting: default codec,IndexWriterConfig, searcher and the stockFieldValueHighlighters. - Hidden when. The field is always fetched:
alwaysFetchFields(...), or amaxLeadingCharactersorverbatimValuehighlighter in the chain that covers it (theiralwaysFetchedFieldsare added to the always-fetched set); or the first query also touches that field. Queries on the same field are correct (executed controls). - Effect. Silent missing highlight fields; the result depends on the argument order; a document that the first query does not match can come back with no fields.
highlightonly readstopDocs, so hits, counts and scores do not change (read from the code). A bounded probe (64 documents, 3 fields, 400 ordered lists of 2 or 3 queries, 4 stock highlighter chains, one segment; 9,600 highlight calls, 187,200 document comparisons, with and without assertions) only ever found fields missing: never a field beyond the combined query's, a value different from the same separate queries with every field force-loaded, or a changed document order. It did not check scores. - Scale. Deterministic, any index size, one document is enough. In the hunt's bounded-exhaustive model, "separate queries give the same fields as their disjunction" failed in 12,221 of 20,130 document comparisons at the small scope (183 documents) and in 136,554 and 132,594 of 180,510 at the full scope (1,641 documents, two position gaps).
- How likely. Rare: the package is far less used than the UnifiedHighlighter (code search found it in none of Solr, Elasticsearch and OpenSearch), the multi-query form is a niche within it, and nothing has been reported since 10.0.0 (2024-10). The class's author wrote on dev@ in 2025-11 that they "use it with Solr a lot" and that "what was missing for me was highlighting multiple queries at once".
The test shows that MatchHighlighter.highlight(topDocs, title:foo, body:bar) on one document (title "foo", body "bar") drops the field that only the second query matches.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.matchhighlight;

import java.util.List;
import java.util.Map;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.search.TopDocs;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestMatchHighlighterMultiQueryFields extends LuceneTestCase {

  public void testLaterQueryOnAnotherFieldIsHighlighted() throws Exception {
    try (Analyzer analyzer = new StandardAnalyzer();
        Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
        Document doc = new Document();
        doc.add(new TextField("title", "foo", Field.Store.YES));
        doc.add(new TextField("body", "bar", Field.Store.YES));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        MatchHighlighter highlighter =
            new MatchHighlighter(searcher, analyzer)
                .appendFieldHighlighter(
                    FieldValueHighlighters.highlighted(
                        80, 1, new PassageFormatter("...", ">", "<"), _ -> true));
        TopDocs topDocs = searcher.search(new MatchAllDocsQuery(), 1);
        // expected: each query's field highlighted; actual on main: {title=[>foo<]}, body dropped
        assertEquals(
            Map.of("title", List.of(">foo<"), "body", List.of(">bar<")),
            highlighter
                .highlight(
                    topDocs,
                    new TermQuery(new Term("title", "foo")),
                    new TermQuery(new Term("body", "bar")))
                .findFirst()
                .orElseThrow()
                .fields);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-595/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/highlighter/build/libs/lucene-highlighter-$V.jar
CP=$CP:$LUCENE/lucene/memory/build/libs/lucene-memory-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.matchhighlight.TestMatchHighlighterMultiQueryFields
- Expected vs actual
- Expected:
{title=[>foo<], body=[>bar<]}; actual (-ea and -da):{title=[>foo<]}, because the DocHit keeps only the field values loaded by the first query's MatchRegionRetriever (MatchHighlighter.java:173, :242).
More files, environment, full output35 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<{title=[>foo<], body=[>bar<]}> but was:<{title=[>foo<]}>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.matchhighlight.TestMatchHighlighterMultiQueryFields.testLaterQueryOnAnotherFieldIsHighlighted(TestMatchHighlighterMultiQueryFields.java:58)- The method says it collects match ranges "for each query", and
highlightedformats fields "only if they contained query matches": the later query's ranges are collected, never shown. - A regression: 9.x loaded every field any query matched (9.0.0 to 9.12.3 pass); #12881 announced only performance changes.
- The result depends on query order, and dropping already-loaded values saves no reads.
The full argument280 words
- The method collects ranges for each query.
MatchHighlighter.java:223: "Collect match ranges for each query and associate each range to the origin query." - Field highlighter contract.
FieldValueHighlighters.highlighted: "Highlights fields matching predicatematchFieldsonly if they contained query matches" (FieldValueHighlighters.java:89).FieldValueHighlighter: highlighters "are probed whether they are applicable to a particular combination of (field, hasMatches) pair", withhasMatches"trueif the field has a non-empty set of match regions" (MatchHighlighter.java:53-67).bodyhas match regions and is never probed. - The class's own test uses the pattern. "Note the query passed to the highlighter are individual sub-clauses of the Boolean query used to fetch documents" (
TestMatchHighlighter.java:757-763);QueryOffsetRange.queryexists to tell the queries apart (MatchHighlighter.java:150-157). - Regression. 9.x loaded every field with matches from any query; 9.0.0, 9.9.0, 9.9.1, 9.10.0 and 9.12.3 pass (executed).
- No announced change. #12881's CHANGES entry (10.0.0 API Changes) and MIGRATE note describe performance work and "minor API changes"; its PR body, comments and reviews discuss performance only.
- Dropping the values saves no reads. The later query's retriever has already read the stored document and loaded the field before it is dropped, so dropping it saves no stored-field I/O. #12881's narrowing itself (each retriever loads only the fields its query affects) is real performance work, and the recommended fix keeps it.
- Order dependence.
highlight(topDocs, title, body)andhighlight(topDocs, body, title)return different fields for the same set of queries. - Author's intent. The class javadoc says "fully featured, ready-to-use component"; on dev@ (2025-11) its author wrote "This one - while not properly documented - is fully functional" and named highlighting multiple queries at once as what had been missing for them.
The devil's-advocate check219 words
The strongest works-as-designed case (the GPT intended-lens review and the devil's-advocate verifier): the class javadoc calls it "An example highlighter" and advises assembling your own from the building blocks; highlight(TopDocs, Query...) has no javadoc, so nothing promises that separate queries equal their disjunction; the only upstream multi-query test calls itself "interesting, if not always super-practical" and keeps both queries on one field; #12881 narrowed field loading on purpose ("so that stored fields of a document are accessed once"); and alwaysFetchFields exists.
Why it fails: the same javadoc sentence calls the class "fully featured, ready-to-use"; it is public and not @lucene.experimental. An order-dependent result for a varargs set of queries cannot be a specification. The narrowing is correct inside MatchRegionRetriever, whose FieldValueProvider documents which fields it exposes; the loss is only in MatchHighlighter's composition, which keeps the later query's ranges but drops the values that query already loaded. alwaysFetchFields is a workaround that loads the field for every hit and is nowhere documented as required. Every verifier judged the bug real and the adjudication confirmed it with high confidence.
What it does not settle: the contract is implied, not stated word for word, and maintainers could choose to document a restriction instead; the 9.x behaviour, the author's stated use case and the small fix make that unlikely.
Recommended Keep the union of every query's field values (validated)
Keep the union of the field values that every query's retriever loaded (putIfAbsent in DocHit, +12/-1). Validated with gradle: the repro passes with assertions on and off and over 10 iterations, and the whole highlighter module passes (724 tests). Field order then follows the queries; option B keeps stored order at extra loading cost.
    DocHit(int docId, MatchRegionRetriever.FieldValueProvider fieldValueProvider) {
      this.docId = docId;
      addFieldValues(fieldValueProvider);
    }

    void addFieldValues(MatchRegionRetriever.FieldValueProvider fieldValueProvider) {
      for (var fieldName : fieldValueProvider) {
        fieldValues.putIfAbsent(fieldName, fieldValueProvider.getValues(fieldName));
      }
    }
    // in highlight(): if (docHit == null) { ... } else { docHit.addFieldValues(fieldValueProvider); }
All options and trade-offs3 options · 739 words
Option A was applied in a scratch worktree at a9779ef3c193 and run through gradle; option B was run with shadowed sources on main; C was not run.
Workarounds today: call alwaysFetchFields(...) for every field the queries can highlight (it loads them for every hit, matched or not), or pass one combined query (which loses the per-query markers).
In MatchHighlighter, DocHit gets an addFieldValues(provider) that adds each loaded field with putIfAbsent; the constructor calls it, and the callback calls it for every later query that reaches an existing DocHit (+12/-1). It uses values every retriever has already loaded: no extra stored-field access, one putIfAbsent per loaded field per later query. All retrievers read the same stored document, so the kept values are identical, and the union is the field set a retriever for the combined query loads. A second diff adds the repro as a regression test; a PR also needs a CHANGES entry.
    DocHit(int docId, MatchRegionRetriever.FieldValueProvider fieldValueProvider) {
      this.docId = docId;
      addFieldValues(fieldValueProvider);
    }

    void addFieldValues(MatchRegionRetriever.FieldValueProvider fieldValueProvider) {
      for (var fieldName : fieldValueProvider) {
        fieldValues.putIfAbsent(fieldName, fieldValueProvider.getValues(fieldName));
      }
    }
    // in highlight(): if (docHit == null) { ... } else { docHit.addFieldValues(fieldValueProvider); }
Trade-offs
Field order: DocHighlights.fields is a LinkedHashMap, and with this fix its order follows the queries: highlight(topDocs, body, title) gives {body=[>bar<], title=[>foo<]}, while the combined query and 9.12.3 give stored order, {title=[>foo<], body=[>bar<]} (executed probe). Fields and values are the same. If maintainers want the stored order kept, use option B.
What the checks validated
- Stock main, gradle: the repro fails 2 of 2 with assertions on and off; the whole highlighter module: 724 tests, 2 failed (only the repro).
- Fix, gradle: the repro passes 2 of 2 with assertions on and off and 20 of 20 over 10 iterations.
- Fix, the whole
lucene/highlightermodule (classic, unified, match and vector highlighters, with the repro): 35 classes, 724 tests, 0 failures. ecjLint,checkGoogleJavaFormat,renderJavadocforlucene/highlighter: pass. Both diffs apply cleanly to a cleana9779ef3c193tree.- Earlier, by the hunt: its equivalent change (the same code, a shorter comment) shadowed into main makes the finder's and the independent reproducer's tests pass, the 48 upstream matchhighlight tests pass, and in the security probe all 187,200 document comparisons get the combined query's field set, with no extra field or value.
- Not tested: a custom field highlighter that also formats fields without matches and declares no
alwaysFetchedFields. By reading, the fix then also emits fields that a later query touches but does not match in that document; the combined query does the same on main, 9.x did not (it loaded only fields with matches). The same holds for option B. - The diffs also apply cleanly (
git apply --check) toMatchHighlighter.javaonbranch_10xandbranch_10_6; not compiled or tested there. Those branches build with Java 21, so the test's_ -> truemust becomef -> true. - Not run: other modules' suites (the change is in
lucene/highlighteronly); no benchmark.
Load, in every retriever, the fields that any of the queries affects (validated with shadowed sources)
Rewrite all queries first, collect the highlighted fields they visit (the same QueryVisitor rule as MatchRegionRetriever), and pass "always fetched or affected by any query" as fieldsToLoadUnconditionally to every retriever (+24/-3).
Trade-offs
For the tested chain (highlighted, then skipRemaining()), it gives the 9.12.3 and combined-query output including the stored field order ({title=[>foo<], body=[>bar<]} in both argument orders, executed probe). Costs more: every retriever copies every query's fields out of the stored document, so with n queries on n fields about n times the field values of option A (each retriever already reads the stored document once per hit). Not measured. Not tried: cheaper designs that also keep stored order, such as loading the stored fields once after all queries (as 9.x did) or letting only the first retriever preload the fields any query affects.
What the checks validated
Run with the standalone JUnit runner and shadowed sources on main (not gradle): the repro passes 2 of 2, the 48 upstream matchhighlight tests pass.
State that separate queries must stay on the first query's fields, or that callers must alwaysFetchFields every highlighted field.
Trade-offs
No code change; the order-dependent silent loss stays for anyone who misses the sentence, and 9.x users upgrading lose highlights without notice. Not run.
Downstream: code search found no use of the matchhighlight package in Solr, Elasticsearch or OpenSearch, and an application should not treat a missing highlight as proof that a query did not match a field.
A bounded-exhaustive model of the Matches-based highlighting pipeline compared the stock jars with reference relations; one relation says that two queries on two fields must give the same highlighted fields as their disjunction. While writing it, the finder spotted the defect in DocHit, the relation witnessed it, and a JUnit reduced it to two fields.
The method in full171 words
Method: bounded-exhaustive translation validation on the real jars (semi-formal tier), in a hunt unit on overlapping and nested match regions in the matchhighlight package.
- Reference semantics written from the javadoc and class comments were compared with the stock classes on every input up to a small scope: a vocabulary of three words, one- to four-word values, 21 queries, every offsets strategy,
PassageSelectorandPassageFormatter, andMatchHighlighterend to end. - Metamorphic relation E5:
highlight(topDocs, q1 on field A, q2 on field B)must give the same highlighted fields ashighlight(topDocs, q1 OR q2). The finder spotted the defect by code reading while modellingMatchHighlighter, and E5 witnessed it: 12,221 of 20,130 document comparisons differ at the small scope (183 documents, with assertions), 136,554 and 132,594 of 180,510 at the full scope (1,641 documents, two position gaps). - The finder then reduced it to a deterministic public-API JUnit; an independent reproducer, an intended-behaviour devil's advocate, reading-only reviews by a model from another family (OpenAI GPT-5.6) and an adjudication checked it (2026-10-26).
No prior report found (2026-10-26: 96 tool queries over GitHub, commits, downstream repositories, the Lucene lists and JIRA, 23 manual GitHub searches, every highlighter issue and PR since 2023-12, Solr lists, web). Closest: #12881, the introducing PR, whose discussion covers only performance.
Searches4 searches
Verdict new: 22 hits read, none the same bug. #12881 (merged 2023-12-07) introduced it; its body, comments and reviews discuss performance only. #15577 (merged 2026-01) is a later change to the retriever and #16847 (open, long doc ids) the only open PR touching MatchHighlighter.java; neither fixes it. The dev@ thread "Deprecating / renaming old highlighters" (2025-11-21) has the class's author naming highlighting multiple queries at once as a motivating feature, which supports the intended use but does not report the bug. JIRA has been read-only since 2022, before the regression. Keyword search cannot prove absence.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories; the dev@, java-user@, issues@ and commits@ lists; the JIRA archive; the web | 2026-10-26 | the hunt's prior-report tool, two runs: 45 and 51 queries | no report; top hit #12881 (the introducing PR) |
| GitHub (apache/lucene issues and PRs, open and closed) | 2026-10-26 | 23 manual searches: class and package names, alwaysFetchFields, "multiple queries", "second query", "different fields"; every highlight-titled issue or PR and every module:highlighter PR since 2023-12 | no report; #15577 and #16847 touch the files, neither is a fix |
| Downstream (Solr, Elasticsearch, OpenSearch) and the Solr lists | 2026-10-26 | code and list searches for MatchHighlighter, MatchRegionRetriever, matchhighlight | 0 hits |
| dev@ thread "Deprecating / renaming old highlighters" | 2026-10-27 | read in full (3 emails, 2025-11-21) | context only: the author uses the class and names multi-query highlighting as a motivating feature |
Introduced by #12881 (755de5aae33, merged into main 2023-12-07, never backported to 9.x), first released in 10.0.0. Executed: 9.0.0 to 9.12.3 pass; 10.0.0, 10.1.0, 10.2.2, 10.3.2, 10.4.0, 10.5.2 and main fail; a source swap of the package isolates the commit.
Versions tested6 rows
Introduced by #12881 "Performance improvements to MatchHighlighter and MatchRegionRetriever" (@dweiss), merged into main on 2023-12-07 as 755de5aae33 (parent b6999818474c); the PR targeted 10 because of minor API changes, so no 9.x release has it. It removed DocHit's lazy document load (which accepted every field with matches from any query), made each retriever load only its own query's fields, and made DocHit copy the values of the query that creates it. git blame puts the DocHit field-value lines (MatchHighlighter.java:168, :170, :172-174) and new DocHit(docId, fieldValueProvider) (:242) on this commit alone, and git log -S 'new DocHit(docId, fieldValueProvider)' returns only this commit. The only later commit on the file is #14308 (ab453b9541a, 2025-02-27), a cosmetic rename to unnamed lambda parameters at :181 and :236-237.
API age. MatchHighlighter was added by LUCENE-9464 (e2f3f626ee4, 2020-09-10), first released in 9.0.0. Not executed: 10.2.0, 10.2.1, 10.3.0, 10.3.1, 10.5.0 and 10.5.1 contain the commit and the same code; branch_10_6, and so 10.6.0 (released 2026-10-29), has the same code. Not fixed upstream (2026-10-26).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the compact JUnit 2 of 2 fail via gradle, assertions on and off; the finder's and the independent reproducer's tests fail with and without assertions |
| 10.0.0, 10.5.2 | affected | the compact JUnit 2 of 2 fail; the independent reproducer's 4 of 4 fail (release jars, SHA-1 checked) |
| 10.1.0, 10.2.2, 10.3.2, 10.4.0 | affected | the finder's JUnit fails |
| 9.0.0, 9.9.0, 9.9.1, 9.10.0, 9.12.3 | not affected | pass (9.0.0 with one import adapted); 9.12.3 also passes the compact JUnit |
package of 755de5aae33^ / 755de5aae33 on the 10.0.0 and 9.12.3 jars | source swap | the parent's package passes on both, the commit's package fails on both: the result follows the package change |
| fix (option A) | not affected | the compact JUnit passes; the whole highlighter module passes (724 tests) |
An independent reproducer wrote its own two-document test (fields with offsets and positions-only, both orders) that fails on main, 10.0.0 and 10.5.2, with controls passing. A devil's advocate found no intended-behaviour argument that holds. Reading-only cross-model reviews agreed on the root cause. An adjudication confirmed it with high confidence.
Checks and verdicts405 words
Every executing check wrote or re-ran its own JUnit on stock main; every control passed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Bounded-exhaustive model (relation E5) plus code reading; its one-document JUnit fails with and without assertions on main and on 10.0.0 and 10.5.2, passes on 9.10.0 and 9.12.3 and with the fix; the 48 upstream matchhighlight tests pass with the fix. |
| independent reproducer | real | Own test (subject and content fields, offsets in postings and positions-only, both orders): 4 of 4 fail on main with and without assertions, on 10.0.0 and 10.5.2; pass on 9.10.0, 9.12.3 and with the fix. Controls (same-field queries; alwaysFetchFields) pass everywhere. A document the first query misses gets no fields. |
| intended-behaviour devil's advocate | real; high that it is not intended | Four not-a-bug arguments, none holds; its probe shows the argument-order dependence and that the second query's own retriever loads body and finds the match. |
| cross-model reviews (refute, intended) | not real (low, procedural); real (medium) | An independent reviewer from another model family (OpenAI GPT-5.6) reviewed by reading only, since it could not run Java. The lenses agreed on the root cause and found the inputs in contract; the refute lens's "not real" only means not reproduced by it, and a separate run re-ran the JUnit: 1 of 1 fail. |
| adjudication | confirmed, high | Re-ran the independent test on main with and without assertions (4 of 4 fail each) and the finder's test without assertions (1 of 1 fail); class silent wrong results. |
| Registration check and this doc | reproduced | Registry re-runs on main: the finder's test fails with and without assertions, passes with the fix. This doc's gradle runs: the compact JUnit fails 2 of 2 on stock main and passes with the fix. |
| Correction to the registry row | 3 wordings out of date | The registry row (shown in the registry card under Sources) has three wordings that the checks corrected in this doc: its title and impact note say "every field" that only a later query matches is dropped (not when the field is always fetched or the first query also touches it); affected_versions says "no later commit touches the DocHit lines" (the field-value lines blame only to #12881, but #14308 later renamed lambda parameters at MatchHighlighter.java:181 and :236-237, a cosmetic change); upstream says 16 manual GitHub searches (23 were run). This doc's text is the corrected account. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 536 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,270 words
- Registry title
- MatchHighlighter.highlight(topDocs, q1, q2, ...) silently drops the highlights of every field that only the second or a later query matches: each document keeps only the stored field values of the first query's MatchRegionRetriever, which loads just the fields that first query affects (regression in 10.0.0)
- Area
- highlighter / matchhighlight: MatchHighlighter multi-query highlighting (DocHit field values on top of MatchRegionRetriever's per-query stored-field loading)
- Priority
- Low, rank 361: Highlighting-only, in the multi-query form of the little-used matchhighlight package.
- Impact class
- silent wrong results
- Impact note
- Hits applications that use the matchhighlight package's MatchHighlighter with default codec, IndexWriterConfig, searcher and the stock FieldValueHighlighters, and pass two or more queries that touch different fields to highlight(TopDocs, Query...), for example the title and body clauses of the search query passed separately to tell their markers apart; it is deterministic, needs no scale and behaves the same with -ea and -da: every field that only a later query matches is missing from DocHighlights.fields, the result depends on the order of the queries, and a document that the first query does not match can come back with no fields at all; hits, counts, scores and document order are unaffected; it is hidden for fields that are always fetched (alwaysFetchFields, or a maxLeadingCharacters or verbatimValue highlighter covering the field); the package is far less used than the UnifiedHighlighter (code search found it in none of Solr, Elasticsearch and OpenSearch).
- Summary
- You pass several queries to MatchHighlighter.highlight(topDocs, q1, q2), for example title:foo and body:bar for a document whose title is 'foo' and whose body is 'bar'; the class's own test passes the sub-clauses of the search query this way to give each query its own markers. You expect both fields to be highlighted, exactly as highlight(topDocs, title:foo OR body:bar) returns them: {title=[>foo<], body=[>bar<]}. Instead you get only {title=[>foo<]} (only {body=[>bar<]} with the queries swapped), with no error, because each document keeps only the stored fields that the first query's retriever loaded; 9.x returned both fields.
- Introduced
- 755de5aae331301acf4c1acd3af6d7329998ee48 (#12881 'Performance improvements to MatchHighlighter and MatchRegionRetriever', author dweiss, merged into main only and never backported to 9.x). It removed DocHit's lazy document load, whose stored-field visitor accepted 'matchRanges.containsKey(field) || needsField.test(field)' (every field that any query matched; MatchHighlighter.java:191-197 at the parent b6999818474c), made DocHit copy the FieldValueProvider of the query that first reaches the document, and made each MatchRegionRetriever load only fieldsToLoadUnconditionally plus its own query's affected fields; both halves arrived in this one commit [read: git blame of MatchHighlighter.java:168-174 and 242, git log -L on the DocHit lines and git log -S 'new DocHit(docId, fieldValueProvider)' return only this commit; exec: the matchhighlight package sources of 755de5aae33^ shadowed onto the 10.0.0 and the 9.12.3 jars pass, those of 755de5aae33 fail on both] (2023-12-07 (#12881 merged into main))
- First affected version
- 10.0.0 [exec: fails]; 9.12.3, the last 9.x release, passes [exec], as do 9.0.0 (the first release with MatchHighlighter), 9.9.0, 9.9.1 and 9.10.0 [exec]
- Affected versions
- every release from 10.0.0 through 10.6.0 (10.6.0 by reading) and main a9779ef3c193, never fixed. [exec] the finder's JUnit fails on 10.0.0, 10.1.0, 10.2.2, 10.3.2, 10.4.0 and 10.5.2 (-ea) and on main (-ea and -da); the independent reproduction's JUnit fails 4/4 on 10.0.0, 10.5.2 and main (-ea and -da); the intended-behaviour check re-ran the finder's JUnit on 10.5.2 (fail) and 9.12.3 (pass). [read] 10.2.0, 10.2.1, 10.3.0, 10.3.1, 10.5.0 and 10.5.1 contain the commit (git tag --contains) and no later commit touches the DocHit lines; branch_10_6 (2763db11b0a), and so 10.6.0 (released 2026-10-29), has the same DocHit code, not executed. Not affected: the whole 9.x line [exec 9.0.0 with an import-adapted copy of the JUnit, 9.9.0, 9.9.1, 9.10.0, 9.12.3]. Releases were run on JDK 25. No open upstream PR changes the DocHit field values (2026-10-26).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record): two scripted prior-report searches (96 queries over apache/lucene issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists and the JIRA archive; 0 high-overlap hits), 16 manual GitHub searches (apache/lucene, Solr, Elasticsearch, OpenSearch, all of GitHub), the open-PR lists for MatchHighlighter, matchhighlight, highlighter and the module:highlighter label (only #16847, long doc ids, touches the files; not a fix), Solr list searches, 6 web searches, and full reads of #12881 (the introducing PR; body, comments, reviews and inline comments discuss performance only), #15577, #16847, #16820 and the 2025-11 dev@ thread 'Deprecating / renaming old highlighters'; JIRA is read-only since 2022 and the regression dates from 2023-12
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): the compact JUnit through gradle in a scratch worktree, stock and with the fix, assertions on and off, 10 iterations with the fix, and the wholelucene/highlightermodule stock and with the fix (2026-10-27); the same file through the standalone JUnit runner on main (-ea,-da) and on the 10.0.0, 10.5.2 and 9.12.3 jars. Hunt runs of other tests on 9.0.0, 9.9.0, 9.9.1, 9.10.0, 9.12.3, 10.0.0, 10.1.0, 10.2.2, 10.3.2, 10.4.0, 10.5.2 and main, plus a source swap of the package at755de5aae33and its parent onto the 10.0.0 and 9.12.3 jars.
- Finding record
lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/MatchHighlighter.java:37-44 (at a9779ef3c193) (class javadoc: 'An example highlighter ... fully featured, ready-to-use component'), :53-67 (FieldValueHighlighter, hasMatches), :133-138 (alwaysFetchFields), :170-175 (DocHit copies the field values of the provider it is created with), :177-184 (addMatches), :203 (highlight, no javadoc), :223 ('Collect match ranges for each query and associate each range to the origin query'), :224-247 (one MatchRegionRetriever per query; DocHit created at the first callback, :242; later queries only add matches, :245), :254-274 (computeDocFieldValues iterates DocHit.fieldValues only, :257)lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/MatchRegionRetriever.java:180-192 (at a9779ef3c193) (queryAffectedHighlightedFields), :200-204 (shouldLoadStoredField = fieldsToLoadUnconditionally or the query's own affected fields), :382-388 (consumer called for every document of topDocs)lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/FieldValueHighlighters.java:89 (at a9779ef3c193) ('Highlights fields matching predicate matchFields only if they contained query matches'), :76 and :124 (maxLeadingCharacters and verbatimValue declare alwaysFetchedFields)lucene/highlighter/src/test/org/apache/lucene/search/matchhighlight/TestMatchHighlighter.java:638-644 (at a9779ef3c193) (testHighlightMoreQueriesAtOnceShowoff: 'interesting, if not always super-practical'), :652-659 (both queries on FLD_TEXT1), :757-759 ('the query passed to the highlighter are individual sub-clauses of the Boolean query used to fetch documents')
- The finding in 30 seconds
lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/MatchHighlighter.java:150-157, (at a9779ef3c193) 165-185, 203-274lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/MatchRegionRetriever.java:180-204, (at a9779ef3c193) 357-388
- Who is affected
lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/MatchHighlighter.java:127-138; (at a9779ef3c193) FieldValueHighlighters.java:75-78, 123-126lucene/highlighter/src/test/org/apache/lucene/search/matchhighlight/TestMatchHighlighter.java:757-763 (at a9779ef3c193)lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/MatchHighlighter.java:203-251 (at a9779ef3c193) (highlight only reads topDocs)
- Why it looks unintended
lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/MatchHighlighter.java:37-44, (at a9779ef3c193) 53-67, 150-157, 203, 223lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/FieldValueHighlighters.java:88-115 (at a9779ef3c193)lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/MatchRegionRetriever.java:93-105, (at a9779ef3c193) 145-164lucene/highlighter/src/test/org/apache/lucene/search/matchhighlight/TestMatchHighlighter.java:638-644, (at a9779ef3c193) 652-659, 757-763lucene/CHANGES.txt:2155-2225 (at a9779ef3c193) (10.0.0 API Changes, GITHUB#12881); lucene/MIGRATE.md:883-886lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/MatchRegionRetriever.java:180-181 (at a9779ef3c193) ('so that we don't load or scan fields that are irrelevant')
- Suggested fix
lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/MatchHighlighter.java:212-221, (at a9779ef3c193) 257-266 (fieldsToLoadIfWithHits; formatting with or without matches)
- TestMatchHighlighterMultiQueryFields.java (JUnit test):
repro/LFV-595/src/org/apache/lucene/search/matchhighlight/TestMatchHighlighterMultiQueryFields.java(71 lines)
Made in parallel with this doc from an executed probe on main a9779ef3c193 (with and without assertions, and with the fix shadowed in) and on the 10.0.0, 10.5.2 and 9.12.3 jars; the values on screen come from the probe's log. The diagram uses the one-document example; the compact repro adds a second document that the first query does not match.
assets/LFV-595/bug.png(536 KB)