SSDV facets store a facet path as one term, with U+001F between dimension and label; a U+001F or U+001E inside a name is escaped with U+001E so the path reads back unchanged. A flat dimension set to multiValued + requireDimCount also gets one extra term per document, the dimension name alone, for an exact dimension count.
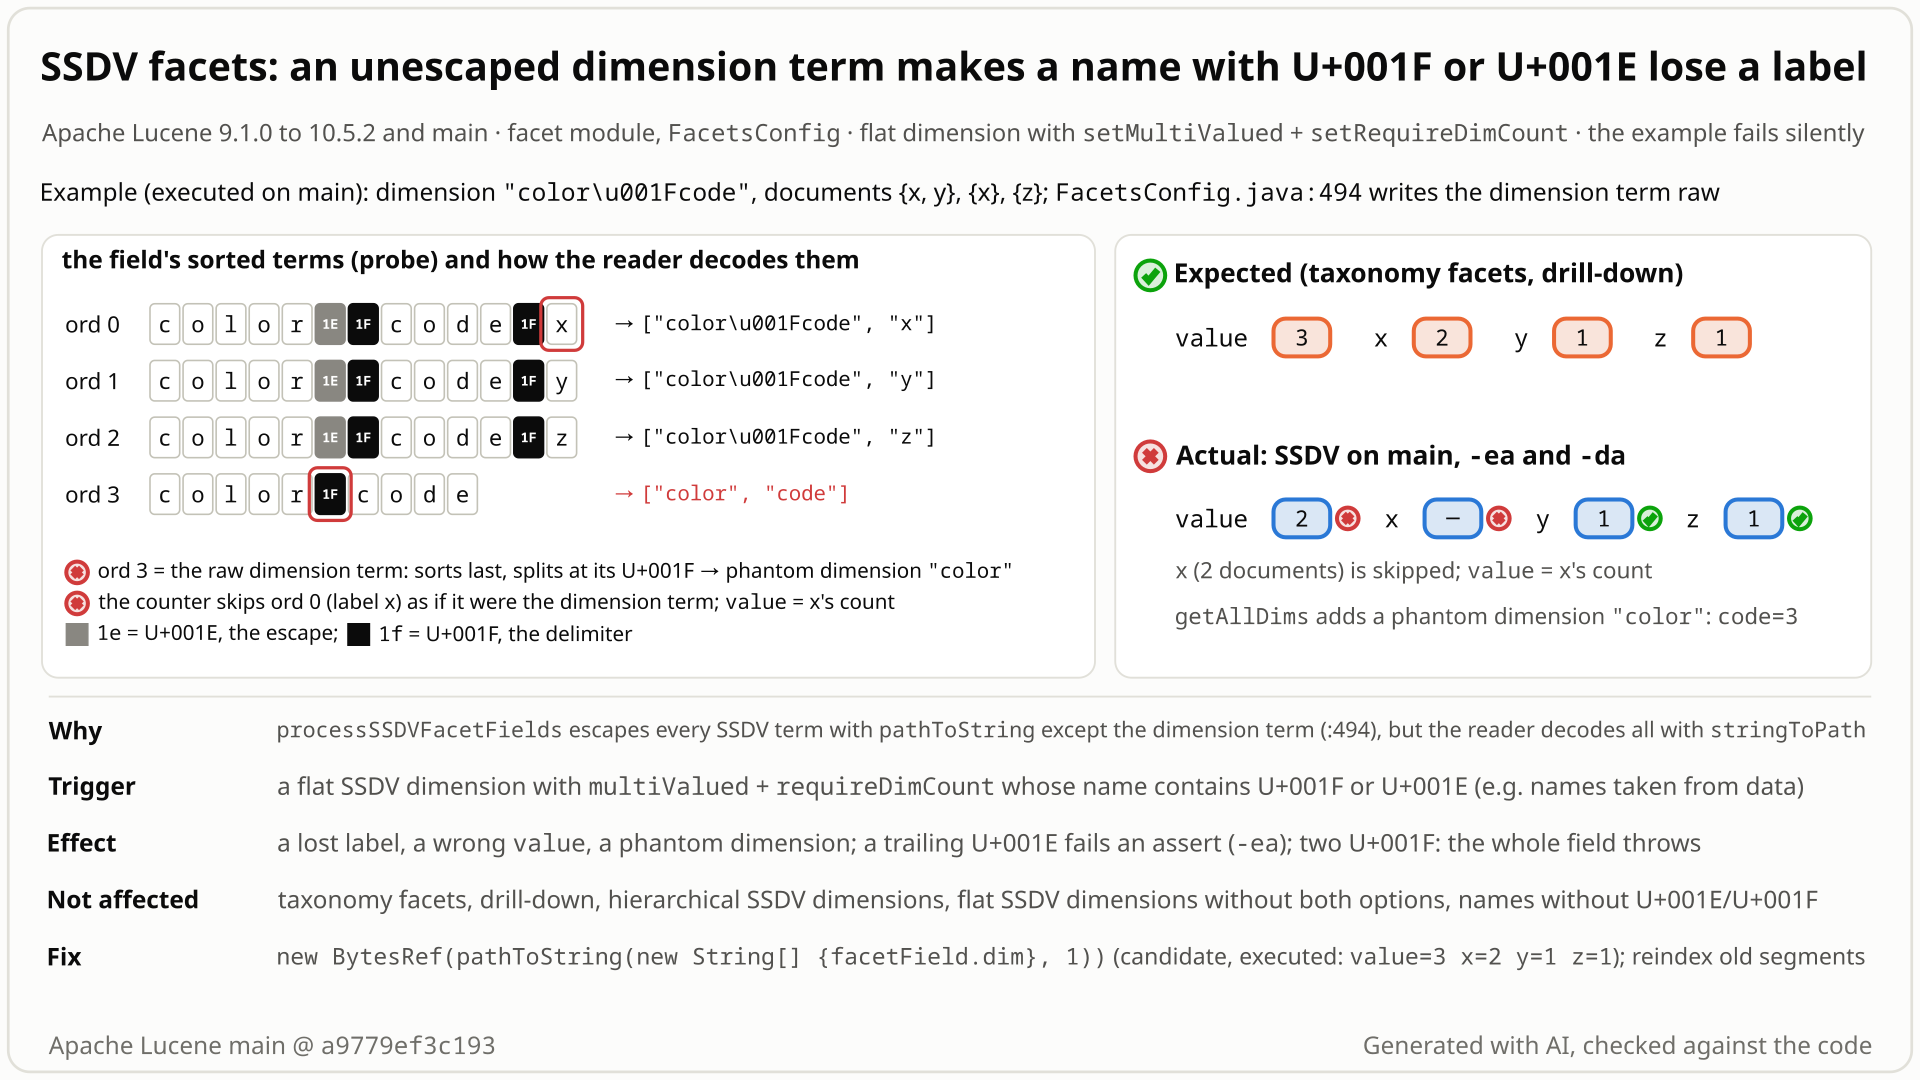
color\u001Fcode with documents {x, y}, {x}, {z}: its four terms in byte order, how the reader groups them, and why x is lost and a phantom dimension appears; then the one-line fix. Select the still to open it at full size. Generated with AI, checked against the code.- Configure a flat dimension named
color\u001Fcode(the text "color", the control character U+001F, "code") withsetMultiValuedandsetRequireDimCount, and index 3 documents with the labels {x, y}, {x} and {z}. - You expect
getTopChildrento return value=3 with x=2, y=1, z=1. That is what you get for the namecolor, and what taxonomy facets return for this name. - Instead you get value=2 with only y=1 and z=1: label x is gone and its count, 2, is shown as the dimension total.
getAllDimsalso lists a dimensioncolorwith a labelcodethat nobody indexed. - Why: each facet term is one string, parts joined by U+001F, with these characters inside a name escaped by U+001E; only the dimension's own term is written raw. In byte order the raw
color\u001Fcodesorts after the escaped label terms, so label x is taken for the dimension term and skipped, and the raw term is decoded as dimensioncolor, labelcode. - Other names fail harder: a name with two U+001F whose first part is a flat dimension (the default) makes building the facet state throw
IllegalArgumentExceptionfor every dimension of the facet field, and with assertions on a name ending in U+001E throwsAssertionError.
Applications using SSDV facets with a flat dimension configured multiValued and requireDimCount (both opt-in) whose name contains U+001F or U+001E, which the API accepts; for example names taken from data. Three documents are enough. With assertions off the counts are silently wrong, and segments written before a fix stay wrong until reindexed.
Mechanism, terms and numbers758 words
SortedSetDocValues (SSDV) facets store each facet path as one term: the dimension and the label joined by U+001F, with U+001F and U+001E inside a name escaped by U+001E (pathToString), and the reader decodes every term with the inverse, stringToPath. For a flat dimension configured setMultiValued + setRequireDimCount, FacetsConfig also indexes a bare dimension term so the dimension count is exact, and that one term is written raw, new BytesRef(facetField.dim) (FacetsConfig.java:494). A dimension name containing U+001F or U+001E, which the API accepts, is then read back as a different path. With 3 documents {x, y}, {x}, {z} under color\u001Fcode, getTopChildren returns value=2 childCount=2 y=1 z=1 instead of value=3 childCount=3 x=2 y=1 z=1, and getAllDims lists a phantom dimension color with label code. A name with two U+001F whose first part is a flat dimension (the default) makes the DefaultSortedSetDocValuesReaderState constructor throw IllegalArgumentException for the whole facet field, and with assertions on a name ending in U+001E throws AssertionError. In a single-dimension index, taxonomy facets, hierarchical SSDV dimensions and flat dimensions without requireDimCount handle the same names as a plain name. It came with LUCENE-9952 (PR #611, 2022), whose first revision escaped the term; a review suggestion replaced it with the raw name as an assumed-equivalent simplification. Every release from 9.1.0 to 10.6.0 (10.6.0 by reading) and main is affected. Escaping the term fixes it and leaves every other index byte-identical; segments written before the fix keep the raw term until they are reindexed.
- SSDV facets:
SortedSetDocValuesFacetField(dim, label)indexes each facet value as a term in one SortedSetDocValues field ($facetsby default).DefaultSortedSetDocValuesReaderStatewalks the field's terms in byte order and groups them into dimensions;SortedSetDocValuesFacetCountscounts them. - Path encoding:
FacetsConfig.pathToStringjoins the parts with U+001F (DELIM_CHAR) and puts U+001E (ESCAPE_CHAR) before any U+001F or U+001E inside a part (FacetsConfig.java:543-553,:569-593).stringToPathis the inverse: "Turns an encoded string (from a previous call topathToString) back into the originalString[]" (:595-626). - multiValued + requireDimCount: with several labels per document, adding up label counts over-counts the dimension, so for this opt-in configuration
FacetsConfigindexes one more term per document, the bare dimension, and the readers read the dimension count from it (LUCENE-9952).
- The write (
FacetsConfig.java:491-497): the bare term isnew BytesRef(facetField.dim), raw; the label term ispathToString(facetLabel.components, facetLabel.length), escaped. The hierarchical branch writes its bare term escaped,pathToString(facetLabel.components, i + 1)(:477-480). - The terms in byte order for
color\u001Fcode(executed term dump of this name on main, from the diagram probe; an independent check's dump of a similar name has the same shape):
ord 0   color \u001E \u001F code \u001F x    escaped label term  -> [color\u001Fcode, x]
ord 1   color \u001E \u001F code \u001F y                         -> [color\u001Fcode, y]
ord 2   color \u001E \u001F code \u001F z                         -> [color\u001Fcode, z]
ord 3   color \u001F code                    raw dimension term  -> [color, code]
After color, U+001E (escaped terms) is smaller than U+001F (raw term), so the raw term sorts last. For a plain name the bare term color is a prefix of every label term and sorts first, which the readers rely on.
- The read (
DefaultSortedSetDocValuesReaderState.java:101-111,:209-221): every term is decoded withstringToPath, and a new dimension starts when the first part changes. Ords 0-2 become dimensioncolor\u001Fcode; ord 3 becomes a second flat dimensioncolorwith labelcode. - The count (
AbstractSortedSetDocValueFacetCounts.java:274-281,:341-350;getTopDims:172-178): for multiValued + requireDimCount the first ordinal of the dimension is taken as the bare term; the dimension count is read from it and it is skipped when listing labels. Here it is label x: value = count(x) = 2, and x is not listed.
| dimension name | getTopChildren | getAllDims |
|---|---|---|
color (control) | value=3 childCount=3 x=2 y=1 z=1 | [color] |
color\u001Fcode | value=2 childCount=2 y=1 z=1 | [color, color\u001Fcode] |
color\u001Ecode | value=2 childCount=2 y=1 z=1 | [colorcode, color\u001Ecode] (the raw \u001E escapes the c) |
color\u001E | assertions on: AssertionError at FacetsConfig.stringToPath (:624, assert !lastEscape) while the reader state is built; off: value=2 childCount=2 y=1 z=1 | off: [color, color\u001E] |
a\u001Fb\u001Fc | IllegalArgumentException: dimension not configured to handle hierarchical field; got: [a, b, c] from the reader state constructor (DefaultSortedSetDocValuesReaderState.java:198-206: a flat dimension's first term must have 1 or 2 parts) | - |
A reader cannot repair this: the raw term D\u001FL has exactly the bytes of the escaped term of dimension D, label L.
Exposure and likelihood354 words
- Who is exposed. SSDV faceting with a flat dimension set to
setMultiValued(dim, true)andsetRequireDimCount(dim, true)(both off by default; the javadoc calls requireDimCount "unusual",FacetsConfig.java:121-122), directly or through agetDefaultDimConfig()override ("Useful when the dimension is not known beforehand",:143-144), and a dimension name with U+001F or U+001E.FacetField.verifyLabelrejects only null or empty names (FacetField.java:64-73), andSortedSetDocValuesFacetFieldapplies it to the dimension (SortedSetDocValuesFacetField.java:53). Realistically: dimension names built from data that uses these characters as separators. - No scale needed. 3 documents, an uncustomized
IndexWriterConfig, assertions on or off; the JUnit's randomized test codec and amain()probe with Lucene's plain defaults give the same counts. - Silent. With one U+001F or U+001E and assertions off nothing fails: a label disappears, its count is shown as the dimension total, and a made-up dimension appears in
getAllDims. - Whole-field failure. A name with two U+001F whose first part is a flat dimension (the default) makes the reader state constructor throw, so SSDV faceting fails for every dimension in that index field, also for queries that do not match the document, and also after the document is deleted, until a merge removes it (executed on main and 10.5.2, with controls).
- Lasting. A fix changes only the writer. A fixed build reading segments written before the fix still lists the phantom dimension and leaves the old documents out of the dimension total: 3 old + 3 new documents give value=3 x=4 y=2 z=2 instead of 6, and
forceMerge(1)keeps it (executed). Affected documents must be reindexed. - Not affected by this raw term. In a single-dimension index: taxonomy facets, hierarchical SSDV dimensions and flat SSDV dimensions without requireDimCount (executed; two-dimension indexes can still hit the sibling ordering bug). Drill-down, which uses its own escaped terms (
DrillDownQuery.java:51,FacetsConfig.java:419-460; executed with drill-down oracles). Search hits (by reading the code: the raw term is only a doc-values value, never an indexed term). - How likely. Rare: dimension names are usually constants, the bounded prior-report searches found no report in four years, and a public code search found no project that reaches the trigger.
The test shows that for a flat SortedSetDocValues facet dimension configured multiValued + requireDimCount whose name contains U+001F ("c\u001Fd"), FacetsConfig writes the bare dimension term unescaped, so the reader loses one label.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.facet.sortedset;

import java.util.Arrays;
import org.apache.lucene.document.Document;
import org.apache.lucene.facet.Facets;
import org.apache.lucene.facet.FacetsConfig;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSortedSetDocValuesDimCountReservedChar extends LuceneTestCase {

  public void testDimNameWithDelimChar() throws Exception {
    String dim = "c\u001Fd";
    FacetsConfig config = new FacetsConfig();
    config.setMultiValued(dim, true);
    config.setRequireDimCount(dim, true);
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new SortedSetDocValuesFacetField(dim, "x"));
        doc.add(new SortedSetDocValuesFacetField(dim, "y"));
        w.addDocument(config.build(doc));
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        Facets facets =
            new SortedSetDocValuesFacetCounts(new DefaultSortedSetDocValuesReaderState(reader, config));
        // expected: children x and y; actual: only y (x's ordinal is read as the dimension's own)
        assertEquals("[x (1), y (1)]", Arrays.toString(facets.getTopChildren(10, dim).labelValues));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-597/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/facet/build/libs/lucene-facet-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.facet.sortedset.TestSortedSetDocValuesDimCountReservedChar
# the module(s) facet also need their third-party runtime jars
- Expected vs actual
- One document with labels x and y; expected
getTopChildrenlabels[x (1), y (1)]; actual[y (1)], with-eaand-da.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[[x (1), ]y (1)]> but was:<[[]y (1)]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.facet.sortedset.TestSortedSetDocValuesDimCountReservedChar.testDimNameWithDelimChar(TestSortedSetDocValuesDimCountReservedChar.java:48)- Nothing limits dimension names; taxonomy facets and the other SSDV configurations treat them like plain names.
- The dimension term is the only SSDV facet term not built with
pathToString, yet the reader decodes every term with its inverse,stringToPath. - The introducing PR's first revision escaped this term; a review suggestion swapped in the raw name as an assumed-equivalent simplification.
The full argument222 words
- No restriction. No javadoc, package doc, CHANGES or MIGRATE entry limits the characters of a dimension name;
FacetField.verifyLabelchecks only null or empty (FacetField.java:64-73). - Escaping is the design. LUCENE-5339 (2013; its commit "remove delim char") replaced the TODO "nuke delimChar? can we escape instead?" with
pathToString/stringToPath, which escape every part, the dimension included.stringToPathtakes "an encoded string (from a previous call topathToString)" (FacetsConfig.java:595-598). - Everything else escapes. The hierarchical bare term (
:479-480), the flat label term (:496-497), drill-down terms (:419-460,DrillDownQuery.java:51) andgetSpecificValue(AbstractSortedSetDocValueFacetCounts.java:103). - The same names work elsewhere. In a single-dimension index, taxonomy facets and hierarchical SSDV return value=3 x=2 y=1 z=1 for them, and flat SSDV without requireDimCount returns the same labels with value=-1 (no dimension count for a multiValued dimension, by design,
AbstractSortedSetDocValueFacetCounts.java:350-353), exactly as for the plain name (executed). UpstreamTestTaxonomyFacetCounts#testLabelWithDelimiterasserts reserved characters in labels are supported. - History. PR #611's first revision wrote
String dimString = pathToString(facetLabel.components, 1);. Review comment: "I believe you can just usefacetField.dimhere instead of reconstructing the dimension from the label." Reply: "Doh, yep. Thanks!" The "pr feedback" commit switched to the raw name. The two are equal only for names without U+001F/U+001E, and neither the PR nor its issue discusses them.
The devil's-advocate check191 words
The strongest "intended" case (the devil's-advocate verifier and the prior-report search): dimension names are application constants, so a control character in one is garbage input; a 2013 review comment on the first SSDV facet code (LUCENE-4795) says "I want to assert that the label is allowed to use the delimiter; only the dimension is not allowed to"; FacetsConfig and Facets are @lucene.experimental and DELIM_CHAR is @lucene.internal; no upstream test puts a reserved character in a dimension name; and the AssertionError is stringToPath's documented precondition.
Why it fails: rarity bounds the impact, not the validity, and getDefaultDimConfig's javadoc and the "sparse" faceting of Facets#getAllDims allow for dimensions not known beforehand (which makes data-derived names plausible; it does not say they come from untrusted data). The 2013 remark predates LUCENE-5339, which replaced that code with escaping of every part, dimensions included; today's API never rejects such a name and handles it in every other path. "Experimental" allows API changes, not wrong counts. An untested input is not an unsupported one. And it is FacetsConfig itself that feeds stringToPath a string pathToString did not produce. Verdict: a defect (adjudication: confirmed, high).
Recommended Escape the bare dimension term with pathToString (one line)
Escape the bare dimension term like every other facet term: pathToString(facetLabel.components, 1) instead of facetField.dim (the introducing PR's first revision). Names without U+001F or U+001E get byte-identical terms. The repro and the whole lucene/facet module (311 tests) pass; documents indexed before the fix need reindexing.
           if (dimConfig.multiValued && dimConfig.requireDimCount) {
             // If non-hierarchical but multi-valued and requiring dim count, make sure to
             // explicitly index the dimension so we can get accurate counts for it:
-            doc.add(new SortedSetDocValuesField(indexFieldName, new BytesRef(facetField.dim)));
+            // Escape the dimension like every other facet term, so stringToPath decodes it back:
+            String dimString = pathToString(facetLabel.components, 1);
+            doc.add(new SortedSetDocValuesField(indexFieldName, new BytesRef(dimString)));
           }
All options and trade-offs3 options · 684 words
Only the writer can be fixed: the raw term D\u001FL has the same bytes as the escaped term of dimension D, label L, so a reader cannot tell them apart, and a reader-side fix for the sibling ordering bug in the same area would not repair this. Segments written before the fix keep the raw term; executed: a fixed build reading 3 old and 3 new documents gives value=3 x=4 y=2 z=2 (expected 6) and keeps the phantom dimension, also after forceMerge(1). Add the new test with the fix (worth adding: a name equal to another dimension + U+001F + one of its labels), and a CHANGES note that documents indexed with such dimension names must be reindexed. Until a fix ships, applications can reject or normalize U+0000..U+001F in dimension names, or use taxonomy facets. Two more options change behaviour: configuring such dimensions as hierarchical (their bare term is escaped, but hierarchical dimensions can hit the sibling ordering bug when one name is another plus a trailing control character), or dropping requireDimCount on data-derived flat dimensions (the dimension value is then -1, no count).
In FacetsConfig.processSSDVFacetFields, write the bare term of a flat multiValued + requireDimCount dimension through pathToString, as the hierarchical branch and every label term already do. This restores the encoding of PR #611's first revision. Equivalent spellings with the same bytes: pathToString(new String[] {facetField.dim}, 1) (the finder's) or pathToString(facetField.dim). +3/-1 in FacetsConfig.java.
           if (dimConfig.multiValued && dimConfig.requireDimCount) {
             // If non-hierarchical but multi-valued and requiring dim count, make sure to
             // explicitly index the dimension so we can get accurate counts for it:
-            doc.add(new SortedSetDocValuesField(indexFieldName, new BytesRef(facetField.dim)));
+            // Escape the dimension like every other facet term, so stringToPath decodes it back:
+            String dimString = pathToString(facetLabel.components, 1);
+            doc.add(new SortedSetDocValuesField(indexFieldName, new BytesRef(dimString)));
           }
Trade-offs
- No change for correct data:
pathToStringof one part without U+001F/U+001E is the name itself, so every index that works today gets byte-identical terms. For a reserved name the bare term becomescolor\u001E\u001Fcode, a prefix of its label terms, so it sorts first and decodes back to[color\u001Fcode]. - Old segments keep the raw term until reindexed (executed: the phantom dimension and a dimension total of the new documents only stay, also after
forceMerge(1)).
What the checks validated
- Gradle, scratch worktree of
a9779ef3c193, JDK 25: stock + the new test fails 4 of 5 with assertions on and off; with the fix the new test andTestSortedSetDocValuesFacets(2 suites, 24 tests: 5 + 19, the one nightly-only test skipped) pass with assertions on and off;TestSortedSetDocValuesFacetswith nightly tests, 19 of 19; the wholelucene/facetmodule, 40 suites, 311 tests, 0 failures with assertions on (7 skipped) and off (8 skipped);:lucene:facet:check -x test(ecjLint, forbiddenApis, checkGoogleJavaFormat) passes. - Standalone runner: the new test 5 of 5 with
-eaand-da; a fresh index written by the fixed build gives value=3 x=2 y=1 z=1 and one dimension. - Earlier checks with the finder's spelling: the finder's, the independent reproducer's and the devil's advocate's tests and the 7-test whole-field probe pass;
TestSortedSetDocValuesFacets18 of 18 run on the standalone runner; in the finder's bounded-exhaustive harness the failing scenarios drop from 274 to 36 of 1,380, all 36 from the sibling ordering bug.
For example in FacetField.verifyLabel for the dimension, or in FacetsConfig.build only for flat multiValued + requireDimCount dimensions.
Trade-offs
Breaks names that work today in taxonomy facets and hierarchical SSDV, and reverses LUCENE-5339's choice of escaping over forbidding; the narrow variant is an odd rule for one configuration. Neither repairs existing indexes. Reasonable only as an application-side workaround.
Recognize or skip the raw bare term in DefaultSortedSetDocValuesReaderState.
Trade-offs
Impossible in general: the raw term D\u001FL is byte-identical to the escaped term of dimension D, label L. A reader-side fix of the sibling ordering bug would not repair this one either.
Applications that let documents choose their own facet dimension names and make those dimensions flat multiValued + requireDimCount (for example through getDefaultDimConfig) should reject control characters: there, one document whose name contains two U+001F makes SSDV faceting on its field throw for every user, also after the document is deleted, until a merge removes it.
A review of every use of the facet delimiter and escape characters found one SSDV facet term built without the encoder. A bounded-exhaustive differential check then compared SSDV facets with taxonomy facets for every short name made of a, U+001E and U+001F: 274 of 1,380 scenarios were wrong; with the one-line fix only 36 remained, all from a sibling bug.
The method in full193 words
Method: bounded-exhaustive differential check on the stock main jars (the study's "semi-formal" tier). A hunt unit, "in-band separators and reserved symbols", 2026-10-26.
- A static inventory of the uses of
DELIM_CHARandESCAPE_CHARshowedFacetsConfig.java:494as the only SSDV facet term not built bypathToString. - The model ran SSDV facet counts against taxonomy facets and brute-force drill-down counts for every dimension name of length 1 to 2 over {a, U+001E, U+001F}, labels {a, U+001E, U+001F, U+1F600}, 5 dimension configurations and one- and two-dimension indexes: 1,380 scenarios, 274 failing with assertions on and with them off. With the one-line fix shadowed in, 36 remain, all two-dimension indexes in which one name is the other followed by U+001E or U+001F (for example
aanda\u001E), 12 in each of three configurations: the sibling ordering bug of the same area. - The model ran on a separate test host with the previous main
ea57360912ed, whoselucene/facetis identical; all later mainline confirmations useda9779ef3c193, and the release checks used their release jars. - An AI finder then reduced it to a public-API JUnit, and independent AI tools reproduced, reviewed and judged it (see the checks).
No prior report found (2026-10-26): seven runs of a prior-art search over GitHub, the mailing lists, JIRA and downstream projects, 53 manual GitHub searches, 41 related items read in full and the files of all 407 open PRs. The introducing PR's review switched to the raw name without discussing reserved characters.
Searches4 searches
None of the issues, PRs, commits, JIRA entries, list threads or web pages found reports the unescaped bare dimension term, or reserved characters in SSDV dimension names giving wrong counts. Every hit about escaping or the delimiter predates the 2022 change. The line is unchanged on upstream main and branch_10_6, and no open PR touches it.
Closest, not this bug: #611 / #621 (introduced it; the first revision escaped the term), #10991 (LUCENE-9952), #5860 (LUCENE-4795, 2013: "only the dimension is not allowed to" use the delimiter), #6403 (LUCENE-5339, which introduced the escaping), #747 / #777 / #914 (reuse the skip-the-dimension-ordinal logic, never discuss the encoding), #509 (LUCENE-10250, hierarchical SSDV, escaped), #10432 / #5871 (DELIM_CHAR made public; U+001F chosen), #14008 (wrong taxonomy counts, another cause). Open PRs #12862, #11780 and #16847 touch FacetsConfig or the reader state but not this term. A sibling bug in the same area, found in the same hunt, has an overlapping symptom and another cause.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), downstream repositories, dev@ / java-user@ / issues@ lists, JIRA archive | 2026-10-26 | seven runs of a scripted prior-report search (four follow-up runs: the first run, explicit terms, cache + web, registry-derived terms; plus the finder's, the independent reproducer's and the devil's advocate's) | only the introducing PRs and older escaping discussions; no report |
| GitHub (apache/lucene and all repositories) | 2026-10-26 | 53 manual issue/PR searches, every facet issue (70) and facet PR title (41) created after 2022-01-20, 3 code searches, 41 items and 5 downstream items read in full | no report; no fork escapes the bare term |
| Open PRs | 2026-10-26 | the changed files of all 407 open apache/lucene PRs | #12862, #11780, #16847 touch FacetsConfig or the reader state, not this term |
| Mailing lists, JIRA, web | 2026-10-26 | 23 list queries (13 mails read), 5 JQL queries, 12 web queries | nothing relevant |
Introduced by LUCENE-9952 (PR #611, merged 2022-01-24; backport #621), first released in 9.1.0. A version-neutral probe is wrong on all 32 releases 9.1.0-10.5.2 and on main, with no reserved-name difference on 9.0.0 and 8.11.4; restoring this one line on 9.1.0 makes it pass.
Versions tested6 rows
Introduced by LUCENE-9952 "Fix dim count inaccuracies in SSDV faceting when a dim is multi-valued" (gsmiller): PR #611, 9e560c1af19e on main, merged 2022-01-24; backport PR #621, 225fd1527c8f on branch_9x, the same day. git blame of FacetsConfig.java:494 and git log -S 'new BytesRef(facetField.dim)' point only to these commits. CHANGES, 9.1.0 Bug Fixes: "LUCENE-9952: Address inaccurate dim counts for SSDV faceting in cases where a dim is configured as multi-valued." The same commit made the readers skip the first ordinal of such a dimension. Before 9.1.0 SSDV wrote no bare term for flat dimensions and ignored requireDimCount. Hierarchical SSDV dimensions (LUCENE-10250, also 9.1.0) write their bare term escaped and were never affected. Not fixed upstream; 10.6.0 (released 2026-10-29) was not run, but the prior-art check read the line unchanged on branch_10_6.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the brief's test 4 of 5 fail (gradle and the standalone runner, assertions on and off) |
| 10.5.2, 9.1.0 | affected | the brief's test 4 of 5 fail, assertions on and off (two of the four runs by the fact check); the finder's and the independent reproducer's tests also fail on 9.12.3 |
| 9.1.0-10.5.2 (32 releases) | affected | the version-neutral probe: value=2 instead of 3 and a phantom dimension on each, with assertions off; also with them on for 9.1.0, 9.12.3, 10.0.0 and 10.5.2 |
| 9.0.0, 8.11.4 | not affected | reserved names give the same result as color (no bare term is written; both give value=4, the older sum of label counts) |
9.1.0 with only the bare-dimension line escaped (FacetsConfig.java:511 in 9.1.0) | isolation | the probe passes (run with assertions on) and the finder's test passes with assertions on and off |
| main + fix | not affected | the repro passes; the whole lucene/facet module, 311 tests, 0 failed |
An independent reproducer, a devil's advocate and an intended-lens review by another model family found it real; the refute-lens review could not run Java and agreed with the root cause. The adjudication confirmed it with high confidence, and a registry re-run and an audit reproduced it.
Checks and verdicts397 words
Each check ran its own test against the stock jars, with assertions on and off, except the cross-model reviews, whose environment could not run Java; a separate run re-ran the finder's test.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API JUnit fails 3 of 4 on main (-ea, -da), 10.5.2, 9.12.3 and 9.1.0; passes 4 of 4 with the fix; TestSortedSetDocValuesFacets 18 of 18 with the fix. |
| cross-model review, refute lens | not real (low, procedural) | An independent reviewer from another model family (OpenAI GPT-5.6) could not run Java; it agreed with the root cause, rated the intended-behaviour argument weak and asked for a note on mixed old and new segments. A separate run re-ran the test: 3 of 4 fail. |
| Independent reproducer | real | Own 5-test JUnit with taxonomy and drill-down oracles fails 3 of 5 on main (-ea, -da), 10.5.2, 9.12.3 and 9.1.0; passes with its own one-line fix; phantom dimensions in getAllDims. |
| Cross-model review, intended lens | real (medium) | OpenAI GPT-5.6: the intended-behaviour argument is weak. A separate run re-ran the test on main and 10.5.2 (3 of 4 fail) and with the fix (4 of 4 pass), and a control of the other configurations passes 3 of 3. |
| Devil's advocate | real (high on intent) | Built five not-a-bug arguments and rejected them; found that PR #611's first revision escaped the term; its probe fails 3 of 7 on main and 10.5.2 and passes with the fix. |
| adjudication | confirmed (high) | Silent wrong results; re-ran the independent reproduction's test with -ea and -da (3 of 5 fail, controls pass) and with the fix (5 of 5 pass); related to, but not a duplicate of, the sibling ordering bug. |
| registry re-run and audit | keep | The finder's test fails 3 of 4 with -ea and -da and passes 4 of 4 with the fix. |
| Independent fact and diagram checks | errors fixed | A fact check re-ran the repro (gradle and the standalone runner, -ea and -da, a third seed, 10.5.2 and 9.1.0 both ways), the fix, the history probe on 34 versions, the mixed-segments and whole-field probes and the model; a cross-model fact check (OpenAI GPT-5.6) re-read every citation; a diagram check re-ran the diagram probe. Their wording and precision errors are fixed; none changed the finding or the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 432 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,166 words
- Registry title
- FacetsConfig writes the bare dimension term of a flat multiValued + requireDimCount SortedSetDocValues dimension without escaping it, so a dimension name containing U+001F or U+001E is read back as a different path: the dimension loses one label and reports that label's count as its own, a phantom dimension appears, a name with two U+001F makes facet-state construction throw for the whole field, and (-ea) a name ending in U+001E throws AssertionError
- Area
- facet / SortedSetDocValues faceting (FacetsConfig.processSSDVFacetFields path encoding with DELIM_CHAR U+001F / ESCAPE_CHAR U+001E, decoded by DefaultSortedSetDocValuesReaderState)
- Priority
- Low, rank 331: Needs an opt-in flat multiValued + requireDimCount SortedSetDocValues dimension whose name contains U+001F or U+001E.
- Impact class
- silent wrong results
- Impact note
- Hits only applications that use SortedSetDocValues faceting with a flat dimension configured setMultiValued + setRequireDimCount (opt-in, also reachable through a getDefaultDimConfig override for data-driven dimensions) whose dimension name contains U+001F or U+001E, which the API accepts (FacetField.verifyLabel rejects only null or empty); default codec, IndexWriterConfig and searcher, any scale (3 documents), -ea and -da: getTopChildren drops one label and reports its count as the dimension count, getAllDims lists a phantom dimension, a name with two U+001F makes building DefaultSortedSetDocValuesReaderState throw IllegalArgumentException for every dimension of the facet field (even from a deleted, not yet merged document), and with -ea a name ending in U+001E throws AssertionError; taxonomy faceting, drill-down, search hits and every other SSDV configuration are correct for the same names.
- Summary
- You index three documents under a flat SortedSetDocValues facet dimension named 'color<U+001F>code', configured multiValued and requireDimCount, with labels {x, y}, {x} and {z}, and expect getTopChildren to return value=3 with x=2, y=1, z=1, as taxonomy faceting does for the same name. Instead it returns value=2 with only y=1 and z=1, and getAllDims also shows a phantom dimension 'color' with label 'code'. FacetsConfig escapes U+001F/U+001E in every facet term except this one bare dimension term (FacetsConfig.java:494), while the reader decodes every term as if it were escaped, so the raw term is read back as a different path.
- Introduced
- 9e560c1af19e3d785af52ebb6bdc12b8c75ed125 (LUCENE-9952 / apache/lucene#611 'Fix dim count inaccuracies in SSDV faceting when a dim is multi-valued', author gsmiller, merged 2022-01-24; branch_9x backport 225fd1527c8f78a1837538ea0dcbe3644166ef13, #621) [read: git blame, git log -L491,495 and git log -S 'new BytesRef(facetField.dim)' return only this commit (and only 225fd1527c8f on the 9.1.0 tag history); exec: on the 9.1.0 jars, shadowing FacetsConfig with only this line restored to the escaped encoding of the PR's first revision makes the history probe and the JUnit pass with -ea and -da]. The PR's first revision 74205b42b946 escaped the term (pathToString(facetLabel.components, 1)); review comment r788936337 suggested facetField.dim as an equivalent simplification, the author agreed (r789158522) and commit d9a9621acca2 switched to the raw form; the two are equal only for names without U+001F/U+001E (2022-01-24 (#611 on main and backport #621 on branch_9x, same day))
- First affected version
- 9.1.0 [exec]; last unaffected 9.0.0 [exec] (8.11.4 also executed, not affected): before 9.1.0 SSDV wrote no bare dimension term for flat dimensions and ignored requireDimCount
- Affected versions
- All 32 releases 9.1.0 through 10.5.2, 10.6.0 (by reading) and main a9779ef3c193, never fixed. [exec] the follow-up's version-neutral history probe (relative oracle: the same documents under a dimension named 'color') is wrong on every one of the 32 releases and on main with -da, and on 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main with -ea, and correct on 8.11.4 and 9.0.0; the finder's JUnit fails 3 of 4 on main (-ea and -da), 10.5.2, 9.12.3 and 9.1.0; the independent reproduction's JUnit fails 3 of 5 on main (-ea and -da), 10.5.2, 9.12.3 and 9.1.0; the intended-behaviour check's probe fails 3 of 7 on main and 10.5.2. [read] FacetsConfig.java lines 491-495 are unchanged on main since 2022; branch_10_6 was not in the local clone then and 10.6.0 was not executed; the prior-art check read the line unchanged on branch_10_6. Hierarchical SSDV dimensions write their bare term with pathToString and were never affected. Not executed: x86 (pure Java logic), ConcurrentSortedSetDocValuesFacetCounts (shares the reader state). Runs on JDK 25.0.3, aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- None found (prior-report search re-run 2026-10-26, read-only; closest hits, none the same bug: the introducing PRs #611/#621, whose review replaced the escaped pathToString form with facetField.dim, their issue #10991 (LUCENE-9952), the 2013 escaping debate in LUCENE-4795 (#5860) and LUCENE-5339 (#6403), which introduced the escaping; not fixed on main a95c754ee003 or branch_10_6, and no open PR touches the line
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 9.1.0 release jars with the brief's test, assertions on and off (two of the four runs by the fact check); the follow-up's version-neutral probe on all 32 releases 9.1.0-10.5.2, 9.0.0 and 8.11.4. The fix was validated in the scratch worktree: the new test andTestSortedSetDocValuesFacetswith assertions on and off,TestSortedSetDocValuesFacetswith nightly tests, the wholelucene/facetmodule (311 tests) with assertions on and off, and:lucene:facet:check -x test; plus a probe that reads segments written by the unfixed build with the fixed one.
- Finding record
lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java:474-481 (at a9779ef3c193) (hierarchical bare term via pathToString), :491-495 (flat multiValued + requireDimCount: new BytesRef(facetField.dim), raw), :496-497 (flat label term via pathToString), :595-625 (stringToPath, javadoc 'from a previous call to pathToString', assert !lastEscape at :624)lucene/facet/src/java/org/apache/lucene/facet/sortedset/DefaultSortedSetDocValuesReaderState.java:101-111 (at a9779ef3c193) (every ordinal decoded with stringToPath to find its dimension)lucene/facet/src/java/org/apache/lucene/facet/sortedset/AbstractSortedSetDocValueFacetCounts.java:274-281 (at a9779ef3c193) (ordRange.start() taken as the dimension ordinal and skipped for multiValued + requireDimCount)lucene/facet/src/java/org/apache/lucene/facet/FacetField.java:65-73 (at a9779ef3c193) (verifyLabel rejects only null or empty)
- The finding in 30 seconds
lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java:477-480, (at a9779ef3c193) :491-497 (raw bare term at :494), :543-553 (DELIM_CHAR, ESCAPE_CHAR), :569-593 (pathToString), :595-626 (stringToPath, assert !lastEscape at :624)lucene/facet/src/java/org/apache/lucene/facet/sortedset/DefaultSortedSetDocValuesReaderState.java:101-111, (at a9779ef3c193) :198-206, :209-221lucene/facet/src/java/org/apache/lucene/facet/sortedset/AbstractSortedSetDocValueFacetCounts.java:172-178, (at a9779ef3c193) :274-281, :341-350
- Who is affected
lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java:121-122, (at a9779ef3c193) :143-151; lucene/facet/src/java/org/apache/lucene/facet/FacetField.java:64-73; (at a9779ef3c193) lucene/facet/src/java/org/apache/lucene/facet/sortedset/SortedSetDocValuesFacetField.java:53; (at a9779ef3c193) lucene/facet/src/java/org/apache/lucene/facet/DrillDownQuery.java:51 (at a9779ef3c193)
- Why it looks unintended
lucene/facet/src/java/org/apache/lucene/facet/FacetField.java:64-73; (at a9779ef3c193) lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java:419-460, (at a9779ef3c193) :477-480, :494, :496-497, :595-598; lucene/facet/src/java/org/apache/lucene/facet/sortedset/AbstractSortedSetDocValueFacetCounts.java:103, (at a9779ef3c193) :350-353; lucene/facet/src/java/org/apache/lucene/facet/DrillDownQuery.java:51; (at a9779ef3c193) lucene/facet/src/java/org/apache/lucene/facet/Facets.java:52-57 (at a9779ef3c193)lucene/facet/src/test/org/apache/lucene/facet/taxonomy/TestTaxonomyFacetCounts.java:422-469 (at a9779ef3c193) (testLabelWithDelimiter)
- Suggested fix
lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java:477-480, (at a9779ef3c193) :494
- TestSortedSetDocValuesDimCountReservedChar.java (JUnit test):
repro/LFV-597/src/org/apache/lucene/facet/sortedset/TestSortedSetDocValuesDimCountReservedChar.java(52 lines)
A step-by-step picture of the repro's first failing case, made in parallel with this doc from an executed probe on main a9779ef3c193 and the code; the PNG is the final summary card. The alt text describes the intended content.
assets/LFV-597/bug.png(432 KB)