The delimitedPayload filter turns word|1.0 into the term word with a payload, made by a PayloadEncoder. For a custom encoder class, the factory creates one instance and gives that same object to the filter of every thread. If encode() reuses its output BytesRef, another thread overwrites a payload before the indexer copies it.
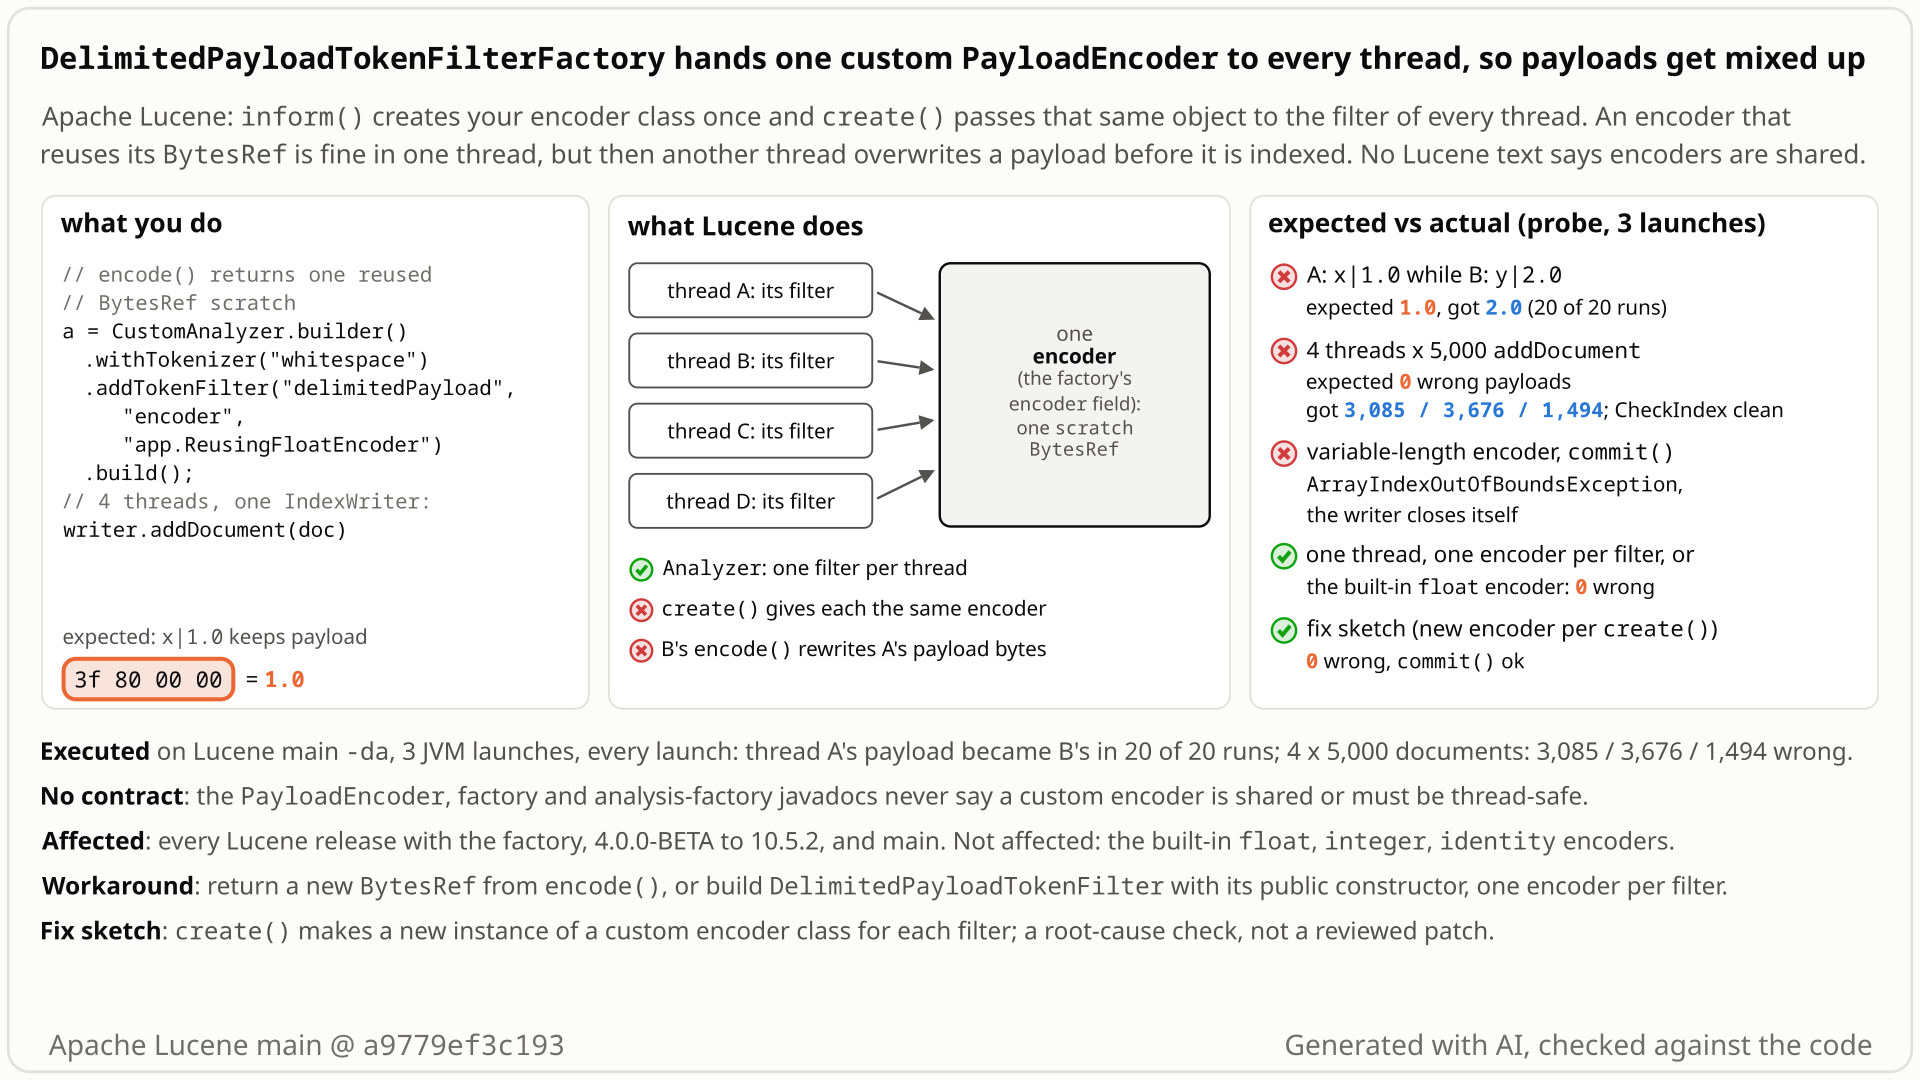
BytesRef, loaded by class name, used by 4 threads), what Lucene does (4 filters, one shared encoder), and what happens on main: thread A sees 2.0 instead of 1.0, and 1,494 to 3,676 of 20,000 documents get a wrong payload. Select the still to open it at full size. Generated with AI, checked against the code.- You plug your own encoder into the factory by class name:
addTokenFilter("delimitedPayload", "encoder", "com.example.ReusingFloatEncoder"). To avoid allocating, itsencode()fills and returns one reused 4-byteBytesRef. On one thread,x|1.0gives payload 1.0, as it should. - You index
t0|0,t1|1, ...,t19999|19999from 4 threads through oneIndexWriter. You expect every term to keep its own payload, as it does with one thread, with the built-infloatencoder, or with one encoder per filter. - Instead every run stores a wrong payload (another document's, or a torn mix of bytes) on hundreds to thousands of documents: 2,992 of 20,000 in one run, where
t0stored 10000.0. There is no exception, andCheckIndexfinds nothing. - The cause: the factory creates your encoder once and passes that one object to every filter it creates. The analyzer has one filter per thread, so thread B's
encode()rewrites the bytes that thread A's filter just handed to the indexer, before the indexer copies them. - With a variable-length encoder (a reused
BytesRefBuilder),commit()throwsArrayIndexOutOfBoundsException, theIndexWritercloses itself and all 12,000 uncommitted documents are lost. The built-in encoders return a newBytesRefper call and are not affected.
Applications that load their own encoder class through this factory (CustomAnalyzer, the SPI name or a Solr schema) whose encode() keeps per-instance state, and that use the analyzer from several threads, as any multi-threaded IndexWriter does. The built-in float, integer and identity encoders, and Elasticsearch and OpenSearch, are not affected.
Mechanism, terms and numbers880 words
DelimitedPayloadTokenFilterFactory (SPI name delimitedPayload) accepts encoder=float|integer|identity or the fully qualified name of your own PayloadEncoder class. For a class name, inform() creates one instance (DelimitedPayloadTokenFilterFactory.java:82) and create() passes that same instance to every DelimitedPayloadTokenFilter it builds (:69-71). An Analyzer keeps one set of components per thread (Analyzer.java:91-96), and CustomAnalyzer calls create() once per thread on its single factory (CustomAnalyzer.java:161-168), so every thread calls the same encoder object. The filter stores the returned BytesRef by reference (DelimitedPayloadTokenFilter.java:59) and the indexing chain copies it a moment later (FreqProxTermsWriterPerField.java:88-92). An encoder that reuses one BytesRef is correct when only one token stream uses it, because the consumer copies the payload bytes before it asks that stream for the next token; through the factory every thread uses the same encoder, and another thread's encode() overwrites the bytes first. With 4 threads x 5,000 addDocument calls, 384 to 7,153 of 20,000 documents silently stored a wrong payload (another document's, or a torn mix of bytes) across all runs, and CheckIndex stayed clean. With a variable-length encoder the commit's flush throws and the IndexWriter closes itself, losing every document since the last commit. PayloadEncoder, the factory and the factory lifecycle docs say nothing about sharing or threads, while PhoneticFilterFactory and SnowballPorterFilterFactory, the siblings that load a class by name, create one instance per create(). Nothing Lucene ships is affected: the built-in encoders return a new BytesRef per call, so this is a documentation and hardening defect (impact class minor). Affected: every release from 4.0.0-BETA to 10.6.0 (10.6.0 by reading), and main. Creating a new custom encoder per create() fixes it; with that change the whole :lucene:analysis:common:test suite passes.
DelimitedPayloadTokenFilter: splits a token such asword|1.0at the delimiter, keepswordas the term and turns1.0into the token's payload (bytes stored at that position in the index) with aPayloadEncoder. Built-in encoders:float,integer,identity; any other value of the factory'sencoderargument is loaded as a class name.- Per-thread components: an
Analyzerbuilds its tokenizer and filters once per thread and reuses them (Analyzer.java:91-96).CustomAnalyzerbuilds them by callingcreate()on the same factory objects in every thread (CustomAnalyzer.java:161-168). - Payload ownership: a filter hands the payload to the consumer as a
BytesRefin itsPayloadAttribute. The consumer reads it before it callsincrementToken()again, and a filter that keeps a token for later gets a deep copy (captureState()clones the attributes;PayloadAttributeImpl.clone()andcopyTo()useBytesRef.deepCopyOf), so a producer may reuse oneBytesRefwithin its own stream; Lucene's own test filterPayloadSetterdoes ("reuse the payload / byte[]"). Between twoincrementToken()calls the attributes belong to the caller (TokenStream.java:124-127).
inform()creates the custom encoder once:encoder = loader.newInstance(encoderClass, PayloadEncoder.class);(DelimitedPayloadTokenFilterFactory.java:82, field at:51).create()passes that same object to every filter:return new DelimitedPayloadTokenFilter(input, delimiter, encoder);(:69-71). With 4 indexing threads, 4 filters share one encoder.- The filter stores the returned
BytesRefby reference:payAtt.setPayload(encoder.encode(buffer, i + 1, (length - (i + 1))));(DelimitedPayloadTokenFilter.java:59). - The indexing chain copies the payload right after
incrementToken()returns, inFreqProxTermsWriterPerField.writeProx: it writespayload.length(:91) and then the bytes (:92). In between, thread B'sencode()on the same object has rewritten the shared bytes, so A's document stores B's value, or a torn mix of bytes (the delivered test once stored 2.2959E-41 fort0, whose payload is 0.0). - With a variable-length encoder (
BytesRefBuilder.copyCharsgrows the array, then sets the length), the length can change between:91and:92; the in-memory position stream gets out of step and the flush that decodes it fails inFreqProxFields$FreqProxPostingsEnum.nextPosition. A flush exception is an aborting exception: the flush aborts and fires a tragic event (DocumentsWriterPerThread.java:585-587,:594-605), and on a tragic event the writer rolls back and closes (IndexWriter.java:6098-6106), so every document since the last commit is lost. The length change between the two lines is read from the code, not instrumented.
New JUnit class through gradle on main, 13 runs each (assertions off twice, on once, and 10 repetitions): the latch test sees 2.0 instead of 1.0 every time; 4 threads x 5,000 addDocument give 693 to 2,992 of 20,000 documents with a wrong payload; the variable-length test's commit() fails 13 of 13 with the writer closed. Across all earlier runs on main and releases: 384 to 7,153 of 20,000. In the security screen's 30 variable-length rounds, addDocument never threw, the commit failed every time, all 12,000 new documents were lost, and the earlier commit stayed CheckIndex-clean. Controls (one encoder per filter; the built-in float encoder through the factory): 0 wrong in every run.
The concurrent user can also be query parsing with the same Analyzer object: two threads analysing q|666.0 with QueryBuilder made 170 to 828 of 10,000 concurrently indexed documents store 666.0, and variable-length query payloads closed the writer in 11 of 15 rounds. These counts reflect the probe's load (two threads analysing queries continuously while two threads indexed): they show the path is reachable, not how often it happens in practice.
Exposure and likelihood363 words
- Who is exposed. Users of
encoder=<your class>: throughCustomAnalyzerwithdelimitedPayload, the SPI name, or a Solr schema. Theirencode()must keep per-instance state, such as a reusedBytesReforBytesRefBuilder, a natural allocation-saving choice that is safe while only one token stream uses the encoder. - What it takes. More than one thread using the analyzer:
IndexWriteris "completely thread safe" and its indexing threads share the one analyzer of its config (IndexWriter.java:167-168); query parsing with the sameAnalyzerobject counts too. One thread is enough when two filters from the same factory are consumed interleaved (the independent reproducer'stestTwoFiltersFromOneFactory, direct factory use: stream A reads 2.0, not 1.0). No special input and no scale, assertions on or off, 4 threads. The tests set no codec,IndexWriterConfigor JVM option (a plainnew IndexWriterConfig(analyzer)); through gradle the test framework chose its randomized environment (recorded: codecAsserting(Lucene104)) and the build's default test JVM options, and the security probe, a plainmain()with the default codec, failed the same way. - What the damage looks like. Fixed-length encoder: wrong payloads in the index with no exception, and
CheckIndexclean, so payload scoring and payload checks use wrong values. Variable-length encoder: the next flush throws, the writer closes itself and every document since the last commit is lost; in the security screen it happened again in every round, each with a new writer and directory. No memory corruption; every surviving commit wasCheckIndex-clean. - Not affected. The built-in encoders (a new
BytesRefper call); custom encoders that return a newBytesRefper call and keep no other mutable state; the filter built through its public constructor with one encoder per filter; one thread that consumes one token stream at a time, as a single indexing thread does (probe: 0 of 20,000 wrong). Elasticsearch and OpenSearch accept only the built-in encodings (read from their code, not run). - How likely. Rare (registry): it needs a user-written stateful encoder loaded by class name; the only public custom encoders found that are used through this factory allocate per call, and the saved searches found no report since the factory was added in 2009.
The test shows that two filters created by one DelimitedPayloadTokenFilterFactory (as an Analyzer creates one per thread) share the one custom PayloadEncoder instance made in inform(), so an encoder that reuses its BytesRef lets filter b overwrite filter a's payload.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.payloads;

import java.io.StringReader;
import java.util.HashMap;
import java.util.Map;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.analysis.tokenattributes.PayloadAttribute;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;
import org.apache.lucene.util.ClasspathResourceLoader;

public class TestDelimitedPayloadFactoryEncoderSharing extends LuceneTestCase {

  public static final class ReusingFloatEncoder extends AbstractEncoder {
    private final BytesRef scratch = new BytesRef(new byte[4]);

    @Override
    public BytesRef encode(char[] buffer, int offset, int length) {
      float value = Float.parseFloat(new String(buffer, offset, length));
      PayloadHelper.encodeFloat(value, scratch.bytes, 0);
      return scratch;
    }
  }

  public void testFiltersFromOneFactoryKeepTheirOwnPayloads() throws Exception {
    Map<String, String> args = new HashMap<>();
    args.put("encoder", ReusingFloatEncoder.class.getName());
    DelimitedPayloadTokenFilterFactory factory = new DelimitedPayloadTokenFilterFactory(args);
    factory.inform(new ClasspathResourceLoader(getClass()));
    TokenStream a = factory.create(whitespace("x|1.0"));
    TokenStream b = factory.create(whitespace("y|2.0"));
    PayloadAttribute payloadA = a.addAttribute(PayloadAttribute.class);
    a.reset();
    b.reset();
    assertTrue(a.incrementToken());
    assertTrue(b.incrementToken());
    BytesRef p = payloadA.getPayload();
    // expected: x|1.0 keeps payload 1.0; actual: 2.0, written by b through the shared encoder
    assertEquals("payload of x|1.0", 1.0f, PayloadHelper.decodeFloat(p.bytes, p.offset), 0f);
  }

  private static Tokenizer whitespace(String text) {
    Tokenizer t = new WhitespaceTokenizer();
    t.setReader(new StringReader(text));
    return t;
  }
}
# in a copy of this finding's repro folder (repro/LFV-598/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.payloads.TestDelimitedPayloadFactoryEncoderSharing
- Expected vs actual
- Expected: a's token
x|1.0keeps payload 1.0 after b readsy|2.0. Actual:payload of x|1.0 expected:<1.0> but was:<2.0>(single thread, -ea and -da).
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: payload of x|1.0 expected:<1.0> but was:<2.0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:577)
org.apache.lucene.analysis.payloads.TestDelimitedPayloadFactoryEncoderSharing.testFiltersFromOneFactoryKeepTheirOwnPayloads(TestDelimitedPayloadFactoryEncoderSharing.java:57)- No text says the encoder is shared or must be thread-safe; since 2009 the only stated precondition for a custom class is a no-arg constructor.
- Reusing the returned
BytesRefis safe inside one stream; a Lucene test filter does it. - Sibling factories that load a class by name create one instance per filter (
PhoneticFilterFactory, after a 2012 thread-safety fix).
The full argument387 words
- No text states the precondition.
PayloadEncoder's javadoc is "Mainly for use with the DelimitedPayloadTokenFilter, converts char buffers to BytesRef. NOTE: This interface is subject to change";encodesays "Convert a char array to a BytesRef / @return encoded BytesRef" (PayloadEncoder.java:21-35). The factory javadoc shows onlyencoder="float"(DelimitedPayloadTokenFilterFactory.java:25-38), andAbstractAnalysisFactorysays only "Consumer calls create() to obtain instances" (AbstractAnalysisFactory.java:45-52). A grep for "thread" finds nothing in these files or inTokenFilterFactory,ResourceLoader(Aware),CustomAnalyzerandPayloadAttribute(Impl);Analyzermentions threads only for its own per-thread reuse of components (Analyzer.java:91-96), not for factories or the objects they hold. - The custom-class path was designed in. The commit that added the factory (SOLR-1285,
b5620d86146, 2009) documented it in the example schema: "Fully Qualified class name implementing PayloadEncoder Encoder must have a no arg constructor." Thread safety is not in that list. - Reuse is an accepted pattern inside one stream. The consumer reads the payload before the next
incrementToken(), a filter that keeps a token gets a deep copy (captureState();PayloadAttributeImpl.clone()andcopyTo()), andTestAnalyzers.PayloadSetterreuses oneBytesRef("reuse the payload / byte[]"). - The token-stream contract gives the attributes to the caller.
TokenStream.incrementToken(): "The producer must make no assumptions about the attributes after the method has been returned: the caller may arbitrarily change it" (TokenStream.java:124-127). Between two calls the payload belongs to that stream's consumer; a shared encoder lets a different stream rewrite its bytes in that window. - Siblings create one instance per filter.
PhoneticFilterFactory.getEncoder(): "Must be thread-safe." "Unfortunately, Commons-Codec doesn't offer any thread-safe guarantees so we must play it safe and instantiate every time." (PhoneticFilterFactory.java:160-166). That came from SOLR-3424, "PhoneticFilterFactory thread-safety bug" (9707be81c1c, 2012), where a committer wrote that user-provided classes "may not be thread safe (unless this is explicitely specified in their spec / javadocs - which isn't)".SnowballPorterFilterFactoryresolves the class once and creates a new stemmer percreate()(:83,:94). - At least one comparable factory states its sharing assumption.
Word2VecSynonymProviderFactory: "Assumes synonymProvider implementations are thread-safe." (:29). Factories that share plain data (stop sets, maps) do not say so. - Precedent for the bug class. LUCENE-2943 (#4017, 2011): an ICU
Collatorshared across threads' token streams, fixed by cloning per stream.
The devil's-advocate check241 words
Every checker built the strongest case for "intended": objects a factory builds in inform() are conventionally shared by all its filters and so by all threads (stop sets, SynonymMap, dictionaries); the built-in encoders return a new BytesRef per call and are safe to share, and the interface reads as a pure function; the factory javadoc never advertises the custom-class path; so a stateful encoder is the user's bug, and a committer may close it as user error or answer with one javadoc sentence.
Why it fails as a reason to do nothing: those shared objects are immutable data, while an encoder is user code with an output buffer; no text tells the user it is shared; the custom path was documented with a precondition list that leaves thread safety out; the 2012 sibling fix decided the same question the other way; and at least one comparable factory states its sharing assumption. It is still why the row is minor: there is no broken contract, only a missing one, and a javadoc-only fix is a legitimate answer (option B). Verdict: not intended as written; a documentation and hardening defect. The one "not real" review had two grounds: it could not run its own repro, so it voted not real on procedure, and it judged the class-name path outside the documented inputs because the factory javadoc shows only encoder="float" (the 2009 schema comment speaks against that); it agreed on the mechanism.
Recommended A. A new custom encoder per create(), as the sibling factories do
Create a new instance of a custom encoder class in every create(), as PhoneticFilterFactory and SnowballPorterFilterFactory do. The built-in encoders (a new BytesRef per call) stay shared, and inform() still builds one instance so a bad class name fails early. Validated: the new test passes, also 50 of 50 repetitions, and all of :lucene:analysis:common:test passes.
All options and trade-offs4 options · 748 words
Options A and A2 were applied in a scratch worktree of a9779ef3c193 and run through gradle; the worktree was removed afterwards. Option B is documentation only. A workaround for users today: return a new BytesRef from encode(), or build the filter in your own Analyzer.createComponents with new DelimitedPayloadTokenFilter(input, '|', new MyEncoder()).
A. A new custom encoder per create(), as the sibling factories do (validated by the checks) (recommended)
+16/-1 in DelimitedPayloadTokenFilterFactory: inform() still creates one instance through the ResourceLoader (early errors) and remembers its class; create() passes the shared built-in encoder, or a new instance of the custom class.
   private PayloadEncoder encoder;
+  // set for a custom encoder class: create() then makes a new instance for every filter, because
+  // the filters of all threads using the analyzer would otherwise share one, and nothing requires a
+  // PayloadEncoder implementation to be thread-safe
+  private Class<? extends PayloadEncoder> customEncoderClass;
@@
   public DelimitedPayloadTokenFilter create(TokenStream input) {
-    return new DelimitedPayloadTokenFilter(input, delimiter, encoder);
+    return new DelimitedPayloadTokenFilter(
+        input, delimiter, customEncoderClass == null ? encoder : newCustomEncoder());
+  }
+
+  private PayloadEncoder newCustomEncoder() {
+    try {
+      return customEncoderClass.getConstructor().newInstance();
+    } catch (ReflectiveOperationException e) {
+      throw new IllegalArgumentException("Cannot create payload encoder: " + encoderClass, e);
+    }
   }
@@
     } else {
+      // one instance now, so that a bad class name fails here
       encoder = loader.newInstance(encoderClass, PayloadEncoder.class);
+      customEncoderClass = encoder.getClass();
     }
Trade-offs
- One reflective construction per
create(): once per thread and analyzer withCustomAnalyzer(the defaultGLOBAL_REUSE_STRATEGY), not per token or document.PhoneticFilterFactory's comment calls the same pattern "negligible". getConstructor().newInstance()is what the defaultResourceLoader.newInstancedoes (ResourceLoader.java:33-40) and what both siblings do, but it bypasses a customResourceLoaderthat overridesnewInstance; option A2 keeps that hook.- A custom encoder that is expensive to construct, or that relies on being one shared instance, changes behaviour.
What the checks validated
TestDelimitedPayloadFactorySharedEncoderpasses with assertions off, and 50 of 50 with-Ptests.iters=10and assertions on (stock: 30 of 50 fail). With the existing payload tests: 6 classes, 15 tests, 0 failures.- All of
:lucene:analysis:common:testwith assertions on: 340 classes, 1,914 tests, 18 skipped, 0 failures, 0 errors. :lucene:analysis:common:check -x testpasses (checkGoogleJavaFormat,ecjLint,forbiddenApis) with the new test file.- Earlier: the original hunt test (4 of 4) and the independent reproducer's 5 tests (5 of 5, also with a new seed) pass with the same approach, and so does the version-portable check.
Keep the ResourceLoader given to inform() and call loader.newInstance(encoderClass, PayloadEncoder.class) in create() for a custom class (+11/-1).
Trade-offs
Honours a custom ResourceLoader's instantiation (a hunt reviewer asked for this), but the factory, and so the analyzer, keeps the loader (possibly with a class loader) reachable for its lifetime and uses it after inform(), which the lifecycle text does not describe. How Solr's loader behaves when called after core initialisation was not checked.
What the checks validated
The payload tests (org.apache.lucene.analysis.payloads.*, the new class included): 6 classes, 15 tests, 0 failures; checkGoogleJavaFormat passes. The module suite, check and repetitions were run only for A.
If maintainers prefer one shared instance, the javadoc of PayloadEncoder and of the factory must say more than "thread-safe": the factory shares one instance of a custom class among all its filters and so all threads; encode() must be safe to call concurrently and must return a new BytesRef, or one that is never modified afterwards, on every call, because the filter keeps the returned reference until the consumer has copied it. A synchronized encode() that returns a shared scratch BytesRef is still broken.
Trade-offs
No code and no cost, but users with a stateful encoder keep the silent failure until they read the javadoc; the new test would then document misuse instead of failing. Not run.
payAtt.setPayload(BytesRef.deepCopyOf(encoder.encode(...))).
Trade-offs
One more allocation per token for the built-in encoders, and it does not help when two threads run encode() on the same scratch buffer at the same time: the copy itself can see the other thread's writes (reasoned from the code, not run). A ThreadLocal encoder in the factory would cover the threads but adds state and still shares one encoder between two filters on one thread; one encoder per filter covers both.
Solr passes a schema's encoder class name to this factory, so a Solr plugin encoder that reuses its BytesRef would be affected (and a field type with a single analyzer also sends query text through it); Elasticsearch and OpenSearch accept only the built-in encoders (read from their code, not run).
An inventory of the state analysis factories hand to their components listed this factory's encoder and classed it safe, because the built-in encoders are safe to share. An independent reviewer from another model family (OpenAI GPT-5.6), asked to attack that result, pointed out that a user-named encoder class has no thread-safety contract; a deterministic two-thread test then confirmed it.
The method in full147 words
Method: a shared-state inventory plus a directed test (registry tier semi-formal: no formal tool produced the counterexample).
- The hunt unit on shared state in analysis components built a bytecode inventory of the factory and
Analyzerfields that reach token-stream components. It listedDelimitedPayloadTokenFilterFactory.encoder, read increate(), and classed it safe because the three built-in encoders are safe to share. - An independent reviewer from another model family (OpenAI GPT-5.6), asked to refute that negative result, named the hole: a closure over the shipped classes cannot cover a user-named encoder class whose interface promises nothing about threads.
- The finder then wrote the public-API JUnit with a deterministic latch interleaving and concurrent
IndexWriterindexing, measured the hit rate (20 of 20 with assertions off; the per-filter control 0 of 20), ran it with assertions on and off, on 10.5.2 and on 9.12.3, and checked the per-create()fix.
No prior report found (searched 2026-10-26): GitHub issues, PRs and commits, the changed files of all 407 open PRs, the LUCENE and SOLR JIRA archives, the Lucene and Solr mailing lists, downstream projects and the web. The closest items fixed the same bug class elsewhere: SOLR-3424 (PhoneticFilterFactory, 2012) and LUCENE-2943 (a shared ICU Collator, 2011).
Searches5 searches
No report was found of DelimitedPayloadTokenFilterFactory sharing one instance of a user-named PayloadEncoder, or of PayloadEncoder lacking a thread-safety statement. Some later GitHub searches were rate-limited, and searches cannot prove absence.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search, two runs | 2026-10-26 | 51 queries (GitHub, commits, downstream, lists, JIRA, web): 3,033 hits; then 100 queries with class names, newInstance and symptoms over apache/lucene, downstream repositories, the dev@, java-user@, java-dev@, general@, solr-user@ and solr-dev@ lists and the LUCENE and SOLR JIRA archives: 1,661 hits | the first run's two high hits are unrelated thread-safety items (#412, #11955); the second's 3 medium hits (LUCENE-7866, LUCENE-2510, LUCENE-2943) were read: none is this bug |
| GitHub (manual) | 2026-10-26 | 16 phrasings on apache/lucene issues and PRs: class names, "PayloadEncoder thread", "encoder shared threads factory", ... | only unrelated #4822, #3584, #5942, #2465, #8917, #3233, #8681 |
| Open apache/lucene PRs | 2026-10-26 | the changed files of all 407 open PRs | none touches analysis/payloads, PayloadEncoder, AbstractAnalysisFactory or ResourceLoader |
| JIRA, lists, downstream, web | 2026-10-26 | 13 JIRA issues on PayloadEncoder / DelimitedPayloadTokenFilter(Factory) read; 79 list messages scanned; Elasticsearch, OpenSearch, Solr and Lucene.NET; 8 web queries | no report; SOLR-14151 and apache/solr#2707 show an outside Base64Encoder used through this factory (class-loading issues), which allocates per call |
| Related items (read) | 2026-10-26 | SOLR-3424, LUCENE-2943 (#4017), LUCENE-7866, SOLR-1285, LUCENE-1676, LUCENE-2510 | SOLR-3424 and LUCENE-2943: the same bug class fixed in other components (per-create() instances; clone per stream); LUCENE-7866: the random tests cannot pick a specific encoder for this filter; the origin issues never discuss threads |
Written with the factory in Solr in 2009 (SOLR-1285, b5620d86146) and moved into Lucene with its sharing unchanged in 2012 (LUCENE-2510); first Lucene release 4.0.0-BETA. Reproduced on 14 releases from 4.0.0-BETA to 10.5.2 and on main; 4.0.0-ALPHA has no such factory. Not fixed upstream.
Versions tested9 rows
Introduced by SOLR-1285 "Add DelimitedPayloadTokenFilterFactory, tests and short example" (b5620d86146, 2009-07-16; SVN era, no pull request): one encoder field, set in inform(), passed in create(). git blame -w -M -C on main attributes lines 51, 68-71 and 74-84 of the factory to it, except line 82, which SOLR-3357 (a4cbd8a6051, 2012-04-17) changed only to the typed loader.newInstance(encoderClass, PayloadEncoder.class). Into Lucene with LUCENE-2510 (#3584): branch commit fe2d1194fb6 (2012-07-24), trunk merge 142d3c788fa and branch_4x merge 677846e6a0f (2012-07-25); first release 4.0.0-BETA (tagged 2012-08-10). Solr 1.4.0 to 4.0.0-ALPHA shipped the same sharing pattern in Solr's own package (read, not run). The trunk merge changed only the package and added a check for a missing encoder argument.
At every release tag the factory has the same shape; later changes were annotations, javadoc, argument parsing (4.3), the SPI name (8.3), package moves and the SPI default constructor (9.0), and formatting. SOLR-3424 fixed the same pattern in PhoneticFilterFactory in May 2012, about two and a half months before this factory moved into Lucene with its sharing unchanged. All runs used JDK 25 on aarch64 Linux; 14 releases and main were run (and 4.0.0-ALPHA, which has no factory), and the other releases rest on the unchanged code.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the new test fails 3 of 5 through gradle (assertions off and on); 30 of 30 bug-test repetitions fail; every hunt and verifier JUnit fails |
| 10.5.2, 10.0.0 | affected | portable check affected; index-level JUnit 4,930-6,001 of 20,000 wrong (10.5.2 also with -da: 4,175) |
| 9.12.3, 9.0.0 | affected | portable check affected; index-level JUnit 5,110 and 5,929 of 20,000 wrong |
| 8.11.4, 8.0.0 | affected | portable check affected; index-level JUnit 7,116 and 6,628 of 20,000 wrong |
| 7.7.3, 6.6.6, 5.5.5, 5.0.0 | affected | portable check affected (thread A reads 2.0, not 1.0) |
| 4.10.4, 4.3.0, 4.0.0 | affected | portable check affected |
| 4.0.0-BETA | first release | portable check affected: the two filters share one encoder; A reads 2.0 |
| 4.0.0-ALPHA | no such API | the filter exists, the factory does not |
| main + per-create() fix | not affected | portable check passes; the new test passes 5 of 5 and 50 of 50 with -Ptests.iters=10 |
An independent reproducer, an intended-behaviour devil's advocate and an adjudication each re-ran and confirmed it; reading-only reviews by a reviewer from another model family (OpenAI GPT-5.6) agreed on the mechanism, one calling it real, one not real (no repro; class-name path judged undocumented). A credibility audit kept it, and this doc's gradle run validated the fix.
Checks and verdicts375 words
Every executed check ran public-API tests on the stock jars; the run records are in the sources. Neither GPT review executed code; a separate run re-ran the original test on main (2 of 4 fail) both times.
| Check | Verdict | What it found |
|---|---|---|
| Independent reproducer | real | Own 5-test JUnit fails 3 of 5 on main (assertions on and off), 10.5.2 and 9.12.3 (5,005 to 7,098 of 20,000 wrong); 10 of 10 repetitions fail, control 0 of 10; passes 5 of 5 with the fix. |
| Cross-model review, intended lens | real (medium) | OpenAI GPT-5.6, reading only: the intended-behaviour argument is moderate but not enough, since no API text states the precondition and the siblings instantiate per filter; asked that a fix keep ResourceLoader.newInstance. |
| Cross-model review, refute lens | not real (medium): not reproduced, input judged undocumented | Could not run its own repro, so the refute-lens review voted not real on procedure; argued the class-name path is outside the documented inputs, which the 2009 schema comment speaks against; agreed on the mechanism. A separate run re-ran the original test with assertions on and off: 2 of 4 fail each. |
| Intended-behaviour devil's advocate | real (medium) | Built the strongest "user error" case and showed why it fails (thread grep, the 2009 schema comment, SOLR-3424, Word2Vec, PayloadSetter); asked that a javadoc fix require a new or never-modified BytesRef. |
| Adjudication | confirmed (medium), minor | Re-ran the independent reproduction's test on main with a new seed (3 of 5 fail, controls pass) and with the fix (5 of 5 pass); classed it a documentation and hardening defect. |
| Version sweep and security screen | 14 releases and main; not security-sensitive | Affected on 14 releases and main; the probe added the variable-length tragic close and the query-side trigger. Re-evaluated under the strict rule: not security-sensitive. |
| Credibility audit | keep | Re-ran the original test with a new seed (2 of 4 fail, 6,807 of 20,000 wrong); impact already at the floor. |
| This doc's gradle validation | fails on stock, fix validated | The new test class through gradle: 3 of 5 fail on stock (assertions off, on, 10 repetitions); fix A passes it, the whole module suite and check; fix A2 passes the payload tests. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 498 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,505 words
- Registry title
- DelimitedPayloadTokenFilterFactory creates one instance of a custom PayloadEncoder class and hands it to every filter it creates, so all threads using the analyzer share it, and nothing documents that a custom encoder must be thread-safe: an encoder that reuses its BytesRef silently stores other documents' payloads during ordinary concurrent indexing, and one whose payloads vary in length makes the next flush throw and the IndexWriter close itself
- Area
- analysis / analysis-common payloads (DelimitedPayloadTokenFilterFactory, PayloadEncoder, DelimitedPayloadTokenFilter)
- Priority
- Low, rank 505: Payloads get silently mixed up only with a user-written stateful PayloadEncoder loaded through the factory, which is a documentation and hardening gap rather than a broken contract.
- Impact class
- minor
- Impact note
- Hits only applications that give DelimitedPayloadTokenFilterFactory their own encoder class (encoder=<class name>, through CustomAnalyzer's 'delimitedPayload', the SPI name or a Solr schema) whose encode() keeps per-instance state such as a reused BytesRef, and that use the analyzer from several threads, which is normal for IndexWriter; default codec, IndexWriterConfig and JVM settings (-ea and -da), no scale (4 threads x 5,000 documents), every release since 4.0.0-BETA: hundreds to about 7,000 of 20,000 documents silently get another document's payload (CheckIndex does not notice), and with a variable-length encoder the next flush throws and the IndexWriter closes itself, losing every document since the last commit; the built-in float, integer and identity encoders are unaffected, and the row is classed minor because no Lucene text states either the sharing or a thread-safety requirement, so it is a documentation and hardening defect rather than a broken contract.
- Summary
- You configure DelimitedPayloadTokenFilterFactory with your own PayloadEncoder class whose encode() reuses one BytesRef, which is correct inside any single token stream because PayloadAttributeImpl deep-copies payloads, and you index from four threads; you expect every document to keep its own payload, as it does when each filter gets its own encoder through the public constructor. Instead the factory creates the encoder once in inform() and passes that one instance to every filter in create(), so the per-thread analyzer components share it and another thread's encode() overwrites a payload before the indexer reads it: on main, 384 to 7,153 of 20,000 documents end up with another document's payload, with no exception. PayloadEncoder, the factory and the analysis-factory javadocs say nothing about the encoder being shared or needing to be thread-safe, while the sibling PhoneticFilterFactory creates its class-loaded encoder per filter for exactly this reason.
- Introduced
- b5620d8614606e70241db30e117d32404010be84 (SOLR-1285 'Add DelimitedPayloadTokenFilterFactory, tests and short example', Grant Ingersoll, 2009-07-16, Solr trunk svn r794669) [read: git blame on main attributes lines 51, 68-71 and 74-84 of the factory to this commit, except line 82, which a4cbd8a6051 (SOLR-3357, 2012-04-17) changed only to the typed loader.newInstance(encoderClass, PayloadEncoder.class)]. The factory entered a Lucene artifact unchanged with LUCENE-2510 (GitHub #3584, factories moved from Solr to the analysis module): branch commit fe2d1194fb6 ('apply movefactories.sh', Robert Muir, 2012-07-24), trunk merge 142d3c788fa and branch_4x merge 677846e6a0f (Uwe Schindler, 2012-07-25), the latter putting it into the 4.0 release line. No pull request (Subversion era) (2009-07-16 (Solr code, SOLR-1285); 2012-07-25 (moved unchanged into Lucene's analysis module and branch_4x, LUCENE-2510))
- First affected version
- Lucene 4.0.0-BETA [exec] (pre-release, tagged 2012-08-10; first GA release 4.0.0 [exec]); 4.0.0-ALPHA and earlier have the filter but not the factory [exec on 4.0.0-ALPHA]; Solr 1.4.0 to 4.0.0-ALPHA shipped the same code as org.apache.solr.analysis.DelimitedPayloadTokenFilterFactory [read, not executed]
- Affected versions
- Every Lucene release from 4.0.0-BETA through 10.6.0 (10.6.0 by reading), and main a9779ef3c193; never fixed. [exec] the follow-up's version-portable stream check (two filters from one factory, one and two threads, controls: built-in float encoder through the factory and the custom encoder through the public constructor) is AFFECTED on 4.0.0-BETA, 4.0.0, 4.3.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main and passes with the fix shadowed; the index-level JUnit (4 threads x 5,000 documents) fails on 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea; -da on 10.5.2 and main), 4,003 to 7,116 of 20,000 documents wrong; the finder's JUnit fails 2 of 4 on main (-ea and -da), 10.5.2 and 9.12.3; the independent reproduction's JUnit fails 3 of 5 on main (-ea and -da), 10.5.2 and 9.12.3; the security probe's facts hold on main (-ea, -da) and 10.5.2 (-da). [read] at every release tag in the history clone (lucene-solr 4.0.0-beta to 8.8.1, lucene 9.0.0 to 10.5.2) the factory has the same shape (one encoder field, set once in inform(), passed to every filter in create()); 8.8.2 to 8.11.x are not tagged in the clone (8.11.4 executed); the same factory blob is on origin/main a95c754ee00, and branch_10x and branch_10_6 carry the 10.x blob (refs fetched 2026-10-26). The 7 commits between ea57360912ed and a9779ef3c193 do not touch lucene/analysis. Built-in encoders were stateless at every point checked [read]. Runs on JDK 25.0.3, aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code and voted “not real” while agreeing with the root cause (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (2026-10-26, read-only; the follow-up's: 100 queries over apache/lucene issues, PRs and commits, downstream repositories, the dev@, java-user@, java-dev@, general@, solr-user@ and solr-dev@ lists and the LUCENE and SOLR JIRA archives, 1,661 hits, 0 high, 3 medium: LUCENE-7866, LUCENE-2510, LUCENE-2943, all read, none this bug), 16 manual gh search phrasings (only unrelated #4822, #3584, #5942, #2465, #8917, #3233, #8681), all 407 open apache/lucene PRs scanned by changed files (none touches analysis/payloads, PayloadEncoder, AbstractAnalysisFactory or ResourceLoader), 13 JIRA issues on PayloadEncoder / DelimitedPayloadTokenFilter(Factory) read, 79 list messages scanned, downstream repositories and 8 web queries. Closest items are precedents of the same bug class in other components, not partial overlaps: LUCENE-2943 (#4017, an ICU Collator shared across threads, fixed by cloning per stream) and SOLR-3424 (PhoneticFilterFactory thread-safety fix, whose 2012 discussion states that user-provided classes may not be thread safe unless their javadocs say so), plus the registry sibling LFV-483. Some later GitHub searches were rate-limited.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree, removed afterwards: the new test class on stock (3 of 5 tests fail with assertions off and on; with-Ptests.iters=10all 30 repetitions of the 3 bug tests fail and all 20 control repetitions pass), with fix A (passes, also 50 of 50 with-Ptests.iters=10and assertions on; all of:lucene:analysis:common:test;:lucene:analysis:common:check -x test) and with fix A2 (the payload tests); the delivered file once more on stock (3 of 5 fail). The hunt's and the verifiers' JUnit tests on maina9779ef3c193, 10.5.2 and 9.12.3; a version-portable check on 4.0.0-BETA, 4.0.0, 4.3.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (4.0.0-ALPHA has no such factory), and an index-level JUnit on 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main. JDK 25, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/payloads/DelimitedPayloadTokenFilterFactory.java:25-38 (at a9779ef3c193) (class javadoc shows only encoder="float", nothing on sharing or threads), :51 (one encoder field), :69-71 (create() passes that encoder to every new filter), :74-84 (inform() sets it once; custom class via loader.newInstance at :82)lucene/analysis/common/src/java/org/apache/lucene/analysis/payloads/PayloadEncoder.java:21-38 (at a9779ef3c193) (javadoc 'Mainly for use with the DelimitedPayloadTokenFilter, converts char buffers to BytesRef. NOTE: This interface is subject to change'; no thread-safety or ownership statement)lucene/analysis/common/src/java/org/apache/lucene/analysis/payloads/DelimitedPayloadTokenFilter.java:59 (at a9779ef3c193) (stores the encoder's returned BytesRef by reference via setPayload)lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/PayloadAttributeImpl.java:41-43, (at a9779ef3c193) 51-57, 82-85 (setPayload keeps the reference; clone()/copyTo() deep-copy)lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:93-96 (at a9779ef3c193) (one set of components per thread); lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:165 (createComponents calls the shared factory's create())lucene/core/src/java/org/apache/lucene/index/FreqProxTermsWriterPerField.java:84-98 (at a9779ef3c193) (writeProx reads the payload BytesRef later, length read twice)lucene/analysis/phonetic/src/java/org/apache/lucene/analysis/phonetic/PhoneticFilterFactory.java:160-166 (at a9779ef3c193) ('Must be thread-safe' ... 'instantiate every time'); lucene/analysis/common/src/java/org/apache/lucene/analysis/snowball/SnowballPorterFilterFactory.java:83,94 (newInstance per create()); lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProviderFactory.java:29 ('Assumes synonymProvider implementations are thread-safe')
- The finding in 30 seconds
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/payloads/DelimitedPayloadTokenFilterFactory.java:51, 69-71, 74-84a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/payloads/DelimitedPayloadTokenFilter.java:59a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/PayloadAttributeImpl.java:41-43, 51-57, 82-85; lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:124-127; lucene/core/src/java/org/apache/lucene/util/AttributeSource.java:300 (captureState)a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/test/org/apache/lucene/analysis/core/TestAnalyzers.java:232-248 (PayloadSetter)a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:91-96; lucene/analysis/common/src/java/org/apache/lucene/analysis/custom/CustomAnalyzer.java:161-168a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/FreqProxTermsWriterPerField.java:84-98; lucene/core/src/java/org/apache/lucene/util/BytesRefBuilder.java:146-149; lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:585-587, 594-605; lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:6098-6112
- Who is affected
a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:167-168
- Why it looks unintended
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/payloads/PayloadEncoder.java:21-35; DelimitedPayloadTokenFilterFactory.java:25-38a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:45-52a Lucene main checkout (a9779ef3c193) lucene/analysis/phonetic/src/java/org/apache/lucene/analysis/phonetic/PhoneticFilterFactory.java:160-166, 179-181; lucene/analysis/common/src/java/org/apache/lucene/analysis/snowball/SnowballPorterFilterFactory.java:83, 94; lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymProviderFactory.java:29a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:124-127; lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:32, 91-96 (the only "thread" hits in the files grepped)
- Suggested fix
a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/util/ResourceLoader.java:33-40; lucene/analysis/phonetic/src/java/org/apache/lucene/analysis/phonetic/PhoneticFilterFactory.java:162-164
- TestDelimitedPayloadFactoryEncoderSharing.java (JUnit test):
repro/LFV-598/src/org/apache/lucene/analysis/payloads/TestDelimitedPayloadFactoryEncoderSharing.java(65 lines)
Summary card (bug.png), made in parallel with this doc. The numbers come from the diagram's own probe on main a9779ef3c193 (assertions off, 3 launches, stock and with the fix).
assets/LFV-598/bug.png(498 KB)