At build time FreeTextSuggester never looks at the analyzer's tokens. It counts the separators in each stored n-gram and rejects only an n-gram that seems to have more than grams words. A token that contains one separator looks exactly like a 2-gram, so with the default bigram model a lone foo␞bar passes; with a neighbour it is caught.
FreeTextSuggesterbuilds an n-gram model from text. With the defaultgrams = 2it stores every word (unigram) and every pair of neighbouring words (bigram) with its count in one FST.- A bigram is stored as its two words joined by a separator byte:
fooandbarbecomefoo␞bar. The separator is U+001E by default (any 7-bit byte if configured); no analyzed token may contain it. lookup("foo ")(a trailing space means "predict the next word") finds the bigrams starting withfoo␞and scores each by count(foo bar) / count(foo). So every bigram's first word must also be stored as a unigram.
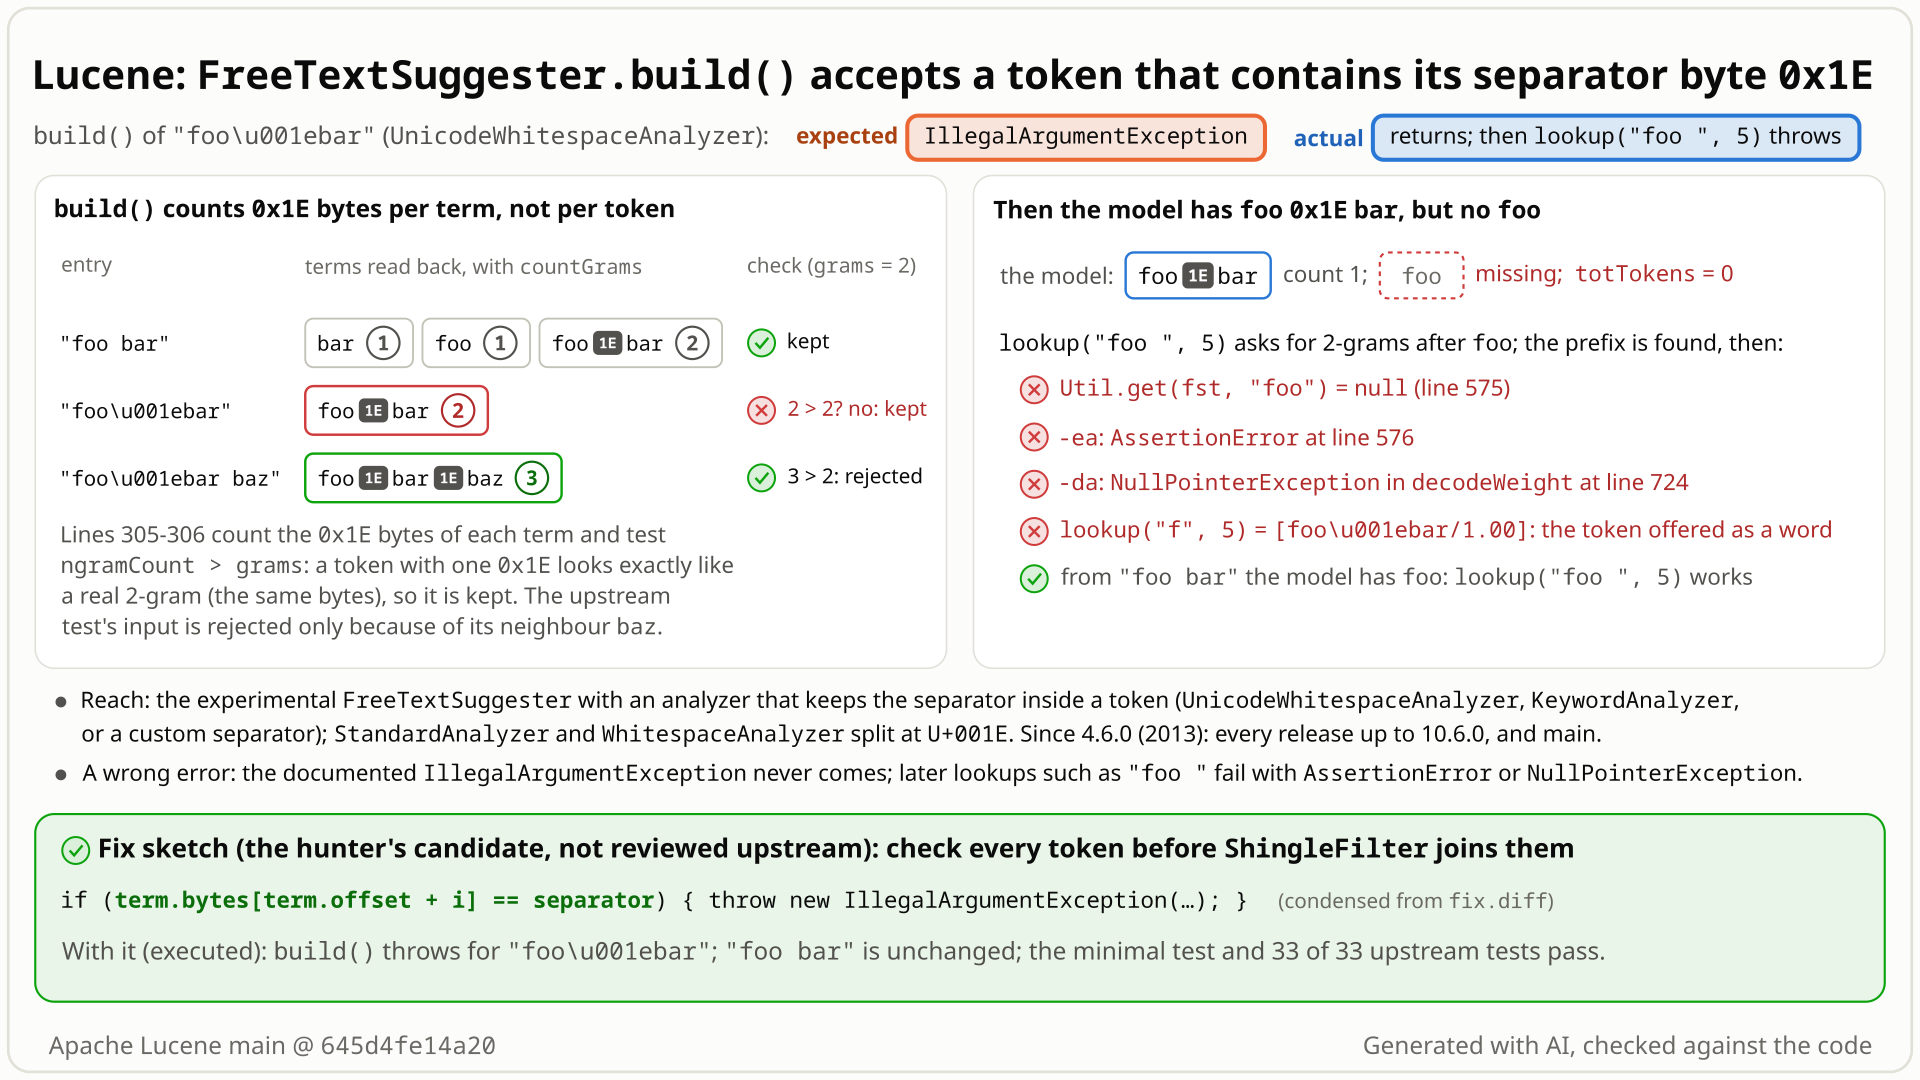
foo␞bar alone passes while foo␞bar baz is rejected, and the lookup that then throws. Select the still to open it at full size. Generated with AI, checked against the code.- Build a
FreeTextSuggesterwith the defaults (bigrams, separator U+001E, written ␞ below) andKeywordAnalyzerorUnicodeWhitespaceAnalyzer, which keep ␞ inside a token, over the single entryfoo\u001ebar. - You expect
IllegalArgumentException: the javadoc says "No input tokens should have this byte, otherwise IllegalArgumentException is thrown", and the upstream test asserts it forfoo\u001ebar baz. - You get a successful build. The check counts separators in each stored n-gram:
foo␞barhas one, so it counts as 2 words, which a bigram model allows. With the neighbourbaz, the n-gramfoo␞bar␞bazcounts 3 and is rejected: the only reason the upstream test passes. - The model now holds the "bigram" foo-bar but no word
foo. WithUnicodeWhitespaceAnalyzer(it splits the query into words),lookup("foo ")looks up the count offooand throwsNullPointerException(AssertionErrorwith assertions on);lookup("f")suggestsfoo␞bar(score 1.00 for this single entry, as in the diagram; 0.50 after a build overfoo␞barandhello world).
Users of the opt-in, @lucene.experimental FreeTextSuggester whose analyzer keeps the separator inside a token: KeywordAnalyzer or UnicodeWhitespaceAnalyzer with the default U+001E, or a custom separator the tokenizer keeps, such as a space with a comma tokenizer. StandardAnalyzer, WhitespaceAnalyzer and SimpleAnalyzer split on U+001E and are safe. Every release since 4.6.0.
Mechanism, terms and numbers838 words
FreeTextSuggester builds an n-gram model: ShingleFilter joins neighbouring tokens with a separator byte (U+001E by default, any 7-bit byte if configured) and every unigram and n-gram goes into one FST. Its 4-arg constructor javadoc says "No input tokens should have this byte, otherwise IllegalArgumentException is thrown" (FreeTextSuggester.java:179-180 on main 645d4fe14a20). build() never inspects the tokens, though: it reads the shingled terms back from a temporary index and throws only if a term's separator count implies more than grams words (:305-306). A token that itself contains k separators therefore looks like a (k+1)-gram; it passes whenever every shingle it ends up in still counts at most grams (with bigrams and no position gaps: a token with one separator passes whenever it is the only token of its entry). With the default bigram model the one-token entry foo\u001ebar is accepted, while the upstream test input foo\u001ebar baz is rejected only because its shingle foo␞bar␞baz counts 3. The token is stored as the bigram (foo, bar) without a unigram foo; lookup("foo ") with a word-splitting analyzer then throws AssertionError at :576 (-ea) or NullPointerException in decodeWeight at :724 (-da, as in production), and the token can come back from the no-context (1-gram) search with a wrong score. Only the opt-in, @lucene.experimental FreeTextSuggester with an analyzer that keeps the separator inside a token is affected (KeywordAnalyzer, UnicodeWhitespaceAnalyzer, or a custom separator the tokenizer keeps); StandardAnalyzer, WhitespaceAnalyzer and SimpleAnalyzer split on U+001E. The check reads the same in every release from 4.6.0 (2013) to 10.6.0 and on main (12 releases and main executed, the rest read from source or inferred).
- Contract.
DEFAULT_SEPARATOR = 0x1e: "The input tokens produced by the analyzer must not contain this character" (:147-151). The 4-arg constructor: the separator "must be an ascii (7-bit-clean) byte. No input tokens should have this byte, otherwiseIllegalArgumentExceptionis thrown" (:176-181); the other constructors delegate to it (:157-174). - Shingling. Unless
grams == 1, both analyzers get aShingleFilter(stream, 2, grams)with the separator as token separator (:185-186,:214-235). It emits each token and each run of 2 togramsneighbouring tokens joined by the separator. - Build. Each entry is indexed in a temporary index (
:276-284); the terms are read back andcountGrams(term), 1 + the number of separator bytes (:414-423), is compared withgrams: onlyngramCount > gramsthrows "tokens must not contain separator byte" (:305-313). Only terms with count 1 add to the unigram total (:315-317); every term goes into the FST (:319-320). A term read back from an index carries no position length, so the build cannot tell the tokenfoo␞barfrom the shingle offooandbar. - When it misses. The separator check in
build()throws exactly when some emitted term hascountGrams(term) > grams(build()also throws for payloads, contexts and an empty term set,:247-252,:287-290). For an entry without position gaps and with one separator-carrying token, a token with k separators passes when k + 1 <= grams and it has at most grams - 1 - k neighbours: with bigrams, an entry that is that single token; withgrams = 3, a token with one separator next to one other token. Several such tokens in one shingle add up, and across a position gapShingleFilterinserts its filler token_(ShingleFilter.java:46), which adds one more join. - Lookup checks exactly. For each query token it compares
countGramswith theShingleFilterposition length (// Safety: make sure the recalculated count "agrees",:459-468). - Lookup fails. For
"foo "the last token becomes the contextfoo␞(:494-509). That prefix exists in the FST (fromfoo␞bar), solookupfetches the count offoo:Util.getreturns null andassert output != nullfails (:575-576); without assertionsdecodeWeight(null)unboxes null (:724).
| input (bigram model) | n-grams the check sees (count) | result |
|---|---|---|
foo␞bar (KeywordAnalyzer or UnicodeWhitespaceAnalyzer) | foo␞bar (2) | accepted, should throw |
foo␞bar baz (upstream test shape) | baz (1), foo␞bar (2), foo␞bar␞baz (3) | IAE |
foo␞bar, grams = 1 | foo␞bar (2) | IAE |
separator '_' (StandardAnalyzer), grams = 3: foo_bar baz | baz (1), foo_bar (2), foo_bar_baz (3) | accepted, should throw |
separator ' ', comma tokenizer: new york | new york (2) | accepted, should throw |
After a build over foo␞bar and hello world with UnicodeWhitespaceAnalyzer: lookup("foo ") throws and lookup("f") returns foo␞bar/0.50 (the single entry foo␞bar alone fails the same way, and there lookup("f") gives 1.00 because no unigram was counted); the probes' unrelated lookups kept working (lookup("hello "), also with separator '_' after [foo_bar, hello world, hello there]). With separator '_' and [foo bar, foo_bar], lookup("f") returns foo_bar/1.00 ahead of foo/0.50. If foo also occurs on its own in the build text ([foo_bar, foo qux]), lookup("foo ") works.
Exposure and likelihood346 words
- Reach. The default U+001E reaches it with
KeywordAnalyzer,UnicodeWhitespaceAnalyzer(U+001E is not Unicode White_Space) or a keyword- or pattern-style tokenizer. A custom separator (any 7-bit byte; in Solr aFreeTextLookupFactorysetting next to any analyzer field type) reaches it whenever the tokenizer keeps it inside words.StandardAnalyzer,WhitespaceAnalyzerandSimpleAnalyzersplit the token and are unaffected with the default separator:WhitespaceTokenizerbecauseCharacter.isWhitespace(0x1E)is true,SimpleAnalyzer'sLetterTokenizerbecause U+001E is not a letter,StandardTokenizerby its UAX #29 word-break rules. - What goes wrong. The documented
IllegalArgumentExceptionis not thrown, so a model the API means to reject is built. With a query analyzer that splits the key into words, lookups whose last complete word is the token's part before the separator (fooforfoo␞bar:"foo ","foo b","x foo "), when that word never occurs on its own in the build text, then throw on every such request until the model is rebuilt (also afterstore()/load()). Lookups on the part after it ("bar ","x bar ") return nothing, and withKeywordAnalyzeron both sides these lookups do not throw; the probes' unrelated lookups kept working. The token can also come back from the no-context (1-gram) search with an inflated score. - What it takes. With bigrams, an entry that is that single token (for example one-word query-log lines); with
grams >= 3, few enough neighbours. The lookup failure also needs the token's part before the separator to be absent as a standalone word, and a query analyzer that splits the key into words (withKeywordAnalyzeron both sides,foo␞baryields only the stray completion, because the queryfoostays one token). - Cost. Deterministic, no scale. The application's index is never touched: build writes only to its own temporary index, which it always deletes (after rolling it back when the build succeeds). No hang (a failing lookup takes a few microseconds).
- Workaround. Strip or replace the separator byte in the build text, or pick a separator the analyzer always splits on.
One JUnit method on the public API, in the analyzing test package like the upstream tests: KeywordAnalyzer, the default constructor (bigrams, separator U+001E) and the one-entry dictionary foo\u001ebar, with expectThrows(IllegalArgumentException) around build(). Fixed test data, single-threaded; fails with assertions on and off and with two seeds.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.analyzing;

import java.io.StringReader;
import org.apache.lucene.analysis.core.KeywordAnalyzer;
import org.apache.lucene.search.spell.PlainTextDictionary;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestFreeTextSuggesterSeparatorInToken extends LuceneTestCase {

  public void testTokenWithDefaultSeparatorRejected() throws Exception {
    try (KeywordAnalyzer analyzer = new KeywordAnalyzer()) {
      FreeTextSuggester suggester = new FreeTextSuggester(analyzer); // bigrams, separator 0x1e
      // javadoc: a token containing the separator byte -> IllegalArgumentException; actual: build succeeds
      expectThrows(
          IllegalArgumentException.class,
          () -> suggester.build(new PlainTextDictionary(new StringReader("foo\u001ebar"))));
    }
  }
}
cp $REPRO/TestFreeTextSuggesterSeparatorInToken.java $LUCENE/lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/
cd $LUCENE && ./gradlew :lucene:suggest:test --tests org.apache.lucene.search.suggest.analyzing.TestFreeTextSuggesterSeparatorInToken -Ptests.seed=DEADBEEF
- Expected
build()throwsIllegalArgumentException: the only token,foo␞bar, contains the separator byte.- Observed
build()succeeds:Expected exception IllegalArgumentException but no exception was thrown.
More files, environment, full output239 words
Copy the test into lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/ of a Lucene checkout and run it with gradle (command below). With the per-token check (Suggested fix) it passes unchanged, so it doubles as the regression test.
Executed: this gradle command on a clean 645d4fe14a20 (assertions off for this seed) and again with -Ptests.asserts=true in a fresh scratch worktree (fails, same message); the standalone runner on the stock main jars and on the 10.6.0 release jars, each with -ea and -da (fails, same message).
With -Ptests.seed=DEADBEEF, Lucene's gradle runs with assertions off (it picks tests.asserts at random per seed); add -Ptests.asserts=true for an assertions-on run, which fails the same way.
Left out on purpose: the lookup failure. It needs no second entry, but a query analyzer that splits the key into words (for example UnicodeWhitespaceAnalyzer; with this test's KeywordAnalyzer, lookup("foo ") returns nothing). It is described under "The finding in 30 seconds" with its executed output.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; also fails on the 10.6.0 release jar |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (nothing platform-specific) |
cp $REPRO/TestFreeTextSuggesterSeparatorInToken.java $LUCENE/lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/
cd $LUCENE && ./gradlew :lucene:suggest:test --tests org.apache.lucene.search.suggest.analyzing.TestFreeTextSuggesterSeparatorInToken -Ptests.seed=DEADBEEF
# gradle, main 645d4fe14a20, -Ptests.seed=DEADBEEF
TestFreeTextSuggesterSeparatorInToken > testTokenWithDefaultSeparatorRejected FAILED
    junit.framework.AssertionFailedError: Expected exception IllegalArgumentException but no exception was thrown
        at org.apache.lucene.tests.util.LuceneTestCaseParent.expectThrows(LuceneTestCaseParent.java:1432)
        at org.apache.lucene.tests.util.LuceneTestCaseParent.expectThrows(LuceneTestCaseParent.java:1418)
        at org.apache.lucene.search.suggest.analyzing.TestFreeTextSuggesterSeparatorInToken.testTokenWithDefaultSeparatorRejected(TestFreeTextSuggesterSeparatorInToken.java:30)

# standalone runner, seed DEADBEEF
main 645d4fe14a20  -ea / -da   tests_run=1 failures=1   same message
10.6.0 -ea / -da tests_run=1 failures=1 same message- The javadoc states the consequence: "No input tokens should have this byte, otherwise
IllegalArgumentExceptionis thrown" (FreeTextSuggester.java:179-180). - Upstream
testIllegalByteDuringBuildasserts it forfoo\u001ebar baz; withoutbazthe same token passes. A rejection that depends on neighbours and ongramsis an accident. - Lookup checks every token exactly (
:459-468) and asserts that each context word exists (:576).
The full argument196 words
- Contract.
DEFAULT_SEPARATOR: "The input tokens produced by the analyzer must not contain this character" (:147-150). The 4-arg constructor promises the IAE (:179-180), and the build's error message names exactly this condition: "tokens must not contain separator byte" (:308). - Test.
testIllegalByteDuringBuild(TestFreeTextSuggester.java:121-134), with the comment "no input token is allowed to contain it", asserts the IAE at build time forfoo\u001ebar baz. It passes only because of the neighbourbaz. - Code. Where the position length is available (lookup), the check is exact (
:459-468), and lookup asserts the model invariant that every context exists (:576). Sibling suggest code checks reserved characters one by one and throws an IAE:SuggestFieldandContextSuggestFielddocument it in their javadoc (SuggestField.java:75-76,ContextSuggestField.java:62-63);AnalyzingSuggesterthrows it, with a message but no javadoc, for a lookup key and, with payloads, for a surface form at build. - History. The promise, the check,
countGrams, the lookup assert and the test came in one commit (LUCENE-5214, 2013). Its issue (#6278, 12 comments) never calls the build check partial or best-effort, and no comment, CHANGES or MIGRATE entry does.
The devil's-advocate check182 words
The strongest case for "works as designed" (the cross-model lenses and the intended-behaviour checker): separator-free tokens are a caller precondition ("should", "must not"), so behaviour after violating it is unsupported; the class is experimental; checking each unique indexed term may have been chosen as a cheap safeguard rather than complete validation; and SOLR-11139 even asks for a more lenient build. Also conceded: the javadoc does not say when the IAE is thrown (at build or at lookup).
Why it fails: the same javadoc sentence promises the IAE for exactly this violation and the upstream test asserts it at build; here it is thrown neither at build nor at lookup; nothing records the check as best-effort; a per-token check is one byte scan per token, the same work lookup already does for every token; and under any reading the outcome is wrong, with a word-splitting query analyzer, a later NullPointerException on a lookup key that itself contains no separator, instead of the documented IAE. SOLR-11139 is about the fix direction (reject or skip), not evidence that silent acceptance is wanted. Verdict: a defect.
Recommended Reject a separator-containing token before shingling (matches the javadoc)
Check the tokens, not the n-grams: in addShingles, put a small token filter before ShingleFilter that throws IllegalArgumentException for any token containing the separator byte (+31/-1 lines). The minimal test and the whole suggest suite pass. Trade-off: such inputs now fail the whole build, as documented; that is stricter than today and the opposite of what SOLR-11139 asks.
TokenStream checked = new SeparatorCheckFilter(components.getTokenStream(), separator);
ShingleFilter shingles = new ShingleFilter(checked, 2, grams); // was: (components.getTokenStream(), 2, grams)

private static final class SeparatorCheckFilter extends TokenFilter {
  ...
  public boolean incrementToken() throws IOException {
    if (input.incrementToken() == false) return false;
    BytesRef term = termAtt.getBytesRef();
    for (int i = 0; i < term.length; i++)
      if (term.bytes[term.offset + i] == separator)
        throw new IllegalArgumentException("tokens must not contain separator byte; got token=" + term);
    return true;
  }
}
All options and trade-offs3 options · 646 words
Three options. The per-token check was validated with gradle in a fresh scratch worktree at 645d4fe14a20 (assertions on, whole suggest suite); the other two were not executed. Whatever the choice, the token has to be treated the same with or without neighbours.
Reject a separator-containing token before shingling (matches the javadoc) (validated by the checks) (recommended)
In FreeTextSuggester.addShingles, wrap the wrapped analyzer's token stream in a private SeparatorCheckFilter and feed that to ShingleFilter. The filter scans each token's bytes and throws IllegalArgumentException("tokens must not contain separator byte; got token=..."). It applies to the index and the query analyzer; with grams == 1 there is no shingling and the existing build check is already exact.
TokenStream checked = new SeparatorCheckFilter(components.getTokenStream(), separator);
ShingleFilter shingles = new ShingleFilter(checked, 2, grams); // was: (components.getTokenStream(), 2, grams)

private static final class SeparatorCheckFilter extends TokenFilter {
  ...
  public boolean incrementToken() throws IOException {
    if (input.incrementToken() == false) return false;
    BytesRef term = termAtt.getBytesRef();
    for (int i = 0; i < term.length; i++)
      if (term.bytes[term.offset + i] == separator)
        throw new IllegalArgumentException("tokens must not contain separator byte; got token=" + term);
    return true;
  }
}
Trade-offs
- Builds that succeed today with such a token now fail as a whole, as the javadoc says. That is stricter, and the opposite of SOLR-11139's request.
- Cost: one byte scan per analyzed token at build and lookup (lookup already counts separators per token); not benchmarked.
- A lookup key whose token contains the separator still gets an
IllegalArgumentException(now from the filter), so upstreamtestIllegalByteDuringQuerykeeps passing. - The existing n-gram check stays. It still fires in one case the new filter cannot see: across a position gap
ShingleFilterinserts its filler token_, so with separator_a legal entry such asthe foo(stop wordthe) is rejected, on main today and with the fix alike. - Constructor order is safe:
addShingles()runs beforethis.separatoris assigned, but the wrapper builds its token stream only when the analyzer is first used, after construction, and the new line reads the suggester's final fieldseparator, as the existingsetTokenSeparatorline does.
What the checks validated
- Gradle, fresh scratch worktree at
645d4fe14a20, JDK 25,-Ptests.seed=DEADBEEF -Ptests.asserts=true: stock, the minimal test fails; with the fix,:lucene:suggest:checkGoogleJavaFormatpasses and the whole:lucene:suggest:testsuite passes, 237 tests in 32 suites, 7 skipped, 0 failures, including the minimal test,TestFreeTextSuggester(testIllegalByteDuringBuildandtestIllegalByteDuringQuerypass) andTestAnalyzingSuggester. - An earlier run of the same suite with assertions at the seed's default (off): 237 tests, 0 failures; an independent fact check repeated it.
- The test file used in the gradle runs has its one 107-character comment line wrapped onto two lines, which the format check requires; nothing else differs from the repro.
- Standalone runner with the patched class shadowed: the minimal test passes; the steps probe gets the
IllegalArgumentExceptionforfoo␞baralone and forfoo␞bar baz, still buildsfoo bar, and rejects the two-entry build at build time, so no lookup can fail; the lookup audit probe passes 4 of 4. - Earlier shadow runs of the hunt's equivalent diff: the finder's 4 tests, an independent reproducer's 6 and the intended-behaviour checker's 7 pass.
Drop such tokens (or the entries that contain them) before shingling instead of failing the build, and change the javadoc to say so. Not executed.
Trade-offs
Lenient, and it resolves SOLR-11139 too, but it contradicts the current javadoc and test, so it is an API behaviour change; silently dropping input can hide a misconfigured separator. The check must still be per token, or the hole stays.
Say in the javadoc that only tokens whose separators push an n-gram past grams are rejected. Not executed (documentation only).
Trade-offs
No behaviour change, but the lookup NullPointerException and the stray completions stay; not recommended.
In Solr the separator is a free FreeTextLookupFactory setting next to any analyzer field type, so a configuration whose analyzer keeps the separator inside words reaches this; the separator and the analyzer are operator configuration, not user input.
A bounded-exhaustive check of the documented separator rule on the stock jar: 8,712 builds (two separators, three analyzer types, grams 1 to 3, every tiny dictionary) and 528,216 lookups. 2,536 builds accepted a token that contains the separator, no legal input was rejected, and every lookup failure followed such a build.
The method in full179 words
Method: bounded-exhaustive translation validation (the hunt's semi-formal tier), in a hunt unit on in-band separators and reserved symbols, run on the stock main jars at ea57360912ed (FreeTextSuggester.java is unchanged since).
- Property P1:
build()throwsIllegalArgumentExceptionif and only if an analyzer token contains the separator byte. Property P2: after a successful build,lookup()throws nothing butIllegalArgumentException. - Inputs: separators U+001E and
_; keyword, space-splitting and standard analyzers; grams 1 to 3; every 1-entry dictionary of strings of length <= 3 and every 2-entry dictionary of strings of length <= 2 over {a, b, space, separator}; every lookup key of length <= 3 over {a, b, space}, with 1 and 5 results. - Result: 2,536 accepted-illegal builds, 0 legal inputs rejected; lookup failures only after accepted-illegal builds (3,564
AssertionErrorwith-ea, 2,820NullPointerExceptionwith-da), none after legal builds. - The hypothesis came from reading the build check while listing the reserved in-band constants; the harness then witnessed and bounded it, and the finding was reduced to a public-API JUnit test, later to the single test shown here.
No prior report found (searched 2026-10-26, re-checked 2026-10-30) in GitHub issues, PRs and commits including the JIRA archive, the mailing lists, downstream projects or the web. Related only: SOLR-11139 (open since 2017) asks for the opposite, that the same build loop skip bad tokens instead of failing.
Searches4 searches
SOLR-11139 "FreeTextSuggester exits on first error while building suggester index" (open since 2017-07-24, no comments) quotes the same build loop and asks to skip offending terms; it does not mention that the check misses tokens, the javadoc promise or any lookup failure. The per-token check does not resolve SOLR-11139 (the build still fails), and skipping only the terms today's check flags would not fix this bug; skipping bad tokens one by one could address both. Its solr-user thread shows a configuration whose analyzer put the separator inside tokens (there the check fired). A strict "same code block" reading would make this bug known; the hunt kept "new". Other items, not this bug: SOLR-7084 (an NPE when lookup runs before build, fixed 2015), SOLR-11668, SOLR-5631, #11328, #6955, #7264, #15134, #13390 (the only open PR that touches the file, a stale ShingleFilter builder refactor that keeps the check), and reserved-byte issues of other suggesters (#5600, #4915, #5885, #6094). Gaps: one Stack Overflow page could not be read; private reports cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| Search tool (GitHub issues/PRs/commits incl. the JIRA archive, dev@, java-user@, issues@, commits@, solr-user@, downstream, web) | 2026-10-26 | 95 queries: FreeTextSuggester, countGrams, the error text, separator byte, NullPointerException and AssertionError phrasings | 350 hits, 0 high; none about this bug |
| JIRA (LUCENE and SOLR) and GitHub (apache/lucene, apache/solr, Lucene.NET, two downstream engines) | 2026-10-26 | manual searches; body and 12 comments of #6278 read | SOLR-11139 related (opposite request); the rest unrelated |
| All apache/lucene PRs | 2026-10-26 | changed files of 407 open and 4547 closed PRs | the only open PR touching the file is #13390 (a stale ShingleFilter builder refactor that keeps the check); the six closed PRs touching it (#15134, #13795, #12831, #12803, #12715, #38) are merged refactors, none about the check |
| GitHub apache/lucene (read-only gh) | 2026-10-30 | FreeTextSuggester, "separator byte", "tokens must not contain separator", FreeTextSuggester NullPointerException; open PRs | only #15134, #6278, #11328, #6955, #7264 (unrelated); no open PR; repeated live by the doc's fact check the same day, same results |
Present since the class was added: LUCENE-5214 (b50a2edbb23 on trunk, 2013-10-02; released through the backport 9494be7ec2a in 4.6.0). The check has never changed: it reads the same in every release from 4.6.0 to 10.6.0 and on main (12 releases and main executed, the other release tags read from source, 8.8.2-8.11.3 inferred).
Versions tested5 rows
The one introducing commit added the javadoc promise, the build check on shingled terms, countGrams, the exact lookup-side check, the lookup assert and testIllegalByteDuringBuild. Later commits that touch the check lines only reformat or change resource handling (LUCENE-5259, LUCENE-9570, #15134); #16255 (2026) fixed a comment typo elsewhere in the file. The check is text-identical in all 112 release tags 4.6.0-10.5.2 of the history clone; releases between the executed points are affected by reading only. Old releases ran on JDK 25.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails (gradle; standalone -ea and -da); the lookup probe throws (-ea AssertionError, -da NullPointerException) |
| 10.6.0 | affected | the minimal test fails on the published release jars (-ea, -da); at the release tag the check reads the same |
| 4.6.0 to 10.5.2 | 11 releases | a public-API main() probe fails 4 of 4 contract cases, controls pass, on 4.6.0 (-ea, -da), 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3 (-ea, -da), 10.0.0 and 10.5.2 (-ea, -da) |
| 4.5.1 and older | not affected | no FreeTextSuggester (the probe does not compile) |
per-token check (scratch worktree at 645d4fe14a20) | not affected | the minimal test and the whole suggest suite pass, assertions on (237 tests in 32 suites, 7 skipped, 0 failures) |
An independent reproducer, an intended-behaviour devil's advocate, a model from another family (reading only, lenses), an adjudication, a credibility audit and fresh-seed registry re-runs all confirm it; this doc re-ran the minimal test on main and 10.6.0 and validated the fix with gradle.
Checks and verdicts452 words
The cross-model reviewer could not run Java, so its refute-lens review voted not real on procedure only ("a procedural verdict, not a technical refutation") while agreeing on the root cause; a re-run of the finder's repro for each review failed (4 of 4).
| Check | Verdict | What it found |
|---|---|---|
| finder (bounded-exhaustive harness) | candidate | 2,536 accepted-illegal builds out of 8,712, lookup failures only after them; its 4-test JUnit fails 4 of 4 on main (-ea, -da), 10.5.2 and 9.12.3. |
| cross-model review (OpenAI GPT-5.6, lenses, reading only) | refute: procedural "not real" (medium); intended: real (medium) | Could not run Java; agreed on the root cause; strongest counter-argument (moderate): separator-free tokens are a caller precondition. |
| The cross-model review controls | real | Finder's JUnit 4 of 4 fail (-ea, -da); its control JUnit (separator-free input works, the neighbour case is rejected, the lookup side rejects the token) passes 3 of 3. |
| independent reproducer | real | Own 6-test JUnit with different analyzers and inputs: 4 of 6 fail on main (-ea, -da), 10.5.2 and 9.12.3; both controls pass. |
| intended-behaviour devil's advocate | real (high) | Built the works-as-designed case and rejected it; its 7-test probe fails exactly the lone-token and space-separator cases, 5 controls pass, on main, 10.5.2 and 9.12.3. |
| adjudication | confirmed (high) | Re-ran the reproducer's JUnit with a fresh seed (-ea, -da: 4 of 6 fail, controls pass); impact class wrong error; security none. |
| registry re-run and credibility audit | keep | Fresh seeds: all three test classes fail stock and pass with the fix shadowed; an independent stock-analyzer probe fails 3 of 4 with its control passing. |
| this doc | reproduced, fix validated | Gradle in a fresh scratch worktree at 645d4fe14a20, assertions on: the minimal test fails, and with the per-token check the format check and the whole suggest suite pass (237 tests, 0 failures); the minimal test also fails with the standalone runner (-ea, -da) and on the 10.6.0 jars; the steps probe reproduces the lookup failure and, with the fix, gets the documented exception at build time. |
| fact checks of this doc (2026-10-30) | real; wording fixed | Two rounds of an independent fact check re-ran the gradle command as written (assertions off) and with assertions on, the standalone runs on main and 10.6.0, the fix with the whole suggest suite (237 tests, 0 failures) and their own public-API probes, including the single-entry lookups; two rounds of a cross-model fact check (OpenAI GPT-5.6, reading only) re-read the code and the records; two rounds of a diagram check measured contrast and checked the frames. Their corrections are applied; what was not applied, and why. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 451 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,627 words
- Registry title
- FreeTextSuggester.build accepts a token that contains the separator byte whenever the shingled term stays within the gram limit, although its javadoc promises an IllegalArgumentException; later lookups whose last complete word occurs only inside that token throw AssertionError (-ea) or NullPointerException (-da)
- Area
- suggest / FreeTextSuggester (n-gram model joined with an in-band separator byte; build-side separator check)
- Priority
- Low, rank 635: The experimental FreeTextSuggester accepts a token containing its separator instead of throwing the documented exception, and later lookups then fail loudly.
- Impact class
- wrong error
- Impact note
- Only applications that use the opt-in, @lucene.experimental FreeTextSuggester with an analyzer that keeps the separator byte inside a token are hit (the default U+001E with UnicodeWhitespaceAnalyzer, KeywordAnalyzer or a keyword- or pattern-style tokenizer, or a custom separator, any 7-bit byte and a Solr configuration parameter, that the tokenizer keeps inside words), and then only for a token whose separator count plus neighbours stays within grams (with the default bigram model: an entry that is that single token): build() succeeds instead of throwing the documented IllegalArgumentException, later lookups whose last complete word occurs nowhere else as a standalone token throw AssertionError (-ea) or NullPointerException (-da, as in production), and the token can surface among single-word completions with an inflated score; StandardAnalyzer, WhitespaceAnalyzer and SimpleAnalyzer split on U+001E, so they are unaffected with the default separator; no scale is needed, and the index and other lookups are unaffected.
- Summary
- You build a FreeTextSuggester with the default bigram model and separator U+001E over the single entry 'foo\u001ebar' (the upstream test input 'foo\u001ebar baz' without its neighbour 'baz'), using an analyzer that keeps it as one token such as UnicodeWhitespaceAnalyzer, and expect build() to throw IllegalArgumentException, as the constructor javadoc promises and as it does for 'foo\u001ebar baz'. Instead build() succeeds, because it only rejects an indexed shingle whose separator count implies more than grams words, so the token is stored as if it were the bigram (foo, bar) with no unigram 'foo'. A later lookup('foo ') then fails inside the suggester with AssertionError at FreeTextSuggester.java:576 (-ea) or NullPointerException in decodeWeight (-da), and lookup('f') returns the token itself with a wrong score.
- Introduced
- b50a2edbb2389797a7354775414052df91b108f6 (trunk, svn r1528517) and its branch_4x backport 9494be7ec2ae84e88b6fc07046c35cac15e790d2 (svn r1528521, the commit 4.6.0 contains): LUCENE-5214 'Add new FreeTextSuggester, to handle "long tail" suggestions' (migrated issue apache/lucene#6278; Subversion era, no pull request; by GitHub mikemccand), which added in one change the 4-arg constructor javadoc promise, the DEFAULT_SEPARATOR javadoc, the build-side check on shingled terms read back from a temporary index, countGrams, the exact per-token lookup-side check, the lookup assert and testIllegalByteDuringBuild [read: git log -S 'countGrams(term)' and -S 'tokens must not contain separator byte' find only b50a2edbb23; git log -G 'ngramCount|countGrams' finds only 64a795b6e3d (LUCENE-5259), 2cbf261032d (LUCENE-9570 reformatting) and b85f030c6cc (#15134), none of which changes the check]. Original defect, not a regression. The introducing tree itself was not built (2013 ant build); exec at release granularity: 4.5.1 has no FreeTextSuggester (compile error), 4.6.0 reproduces 4/4 with -ea and -da (2013-10-02)
- First affected version
- 4.6.0 [exec, -ea and -da: 4/4 contract cases, both controls throw IAE], the first release with FreeTextSuggester; 4.5.1 and older do not have the class [exec: compile error, API absent]
- Affected versions
- every release from 4.6.0 through 10.5.2 (121 releases), 10.6.0 [exec: the doc's minimal test on the release jars, -ea and -da, 2026-10-30] and main a9779ef3c193; not fixed on upstream main a95c754ee003, branch_10x 1309534296e3 or branch_10_6 2763db11b0a7 (local clone, read 2026-10-26). [exec, the follow-up's public-API main() FreeTextSepHistoryProbe, controls C1 (grams=1) and C2 (the upstream-test shape) throw IAE on every version] 4/4 contract cases fail on 4.6.0 (-ea and -da), 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3 (-ea and -da), 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da); with the candidate fix shadowed on main all four inputs are rejected. [exec, JUnits] the finder's JUnit fails 4/4 on main (-ea, -da), 10.5.2 and 9.12.3; the independent reproduction's fails 4/6 on main, 10.5.2 and 9.12.3 (-ea and -da; its 2 controls pass); the intended-behaviour check's probe fails 2/7 on main (-ea, -da), 10.5.2 and 9.12.3 (its 5 controls pass). [read] the check and countGrams are text-identical after whitespace normalisation in all 112 release tags of the history clone that contain the file; 8.8.2 to 8.11.3 are not tagged there and are inferred (bracketed by 8.8.1, read, and 8.11.4, executed). Releases were run on JDK 25.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code and voted “not real” while agreeing with the root cause (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record, verdict new, confidence medium-high): 95 scripted prior-report search queries (40 GitHub issue/PR queries on apache/lucene, 6 commit, 5 downstream, 30 mailing-list queries over dev@, java-user@, issues@, commits@ and solr-user@, 8 JIRA-archive, plus web; 350 hits, 0 high), manual JIRA REST searches (LUCENE and SOLR: FreeTextSuggester, FreeTextLookupFactory, the error text, 'separator byte'), GitHub searches in apache/lucene, apache/solr, apache/lucenenet, elastic/elasticsearch and opensearch-project/OpenSearch, the changed files of all 407 open (only #13390, a stale ShingleFilter refactor, touches FreeTextSuggester.java) and 4547 closed apache/lucene PRs, the body and comments of #6278 (LUCENE-5214, the introducing issue, 12 comments), #11328, #6955, #7264 and #15134, lists.apache.org threads and 8 web queries; the finder's, the independent reproduction's and the intended-behaviour check's searches agree. Closest related item, not the same bug: SOLR-11139 (open since 2017-07-24, no comments, mirrored on dev@) quotes the same build loop and asks for the opposite behaviour (skip offending terms instead of failing the whole build); it does not mention that the check misses separator-containing tokens, the javadoc promise or any lookup failure, and neither fix resolves the other; its solr-user thread (2017-07) shows a configuration whose analyzer emits the separator inside tokens, where the check fired correctly. Different items: SOLR-7084 (fixed 2015, an NPE when lookup runs before build), SOLR-11668, SOLR-5631, #5600 (LUCENE-4534), #4915 / #5885 / #6094 (AnalyzingSuggester separators). Not fixed upstream: the check is unchanged on upstream main a95c754ee003, branch_10x and branch_10_6. Gaps: Stack Overflow question 71582458 could not be read; GitHub search is best effort (rate limits, retried); private reports cannot be searched
- Lucene commit tested
- main
645d4fe14a20(11.0.0-SNAPSHOT): the minimal test with gradle in a fresh scratch worktree, assertions on (fails; with the per-token check it passes,checkGoogleJavaFormatpasses and the whole suggest suite passes: 237 tests in 32 suites, 7 skipped, 0 failures), the same earlier with assertions off, and the standalone runner (-ea,-da: fails; with the fix shadowed: passes); the 10.6.0 release jars (-ea,-da: fails); a steps probe withUnicodeWhitespaceAnalyzer(-ea:AssertionError,-da:NullPointerException; with the fix the bad builds throw the documentedIllegalArgumentException). The hunt's tests and its verifiers ran on maina9779ef3c193, whereFreeTextSuggester.javais byte-identical (the exhaustive harness onea57360912ed, also unchanged), and on the 10.5.2 and 9.12.3 jars; the history sweep ran a public-API probe on 11 releases from 4.6.0 to 10.5.2 and on main ata9779ef3c193. The file is unchanged on upstream main716d6f216f5(2026-10-29).
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:87 (at a9779ef3c193) (javadoc: 'Likely this suggester would only be used as a fallback'), :103 (@lucene.experimental), :147-151 (DEFAULT_SEPARATOR = 0x1e: 'The input tokens produced by the analyzer must not contain this character'), :176-180 (4-arg constructor javadoc: 'No input tokens should have this byte, otherwise {@code IllegalArgumentException} is thrown'), :185-186 (both analyzers wrapped by addShingles), :214-235 (addShingles: ShingleFilter(tokens, 2, grams) joins tokens with the separator, :229), :300-322 (build: for each shingled term read back from the temporary index, ngramCount = countGrams(term); throws only if ngramCount > grams, :305-306; unigram count totTokens only for ngramCount == 1), :328 (fst assigned only after a successful build), :414-423 (countGrams = 1 + number of separator bytes), :455-468 (lookup: exact per-token check of countGrams against the shingle position length, 'Safety: make sure the recalculated count "agrees"'), :571-580 (lookup: the context prefix must exist in the FST, 'assert output != null' at :576, decodeWeight at :577), :721-725 (decodeWeight unboxes the null Long at :724)lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestFreeTextSuggester.java:121-134 (at a9779ef3c193) (testIllegalByteDuringBuild: 'no input token is allowed to contain it', asserts IAE for 'foo\u001ebar baz', which has the neighbour 'baz')a Lucene clone origin/main a95c754ee003, origin/branch_10x 1309534296e3, origin/branch_10_6 2763db11b0a7 FreeTextSuggester.java (read 2026-10-26: the javadoc promise at :180, ShingleFilter at :229 and the 'ngramCount > grams' check at :306 or :310 are unchanged)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:147-151, :157-186, :214-235, :276-284, :300-321, :414-423, :459-468, :494-509, :550, :572-581, :722-725
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:87 (fallback), :103 (@lucene.experimental), :147-151, :176-181, :328 (fst assigned only after a successful build), :342, :345a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/core/WhitespaceTokenizer.java:70-74 (Character.isWhitespace), LetterTokenizer.java:57-61 (Character.isLetter), SimpleAnalyzer.java:36 (LetterTokenizer); lucene/core/src/java/org/apache/lucene/analysis/standard/StandardTokenizer.java:28-38 (UAX #29)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:147-151, :176-181, :305-313, :459-468, :576a Lucene main checkout (645d4fe14a20) lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestFreeTextSuggester.java:121-134 (testIllegalByteDuringBuild), :136-151 (testIllegalByteDuringQuery)
- History
a Lucene clone: git show 54283150a81 (comment typo only); origin/main 716d6f216f5 FreeTextSuggester.java identical to 645d4fe14a20
- Diagrams
a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:214-235, :305-313, :414-423, :572-581, :724
- TestFreeTextSuggesterSeparatorInToken.java (lucene/suggest, package org.apache.lucene.search.suggest.analyzing, 1 test):
repro/LFV-600/src/org/apache/lucene/search/suggest/analyzing/TestFreeTextSuggesterSeparatorInToken.java(35 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the executed runs listed under Sources.
assets/LFV-600/bug.png(451 KB)