Lucene keeps two numbers that BM25 divides: each document's field length dl, stored in the norm, and the field's sumTotalTermFreq, from which it computes the average length avgdl. On a DOCS_AND_CUSTOM_FREQS field the first counts terms and the second adds up the custom values.
- Custom term frequencies. An analysis chain can attach an integer to each term:
DelimitedTermFrequencyTokenFilterturnsa|5into the termawith frequency 5. Lucene stores that number in the postings, and scorers read it as the term's frequency in the document. DOCS_AND_CUSTOM_FREQS(new in 10.5.0) marks a field whose custom values are opaque scores, not counts: a term may occur only once per document, and the field length counts 1 per term, so that large values cannot overflow it.- BM25 length normalisation favours shorter documents: it compares each document's length dl (from the norm) with the field's average length avgdl =
sumTotalTermFreq/ number of documents with the field.
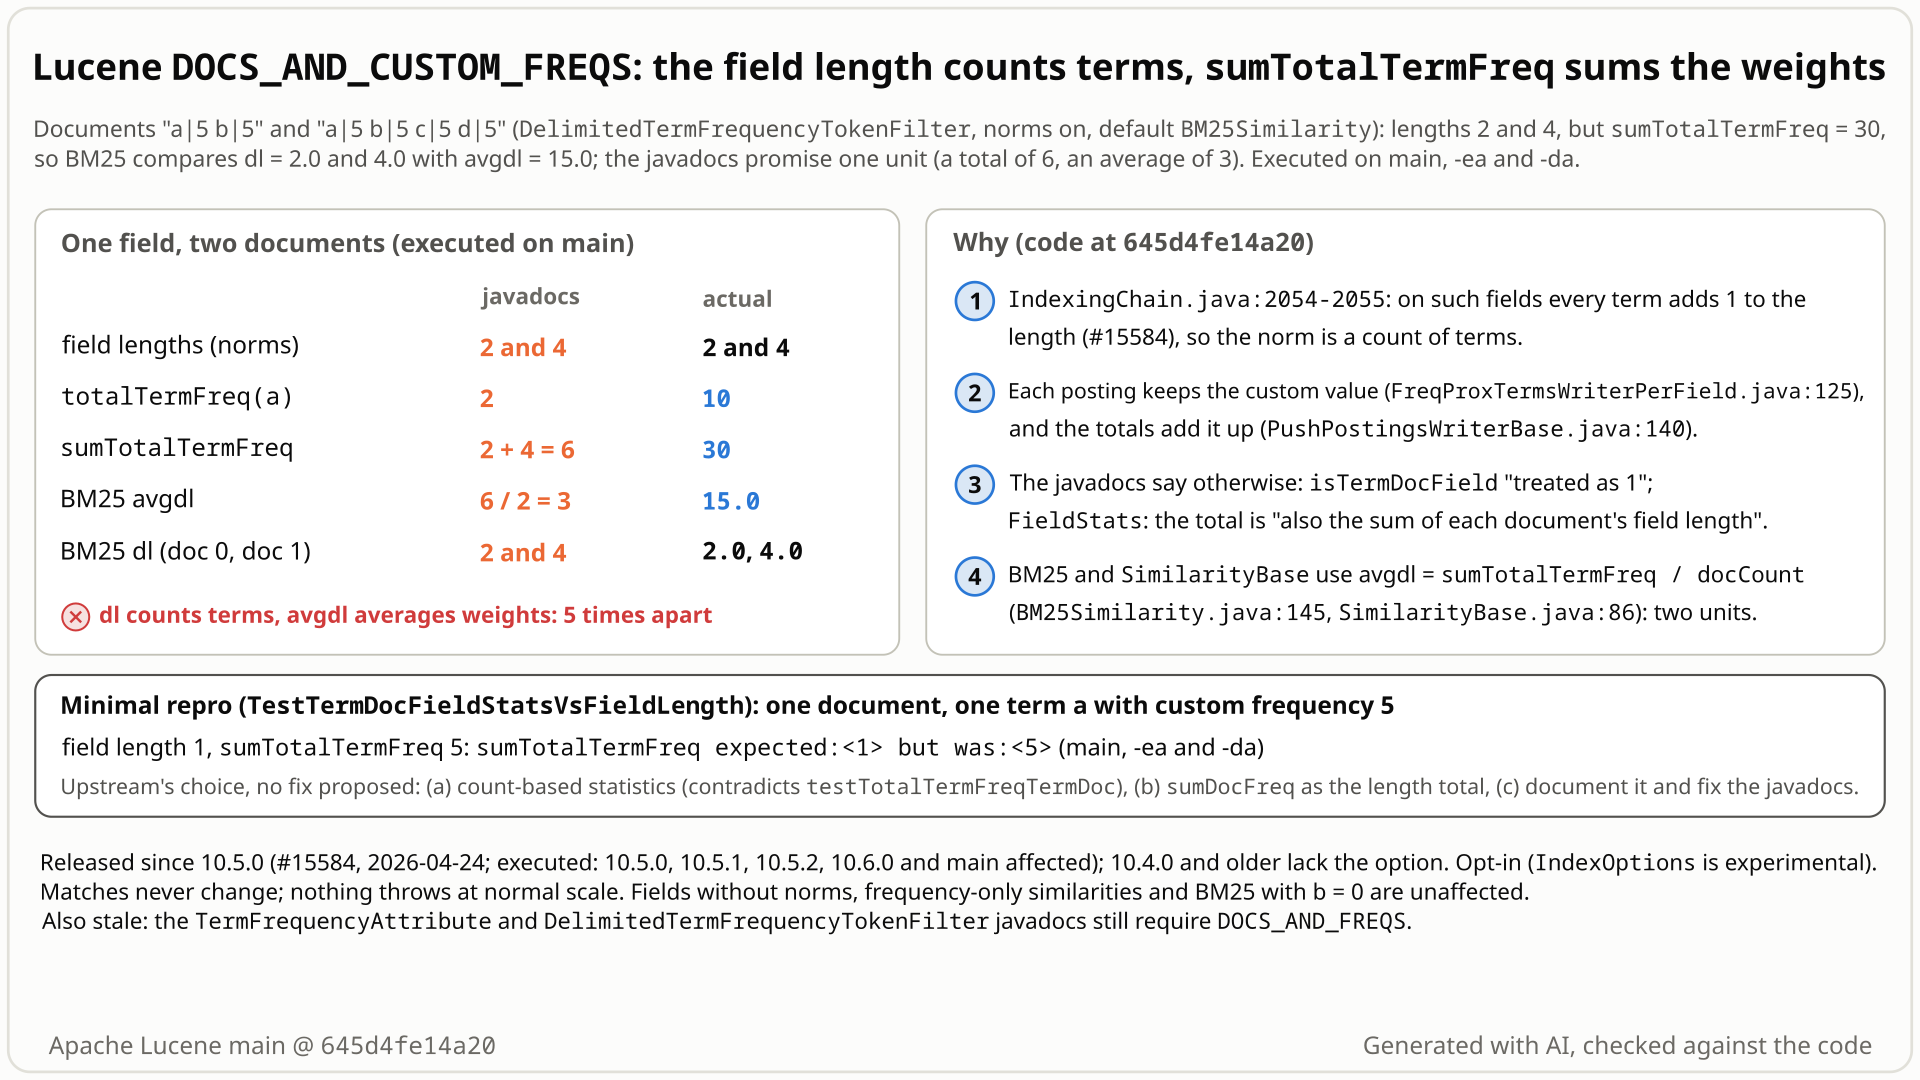
sumTotalTermFreq adds up the custom 5s (30), so dl 2 and 4 meet avgdl 15. Select the still to open it at full size. Generated with AI, checked against the code.- You index "a|5 b|5" and "a|5 b|5 c|5 d|5" into a
TextField-type field (norms on) set toDOCS_AND_CUSTOM_FREQS, so every term carries the custom frequency 5. Lucene records the field lengths as 2 and 4: one per term. - The javadocs say such frequencies count as 1 "for statistical and scoring purposes" (
FieldInfo#isTermDocField) and thatsumTotalTermFreq"is also the sum of each document's field length" (FieldStats). So you expectsumTotalTermFreq= 2 + 4 = 6, and BM25's average length avgdl = 6 / 2 = 3. - Instead
sumTotalTermFreqis 30, the sum of the 5s, and BM25 explains dl = 2.0 and 4.0 against avgdl = 15.0: the lengths are in terms, the average is in custom-value units. - Length normalisation is much weaker: query
ascores the short document 0.1682 and the long one 0.1646, 2% apart. The same data on a legacyDOCS_AND_FREQSfield, where both sides sum the custom values, scores 0.1545 and 0.1402, 10% apart. No error, and the same documents match.
Only fields indexed with the opt-in DOCS_AND_CUSTOM_FREQS (10.5.0 and later). Anyone relying on the FieldInfo or FieldStats javadocs gets a wrong contract; scores change only with norms on and a length-normalising similarity such as the default BM25. In the recorded probes, matches, deletions and CheckIndex are unaffected, and nothing throws at normal scale.
Mechanism, terms and numbers575 words
Since 10.5.0 a field can be indexed with IndexOptions.DOCS_AND_CUSTOM_FREQS: each term occurs at most once per document and carries an opaque custom value. For such fields IndexingChain adds 1 per term to the field length, so the norm stores a term count (minus overlapping tokens, by default), while the postings keep the custom value, so totalTermFreq and sumTotalTermFreq sum the custom values. FieldInfo#isTermDocField says the frequency "for statistical and scoring purposes is treated as 1" and FieldStats says sumTotalTermFreq "is also the sum of each document's field length"; neither holds on this option, and nothing documents the exception.
The measured consequence: BM25 and every SimilarityBase model take avgdl from sumTotalTermFreq / docCount and compare it with dl from the norm, so on such fields dl counts terms while avgdl is inflated by the mean custom value per posting (without overlapping tokens). For two documents with custom frequency 5 everywhere, dl = 2 and 4 meet avgdl = 15 instead of 3, and the short document's lead for query a drops from 10.2% to 2.2%. In the recorded default-BM25 scope probes, hit sets, deletions, CheckIndex and pruned top-k matched the controls, and nothing throws at normal scale. Both halves are deliberate and tested upstream, so this is a documentation and API-contract defect, with the BM25 effect as an open question: the #15584 author asked about BM25 on such fields, and nobody discussed dl against avgdl.
IndexingChain.java:2053-2064, once per token:
if (fieldInfo.isTermDocField()) {
  invertState.length = Math.addExact(invertState.length, 1);                       // :2054-2055
} else {
  invertState.length =
      Math.addExact(invertState.length, invertState.termFreqAttribute.getTermFrequency()); // :2057-2059
}- Length. On
DOCS_AND_CUSTOM_FREQSthe length grows by 1 per term; on every other option by the custom value.Similarity#computeNormencodes it (minus overlaps by default) into the norm (Similarity.java:151-161). This is the #15584 change, made so that large custom values no longer overflow the per-document length ("too many tokens", the #11086 / LUCENE-10048 use case). - Postings and term statistics. The posting freq is still the custom value (
FreqProxTermsWriterPerField.java:125,:177, viagetTermFreq()at:208-209); a second occurrence of a term in one document is rejected (:193-194). The postings writer sumsfreq()intototalTermFreq(PushPostingsWriterBase.java:139-140), as theTermsEnumandTermsjavadocs define it andCheckIndexenforces. - Search-time statistics.
IndexSearcher#fieldStatssumsTerms#getSumTotalTermFreqover the leaves (IndexSearcher.java:1144-1159);termStatspassestotalTermFreqthrough (:1130-1133). - Consumers.
BM25Similarity#avgFieldLengthissumTotalTermFreq / docCount(BM25Similarity.java:143-145);SimilarityBasesets the field's token count and average length fromsumTotalTermFreq(SimilarityBase.java:85-86). TheSimilarityclass javadoc recommends exactly that (Similarity.java:54-55).
So only on this option is dl in terms while avgdl is in custom-value units: without overlapping tokens, avgdl is multiplied by sumTotalTermFreq / sumDocFreq, the mean custom value per posting (30 / 6 = 5 in the example). On legacy DOCS_AND_FREQS custom frequencies both sides sum the custom values; on DOCS fields both count unique terms.
| field | doc "a|5 b|5" | doc "a|5 b|5 c|5 d|5" | short doc ahead by |
|---|---|---|---|
DOCS_AND_CUSTOM_FREQS | 0.16819333 (dl 2, avgdl 15) | 0.16455016 (dl 4, avgdl 15) | 2.2% |
legacy DOCS_AND_FREQS, same custom values | 0.1545098 (dl 10, avgdl 15) | 0.14024736 (dl 20, avgdl 15) | 10.2% |
DOCS_AND_CUSTOM_FREQS with option B (count-stats) | 0.1545098 (dl 2, avgdl 3) | 0.14024736 (dl 4, avgdl 3) | 10.2% |
sumDocFreq is 6 and sumTotalTermFreq 30 on both stock fields. The probe is a printing test, not the repro.
Exposure and likelihood334 words
- Who. Applications that index a field with
IndexOptions.DOCS_AND_CUSTOM_FREQS(released in 10.5.0; theIndexOptionsenum is@lucene.experimental).- Code that reads
FieldInfo#isTermDocField,FieldStatsor theSimilarityjavadoc to decide what the statistics mean, for example a custom similarity or a distributed-statistics layer, gets a wrong contract. - Scores change with norms on (a
TextField-derived type keeps them) and a length-normalising similarity: the defaultBM25Similarityor anySimilarityBasemodel (DFR, IB, LM). Without overlapping tokens, dl / avgdl shrinks by the mean custom value per posting: 5 in the example, where the short document's lead drops from 10.2% to 2.2%. Custom values may go up toInteger.MAX_VALUE(upstream'stestNoOverflowInt), and larger values can weaken length normalisation much further; how much depends on b, k1 and how the values are spread. One document with large values raises avgdl for the whole field.
- Code that reads
- Not affected. Fields without norms (every document then has dl = 1), BM25 with b = 0, similarities that ignore length (upstream's tests score this option with pass-through similarities, and
BaseSimilarityTestCaseruns it with norms omitted), legacyDOCS_AND_FREQScustom frequencies, and, in the recorded default-BM25 scope probes, everything except scoring: on an index with deletions, 120 queries gave the same hit sets as a legacy custom-frequency index and CheckIndex was clean on both; on 150 queries pruned top-1/top-10 equalled exhaustive scoring; scores stayed finite. The probes cover the tested cases, not every query, codec or similarity. - Silent. At normal scale, no exception and no log; only
explain()shows the mismatch between dl and avgdl. - No scale needed. One document shows it. Nothing wrong is written to the index:
IndexSearchercombines the statistics at search time, so a search-time fix (option B) changes the statistics it gives the scorers without a reindex; the raw postings statistics (TermsEnum,Terms) stay in custom-value units. - How likely: rare. The option is new (April 2026) and meant for opaque per-term scores with custom scoring; code search found no downstream user beyond an Elasticsearch back-compat test.
One JUnit test on the public API, core and test-framework only: one document whose single term a has custom frequency 5, in a TextField-type field set to DOCS_AND_CUSTOM_FREQS. A BM25Similarity subclass adds up the field lengths Lucene passes to computeNorm; the test compares that sum with fieldStats("f").sumTotalTermFreq().
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.FieldInvertState;
import org.apache.lucene.index.IndexOptions;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.similarities.BM25Similarity;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.CannedTokenStream;
import org.apache.lucene.tests.analysis.Token;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestTermDocFieldStatsVsFieldLength extends LuceneTestCase {

  public void testSumTotalTermFreqIsSumOfFieldLengths() throws IOException {
    long[] sumOfFieldLengths = new long[1];
    IndexWriterConfig iwc = new IndexWriterConfig();
    iwc.setSimilarity(
        new BM25Similarity() {
          @Override
          public long computeNorm(FieldInvertState state) {
            sumOfFieldLengths[0] += state.getLength();
            return super.computeNorm(state);
          }
        });
    FieldType ft = new FieldType(TextField.TYPE_NOT_STORED);
    ft.setIndexOptions(IndexOptions.DOCS_AND_CUSTOM_FREQS);
    Token a = new Token("a", 0, 1);
    a.setTermFrequency(5);
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, iwc)) {
      Document doc = new Document();
      doc.add(new Field("f", new CannedTokenStream(a), ft));
      w.addDocument(doc);
      try (DirectoryReader r = DirectoryReader.open(w)) {
        // expected 1 (FieldStats: "also the sum of each document's field length"); actual 5
        assertEquals(
            "sumTotalTermFreq",
            sumOfFieldLengths[0],
            new IndexSearcher(r).fieldStats("f").sumTotalTermFreq());
      }
    }
  }
}
cd $LUCENE && ./gradlew :lucene:core:test --tests TestTermDocFieldStatsVsFieldLength -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
sumTotalTermFreqis 1, the sum of the field lengths (one document, one term).- Observed
sumTotalTermFreq expected:<1> but was:<5>: it is the custom frequency, with assertions on and off.
More files, environment, full output258 words
Deterministic, single thread, no random() in the test body; the test framework's per-seed codec choice does not change the values (seeds DEADBEEF, 5EED1234 and C0FFEE, assertions on and off).
The custom value comes from a test-framework Token (setTermFrequency(5), i.e. the TermFrequencyAttribute), as upstream's TestCustomTermFreq feeds this option with its own CannedTermFreqs stream; the javadocs of the documented feeders (TermFrequencyAttribute, DelimitedTermFrequencyTokenFilter) still say DOCS_AND_FREQS (option A fixes them).
It asserts the documented identity only and does not say which half upstream should change; both are deliberate and tested. It passes with option B and keeps failing with the javadoc-only option A, so it is a regression test only for a behavioural fix. The BM25 consequence is the probe in the full explanation above, deliberately not part of the repro.
On 10.x, call new IndexSearcher(r).collectionStatistics("f") instead of fieldStats("f"): main renamed CollectionStatistics to FieldStats in fa0e704d2a0 (#15929), and 10.x carries the same javadoc sentence.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; with option B: passes. Also fails on the 10.6.0, 10.5.2, 10.5.1 and 10.5.0 release jars (10.x port: collectionStatistics) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; plain integer statistics) |
cp $REPRO/TestTermDocFieldStatsVsFieldLength.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestTermDocFieldStatsVsFieldLength -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
TestTermDocFieldStatsVsFieldLength > testSumTotalTermFreqIsSumOfFieldLengths FAILED
    java.lang.AssertionError: sumTotalTermFreq expected:<1> but was:<5>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:916F8584BC265B64]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:647)
        at org.apache.lucene.search.TestTermDocFieldStatsVsFieldLength.testSumTotalTermFreqIsSumOfFieldLengths(TestTermDocFieldStatsVsFieldLength.java:60)

1 test completed, 1 failed

# the same test on IndexOptions.DOCS_AND_FREQS passes: length 5 == sumTotalTermFreq 5FieldInfo#isTermDocFieldsays the frequency "for statistical and scoring purposes is treated as 1"; upstream's own tests expecttotalTermFreq92 = 42 + 50 and a score of 17.FieldStats:sumTotalTermFreq"is also the sum of each document's field length", true for custom frequencies until 10.5.0.- Nothing documents the split, and nobody on #15584 or #11086 discussed dl against avgdl.
The full argument392 words
- The javadoc says the opposite of what the index does.
FieldInfo.java:717-720: "Returns true if the field has custom term frequencies indexed that are to be treated as opaque values, while the term frequency for statistical and scoring purposes is treated as 1." Upstream's tests contradict both halves:TestCustomTermFreq#testTotalTermFreqTermDoc(:314-344) expectstotalTermFreq92 = 42 + 50 and 188 = 128 + 60, andTestSimilarity#testTermDocSimilarity(:207-248) expects aTermQueryscore of 17, the custom value, under a similarity whosetf(freq)isfreq(:48). FieldStatsdocuments an identity that held until 10.5.0.FieldStats.java:55-58: sumTotalTermFreq "is the sum of TermStats#totalTermFreq() across all terms. It is also the sum of each document's field length across all documents." The sentence dates from LUCENE-8007 (2017); the same repro onDOCS_AND_FREQSpasses on 9.12.3, 10.4.0, 10.5.0, 10.5.1, 10.5.2, 10.6.0 and main.Similarity.java:54-55tells similarity authors to compute the average length from it.- Nothing documents the exception. No javadoc,
MIGRATE.mdor CHANGES text mentions termdoc statistics; the CHANGES entry covers the length half and ends mid-sentence: "IndexWriter counts their terms rather than summing their freqs. Use" (lucene/CHANGES.txt:919-920). TheTermFrequencyAttributeandDelimitedTermFrequencyTokenFilterjavadocs still say the field "must be indexed with IndexOptions#DOCS_AND_FREQS" (2017), although upstream's tests feed custom frequencies intoDOCS_AND_CUSTOM_FREQSfields. - The question was asked; the units were never discussed. On #15584 (2026-01-17) msokolov wrote "I guess someone might try using BM25 simlarity with this field, or some scoring that assumes that totalTermFrequency > termFrequency(doc)?", and rmuir answered "Searching and pruning would be my concerns. Look at BaseSimilarityTestCase for the former." The PR then ran
BaseSimilarityTestCaseon the option with norms omitted and synthetic statistics, and added a pass-through-similarity score test, so nothing exercises dl against avgdl. On #11086 (2026-01-16) msokolov asked what would happen "if someone were to, say, compute the default Similarity over such a field (we don't plan to do that, but someone could, and it shouldn't break in a horrible way)"; nobody replied. No comment on either thread mentions the length /sumTotalTermFreqsplit. - Precedent for one unit. LUCENE-8025 (#9073) and LUCENE-8031 (#9079), the same kind of mismatch on
DOCSfields, were fixed as bugs in 2017 and 2018; on one test collection rmuir measured BM25 MAP 0.0531 before and 0.1390 after. LUCENE-7854 (#8905) asked for custom frequencies to give lengths "same as if i stacked".
The devil's-advocate check290 words
The strongest case for "intended" (the intended-behaviour check, the study's cross-model lenses and the adjudication rated it moderate; the 2026-10-31 refute re-run and the cross-model fact check rated it strong for the code behaviour, the fact check "weak for the documentation as written"): each half is deliberate and tested. testFieldInvertState pins the length at 2 for the freqs {42, 128} (TestCustomTermFreq.java:612-631) and testTotalTermFreqTermDoc pins totalTermFreq at 92. Terms and TermsEnum define the totals as sums of freq(), and CheckIndex enforces it. The custom values are "scores", not counts; the author called BM25 on such fields a non-goal that "shouldn't break in a horrible way"; on the first, attribute-based draft of #15584 rmuir wrote that it "won't fix the issue of all kinds of crazy/undefined behavior at search-time. It is just allowing it to happen at index-time."; and rmuir called avgdl "just a pivot" on LUCENE-8000 (#9048, open). BM25Similarity#avgFieldLength is protected and documented as sumTotalTermFreq / docCount, so an application can override it. And the FieldStats sentence is already loose: on a DOCS field "a a" the length is 2 while sumTotalTermFreq is 1, and with a stacked synonym BM25 sees dl 1.0 against avgdl 2.0.
Why it fails: it defeats a claim that the statistics code is wrong, which this report does not make. It does not defeat the documentation defect: the isTermDocField javadoc is false for statistics and for scoring whichever side upstream keeps, and nothing documents the split. On DOCS fields BM25 still compares dl and avgdl in one unit, and synonyms follow the documented discountOverlaps rule; only the termdoc option fails both readings (length vs sumTotalTermFreq, dl vs avgdl). "Not horrible" is why the impact is minor, not why it is correct.
Recommended Correct the javadocs (the minimum)
At minimum, correct the javadocs: FieldInfo#isTermDocField, IndexOptions, FieldStats and Similarity should say that the field length counts terms while statistics and scorers see the custom values, and the feeder javadocs should allow this option. To keep the old promise instead, count each term once in IndexSearcher's statistics: the repro and 2,355 tests pass.
/**
 * Returns true if the field is indexed with {@link IndexOptions#DOCS_AND_CUSTOM_FREQS}: each term
 * occurs at most once per document and carries a custom term frequency, an opaque value rather
 * than a count. Only the field length ({@link FieldInvertState#getLength()}) counts each term
 * once; {@link PostingsEnum#freq()} returns the custom value, and {@link
 * TermsEnum#totalTermFreq()} and {@link Terms#getSumTotalTermFreq()} sum the custom values.
 */
public boolean isTermDocField() {
All options and trade-offs4 options · 791 words
Both options were built and checked with gradle in a scratch worktree of 645d4fe14a20 (OpenJDK 25.0.3, 2026-10-31). Which is right is a design choice for upstream; option A is needed under every choice, because the "scoring purposes" half of the FieldInfo javadoc is false whatever happens to the statistics.
Javadoc only, +16/-6 lines in 6 files: FieldInfo#isTermDocField (below); IndexOptions.DOCS_AND_CUSTOM_FREQS adds "The field length counts each term once, while TermsEnum#totalTermFreq() and Terms#getSumTotalTermFreq() sum the custom freqs, so a similarity that compares a document's length with the average length (such as BM25) sees the two in different units."; FieldStats (sumTotalTermFreq) and the Similarity class javadoc name the exception; TermFrequencyAttribute and DelimitedTermFrequencyTokenFilter allow DOCS_AND_CUSTOM_FREQS next to DOCS_AND_FREQS.
/**
 * Returns true if the field is indexed with {@link IndexOptions#DOCS_AND_CUSTOM_FREQS}: each term
 * occurs at most once per document and carries a custom term frequency, an opaque value rather
 * than a count. Only the field length ({@link FieldInvertState#getLength()}) counts each term
 * once; {@link PostingsEnum#freq()} returns the custom value, and {@link
 * TermsEnum#totalTermFreq()} and {@link Terms#getSumTotalTermFreq()} sum the custom values.
 */
public boolean isTermDocField() {
Trade-offs
- No behaviour change, so it fits a bugfix release.
- BM25's units stay split; the javadoc then says so instead of promising the opposite.
- The minimal repro keeps failing, so it is not a regression test for this option.
- The study's audit, written from a committer's view, would merge exactly this: a javadoc fix "saying that the statistics and scoring see the custom value, and that length-normalising similarities such as BM25 compare a term-count dl with an avgdl in custom-value units".
What the checks validated
checkGoogleJavaFormat (after applyGoogleJavaFormat rewrapped one line), renderJavadoc and ecjLintMain pass for lucene:core and lucene:analysis:common.
+22/-1 lines in IndexSearcher.java: for a field whose FieldInfo#isTermDocField() is true, termStats reports totalTermFreq = docFreq and fieldStats reports sumTotalTermFreq = sumDocFreq, the term count that the field length uses. The raw index statistics are unchanged.
public TermStats termStats(Term term, int docFreq, long totalTermFreq) throws IOException {
  if (isTermDocField(term.field())) {
    // custom freqs are opaque values, not counts: each term counts once per document
    totalTermFreq = docFreq;
  }
  // This constructor will throw an exception if docFreq <= 0.
  return new TermStats(term.bytes(), docFreq, totalTermFreq);
}
// fieldStats(): sumTotalTermFreq += termDoc ? terms.getSumDocFreq() : terms.getSumTotalTermFreq();
// isTermDocField(field): the FieldInfo of the first leaf that has the field
Trade-offs
- Makes the
TermStatsandFieldStatsthatIndexSearchersupplies count-based for termdoc fields, so "for statistical purposes treated as 1" and bothFieldStatsidentities hold for those statistics, and puts dl and avgdl in one unit: the example then scores exactly like the legacyDOCS_AND_FREQSfield (0.1545 and 0.1402). The publicTermsEnum#totalTermFreq()andTerms#getSumTotalTermFreq()stay in custom-value units; CheckIndex andtestTotalTermFreqTermDocare untouched; no reindex. - Behaviour change: BM25 and
SimilarityBasescores on existing termdoc fields with norms change (LM, DFR and IB models also see count-based collection statistics), so it may suit main better than a 10.x bugfix release. - Both methods must change together: changing only
fieldStatswould break the documentedtotalTermFreq <= sumTotalTermFreqand trip the assertion inSimilarityBase.java:80. - Subclasses that override
termStats/fieldStats(distributed statistics) keep the raw values, and the "scoring purposes" half of the javadoc still needs option A's wording. isTermDocField(field)takes theFieldInfoof the first leaf that has the field. Within one index a field's index options cannot change (FieldInfo#verifySameIndexOptions), but anIndexSearcherover aMultiReaderthat combines a termdoc leaf and a legacy leaf of the same field name would apply the first leaf's rule to every leaf; a real patch should decide per leaf or reject the mix.- One
FieldInfoslookup over the leaves per call (it stops at the first leaf with the field); not benchmarked.
What the checks validated
- Stock: the minimal test fails. With the patch it passes, with assertions on and off.
:lucene:core:test --tests "org.apache.lucene.search.*" --tests TestCustomTermFreq(216 classes, includingTestSimilarity,search.similarities.*and the repro): 2,355 tests, 0 failures with seed DEADBEEF and assertions on, and again with seed C0FFEE and assertions off.checkGoogleJavaFormat,ecjLintMainandforbiddenApisMainfor core pass.- The BM25 probe with the patch gives avgdl 3.0 and the legacy field's scores.
The LUCENE-8025 pattern: BM25 and SimilarityBase use sumDocFreq / docCount as the average length on termdoc fields.
Trade-offs
FieldStats carries no index options, so it needs a new flag; it fixes BM25 but not the javadocs, and the repro keeps failing.
Revert the IndexingChain.java:2054-2055 branch.
Trade-offs
Restores one unit but brings back the per-document "too many tokens" overflow that #15584 removed.
Downstream: code search found no product that exposes DOCS_AND_CUSTOM_FREQS yet, only an Elasticsearch back-compat test, so today the reach is applications that choose the option themselves.
A metamorphic test indexed the same weighted terms three ways (repeated terms, legacy custom frequencies, DOCS_AND_CUSTOM_FREQS) and expected equal scores. The termdoc field with norms needed its own score class; checking why against the FieldStats javadoc exposed the split, which was then minimised by hand into a public-API JUnit.
The method in full123 words
Method: non-formal (a randomized differential and metamorphic harness, the hunt's tier for executed testing without a model checker or prover).
- A hunt unit tests index-options invariance: family W indexes the same weighted terms as natural repetitions, as legacy custom frequencies on
DOCS_AND_FREQS, and asDOCS_AND_CUSTOM_FREQS, and relation R2 expects bit-identical scores within a score class. - R2 had to put
DOCS_AND_CUSTOM_FREQSwith norms in a class of its own, because its field length counts terms; with norms off R2 held bit-exactly over 440 seeds. Checking that class split against theFieldStatsjavadoc exposed the inconsistency. - The finder minimised it into a 4-test public-API JUnit on the stock jars of main
a9779ef3c193; the registry later reduced it to the one-test repro above.
No prior report found: GitHub issues and PRs (including the migrated JIRA archive), commits, mailing lists, downstream projects and the web, searched on 2026-10-26 and again on 2026-10-31. The introducing PR asked about BM25 on such fields in general; nobody identified the split.
Searches2 searches
- Closest items, none a report of this bug: #15584 and #11086 (the BM25 questions); #9547 (LUCENE-8501: jpountz foresaw in 2018 that changing the length computation would also need
totalTermFreqchanges, for a hypothetical change); #8905 (LUCENE-7854); #9073 and #9079 (LUCENE-8025 and LUCENE-8031, theDOCSanalogue, fixed); #9048 (LUCENE-8000, open, "just a pivot"); #15984, #15999 and elastic/elasticsearch#148022 (other fallout of #15584). Tracking issue #16937 lists this bug. - Limits: GitHub search does not index review comments (the #15584 review thread was read directly); private discussions are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs, commits and code (apache/lucene incl. the JIRA archive, downstream projects), mailing lists, JIRA, web | 2026-10-26 | three scripted prior-report search runs and manual queries, 259 in total (48 GitHub, 54 GitHub-issue, 4 code, 13 commit, 6 downstream, 84 list, 19 JIRA, 31 web); direct reads of #15584 (body, comments, reviews, patch), #11086 and 13 related threads; the changed files of all 407 open apache/lucene PRs | no report; 15 related hits, all a different matter |
| the same channels, fresh round | 2026-10-31 | fresh tool runs and manual queries (223 queries); every apache/lucene issue and PR updated since 2026-10-25 and the changed files of the 53 open PRs among them; recent commits on main, branch_11x and branch_10_6 for the 12 relevant files; lists for the last two months; web | no report and no open PR that changes the code or the javadocs; 19 hits, the same related items |
Introduced by #15584 (5158a52a082, msokolov, merged 2026-04-24; backport 3a55cc9ac5e), which added the option, the isTermDocField javadoc and the term-counting length together. Released in 10.5.0; 10.5.0 to 10.6.0 and main are affected (executed); 10.4.0 and earlier lack the option.
Versions tested5 rows
Introduced by 5158a52a082b (apache/lucene#15584, "Compute 'length' of fields with custom term frequencies as docFreq", fixing #11086 / LUCENE-10048), merged to main on 2026-04-24 and backported to branch_10x as 3a55cc9ac5e. The one commit added IndexOptions.DOCS_AND_CUSTOM_FREQS, FieldInfo#isTermDocField with its javadoc, and the IndexingChain branch; the postings and statistics kept summing freq(). git tag --contains 3a55cc9ac5e gives 10.5.0, 10.5.1, 10.5.2 and 10.6.0. No bisection was needed: the option and the defect arrive in the same commit.
The FieldStats (formerly CollectionStatistics) sentence "also the sum of each document's field length" dates from LUCENE-8007 (2017) and held for custom frequencies until #15584. Upstream main 2f424fd428da (2026-10-30) still has the code and the javadocs.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails with assertions on and off (gradle and standalone runner); passes with option B |
| 10.6.0, 10.5.2 | affected | fails with assertions on and off (release jars, SHA-1 checked; 10.x port of the test) |
| 10.5.1 | affected | fails with assertions on, the same values; the DOCS_AND_FREQS control passes (assertions off, 2026-10-31 fact check) |
| 10.5.0 | first release | fails with assertions on and off, the same values |
| 10.4.0, 9.12.3 | not affected | the option does not exist (the test does not compile); the DOCS_AND_FREQS control passes |
An independent reproducer, a devil's-advocate verifier, an adjudication, a credibility audit, a current-main reproducer and a tie-breaker all reproduced it and scoped it as a documentation and contract defect. Read-only reviews by OpenAI GPT-5.6 agreed on the root cause but could not run code.
Checks and verdicts474 words
No cross-model review could run code (the reviewer could only read files); all execution evidence comes from the Claude-family AI tools and separate runs.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit, metamorphic index-options relations, JUnit) | candidate | A 4-test JUnit fails 2 of 4 on main a9779ef3c193 with assertions on and off: sumTotalTermFreq 30 vs 6, BM25 avgdl 15.0 vs mean dl 3.0; both legacy controls pass. |
| Refute review (OpenAI GPT-5.6, read-only) | not real, by procedure (medium) | Could not run Java; agrees on the root cause and calls its own refutation, the stale feeder javadocs, fragile. |
| Intended-behaviour review (OpenAI GPT-5.6, read-only) | real (medium) | A documentation and API-contract defect, not proof that totalTermFreq must change; the step's re-runs fail 2 of 4. |
| Independent reproducer | real | Own core-only JUnit fails 2 of 5 on main, 10.5.0 and 10.5.2 (lengths sum to 5 vs sumTotalTermFreq 22; dl 2 and 3 vs avgdl 11.0); corrected "unreleased" to "released in 10.5.0". |
| Devil's advocate | real, as a documentation defect | Each half is pinned upstream; the DOCS and synonym controls show the FieldStats sentence is loose; the isTermDocField contradiction survives every intent argument. |
| Adjudication | confirmed (medium), minor | Re-ran the independent reproduction's JUnit with seed C0FFEE: 5 run, 2 fail, with assertions on and off; scoped to the javadoc contradiction and its BM25 consequence. |
| Credibility audit | keep | Re-ran both JUnits with new seeds; minor, as a contract defect. |
| Current-main reproducer (2026-10-31) | real | The minimal test fails on 645d4fe14a20 (on and off), 10.5.2 (on and off) and 10.6.0; the DOCS_AND_FREQS control passes. |
| Refute review re-run (OpenAI GPT-5.6, read-only, 2026-10-31) | not real, by procedure (medium) | Could not start commands, and a separate re-run stopped on a parse error; root cause agrees. |
| Tie-breaker (2026-10-31) | real, scoped as a documentation defect | Re-ran on main (on and off) and 10.6.0 (off); a four-field-type probe shows only the termdoc option fails both readings. |
| This doc (2026-10-31) | real | Gradle in a scratch worktree: stock fails; option B passes the repro and 2,355 tests twice and the core lint checks; option A passes the format, javadoc and lint checks; the BM25 probe on stock and with B. |
| Fact check of this doc (2026-10-31) | correct after two text fixes | Re-ran the repro (main with assertions on and off, 10.6.0, 10.5.1, 10.5.0), the DOCS_AND_FREQS controls (main, 10.5.1, 10.5.2), option B, the BM25 probe and the gradle commands (stock and option B suites, assertions on and off; options A+B format, lint and javadoc). Found two wrong statements, both fixed: the #15584 BM25 question did get a reply, and LUCENE-8031 was fixed in 2018. |
| Cross-model fact check (OpenAI GPT-5.6, read-only, 2026-10-31) | sound on the core defect | Read the code and the recorded runs; its wrong statements, overclaims and missing caveats are fixed or answered. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 446 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,405 words
- Registry title
- DOCS_AND_CUSTOM_FREQS fields (10.5.0+): the norm length counts terms but sumTotalTermFreq and totalTermFreq sum the custom frequencies, contradicting the FieldInfo#isTermDocField, IndexOptions and FieldStats javadocs and putting BM25's dl and avgdl in different units
- Area
- core index / DOCS_AND_CUSTOM_FREQS (termdoc) field length vs term statistics; search similarities (BM25, SimilarityBase)
- Priority
- Low, rank 728: Experimental DOCS_AND_CUSTOM_FREQS fields (10.5) put BM25's dl and avgdl in different units, which contradicts the javadocs but only weakens length normalization for a niche option.
- Impact class
- minor
- Impact note
- This hits applications that index a field with the opt-in, experimental IndexOptions.DOCS_AND_CUSTOM_FREQS (released in 10.5.0). It matters if they rely on the FieldInfo#isTermDocField, IndexOptions or FieldStats javadocs, which promise count-based statistics that the index does not provide. It also matters if they score the field with norms on (TextField keeps them) using the default BM25Similarity or a SimilarityBase model. Length normalisation is then weakened by a factor equal to the mean custom value (5 in the repro). Matches are never wrong, nothing throws, nothing is corrupted, and no scale is needed. Fields without norms, frequency-only similarities and BM25 with b=0 are unaffected.
- Summary
- You index two documents, 'a|5 b|5' and 'a|5 b|5 c|5 d|5', into a field with IndexOptions.DOCS_AND_CUSTOM_FREQS (DelimitedTermFrequencyTokenFilter, a TextField type with norms). Lucene stores their lengths as term counts, 2 and 4. FieldInfo#isTermDocField says such frequencies count as 1 'for statistical and scoring purposes', and FieldStats says sumTotalTermFreq 'is also the sum of each document's field length'. So you expect sumTotalTermFreq to be 6 and BM25's average length to be 3. Instead, sumTotalTermFreq and totalTermFreq sum the custom values (30), and BM25 explains dl=2.0 against avgdl=15.0. Each document's length is compared with an average inflated by the mean custom value, which quietly weakens length normalisation.
- Introduced
- 5158a52a082b842c29918c8b955323d2a0848eb5. This is apache/lucene PR #15584, 'Compute 'length' of fields with custom term frequencies as docFreq', by msokolov, merged into main on 2026-04-24; it fixes #11086 (LUCENE-10048). It was backported to branch_10x as 3a55cc9ac5e96e39a75e837e326085c5efdc894d, and the 10.5.0, 10.5.1 and 10.5.2 tags contain that commit. The PR added three things together: IndexOptions.DOCS_AND_CUSTOM_FREQS with its javadoc, FieldInfo#isTermDocField with its javadoc, and the IndexingChain branch that adds 1 per term to the field length. Postings keep the custom value, so totalTermFreq and sumTotalTermFreq still sum it. Evidence [read]: blame and git log -S in the history clone, git tag --contains; the parent commit d8677f60a22 lacks the option. Evidence [exec]: on 10.4.0 the repro does not compile because the option is absent, and 10.5.0 fails. No commit-level bisection build was needed, because the option and the defect arrive in the same commit. (2026-04-24)
- First affected version
- 10.5.0 [exec]
- Affected versions
- Executed, failing 4 run / 2 failed with the same values: 10.5.0 (-ea and -da), 10.5.1 (-ea), 10.5.2 (-ea and -da) and main a9779ef3c193 (-ea and -da); the independent reproduction's independent JUnit also fails on 10.5.0 and 10.5.2. By reading, the heads of branch_10_5, branch_10_6 and branch_10x are affected too: they have the same IndexingChain branch and javadoc. Not affected: 10.4.0 and every earlier release, including all of 9.x, which lack the option; the repro does not compile on 9.12.3 or 10.4.0 [exec]. On those releases, custom frequencies on DOCS_AND_FREQS keep field length and sumTotalTermFreq in the same unit: the pre-option control passes on 9.12.3, 10.4.0, 10.5.0, 10.5.2 and main [exec]. The defect is not fixed upstream: main a95c754ee003 (2026-10-26) still has the code, and no open PR changes it.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found. Searched 2026-10-26, read-only (the prior-report record, verdict new). The search had three scripted prior-report searches and manual queries: 48 GitHub, 54 GitHub-issue and 4 GitHub-code queries, 9 + 4 commit queries, 6 downstream, 84 mailing-list (dev@, java-user@, issues@, commits@), 19 JIRA and 31 web queries. Read directly: #15584 (body, 22 comments, reviews, review comments, patch), #11086, #8905, #9547, #9990, lucene-solr PR #2080, #9073, #9079, #9048, #9055, #15984, #15986, #15987, #15999, elastic/elasticsearch #148022, two related dev@ threads, the changed files of all 407 open apache/lucene PRs, and the 2026 commits on main, branch_10x and branch_10_6 for the 12 relevant files. No issue, PR, commit, list thread, JIRA entry, downstream report or web page reports the unit split or the javadoc contradictions. No open PR changes the code: #16269 only refactors near it. Related items (context, not reports): in #15584 and #11086, the author and a reviewer raised BM25 or default-similarity behaviour on such fields as an open question ('someone might try using BM25 simlarity with this field'; 'remaining concerns are in scoring system and pruning'). Precedent that bears on intent: LUCENE-7854 (#8905, the length must equal the stacked count), LUCENE-8501 (#9547), LUCENE-8025 and LUCENE-8031 (#9073 and #9079, the DOCS-field analogue, fixed as a bug), and LUCENE-8000 (#9048, open: avgdl is 'just a pivot'). Upstream main a95c754ee003 still has the code.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off through gradle in a scratch worktree (2026-10-31) and through a standalone runner (2026-10-29 and 2026-10-31). With option B (count each term once inIndexSearcher's statistics) it passes, together with the core search package andTestCustomTermFreq(2,355 tests, assertions on and off) and the core format and lint checks; option A's javadoc passes the format, javadoc and lint checks. Release jars: 10.6.0 and 10.5.2 fail with assertions on and off, 10.5.1 and 10.5.0 fail; 10.4.0 and 9.12.3 lack the option, and theDOCS_AND_FREQScontrol passes on all of them (10.5.1 and 10.5.2 run in the 2026-10-31 fact check). Upstream main2f424fd428da(2026-10-30) has the same code and javadocs [read].
- Finding record
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2054-2060 (at a9779ef3c193) (termdoc: length += 1 per term; otherwise length += TermFrequencyAttribute value)lucene/core/src/java/org/apache/lucene/index/FreqProxTermsWriterPerField.java:125, (at a9779ef3c193) 177 (posting freq = the custom value), 193-196 (duplicate termdoc term rejected)lucene/core/src/java/org/apache/lucene/index/FieldInfo.java:717-723 (at a9779ef3c193) (isTermDocField: 'the term frequency for statistical and scoring purposes is treated as 1')lucene/core/src/java/org/apache/lucene/index/IndexOptions.java:52-56 (at a9779ef3c193) (DOCS_AND_CUSTOM_FREQS: custom freqs 'are treated as scores and do not represent term counts ... its frequency in that sense is always 1')lucene/core/src/java/org/apache/lucene/search/FieldStats.java:55-60 (at a9779ef3c193) (sumTotalTermFreq 'is the sum of TermStats#totalTermFreq() across all terms. It is also the sum of each document's field length across all documents')lucene/core/src/java/org/apache/lucene/search/similarities/Similarity.java:54-55 (at a9779ef3c193) (average document length from sumTotalTermFreq and docCount), :151-161 (computeNorm: unique-term count for DOCS, else length minus overlaps or length)lucene/core/src/java/org/apache/lucene/search/similarities/BM25Similarity.java:143-146 (at a9779ef3c193) (avgFieldLength = sumTotalTermFreq / docCount); SimilarityBase.java:85-86 (numberOfFieldTokens and avgFieldLength from sumTotalTermFreq)lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/TermFrequencyAttribute.java:23-27 (at a9779ef3c193) and lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DelimitedTermFrequencyTokenFilter.java:29-32 (field 'must be indexed with IndexOptions#DOCS_AND_FREQS', stale since #15584)lucene/core/src/java/org/apache/lucene/index/Terms.java:105-109 (at a9779ef3c193) and TermsEnum.java:133-138 (getSumTotalTermFreq = sum of totalTermFreq = sum of freq(): the contract the implementation follows)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2053-2064 (at 645d4fe14a20) (length += 1 per term for termdoc fields, else += custom value)lucene/core/src/java/org/apache/lucene/index/FreqProxTermsWriterPerField.java:125, (at 645d4fe14a20) :177, :193-194, :208-209 (posting freq = custom value; duplicate termdoc term rejected)lucene/core/src/java/org/apache/lucene/codecs/PushPostingsWriterBase.java:139-140 (at 645d4fe14a20) (totalTermFreq += freq)lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:1130-1133 (at 645d4fe14a20) (termStats), :1144-1159 (fieldStats sums Terms#getSumTotalTermFreq)lucene/core/src/java/org/apache/lucene/search/similarities/BM25Similarity.java:143-145 (at 645d4fe14a20) (avgFieldLength = sumTotalTermFreq / docCount)lucene/core/src/java/org/apache/lucene/search/similarities/SimilarityBase.java:85-86 (at 645d4fe14a20) (numberOfFieldTokens and avgFieldLength from sumTotalTermFreq)lucene/core/src/java/org/apache/lucene/search/similarities/Similarity.java:54-55 (at 645d4fe14a20) (average length via sumTotalTermFreq and docCount), :151-161 (computeNorm)
- Who is affected
lucene/core/src/java/org/apache/lucene/index/IndexOptions.java:24 (at 645d4fe14a20) (@lucene.experimental), :52-56 (DOCS_AND_CUSTOM_FREQS)lucene/core/src/test/org/apache/lucene/index/TestCustomTermFreq.java:431-468 (at 645d4fe14a20) (testNoOverflowInt: custom value Integer.MAX_VALUE)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/FieldInfo.java:717-723 (at 645d4fe14a20) (isTermDocField javadoc)lucene/core/src/java/org/apache/lucene/search/FieldStats.java:55-58 (at 645d4fe14a20) (sumTotalTermFreq javadoc)lucene/core/src/java/org/apache/lucene/search/similarities/Similarity.java:54-55 (at 645d4fe14a20)lucene/core/src/test/org/apache/lucene/index/TestCustomTermFreq.java:314-344 (at 645d4fe14a20) (testTotalTermFreqTermDoc), :612-631 (testFieldInvertState)lucene/core/src/test/org/apache/lucene/search/TestSimilarity.java:48 (at 645d4fe14a20) (tf(freq) = freq), :207-248 (testTermDocSimilarity, score 17)lucene/CHANGES.txt:919-920 (at 645d4fe14a20) (GITHUB#15584 entry, truncated)lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/TermFrequencyAttribute.java:23-27; (at 645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DelimitedTermFrequencyTokenFilter.java:29-32 (at 645d4fe14a20)
- Suggested fix
lucene/core/src/java/org/apache/lucene/search/TermStats.java:36-38 (at 645d4fe14a20) (documented conditions)lucene/core/src/java/org/apache/lucene/search/similarities/SimilarityBase.java:80 (at 645d4fe14a20) (assert totalTermFreq <= sumTotalTermFreq)lucene/core/src/java/org/apache/lucene/index/FieldInfo.java:276-287 (at 645d4fe14a20) (verifySameIndexOptions: a field's index options cannot change within one index)
- TestTermDocFieldStatsVsFieldLength.java (one test, public API):
repro/LFV-608/src/org/apache/lucene/search/TestTermDocFieldStatsVsFieldLength.java(67 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and an executed probe of the real jar on the same two documents (field lengths, postings, statistics and BM25 explain, with the DOCS_AND_FREQS control).
assets/LFV-608/bug.png(446 KB)