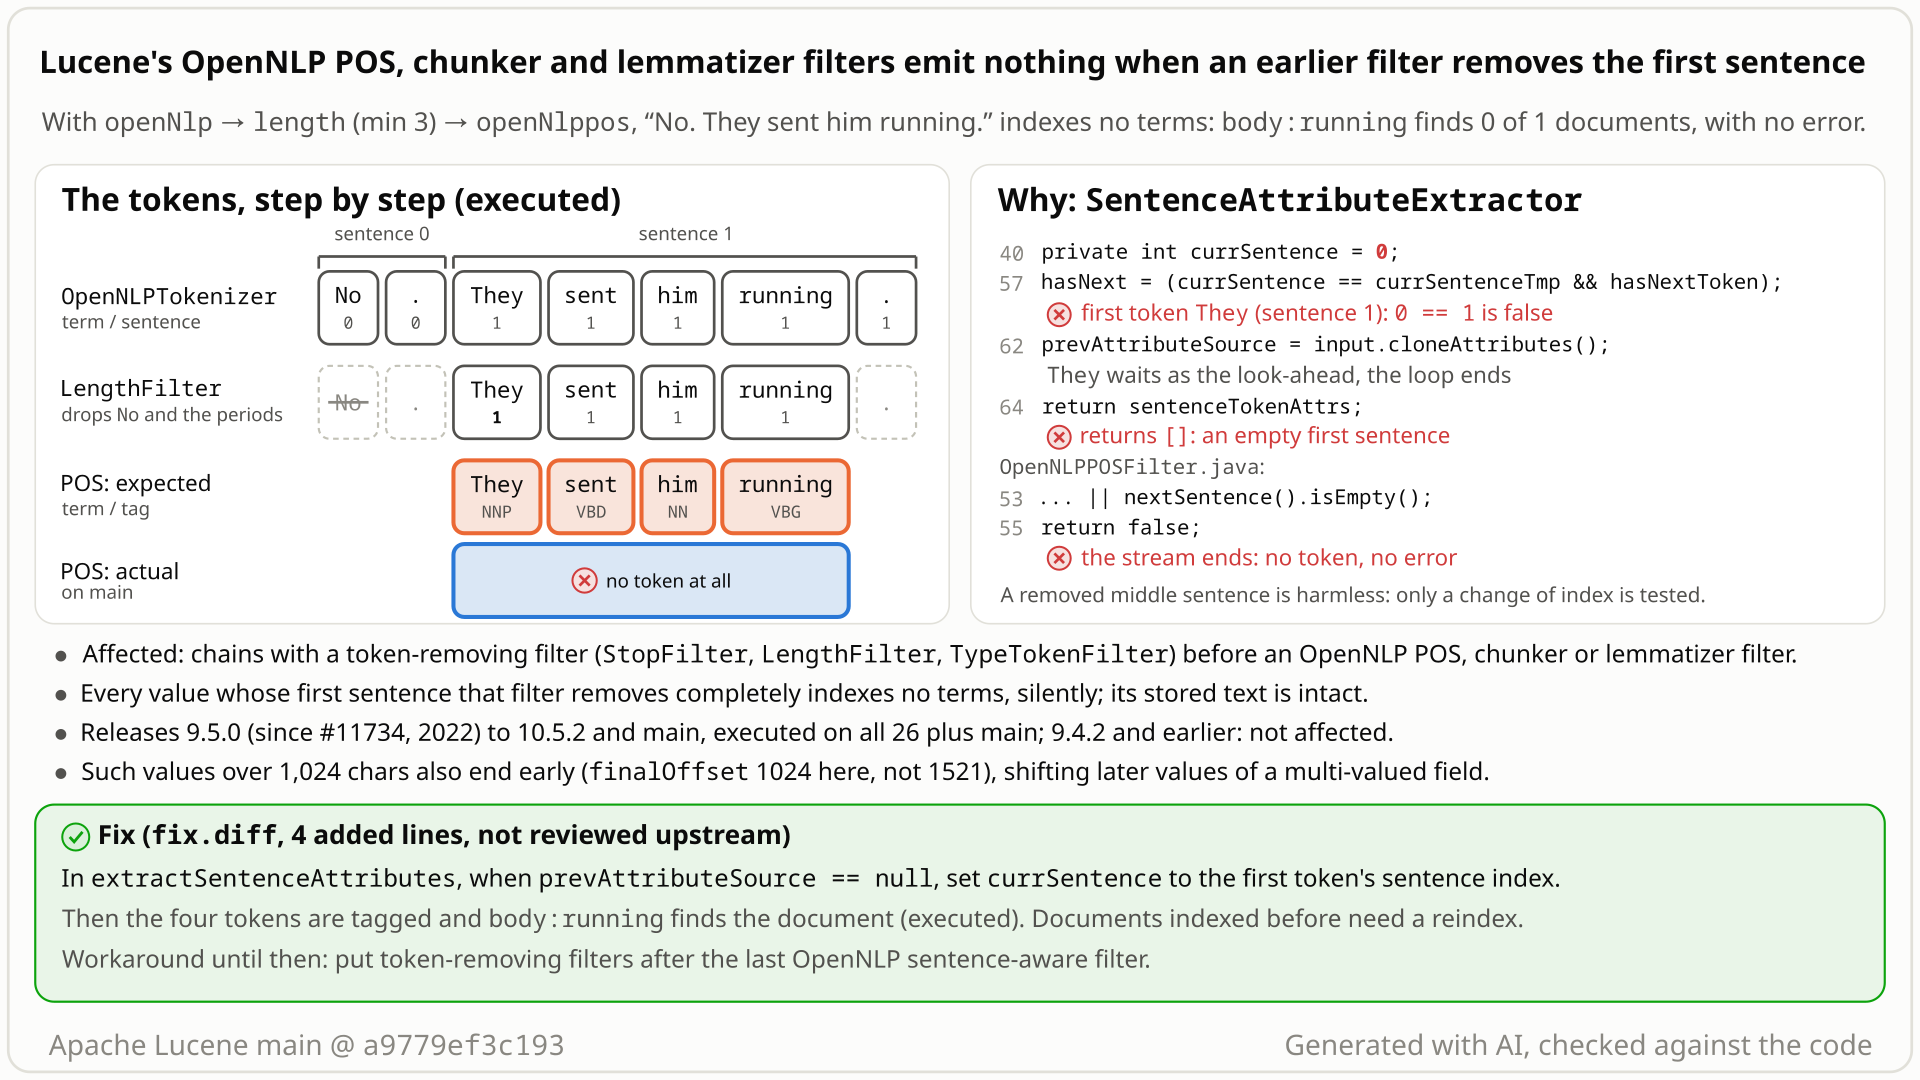
The OpenNLP tokenizer gives every token the index of its sentence (0, 1, 2, ...). The POS, chunker and lemmatizer filters collect one sentence at a time with a shared helper that assumes the first sentence is number 0.
- You keep only nouns and lemmatize them: OpenNLP tokenizer,
OpenNLPPOSFilter,TypeTokenFilterallowingNN,NNS,NNP,NNPS, thenOpenNLPLemmatizerFilter.They sent him running in the evening.gives[they, evening]. - You expect the same
[they, evening]forHe did not come back. They sent him running in the evening.: its first sentence has no noun, so the type filter removes all of it. - You get
[]: not a single token for the whole value. No error; the stored text is intact, but none of its terms reaches the index. - Why: the tokenizer numbers sentences 0, 1, 2. The shared helper
SentenceAttributeExtractorstarts at sentence 0, so when the first token it sees is already in sentence 1 it returns an empty sentence, and all three filters read "empty" as "end of stream". - Same with a stop list {
hi,.} before the chunker:Hi. They sent him running in the evening. He did not come back.gives 0 of 12 tokens, whileHi.in the middle gives all 12.
Users of the opt-in OpenNLP module whose chain removes tokens (a stop list, a minimum length, a POS type filter) before the POS, chunker or lemmatizer filter. Every value whose first sentence that filter empties, punctuation included (Hi., No., or a first sentence without nouns), indexes nothing. Silent and deterministic; existing indexes need reindexing.
Mechanism, terms and numbers698 words
The OpenNLP POS, chunker and lemmatizer filters read their input one sentence at a time through the shared helper SentenceAttributeExtractor, which starts at sentence index 0. When an earlier filter in the chain removed every token of the value's first sentence, the first token the helper sees belongs to sentence 1, the helper returns an empty first sentence, and the filter takes that as the end of the stream. The whole value then indexes no terms while its stored text stays intact: a nouns-only chain turns He did not come back. They sent him running in the evening. into [] instead of [they, evening]. A removed sentence in the middle is handled correctly. Every release from 9.5.0 to 10.6.0 (10.6.0 by reading) and main is affected; the 4-line fix in the helper was validated with the module's tests.
- Sentence index:
OpenNLPTokenizerstores, for each token, the number of its sentence inSentenceAttribute: 0 for the first sentence, 1 for the second, and so on (OpenNLPTokenizer.java:31-34; the index starts at -1 at:45and goes up by one for each detected sentence at:73). - Sentence-aware filters:
OpenNLPPOSFilter,OpenNLPChunkerFilterandOpenNLPLemmatizerFiltertag or rewrite whole sentences, so they first collect one sentence of tokens throughSentenceAttributeExtractor, then emit its tokens one by one. - Look-ahead: the helper reads one token past the end of a sentence to see that the index changed, and keeps that token for the next sentence.
SentenceAttributeExtractorstarts withcurrSentence = 0(SentenceAttributeExtractor.java:40;reset()sets it back to 0 at:78).extractSentenceAttributes()(:51-65) reads tokens whilecurrSentence == currSentenceTmp && hasNextToken(:57). Each token it reads is only stored as the look-ahead (:62); the previous look-ahead is added to the sentence (:59-61).- An earlier filter removed every token of sentence 0, so the first token the helper ever sees,
They, has index 1. First call:0 == 1is false, the loop stops after one token, there is no previous look-ahead to add, andTheybecomes the look-ahead. The call returns an empty list. - The three filters end the stream when
allSentencesProcessed() || nextSentence().isEmpty()is true (OpenNLPPOSFilter.java:52-56,OpenNLPChunkerFilter.java:55-59,OpenNLPLemmatizerFilter.java:66-70). More input is left, but the sentence is empty, soincrementToken()returns false:Theyand everything after it are lost, and the rest of the input is never read. - In the middle of a stream the look-ahead is never null and only a change of index is tested, so a skipped index (0, 0, 2, 2) still splits correctly. Only the initial value 0 is wrong.
- The loss needs a surviving token in a later sentence: if the filter removes every token of a one-sentence value, empty output is correct. If the first two or more sentences are removed, the first index is 2 or more, with the same result.
| chain (stock factories) | input | expected | actual |
|---|---|---|---|
tokenizer, POS, TypeTokenFilter (nouns), dictionary lemmatizer | He did not come back. They sent him running in the evening. | [they, evening] | [] |
tokenizer, POS, StopFilter {hi, .}, chunker | Hi. They sent him running in the evening. He did not come back. | 12 tokens | [] |
tokenizer, StopFilter {hi, .}, POS | the same | 12 tokens | [] |
tokenizer, LengthFilter (min 3), POS | No. They sent him running. | [They, sent, him, running] | [] |
the same chains, Hi. in the middle, or no removed sentence | all tokens | all tokens (correct) | |
| tokenizer directly followed by the filters | 9 adversarial inputs, 404 generated documents | all tokens | all tokens (correct) |
For a value longer than the tokenizer's 1024-char buffer (SegmentingTokenizerBase.java:39), the blanked value is never read to its end, so end() reports a premature final offset, the amount read so far (SegmentingTokenizerBase.java:119-122), instead of its length: 1024 instead of 1504 in the reproducer's test; the differential run also recorded 1029 and 1049. In a multi-valued field the next value's offsets shift accordingly ([1054,1061) instead of [1539,1546)), pointing into the earlier value's text. CheckIndex stays clean.
Exposure and likelihood287 words
- Who is exposed. Users of the
lucene-analysis-opennlpmodule (factoriesopennlpPOS,opennlpChunker,opennlplemmatizer, or the classes) whose chain puts a token-removing filter before a sentence-aware OpenNLP filter:StopFilter,LengthFilterand aTypeTokenFilteron POS tags were executed; any filter that can drop every token of a sentence works. The module is opt-in, and no documented example, upstream test or third-party configuration found uses such a chain (they keep the OpenNLP stages together and putTypeTokenFilterlast). - What it takes. The filter must remove every token of the value's first sentence, punctuation included: a short opener such as
Hi.orNo.under a stop list or a minimum length, or any first sentence without a noun under a nouns-only filter. Once such a chain exists, it fires on every value of that shape. - Effect. The whole value indexes no terms (as long as a later sentence keeps a token): no exception, no log line,
CheckIndexclean, stored text intact. Deterministic, with assertions on and off, at any size. In a differential run on 404 generated documents, the POS filter's output in the chain tokenizer,StopFilter, POS differed from the library reference for 17 documents; with the fixes, for none. - Query side. If the same chain analyzes queries, a query text whose first sentence is removed builds no query at all (
QueryBuilderreturnsnull). - Offsets. Values longer than 1024 chars end with a premature final offset (1024 in the repros), which shifts the offsets of later values of a multi-valued field.
- Lasting. Documents indexed with an affected chain keep the empty field until reindexed.
- How likely. Rare: it needs a legal but undocumented chain shape, and nobody has reported it since 9.5.0 (2023).
The test shows that a sentence-aware OpenNLP filter (here the chunker) emits no token at all when an earlier filter removed every token of the first sentence (opennlp tokenizer -> POS -> LengthFilter(min 3) -> chunker, module test models).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.opennlp;

import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.custom.CustomAnalyzer;
import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.ClasspathResourceLoader;

public class TestChunkerAfterRemovedFirstSentence extends LuceneTestCase {

  public void testFirstSentenceRemoved() throws Exception {
    List<String> terms = new ArrayList<>();
    try (Analyzer a =
            CustomAnalyzer.builder(new ClasspathResourceLoader(getClass()))
                .withTokenizer(
                    "opennlp",
                    "tokenizerModel",
                    "en-test-tokenizer.bin",
                    "sentenceModel",
                    "en-test-sent.bin")
                .addTokenFilter("opennlpPOS", "posTaggerModel", "en-test-pos-maxent.bin")
                .addTokenFilter("length", "min", "3", "max", "100")
                .addTokenFilter("opennlpChunker", "chunkerModel", "en-test-chunker.bin")
                .build();
        TokenStream ts = a.tokenStream("f", "No. They sent him running.")) {
      CharTermAttribute term = ts.addAttribute(CharTermAttribute.class);
      ts.reset();
      while (ts.incrementToken()) {
        terms.add(term.toString());
      }
      ts.end();
    }
    // LengthFilter removed all of sentence 0; expected the tokens of sentence 1, actual: none
    assertEquals(List.of("They", "sent", "him", "running"), terms);
  }
}
# in a copy of this finding's repro folder (repro/LFV-621/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/analysis/opennlp/build/libs/lucene-analysis-opennlp-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.opennlp.TestChunkerAfterRemovedFirstSentence
# the module(s) analysis-opennlp also need their third-party runtime jars
- Expected vs actual
- Expected [They, sent, him, running] for "No. They sent him running."; actual [] on main, with -ea and -da.
More files, environment, full output37 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[They, sent, him, running]> but was:<[]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.opennlp.TestChunkerAfterRemovedFirstSentence.testFirstSentenceRemoved(TestChunkerAfterRemovedFirstSentence.java:53)- The POS filter "Tags all terms"; the chunker and lemmatizer only annotate or rewrite terms. None removes tokens, and the chunker only requires an order, not adjacency.
- A removed sentence in the middle is handled correctly; only the starting value 0 is wrong.
- #11734, which added this code, fixed these same filters losing tokens or ending the stream early.
The full argument268 words
- The contracts.
OpenNLPPOSFilter.java:32: "Run OpenNLP POS tagger. Tags all terms in the TypeAttribute."OpenNLPChunkerFilter.java:32-36: "Prerequisite: the OpenNLPTokenizer and OpenNLPPOSFilter must precede this filter. Tags terms in the TypeAttribute, replacing the POS tags previously put there by OpenNLPPOSFilter." The lemmatizer "Runs OpenNLP dictionary-based and/or MaxEnt lemmatizers" (OpenNLPLemmatizerFilter.java:34) and replaces each non-keyword term by its lemma (:73-76). No javadoc, CHANGES or MIGRATE entry, code comment or test restricts which filters may sit between the stages.SentenceAttributeonly "tracks what sentence a given token belongs to" and promises nothing about index 0. - Filters between the stages are expected. The lemmatizer reads
KeywordAttribute(OpenNLPLemmatizerFilter.java:49,:74,:87) so that keyword filters between POS and lemmatizer work. Upstream tests putKeywordRepeatFilterbetween the tokenizer and the POS filter (TestOpenNLPPOSFilterFactory.java:150-160) and between the POS filter and the lemmatizer (TestOpenNLPLemmatizerFilterFactory.java:230-238,:301-308,:323-345). - The asymmetry. A fully removed middle sentence works, because the helper only tests for a change of index; the initial
currSentence = 0is the only assumption that breaks. Losing the whole value is not a trade-off anyone chose. - History. #11734, "Fix repeating token sentence boundary bug", added the helper and fixed the 9.5.0 CHANGES entries GITHUB#11735 "KeywordRepeatFilter + OpenNLPLemmatizer always drops last token of a stream" and GITHUB#11771 "... sometimes arbitrarily exits token stream" (
lucene/CHANGES.txt:3859-3863). Its review did not discuss a first sentence whose index is not 0. - Nothing pins the current output. No upstream test puts a token-removing filter before a sentence-aware filter; with the fix all 33 upstream tests of the module pass.
The devil's-advocate check243 words
The checkers built the strongest case for "unsupported chain": (1) no documented or example chain triggers it; the factory javadoc, the Solr reference guide, the upstream tests and the third-party configurations found keep the OpenNLP stages next to each other and put TypeTokenFilter after the last one; (2) the module overview says the tokenizer keeps punctuation because "This is required for the following taggers to operate properly" (overview.html:32-36), and the Solr reference guide ("OpenNLP Integration") says "the same tokenization using the same models must be used at runtime for optimal performance"; POS tagging and chunking use the sentence as context; (3) the chunker is excluded from the random-chain tests because "other filters must precede this one (see docs)" (OpenNLPChunkerFilter.java:37). So a maintainer could call removing tokens before the POS filter or the chunker unsupported, and lower tag quality there acceptable.
Why it fails: those notes are about tagging quality, not about losing every token, and nothing in them explains ending the stream for the whole value. For the dictionary lemmatizer the quality argument has nothing to hold on to in the repro: with fix A the nouns-only chain gives the same [they, evening] with and without the noun-free first sentence. Nothing restricts in-between filters, upstream tests use them, and the same code handles a removed middle sentence. The cross-model fact check rated the "intended" case moderate before the POS filter and before the chunker, weak before the dictionary lemmatizer.
Recommended A. Adopt the first token's sentence index in SentenceAttributeExtractor
Let the first token of the stream set the current sentence: in SentenceAttributeExtractor.extractSentenceAttributes(), when the look-ahead is still null, take the token's sentence index as currSentence (4 lines). Validated: the 3 new tests pass, as do all 36 module tests and check; streams that start at sentence 0 behave as before.
       hasNextToken = input.incrementToken();
       int currSentenceTmp = sentenceAtt.getSentenceIndex();
+      if (prevAttributeSource == null) {
+        // first token of the stream: its sentence is the current one, whatever its index
+        currSentence = currSentenceTmp;
+      }
       hasNext = (currSentence == currSentenceTmp && hasNextToken);
All options and trade-offs3 options · 567 words
Options A and B were each applied in a scratch worktree of main a9779ef3c193 and run through gradle with assertions on and off; the workaround needs no code change. Indexes built with an affected chain keep the empty fields until the documents are reindexed.
A. Adopt the first token's sentence index in SentenceAttributeExtractor (validated by the checks) (recommended)
In extractSentenceAttributes() (SentenceAttributeExtractor.java:54-58), when prevAttributeSource == null (the first call after reset()), set currSentence to the first token's index before the comparison. This is the finder's fix.
What it changes. Only that first call. Streams whose first token has index 0 behave exactly as before; an empty stream still returns an empty list, so the filters still end it. All three filters, and any other user of the public helper, are fixed at once.
       hasNextToken = input.incrementToken();
       int currSentenceTmp = sentenceAtt.getSentenceIndex();
+      if (prevAttributeSource == null) {
+        // first token of the stream: its sentence is the current one, whatever its index
+        currSentence = currSentenceTmp;
+      }
       hasNext = (currSentence == currSentenceTmp && hasNextToken);
Trade-offs
- The smallest change, at the root cause. Indexed terms change only for values that were losing all their tokens.
- It does not touch the separate lemmatizer bug with sentence-final keyword tokens (a different fix site): in the exhaustive check fix A removes every first-sentence case and that bug's own fix removes the rest (both fixes: 0 of 55,987 lemmatizer cases).
What the checks validated
- The 3 new tests pass with assertions on and off (stock: 3 of 3 fail).
- All of
:lucene:analysis:opennlp:test: 6 classes, 36 tests, 0 failures, assertions on and off (stock: only the 3 new tests fail). :lucene:analysis:opennlp:check -x testpasses (google-java-format, ecjLint, forbiddenApis, licenses).- Through the repro harness with the fix shadowed: the new test 3 of 3, the finder's test 3 of 3, the independent reproducer's 5 of 5 and a separate verification test pass.
- The hunt's exhaustive check: no first-sentence case left (728 POS, 728 chunker and 37,324 per lemmatizer variant before).
In OpenNLPPOSFilter, OpenNLPChunkerFilter and OpenNLPLemmatizerFilter, replace allSentencesProcessed() || nextSentence().isEmpty() by a loop that ends the stream only when allSentencesProcessed() is true and otherwise reads the next sentence while it is empty (do { if (allSentencesProcessed()) return false; } while (nextSentence().isEmpty());).
Trade-offs
Three call sites instead of one, and every other consumer of the helper must do the same; the helper still returns a misleading empty first sentence. It also retries after other empty batches, but each filter first runs its OpenNLP operation on the empty arrays (OpenNLPPOSFilter.java:70-71, OpenNLPChunkerFilter.java:76-77, OpenNLPLemmatizerFilter.java:94-96); that was validated only for the demonstrated case, with the bundled OpenNLP version. A and B can be combined; A alone covers every case found.
What the checks validated
- The 3 new tests pass with assertions on and off.
- All of
:lucene:analysis:opennlp:test: 6 classes, 36 tests, 0 failures, assertions on and off. - Not run through
checkor the exhaustive harness.
For example tokenizer, POS, lemmatizer, then TypeTokenFilter or StopFilter: the order the documented examples use. No code change.
Trade-offs
Not always possible: the chunker replaces the POS tags with chunk tags, so a POS-based TypeTokenFilter cannot simply move after it. Existing documents still need reindexing.
Downstream, a keyword screen or a content-based deny rule over such a field misses a document whose text starts with a sentence the chain removes: MUST_NOT body:evening left the example document visible (executed through Lucene's own query API; not run on a downstream product).
While building an independent reference that calls the OpenNLP library one sentence at a time, the finder suspected the helper's starting index. A bounded-exhaustive check of the real filters then confirmed it: every sentence-index pattern up to 6 tokens, and every case whose first token was not in sentence 0 gave empty output.
The method in full197 words
- Method (semi-formal): bounded-exhaustive translation validation of the stock main jar, in the hunt's unit on the OpenNLP filters against the OpenNLP library. The finder built an independent per-sentence reference that calls the OpenNLP operations directly, and formed the hypothesis by reading
SentenceAttributeExtractorwhile doing so. - Enumeration. Every sentence-index sequence over {0, 1, 2}^n for n <= 6 (and every keyword pattern for the lemmatizer): 1,093 cases each for POS and chunker, 55,987 per lemmatizer variant. Every case whose first token had a sentence index other than 0 gave empty output: 728 for POS, 728 for the chunker, 37,324 per lemmatizer variant, 0 unexplained; with fix A, 0. These count a diagnostic model space that also enumerates gaps and non-monotone index sequences the tokenizer does not emit; they say nothing about how often real text triggers the bug.
- Real text. A differential run of 404 generated documents through the tokenizer and 10 chains, with the library called directly as the reference, showed the same defect (the POS stage of tokenizer,
StopFilter, POS differed for 17 of 404 documents); with both of the unit's fixes shadowed, 0 mismatches. - Then a public-API JUnit; independent checkers followed (see "Independent checks").
No prior report found (searched 2026-10-26: 298 queries over GitHub issues, PRs, commits and code, all 407 open PRs, JIRA, the Lucene and Solr lists and the web). Closest: #11735 and #11771, the pre-9.5 token losses that the change introducing this bug fixed.
Searches6 searches
23 plausible hits were read; none describes this bug. Keyword search only; StackOverflow seen only through titles and snippets; the dev@ "opennlp" mails reviewed by subject from 2022-09 on; private reports cannot be seen.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search | 2026-10-26 | 173 queries: GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA, the web (plus the finder's earlier run of 51 queries) | no report; 1 high and 16 medium hits, none this bug |
| GitHub (manual) | 2026-10-26 | 14 searches: all of GitHub for the three filter names and SentenceAttributeExtractor, apache/solr, apache/lucene items since 2022-09, code search for extractSentenceAttributes; the file lists of all 407 open apache/lucene PRs | no report; only #16911 (branch_10x decommission) touches the files |
| JIRA (LUCENE, SOLR, OPENNLP) | 2026-10-26 | REST searches for OpenNLP and Lucene items | nothing about sentence-aware filters losing tokens |
| Mailing lists | 2026-10-26 | 30 manual queries; subjects of every "opennlp" mail since 2022-09 on the Lucene and Solr lists; 3 threads read | only the #11734/#11735/#11771 threads and a thread-safety discussion |
| Web | 2026-10-26 | 15 searches, 3 page fetches | no relevant hit |
| Closest items (read) | 2026-10-26 | full threads | #11734 / #11802 (introduced the code; review did not discuss this case), #11735 and #11771 (pre-9.5 trigger and root cause), #14194 / #14188 (POS tag format), #11955 (thread safety), #3973 (LUCENE-2899, the module's original issue) |
Introduced in 9.5.0 by #11734 (3a04aa44c22, 2022-09-23; branch_9x b253e4353f0), which added the helper while fixing older token losses. Fails on all 26 releases from 9.5.0 to 10.5.2 and on main; passes on 12 releases from 7.3.0 to 9.4.2. Not fixed upstream.
Versions tested6 rows
Introduced by apache/lucene#11734, "Fix repeating token sentence boundary bug" (author kotman12): main 3a04aa44c22 (2022-09-23) and the branch_9x backport b253e4353f0 (2022-09-24, after a first backport b79edbb54ac was reverted the same day by 64b124349ba; the class is identical in all three). It replaced the old end-of-sentence flag with a sentence index per token, added SentenceAttributeExtractor with currSentence = 0, and moved the three filters onto it with the nextSentence().isEmpty() end-of-stream check. git blame on main attributes every line of the class and the conditions of the three checks to it (the return false; lines below them are older).
Older releases have the mirror bug. They lose tokens when the last sentence is removed (the end-of-sentence-flag logic that #11734 replaced); that is a different root cause. Executed on 7.3.0, 8.11.4 and 9.4.2; inferred for the releases in between, which have the same filter code.
What was executed. Each release ran on its own jars and its own release-tag test models, except 8.11.4 (the 8.8.1 test models: the local history clone has no 8.9+ tags). Of 7.3.0 to 9.4.2, 12 selected releases ran; 7.3.1, 7.4.0 to 7.7.2 and the 8.x releases other than 8.0.0, 8.8.1 and 8.11.4 did not, and their filter code matches 7.3.0 and 9.4.2 apart from formatting, javadoc and annotations (read).
Not fixed upstream. On upstream main a95c754ee00 (2026-10-26), branch_10x and branch_10_6 the last change to SentenceAttributeExtractor.java is still 3a04aa44c22, and on upstream main c5ab3e57b9b (2026-10-28) the file is byte-identical to a9779ef3c193 (read, not executed), so 10.6.0 (released 2026-10-29) and the unreleased lines are affected too.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | new test 3 of 3 fail through gradle (assertions on and off); history test fails |
| 10.0.0 to 10.5.2 (12 releases) | affected | history test fails on every one; the finder's and the reproducer's JUnit fail on 10.5.2 |
| 9.5.0 to 9.12.3 (14 releases) | affected | history test fails on every one; the finder's and the reproducer's JUnit fail on 9.5.0 and 9.12.3 |
| 7.3.0 to 9.4.2 (12 releases executed) | not affected | history test passes on the 12 executed releases (the others read: same filter code); 7.3.0, 8.11.4 and 9.4.2 lose tokens in the mirror case instead (last sentence removed) |
| 9.4.2 jars + #11734 classes / 9.5.0 jars minus #11734 | commit A/B | fails / passes: the change between the two releases is #11734 alone |
fix A on main a9779ef3c193 | not affected | 3 new tests and all 36 module tests pass; the exhaustive check finds no such case |
An independent reproducer (own test, different trigger), a works-as-designed review by a reviewer from another model family, an intended-behaviour devil's advocate, an adjudication and a credibility audit all judged it real and re-ran it on main. A read-only refute review said "not real" only because it could not run code.
Checks and verdicts475 words
Every verdict below that re-ran a repro did so on main a9779ef3c193; the cross-model reviews could only read code. This doc's own fix validation ran on a9779ef3c193 through gradle.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model refute review | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: it could run no command, so it could not vote real; its notes call this "not a substantive refutation". It agreed with the root cause and found the inputs within the contract (8 evidence items for real, 1 against). |
| Works-as-designed review | real (medium) | The same reviewer with an intended-behaviour lens, reading only: the "intended" argument is weak. A separate a separate verification test derived from that review (StopFilter {it, is, the, a, .} then POS on The. They sent him running in the evening. The dog barked.: 8 tokens without the POS filter, 0 with it) fails on main and passes with the fix. |
| Independent reproducer | real (high) | Own public-API test with a different trigger (StopFilter {hi, .}) and a model-free oracle: 4 of 5 fail on main (assertions on and off), 10.5.2, 9.12.3 and 9.5.0, controls pass; 5 of 5 pass with the fix. Found the final offset of 1024 instead of 1504. |
| Intended-behaviour devil's advocate | real (high) | No "intended" or "misuse" argument survives; the overview's punctuation note concerns tagging quality. Its probe of 9 adversarial inputs found no input for which the tokenizer alone starts at a sentence other than 0. |
| Adjudication | confirmed (high) | Re-ran the reproducer's test on main: 4 of 5 fail with assertions on and off, 5 of 5 pass with the fix. |
| Credibility audit | keep | Re-ran the finder's test on main with a new seed: 3 of 3 fail with assertions on and off, 3 of 3 pass with the fix; score kept. |
| Fix validation (this doc) | fix A and fix B pass | Gradle in a scratch worktree of a9779ef3c193: stock, the 3 new tests fail and the 33 upstream tests pass; with fix A or fix B all 36 pass, assertions on and off; check -x test passes with fix A. |
| Fact checks of this doc | pass after corrections | Independent fact checks of this doc and its brief. One re-ran the test (3 of 3 fail on main, assertions on and off; 3 of 3 also on 10.5.2 and 9.5.0 with their own test models), both fixes, and every cited line and count: no error. The reviewer from the other model family, reading only (with command outputs prepared beforehand), found the bug, its cause and its fixes sound and asked for precision fixes (the final offset is not always 1024, the plain chain is probed rather than proven safe, which releases were executed); they are applied here. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 460 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,575 words
- Registry title
- OpenNLP POS, chunker and lemmatizer filters emit no token for a whole field value when an earlier filter removes every token of its first sentence, because SentenceAttributeExtractor starts at sentence index 0 and reads a first token from sentence 1 as an empty sentence, which the filters take as the end of the stream
- Area
- analysis-opennlp / sentence-aware filters (SentenceAttributeExtractor.extractSentenceAttributes, shared by OpenNLPPOSFilter, OpenNLPChunkerFilter and OpenNLPLemmatizerFilter; factories opennlpPOS, opennlpChunker, opennlplemmatizer)
- Priority
- Low, rank 483: A whole field value silently indexes no terms, which is severe, but only under an OpenNLP chain that removes tokens before a sentence-aware filter, a setup no documented example or known configuration uses.
- Impact class
- silent wrong results
- Impact note
- Hits only applications that use the opt-in analysis-opennlp module with a chain that puts a token-removing filter (StopFilter, LengthFilter or a TypeTokenFilter on POS tags, all executed) before an OpenNLP POS, chunker or lemmatizer filter, a legal chain that the documented examples and upstream tests do not use; for them every field value whose first sentence that filter empties completely, punctuation included (a short opener such as 'Hi.' or 'No.', or under a nouns-only filter any first sentence without a noun), silently indexes no terms at all while its stored text stays intact, deterministically, with -ea and -da, at any size, in every release from 9.5.0 to 10.6.0 (10.6.0 by reading) and main; values longer than 1024 chars also end with a wrong final offset (1024), which shifts the offsets of later values of a multi-valued field; chains with the OpenNLP stages directly after each other are not affected.
- Summary
- You build an OpenNLP chain that removes some tokens before a sentence-aware filter, for example tokenizer -> POS tagger -> TypeTokenFilter keeping only nouns -> lemmatizer, and analyze 'He did not come back. They sent him running in the evening.', expecting the lemmatized nouns of the second sentence, [they, evening], as you get for that sentence alone. Instead the whole value yields no token: SentenceAttributeExtractor starts with currSentence = 0, so when the first token it receives already belongs to sentence 1 it returns an empty first sentence, and the POS, chunker and lemmatizer filters all treat an empty sentence as the end of the stream. A fully removed sentence in the middle of the text is handled correctly; only the first one is not.
- Introduced
- 3a04aa44c22aad7c63f806b436a79515285c6ea9 on main ('Fix repeating token sentence boundary bug (#11734)', apache/lucene#11734 by kotman12, co-authored and merged by dweiss), which added SentenceAttributeExtractor with 'private int currSentence = 0;' (line 40, and 'currSentence = 0;' in reset() at line 78) and moved the three filters onto it with the nextSentence().isEmpty() end-of-stream check; the 9.x line got it through the branch_9x backport b253e4353f091dc53d2167985ba09fd40954d0c3 (an earlier backport b79edbb54ac was reverted the same day by 64b124349ba and re-applied as b253e4353f0; the class is identical in all three). A regression introduced by a fix: #11734 fixed GITHUB#11735 and #11771 (tokens lost when the last token of a sentence was repeated or removed). [read: git log --follow and git blame on main attribute every line of the class and the three end-of-stream checks to 3a04aa44c22; the file is byte-identical in 3a04aa44c22, 9.5.0, 9.12.3, 10.0.0, 10.5.2 and main. exec: commit-level A/B without a gradle build, shadowing the #11734 files over the 9.4.2 jars makes 9.4.2 fail like 9.5.0, and shadowing the pre-#11734 files of its parent 8f41b3fe853 over the 9.5.0 jars makes 9.5.0 pass like 9.4.2] (2022-09-23 (main, 3a04aa44c22, PR merged 10:59:46Z); 2022-09-24 (branch_9x backport b253e4353f0); first release 9.5.0, tagged 2023-01-30)
- First affected version
- 9.5.0 [exec: the follow-up's history test fails 3 of 3 with -ea and -da]; last unaffected: 9.4.2 [exec: passes 3 of 3 with -ea and -da]. 7.3.0 (the module's first release, LUCENE-2899) to 9.4.2 used the older end-of-sentence-flag logic and do not have this bug [exec on 12 releases]; they lose tokens in the mirror case instead (the last sentence removed), a different root cause that #11734 fixed
- Affected versions
- Every release from 9.5.0 through 10.6.0 (9.5.0-9.12.3 and 10.0.0-10.5.2, 26 releases, and 10.6.0 by reading) and main a9779ef3c193; never fixed. [exec] the follow-up's history test (oracle: chain(FIRST + ' ' + SECOND) equals chain(SECOND) in terms and types, with its preconditions asserted) fails 3 of 3 on all 26 releases, each with its own jars and its own release-tag test models (-ea; 9.5.0 also -da), and on main (-ea and -da); it passes on 7.3.0, 7.7.3, 8.0.0, 8.8.1, 8.11.4, 9.0.0, 9.1.0, 9.2.0, 9.3.0, 9.4.0, 9.4.1 and 9.4.2 and on main with the fix shadowed. The finder's JUnit fails 3 of 3 on main (-ea and -da), 10.5.2, 9.12.3 and 9.5.0 (it also fails on 9.4.2, but only through the older trailing-removal mechanism, because its inputs end with a removed '.'); the independent reproduction's JUnit fails 4 of 5 on main (-ea and -da), 10.5.2, 9.12.3 and 9.5.0 and fails differently on 9.4.2. [read] on upstream main (a95c754ee00, 2026-10-26), branch_10x and branch_10_6 the last change to SentenceAttributeExtractor.java is still 3a04aa44c22, so 10.6.0 (released 2026-10-29) and the unreleased 11.0 line are affected (branch heads not executed); the 7 commits ea57360912ed..a9779ef3c193 do not touch lucene/analysis/opennlp. Not executed: x86 (pure Java logic). JDK 25.0.3, aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (2026-10-26, read-only). Follow-up prior-art step (verdict new: 298 logged query records, including the finder's scripted prior-report search of 51 queries, and 23 hits read, none the same bug): a scripted prior-report search over apache/lucene issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web (163 live queries plus a cached run with 10 ingested web queries); 14 manual GitHub searches (all of GitHub for the three filter names and SentenceAttributeExtractor, apache/solr, apache/lucene items since 2022-09, code search for extractSentenceAttributes); the file lists of all 407 open apache/lucene PRs; upstream commit history and CHANGES.txt; LUCENE, SOLR and OPENNLP JIRA; 30 manual mailing-list queries with 3 threads read; 15 web searches. Closest items, not this bug: #11734 and its duplicate #11802 (the change that introduced the code; the review asked for a run over a larger text base and nobody discussed a first sentence whose index is not 0), #11735 and #11771 (KeywordRepeatFilter plus the lemmatizer dropping the last token or exiting early: same symptom family, but a different trigger and the pre-9.5 root cause that #11734 fixed). Not fixed upstream: SentenceAttributeExtractor.java is unchanged since 3a04aa44c22 on main (a95c754ee00), branch_10x and branch_10_6, and no open PR changes it or the filters' sentence loop (only #16911, the branch_10x decommission, touches the files, by deleting every file). Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree: the new 3-test class with assertions on and off (stock: 3 of 3 fail; fix A and fix B: 0), all 36 tests of:lucene:analysis:opennlp:test(stock: only the 3 new tests fail; fix A and fix B: 0), and:lucene:analysis:opennlp:check -x testwith fix A; the worktree was removed afterwards. The same class through the repro harness on main (-ea,-da; 0 failures with fix A shadowed). The finder's and the independent reproducer's tests on main, 10.5.2, 9.12.3 and 9.5.0; the follow-up's history test on all 26 releases from 9.5.0 to 10.5.2 (fail), 12 releases from 7.3.0 to 9.4.2 (pass) and main. JDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/SentenceAttributeExtractor.java:40 (at a9779ef3c193) ('private int currSentence = 0;'), :51-65 (extractSentenceAttributes: compare with currSentence, add the previous look-ahead, store the new one), :75-80 (reset() sets currSentence = 0 and clears the look-ahead)lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPPOSFilter.java:32 (at a9779ef3c193) (javadoc 'Run OpenNLP POS tagger. Tags all terms in the TypeAttribute.'), :48-60 (incrementToken returns false when nextSentence() is empty)lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPChunkerFilter.java:33-35 (at a9779ef3c193) (javadoc: 'the OpenNLPTokenizer and OpenNLPPOSFilter must precede this filter. Tags terms in the TypeAttribute'), :50-64 (same end-of-stream check)lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPLemmatizerFilter.java:62-71 (at a9779ef3c193) (same end-of-stream check)lucene/analysis/opennlp/src/java/overview.html:33-36 (at a9779ef3c193) (punctuation is tokenized, 'required for the following taggers to operate properly')lucene/analysis/opennlp/src/test/org/apache/lucene/analysis/opennlp/TestOpenNLPPOSFilterFactory.java:150-160 (at a9779ef3c193) (testNoBreakWithRepeatKeywordFilter: KeywordRepeatFilter between the tokenizer and the POS filter); lucene/analysis/opennlp/src/test/org/apache/lucene/analysis/opennlp/TestOpenNLPLemmatizerFilterFactory.java:323 (testPreventEarlyExit)lucene/CHANGES.txt:3682 (at a9779ef3c193) (Lucene 9.5.0 section), :3859-3863 (GITHUB#11735 and GITHUB#11771, both fixed by #11734)lucene/analysis/common/src/java/org/apache/lucene/analysis/util/SegmentingTokenizerBase.java:39 (at a9779ef3c193) (BUFFERMAX = 1024: why a blanked long value ends with finalOffset 1024)
- The finding in 30 seconds
lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/SentenceAttributeExtractor.java:40, :51-65, :75-80 @ a9779ef3c193lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPPOSFilter.java:47-61; lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPChunkerFilter.java:50-64; lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPLemmatizerFilter.java:62-78 @ a9779ef3c193lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPTokenizer.java:31-34, :45, :73, :87, :97 @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/util/SegmentingTokenizerBase.java:39, :119-122 @ a9779ef3c193
- Why it looks unintended
lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPPOSFilter.java:32; lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPChunkerFilter.java:32-36, :37; lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPLemmatizerFilter.java:34, :49, :73-76, :87 @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/SentenceAttribute.java:22-25 @ a9779ef3c193lucene/analysis/opennlp/src/test/org/apache/lucene/analysis/opennlp/TestOpenNLPPOSFilterFactory.java:150-160; lucene/analysis/opennlp/src/test/org/apache/lucene/analysis/opennlp/TestOpenNLPLemmatizerFilterFactory.java:230-238, :301-308, :323-345 @ a9779ef3c193lucene/CHANGES.txt:3682 (Lucene 9.5.0), :3859-3863 (GITHUB#11735, GITHUB#11771) @ a9779ef3c193lucene/analysis/opennlp/src/java/overview.html:32-36 @ a9779ef3c193
- Suggested fix
lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/SentenceAttributeExtractor.java:51-65; lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPPOSFilter.java:52-56; lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPChunkerFilter.java:55-59; lucene/analysis/opennlp/src/java/org/apache/lucene/analysis/opennlp/OpenNLPLemmatizerFilter.java:66-70 @ a9779ef3c193
- TestChunkerAfterRemovedFirstSentence.java (JUnit test):
repro/LFV-621/src/org/apache/lucene/analysis/opennlp/TestChunkerAfterRemovedFirstSentence.java(55 lines)
assets/LFV-621/bug.png(460 KB)