A Hunspell affix rule can carry a continuation class: PFX U 0 kilo/S means "after kilo-, the suffix S is allowed too". Lucene's spell-checker honours this; its word-form generator does not, so a prefix plus a suffix that only the prefix allows is silently left out.
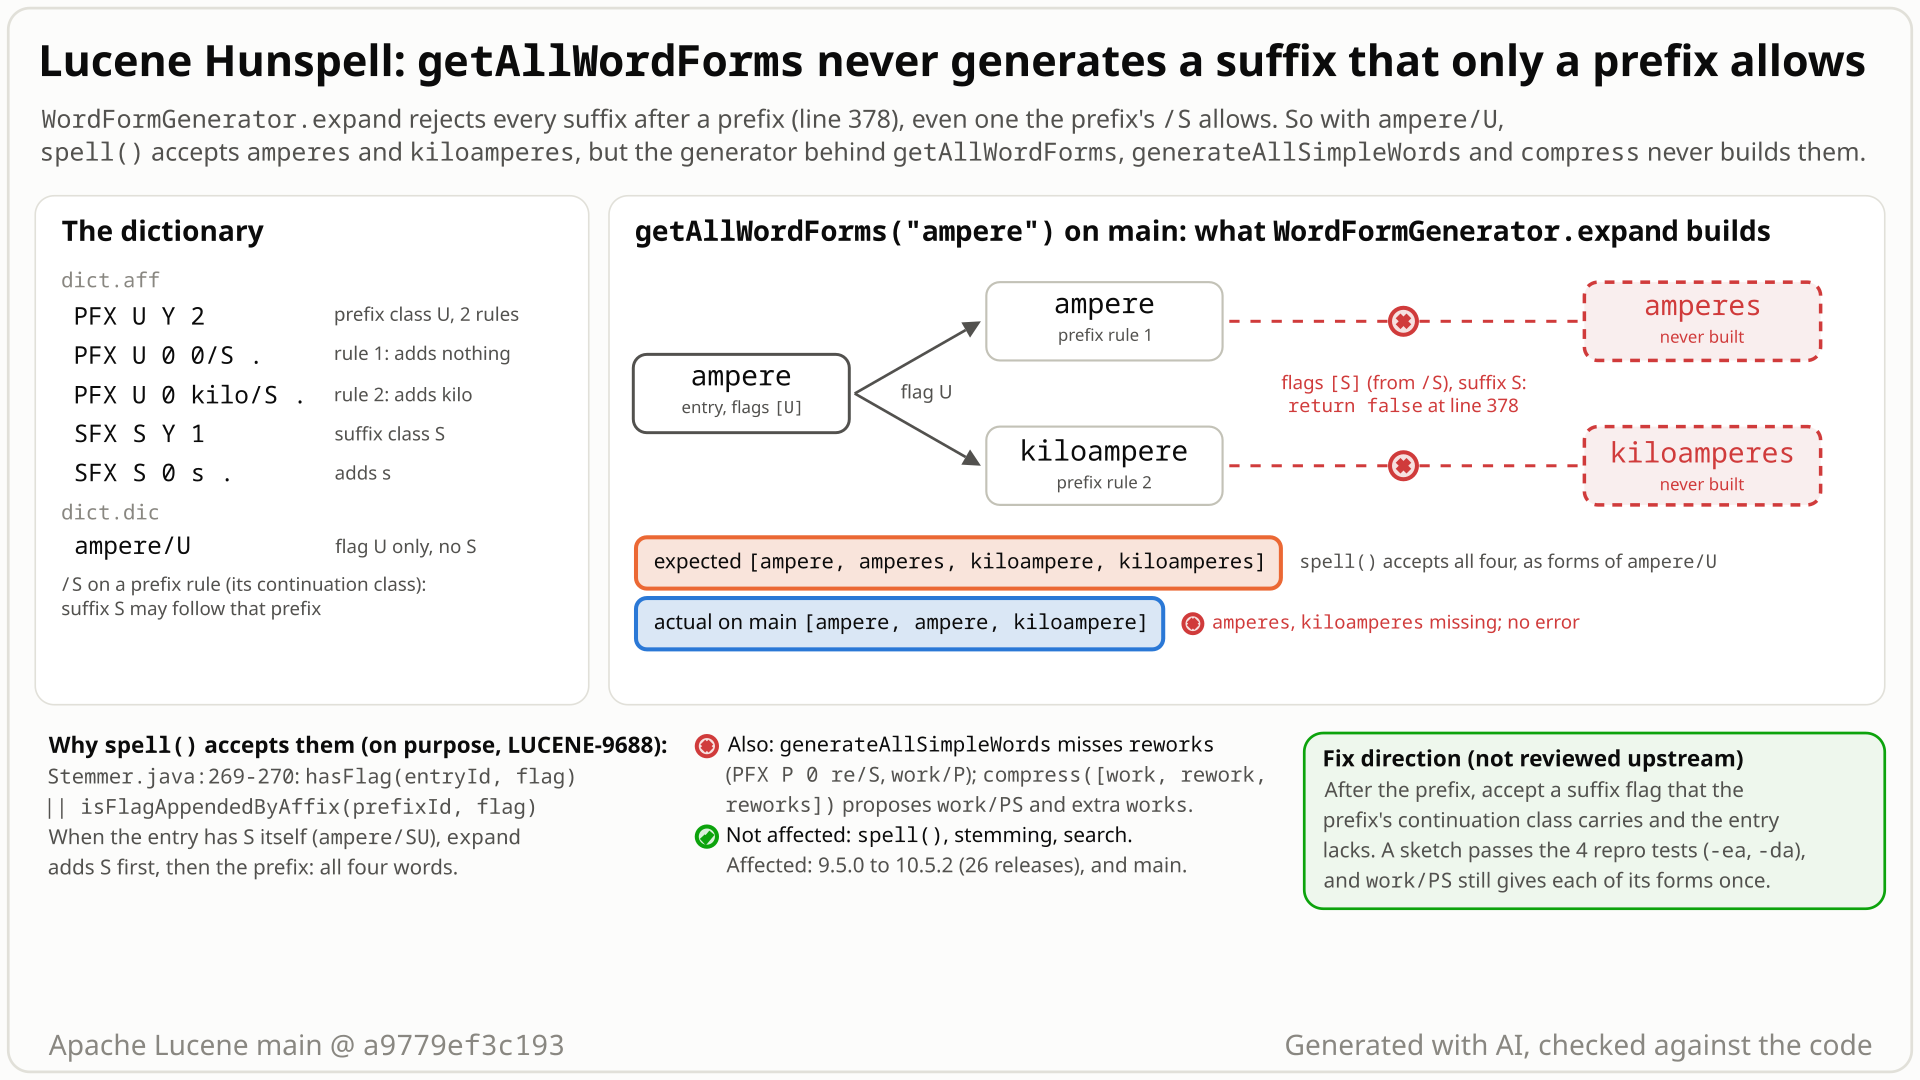
ampere/U dictionary: spell() accepts four words, but getAllWordForms("ampere") yields only two of them, because a suffix after a prefix is rejected at WordFormGenerator.java:378. Select the still to open it at full size. Generated with AI, checked against the code.- You load a dictionary with two prefix rules,
PFX U 0 0/S .andPFX U 0 kilo/S ., the plural ruleSFX S 0 s .and the entryampere/U. The/Son a prefix rule means: after this prefix, the plural is allowed too. The entry itself has noS. - You expect
getAllWordForms("ampere")=[ampere, amperes, kiloampere, kiloamperes]: Lucene'sspell()accepts all four,analyzeSimpleWord()analyses each as a form ofampere/U, and C Hunspell 1.7.2 agrees. - Instead you get only the words
ampereandkiloampere(the raw list is[ampere, ampere, kiloampere]; the empty prefix rebuildsampere). After a prefix the generator recurses with the prefix'sS, butWordFormGenerator.java:378rejects every suffix once a prefix is applied, so thatSis never used; only a suffix flag on the entry itself can combine with a prefix (suffix first). - No error.
generateAllSimpleWordsmisses the same words, and forwork/PwithPFX P 0 re/Scompress([work, rework, reworks])proposeswork/PS, an edit that also addsworks, a word the dictionary rejects. - Real dictionary: in the current French dictionary
getAllWordForms("ampère")returns 29 singular forms and none of the 25 pluralsspell()accepts. Over the whole dictionary a fix adds 833 forms, all accepted byspell(), and removes none.
Only callers of the opt-in Hunspell dictionary-tooling API (getAllWordForms, generateAllSimpleWords, compress, NGramFragmentChecker.fromAllSimpleWords) with a dictionary whose prefix rules enable suffixes, such as the French unit prefixes. Word lists come back incomplete and compress suggests needless edits. Spell-checking, stemming and search are not affected.
Mechanism, terms and numbers718 words
Hunspell lets a prefix rule enable a suffix through its continuation class: with PFX U 0 kilo/S ., SFX S 0 s . and the entry ampere/U, the dictionary defines ampere, amperes, kiloampere and kiloamperes, although the entry has no S. Lucene's spell-checker has accepted this since LUCENE-9688 (2021), and C Hunspell 1.7.2 accepts all four words. Lucene's word-form generator (Hunspell.getAllWordForms, WordFormGenerator.getAllWordForms, generateAllSimpleWords, compress, and through them NGramFragmentChecker.fromAllSimpleWords) never produces these forms: getAllWordForms("ampere") yields only the words ampere and kiloampere. After a prefix it recurses with the prefix's continuation flags, but the guard if (!isPrefix && !stem.getPrefixes().isEmpty()) return false; (WordFormGenerator.java:378 on main a9779ef3c193) rejects every suffix once a prefix is applied, so a prefix-plus-suffix form is built only suffix first, from a suffix flag the entry itself carries. No error is raised, and compress proposes needless edits that over-generate. In the current French dictionary getAllWordForms("ampère") returns 29 singular forms and none of the 25 plurals; over the whole dictionary a fix adds 833 forms, all accepted by spell(). Every release from 9.5.0 through 10.6.0 (10.6.0 by reading) and main is affected. Spell-checking, stemming, HunspellStemFilter, indexing and search do not use this code.
- Entry: a line of the
.dicfile.ampere/Uhas the stemampereand the flagU. - Affix rule:
SFX S 0 s .says that entries with flagStake the suffixs(amperes);PFX U 0 kilo .adds the prefixkilo. - Continuation class: the flags an affix gives to the word it creates.
PFX U 0 kilo/S .givesStokiloampere, sokiloamperesis a word even thoughampere/Uhas noS. hunspell(5): "affix (optionally with flags of continuation classes, separated by a slash)".
expand(WordFormGenerator.java:233-259) walks the entry's flags. For each affix it checksisCompatibleWithPreviousAffixes(:240), applies it, keeps the word if stemming it reaches a stem with the entry's stem text and no forbidden word (canStemToOriginal,:184-217; it compares the stem string only, not the entry's flags), and recurses withupdateFlags(flags, flag, append)(:251-252): the applied flag removed, the affix's continuation flags added.isCompatibleWithPreviousAffixes(:372-383), line 378:if (!isPrefix && !stem.getPrefixes().isEmpty()) return false;. No suffix after a prefix, which fixes the order: suffixes first, prefixes second.- For
ampere/Uthe flags are[U]. Applyingkilogiveskiloampereand recurses with[S], the prefix's continuation.Sis a suffix, a prefix is present, and line 378 rejects it:kiloamperesis never built. The empty prefix (PFX U 0 0/S) losesamperesthe same way. - The other cases work. If the entry has
S(work/PS),Sis applied first andPsecond, and the guard only prevents buildingreworkstwice. In the mirror case, a suffix whose continuation allows a prefix (SFX S 0 s/P,work/S), a prefix after a suffix is allowed, soreworksis generated. - The spell-checker accepts this exact path on purpose:
Stemmer.java:269-270,dictionary.hasFlag(entryId, flag) || dictionary.isFlagAppendedByAffix(prefixId, flag)(LUCENE-9688).
| call (distinct words) | expected | main a9779ef3c193 |
|---|---|---|
getAllWordForms("ampere") (ampere/U) | [ampere, amperes, kiloampere, kiloamperes] | [ampere, kiloampere] |
getAllWordForms("work") (work/P, PFX P 0 re/S) | [rework, reworks, work] | [rework, work] |
generateAllSimpleWords (work/P) | work, rework, reworks | work, rework |
compress([work, rework, reworks]) | toEdit=[work/P], extra=[] | toEdit=[work/PS], extra=[works] |
getAllWordForms("book") (a zero-length prefix: book/Z, PFX Z 0 0/S) | [book, books] | [book] |
Lucene's fixture dependencies (calorie/p, PFX p 0 0/s) | [calorie, calories] | [calorie] |
The raw lists repeat a word: getAllWordForms("ampere") is [ampere, ampere, kiloampere] on main, because the empty prefix PFX U 0 0/S rebuilds ampere (likewise book and calorie). The table shows distinct words, as the repro compares them.
French dictionary (LibreOffice 4f1df64b2e8e): 29 unit-prefix rules PFX Um, 25 of them with continuation S. (the plural), on 35 entries such as ampère/Um. getAllWordForms("ampère") gives 29 distinct words on main, all singular, and 54 with the fix (plus ampères, kiloampères, d'ampères and 22 more). generateAllSimpleWords: 3,063,236 distinct words on main, 3,064,069 with the fix (+833, none removed); the number spell() rejects is 19,484 in both, so every added word is accepted.
Exposure and likelihood263 words
- Who is hit. Callers of
Hunspell.getAllWordFormsandcompress, bothWordFormGenerator.getAllWordFormsoverloads,generateAllSimpleWordsandcompress, andNGramFragmentChecker.fromAllSimpleWords. The API exists "to aid dictionary editing" (LUCENE-10626): listing a dictionary's words, minimising entries, building fragment checkers. No setting is involved; which forms go missing depends only on the dictionary, deterministically. - The trigger. A valid dictionary with a
PFXrule whose continuation class carries anSFXflag the entry lacks. Lucene's owndependencies.affhas it (PFX p 0 0/s .). The current French dictionary has it on 35 unit entries: 833 missing forms, 25 of them forampère. The finder's static survey reports the shape in 16 of 191 public.afffiles (French, Danish,de_*_frami, Armenian, Bengali, Kinyarwanda); their 3,000-root samples changed only French, not da_DK, de_DE_frami, lb, nb_NO or sv_SE (not re-checked). - What goes wrong. Incomplete
getAllWordFormsandgenerateAllSimpleWordsoutput, with no error.compressproposes edits the dictionary does not need (ampere/SUfor wordsampere/Ualready covers;work/PSforwork/P), and thework/PSedit addsworks, which it lists ingetExtraGeneratedWords(). A fragment checker fromfromAllSimpleWordslacks n-grams that only the missing forms have: in the hunt's probe it flaggedamperesandkiloamperesas containing an impossible fragment. That checker is opt-in (Suggester.withFragmentChecker;Hunspell.suggestdoes not use one), and no changed suggestion was seen in the probe's 8 misspellings. - Not affected.
spell(),analyzeSimpleWord(), the Stemmer,HunspellStemFilter, indexing and search: they do not call the generator, and the hunt's probe found the same stems and hits with and without a fix.
The test shows that Hunspell getAllWordForms never generates a suffix that only a prefix's continuation class allows (PFX U 0 kilo/S, SFX S 0 s, entry ampere/U), although spell("kiloamperes") accepts it.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.hunspell;

import java.io.ByteArrayInputStream;
import java.nio.charset.StandardCharsets;
import java.util.List;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestWordFormsPrefixEnabledSuffix extends LuceneTestCase {

  public void testSuffixEnabledByPrefixIsGenerated() throws Exception {
    String aff = "PFX U Y 1\nPFX U 0 kilo/S .\nSFX S Y 1\nSFX S 0 s .\n";
    Dictionary dictionary =
        new Dictionary(
            new ByteBuffersDirectory(),
            "dict",
            new ByteArrayInputStream(aff.getBytes(StandardCharsets.UTF_8)),
            new ByteArrayInputStream("1\nampere/U\n".getBytes(StandardCharsets.UTF_8)));
    List<String> forms =
        new Hunspell(dictionary)
            .getAllWordForms("ampere").stream().map(AffixedWord::getWord).sorted().toList();
    // expected kiloamperes too (the prefix kilo/S allows the suffix s); actual [ampere, kiloampere]
    assertEquals(List.of("ampere", "kiloampere", "kiloamperes"), forms);
  }
}
# in a copy of this finding's repro folder (repro/LFV-634/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.hunspell.TestWordFormsPrefixEnabledSuffix
- Expected vs actual
- Expected
[ampere, kiloampere, kiloamperes]; actual[ampere, kiloampere], with-eaand-da.
More files, environment, full output37 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[ampere, kiloampere, kiloamperes]> but was:<[ampere, kiloampere]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.hunspell.TestWordFormsPrefixEnabledSuffix.testSuffixEnabledByPrefixIsGenerated(TestWordFormsPrefixEnabledSuffix.java:39)- The javadoc promises "all word forms", and Lucene's test oracle
checkGoodSugWordsAreGeneratedrequires every accepted word to be generated. - The Stemmer accepts these words on purpose since LUCENE-9688 (2021), and so does C Hunspell 1.7.2.
- The mirror case (a suffix that allows a prefix) is generated; the prefix-first path is not, and nothing excludes it.
The full argument275 words
- The contract.
getAllWordForms: "Generate all word forms for all dictionary entries with the given root word" (WordFormGenerator.java:117-119,Hunspell.java:334-336).generateAllSimpleWords(:294-298) names only compounds and case variants as excluded.NGramFragmentChecker.fromAllSimpleWordsderives "all word forms (using WordFormGenerator) ... to get all words acceptable by the spellchecker" and names only compounds as a limitation (NGramFragmentChecker.java:76-81). - Lucene's test oracle.
TestSpellChecking.checkGoodSugWordsAreGenerated(TestSpellChecking.java:357-376, called at:324-327) asserts, for every fixture whose.dicit can expand whole and whose dictionary needs no input cleaning, that every lowercase.good/.sugword thatanalyzeSimpleWordaccepts is generated;amperesandreworkswould meet those conditions if such a fixture listed them. No fixture it runs on has aPFXrule whose continuation carries anSFXflag;dependencies.aff(:24-25), which does, is used only byTestDependencies. The same check runs inTestHunspellRepositoryTestCaseson the C Hunspell test fixtures (when configured), and none of the 131 C Hunspell 1.7.2 test.afffiles has the shape either. - Deliberate support elsewhere. LUCENE-9688 (#10727, PR apache/lucene-solr#2229,
0a1a3f4c409, 2021-01-22; backported to 8.x and first released in 8.9.0), "Hunspell: consider prefix's continuation flags when applying suffix", made the Stemmer accept exactly this pattern;TestDependencies.java:42-43asserts thatcaloriesstems tocalorie. - The reference implementation. C Hunspell checks a "conditional suffix (enabled by prefix)" (
affentry.cxx:673, 1.7.2) and acceptsamperes,kiloamperes,reworksandbooks, and rejectskiloandworks. - History. The guard came with the generator in #975, without a comment; the PR's 3 conversation and 19 inline review comments and #11904, which moved the line unchanged, never mention prefix continuation classes.
The devil's-advocate check236 words
The case for "intended": the javadoc says getAllWordForms "is equivalent to "unmunch" from the "hunspell-tools" package", and C unmunch does not produce amperes either; line 378 looks like a deliberate canonical order (suffix first, prefix second) that avoids building each prefix+suffix form twice; and the same author wrote LUCENE-9688, so they knew the pattern. Read that way, the generator is a bounded enumerator in one canonical order, not a complete one.
Why it fails: C unmunch 1.7.2 has no continuation-class support at all; on this dictionary it prints ampere, 0/S|ampere and kilo/S|ampere, pasting the raw rule text onto the root. Lucene's generator already goes beyond it (kiloampere, twofold suffixes, suffix-enabled prefixes), so "equivalent" names the tool's purpose, not its limits. The canonical-order argument holds only when the entry carries the suffix flag; without it there is no suffix-first path, so the form is not deduplicated but lost. When the guard was written (d537013e708), the generator also collected forms in a LinkedHashSet<AffixedWord>, so a second copy would not have reached the output then; #11904 switched to lists for speed. The "bounded enumerator" reading conflicts with the method contracts ("all word forms"). Two executed reviews by a model from another family rated the intended-behaviour argument weak, as did the cross-model fact check of this doc, and an intended-behaviour devil's advocate and the adjudication rejected it. The argument does support low impact.
Recommended Allow a suffix after the prefix when only the prefix's continuation class carries it (validated)
Let a suffix follow the prefix when the prefix's continuation class carries its flag and the entry does not (for the tested rules, the entry's own suffixes are already combined suffix-first): +17/-6 in WordFormGenerator.java. Validated: the repro passes; hunspell package 162 tests and analysis-common 1,913 tests, 0 failures; French gains 833 forms, all accepted by spell().
if (!isPrefix && !stem.getPrefixes().isEmpty()) {
  // Suffixes are applied before prefixes, so a suffix that the root allows has already been
  // combined with this prefix. Only a suffix that the prefix's continuation class allows
  // (and the root does not) still needs to be applied here.
  return size == 0
      && stem.getPrefixes().size() == 1
      && !FlagEnumerator.hasFlagInSortedArray(flag, rootFlags, 0, rootFlags.length)
      && dictionary.isFlagAppendedByAffix(stem.getPrefixes().get(0).affixId, flag);
}
All options and trade-offs4 options · 811 words
One option was built and validated in a scratch worktree of a9779ef3c193; the others are alternatives.
Allow a suffix after the prefix when only the prefix's continuation class carries it (validated) (recommended)
Pass the entry's own sorted flags down expand and replace line 378 of isCompatibleWithPreviousAffixes. The new path applies a suffix only when the single prefix's continuation class carries its flag and the entry does not, the condition under which the Stemmer accepts such a word (Stemmer.java:269-270). The new forms still pass canStemToOriginal, but that is no guarantee: it compares stem text only, not flags (with work/P it is true for works, which spell() rejects), and NGramFragmentChecker.processNGrams overrides it to return true. The evidence is the runs: every added form is accepted by spell() (French: all 833; the repro dictionaries). The rootFlags check avoids a second copy when the entry has the flag: for the tested rules (cross-product, no conditions) the suffix-first path has already built the word, so work/PS still gives 4 forms, not 5.
if (!isPrefix && !stem.getPrefixes().isEmpty()) {
  // Suffixes are applied before prefixes, so a suffix that the root allows has already been
  // combined with this prefix. Only a suffix that the prefix's continuation class allows
  // (and the root does not) still needs to be applied here.
  return size == 0
      && stem.getPrefixes().size() == 1
      && !FlagEnumerator.hasFlagInSortedArray(flag, rootFlags, 0, rootFlags.length)
      && dictionary.isFlagAppendedByAffix(stem.getPrefixes().get(0).affixId, flag);
}
Trade-offs
- Scope. One prefix and no suffix yet. A second prefix under
COMPLEXPREFIXES, or a prefix-enabled suffix on top of an entry suffix, stays as today; whether C Hunspell accepts those was not checked. Not tested: affix conditions or strips that let a rule apply in one order only, and the fragment-checker path, wherecanStemToOriginalis bypassed. With a non-cross-product suffix or prefix (SFX S N,PFX P N),spell("reworks")is false and stock, fix A and patch B generate exactly the accepted forms (executed). - Cost. One short scan of the entry's flags per suffix flag after a prefix. French
generateAllSimpleWords: 24.2 and 23.2 s on main, 27.3 and 22.8 s with the fix (four single runs on a loaded host, not a benchmark): no measurable difference. - Compatibility. More forms from the dictionary-tooling API and fewer needless
compressedits; no index, analysis, stemming or spell-checking change. A fragment checker fromNGramFragmentChecker.fromAllSimpleWordsgains the n-grams of the added forms, so aSuggesterconfigured withwithFragmentCheckermay suggest differently (no change in the hunt probe's 8 misspellings). Only private signatures change.
What the checks validated
- stock: the repro fails 3 of 4 with assertions on and off; the hunspell test package (47 classes, 162 tests with the repro) fails only the repro's 3 tests;
- fix A: the repro passes 4 of 4 with assertions on and off; the hunspell package passes (162 tests, 0 failures, 13 skipped: 10 in
TestPerformance(no word corpora configured), 2 inTestAllDictionaries(no dictionary directory configured; one test is@Ignored), 1 inTestHunspellRepositoryTestCases(no C Hunspell test repository configured)); the wholelucene/analysis/commontest task, repro included, runs 340 classes, 1,913 tests, 0 failures, 18 skipped;ecjLint,checkGoogleJavaFormat,forbiddenApisMainandforbiddenApisTestpass;tidychanges nothing; - the hunt's repros with fix A shadowed: the finder's (1 of 1), the independent reproducer's (5 of 5), the cross-model reviewers' tests (2 of 2 each; the intended-lens test includes the duplicate-output control that the finder's patch fails) and the hunt's 5-test security probe pass;
- the finder's patch (option B) shadowed: the repro's
testControlsfails,[work, rework, reworks, works, reworks]; - French whole-dictionary probe: 833 forms added, 0 removed, all accepted by
spell(); equal repeatedAffixedWords 17,001 on main and with fix A (unchanged).
The finder's first patch: size == 0 && prefixes.size() == 1 && isFlagAppendedByAffix(prefix, flag), without the entry check.
Trade-offs
Builds the same form twice when the entry also has the flag: work/PS gives [work, rework, reworks, works, reworks] (equal AffixedWords), and the repro's testControls fails. Found independently by the reproducer and a cross-model reviewer. On the French dictionary it gives the same word list as option A.
For example a LinkedHashSet per entry. Not validated.
Trade-offs
Still does the duplicate work and keeps a set of all forms of an entry; option A avoids the duplicate at the source. The generator's first version (d537013e708) did collect forms in a LinkedHashSet<AffixedWord>; #11904 ("speed up WordFormGenerator") replaced the sets with lists, so this option partly undoes that change.
State in the getAllWordForms, generateAllSimpleWords and compress javadocs that suffixes enabled only by a prefix's continuation class are not generated. Not validated.
Trade-offs
Leaves the inconsistency with spell(), checkGoodSugWordsAreGenerated and LUCENE-9688.
No use of these APIs was found in Elasticsearch, OpenSearch or Solr, so downstream the effect is limited to tools that build word lists, dictionary edits or n-gram fragment checkers with Lucene's generator.
Differential testing of Lucene's word-form generator, spell() and analyzeSimpleWord() against C Hunspell 1.7.2 on 4,000 generated micro-dictionaries and 1,069 fixture cases, where Lucene's own dependencies fixture showed the gap. A public-API JUnit then reproduced it on the stock jar.
The method in full119 words
Method: cross-implementation differential testing (non-formal tier). A hunt unit compared Lucene getAllWordForms, spell and analyzeSimpleWord with C Hunspell 1.7.2 (spell, stem) and the unmunch tool.
- Inputs: 4,000 grammar-built micro-dictionaries (per dictionary, every candidate word reachable by at most 3 affix rules) and 1,069 per-root cases from the Hunspell 1.7.2 and Lucene test fixtures; Lucene's
dependencies.affshowed the difference. - Root causes were separated with switchable shadow fixes: this fix alone adds 21 generated forms that
spell()accepts and attributes to the root. - The finder then wrote a one-test public-API JUnit that fails on the stock jar. Independent checkers and two executed reviews by a model from another family (OpenAI GPT-5.6) reproduced it with their own tests.
No prior report found (2026-10-27): three scripted prior-report search runs (159 queries over GitHub, the mailing lists, JIRA and downstream trackers), 45 manual GitHub searches, a title read of all 47 hunspell issues and PRs since 2022-07 and a file scan of all 409 open PRs. The closest item, #10727, fixed the same pattern in the Stemmer in 2021.
Searches4 searches
No report of this defect was found. The closest item is the Stemmer-side fix.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs, commits; downstream repositories; dev@, java-user@, issues@, commits@; JIRA archive; web | 2026-10-27 | scripted prior-report search, 3 runs, 159 queries (53, 55 and 51) | no report; the expected targets #11662 and LUCENE-9688 were found |
| GitHub, manual | 2026-10-27 | 45 searches: every identifier (WordFormGenerator, getAllWordForms, generateAllSimpleWords, AffixedWord, EntrySuggestion, isFlagAppendedByAffix, isCompatibleWithPreviousAffixes, checkGoodSugWordsAreGenerated, fromAllSimpleWords), symptom phrasings, Elasticsearch, OpenSearch, Solr; title read of all 47 hunspell issues and PRs since 2022-07 | no report |
| Open PRs | 2026-10-27 | changed files of all 409 open apache/lucene PRs | only #16422 (Dictionary directive parsing, changes Dictionary.java only) and #16911 ("Decommission branch 10x", lists all 7,630 files, WordFormGenerator.java included) touch hunspell files; neither fixes this |
| Related threads (read) | 2026-10-27 | #10727, #11662, #975 (all review comments), #11904, #11909, #12447, #13429; JIRA LUCENE-10626, LUCENE-9688; hunspell/hunspell#404, #340 | #10727 is the Stemmer-side fix for the same pattern (the precedent); #975 introduced the guard without discussion; the C unmunch items concern a different code base |
Present since the generator was added in #975 (d537013e708, merged 2022-07-05; first release 9.5.0 via the cherry-pick 3b763af12f5). The hunt's test fails on all 26 releases from 9.5.0 to 10.5.2 and on main; 9.4.2 and older lack the API. Not a regression; not fixed upstream.
Versions tested5 rows
Introduced by apache/lucene#975 "LUCENE-10626: Hunspell: add tools to aid dictionary editing" (by @donnerpeter, approved by @dweiss), merged to main 2022-07-05 as d537013e708; it reached 9.x as the cherry-pick 3b763af12f5 (committed 2023-01-13), hence 9.5.0. git log -S on the guard text over main's history returns only d537013e708 (with --all it also finds the 9.x cherry-pick). 682e5c94e83 (#11904, 2022-11-07) moved the line unchanged into WordFormGenerator.isCompatibleWithPreviousAffixes, so git blame points there. The Stemmer has accepted these words since LUCENE-9688 (0a1a3f4c409, 2021-01-22; backported to 8.x and first released in 8.9.0).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test fails 3 of 4 (gradle and classpath runner, -ea and -da); fix A passes |
| 9.5.0 to 10.5.2 (26 releases) | affected | the finder's test fails 1 of 1 on every release; this doc's test fails 3 of 4 on 9.5.0, 9.12.3 and 10.5.2; the guard is line 406 in 9.5.0 and 378 in 10.5.2 |
| 9.5.0 and 10.5.2 with only the guard line replaced | shadow fix | the finder's test passes |
| 9.3.0 to 9.4.2 | no API | compile error: getAllWordForms and AffixedWord are absent |
upstream main a95c754ee003 and c5ab3e57b9ba, branch_10x, branch_10_6 | source only | the same guard line and method texts (fetched 2026-10-28), not executed |
An independent reproducer, an intended-behaviour devil's advocate and two executed reviews by a model from another family (OpenAI GPT-5.6) rated it real; an adjudication and a credibility audit re-ran it; this doc's gradle runs reproduce it and validate a duplicate-free fix.
Checks and verdicts350 words
Every check ran on main a9779ef3c193 (the cross-model reviews on ea57360912ed, whose hunspell package is identical) with JDK 25.0.3.
| Check | Verdict | What it found |
|---|---|---|
| Independent reproducer | real | Own 5-test JUnit (work/P, book/Z, generateAllSimpleWords, compress, mirror control) fails 4 of 5 on main, 10.5.2, 9.12.3 and 9.5.0; C Hunspell accepts reworks and books; found that the finder's patch emits reworks twice for work/PS. |
| Cross-model review, refute lens (OpenAI GPT-5.6) | real, high | Own test (prebasez) fails with -ea and -da; the control with the suffix flag on the entry passes; intended-behaviour argument weak. |
| Cross-model review, intended lens (OpenAI GPT-5.6) | real, high | Own test (micrometers) fails on main and 10.5.2; found the duplicate output of the finder's patch. |
| Intended-behaviour devil's advocate | real, not intended | Showed the asymmetry in Lucene's own fixture (undrinkables generated, calories not) and that C unmunch has no continuation-class support. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test on main (-ea and -da: 5 run, 4 failed); required a duplicate-free fix. |
| Registration check and credibility audit | keep | Re-ran the finder's and the independent reproduction's tests on main with fresh seeds; same failures. |
| This doc | reproduced; fix A validated | Gradle in a clean worktree: 3 of 4 fail on stock, 0 with fix A; the hunt's five repros and the security probe pass with fix A; French whole-dictionary probe. |
| Fact checks of this doc (independent, and cross-model OpenAI GPT-5.6) | bug confirmed; wording fixed | The independent check re-ran the gradle repro (3 of 4 fail with assertions on and off; 4 of 4 pass with fix A), the hunspell package and analysis-common suites, the lint tasks and the French probe (identical form lists). Both checks found wording errors (the fix A safety argument, the 9.x gradle claim, a package-private method, the LUCENE-9688 PR and release, distinct words vs the raw list); all are corrected, none changes the bug, the numbers or the fix. The cross-model check also rated the intended-behaviour argument weak. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 427 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,294 words
- Registry title
- Hunspell getAllWordForms, generateAllSimpleWords and compress never generate a suffix that only a prefix's continuation class allows: with ampere/U and 'PFX U 0 kilo/S', spell() accepts amperes and kiloamperes, but getAllWordForms("ampere") returns only [ampere, kiloampere]
- Area
- analysis / hunspell (WordFormGenerator: getAllWordForms, generateAllSimpleWords, compress)
- Priority
- Low, rank 469: Silent incomplete word-form lists in the rarely used opt-in Hunspell tooling API that never affect spell-checking, stemming or search, so it closes the silent Hunspell rows after LFV-376.
- Impact class
- silent wrong results
- Impact note
- Only applications that call Lucene's opt-in Hunspell dictionary-tooling API (Hunspell.getAllWordForms and compress, WordFormGenerator.getAllWordForms, generateAllSimpleWords and compress, and indirectly NGramFragmentChecker.fromAllSimpleWords) with a dictionary that has a PFX rule whose continuation class carries an SFX flag that the entry itself lacks are hit: the word-form list is incomplete with no error, and compress() proposes an unneeded flag whose edit can add a word the caller did not ask for (it is listed in getExtraGeneratedWords) [exec]; spell-checking, stemming, HunspellStemFilter, indexing and search are not affected [exec, security probe]; no scale is needed; every release from 9.5.0 through 10.6.0 (10.6.0 by reading) and main [exec]; Lucene's own dependencies.aff test fixture has the pattern, and the finder reports it in the LibreOffice French dictionary (fr.aff 'PFX Um' unit prefixes: 2 of 3,000 sampled roots, 48 missing forms), which the verifiers did not re-check.
- Summary
- You load a Hunspell dictionary in which a prefix rule's continuation class allows a suffix, for example 'PFX U 0 kilo/S' and 'SFX S 0 s' with the entry ampere/U, and ask Hunspell.getAllWordForms("ampere") for all forms of that entry. You expect ampere, amperes, kiloampere and kiloamperes: Lucene's own spell() accepts all four and analyzeSimpleWord() analyses each one as a form of ampere/U, as C Hunspell 1.7.2 also does. Instead you get only [ampere, kiloampere], because WordFormGenerator applies suffixes only from the entry's own flags and then forbids any suffix once a prefix has been applied (WordFormGenerator.java:378); generateAllSimpleWords misses the same words, and compress() suggests an unneeded flag (for work/P with 'PFX P 0 re/S', compress([work, rework, reworks]) proposes work/PS, which also adds the unrequested word works).
- Introduced
- d537013e70872015364c745e5f320727efc034b7 (apache/lucene#975 'LUCENE-10626 Hunspell: add tools to aid dictionary editing', by donnerpeter, approved by dweiss; issue LUCENE-10626, migrated as #11662), merged to main 2022-07-05; on branch_9x as the cherry-pick 3b763af12f576b8b8120e98ae38b7a67461a99e8 (2023-01-13), which is how it reached 9.5.0 [read: git log -S on the guard text returns only d537013e708, where the line sits without a comment in AffixEntry.isCompatibleWithPreviousAffixes; 682e5c94e83 (#11904 'speed up WordFormGenerator', 2022-11-07) moved it verbatim into WordFormGenerator.isCompatibleWithPreviousAffixes, which is why git blame on main points there] [exec at release granularity: 9.3.0-9.4.2 lack the API (compile error), 9.5.0 fails; replacing only the guard line in the release's own WordFormGenerator.java (shadow source) makes 9.5.0 and 10.5.2 pass]. Not a regression: the guard is as old as the generator. The spell-checker side has accepted this affix pattern since LUCENE-9688 (#10727, commit 0a1a3f4c409, 2021-01-22, first released in 9.0.0), 17 months before the generator existed. (2022-07-05 (merged to main); 2023-01-13 (branch_9x cherry-pick 3b763af12f5))
- First affected version
- 9.5.0 [exec] (the first release with Hunspell.getAllWordForms and WordFormGenerator; first 10.x release 10.0.0 [exec]); 9.4.2 and older are unaffected only because the API is absent (the repro is a compile error on 9.3.0, 9.4.0, 9.4.1 and 9.4.2 [exec])
- Affected versions
- every release from 9.5.0 through 10.6.0 (26 releases through 10.5.2, and 10.6.0 by reading) and main a9779ef3c193; never fixed. [exec] the finder's JUnit fails 1/1 at the same assertion on all 26 releases from 9.5.0 to 10.5.2 with -ea, also with -da on 9.5.0, 9.12.3 and 10.5.2, and on main with -ea and -da (31 failing runs, follow-up); the independent reproduction's JUnit fails 4 of 5 on main (-ea and -da), 10.5.2, 9.12.3 and 9.5.0; the GPT reviewers' own tests fail on the previous main ea57360912ed (identical hunspell code), the intended-lens test also on 10.5.2. [read] the method texts of isCompatibleWithPreviousAffixes and expand are identical (md5) in all 26 releases and on main; the guard is also present on upstream main a95c754ee003, branch_10x and branch_10_6 (source check only, not executed). Not affected: 9.4.2 and older (no API). All runs on aarch64 with JDK 25.0.3.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record verdict new): a scripted prior-report search in three runs (53, 55 and 51 queries over GitHub issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web), manual GitHub searches of apache/lucene, Elasticsearch, OpenSearch, Solr and all public repositories, a title read of all 47 apache/lucene hunspell issues and PRs created since 2022-07 (the generator-related #11904, #11909, #12447 and #13429 opened and read), the changed files of all 409 open apache/lucene PRs (only #16422, a Dictionary directive-parsing refactor, and #16911, the branch_10x decommission, touch hunspell sources), JIRA REST (LUCENE-10626, LUCENE-9688 and related) and lists.apache.org; the finder's, the independent reproduction's and the intended-behaviour check's searches agree. Closest items, none a report of this bug: #10727 (LUCENE-9688, closed 2021), the Stemmer-side fix for the same affix pattern with the same fixture (calorie/p, 'PFX p 0 0/s'), which predates the generator and is the contract precedent; #11662 and #975, which introduced the generator and the guard (all review comments read, none about prefix continuation classes); hunspell/hunspell#404 and #340 (C unmunch has no continuation-class support; a different code base). Not fixed upstream: the guard is unchanged on upstream main a95c754ee003 and no open PR changes WordFormGenerator.
- Lucene commit tested
- main
a9779ef3c193(gradle in a clean scratch worktree, and the hunt's classpath runner with-eaand-da); through the classpath runner also 10.5.2, 9.12.3 and 9.5.0 (9.4.2: compile error, the API is absent). The hunt's own test ran on all 26 releases from 9.5.0 to 10.5.2. Whole-dictionary probe on the LibreOffice French dictionary (4f1df64b2e8e), 2026-10-28.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordFormGenerator.java:117-133 (at a9779ef3c193) (getAllWordForms javadoc 'Generate all word forms for all dictionary entries with the given root word' and 'equivalent to "unmunch"'), :135-138 (flags overload, same wording), :233-259 (expand: a prefix application recurses with updateFlags(flags, flag, append), so the prefix's continuation flags are in the list), :294-298 (generateAllSimpleWords javadoc: compounds and case variants excluded, nothing else), :372-383 (isCompatibleWithPreviousAffixes; :378 'if (!isPrefix && !stem.getPrefixes().isEmpty()) return false;')lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java:265-270 (at a9779ef3c193) (a suffix flag is accepted if the entry has it or the prefix's continuation class appends it: dictionary.hasFlag(entryId, flag) || dictionary.isFlagAppendedByAffix(prefixId, flag))lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:334-353 (at a9779ef3c193) (getAllWordForms and compress delegate to WordFormGenerator; 'equivalent to "munch"'); NGramFragmentChecker.java:76-92 (fromAllSimpleWords: 'derive all word forms (using WordFormGenerator) ... to get all words acceptable by the spellchecker', the only named limitation is compounds)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestSpellChecking.java:326 (at a9779ef3c193) and :357-376 (checkGoodSugWordsAreGenerated: every lowercase .good/.sug word that analyzeSimpleWord accepts must be generated); dependencies.aff:24-25 ('PFX p Y 1', 'PFX p 0 0/s .'), dependencies.dic:5 (calorie/p), TestDependencies.java:42-43 (calories stems to calorie)git diff ea57360912ed a9779ef3c193 -- lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/ (empty: the GPT reviews on ea57360912ed exercised identical code)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordFormGenerator.java:117-162, (at a9779ef3c193) 184-217, 233-259, 275-287, 372-383; Stemmer.java:265-276; Dictionary.java:1346-1350
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:334-353; (at a9779ef3c193) NGramFragmentChecker.java:75-92; WordFormGenerator.java:294-348
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordFormGenerator.java:117-119, (at a9779ef3c193) 294-298; Hunspell.java:334-336; NGramFragmentChecker.java:76-81lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestSpellChecking.java:324-327, (at a9779ef3c193) 357-376; dependencies.aff:24-25; dependencies.dic:5; TestDependencies.java:42-43
- TestWordFormsPrefixEnabledSuffix.java (JUnit test):
repro/LFV-634/src/org/apache/lucene/analysis/hunspell/TestWordFormsPrefixEnabledSuffix.java(41 lines)
Made in parallel with this doc from the ampere/U example.
assets/LFV-634/bug.png(427 KB)