Lucene's Hunspell module can list every form of a dictionary word (getAllWordForms, like C unmunch) and suggest dictionary entries for a word list (compress, like munch). A built-in check is meant to keep only forms the spell-checker accepts.
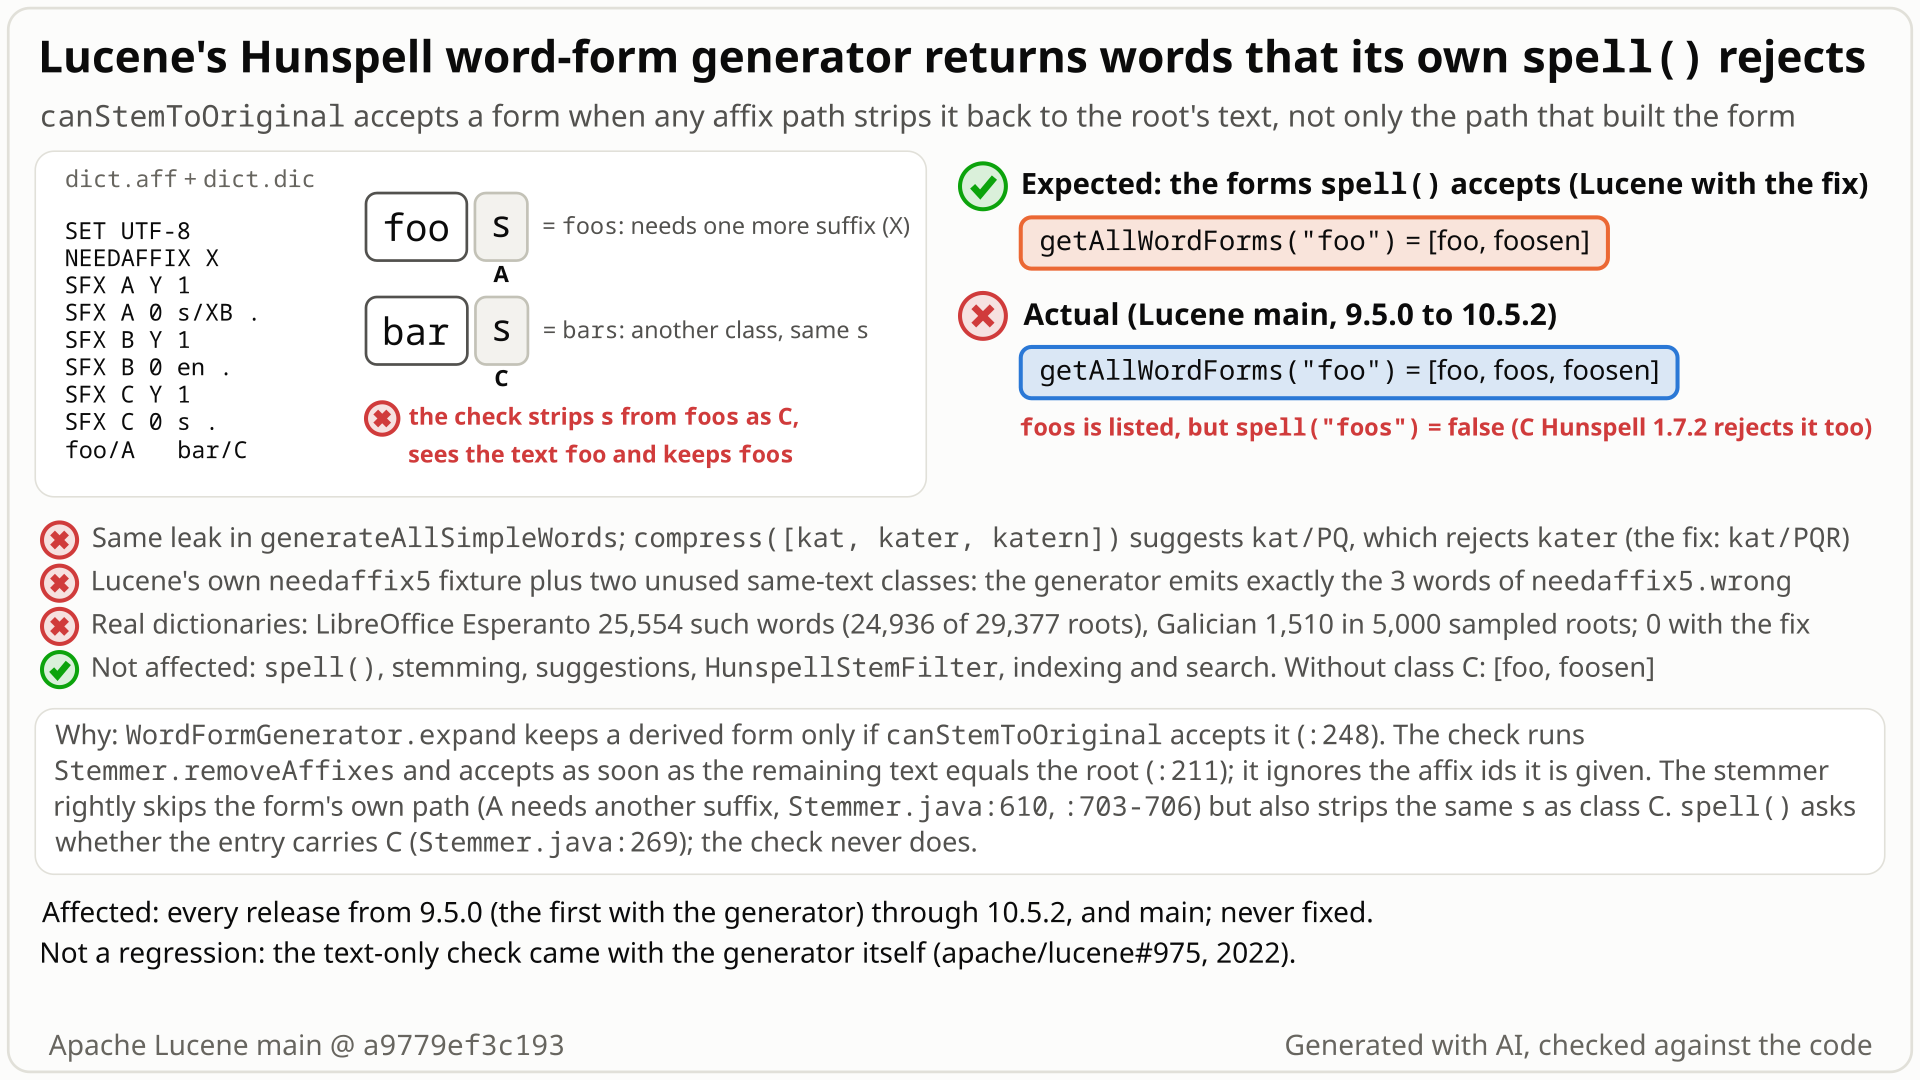
foos is built with class A, which needs one more suffix; the check strips the same s with class C, which foo does not have, finds the text foo and keeps foos, which spell() rejects. Select the still to open it at full size. Generated with AI, checked against the code.- You load a dictionary where class A adds
stofooand its continuation needs one more suffix (NEEDAFFIX):foosis not a word,foosenis. An unrelated class C, used only bybar, also addss. - You call
getAllWordForms("foo")and expect[foo, foosen]:spell("foos")is false, C Hunspell rejects it too, and the generator's check is documented to keep only forms the spell-checker accepts. - You get
[foo, foos, foosen]. The check stripsswith class C, sees the textfooand accepts; it never asks which affixes it stripped (WordFormGenerator.java:211). Without class C the result is[foo, foosen]. compress([foo, foos, foosen])suggestsfoo/AB, which still rejectsfoos. Lucene's own fixtureneedaffix5plus two unused same-text lines generates exactly the 3 words of its.wrongfile.- Real dictionaries: Esperanto gives 25,554 rejected words among 14.2 million forms (bare stems like
zink), Galician 1,510 in 5,000 roots, and C Hunspell rejects nearly all sampled ones (397 of 400, 300 of 300). Nothing throws; spell-checking, stemming and search are unaffected.
Applications that use the Hunspell dictionary-tooling API (getAllWordForms, generateAllSimpleWords, compress) to export word lists or edit dictionaries, with a dictionary where a NEEDAFFIX or CIRCUMFIX affix shares its text with another affix path. Public Esperanto and Galician dictionaries are hit. Spell-checking, suggestions, stemming and search are not. Every release since 9.5.0.
Mechanism, terms and numbers764 words
Hunspell.getAllWordForms(root), and WordFormGenerator.getAllWordForms, generateAllSimpleWords and compress, which share its expansion, keep each affix-derived form only if the check canStemToOriginal passes; its javadoc says the form "is indeed accepted by the spell-checker and analyzed to be the form of the original dictionary entry". The check strips affixes from the form and accepts as soon as any stripping path gives back the stem's text, ignoring which affixes that path removed (WordFormGenerator.java:211 on main a9779ef3c193). When an affix makes a form that is not a word on its own (its continuation carries NEEDAFFIX, or a CIRCUMFIX side is missing), the stemmer skips that path, but any other affix with the same text and strip whose condition matches, even of a class the entry does not have, leads back to the same text and the form is kept. With NEEDAFFIX X, SFX A 0 s/XB, SFX B 0 en, an unrelated SFX C 0 s, foo/A and bar/C, getAllWordForms("foo") returns [foo, foos, foosen] while spell("foos") is false; Lucene's needaffix5 fixture plus two unused same-text lines regenerates exactly its .wrong words; compress suggests foo/AB, which does not accept foos. The public Esperanto dictionary yields 25,554 such words (24,936 of 29,377 roots) and 5,000 Galician roots 1,510. Every release from 9.5.0, the API's first, to 10.6.0 (10.6.0 by reading) and main is affected. Spell-checking, suggestions, stemming, HunspellStemFilter, indexing and search are not.
- Affix class: a flag in the
.afffile, for exampleSFX A 0 s/XB .= class A appendss(strips nothing, any condition) and gives the result the continuation flagsXandB. An entryfoo/Ain the.dicmay take class A. - NEEDAFFIX: a flag (
NEEDAFFIX X) that marks a pseudo-form: a form whose flags contain X is not a word until another affix is applied. Sofoos(foo + A, flags XB) is not a word, butfoosen(foos + B) is. canStemToOriginal: the generator's filter. It runs the stemmer backwards on each generated form and keeps the form if the stemmer gets back to the entry's stem.
WordFormGenerator.expand(:233-259) applies each affix and keeps the result only ifcanStemToOriginalsays so (:248); it has no NEEDAFFIX or CIRCUMFIX check of its own (shouldConsiderAtAll,:247, only drops compound, FORBIDDENWORD and ONLYINCOMPOUND continuations; the bare stem is added without the check unless the entry has NEEDAFFIX,:154-160). For a cross-product affix it recurses with the continuation flags (:251-253), which makesfoosen.canStemToOriginal(:184-217) callsStemmer.removeAffixes(:215) with a processor (:192-214) that receives the ids of the affixes each path removed, but decides on text alone:foundStem |= length == stem.length() && stem.equals(new String(chars, offset, length));(:211).- The stemmer skips the form's own path because A's continuation needs another affix (
needsAnotherAffix,Stemmer.java:610,:693-708). It then tries class C, which also stripss(same strip, matching condition), and offersfoowith C's id. The text matches, sofoosis kept. - The spell-checker would reject that candidate because
foohas no flag C (Stemmer.java:265-269). The generator's check does not look at entry flags (it cannot rely on them, sincecompressruns it for hypothetical flag sets), and nothing else ties the accepted path to the form's own affixes, which the generator knows (AffixedWord.getPrefixes()/getSuffixes()).
| call | expected | main a9779ef3c193 |
|---|---|---|
getAllWordForms("foo") | [foo, foosen] | [foo, foos, foosen] |
| same without class C | [foo, foosen] | [foo, foosen] |
spell: foo, foos, foosen, bars | true, false, true, true | same (C Hunspell 1.7.2: 1, 0, 1, 1) |
needaffix5 + SFX D 0 pseudosuf, PFX E 0 pseudopre (only baz/DE uses them) | the stock 12 forms | 15 forms: + foopseudosuf, pseudoprefoo, pseudoprefoopseudosuf (= needaffix5.wrong) |
compress([foo, foos, foosen]) | an entry that accepts all three | foo/AB (rejects foos); with the fix foo/ABC |
Real dictionaries (stock main vs the fix, public API): LibreOffice Esperanto, all 29,377 roots: 14,235,519 forms, 25,554 rejected by spell() (24,936 roots), 0 with the fix; Galician gl_ES, 5,000 sampled roots: 2,153,392 forms, 1,510 rejected (243 roots), 0 with the fix. C Hunspell 1.7.2 rejects 397 of 400 and 300 of 300 sampled leaks. Most Esperanto leaks are bare stems such as zink (the word needs an ending, zinko); there the other path is a second entry of the same class (SFX O 0 0/2XN€ needs another affix, SFX O 0 0/543 leads to the same text).
Exposure and likelihood396 words
- Who is exposed. Callers of
Hunspell.getAllWordForms/compressandWordFormGenerator.getAllWordForms/generateAllSimpleWords/compress: word-list export (the javadoc calls it equivalent tounmunch), dictionary editing (compress, equivalent tomunch), auxiliary lists built from a dictionary. The Hunspell module is opt-in and this API is a niche part of it. - What goes wrong. Silent non-words in the list: 25,554 of 14.2 million Esperanto forms, mostly bare stems.
compresscan propose an entry that does not accept a word it was asked to cover (foo/ABforfoos), so an editing tool that trusts it writes a wrong entry. The javadoc's second promise breaks too: on Esperanto the fix also removes 2,183 forms thatspell()accepts only as forms of another entry or with no simple-word analysis. - What is not affected.
spell,suggest,getRoots/analyzeSimpleWord,HunspellStemFilter, indexing and querying do not call this check; leaked words stay rejected and unstemmed.NGramFragmentCheckeroverrides the check withreturn trueand is unchanged. In the security probe (which runsspell,analyzeSimpleWord,HunspellStemFilter, indexing and search;suggestandgetRootswere read, not run): no exception, no hang, and the same number of affix applications with or without the bug; memory was not measured. - What it takes. A dictionary in which an affix makes a form that is not valid on its own (NEEDAFFIX or CIRCUMFIX in its continuation) and another affix path, at the same position, with the same affix text and strip and a matching condition, that leads back to the same stem text. No other configuration, no scale; deterministic.
- How common. 24 of 191 public
.afffiles match one conservative syntactic scan (a NEEDAFFIX or CIRCUMFIX entry plus an entry of a different class with the same strip and non-empty text; for example da, de (frami), eo, eu, gl, id, ka, lb, lv, sk). It ignores conditions and the.dic, so it over-counts, and it misses same-class and zero-text collisions such as Esperanto's, so it is not an upper bound. Esperanto and Galician leak at scale. In the sampled Danish and German (frami) runs the fix changed nothing; in Luxembourgish it removed 9 forms that Lucene'sspell()rejects but C Hunspell accepts (a separate stemmer difference, so no clean leak). A Basque run did not finish in its time box; the others were not run.
The test shows that with NEEDAFFIX X, SFX A 0 s/XB, SFX B 0 en, an unused SFX C 0 s and the entry foo/A, Hunspell.getAllWordForms("foo") returns foos, which the same dictionary's spell() rejects.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.hunspell;

import java.io.ByteArrayInputStream;
import java.nio.charset.StandardCharsets;
import java.util.List;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestWordFormsNeedAffixLeak extends LuceneTestCase {

  public void testGeneratedFormsPassSpell() throws Exception {
    String aff =
        "NEEDAFFIX X\n"
            + "SFX A Y 1\nSFX A 0 s/XB .\n"
            + "SFX B Y 1\nSFX B 0 en .\n"
            + "SFX C Y 1\nSFX C 0 s .\n";
    Dictionary dictionary =
        new Dictionary(
            new ByteBuffersDirectory(),
            "dict",
            new ByteArrayInputStream(aff.getBytes(StandardCharsets.UTF_8)),
            new ByteArrayInputStream("1\nfoo/A\n".getBytes(StandardCharsets.UTF_8)));
    Hunspell hunspell = new Hunspell(dictionary);
    List<String> rejected =
        hunspell.getAllWordForms("foo").stream()
            .map(AffixedWord::getWord)
            .filter(word -> !hunspell.spell(word))
            .toList();
    // expected no generated form that spell() rejects; actual [foos] (A needs another affix)
    assertEquals(List.of(), rejected);
  }
}
# in a copy of this finding's repro folder (repro/LFV-638/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.hunspell.TestWordFormsNeedAffixLeak
- Expected vs actual
- Expected: every generated form passes
spell()(empty list of rejected forms); actual (-ea and -da):[foos], because canStemToOriginal accepts class C's path that strips foos back to the text foo.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[]> but was:<[foos]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.hunspell.TestWordFormsNeedAffixLeak.testGeneratedFormsPassSpell(TestWordFormsNeedAffixLeak.java:46)- The check's javadoc promises each kept form "is indeed accepted by the spell-checker and analyzed to be the form of the original dictionary entry".
- Lucene's
TestSpellCheckingfails with "Misspelled words generated" on any such word;needaffix5.wronglists the words that leak. - C Hunspell 1.7.2 rejects
foosand 397 of 400 Esperanto and 300 of 300 Galician sampled leaks.
The full argument264 words
- Contract.
canStemToOriginaljavadoc (WordFormGenerator.java:178-183, added by #11909): "A sanity-check that the word form generated by affixation ingetAllWordForms(String, String, Runnable)is indeed accepted by the spell-checker and analyzed to be the form of the original dictionary entry." - Test.
TestSpellChecking.checkExpansionGeneratesCorrectWords(:378-388), whichexpandWholeDictionary(:337-355) calls for every.dicline (except empty lines and lines with a backslash) of each fixture thatTestSpellCheckingruns throughdoTest, fails with "Misspelled words generated" on any generated word thatspell()rejects oranalyzeSimpleWordcannot analyse. It came with the generator in #975. Stock fixtures do repeat affix texts (germancompounding.aff,compress.aff), andcircumfix.affhas this bug's own shape (CIRCUMFIX XwithSFX C 0 obb .,obb/AXandobb/BX): there stockgetAllWordForms("nagy")returnsnagyobbthree times, twice only because the plainobbpath strips to the same text. It stays invisible becausenagyobbis a real word, andTestCircumfixdoes not run the expansion check. Among the fixtures thatTestSpellCheckingexpands, the ones that repeat an affix text (base,base_utf,germancompounding,germanManualCase) have neither NEEDAFFIX nor CIRCUMFIX, andneedaffix5repeats no affix text, so the test never fired. - Fixture.
needaffix5.wronglistspseudoprefoo,foopseudosuf,pseudoprefoopseudosuf: the three words the generator emits once two unused same-text lines are added. - Independent engine. C Hunspell 1.7.2 rejects
foosand nearly all sampled real-dictionary leaks. - History. The text-only comparison is as old as the generator (#975,
d537013e708); none of its 4 conversation and 19 review comments discusses which affix path the check accepts.
The devil's-advocate check186 words
The strongest case for "intended": the method is a protected, overridable sanity check; NGramFragmentChecker overrides it to "overgenerate a bit, but avoid very expensive checks"; getAllWordForms is documented as equivalent to C unmunch, which has no NEEDAFFIX support at all; and the check has to ignore entry flags because compress() runs it for hypothetical flag sets.
Why it fails: the default implementation's own javadoc promises spell-checker acceptance; the override is an explicit opt-out by one other caller, and its comment implies the default is the precise, expensive check; Lucene's own test demands more than unmunch; and the fix compares only the affix ids the stemmer already reports with the form's own affixes, so it stays independent of entry flags (compress keeps working and suggests foo/ABC). An independent reproducer, an intended-behaviour devil's advocate and a reviewer from another model family all rated the intended-behaviour argument weak, and so did the cross-model fact check of this doc, which adds that the argument does not settle which fix is right: fix A's exact-affix-id rule is one reading of the contract. Verdict: not intended, a defect.
Recommended Accept only the form's own affix path in canStemToOriginal
Accept a stem candidate in canStemToOriginal only when the stripped affixes are the form's own: compare the stemmer's affix ids with the derived word's prefixes and suffixes (+13/-1). Validated on these tests and dictionaries (not proven for every affix graph): the repro passes; analysis-common runs 1,913 tests with 0 failures; Esperanto and Galician drop to 0 rejected words, and no form that analyses to the same root is lost.
--- WordFormGenerator.canStemToOriginal (WordFormGenerator.java:211)
-            foundStem |= length == stem.length() && stem.equals(new String(chars, offset, length));
+            foundStem |=
+                length == stem.length()
+                    && stem.equals(new String(chars, offset, length))
+                    && outerPrefix == affixAt(derived.getPrefixes(), 0)
+                    && innerPrefix == affixAt(derived.getPrefixes(), 1)
+                    && outerSuffix == affixAt(derived.getSuffixes(), 0)
+                    && innerSuffix == affixAt(derived.getSuffixes(), 1);
+
+  private static int affixAt(List<Affix> affixes, int i) {
+    return affixes.size() > i ? affixes.get(i).affixId : -1;
+  }
All options and trade-offs3 options · 847 words
Option A was applied in a scratch worktree at a9779ef3c193 and run through gradle (and re-run by the fact check), and compared with stock in one JVM on the Esperanto and Galician dictionaries. Options B and C are sketches, not run.
One file, +13/-1. The processor already receives the ids of the affixes each stripping path removed; the fix requires them to equal the derived word's own prefixes and suffixes (AffixedWord.getPrefixes() / getSuffixes(), outermost first) in addition to the stem text. It still ignores entry flags, so compress() keeps working on hypothetical flag sets.
--- WordFormGenerator.canStemToOriginal (WordFormGenerator.java:211)
-            foundStem |= length == stem.length() && stem.equals(new String(chars, offset, length));
+            foundStem |=
+                length == stem.length()
+                    && stem.equals(new String(chars, offset, length))
+                    && outerPrefix == affixAt(derived.getPrefixes(), 0)
+                    && innerPrefix == affixAt(derived.getPrefixes(), 1)
+                    && outerSuffix == affixAt(derived.getSuffixes(), 0)
+                    && innerSuffix == affixAt(derived.getSuffixes(), 1);
+
+  private static int affixAt(List<Affix> affixes, int i) {
+    return affixes.size() > i ? affixes.get(i).affixId : -1;
+  }
Trade-offs
It changes only which forms are kept, never which affixes are applied. The processor now keeps enumerating past text matches from other paths until it reaches the form's own path, so it can do more stemming work per form (not benchmarked), and a FORBIDDENWORD candidate met on the way now rejects a form that stock had already accepted; the check was already order-dependent this way when the forbidden candidate came first (read from the code; no test covers it). A maintainer may prefer another fix site. Fix A requires the exact affix ids, which is stricter than the javadoc's wording: on the stock circumfix.aff fixture it drops the two duplicate nagyobb values from the CIRCUMFIX pseudo-paths obb/AX and obb/BX (the word stays through the plain obb path). It follows the current stemmer: where Lucene's spell() rejects a word that C Hunspell accepts, the fix drops that form too (9 Luxembourgish forms, 3 hyphenated Esperanto E- forms). In the finder's 4,000-dictionary differential this fix alone also changed two other counters (dictionaries the harness could not process 1 to 2, words on which Lucene threw 4 to 3); not investigated. Validated on the listed tests and dictionaries; not proven for every affix graph.
What the checks validated
- Stock main
a9779ef3c193, gradle: the repro fails 3 of 4 with assertions on and off. - With the fix, gradle: the repro passes 4 of 4 with assertions on and off; the hunspell test package (47 classes, 162 tests including the repro, 0 failures, 13 skipped: 10
TestPerformancetests need word corpora, oneTestAllDictionariestest needs a dictionary directory,TestHunspellRepositoryTestCasesneeds the C Hunspell test repository, andTestAllDictionaries.testMaxPrologueNeededis@Ignored), among themTestSpellChecking53 of 53, which also checks, for each fixture whose.dicit expands fully and that needs no input cleaning, that every lowercase, analysable.goodand.sugword is still generated; the wholelucene/analysis/commontest task: 340 classes, 1,913 tests, 0 failures, 18 skipped.ecjLint,checkGoogleJavaFormat,forbiddenApisMain,forbiddenApisTestandcheckLicensespass. compress([foo, foos, foosen])suggestsfoo/ABCinstead offoo/AB; theneedaffix5variant generates exactly the stock fixture's 12 forms.- Esperanto, all 29,377 roots, stock and fixed generator side by side: the fix removes the 25,554 rejected forms plus 2,183 forms that
spell()accepts only as forms of another entry (1,604, for examplemanĝu, listed under the rootmanĝubut analysed only as a form ofmanĝ) or with no simple-word analysis (579, which the upstream test also counts as misspelled); it removes no form that analyses to the same root and adds none. Galician, 5,000 roots: 1,185 rejected forms removed plus 1 accepted only through another entry; again none of the same root. - Earlier, with the same affix-path comparison logic shadowed onto stock jars (the finder's version of the hunk: a
samePathvariable, the conditions in another order): the finder's, the reproducer's, the devil's advocate's and the cross-model reviewers' tests pass, and the security probe is unchanged apart from the leaked forms and thecompresssuggestion.
Before keeping a derived form, check whether its own outermost affix still needs another affix (NEEDAFFIX in the appended flags, or a CIRCUMFIX side missing), mirroring Stemmer.needsAnotherAffix.
Trade-offs
Leaves the check untouched, but duplicates the stemmer's rule, which is subtle: a NEEDAFFIX pseudo-suffix is valid once an outer affix follows (prefoopseudosuf is in needaffix5.good). It also would not cover other forms the stemmer cannot reproduce through their own path but accepts through another one (the finder's cross-product variant, not re-checked). Not run.
Keep a form only if spell(word) is true and analyzeSimpleWord(word) contains an analysis of the same entry, the oracle of checkExpansionGeneratesCorrectWords.
Trade-offs
The most literal statement of the contract for getAllWordForms, but it costs a full spell check per form and does not work for compress(), which generates forms for hypothetical entries that are not in the loaded dictionary. Not run.
Elasticsearch, OpenSearch and Solr do not call these methods (read-only code search); their hunspell token filters use the stemmer, which this bug does not affect.
Differential testing of Lucene's Hunspell word-form generator against C Hunspell 1.7.2 on 4,000 generated micro-dictionaries (plus 1,069 fixture cases) found 18 generated words that Lucene's own spell() rejects, in 15 of the micro-dictionaries, and 0 with this fix alone. A public-API JUnit then reproduced it on the stock jar.
The method in full179 words
Method: cross-implementation differential testing (the hunt's non-formal tier): a hunt unit compared Lucene's getAllWordForms, spell and analyzeSimpleWord with C Hunspell 1.7.2 (libhunspell spell and stem) and the hunspell-tools unmunch.
- Inputs: 4,000 seeded, grammar-built micro-dictionaries (per dictionary, every candidate word reachable by at most 3 affix rules) and 1,069 per-root cases from the Hunspell 1.7.2 and Lucene test fixtures.
- Root causes were separated with switchable shadow fixes: with this fix alone, the 18 self-inconsistent words in 15 dictionaries fell to 0 (the finder's counts; the verifiers did not re-run the 4,000 dictionaries).
- The finder wrote the
foo/A+bar/CJUnit; an independent reproducer added theneedaffix5variant and thecompresseffect; a credibility audit measured the Esperanto and Galician reach. - Found 2026-10-27 on main
a9779ef3c193; then checked by an independent reproducer, an intended-behaviour devil's advocate, two executed reviews by a model from another family (OpenAI GPT-5.6), an adjudication, a history and prior-report follow-up, a security screen and the audit. This doc added the gradle runs, the fix validation and the same-root check on Esperanto and Galician.
No prior report found (2026-10-27): 130 queries over GitHub, JIRA, the mailing lists, downstream projects and the web, and the changed files of all 409 open PRs. Nothing upstream fixes it.
Searches3 searches
Verdict new: no report by anyone. canStemToOriginal has no hits beyond commit notifications for #975, #11904 and #11909. Keyword search cannot prove absence, and private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories; dev@, java-user@, issues@ and commits@ lists; JIRA; the web | 2026-10-27 | a scripted prior-report search, two passes (51 + 43 queries) | no report; closest #11662 / #975, #11904, #11909, #13429, #12447, #10745 |
| apache/lucene (GitHub) | 2026-10-27 | 36 manual searches and reads; the commit history of WordFormGenerator.java; changed files of all 409 open PRs | no report; only #16422 (directive-parsing refactor) touches hunspell sources |
| Elasticsearch, OpenSearch, Solr, Lucene.NET, all of GitHub | 2026-10-27 | code and issue search for canStemToOriginal, getAllWordForms, WordFormGenerator | no report; hunspell/hunspell#932 is about C Hunspell |
Present since the API was added: #975 (LUCENE-10626, d537013e708, 2022), first released in 9.5.0. The finder's test fails on every release from 9.5.0 to 10.5.2 and on main; 9.4.2 and older lack the API. Not fixed upstream.
Versions tested5 rows
Introduced by d537013e708 (apache/lucene#975, "LUCENE-10626: Hunspell: add tools to aid dictionary editing: analysis introspection, stem expansion and stem/flag suggestion", merged to main 2022-07-05), cherry-picked to branch_9x as 3b763af12f5 (2023-01-13), which is how it reached 9.5.0. #11904 (682e5c94e83) made the method protected; #11909 (6fbc5f73c39) added the javadoc and the NGramFragmentChecker override. The method body has the same md5 in all 26 releases 9.5.0-10.5.2 and on main (the full text differs only by the private to protected change), and is unchanged on upstream main c5ab3e57b9ba (2026-10-28), branch_10x and branch_10_6.
Not a regression: the spell-checker has rejected these NEEDAFFIX pseudo-forms since LUCENE-9706 (4ba78f2ab25 on main, 2021, which added the needaffix5 fixture; first released in 8.9.0, whose jar has Stemmer.needsAnotherAffix while 8.8.2's does not); the generator never had the matching check.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's JUnit fails 3 of 4 through gradle, assertions on and off; the finder's, the reproducer's and the reviewers' tests fail with -ea and -da |
| 10.0.0 to 10.5.2 | affected | the finder's JUnit fails on all 12 releases; this doc's JUnit fails 3 of 4 on 10.5.2 |
| 9.5.0 to 9.12.3 | affected | the finder's JUnit fails on all 14 releases; this doc's JUnit fails 3 of 4 on 9.5.0 and 9.12.3 |
| 9.5.0, 10.5.2 + the fix hunk only | fixed | the finder's and the reproducer's tests pass |
| 9.3.0 to 9.4.2 | no API | compile error: getAllWordForms and compress do not exist yet (not a fixed version) |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests; two executed reviews by a model from another family (OpenAI GPT-5.6) rated it real; an adjudication re-ran it; a credibility audit measured the Esperanto and Galician reach; this doc's gradle runs reproduce it on a9779ef3c193 and validate the fix.
Checks and verdicts365 words
Every executing check wrote or re-ran its own JUnit on stock main; every control passed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Differential against C Hunspell 1.7.2, then the foo/A + bar/C JUnit: fails on main (-ea, -da), 10.5.2 and 9.12.3; C Hunspell rejects foos; the fix passes. |
| independent reproducer | real | Own test outside the package (kat/P, needaffix5 variant, two controls): 2 of 4 fail on main (-ea, -da), 10.5.2, 9.12.3, 9.5.0; found the compress effect. |
| intended-behaviour devil's advocate | real, high | Own test: 3 of 4 fail (two needaffix5 variants and a CIRCUMFIX variant that generates foot); rebutted the overridable-check, n-gram override, unmunch and flag-blindness arguments. |
| cross-model review, refute lens (OpenAI GPT-5.6) | real, high; intended argument weak | Own kindly test fails with three seeds and -da; control passes; with the fix the hunspell test package ran 145 tests successfully, 0 failed. |
| cross-model review, intended lens (OpenAI GPT-5.6) | real, high; intended argument weak | Own rootz test fails on main, 10.5.2 and 9.12.3; the leak appears only with the same-text class; re-run on a9779ef3c193. |
| adjudication | confirmed, high | Re-ran the reproducer's test (2 of 4 fail with -ea and -da; 4 of 4 pass with the fix) and the finder's test; no duplicate. |
| credibility audit | keep | Own test fails 2 of 3; Esperanto 25,554 and Galician 1,510 rejected words, 0 with the fix; C Hunspell rejects 397/400 and 300/300 samples. |
| this doc | reproduced; fix validated | Gradle: the repro fails 3 of 4 stock and passes with the fix; analysis-common 1,913 tests pass; the fix loses no same-root form on Esperanto or Galician. |
| fact checks of this doc (independent, and cross-model OpenAI GPT-5.6) | bug confirmed; wording corrected | Re-ran the gradle repro (3 of 4 fail stock, 4 of 4 pass with the fix, assertions on and off), the hunspell package and the analysis-common module with the fix, and the final file on main, 10.5.2 and 9.5.0. Found precision errors in the text (fixture claim, the 9.x gradle route, the shape scan's bound, release and upstream details), now corrected; none changes the bug, its mechanism, the numbers or the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 527 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,511 words
- Registry title
- Hunspell getAllWordForms, generateAllSimpleWords and compress return words that spell() rejects: the sanity check canStemToOriginal accepts any affix path that strips a form back to the stem text, so with 'NEEDAFFIX X', 'SFX A 0 s/XB', an unrelated 'SFX C 0 s' and foo/A, getAllWordForms("foo") returns foos
- Area
- analysis / hunspell (WordFormGenerator: canStemToOriginal, getAllWordForms, generateAllSimpleWords, compress)
- Priority
- Low, rank 466: The tooling API's sanity check leaks words that spell() rejects only on a rare affix collision that sampled real dictionaries never hit.
- Impact class
- silent wrong results
- Impact note
- Only applications that call Lucene's opt-in Hunspell dictionary-tooling API (Hunspell.getAllWordForms and compress, WordFormGenerator.getAllWordForms, generateAllSimpleWords and compress) with a dictionary in which an affix gives a form that is not valid on its own (a NEEDAFFIX or CIRCUMFIX continuation [exec]; per the finder also a cross-product mismatch, not re-checked) and another affix class has the same affix text and strip are hit: the word list contains words that the same dictionary's spell() rejects, with no error, and compress() can suggest an entry that does not accept a requested word (kat/PQ for [kat, kater, katern]) [exec]; spell-checking, stemming, suggestions, HunspellStemFilter, NGramFragmentChecker (it overrides the check), indexing and search are not affected [exec, security probe]; no scale is needed; every release from 9.5.0 through 10.6.0 (10.6.0 by reading) and main [exec]; real dictionaries are hit: the credibility audit found 25,554 leaked words in the public LibreOffice Esperanto dictionary (24,936 of 29,377 roots) and 1,510 in 5,000 sampled Galician roots, all removed by the fix, with C Hunspell 1.7.2 rejecting 397/400 and 300/300 sampled leaks [exec]; sampled da_DK, de_DE_frami and lb runs found none.
- Summary
- You load a Hunspell dictionary with 'NEEDAFFIX X', 'SFX A 0 s/XB' (so foos needs one more suffix), 'SFX B 0 en' and an unrelated class 'SFX C 0 s', with the entries foo/A and bar/C, and call Hunspell.getAllWordForms("foo"). You expect [foo, foosen]: spell() rejects foos (C Hunspell 1.7.2 does too), and the generator's check canStemToOriginal is documented to keep only forms that are 'accepted by the spell-checker and analyzed to be the form of the original dictionary entry'. Instead you get [foo, foos, foosen], because canStemToOriginal accepts as soon as any affix-stripping path gives back the stem text, here class C, which foo does not even have, and ignores which affixes were stripped (WordFormGenerator.java:211); generateAllSimpleWords leaks the same words, and compress([kat, kater, katern]) suggests kat/PQ, which does not accept kater.
- Introduced
- d537013e70872015364c745e5f320727efc034b7 (apache/lucene#975 'LUCENE-10626 Hunspell: add tools to aid dictionary editing', by donnerpeter, approved by dweiss; issue LUCENE-10626, migrated as #11662), merged to main 2022-07-05; on branch_9x as the cherry-pick 3b763af12f576b8b8120e98ae38b7a67461a99e8 (2023-01-13), which is how it reached 9.5.0 [read: git log -S on the comparison 'stem.equals(new String(chars, offset, length))' and on 'processStemCandidate' returns only d537013e708; git blame on main gives the method body (WordFormGenerator.java:185-217) to d537013e708, line 184 to 682e5c94e83 (#11904, private -> protected only) and the javadoc (:178-183) to 6fbc5f73c39 (#11909); the method text has the same md5 in d537013e708, 3b763af12f5, all 26 releases 9.5.0-10.5.2 and main] [exec at release granularity: 9.3.0-9.4.2 lack the API (compile error), 9.5.0 fails; adding only the canStemToOriginal hunk of the finder's fix to the release's own WordFormGenerator.java (shadow source) makes 9.5.0 and 10.5.2 pass]. Not a regression: the text-only comparison is as old as the generator. The spell-checker has rejected these NEEDAFFIX pseudo-affix forms since LUCENE-9706 (#10745, commit 4ba78f2ab25, 2021-01-29, first released in 9.0.0), which also added the needaffix5 fixture whose .wrong file lists them. (2022-07-05 (merged to main); 2023-01-13 (branch_9x cherry-pick 3b763af12f5))
- First affected version
- 9.5.0 [exec] (the first release with Hunspell.getAllWordForms and WordFormGenerator; first 10.x release 10.0.0 [exec]); 9.4.2 and older are unaffected only because the API is absent (the repro is a compile error on 9.3.0, 9.4.0, 9.4.1 and 9.4.2 [exec])
- Affected versions
- every release from 9.5.0 through 10.6.0 (26 releases through 10.5.2, and 10.6.0 by reading) and main a9779ef3c193; never fixed. [exec] the finder's JUnit fails 1/1 at the same assertion (actual [foos]) on all 26 releases from 9.5.0 to 10.5.2 with -ea, also with -da on 9.5.0, 9.12.3 and 10.5.2, and on main with -ea and -da (31 failing runs, follow-up); the independent reproduction's JUnit fails 2 of 4 on main (-ea and -da), 10.5.2, 9.12.3 and 9.5.0; the intended-behaviour check's fails 3 of 4 on main (-ea, -da) and 10.5.2; the GPT reviewers' own tests fail on the previous main ea57360912ed (identical hunspell code), the intended-lens test also on 10.5.2 and 9.12.3. [read] the canStemToOriginal method text is identical (md5) in all 26 releases and on main, and also on upstream main a95c754ee003, branch_10x and branch_10_6 (source check only, not executed). Not affected: 9.4.2 and older (no API). All runs on aarch64 with JDK 25.0.3.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record verdict new): 130 queries, from a scripted prior-report search in two passes (GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web) and manual searches of apache/lucene, all of GitHub, Elasticsearch, OpenSearch, Solr and Lucene.NET, the commit history of WordFormGenerator.java and the changed files of all 409 open apache/lucene PRs; canStemToOriginal has 0 hits except commit notifications for #975, #11904 and #11909; the finder's, the independent reproduction's and the intended-behaviour check's searches agree. Closest items, none a report of this bug: #11662 / #975 (introduced the generator and the text-only check; all 4 conversation and 19 review comments read), #11904 (made the method protected), #11909 (added the javadoc contract and the NGramFragmentChecker override that returns true), #10745 (LUCENE-9706, NEEDAFFIX on affixes in the spell-checker, before the generator existed), #13429 and #12447 (other WordFormGenerator changes); hunspell/hunspell#932 is about C Hunspell. Not fixed upstream: the method is unchanged on upstream main a95c754ee003, branch_10x and branch_10_6, and no open PR touches WordFormGenerator.java or Stemmer.java (#16422, a Dictionary directive-parsing refactor, is the only open PR on hunspell sources).
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): the compact JUnit through gradle in a clean worktree, stock and with the recommended fix, assertions on and off, plus the hunspell test package, the wholelucene/analysis/commontest task and its lint checks with the fix; through the hunt's classpath runner the same JUnit on main (-ea,-da), 10.5.2, 9.12.3 and 9.5.0, and 9.4.2 (compile error, no API); a stock-vs-fix comparison in one JVM over the public LibreOffice Esperanto (all 29,377 roots) and Galician (5,000 roots) dictionaries, 2026-10-28. Hunt runs on maina9779ef3c193andea57360912ed(identical hunspell code) and on all 26 releases from 9.5.0 to 10.5.2.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordFormGenerator.java:117-133 (at a9779ef3c193) (getAllWordForms javadoc: 'Generate all word forms for all dictionary entries with the given root word', 'equivalent to "unmunch"'), :178-183 (canStemToOriginal javadoc: 'is indeed accepted by the spell-checker and analyzed to be the form of the original dictionary entry'; 'can be overridden'), :184-217 (canStemToOriginal; :211 'foundStem |= length == stem.length() && stem.equals(new String(chars, offset, length));' ignores the lastAffix/outerPrefix/innerPrefix/outerSuffix/innerSuffix arguments), :233-259 (expand: canStemToOriginal at :248 is the only filter on derived forms), :294-317 (generateAllSimpleWords uses the same expansion), :571-582 (compress regenerates through getAllWordForms(stem, flags))lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java:600-612 (at a9779ef3c193) and :693-708 (removeAffixes skips the form's own path through needsAnotherAffix when the affix's continuation has NEEDAFFIX or a CIRCUMFIX mismatch, then offers other classes' stripping of the same text to the processor)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:334-353 (at a9779ef3c193) (getAllWordForms and compress delegate to WordFormGenerator; 'equivalent to "unmunch"' / '"munch"'); NGramFragmentChecker.java:127-135 (processNGrams overrides canStemToOriginal with 'return true; // overgenerate a bit, but avoid very expensive checks')lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestSpellChecking.java:337-355 (at a9779ef3c193) (expandWholeDictionary runs on every fixture) and :378-388 (checkExpansionGeneratesCorrectWords fails with 'Misspelled words generated' on any generated word that spell() rejects or analyzeSimpleWord cannot analyse); needaffix5.aff and needaffix5.wrong (pseudoprefoo, foopseudosuf, pseudoprefoopseudosuf)git diff ea57360912ed a9779ef3c193 -- lucene/analysis/common/src/{java,test}/org/apache/lucene/analysis/hunspell/ (empty: the GPT reviews on ea57360912ed exercised identical code)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordFormGenerator.java:117-124, (at a9779ef3c193) 143, 178-217 (javadoc; :211), 233-259 (expand; :248 filter), 304-322, 327-340, 581-583lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java:250-275 (at a9779ef3c193) (spell processor; :265-269 flag check), 588-616 (applyAffix; :610), 693-708 (needsAnotherAffix)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/AffixedWord.java:54-63 (at a9779ef3c193) (prefixes/suffixes, outermost first), 94 (affixId)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/needaffix5.aff, (at a9779ef3c193) needaffix5.dic, needaffix5.good, needaffix5.wrong
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:334-353 (at a9779ef3c193) (getAllWordForms, compress; 'equivalent to "unmunch"' / '"munch"'); NGramFragmentChecker.java:127-135 (override returning true)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordFormGenerator.java:117-124, (at a9779ef3c193) 178-183lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestSpellChecking.java:337-355, (at a9779ef3c193) 378-388; needaffix5.wronglucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/NGramFragmentChecker.java:127-135 (at a9779ef3c193)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/circumfix.aff, (at a9779ef3c193) circumfix.dic, germancompounding.aff, compress.aff; TestSpellChecking.java:259-263 (doTest)
- Suggested fix
lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestSpellChecking.java:324-327, (at a9779ef3c193) 357-376 (good-words check), 337-355 (expandWholeDictionary), needaffix5.good
- TestWordFormsNeedAffixLeak.java (JUnit test):
repro/LFV-638/src/org/apache/lucene/analysis/hunspell/TestWordFormsNeedAffixLeak.java(48 lines)
Its compress example is the independent reproducer's kat/PQ case; the repro's foo/AB case fails the same way.
assets/LFV-638/bug.png(527 KB)