Hunspell dictionaries mark words that may also be part of a compound with COMPOUNDBEGIN, COMPOUNDMIDDLE or COMPOUNDEND. Lucene's word-form generator treats these flags like ONLYINCOMPOUND, which forbids a word on its own, and leaves out the entry or the affix.
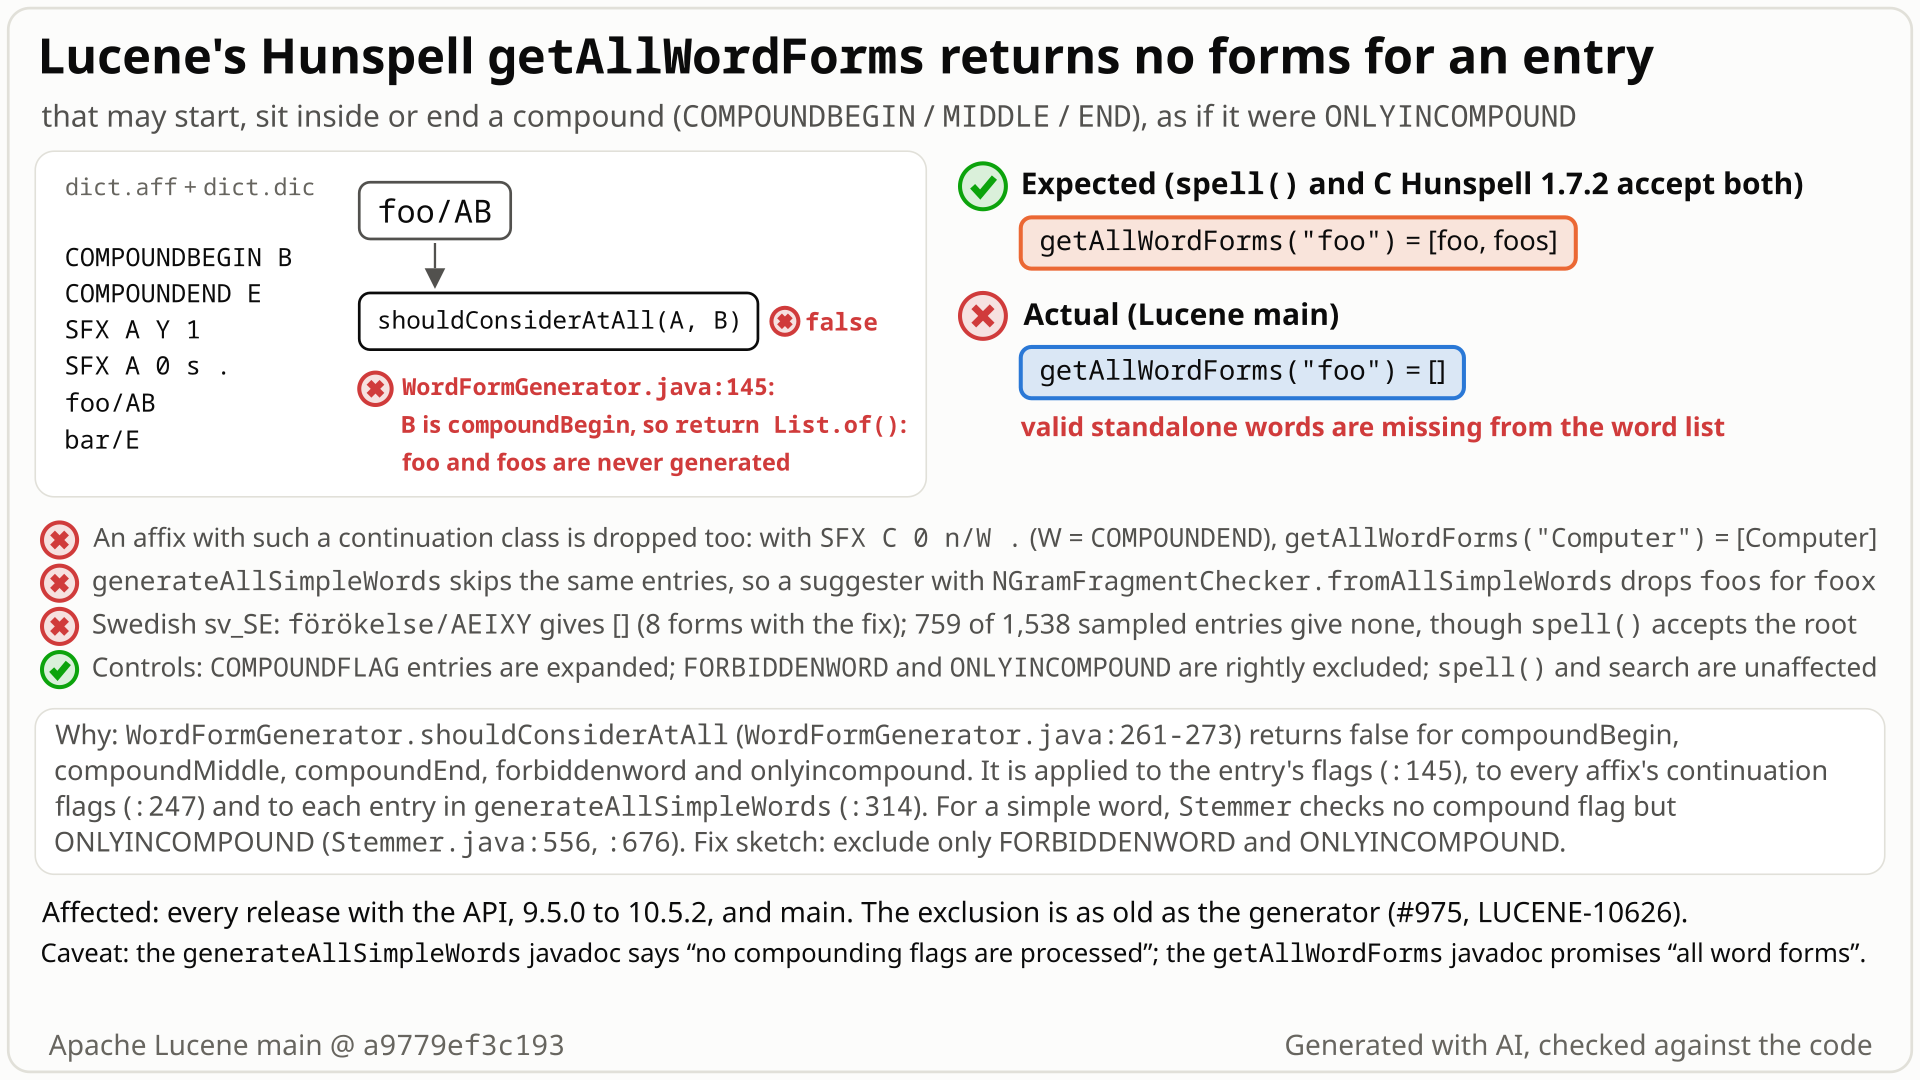
foo/AB dictionary: spell() accepts foo, foos and foobar, but getAllWordForms("foo") is [], because shouldConsiderAtAll treats COMPOUNDBEGIN like ONLYINCOMPOUND; the Computer/C case loses Computern the same way. Select the still to open it at full size. Generated with AI, checked against the code.- You load a dictionary with
COMPOUNDBEGIN B, the suffix ruleSFX A 0 s .and the entryfoo/AB:footakes the suffixs, andBsaysfoomay also start a compound, such asfoobarwithbar/E(COMPOUNDEND E). - You expect
getAllWordForms("foo")=[foo, foos]: Lucene's ownspell()acceptsfoo,foosandfoobar. OnlyONLYINCOMPOUNDwould forbidfooon its own. - Instead you get
[].WordFormGenerator.shouldConsiderAtAll(WordFormGenerator.java:261-273) treats the three position flags likeONLYINCOMPOUNDandFORBIDDENWORD, so the entry yields nothing. The same entry withoutBgives[foo, foos]. - Affixes are dropped the same way: with
SFX C 0 n/W .andCOMPOUNDEND W,getAllWordForms("Computer")=[Computer], withoutComputern, whichspell()accepts and Lucene's owngermancompoundingtest fixture lists as correct. - No error is raised. Over the whole current Swedish dictionary,
generateAllSimpleWordsreturns 483,150 distinct forms instead of 958,540 (Danish: 440,159 instead of 1,037,591), andgetAllWordForms("förökelse")is[]instead of 8 forms.
Applications that call Lucene's opt-in Hunspell dictionary-tooling API (getAllWordForms, generateAllSimpleWords, NGramFragmentChecker.fromAllSimpleWords) with a dictionary that uses compound-position flags, such as Swedish or Danish. Word lists silently miss about half (Swedish) to nearly 60% (Danish) of the valid forms, and a suggester with such a fragment checker can miss suggestions. spell(), stemming, HunspellStemFilter and search do not use this code.
Mechanism, terms and numbers599 words
In a Hunspell dictionary, COMPOUNDBEGIN, COMPOUNDMIDDLE and COMPOUNDEND mark words that may also be the first, middle or last part of a compound; the word stays a normal word on its own, and Lucene's spell() accepts it. ONLYINCOMPOUND is the flag that forbids standalone use. Lucene's word-form generator (Hunspell.getAllWordForms, WordFormGenerator.getAllWordForms, generateAllSimpleWords, and through it NGramFragmentChecker.fromAllSimpleWords) treats the three position flags like ONLYINCOMPOUND and FORBIDDENWORD: an entry that carries one yields no forms, and an affix whose continuation class carries one is dropped with everything derived from it. With COMPOUNDBEGIN B, SFX A 0 s . and foo/AB, getAllWordForms("foo") is [] instead of [foo, foos]. Over the current Swedish dictionary generateAllSimpleWords returns 483,150 distinct forms on main and 958,540 with a one-line fix; for Danish 440,159 and 1,037,591. The cause is WordFormGenerator.shouldConsiderAtAll (WordFormGenerator.java:261-273 on main a9779ef3c193). Every release from 9.5.0 through 10.6.0 (10.6.0 by reading) and main is affected. spell(), stemming, HunspellStemFilter, indexing and search do not use this code; suggestions change only for a suggester with a fragment checker built by NGramFragmentChecker.fromAllSimpleWords.
- Entry: a line of the
.dicfile.foo/ABhas the stemfooand the flagsAandB. - Affix rule:
SFX A 0 s .says that entries with flagAtake the suffixs(foos). - Continuation class: the flags an affix gives to the word it creates.
SFX C 0 n/W .givesWtoComputern. - Position flags:
COMPOUNDBEGIN,COMPOUNDMIDDLE,COMPOUNDEND(the manual's heading saysCOMPOUNDLAST; dictionaries and both parsers useCOMPOUNDEND). hunspell(5): words with them "may be first elements in compound words" (middle, last). They add a permission; they take nothing away. ONLYINCOMPOUND: the flag for parts that are "not correct as a word by itself".FORBIDDENWORDmarks non-words.
WordFormGenerator.shouldConsiderAtAll(WordFormGenerator.java:261-273) returns false if a flag set contains any of five flags:compoundBegin,compoundMiddle,compoundEnd,forbiddenword,onlyincompound.- It is applied to the entry's flags (
:145,return List.of();), soHunspell.getAllWordFormsand bothWordFormGenerator.getAllWordFormsoverloads return nothing for that entry; to the continuation flags of every affix (:246-254), so the affixed form and everything derived from it are dropped; and to each entry ingenerateAllSimpleWords(:313-314). - Only two of the five belong there. Of the compound-related flags, Lucene's
Stemmerchecks onlyONLYINCOMPOUNDfor a simple word, on the affix (Stemmer.java:556) and on the root (:676); the position flags are required only for compound parts (WordContext.java:49-60). Sospell()andanalyzeSimpleWord()accept the words the generator leaves out. - The generic
COMPOUNDFLAG, which also only permits compounding, is not in the list:foo/AZwithCOMPOUNDFLAG Zgives[foo, foos],foo/ABwithCOMPOUNDBEGIN Bgives[].
| main | with the fix | |
|---|---|---|
foo/AB, COMPOUNDBEGIN B: getAllWordForms("foo") | [] | [foo, foos] |
Computer/C, SFX C 0 n/W ., COMPOUNDEND W: getAllWordForms("Computer") | [Computer] | [Computer, Computern] |
sv_SE getAllWordForms("förökelse") (entry förökelse/AEIXY) | [] | 8 forms, förökelse to förökelses |
sv_SE generateAllSimpleWords, distinct forms | 483,150 | 958,540 |
da_DK getAllWordForms("syreregn") | [syreregn] | [syreregn, syreregnen, syreregnens, syreregns] |
da_DK generateAllSimpleWords, distinct forms | 440,159 | 1,037,591 |
In Danish most damage is on the affix side: common suffixes such as the definite singular SFX 2 0 en/34 [^e] and the genitive SFX 10 0 s/34 [^sxz] carry COMPOUNDEND 34 in their continuation class. The fix adds 475,390 (sv_SE) and 597,432 (da_DK) forms and removes none: main misses 49.6% and 57.6% of the forms the fix generates.
Exposure and likelihood233 words
- Who is hit. Callers of
Hunspell.getAllWordForms, bothWordFormGenerator.getAllWordFormsoverloads,generateAllSimpleWords, and through itNGramFragmentChecker.fromAllSimpleWords, with a dictionary that puts a position flag on ordinary entries or on affix continuation classes withoutONLYINCOMPOUND. The API exists for dictionary editing and word lists (LUCENE-10626, "add tools to aid dictionary editing"). Deterministic; which words are hit depends only on the dictionary. - How much. Whole current dictionaries: sv_SE 483,150 distinct forms on main vs 958,540 with the fix; da_DK 440,159 vs 1,037,591, so main misses 49.6% (sv_SE) and 57.6% (da_DK) of the forms. Earlier samples by independent verifiers found about half of the sv_SE entries with no forms (759 of 1,538 entries; 1,029 of 2,000 roots). The finder also reports 102 of 3,000 de_DE_frami roots with missing hyphen forms such as
Balkan-, and none in fr, lb and nb_NO (not re-run). - Fragment checker. A suggester built with
withFragmentChecker(NGramFragmentChecker.fromAllSimpleWords(...))lacks the n-grams of the missing words and can drop valid suggestions: forfoo/SX(COMPOUNDBEGIN X) plusqux/S,suggest("foox")gives[foo, foos]without the checker and[foo]with it; the fix restores[foo, foos]. That javadoc already warns that compounds can be missed, so this is secondary. - Not affected:
spell,getRoots,analyzeSimpleWord,suggestwithout a fragment checker,Stemmer,HunspellStemFilter, indexing and search.compress()was not shown to be affected. - Since 9.5.0, the API's first release.
The test shows that Hunspell.getAllWordForms("foo") returns nothing for the entry foo/AB when B is the COMPOUNDBEGIN flag, although spell() accepts foo and foos.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.hunspell;

import java.io.ByteArrayInputStream;
import java.nio.charset.StandardCharsets;
import java.util.List;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestWordFormsCompoundBeginEntry extends LuceneTestCase {

  public void testCompoundBeginEntryHasStandaloneForms() throws Exception {
    String aff = "COMPOUNDBEGIN B\nSFX A Y 1\nSFX A 0 s .\n";
    String dic = "1\nfoo/AB\n";
    Hunspell h =
        new Hunspell(
            new Dictionary(
                new ByteBuffersDirectory(),
                "dict",
                new ByteArrayInputStream(aff.getBytes(StandardCharsets.UTF_8)),
                new ByteArrayInputStream(dic.getBytes(StandardCharsets.UTF_8))));
    // Expected [foo, foos] (spell() accepts both; only ONLYINCOMPOUND forbids them); actual [].
    assertEquals(
        List.of("foo", "foos"),
        h.getAllWordForms("foo").stream().map(AffixedWord::getWord).sorted().toList());
  }
}
# in a copy of this finding's repro folder (repro/LFV-639/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.hunspell.TestWordFormsCompoundBeginEntry
- Expected vs actual
- Expected, per the getAllWordForms javadoc ("all word forms"):
[foo, foos]. Actual:[].
More files, environment, full output35 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[foo, foos]> but was:<[]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.hunspell.TestWordFormsCompoundBeginEntry.testCompoundBeginEntryHasStandaloneForms(TestWordFormsCompoundBeginEntry.java:38)- hunspell(5): words with
COMPOUNDBEGIN"may be first elements in compound words";ONLYINCOMPOUNDis for parts "not correct as a word by itself". - Lucene's own
spell()accepts the dropped words, and its test oraclecheckGoodSugWordsAreGeneratedfails on a minimal fixture:[foo, foos]not generated. - The
getAllWordFormsjavadoc promises "all word forms", andCOMPOUNDFLAG, which also only permits compounding, is expanded.
The full argument288 words
- The format. hunspell(5) (1.7.2,
man/hunspell.5:435-447): "Words signed with COMPOUNDBEGIN (or with a signed affix) may be first elements in compound words"; COMPOUNDLAST (the heading's name forCOMPOUNDEND, which the manual's own example and both parsers use) and COMPOUNDMIDDLE are worded the same. ONLYINCOMPOUND: "Suffixes signed with ONLYINCOMPOUND flag may be only inside of compounds ... Note: also valuable to flag compounding parts which are not correct as a word by itself." - Lucene's fixture.
germancompounding.aff:20-21: "Hint: ONLYINCOMPOUND is not required everywhere, but the checking will be a little faster with it." Its.goodlist containsComputern, built through a COMPOUNDEND continuation (SFX C 0 n/WD .), which the generator does not produce. - The API. "Generate all word forms for all dictionary entries with the given root word" (
Hunspell.java:334-336,WordFormGenerator.java:117-118), with no exclusion stated. - Lucene's test oracle.
TestSpellChecking.checkGoodSugWordsAreGenerated(TestSpellChecking.java:357-376, called for fixtures that expand completely and need no input cleaning,:324-327) requires every lowercase.goodword thatanalyzeSimpleWordanalyzes to be generated. On a minimal fixture (foo/AB,COMPOUNDBEGIN B) it fails with "Some *.good/sug words weren't generated: [foo, foos]"; plain and ONLYINCOMPOUND controls pass; all pass with the fix. No existing fixture exposes the gap: ingermancompoundingthe missedComputernis capitalized and the check skips capitalized words (:372); Hunspell's own2999225andopentaal_*fixtures list only compounds in.good; other position-flag fixtures escape for fixture-specific reasons. - Other expansion code. C Hunspell's
AffixMgr::expand_rootwordand Lucene'sGeneratingSuggester.hasCompatibleFlags(GeneratingSuggester.java:256-265) skip only NEEDAFFIX, CIRCUMFIX and ONLYINCOMPOUND, never the position flags. - History. The five-flag list is in the first version of the class (#975), uncommented; "compound" appears nowhere in its review or issue comments.
The devil's-advocate check224 words
The case for "deliberate scope limit": the exclusion was written on purpose in #975 and kept by the same author in #11904; #11909 added generateAllSimpleWords with the javadoc "Only "simple" words are returned, no compounding flags are processed" (WordFormGenerator.java:297); NGramFragmentChecker.fromAllSimpleWords warns that compounding languages can miss n-grams; TestSpellChecking builds n-gram checkers only when compoundRules, compoundBegin and compoundFlag are all unset (TestSpellChecking.java:287-294); AffixedWord is "the analysis result of a simple (non-compound) word".
Why it fails for getAllWordForms: these are simple words (no compound is formed), and spell() and analyzeSimpleWord() accept them as such; "no compounding flags are processed" most naturally means that no compounding is done, and it documents generateAllSimpleWords, not getAllWordForms; the list is inconsistent (COMPOUNDFLAG is expanded); and returning nothing for about half of a language's ordinary nouns is an unlikely goal for a dictionary-editing tool. "Equivalent to unmunch" supports neither side: C unmunch reads only PFX, SFX and FULLSTRIP lines and ignores all compound, ONLYINCOMPOUND and FORBIDDENWORD directives. The independent reproducer and the reviews by a model from another family rated the intended-behaviour argument moderate, the devil's advocate found it does not hold for getAllWordForms, and the adjudication confirmed the bug with this caveat. The exclusion looks deliberate; if maintainers keep it, the fallback is to document it on getAllWordForms.
Recommended Exclude only FORBIDDENWORD and ONLYINCOMPOUND (validated)
Let shouldConsiderAtAll exclude only FORBIDDENWORD and ONLYINCOMPOUND (+2/-5 in WordFormGenerator.java). Validated: the repro passes; analysis-common: 1,913 tests, 0 failures. Swedish and Danish output roughly doubles; spell() rejects 0.19% and 0.56% of the added forms, partly through a separate generator bug whose fix can land with this one.
private boolean shouldConsiderAtAll(char[] flags) {
  for (char flag : flags) {
    // COMPOUNDBEGIN/MIDDLE/END only allow compounding; ONLYINCOMPOUND forbids standalone use
    if (flag == dictionary.forbiddenword || flag == dictionary.onlyincompound) {
      return false;
    }
  }
  return true;
}
All options and trade-offs3 options · 615 words
One option was built and validated in a scratch worktree of a9779ef3c193; the other two are fallbacks.
Remove the three position flags from shouldConsiderAtAll (WordFormGenerator.java:261-273). In a plain WordFormGenerator every affixed form must still pass the existing sanity check canStemToOriginal (:184-217), which runs Lucene's stemmer in the simple-word context; the bare entry is not checked that way but is still skipped for NEEDAFFIX (:156-159); no compounds are generated. NGramFragmentChecker.processNGrams turns the sanity check off on purpose ("overgenerate a bit", NGramFragmentChecker.java:130-135), so on that path the newly reached forms are not checked at all. Optional: reword the generateAllSimpleWords javadoc (:297) to "no compounds are generated".
private boolean shouldConsiderAtAll(char[] flags) {
  for (char flag : flags) {
    // COMPOUNDBEGIN/MIDDLE/END only allow compounding; ONLYINCOMPOUND forbids standalone use
    if (flag == dictionary.forbiddenword || flag == dictionary.onlyincompound) {
      return false;
    }
  }
  return true;
}
Trade-offs
- More output, more time. About 2x (sv_SE) and 2.4x (da_DK) as many forms; single runs of
generateAllSimpleWordstook 2.0 s vs 3.4 s (sv_SE) and 2.6 s vs 8.1 s (da_DK), not a benchmark. Still bounded by the dictionary and interruptible throughcheckCanceled. - It exposes the generator's other soundness gaps on newly reached entries.
spell()rejects 885 of the 475,390 added sv_SE forms (0.19%; all capitalized or starting or ending with-, kinds stock already emits: 877 such forms on stock) and 3,336 of the 597,432 added da_DK forms (0.56%; stock emits 4,389). Together with the candidate fix of the sibling bug LFV-638 (the sanity check accepts any affix path back to the stem), 2,709 remain in da_DK; for exampleabscess(abscesplusSFX 7 0 s/11,2,8,35,34 s, whose continuation has NEEDAFFIX8and COMPOUNDEND34) is emitted by this fix alone and removed by the combined fix. The rest were not classified further. A maintainer may prefer to land both together. - Compatibility. The output of the dictionary-tooling API changes, and so do the suggestions of a suggester with an
NGramFragmentChecker.fromAllSimpleWordsfragment checker (suggest("foox"):[foo]on main,[foo, foos]with the fix); no index or analysis change.
What the checks validated
- Stock: the repro fails 3 of 4 with assertions on and off; the hunspell test package (47 classes, 162 tests with the repro) fails only those 3.
- Fix: the repro passes 4 of 4 with assertions on and off; the hunspell package passes (162 tests, 0 failures, 13 skipped: three suites need external dictionaries); the whole
lucene/analysis/commontest task, repro included: 340 classes, 1,913 tests, 0 failures, 18 skipped;ecjLint,checkGoogleJavaFormat,forbiddenApisMainandforbiddenApisTestpass;tidychanges nothing. - Hunt runs with the same change shadowed: the finder's, the independent reproducer's (9 of 9), the root-cause reviewer's and the other cross-model reviewers' tests pass; Lucene's fixture oracle passes on the devil's advocate's fixtures; 125 Hunspell 1.7.2 test fixtures (131 minus the 6 expected failures), run one by one through that oracle by the devil's advocate's own harness, give identical outcomes with and without the fix (
TestHunspellRepositoryTestCasesitself reports "No runnable methods" under plain JUnit). - Whole-dictionary probe (sv_SE, da_DK): forms added, none removed; numbers above.
Say in the getAllWordForms and generateAllSimpleWords javadocs that entries and affixes with COMPOUNDBEGIN, COMPOUNDMIDDLE or COMPOUNDEND produce no forms.
Trade-offs
Leaves the disagreement with spell(), COMPOUNDFLAG and checkGoodSugWordsAreGenerated, and the empty results for Swedish and Danish. Not validated.
For example a WordFormGenerator setting that includes or skips compound-position entries.
Trade-offs
More API for a behaviour for which no explicit rationale was found; the recommended option is simpler. Not validated.
No use of these APIs was found in Elasticsearch, OpenSearch or Solr, so the effect downstream is limited to tools that build word lists or n-gram fragment checkers with Lucene's generator.
Differential testing of Lucene's word-form generator, spell() and analyzeSimpleWord() against C Hunspell 1.7.2 on 4,000 generated micro-dictionaries and 1,069 fixture cases. This exclusion was the largest single source of missing forms: 607 misses on stock, 64 with this fix alone. A public-API JUnit then reproduced it on the stock jar.
The method in full140 words
Method: cross-implementation differential testing (non-formal tier). Hunt unit "Hunspell word-form generator vs munch/unmunch" compared Lucene getAllWordForms, spell and analyzeSimpleWord with C Hunspell 1.7.2 (spell, stem) and the unmunch tool.
- Inputs: 4,000 grammar-built micro-dictionaries (3 grammar families, several seeds; per dictionary every candidate word reachable by at most 3 affix rules) and 1,069 per-root cases from the Hunspell 1.7.2 and Lucene test fixtures (
germancompounding,2999225,opentaal_cpdpat,opentaal_cpdpat2andopentaal_keepcaseshow it). - Root causes were separated with switchable shadow fixes: with only this fix, generator misses of words that
spell()accepts and attributes to the root fell from 607 to 64. - The finder then wrote a two-test public-API JUnit that fails on the stock jar; an independent reviewer from another model family (OpenAI GPT-5.6) reviewed it in executed mode before the candidate was filed.
No prior report found (2026-10-27): 125 tool queries over GitHub, the mailing lists, JIRA and downstream trackers, about 30 manual searches including every hunspell issue and PR since 2022-06, and 15 web searches. The closest text is the API author's own javadoc about compounds, not a report. Not fixed upstream.
Searches5 searches
No report of this defect was found. The nearest text is in-code documentation by the API's author.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs, commits; Elasticsearch, OpenSearch, Solr trackers; dev@, java-user@, issues@, commits@; JIRA archive; web | 2026-10-27 | scripted prior-report search, 3 runs, 125 queries (WordFormGenerator, getAllWordForms, shouldConsiderAtAll, generateAllSimpleWords, NGramFragmentChecker, the flag names, unmunch, germancompounding, Computern, sv_SE, da_DK) | no report |
| GitHub, manual | 2026-10-27 | about 30 searches; title read of all 49 hunspell issues and PRs since 2022-06-01 (the API's whole life) and of the 14 hunspell items mentioning "compound" | no report |
| Related threads (read in full) | 2026-10-27 | #975, #11662, #11904, #11909, #13429, #10738, #10760, #14741; a StackOverflow thread on getAllWordForms | #975 / #11662 introduced the exclusion with no stated reason; #11909's javadoc and the NGramFragmentChecker warning note a compound limitation; none reports the missing forms |
| Open PRs | 2026-10-27 | open hunspell PRs and the newest WordFormGenerator commits upstream | only #16422 (Dictionary directive parsing), which does not touch WordFormGenerator |
| Web | 2026-10-27 | 15 searches, top 10 results each | an outside Go port copies the exclusion without comment |
Present since the generator was added in #975 (d537013e708, merged 2022-07-05; first release 9.5.0). The finder's test fails on all 26 releases from 9.5.0 to 10.5.2 and on main; 9.4.2 and older lack the API. Not a regression and not fixed upstream.
Versions tested5 rows
Introduced by apache/lucene#975 "LUCENE-10626: Hunspell: add tools to aid dictionary editing" (by @donnerpeter, approved by @dweiss), merged to main 2022-07-05 as d537013e708; it reached 9.x as the cherry-pick 3b763af12f5 (committed 2023-01-13), hence 9.5.0. The five-flag check is in the first version of WordFormGenerator.java. 682e5c94e83 (#11904, 2022-11-07) rewrote it over the same five flags; 6fbc5f73c39 (#11909, 2022-11-11) added generateAllSimpleWords with the same check. The method body is byte-identical in all 26 releases and on main.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test fails 3 of 4 (gradle and classpath runner, -ea and -da); the fix passes |
| 9.5.0 to 10.5.2 (26 releases) | affected | the finder's test fails 2 of 2 on every release; this doc's test fails 3 of 4 on 9.5.0, 9.12.3 and 10.5.2 |
| 9.5.0 and 10.5.2 with the three flags removed | shadow fix | the finder's test passes 2 of 2; the independent reproducer's 9 of 9 |
| 9.3.0 to 9.4.2 | no API | compile error: getAllWordForms and AffixedWord are absent; spell() already accepts the words on 9.4.2 |
upstream main a95c754ee00, branch_10x, branch_10_6 | source only | the same method, not executed |
An independent reproducer, a root-cause reviewer and an intended-behaviour devil's advocate reproduced it with their own tests; two further executed reviews by a model from another family (OpenAI GPT-5.6) rated it real; an adjudication and a credibility audit re-ran it; this doc's gradle runs reproduce it on a9779ef3c193 and validate the fix.
Checks and verdicts352 words
Every check ran on main a9779ef3c193 (the cross-model reviews on ea57360912ed, whose hunspell package is identical) with JDK 25.0.3.
| Check | Verdict | What it found |
|---|---|---|
| Independent reproducer | real | Own 9-test JUnit fails 6 of 9 on main, 10.5.2 and 9.12.3, 3 controls pass; shown on the germancompounding fixture and on sv_SE (förökelse gives []; 759 of 1,538 sampled entries give no forms); C Hunspell accepts the words; compress() not shown to be affected (one example unchanged). |
| Root-cause reviewer (the cross-model review, OpenAI GPT-5.6) | real, root cause agrees | Own test fails 6 of 8, ONLYINCOMPOUND and FORBIDDENWORD controls pass; a trace shows the check rejecting exactly the position flag; with the fix 8 of 8 pass. |
| Intended-behaviour devil's advocate | real, moderate-high | Lucene's own checkGoodSugWordsAreGenerated fails on minimal valid fixtures and passes with the fix; 125 Hunspell fixtures unchanged by the fix; on 2,000 sv_SE roots 1,029 give no forms (8 with the fix). |
| Cross-model reviews (refute and intended lenses) | real, high | Each wrote and ran its own test (moss/mossish, clear/clearly; begin, base/basex), also failing on 10.5.2 and 9.12.3; intended-behaviour argument rated moderate. |
| Adjudication | confirmed, high | Re-ran the reproducer's test with a new seed (-ea, -da: 9 run, 6 failed; fix 9 of 9); kept the intent caveat. |
| Registration check and credibility audit | keep | Fresh-seed re-runs on main fail with the same messages; the code was re-read. |
| Fact checks of this doc | bug real; wording corrected | An independent fact check re-ran the gradle repro (3 of 4 fail on stock, 4 of 4 pass with the fix, assertions on and off), the classpath runs and the whole-dictionary probe (every count matches), and re-read every cited line; a reviewer from another model family (OpenAI GPT-5.6) re-checked the brief. Their precision findings are fixed in this version. |
| This doc | reproduced, fix validated | New 4-test repro via gradle (3 fail on stock, 0 with the fix), analysis-common suite with the fix, whole-dictionary probe on sv_SE and da_DK. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 528 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,496 words
- Registry title
- Hunspell getAllWordForms and generateAllSimpleWords return no forms for an entry with a COMPOUNDBEGIN, COMPOUNDMIDDLE or COMPOUNDEND flag and drop every affix whose continuation class has one, although spell() accepts those words on their own: with 'COMPOUNDBEGIN B' and foo/AB, getAllWordForms("foo") = [] instead of [foo, foos] (Swedish sv_SE: förökelse/AEIXY gives [])
- Area
- analysis / hunspell (WordFormGenerator: getAllWordForms, generateAllSimpleWords)
- Priority
- Low, rank 459: GetAllWordForms deterministically returns nothing for about half of Swedish and Danish entries, but only through the rarely used dictionary-tooling API.
- Impact class
- silent wrong results
- Impact note
- Only applications that call Lucene's opt-in Hunspell dictionary-tooling API (Hunspell.getAllWordForms, both WordFormGenerator.getAllWordForms overloads, generateAllSimpleWords, and through it NGramFragmentChecker.fromAllSimpleWords) are hit, and only with a dictionary that puts COMPOUNDBEGIN/MIDDLE/END on ordinary entries or on affix continuation classes without ONLYINCOMPOUND; for them the word-form list silently misses valid standalone words, and for about half of the sampled Swedish sv_SE entries it is empty (the independent reproduction: 759 of 1,538 sampled entries; the intended-behaviour check: 1,029 of 2,000 roots) [exec]; the finder also reports 1,919 of 3,000 sampled Danish da_DK roots and 102 of 3,000 de_DE_frami roots (hyphenated forms such as Balkan-) with missing forms, and none in fr, lb and nb_NO (not re-checked by the verifiers); an n-gram fragment checker built with fromAllSimpleWords lacks those words and can drop valid suggestions (the independent reproduction: suggest("foox") gives [foo] instead of [foo, foos]) [exec]; spell-checking, stemming, HunspellStemFilter, indexing and search are not affected, since they never call WordFormGenerator [read]; compress() was not shown to be affected; no scale is needed; every release from 9.5.0 through 10.6.0 (10.6.0 by reading) and main [exec].
- Summary
- You load a Hunspell dictionary in which an ordinary entry carries a compound-position flag, for example 'COMPOUNDBEGIN B', 'SFX A 0 s .' and the entry foo/AB (foo may also start a compound such as foobar), and ask Hunspell.getAllWordForms("foo") for all forms of that entry. You expect [foo, foos]: Lucene's own spell() accepts both and analyzeSimpleWord() attributes them to foo/AB, as C Hunspell 1.7.2 also does, because COMPOUNDBEGIN/MIDDLE/END only allow a word to take part in compounds while ONLYINCOMPOUND is the flag that forbids it on its own. Instead you get [], because WordFormGenerator.shouldConsiderAtAll (WordFormGenerator.java:261-273) rejects the three compound-position flags together with FORBIDDENWORD and ONLYINCOMPOUND, both for the entry (so the entry yields nothing) and for affix continuation classes (so with 'SFX C 0 n/W' and W = COMPOUNDEND, getAllWordForms("Computer") never yields Computern, a word in Lucene's own germancompounding .good list); generateAllSimpleWords skips the same entries.
- Introduced
- d537013e70872015364c745e5f320727efc034b7 (apache/lucene#975 'LUCENE-10626 Hunspell: add tools to aid dictionary editing', by donnerpeter, approved by dweiss; issue LUCENE-10626, migrated as #11662), merged to main 2022-07-05; on branch_9x as the cherry-pick 3b763af12f576b8b8120e98ae38b7a67461a99e8 (committed 2023-01-13), which is how it reached 9.5.0 [read: git log -S and git log -L show shouldConsiderAtAll with the same five-flag exclusion in the first version of WordFormGenerator.java (lines 227-233 there, applied at :132 to the entry flags and at :213 to affix continuation flags), without a comment and not discussed in the review; 682e5c94e833 (#11904 '[hunspell] speed up WordFormGenerator', 2022-11-07) rewrote it as a char[] loop over the same five flags, which is why git blame on main points there; 6fbc5f73c39 (#11909, 2022-11-11) added generateAllSimpleWords, which applies the same check to every entry] [exec at release granularity: 9.3.0-9.4.2 lack the API (compile error), 9.5.0 fails; removing only the three compound-position flags from the release's own shouldConsiderAtAll (shadow source) makes 9.5.0 and 10.5.2 pass]. Not a regression: the exclusion is as old as the generator, and spell() already accepted the words on 9.4.2 and 9.5.0 (follow-up spell-probe), so generation and spell-checking have disagreed on them since the generator's first release. (2022-07-05 (merged to main); 2023-01-13 (branch_9x cherry-pick 3b763af12f5))
- First affected version
- 9.5.0 [exec] (the first release with Hunspell.getAllWordForms and WordFormGenerator; first 10.x release 10.0.0 [exec]); 9.4.2 and older are unaffected only because the API is absent (the repro is a compile error on 9.3.0, 9.4.0, 9.4.1 and 9.4.2 [exec])
- Affected versions
- every release from 9.5.0 through 10.6.0 (26 releases through 10.5.2, and 10.6.0 by reading) and main a9779ef3c193; never fixed. [exec] the finder's JUnit fails 2/2 at the two getAllWordForms assertions on all 26 releases and main with -ea, and with -da on 9.5.0, 9.12.3, 10.0.0, 10.5.2 and main (32 failing runs, follow-up); the independent reproduction's JUnit fails the same 6 of 9 tests (its 3 controls pass) on main (-ea, -da), 9.5.0, 9.12.3, 10.0.0 and 10.5.2; the GPT reviewers' own tests fail on the previous main ea57360912ed (identical hunspell code), the refute- and intended-lens tests also on 10.5.2 and 9.12.3. [read] the shouldConsiderAtAll method body is byte-identical in all 26 releases and on main, and unchanged on upstream main a95c754ee00, branch_10x and branch_10_6 (source check only, not executed). Not affected: 9.4.2 and older (no API). All runs on aarch64 with JDK 25.0.3.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record verdict new): a scripted prior-report search in three runs (125 queries over apache/lucene issues and PRs, commit messages, the Elasticsearch, OpenSearch and Solr trackers, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web; 0 errors), about 30 manual GitHub searches including a title read of every apache/lucene hunspell issue and PR created since 2022-06-01 (49, the API's whole life) and of all 14 hunspell items mentioning 'compound', the full threads of #975, #11662, #11904, #11909, #13429, #10738, #10760 and #14741, 15 web searches and a StackOverflow thread; the finder's, the independent reproduction's and the intended-behaviour check's searches agree. Closest items, none a report of this bug: #975 / #11662 (LUCENE-10626), which introduced the exclusion with no stated reason and no review comment about it; #11909, whose generateAllSimpleWords javadoc says 'no compounding flags are processed' and whose NGramFragmentChecker.fromAllSimpleWords javadoc warns that n-grams from compounds can be missed (the author's own note of a compound limitation for whole-dictionary enumeration, not a defect report, and silent about getAllWordForms); #10738, #10760, #10749 and #12220 (spell-checker compounding work, 2021-2023); an outside Go port copies the same exclusion without comment. Not fixed upstream: shouldConsiderAtAll is unchanged on upstream main a95c754ee00 (newest WordFormGenerator commit 3a63f5e0723, 2026-06-29, a dependency bump), and the only open hunspell PR (#16422, Dictionary directive parsing) does not touch WordFormGenerator.
- Lucene commit tested
- main
a9779ef3c193(gradle in a clean scratch worktree, and the hunt's classpath runner with-eaand-da); through the classpath runner also 10.5.2, 9.12.3 and 9.5.0 (9.4.2: compile error, the API is absent). The hunt's own test ran on all 26 releases from 9.5.0 to 10.5.2. Whole-dictionary probe on the LibreOffice sv_SE (4f1df64b2e8e) and da_DK (084a2f734edc) dictionaries, 2026-10-28.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordFormGenerator.java:117-133 (at a9779ef3c193) (getAllWordForms javadoc 'Generate all word forms for all dictionary entries with the given root word' and 'equivalent to "unmunch"'), :135-148 (flags overload; :145 'if (!shouldConsiderAtAll(encodedFlags)) return List.of();'), :233-258 (expand; :247 'if (shouldConsiderAtAll(append))' drops an affix whose continuation flags contain one of the five), :261-273 (shouldConsiderAtAll: compoundBegin, compoundMiddle, compoundEnd, forbiddenword, onlyincompound), :294-322 (generateAllSimpleWords javadoc 'Only "simple" words are returned, no compounding flags are processed'; :314 the same check per entry)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:334-341 (at a9779ef3c193) (public getAllWordForms(String), same 'all word forms' and 'unmunch' javadoc); NGramFragmentChecker.java:75-91 (fromAllSimpleWords: 'If the language has compounds, some n-grams possible via those compounds can be missed')lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java:556 (at a9779ef3c193) and :676 (outside compounds, analysis rejects only ONLYINCOMPOUND, on affixes and on the root); WordContext.java:49-58 (requiredFlag: compound-position flags are required only for compound parts); GeneratingSuggester.java:256-265 (hasCompatibleFlags excludes only NEEDAFFIX, CIRCUMFIX and ONLYINCOMPOUND, cited by the intended-behaviour check)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestSpellChecking.java:213 (at a9779ef3c193) (doTest("germancompounding")), :326 and :357-376 (checkGoodSugWordsAreGenerated; :372 drops every .good word that is not all-lowercase, which hides Computern); germancompounding.aff:9-11 (COMPOUNDBEGIN U, COMPOUNDMIDDLE V, COMPOUNDEND W), :47-48 ('SFX C 0 n/WD .'); germancompounding.dic:3 (Computer/BC-); germancompounding.good:2 (Computern)git diff ea57360912ed a9779ef3c193 -- lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/ (empty: the GPT reviews on ea57360912ed exercised identical code)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordFormGenerator.java:117-148, (at a9779ef3c193) 233-273, 294-323; Stemmer.java:550-558, 675-678; WordContext.java:49-60; Dictionary.java:377, 441-448
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/NGramFragmentChecker.java:75-92; (at a9779ef3c193) Hunspell.java:334-342
- Why it looks unintended
Hunspell 1.7.2 man/hunspell.5:431-447 (fetched read-only 2026-10-28)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:334-336; (at a9779ef3c193) WordFormGenerator.java:117-118, 294-298; GeneratingSuggester.java:256-265; AffixedWord.java:25; NGramFragmentChecker.java:75-81lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestSpellChecking.java:287-294, (at a9779ef3c193) 324-327, 357-376; germancompounding.aff:9-11, 20-23, 47-48; germancompounding.dic:3; germancompounding.good:2
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordFormGenerator.java:150-162, (at a9779ef3c193) 184-217, 261-273, 294-298lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/NGramFragmentChecker.java:127-137 (at a9779ef3c193)
- TestWordFormsCompoundBeginEntry.java (JUnit test):
repro/LFV-639/src/org/apache/lucene/analysis/hunspell/TestWordFormsCompoundBeginEntry.java(42 lines)
Made in parallel with this doc from the probe of the foo/AB and Computer/C dictionaries (main -ea and -da, 10.5.2, 9.5.0, and main with the fix shadowed).
assets/LFV-639/bug.png(528 KB)