Hunspell affix files allow "twofold suffixes": a suffix whose continuation class allows a second suffix. Lucene follows such a chain only if both suffix classes say cross product Y, a field the format reserves for prefix + suffix combinations.
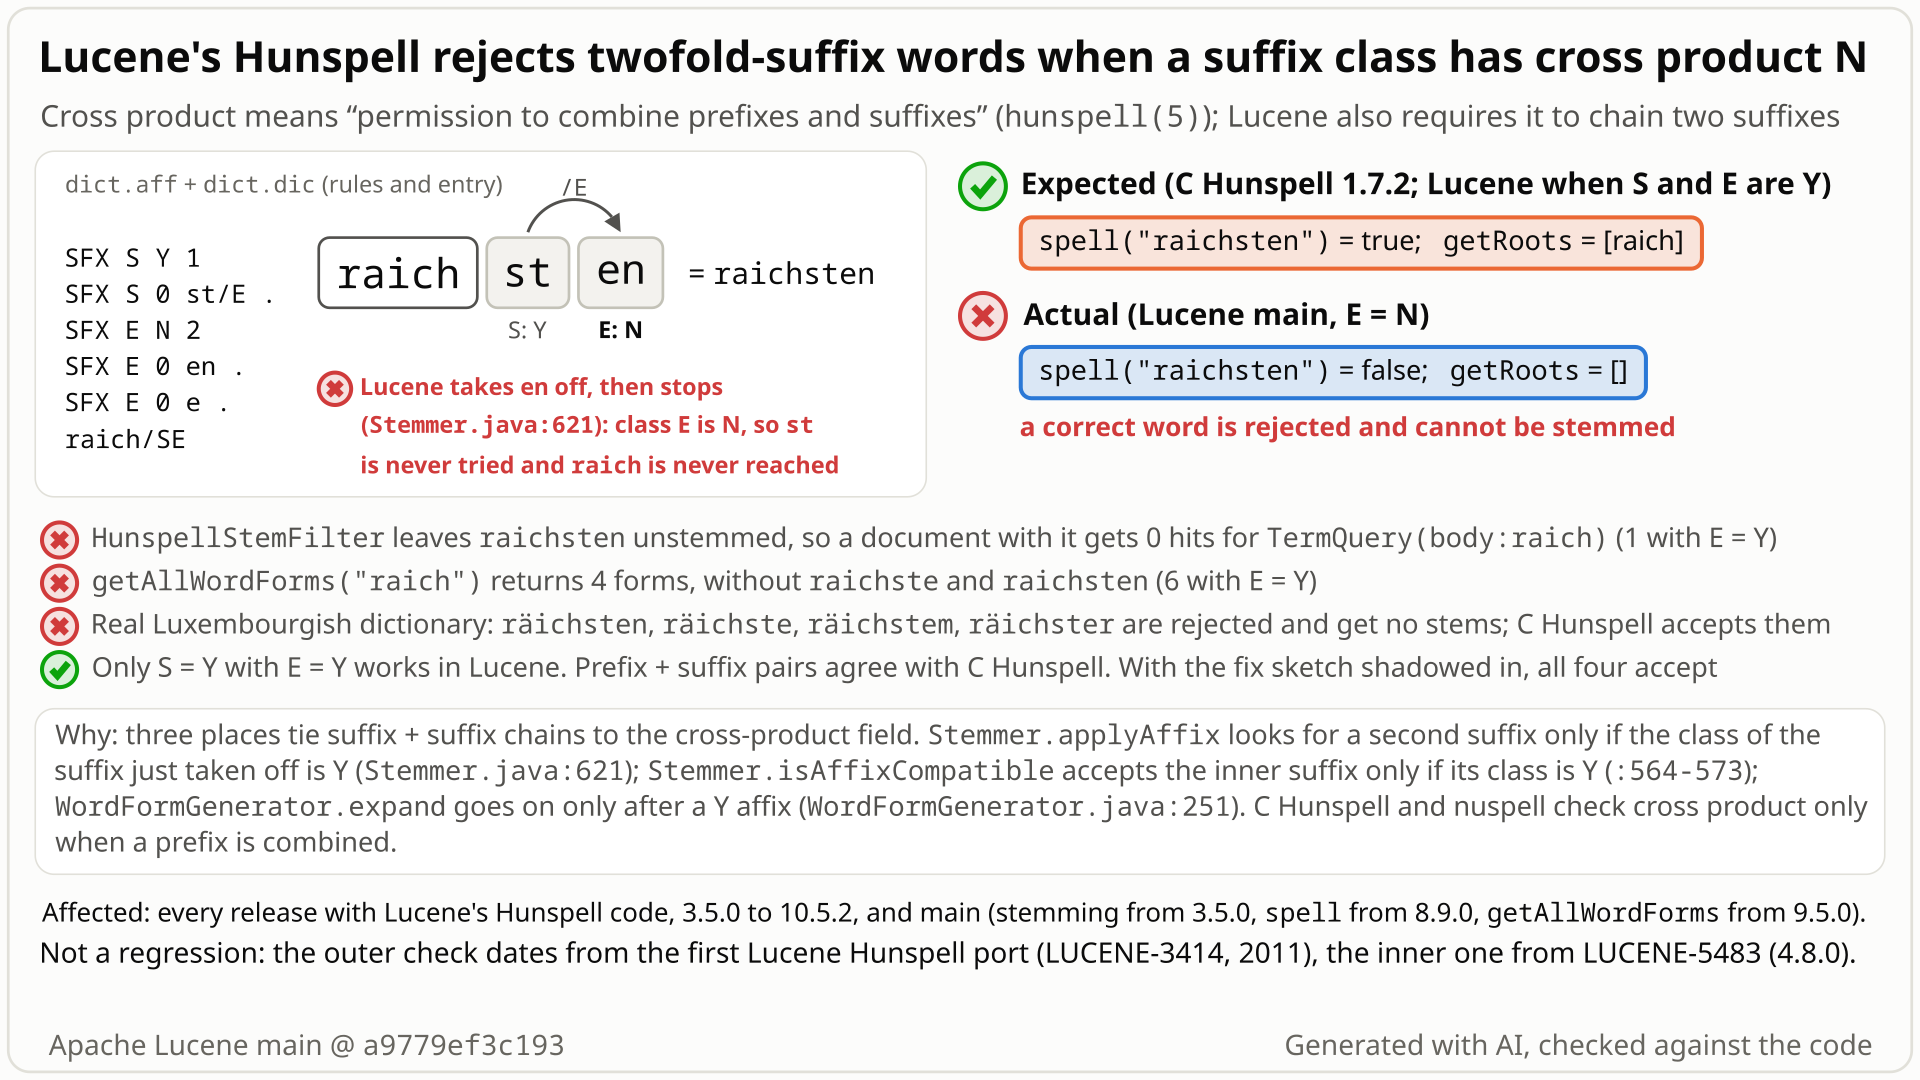
raich/SE dictionary: native Hunspell (and Lucene with both classes Y) accepts raichsten; Lucene with E = N strips en, stops at Stemmer.java:621, and rejects it. Select the still to open it at full size. Generated with AI, checked against the code.- You load a dictionary where the suffix
st(class S) allows the endingsenande(class E) through its continuation class/E, and E's header says cross productN:SFX S Y 1,SFX S 0 st/E .,SFX E N 2(en,e), entryraich/SE. Real Luxembourgish has this shape: räich + st + en = räichsten, "richest". - You expect
raichstenandraichsteto be correct with rootraich: hunspell(5) defines cross product as the "permission to combine prefixes and suffixes", there is no prefix here, and native Hunspell (1.3.2 and 1.7.2) accepts both withNorY. - Instead
spell("raichsten")is false andgetRootsreturns[]. Lucene stripsen, then never looks forst, because class E isN(Stemmer.java:621); with S =Na second check rejectsst(:564). Only S =Ywith E =Yworks. - No error is raised:
HunspellStemFilterleavesraichstenunstemmed, so a document containing it gets 0 hits for the termraich(1 with E =Y), andgetAllWordForms("raich")returns 4 forms instead of 6. - On the real Luxembourgish dictionary, at least 47,840 word forms of 13,526 distinct roots that native Hunspell 1.3.2 accepts are rejected by Lucene main, such as
räichsten,verstümmeltemandHälsercher. A small fix at three sites makes Lucene accept them.
Applications using Lucene's opt-in Hunspell module (spell-checking, HunspellStemFilter, getAllWordForms) with a dictionary whose twofold-suffix chains contain an N class. Real Luxembourgish is hit on ordinary words: correct words are flagged and stay unstemmed, so searches for the root miss them. Silent and deterministic; Elasticsearch's and OpenSearch's hunspell token filters wrap the same filter.
Mechanism, terms and numbers689 words
In a Hunspell .aff file a suffix can carry a continuation class that allows a second suffix after it ("twofold suffix stripping"). Each affix class header also has a cross-product field, Y or N, which hunspell(5) defines as the "permission to combine prefixes and suffixes". Lucene also requires it for suffix + suffix: if either suffix class of a chain says N, Hunspell.spell rejects the word, getRoots, analyzeSimpleWord and Stemmer return no stem, HunspellStemFilter leaves the token unstemmed, and getAllWordForms leaves the form out. Native Hunspell (1.3.2 and 1.7.2, in every Y/N variant tested) accepts these words. Three code sites carry the assumption (Stemmer.java:621, Stemmer.java:564, WordFormGenerator.java:251 on main a9779ef3c193). On the real Luxembourgish dictionary, from the collection Lucene's package docs point to, at least 47,840 word forms of 13,526 distinct roots that native Hunspell 1.3.2 accepts are rejected by Lucene main. All 18 releases tested from 3.5.0 to 10.5.2 fail, and the same gates are in every release since 3.5.0; nothing throws.
- Affix class: a group of
PFXorSFXrules under one flag. Its header line isSFX <flag> <cross product> <count>, for exampleSFX E N 2. - Cross product (
YorN): hunspell(5) field (2), "Cross product (permission to combine prefixes and suffixes)" (Hunspell 1.7.2man/hunspell.5:522). - Continuation class: flags after a slash on a rule,
SFX S 0 st/E .: a word that gotstmay take a suffix of class E next. hunspell(5) calls this "Twofold suffix stripping" (:921); its example isdrink/XwithSFX X 0 able/Y .andSFX Y 0 s ., giving drink, drinkable, drinkables. - Outer / inner suffix (Lucene's naming): the outer suffix is the last one applied and the first one stripped (
enin raich + st + en), the inner suffix the first one applied (st).
Dictionary.java:685parses the field per class (crossProduct = args[2].equals("Y")),:791stores it with every rule andisCrossProduct(affix)reads it back (:812-814).- Outer suffix
N: no search for the inner suffix.Stemmer.applyAffixstrips an affix, checks the stem, then decides whether to strip one more. The decision is gated on the affix just stripped:if (dictionary.isCrossProduct(affix) && recursionDepth <= 1)(Stemmer.java:621); for a suffix it then looks for "another suffix" (:630-634). With E =N, afterenis stripped fromraichsten, the search forstnever starts. - Inner suffix
N: the continuation check is never reached.Stemmer.isAffixCompatibleaccepts an inner suffix only insideif (dictionary.isCrossProduct(affix)) { ... return dictionary.hasFlag(append, prevFlag); }(:564-571) and otherwise returns false (:573). With S =N: afterenis stripped, the intermediateraichstis looked up (:262) and is not an entry; then this check refuses to stripstas the inner suffix, so the rootraichis never reached, althoughst/Ecarries the continuation flag. - The generator copies the rule.
WordFormGenerator.expandrecurses for a further affix onlyif (dictionary.isCrossProduct(affix.id))(WordFormGenerator.java:251-253), sogetAllWordFormsomits the same forms. - Native Hunspell checks cross product only when a prefix is combined:
SfxEntry::check_twosfxskips an entry onlyif ((optflags & aeXPRODUCT) != 0 && (opts & aeXPRODUCT) == 0)(Hunspell 1.7.2affentry.cxx:712, "if this suffix is being cross checked with a prefix"), and without a prefix it checks the inner suffix with optflags 0 (:753-755). nuspell, an independent C++ implementation, does the same.
With the hunspell(5) example, only X = Y, Y = Y accepts drinkables; the other three Y/N combinations give spell = false, roots = [] and getAllWordForms("drink") = [drink, drinkable], while drinkable stays accepted and drinks rejected in all four. Native Hunspell 1.3.2 accepts drinkables and stems it to drink in all four. For prefix + suffix words Lucene already agrees with native Hunspell 1.3.2 on every Y/N combination of a 4-dictionary matrix with a prefix class (S and E each Y or N, the prefix class tied to S); only the suffix chains differ.
Exposure and likelihood299 words
- Who. Users of
Hunspell.spell,suggest,getRoots,analyzeSimpleWord,HunspellStemFilter/HunspellStemFilterFactoryandgetAllWordFormswhose dictionary gives cross productNto a class in a twofold-suffix chain. No setting beyond the dictionary; deterministic; assertions on or off. - What goes wrong. No exception. Spell-checking flags correct words, and
suggestmay offer a different word (suggest("raichsten") = [raichen]in the hunt's probe). Stemming returns nothing, so the stem filter indexes and queries the surface form: in an 8-document probe index a query forraichfound 4 of 6 forms, and a query forraichstenonly itself. Every hit set was a subset of the correct one.getAllWordFormsomits the forms. - Scale on a real dictionary (Luxembourgish
lbfrom wooorm/dictionaries at8cfea406b505, the commit Lucene's regression build pins).generateAllSimpleWordsover every entry gives 293,583 distinct forms on stock and 341,573 with the fix, none lost. Of the letters-only added forms, 47,840 of 13,526 distinct roots are accepted by native Hunspell 1.3.2 (the observedhunspell -lresult), rejected by stock Lucene and accepted with the fix: 36,137 lowercase (for example superlatives and participles with adjective endings:räichsten,verstümmeltem,standardiséierten) and 11,703 capitalised (for example diminutive and feminine plurals:Hälsercher,Steenemerinne). Native-moutput on the named forms shows two suffixes, for exampleverstümmeltem st:verstümmelen po:verb is:adjective is:papa is:em; morphology was not run on all 47,840. - Other dictionaries. A static survey of 191 public
.afffiles found such chains in 8, among themlb,hu_HU,ta_IN,isandfa; onlylbwas executed. Lucene documents Hungarian as unsupported. - Downstream. The
hunspelltoken filters of Elasticsearch and OpenSearch return Lucene'sHunspellStemFilter(source read, not executed). - Since. Every release with Lucene's Hunspell code: stemming since 3.5.0,
Hunspell.spellsince 8.9.0,getAllWordFormssince 9.5.0.
The test shows that with the hunspell(5) twofold-suffix example (drink/X, SFX X 0 able/Y, SFX Y 0 s) and cross product N on class Y, Hunspell.spell("drinkables") is false, although cross product only governs prefix+suffix combinations.
package org.apache.lucene.analysis.hunspell;

import java.io.ByteArrayInputStream;
import java.nio.charset.StandardCharsets;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestTwofoldSuffixCrossProduct extends LuceneTestCase {

  public void testTwofoldSuffixWhenOuterClassHasCrossProductN() throws Exception {
    String aff = "SFX X Y 1\nSFX X 0 able/Y .\nSFX Y N 1\nSFX Y 0 s .\n";
    Dictionary dictionary =
        new Dictionary(
            new ByteBuffersDirectory(),
            "dict",
            new ByteArrayInputStream(aff.getBytes(StandardCharsets.UTF_8)),
            new ByteArrayInputStream("1\ndrink/X\n".getBytes(StandardCharsets.UTF_8)));
    // cross product only governs prefix+suffix: expected drink+able+s valid, actual rejected
    assertTrue(
        "expected spell(\"drinkables\") to be true, was false",
        new Hunspell(dictionary).spell("drinkables"));
  }
}
# in a copy of this finding's repro folder (repro/LFV-641/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.hunspell.TestTwofoldSuffixCrossProduct
- Expected vs actual
- Expected
spell("drinkables")true (as withSFX Y Y); actual false, with-eaand-da.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected spell("drinkables") to be true, was false
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
org.apache.lucene.analysis.hunspell.TestTwofoldSuffixCrossProduct.testTwofoldSuffixWhenOuterClassHasCrossProductN(TestTwofoldSuffixCrossProduct.java:19)- hunspell(5) defines the field as "permission to combine prefixes and suffixes"; native Hunspell and nuspell check it only when a prefix is involved.
- Lucene claims native behaviour:
Hunspell"can be used in place of native Hunspell"; LUCENE-5483 says recursion is "driven correctly by continuation classes". - No test or comment found says
Nblocks suffix chains; all twofold fixtures useY.
The full argument288 words
- The format's contract. hunspell(5) (Hunspell 1.7.2
man/hunspell.5:522): "(2) Cross product (permission to combine prefixes and suffixes). Possible values: Y (yes) or N (no)". Its "Twofold suffix stripping" section (:921-962) ties the second suffix to the continuation class only. A native maintainer restated the rule on hunspell/hunspell#177 (2026): "A prefix and a suffix are only combined on the same word when both the prefix rule and the suffix rule are marked with the cross-product flag Y." - Lucene claims that behaviour.
Hunspelljavadoc: "can be used in place of native Hunspell for many languages" (Hunspell.java:34-37; the listed exceptions are Hungarian, non-BMP characters and PHONE).Stemmerjavadoc: "conforms to the algorithm in the original hunspell algorithm, including recursive suffix stripping" (Stemmer.java:28-32). CHANGES for LUCENE-5483 (4.8.0): "Multi-stage affix-stripping, prefix-suffix dependencies, and COMPLEXPREFIXES now work correctly according to the hunspell algorithm ... rules for recursive affix application are driven correctly by continuation classes in the affix file" (lucene/CHANGES.txt:12545-12549); its issue #6546 "greatly refined this algorithm to match correct hunspell behavior". - No source we found documents the rule. The searches found no test, comment, CHANGES entry, issue or commit message saying
Nblocks suffix chains; no commit message in the full history contains "cross product" or "twofold". - Why tests never caught it. 12 of Lucene's 97 test
.afffiles chain two suffixes (twofold.aff, the manual's example inTestTwoFold, anddependencies.aff,compress.aff,needaffix5.affand others), all withYon both classes; no Lucene fixture and no Hunspell 1.7.2 test fixture puts anNclass in a continuation chain. - Asymmetry. For prefix + suffix words Lucene already applies the cross-product rule exactly as native Hunspell does; only suffix + suffix uses it.
The devil's-advocate check229 words
The strongest case for "intended": the gate is deliberate code from the very first Lucene Hunspell port (2011), LUCENE-5483 (2014) added the inner check, LUCENE-10626 (2022) copied it into the generator, every manual example uses Y, the Hunspell javadoc says not all languages are supported, and in 2012 the original author wrote on LUCENE-4311 (#5379) that "our implementation of Hunspell is not a port of the C/C++ app per se". So it could be read as a conservative supported subset.
Why it fails: no source gives a reason for the gate; the later, explicit intent (LUCENE-5483's issue and CHANGES entry, the Hunspell and Stemmer javadocs, LUCENE-9687 "on a par with the native C++ Hunspell") is native compatibility; the unsupported-language list is about language-specific logic, while this is generic affix semantics shown by a six-line dictionary; and keeping drinkable but dropping drinkables only because an unrelated flag says N is not a coherent subset. The cross-model reviewer rated the argument moderate in a lens and weak in the other; the independent reproducer and the devil's-advocate check rated it weak, and the adjudication found that none of the intended-behaviour arguments holds. Verdict: a defect. WordFormGenerator is the same misreading in a second place, not a separate defect; its javadoc promises "all word forms for all dictionary entries with the given root word" (WordFormGenerator.java:117), which the omission also contradicts.
Recommended Use cross product only when a prefix is combined (suffix chains need only the continuation class)
Check cross product only when a prefix is combined: keep the Stemmer.applyAffix gate for prefixes only, accept an inner suffix in isAffixCompatible by its continuation flag (plus cross product after a prefix), and let WordFormGenerator recurse after affixes with continuation flags. Validated: the repro passes; analysis-common: 1,911 tests, 0 failures, 18 skipped. Analysis output changes, so affected indexes need reindexing.
All options and trade-offs3 options · 771 words
One fix (A) was applied in a scratch worktree at a9779ef3c193 and run through gradle; it was also shadowed onto the stock jars for the hunt's tests and the real-dictionary probe. The finder's broader sketch (B) was run on the same tests for comparison.
Use cross product only when a prefix is combined (suffix chains need only the continuation class) (validated by the checks) (recommended)
Two files, +13/-9. After a suffix Lucene only ever looks for another suffix, never a prefix (Stemmer.java:630-647), so dropping the gate for suffixes changes only suffix chains. A suffix after a prefix still needs Y on both (unchanged), and a prefix + suffix + suffix chain keeps the check on the inner suffix. The generator keeps a form only if Lucene's (fixed) stemmer stems it back to the entry (canStemToOriginal, WordFormGenerator.java:248), a Lucene self-check, not a comparison with native Hunspell.
--- Stemmer.isAffixCompatible (Stemmer.java:564)
-    if (dictionary.isCrossProduct(affix)) {
-      if (previousWasPrefix) return true;
-      if (outerSuffix >= 0) {
-        char prevFlag = dictionary.affixData(outerSuffix, Dictionary.AFFIX_FLAG);
-        return dictionary.hasFlag(append, prevFlag);
-      }
+    if (previousWasPrefix) return dictionary.isCrossProduct(affix);
+    if (outerSuffix >= 0) {
+      char prevFlag = dictionary.affixData(outerSuffix, Dictionary.AFFIX_FLAG);
+      return dictionary.hasFlag(append, prevFlag)
+          && (outerPrefix < 0 || dictionary.isCrossProduct(affix));
     }
--- Stemmer.applyAffix (Stemmer.java:621)
-    if (dictionary.isCrossProduct(affix) && recursionDepth <= 1) {
+    if ((!prefix || dictionary.isCrossProduct(affix)) && recursionDepth <= 1) {
--- WordFormGenerator.expand (WordFormGenerator.java:251)
-            if (dictionary.isCrossProduct(affix.id)) {
+            if (dictionary.isCrossProduct(affix.id) || append.length > 0) {
Trade-offs
- Bounded extra work: suffix recursion still stops at two suffixes, and the generator at two affixes of a kind (
WordFormGenerator.java:376). - It leaves the mirror case unchanged: under COMPLEXPREFIXES, two prefixes whose classes say
N(reunfoo) are accepted by native Hunspell and rejected by Lucene with or without this fix. That path is entangled with a separate prefix-recursion bug (option B) and is better fixed on its own. - Compatibility: the fix changes analysis output.
HunspellStemFilternow stems the affected words, so an index built before the fix keeps their surface forms and needs reindexing to match the fixed query-time analysis. A Lucene-only dictionary that relied onNto block a suffix chain (nonportable: native Hunspell ignores it there) would accept more words, andgetAllWordFormsreturns more forms (on Luxembourgish 341,573 instead of 293,583); no benchmark was run.
What the checks validated
- Stock main
a9779ef3c193, gradle: the repro fails 2 of 2 with assertions on and off. - With the fix, gradle: the repro passes with assertions off; the whole
lucene/analysis/commontest task with assertions on, repro included, runs 340 classes, 1,911 tests, 0 failures, 18 skipped (the hunspell package: 47 classes, 160 tests, 13 skipped, becauseTestAllDictionaries,TestHunspellRepositoryTestCasesandTestPerformanceneed external dictionaries).ecjLint,checkGoogleJavaFormatandforbiddenApispass with the test in place; both diffs apply cleanly toa9779ef3c193. - With the fix shadowed onto the stock jars: the finder's test, the independent reproducer's spell/stem and generator tests (4 of 4 each), the cross-model review's 4-dictionary prefix/suffix matrix (prefix + suffix results unchanged, now equal to native everywhere), the cross-model reviewers' tests (6 of 6, 2 of 2), and the hunt's security probe (no query loses hits; its COMPLEXPREFIXES
Ndictionary still does not overflow, as on stock, while itsYdictionary still overflows forbxandbbx, as on stock: that is the separate LFV-375). - Real dictionary: on Luxembourgish the generator adds 47,990 forms and loses none;
spellaccepts all but 36 of them (hyphenated or special forms). - Not run: the full Lucene suite, the external-dictionary suites, a benchmark.
Also lets a second prefix under COMPLEXPREFIXES combine without cross product, which fixes the mirror case (reunfoo accepted). It passes the repro and, by the finder's run, the 146 hunspell tests of the time.
Trade-offs
Alone it lets a separate known bug, the COMPLEXPREFIXES third-prefix recursion that ends in StackOverflowError (registry LFV-375), reach dictionaries whose chained prefix classes say N, which today are immune: in the hunt's security probe the COMPLEXPREFIXES dictionary with N overflows for bx with B, and not with A or on stock. In the finder's differential, words Lucene accepts and native rejects went from 49 to 96, all new ones under COMPLEXPREFIXES. Only safe together with or after the LFV-375 fix (doPrefix = false at Stemmer.java:640) and the sibling second-prefix continuation fix.
State in the Hunspell javadoc that suffix chains need cross product Y.
Trade-offs
Contradicts hunspell(5) and the class's "in place of native Hunspell" claim, and leaves real dictionaries such as Luxembourgish broken.
Elasticsearch and OpenSearch build their hunspell token filter on Lucene's HunspellStemFilter (source read, not executed), so their users of dictionaries with this shape get the same missed stems; the effect is lower recall only.
Differential testing of Lucene's Hunspell code against native Hunspell 1.7.2 on 4,000 generated micro-dictionaries and 1,069 fixture cases; with the finder's fix (option B) alone, the words native accepts and Lucene rejects fell from 202 to 24. A public-API JUnit then reproduced it on the stock jar.
The method in full190 words
Method: cross-implementation differential testing (the hunt's non-formal tier), in a hunt unit comparing Lucene's word-form generator, spell and analyzeSimpleWord with native Hunspell 1.7.2 (libhunspell spell and stem) and the hunspell-tools unmunch/munch.
- Inputs: 4,000 seeded, grammar-built micro-dictionaries (per dictionary every candidate word reachable by at most 3 affix rules) and 1,069 per-root cases from the Hunspell 1.7.2 and Lucene test fixtures.
- Root causes were separated with switchable shadow fixes: with the finder's fix for this bug (option B) alone, words native accepts and Lucene rejects fell from 202 to 24 (the rest are other causes or native deviations from hunspell(5)).
- The finder then wrote a public-API JUnit (
raich/SE) that fails on the stock jar, found the real Luxembourgish case and checked native Hunspell on it. - Found 2026-10-27 on main
a9779ef3c193; then checked by an independent reproducer, an intended-behaviour devil's advocate, two executed reviews by a model from another family (OpenAI GPT-5.6), a re-run of the intended lens, an adjudication, a history and prior-report follow-up, a security screen and a credibility audit. This doc added the gradle runs, the fix validation and the Luxembourgish count.
No prior report found (2026-10-27): three runs of 45 queries over GitHub, the lists and JIRA, 30 manual searches, all 179 hunspell-titled issues and PRs, downstream projects, native Hunspell and nuspell, and the changed files of all 409 open PRs. Nothing upstream fixes it.
Searches4 searches
Verdict new: no report by anyone. Keyword search cannot prove absence, and private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories; Lucene, Solr and OpenNLP lists; JIRA | 2026-10-27 | a scripted prior-report search, three query variants (classes and terms; symptoms; generator side), 45 queries each | no report; closest: #6546, #6547, #5379, #11662, #10727, #10838, #10842 |
| apache/lucene (GitHub) | 2026-10-27 | 30 manual searches; titles of all 179 items with "hunspell" in the title; the 98 sub-tasks of #10726; changed files of all 409 open PRs | no report; only #16422 (directive-parsing refactor) and #16911 (branch decommission) touch hunspell files |
| Elasticsearch, OpenSearch, Solr, Lucene.NET, hunspell/hunspell, nuspell, Luxembourgish dictionary repositories, all of GitHub | 2026-10-27 | 47 searches | no Lucene report; hunspell/hunspell#177 states the native rule |
| JIRA, lists.apache.org, the web | 2026-10-27 | 15 JIRA queries, 72 list queries, 7 web queries | nothing about Lucene |
Present since Lucene's first Hunspell code, LUCENE-3414 (e3172b9239c, 2011; first release 3.5.0); LUCENE-5483 added the inner check in 4.8.0 and LUCENE-10626 copied the rule into the generator in 9.5.0. Probes fail on 18 releases from 3.5.0 to 10.5.2 and on main. Not fixed upstream.
Versions tested9 rows
Introduced by e3172b9239c on trunk, LUCENE-3414 "Added Hunspell for Lucene" (2011-09-10, svn r1167467; JIRA migrated as #4487), backported to branch_3x as 1e084f1d08e the same day: HunspellStemmer.applyAffix recursed only if (affix.isCrossProduct() && recursionDepth < RECURSION_CAP), today's Stemmer.java:621. Widened by 56babb83687 (LUCENE-5483 "fix hunspell inaccuracies", #6546, 2014-03-02; branch_4x 040cf121458; 4.8.0), which added the inner-suffix check that is today's isAffixCompatible condition; before it, the inner-N case passed only because continuation classes were not checked at all. Copied by d537013e708 (LUCENE-10626, PR #975, 2022-07-05; branch_9x 3b763af12f5; 9.5.0) into WordFormGenerator.expand. Refactors since (LUCENE-4542, LUCENE-5468, LUCENE-9671, LUCENE-9685, LUCENE-9748) kept the gates; branch_10x, branch_10_6 and upstream main a95c754ee003 have the same lines.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the compact JUnit fails 2 of 2 through gradle, assertions on and off; the finder's, the reproducer's and the reviewers' tests fail with -ea and -da |
| 10.0.0, 10.5.2 | affected | spell, stem and getAllWordForms fail; the compact JUnit fails 2 of 2 on 10.5.2 |
| 9.5.0, 9.12.3 | generator from 9.5.0 | spell, stem and getAllWordForms fail; the compact JUnit fails 2 of 2 on 9.5.0 and 9.12.3 |
| 8.9.0, 8.11.4, 9.0.0, 9.4.2 | spell from 8.9.0 | spell and stem fail; no getAllWordForms yet |
| 4.8.0, 4.10.4, 5.5.5, 6.0.0, 6.6.6, 7.7.3 | affected | stemming fails for outer N and inner N |
| 3.5.0, 3.6.2, 4.0.0, 4.7.2 | first release | stemming fails for outer N; inner N passes only because continuation classes were not checked |
4.8.0 + hunspell package at 040cf121458^ vs 040cf121458 (LUCENE-5483) | commit A/B | only the inner-N case flips |
| 3.4.0 | no Hunspell code | the probe does not compile |
| main + fix A | not affected | the repro passes; analysis-common: 1,911 tests, 0 failures (18 skipped); Luxembourgish forms accepted |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests and real Luxembourgish words; two executed reviews by a model from another family (OpenAI GPT-5.6) rated it real; an adjudication re-ran it; this doc's gradle runs reproduce it on a9779ef3c193 and validate the fix.
Checks and verdicts379 words
Every executing check wrote or re-ran its own JUnit on stock main; every control passed, and native Hunspell accepted the words in every check that ran it.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Differential against native Hunspell 1.7.2, then the raich/SE JUnit: fails on main (-ea, -da), 10.5.2 and 9.12.3; native accepts with N and Y; the fix sketch passes. |
| cross-model review, refute lens (OpenAI GPT-5.6) | real, high; intended argument weak | Own spell and generation tests fail 2 of 3 each with -ea and -da; Y/Y controls pass; native Hunspell 1.3.2 accepts for YY, YN and NY. |
| cross-model review, intended lens (OpenAI GPT-5.6) | real, high; intended argument moderate | Own test fails on main, 10.5.2 and 9.12.3; its prefix + suffix control passes. Rated the 'deliberate subset' reading moderate, then rejected it: nothing documents N as blocking suffix chains. |
| independent reproducer | real | The hunspell(5) drinkables example: 3 of 4 combinations fail on main (-ea, -da), 10.5.2, 9.12.3, 9.4.2, 8.11.2; real Luxembourgish words rejected; its probe patch shows all three sites must change. |
| intended-lens re-run | reproduced | Re-ran the intended-lens test on a9779ef3c193 and built a 4-dictionary Y/N matrix with a prefix class: Lucene matches native Hunspell 1.3.2 on every prefix + suffix word and differs only on the twofold words. |
| intended-behaviour devil's advocate | real | Lucene needs Y on both classes, native 1.7.2 on neither; real Luxembourgish in both engines; no Lucene or Hunspell fixture combines N with a continuation chain; rebutted the 'not a port' and 'examples use Y' arguments. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test (4 run, 3 failed, -ea and -da) and the finder's test; native 1.3.2 accepts all four combinations. |
| credibility audit | keep | Re-ran the finder's test and its own drinkables matrix with an N prefix control on main (-ea, -da) and 10.5.2: only Y/Y works, the prefix control is rejected as it should be; native Hunspell 1.3.2 accepts all four. |
| this doc | reproduced; fix validated | Compact JUnit fails 2 of 2 through gradle on stock (asserts on and off) and passes with fix A; the analysis-common test task runs 1,911 tests, 0 failures (18 skipped); Luxembourgish count 47,840 forms; the fix does not make the COMPLEXPREFIXES N dictionary overflow. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 507 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,586 words
- Registry title
- Hunspell rejects, cannot stem and does not generate twofold-suffix words (a second suffix allowed by the first suffix's continuation class) when either suffix class has cross product N, although cross product only governs prefix+suffix combinations: with 'SFX S 0 st/E', 'SFX E N 2' (en, e) and raich/SE, spell("raichsten") is false; the real Luxembourgish dictionary rejects räichsten
- Area
- analysis / hunspell (Stemmer affix stripping: Hunspell.spell, getRoots, analyzeSimpleWord, Stemmer.stem, HunspellStemFilter; WordFormGenerator.getAllWordForms)
- Priority
- Medium, rank 254: Since 3.5, Hunspell spell and stemming silently fail on ordinary twofold-suffix words in a real public dictionary (Luxembourgish), which changes index-time stemming and recall, but only a few dictionaries have this shape, so it ends the narrow silent-result Medium rows after LFV-479.
- Impact class
- silent wrong results
- Impact note
- Only applications that use the opt-in Hunspell analysis (Hunspell.spell, getRoots and analyzeSimpleWord, Stemmer.stem and HunspellStemFilter, and the getAllWordForms tooling) with a dictionary in which a suffix class of a twofold-suffix chain has cross product N are hit: valid twofold-suffix words are reported as misspelled, get no stems (HunspellStemFilter passes them through unstemmed, so a search for the root misses them) and are missing from getAllWordForms, with no error [exec]; no scale is needed; the real Luxembourgish dictionary (lb, from the dictionary collection at the commit Lucene's regression build pins) triggers it on ordinary superlatives such as räichsten, räichste, räichstem and räichster [exec, the independent reproduction and the intended-behaviour check]; the finder's static survey of 191 public .aff files found such chains in 8 files (among them lb, hu_HU, ta_IN, is and fa; only lb was executed, and Lucene documents Hungarian as unsupported); every release with Lucene's Hunspell code, 3.5.0 to 10.6.0 (10.6.0 by reading), has it [exec].
- Summary
- You load a Hunspell dictionary with a twofold suffix, where the first suffix's continuation class allows a second suffix (for example 'SFX S Y 1 / SFX S 0 st/E .', 'SFX E N 2 / SFX E 0 en . / SFX E 0 e .' and the entry raich/SE), and spell-check or stem raichsten. You expect it to be accepted and stemmed to raich: hunspell(5) defines the cross-product field only as the 'permission to combine prefixes and suffixes', no prefix is involved, and C Hunspell accepts the word with N as with Y. Instead Lucene rejects raichsten and raichste, returns no stems and leaves them out of getAllWordForms("raich"), because Stemmer.applyAffix (Stemmer.java:621), Stemmer.isAffixCompatible (:564) and WordFormGenerator.expand (:251) follow a suffix+suffix chain only when the suffix classes are cross product Y; the real Luxembourgish dictionary shows the same for räichsten, räichste, räichstem and räichster.
- Introduced
- e3172b9239cda3c53769a9e1dd82ea122178b93b (svn r1167467, LUCENE-3414 'Added Hunspell for Lucene', migrated as apache/lucene#4487; svn era, no PR), 2011-09-10: the first Lucene Hunspell code, HunspellStemmer.applyAffix, recursed to a second affix only 'if (affix.isCrossProduct() && recursionDepth < RECURSION_CAP)'; it shipped through the branch_3x backport 1e084f1d08e (r1167505, same day) [read: git show; exec: 3.5.0 rejects the outer-N case]. That gate is today's Stemmer.java:621. Contributing commits: 56babb83687 (branch_4x 040cf121458; LUCENE-5483 'hunspell inaccuracies', #6546; 2014-03-02; first released in 4.8.0) added the cross-product requirement on the inner suffix that is today's isAffixCompatible condition (Stemmer.java:564-570), so N on either class breaks the chain [exec: commit-level A/B, the hunspell package at 040cf121458^ and at 040cf121458 shadowed over the 4.8.0 jars, flips only the inner-N case]; d537013e708 (LUCENE-10626, PR #975, issue #11662; 2022-07-05; branch_9x 3b763af12f5; first released in 9.5.0) copied the gate into WordFormGenerator.expand (WordFormGenerator.java:251) [read]. Later refactors kept the gate unchanged (LUCENE-4542, LUCENE-5468, LUCENE-9671, LUCENE-9685, LUCENE-9748). Not a regression. Whether the external project that LUCENE-3414 ported already had the gate was not checked. (2011-09-10 (LUCENE-3414, outer recursion gate); 2014-03-02 (LUCENE-5483, inner-suffix check); 2022-07-05 (LUCENE-10626, generator copy))
- First affected version
- 3.5.0 [exec] (the first release with Lucene's Hunspell code; 3.4.0 has none [exec: the probe does not compile]). The outer-N case fails in every release; the inner-N case fails from 4.8.0 (LUCENE-5483) [exec]. Entry points by release: stemming 3.5.0+, Hunspell.spell 8.9.0+, getAllWordForms 9.5.0+ [exec]
- Affected versions
- every release with Lucene's Hunspell code, 3.5.0 through 10.6.0 (10.6.0 by reading), and main a9779ef3c193; never fixed. [exec] the follow-up's version-portable probes fail on 18 releases (3.5.0, 3.6.2, 4.0.0, 4.7.2, 4.8.0, 4.10.4, 5.5.5, 6.0.0, 6.6.6, 7.7.3, 8.9.0, 8.11.4, 9.0.0, 9.4.2, 9.5.0, 9.12.3, 10.0.0, 10.5.2) and on main with -ea and -da; the finder's JUnit fails on main (-ea, -da), 10.5.2, 10.0.0, 9.12.3 and 9.5.0 (it does not compile before 9.5.0, its spell-only variant fails on 9.4.2); the independent reproduction's tests fail on main (-ea, -da), 10.5.2, 9.12.3, 9.4.2 and 8.11.2 (stem-only variant); the intended-behaviour check re-ran the finder's test on 10.5.2 (fail). In 3.5.0-4.7.2 the inner-N case is accepted only because those versions did not check continuation classes at all (they also accept drinkables when 'able' has no continuation class, which C Hunspell rejects). [read] Stemmer.java and WordFormGenerator.java on upstream main a95c754ee003 are byte-identical to a9779ef3c193; the gates are also on branch_10x and branch_10_6. All runs on aarch64 with JDK 25.0.3.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record verdict new): a scripted prior-report search in three runs (45 queries each over GitHub issues, PRs and commits, downstream repositories, the Lucene, Solr and OpenNLP lists and JIRA), 30 manual gh searches of apache/lucene, a title scan of all 179 apache/lucene issues and PRs with hunspell in the title, the 97 sub-tasks of #10726 (LUCENE-9687), searches of Elasticsearch, OpenSearch, Solr, Lucene.NET, hunspell/hunspell, nuspell, wooorm/dictionaries and all of GitHub, commit search and git log over the full history, the changed files of all 409 open apache/lucene PRs, 15 JIRA queries, 72 lists.apache.org queries and 7 web queries; the finder's, the independent reproduction's and the intended-behaviour check's searches agree. Closest items, none a report of this bug: #6546 (LUCENE-5483, origin of the inner check, which set out to 'match correct hunspell behavior'), #6547 (LUCENE-5484: recursion is 'driven correctly by continuation classes'), #5379 (LUCENE-4311, Czech over-stemming with cross product Y, fixed by a recursion limit), #11662 and #975 (introduced the generator gate), #8431 (LUCENE-7378) and #7237 (LUCENE-6175), open Hungarian complaints that name another mechanism or none (Hungarian is documented as unsupported), and hunspell/hunspell#177 (a native maintainer's statement that cross product governs prefix+suffix combinations). Not fixed upstream: no open PR changes Stemmer.java or WordFormGenerator.java (only #16422, a Dictionary directive-parsing refactor, and #16911, the branch_10x decommission, touch hunspell files).
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): the compact JUnit through gradle in a clean worktree, stock and with the recommended fix, assertions on and off, plus the wholelucene/analysis/commontest task and its lint checks with the fix; through the hunt's classpath runner, the same JUnit on main (-ea,-da), 10.5.2 and 9.12.3, the hunt's other repros with the fix shadowed, and a reach probe over the real Luxembourgish dictionary (stock, with the fix, and native Hunspell 1.3.2), 2026-10-28. Hunt runs on maina9779ef3c193andea57360912ed(identical hunspell code), version-portable probes on 18 releases from 3.5.0 to 10.5.2, and a commit-level A/B of LUCENE-5483 over the 4.8.0 jars.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java:560-574 (at a9779ef3c193) (isAffixCompatible: after the 'no previous affix' early return, an inner suffix after an outer suffix is accepted only inside 'if (dictionary.isCrossProduct(affix))' at :564, by the outer suffix's flag at :567-569; otherwise 'return false' at :573), :615-621 (applyAffix: 'if (innerSuffix >= 0) return true;' and the recursion gate 'if (dictionary.isCrossProduct(affix) && recursionDepth <= 1)' at :621), :28-31 (class javadoc 'conforms to the algorithm in the original hunspell algorithm, including recursive suffix stripping')lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordFormGenerator.java:238-256 (at a9779ef3c193) (expand: recursion after an applied affix only 'if (dictionary.isCrossProduct(affix.id))' at :251)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:34-46 (at a9779ef3c193) (class javadoc 'can be used in place of native Hunspell for many languages'; exceptions: Hungarian, non-BMP characters, PHONE); HunspellStemFilter.java:113 (a word without stems is returned unchanged); Dictionary.java:685 and :790-791 (the header's cross-product field is parsed as args[2].equals("Y") and stored per affix)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/twofold.aff (at a9779ef3c193) (Lucene's only twofold fixture: the hunspell(5) example with 'SFX Y Y 1' and 'SFX X Y 1')git diff ea57360912ed a9779ef3c193 -- lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/ (empty: the GPT reviews on ea57360912ed exercised identical code)hunspell(5) of Hunspell 1.7.2, man/hunspell.5:522 '(2) Cross product (permission to combine prefixes and suffixes)' and the 'Twofold suffix stripping' section (:921), as quoted by the independent reproduction and the intended-behaviour check; C Hunspell 1.7.2 src/hunspell/affentry.cxx:630-634, :700-760 and affixmgr.cxx affix_check/suffix_check_twosfx, as read by the finder, the intended-behaviour check and the adjudication
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:685, (at a9779ef3c193) 790-791, 812-814; Stemmer.java:262, 537-574, 588-655; WordFormGenerator.java:233-259Hunspell 1.7.2 man/hunspell.5:522, 921-962 and src/hunspell/affentry.cxx:633, 712, 745-756 (fetched read-only, 2026-10-28)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:34-47 (at a9779ef3c193) (Hungarian unsupported); HunspellStemFilter.java:113; lucene/analysis/common/build.gradle:150-153 (pinned dictionary commit); package-info.java:23-25
- Why it looks unintended
Hunspell 1.7.2 man/hunspell.5:522, 921-962 (fetched read-only, 2026-10-28)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:34-47; (at a9779ef3c193) WordFormGenerator.java:117; Stemmer.java:28-32; lucene/CHANGES.txt:12545-12549; lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/twofold.aff, TestTwoFold.javaapache/lucene#6546 body (gh issue view, read-only, 2026-10-28)
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java:617-652, (at a9779ef3c193) 630-647; WordFormGenerator.java:248, 376
- TestTwofoldSuffixCrossProduct.java (JUnit test):
repro/LFV-641/src/org/apache/lucene/analysis/hunspell/TestTwofoldSuffixCrossProduct.java(23 lines)
The diagram uses the finder's raich/SE example, the miniature of the Luxembourgish räich/b0a0 case; the compact repro uses the hunspell(5) drinkables example. Both fail the same way.
assets/LFV-641/bug.png(507 KB)