Under COMPLEXPREFIXES a word may carry two prefixes. As with two suffixes, the outer prefix is allowed only if the inner prefix's own rule lists its flag after the slash. Lucene now only checks that some rule in the dictionary lists it.
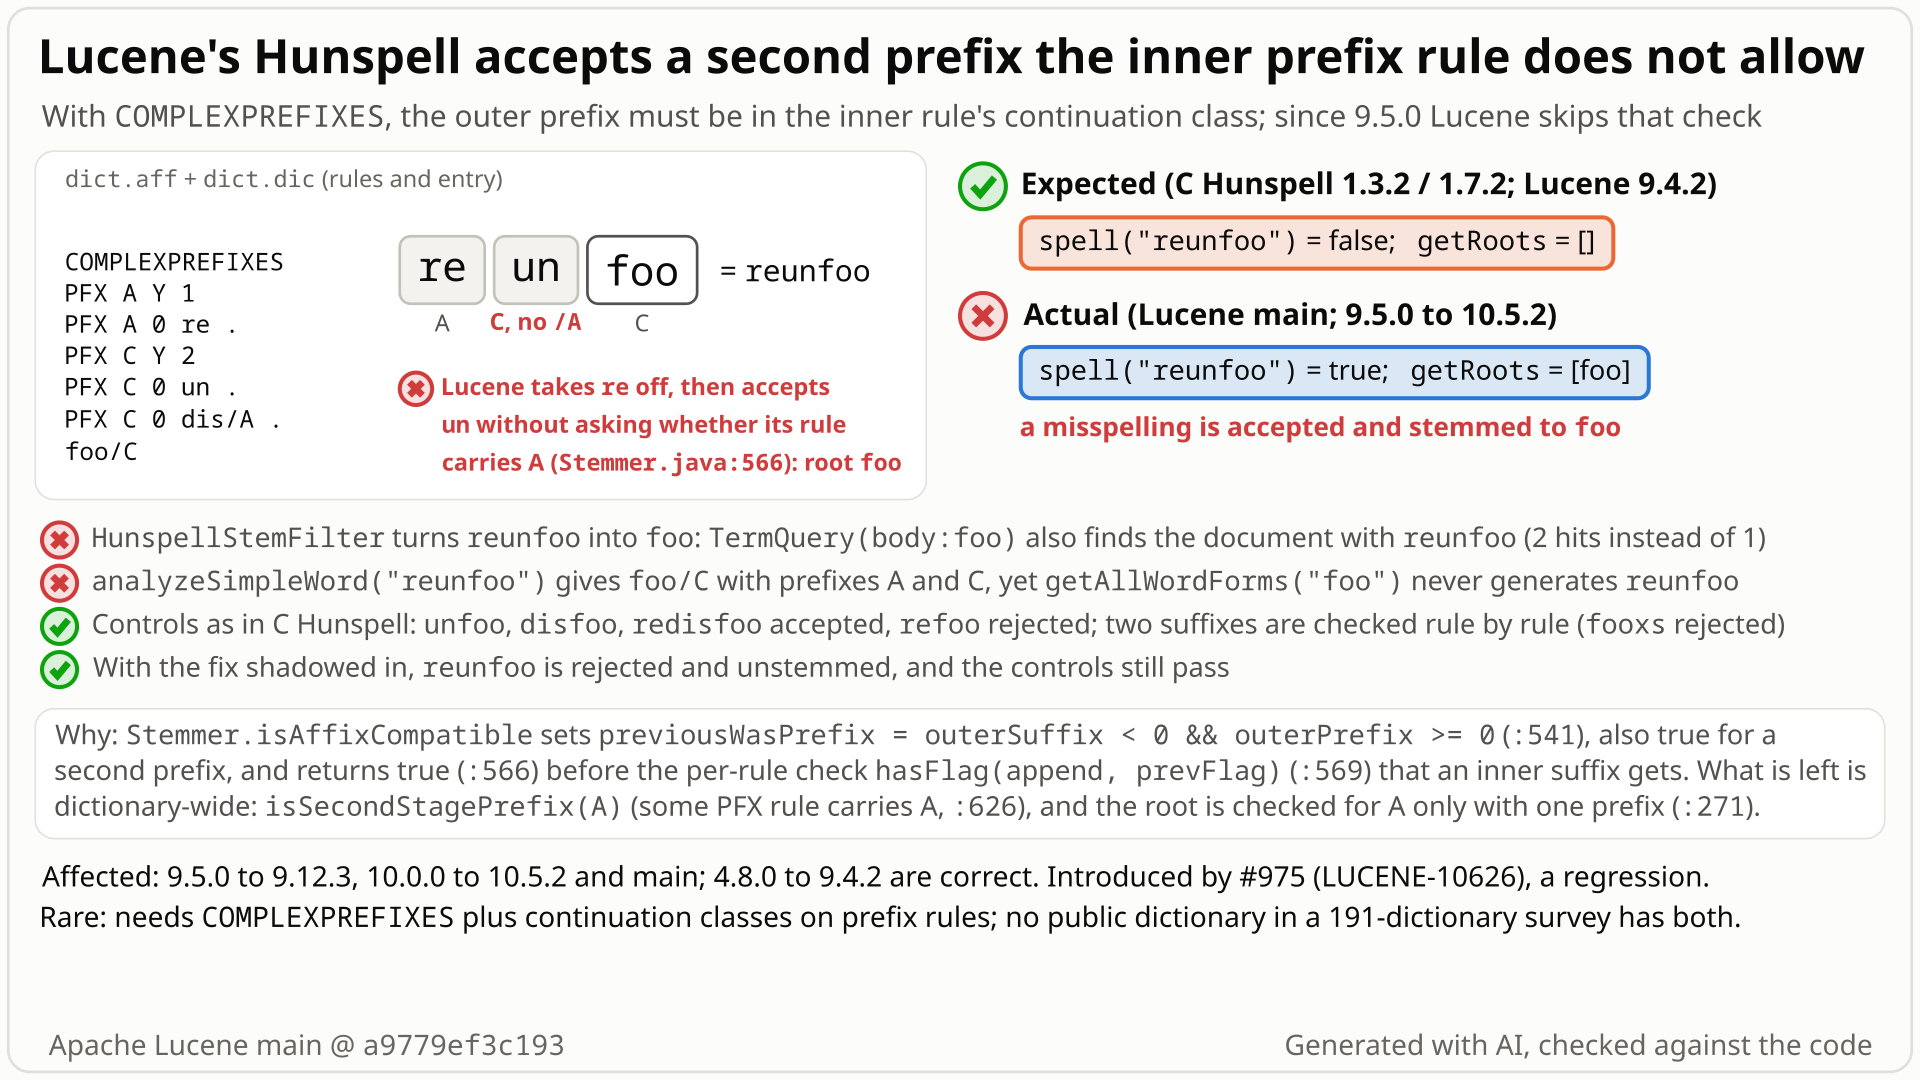
re off, then accepts un without asking whether its rule carries A, and reaches the root foo; native Hunspell and Lucene 9.4.2 reject reunfoo. Select the still to open it at full size. Generated with AI, checked against the code.- You load a Hunspell dictionary with
COMPLEXPREFIXES(a word may carry two prefixes) and three prefix rules:re(flag A), and in class Cunanddis/A. The/Aondissaysremay come in front ofdis. The root isfoo/C. - You expect
unfoo,disfooandredisfooto be words andreunfoonot, because onlydis, notun, allowsre. Native Hunspell 1.3.2 and 1.7.2 and Lucene 9.4.2 agree. - Instead, on 9.5.0 to 10.5.2 and main,
spell("reunfoo")is true andgetRoots("reunfoo")is[foo].HunspellStemFilterindexesreunfooasfoo, so in a 3-document index (foo,reunfoo,bar) a query forfoomatches 2 documents instead of 1. No error is raised. - Why: after stripping
re,Stemmer.isAffixCompatibleaccepts a cross-product second prefix without reading that prefix's continuation class (return true,Stemmer.java:566); the only chain check left is whether some prefix rule anywhere carriesA. A 2022 refactor (#975) dropped the per-rule check that 9.4.2 had; two suffixes are still checked rule by rule.
Only applications that load a custom Hunspell dictionary with COMPLEXPREFIXES and continuation classes on prefix rules (spell-checking, getRoots, analyzeSimpleWord, HunspellStemFilter). Misspellings pass and non-words are indexed and searched as their root, silently. None of 191 surveyed public dictionaries has this shape. Affected: 9.5.0 to 10.6.0 (10.6.0 by reading) and main.
Mechanism, terms and numbers748 words
Hunspell's COMPLEXPREFIXES option allows two prefixes on one word. As with two suffixes, the outer affix may only follow an inner affix rule that lists the outer affix's flag in its continuation class (the flags after the slash). With PFX A 0 re, PFX C 0 un, PFX C 0 dis/A and the root foo/C, redisfoo is a word and reunfoo is not. Since 9.5.0 Lucene no longer checks the inner rule: after stripping re, Stemmer.isAffixCompatible accepts an inner prefix of a cross-product class (one that passes the compound checks) without reading its continuation class (Stemmer.java:541, 566 on main a9779ef3c193), and what is left of the chain check is dictionary-wide: whether some prefix rule carries A. So Hunspell.spell("reunfoo") is true, getRoots returns [foo] and HunspellStemFilter indexes the token as foo, silently. Native Hunspell 1.3.2 and 1.7.2 reject reunfoo, and so does Lucene from 4.8.0 to 9.4.2 (11 of those releases run, the rest inferred from the unchanged check). The check was lost in the 2022 refactor #975 (LUCENE-10626), which reached 9.x in 9.5.0 and kept the per-rule check for twofold suffixes. Every release from 9.5.0 to 10.6.0 (10.6.0 by reading) and main is affected; reach is narrow, because it needs a custom dictionary with COMPLEXPREFIXES and continuation classes on prefix rules.
- Continuation class: flags after a slash on an affix rule.
PFX C 0 dis/A .means: a word that got the prefixdismay take a prefix of class A next. hunspell(4)/(5) calls the suffix version "twofold suffix stripping": "A seconds' suffix (affix class Y) will be the continuation class of the suffixable'", and adds that Hunspell "can strip another one yet (or a plus prefix in COMPLEXPREFIXES mode)". COMPLEXPREFIXES: "Set twofold prefix stripping (but single suffix stripping) eg. for morphologically complex languages with right-to-left writing system".- Outer / inner prefix (Lucene's naming): the outer prefix is written first and stripped first (
rein re+un+foo); the inner prefix is next to the root (un).
SET UTF-8
COMPLEXPREFIXES

PFX A Y 1
PFX A 0 re .

PFX C Y 2
PFX C 0 un .
PFX C 0 dis/A .
with the entry foo/C. Expected words: foo, unfoo, disfoo, redisfoo. Not words: refoo (the root does not carry A) and reunfoo (the rule un does not carry A).
Dictionarycollects every flag that appears in the continuation class of anyPFXrule (Dictionary.java:738-740,:482). Its javadoc describes it as a pre-filter: "If an outer affix's flag isn't here, there's no need to do 2-level affix stripping with it" (Dictionary.java:138-141).dis/AputsAin it.Stemmer.applyAffixstripsreand, underCOMPLEXPREFIXES, looks for a second prefix becauseisSecondStagePrefix(A)is true (Stemmer.java:626).- For the candidate
un,isAffixCompatibleis called withouterPrefix = re(:424):
boolean previousWasPrefix = outerSuffix < 0 && outerPrefix >= 0;      // Stemmer.java:541
...
if (dictionary.isCrossProduct(affix)) {                              // :564
  if (previousWasPrefix) return true;                                // :566, also taken for a 2nd prefix
  if (outerSuffix >= 0) {
    char prevFlag = dictionary.affixData(outerSuffix, Dictionary.AFFIX_FLAG);
    return dictionary.hasFlag(append, prevFlag);                     // :567-569, suffixes only
  }
}
previousWasPrefix is meant for "a suffix after a prefix", which needs no continuation requirement, but it is also true when the affix being checked is itself a prefix, so for a cross-product inner prefix (class C is Y) un's continuation flags are never read.
- The candidate
foocarriesun's flagC(:269-270). The root-level check of the outer prefix's flag runs only when there is no inner prefix (:271-276), so nothing rejectsreunfoo. - Before #975 the prefix loop passed
falsefor thepreviousWasPrefixparameter and the method ended inreturn previousWasPrefix || dictionary.hasFlag(append, prevFlag);, so a second prefix had to carry the outer flag (the 9.4.2 code). #975 derivedpreviousWasPrefixfrom affix ids instead. - Native Hunspell stores prefix rules as internal suffixes under
COMPLEXPREFIXES, so a twofold prefix gets the same per-rule continuation check as a twofold suffix (Hunspell 1.7.2affixmgr.cxx,SfxEntry::checkword).
The trigger is wider than one class: un may sit in a class of its own, and a root that itself carries A (foo/AC) does not make reunfoo valid in native Hunspell while Lucene accepts it. It is enough that some prefix rule anywhere carries the outer flag.
Exposure and likelihood237 words
- Who. Users of
Hunspell.spell,getRoots,analyzeSimpleWordandHunspellStemFilter/HunspellStemFilterFactory(@lucene.experimental) with a dictionary that setsCOMPLEXPREFIXESand gives some prefix rules continuation classes, where an inner prefix rule lacks a flag that another prefix rule carries (both prefix classes cross-product). Nothing else to configure; deterministic; assertions on or off. - What goes wrong. No exception. The spell checker accepts misspellings such as
reunfoo; stemming returns a root for a non-word, so the stem filter indexes and queries it as the root. In a probe index with the documentsfoo,reunfooandbar, the queryfoomatched 2 documents on main and 1 on 9.4.2, and the query stringreunfooparsed tof:foo. - Reach. Narrow. Of 191 surveyed public
.afffiles (99 LibreOffice, 92 wooorm/dictionaries) only one (Central Kurdish,ckb) setsCOMPLEXPREFIXES, and none of its 1,812 prefix rules has a continuation class, so the second-prefix stage is never entered (the finder's survey; theckbstructure was re-checked; the 92 wooorm files were not kept, so the full survey cannot be re-run). Custom dictionaries for languages with complex prefixing are the likely users. - In the hunt's differential over 4,000 generated micro-dictionaries, words Lucene accepts and native Hunspell 1.7.2 rejects fell from 49 to 16 with only this fix (finder's run).
- Since when. 9.5.0 (January 2023) on 9.x and 10.0.0 on 10.x, through 10.6.0 (10.6.0 by reading) and main.
The test shows that with COMPLEXPREFIXES, PFX A 0 re, PFX C 0 un, PFX C 0 dis/A and foo/C, Hunspell accepts re before un although only dis carries A.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.hunspell;

import java.io.ByteArrayInputStream;
import java.nio.charset.StandardCharsets;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestComplexPrefixesSecondPrefix extends LuceneTestCase {

  public void testSecondPrefixNeedsContinuationClass() throws Exception {
    String aff =
        """
        COMPLEXPREFIXES
        PFX A Y 1
        PFX A 0 re .
        PFX C Y 2
        PFX C 0 un .
        PFX C 0 dis/A .
        """;
    Dictionary dictionary =
        new Dictionary(
            new ByteBuffersDirectory(),
            "dict",
            new ByteArrayInputStream(aff.getBytes(StandardCharsets.UTF_8)),
            new ByteArrayInputStream("1\nfoo/C\n".getBytes(StandardCharsets.UTF_8)));
    // "re" (A) may only precede "dis/A", not "un": expected spell("reunfoo") false, actual true
    assertFalse(
        "spell(\"reunfoo\") expected false, was true", new Hunspell(dictionary).spell("reunfoo"));
  }
}
# in a copy of this finding's repro folder (repro/LFV-642/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.hunspell.TestComplexPrefixesSecondPrefix
- Expected vs actual
- Expected:
spell("reunfoo")is false (as in C Hunspell and Lucene 9.4.2); actual (-ea and -da): true, becauseStemmer.isAffixCompatiblereturns true for any prefix after a prefix (Stemmer.java:566).
More files, environment, full output35 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: spell("reunfoo") expected false, was true
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
       org.junit.Assert.assertFalse(Assert.java:65)
org.apache.lucene.analysis.hunspell.TestComplexPrefixesSecondPrefix.testSecondPrefixNeedsContinuationClass(TestComplexPrefixesSecondPrefix.java:43)- The format licenses the second affix through the first affix's rule; native Hunspell 1.3.2 and 1.7.2 reject
reunfoo. - Lucene 4.8.0 to 9.4.2 checked the inner rule; #975, a feature PR, dropped the check with no CHANGES note, test or review comment about it.
- Lucene still checks two suffixes rule by rule (
fooxsrejected), and its owngetAllWordForms("foo")omitsreunfoo.
The full argument346 words
- The format's contract. hunspell(4) as shipped with Hunspell 1.3.2 (hunspell(5) later):
COMPLEXPREFIXES"Set twofold prefix stripping (but single suffix stripping)"; "Twofold suffix stripping": "Hunspell can strip another one yet (or a plus prefix in COMPLEXPREFIXES mode)" and "A seconds' suffix (affix class Y) will be the continuation class of the suffixable'". Native Hunspell 1.3.2 (run for this doc) and 1.7.2 acceptunfoo,disfoo,redisfooand rejectrefooandreunfoo. - Lucene's own design record. CHANGES for LUCENE-5483 (4.8.0): "Multi-stage affix-stripping, prefix-suffix dependencies, and COMPLEXPREFIXES now work correctly according to the hunspell algorithm. ... rules for recursive affix application are driven correctly by continuation classes in the affix file." A committer on LUCENE-5484 (#6547): "You should never recurse, unless the affix actually allows for it with a continuation class". The javadoc #975 deleted: "if we are removing a suffix, and it has no continuation requirements, it's ok. but two prefixes (COMPLEXPREFIXES) or two suffixes must have continuation requirements to recurse."
- Lucene claims native behaviour.
Hunspell"can be used in place of native Hunspell for many languages" (its listed exceptions are Hungarian, non-BMP characters and PHONE);Stemmer"conforms to the algorithm in the original hunspell algorithm". - Lucene disagrees with itself. The twofold-suffix path keeps the per-rule check (
fooxsis rejected forSFX C 0 x,SFX C 0 y/A,SFX A 0 s), andgetAllWordForms, documented as "equivalent to \"unmunch\"", returns[disfoo, foo, redisfoo, unfoo]whilespell("reunfoo")is true. - The change was not meant to change behaviour. #975 ("add tools to aid dictionary editing") has no CHANGES or MIGRATE note about stemming; its test changes add tests and fixtures, none about prefix chains or continuation classes (its one rewritten assertion, in
TestDictionary, keeps its value); none of its 3 comments, 12 reviews and 19 inline comments mentionsStemmer, prefixes or continuation classes. 9.4.2 is correct. - Why tests never caught it.
TestComplexPrefixhas one rule per prefix class, so it cannot tell "this rule allows it" from "some rule allows it"; no other Lucene fixture setsCOMPLEXPREFIXES.
The devil's-advocate check146 words
The strongest case for "intended" (the devil's-advocate verifier and the cross-model reviewer's intended lens): the Hunspell javadoc concedes incomplete language support, the class-wide second-stage flag set (LUCENE-9799/9803, #10838/#10842) is deliberate, and over-accepting is low-harm for stemming, so the dictionary-wide check could be a permissive approximation.
Why it fails: Dictionary documents that set as a pre-filter ("no need to do 2-level affix stripping"), and LUCENE-9799/9803 introduced it as pruning while the per-rule check in isAffixCompatible stayed; the per-rule check then survived until a refactor that never mentions it; the twofold-suffix twin keeps it; Lucene's own generator disagrees with its spell checker; and the unsupported-language list is about language-specific logic, while this is generic affix semantics shown by a seven-line dictionary. Every check rejected the argument; the ones that rated its strength (the cross-model reviews and the adjudication) rated it weak. Verdict: a defect, a regression since 9.5.0.
Recommended Restore the per-rule check for a second prefix
Restore the per-rule check in Stemmer.isAffixCompatible: when the affix being checked is a second prefix, return hasFlag(append, flag of outerPrefix) instead of true (+7/-1, the 9.4.2 rule). Validated: the repro and an extended TestComplexPrefix pass; hunspell tests: 160 run, 0 failures, 13 skipped. LFV-375 needs its own one-liner; one PR can carry both.
--- Stemmer.isAffixCompatible (Stemmer.java:564)
     if (dictionary.isCrossProduct(affix)) {
       // cross-check incoming continuation class (flag of previous affix) against this affix's flags
-      if (previousWasPrefix) return true;
+      if (previousWasPrefix) {
+        // a suffix after a prefix needs no continuation requirement, but a second prefix
+        // (COMPLEXPREFIXES) must carry the outer prefix's flag, as a second suffix must
+        if (!isPrefix) return true;
+        char prevFlag = dictionary.affixData(outerPrefix, Dictionary.AFFIX_FLAG);
+        return dictionary.hasFlag(append, prevFlag);
+      }
       if (outerSuffix >= 0) {
All options and trade-offs3 options · 702 words
Option A was applied in a scratch worktree at a9779ef3c193 and run through gradle, then shadowed onto the stock jars for the hunt's tests. Option B (A plus LFV-375's fix) was run through gradle and the classpath runner too. Option C is a sketch only.
Stemmer.java +7/-1. A suffix after a prefix keeps return true; a prefix after a prefix must carry the outer prefix's flag in its continuation class, as before 9.5.0 and as a second suffix must. A prefix only reaches this branch with outerSuffix < 0 (after a suffix Lucene never looks for a prefix, Stemmer.java:630-647), so the new branch covers exactly "prefix after prefix". For the PR, extend the existing fixture: PFX B 0 pthree . in complexprefix.aff (class B becomes PFX B Y 2) and assertStemsTo("pthreefoo", "foo"); assertStemsTo("ponepthreefoo"); in TestComplexPrefix, or add the repro.
--- Stemmer.isAffixCompatible (Stemmer.java:564)
     if (dictionary.isCrossProduct(affix)) {
       // cross-check incoming continuation class (flag of previous affix) against this affix's flags
-      if (previousWasPrefix) return true;
+      if (previousWasPrefix) {
+        // a suffix after a prefix needs no continuation requirement, but a second prefix
+        // (COMPLEXPREFIXES) must carry the outer prefix's flag, as a second suffix must
+        if (!isPrefix) return true;
+        char prevFlag = dictionary.affixData(outerPrefix, Dictionary.AFFIX_FLAG);
+        return dictionary.hasFlag(append, prevFlag);
+      }
       if (outerSuffix >= 0) {
Trade-offs
- Speed: not measured (no benchmark run); on the second-prefix path only, an
affixDataread and ahasFlaglookup replace the immediatereturn true. - Behaviour change: dictionaries that relied on the 9.5-10.5 over-acceptance lose those words, which native Hunspell never accepted.
HunspellStemFilterstops stemming them, so an index built with an affected version keeps such words as the root term and needs reindexing for exact agreement. - Leaves LFV-375 in place: with A alone, LFV-375's repro still fails 3 of 4 with
StackOverflowError; with only LFV-375's fix, this repro still fails 2 of 2. Also unchanged: a second prefix whose class has cross productNis still rejected (native accepts it; noted with LFV-641's fix).
What the checks validated
- Stock main
a9779ef3c193, gradle: the repro fails 2 of 2 and the extendedTestComplexPrefix1 of 1, with assertions on and off. - With A, gradle: the repro and
TestComplexPrefixpass with assertions on and off; the whole hunspell test package (org.apache.lucene.analysis.hunspell.*, assertions on, repro and extended fixture included) runs 47 classes, 160 tests, 0 failures, 13 skipped (TestAllDictionaries,TestHunspellRepositoryTestCasesandTestPerformanceneed external dictionaries); that run used the repro before one statement was rewrapped for google-java-format, same assertions;ecjLint,checkGoogleJavaFormat,forbiddenApisMainandforbiddenApisTestpass with the fix and both tests in place;fix.diffandfix-with-test.diffapply cleanly toa9779ef3c193. - With A shadowed onto the stock jars (classpath runner): the repro (
-ea,-da), the finder's test (1 of 1), the independent reproducer's test (4 of 4,-eaand-da), the cross-model review's variants (2 of 2), the intended-behaviour check's prefix-versus-suffix test (2 of 2) and the cross-model reviewers' tests (4 of 4, 1 of 1) pass. - Not run: the full Lucene suite, the external-dictionary suites, a benchmark.
A and doPrefix = false at Stemmer.java:640 ("we took away the second prefix: go look for another suffix"), as before 9.5.0. Fits one issue, "the #975 refactor broke COMPLEXPREFIXES twofold-prefix handling", with both repros.
Trade-offs
Same as A, plus LFV-375's own behaviour change (no third prefix under COMPLEXPREFIXES). Reviewers may prefer two small PRs; each fix leaves the other bug in place.
What the checks validated
- Classpath runner: this repro 2 of 2 and LFV-375's repro 4 of 4 pass.
- Gradle: A plus LFV-375's line, with both repros in the hunspell package: 48 classes, 164 tests, 0 failures, 13 skipped.
In processStemCandidate, when innerPrefix >= 0, require isFlagAppendedByAffix(innerPrefix, flag of outerPrefix) next to the existing outer-prefix check (Stemmer.java:271).
Trade-offs
Strips first and rejects later (more work per candidate), and leaves isAffixCompatible treating prefix and suffix chains differently. Not recommended. Not run.
On its own it only over-accepts words; together with the sibling third-prefix recursion bug LFV-375 (same commit, in every affected release) it lets more COMPLEXPREFIXES dictionaries reach that bug's StackOverflowError and exponential-time shapes (one 57-character token took 11 s).
Differential testing of Lucene's Hunspell code against native Hunspell 1.7.2 on 4,000 generated micro-dictionaries and 1,069 fixture cases; a switchable fix separated this cause from the others, and a public-API JUnit reproduced it on the stock jar. A verifier of LFV-375 had noticed the same wrong chain a day earlier as a side probe.
The method in full147 words
Method: cross-implementation differential testing (the hunt's non-formal tier): Lucene's getAllWordForms, spell and analyzeSimpleWord against native Hunspell 1.7.2 (libhunspell spell and stem) and the hunspell-tools unmunch/munch.
- Inputs: 4,000 seeded, grammar-built micro-dictionaries (per dictionary every candidate word reachable by at most 3 affix rules) and 1,069 per-root cases from the Hunspell 1.7.2 and Lucene test fixtures.
- Root causes were separated with switchable shadow fixes: with only this fix, words Lucene accepts and native rejects fell from 49 to 16.
- First observation: on 2026-10-26 the intended-behaviour verifier of LFV-375 read the #975 change and ran a targeted probe (
spell("cax")true on main, 10.5.2 and 9.5.0, false on 9.4.0 and in native Hunspell); it was kept as an unregistered sibling note until this hunt found it independently. - Native oracle: use native
spell(), notstem(), which returns nothing for prefixed words underCOMPLEXPREFIXES.
No prior report found (2026-10-27): three runs of 72 queries over GitHub, the lists, JIRA and the web, 44 manual searches, a keyword scan of the 10,441 apache/lucene issues and PRs updated since July 2022, and the changed-file lists of the 409 open PRs. Not fixed upstream.
Searches4 searches
Verdict new: no report by anyone. Keyword search cannot prove absence, private channels cannot be searched, and this is a 2026-10-27 snapshot.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; Elasticsearch, OpenSearch, Solr; dev@, java-user@, issues@, commits@; JIRA; web | 2026-10-27 | a scripted prior-report search, three query specs (code site, symptom, regression history), 72 queries each, 27 of them web queries | no report; one high-scoring hit, a false positive |
| GitHub (apache/lucene, Elasticsearch, OpenSearch, Solr, Lucene.NET, OpenNLP, hunspell/hunspell) | 2026-10-27 | 44 manual searches (COMPLEXPREFIXES, twofold, second prefix, continuation class, previousWasPrefix, isAffixCompatible, isSecondStagePrefix, ...) | no report |
| apache/lucene (GitHub API) | 2026-10-27 | keyword scan of the titles and bodies of the 10,441 issues and PRs updated since 2022-07-01; changed-file lists of the 409 open PRs (at most 100 files per PR, so 4 large PRs were seen only in part; by title none is about hunspell); the #975 thread | 158 hunspell items, none this bug; only #16422 (Dictionary.java) and #16911 (branch_10x decommission; hunspell CI workflows in the saved list) touch hunspell paths, none Stemmer.java; #975 never discusses the check |
| lists.apache.org | 2026-10-27 | a pull of hunspell mails since 2022-07-01 from dev@ (17), java-user@ (4) and issues@ (240), subjects read; commits@ only through the tool's queries | no report |
Introduced by #975 (LUCENE-10626, d537013e708, merged to main 2022-07-05), which reached 9.x as a cherry-pick in 9.5.0. 9.4.2 and the releases back to 4.8.0 are correct (11 run, the rest inferred); 9.5.0 to 10.5.2 and main fail. Before 4.8.0 an older stemmer also accepted reunfoo, for a different reason that 4.8.0 fixed. Not fixed upstream.
Versions tested7 rows
Introduced by d537013e70872015364c745e5f320727efc034b7, "LUCENE-10626: Hunspell: add tools to aid dictionary editing: analysis introspection, stem expansion and stem/flag suggestion (#975)", merged to main 2022-07-05 (issue #11662); branch_9x got it as the cherry-pick 3b763af12f5 (committed 2023-01-13). 9.4.2 was cut from branch_9x before the cherry-pick, so it is the last correct release. The correct check dates from LUCENE-5483 (trunk 56babb83687, backported to branch_4x as 040cf121458, released in 4.8.0). Before 4.8.0 the old HunspellStemmer stripped up to two affixes of any kind and let an affix without a continuation class be followed by any affix, so 4.0.0 and 4.7.2 also stem reunfoo to foo (executed in this doc's fact check); LUCENE-5483 fixed that, so this bug is a regression of the 4.8.0 behaviour. Affected releases by tag containment: 9.5.0 to 9.12.3 and 10.0.0 to 10.5.2 (26 releases); upstream main, branch_10x and branch_10_6 still carry the line. Same introducing commit as LFV-375, a different line.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the compact JUnit fails 2 of 2 through gradle, assertions on and off; the hunt's tests fail with -ea and -da |
| 10.0.0, 10.5.2 | affected | the hunt's JUnit and stem-filter probe fail (reunfoo accepted, stemmed to foo); the compact JUnit fails 2 of 2 on 10.5.2 |
| 9.5.0, 9.12.3 | first affected | the compact JUnit fails 2 of 2; the hunt's JUnit and main() variants fail (9.5.0 with -ea and -da) |
| 9.4.2 | last correct | the compact JUnit passes 2 of 2; reunfoo rejected, controls pass (-ea and -da) |
| 4.8.0, 5.5.5, 6.0.0, 7.7.3, 8.0.0, 8.8.2, 8.9.0, 8.11.4, 9.0.0, 9.4.0 | not affected | version-portable probes (spell, stem filter, or Stemmer on 4.8.0 and 5.5.5) reject reunfoo or leave it unstemmed; controls pass. The releases in between were not run (inferred from the unchanged check) |
| 4.0.0, 4.7.2 (before LUCENE-5483) | accepts reunfoo, older cause | the old HunspellStemmer (up to two affixes of any kind; an affix without a continuation class may be followed by any affix) stems reunfoo to foo, as it does unfoo, disfoo and redisfoo; refoo gives nothing. Fixed in 4.8.0 by LUCENE-5483 |
| main + fix A | not affected | the repro and the extended TestComplexPrefix pass; hunspell tests: 160 run, 0 failures, 13 skipped |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests and native Hunspell; two executed reviews by a model from another family (OpenAI GPT-5.6) rated it real; an adjudication and an audit re-ran it; this doc's gradle runs reproduce it on a9779ef3c193 and validate the fix.
Checks and verdicts339 words
Every executing check wrote or re-ran its own JUnit on stock main; every control passed, and native Hunspell rejected reunfoo in every check that ran it.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Differential against native Hunspell 1.7.2, then a spell-only JUnit: fails on main (-ea, -da), 10.5.2 and 9.12.3, passes on 9.4.2 and with the fix; still fails with LFV-375's fix. |
| cross-model review, refute lens (OpenAI GPT-5.6) | real, high; intended argument weak | Own test (ultraminiroot) fails with -ea and -da while the nearest controls pass; native 1.3.2 rejects it; passes on 9.4.2 and with the fix. |
| cross-model review, intended lens (OpenAI GPT-5.6) | real, high; intended argument weak | Own test (preinroot) fails on main, 9.5.0 and 10.5.2, passes on 9.4.2 and with the fix; analyzeSimpleWord over-accepts too. |
| Independent reproducer | real | Own test in a separate package: 3 of 4 fail (control passes) on main, 10.5.2, 9.12.3 and 9.5.0; 4 of 4 pass on 9.4.2 and with the fix. |
| The cross-model review, variants | real | Re-ran the intended-lens test on a9779ef3c193; its own variants (foo/AC, split classes) fail 2 of 2 on main and pass on 9.4.2; native 1.7.2 rejects reunfoo in all four dictionaries. |
| Intended-behaviour devil's advocate | real | Prefix-versus-suffix test: reunfoo accepted, fooxs rejected on main and 9.5.0, both right on 9.4.2; read native 1.7.2's source; Lucene's generator omits reunfoo. |
| adjudication | confirmed, high | Re-ran the independent reproduction's and the finder's tests (fail) and the independent reproduction's with the fix (4 of 4 pass); native 1.3.2 rejects reunfoo. |
| audit and registry re-run | keep | Fresh-seed re-runs fail on main and pass with the fix; the auditor's own three-class variant is accepted on main, 9.5.0 and 10.5.2 and rejected on 9.4.2. |
| this doc | reproduced; fix validated | Compact JUnit through gradle (stock fails, fix passes, lint clean) and through the classpath runner on main and 4 releases; the hunt's tests and LFV-375's repro with the fix shadowed; native 1.3.2 re-run. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 496 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,358 words
- Registry title
- Hunspell COMPLEXPREFIXES accepts a second prefix after an inner prefix rule whose continuation class does not allow it: with 'PFX A 0 re', 'PFX C 0 un', 'PFX C 0 dis/A' and foo/C, spell("reunfoo") is true and HunspellStemFilter stems reunfoo to foo, although only dis, not un, allows re (a regression since 9.5.0)
- Area
- analysis / hunspell (Stemmer affix compatibility: COMPLEXPREFIXES twofold prefixes)
- Priority
- Low, rank 465: This 9.5 regression makes spell and stem over-accept twofold prefixes only with a custom COMPLEXPREFIXES dictionary, the same profile as its affix sibling LFV-374, so it follows that row.
- Impact class
- silent wrong results
- Impact note
- Only applications that load a hunspell dictionary combining COMPLEXPREFIXES with continuation classes on prefix rules are hit: Hunspell.spell() then accepts, and getRoots(), analyzeSimpleWord() and HunspellStemFilter stem, words whose outer prefix the stripped inner prefix rule does not allow (it is enough that some prefix rule anywhere in the .aff carries the outer flag), so misspellings pass the spell checker and non-words are indexed and searched as their root, with no error [exec]; no scale is needed; every release from 9.5.0 through 10.6.0 (10.6.0 by reading) and main [exec at 9.5.0, 9.12.3, 10.0.0, 10.5.2 and main]; no surveyed public dictionary has this shape (the only public COMPLEXPREFIXES dictionary of 191, ckb, has no prefix continuation classes).
- Summary
- You load a hunspell dictionary that sets COMPLEXPREFIXES (twofold prefix stripping) with the outer prefix 'PFX A 0 re', an inner prefix class C with two rules, 'un' without a continuation class and 'dis/A', and the root foo/C, and expect what hunspell(5), C Hunspell 1.3.2 and 1.7.2 and Lucene up to 9.4.2 do: re may only precede dis, so redisfoo is a word and reunfoo is not, just as Lucene still checks the mirror-image twofold suffixes rule by rule. Instead spell("reunfoo") is true, getRoots("reunfoo") is [foo] and HunspellStemFilter turns the token reunfoo into foo, because since 9.5.0 Stemmer.isAffixCompatible returns true for any prefix stripped after another prefix (Stemmer.java:541, 566) and the only remaining gate is the dictionary-wide check that some prefix rule carries the flag A (Dictionary.isSecondStagePrefix).
- Introduced
- d537013e70872015364c745e5f320727efc034b7 (apache/lucene#975, LUCENE-10626 'Hunspell: add tools to aid dictionary editing: analysis introspection, stem expansion and stem/flag suggestion', a feature PR by donnerpeter; issue migrated as #11662), merged to main 2022-07-05; reached branch_9x as the cherry-pick 3b763af12f576b8b8120e98ae38b7a67461a99e8 (committed 2023-01-13), first released in 9.5.0 [read: git blame and git log -S on Stemmer.java: the prefix loop's isAffixCompatible(prefix, prevFlag, recursionDepth, true, false, context) with a hard-coded previousWasPrefix = false, which reached 'return previousWasPrefix || dictionary.hasFlag(append, prevFlag)', became 'boolean previousWasPrefix = outerSuffix < 0 && outerPrefix >= 0' plus 'if (previousWasPrefix) return true;', which is also taken for an inner prefix; #975 also deleted the javadoc 'two prefixes (COMPLEXPREFIXES) or two suffixes must have continuation requirements to recurse'] [exec: release bracket 9.4.2 pass / 9.5.0 fail with three independent variants]. Same commit as LFV-375, different line and different fix (2022-07-05 (merged to main); 2023-01-13 (branch_9x cherry-pick, author date kept as 2022-07-05))
- First affected version
- 9.5.0 [exec] (10.0.0 on the 10.x line [exec]); 9.4.2 is the last unaffected release [exec]: it was released after the main commit but cut from branch_9x before the cherry-pick
- Affected versions
- 9.5.0 - 9.12.3, 10.0.0 - 10.6.0 (10.6.0 by reading) and main a9779ef3c193. [exec] the finder's JUnit fails on 9.5.0 (-ea and -da), 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da), a main() spell() variant fails on 9.5.0, 9.12.3, 10.5.2 and main and a main() HunspellStemFilter variant on 9.5.0, 9.12.3, 10.0.0, 10.5.2 and main (follow-up); the independent reproduction's JUnit fails 3 of 4 on main (-ea and -da), 10.5.2, 9.12.3 and 9.5.0; the GPT reviewers' own tests fail on 9.5.0 and 10.5.2. [read] git tag --contains on both commits: all 26 releases 9.5.0, 9.6.0, 9.7.0, 9.8.0, 9.9.0-9.9.2, 9.10.0, 9.11.0, 9.11.1, 9.12.0-9.12.3, 10.0.0, 10.1.0, 10.2.0-10.2.2, 10.3.0-10.3.2, 10.4.0 and 10.5.0-10.5.2 contain 'if (previousWasPrefix) return true;'; upstream main a95c754ee003, branch_10x and branch_10_6 still do (2026-10-27, source only). Not affected: 4.8.0 - 9.4.2 [exec on 4.8.0, 5.5.5, 6.0.0, 7.7.3, 8.0.0, 8.8.2, 8.9.0, 8.11.4, 9.0.0, 9.4.0 and 9.4.2 with the controls passing; the other releases in the range by code reading]; before 4.8.0 there was no twofold prefix stripping [read]. All runs on aarch64 with JDK 25.0.3
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record verdict new, confidence high): a scripted prior-report search with three specs (3 x 72 queries over GitHub issues, PRs and commits, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, JIRA and 27 web queries each; one high-scoring hit, a false positive), 44 manual GitHub searches over apache/lucene, Elasticsearch, OpenSearch, Solr, Lucene.NET, OpenNLP and hunspell/hunspell, a title and body scan of all 10,441 apache/lucene issues and PRs updated since 2022-07-01 (158 mention hunspell, all titles read), the changed files of all 409 open apache/lucene PRs (only #16422, a Dictionary.java directive-parsing refactor, and #16911, the branch_10x decommission, touch hunspell files), all lists.apache.org hunspell mails since 2022-07-01 (dev@ 17, java-user@ 4, issues@ 240, subjects read), JIRA and git history; the finder's, the independent reproduction's and the intended-behaviour check's searches agree. Origin, not a report: #975 (LUCENE-10626, issue #11662), whose 3 comments, 12 reviews and 19 inline comments never mention Stemmer, prefixes or continuation classes. Contract context: #6546 (LUCENE-5483) and #6547 (LUCENE-5484), 2014: recursion is driven by continuation classes, at most two prefixes under COMPLEXPREFIXES; #10842 (LUCENE-9803, 2021) added the isSecondStagePrefix short-cut that is now the only gate. Not fixed upstream: upstream main a95c754ee003, branch_10x and branch_10_6 still carry both lines unchanged and no open PR changes Stemmer.java.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): the compact JUnit through gradle in a scratch worktree of that commit, stock and with the recommended fix, assertions on and off, plus the hunspell test package and the module's lint checks with the fix, and the combined fix with LFV-375's one-liner; through the hunt's classpath runner, the same JUnit on main (-ea,-da), 10.5.2, 9.12.3 and 9.5.0 (fail) and 9.4.2 (pass), the hunt's other repros and LFV-375's repro with the fix shadowed, and native Hunspell 1.3.2 on the repro dictionary, 2026-10-28. Hunt runs on maina9779ef3c193andea57360912ed(identical hunspell code) and version-portable probes on 15 releases from 4.8.0 to 10.5.2.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java:537-575 (at a9779ef3c193) (isAffixCompatible; :541 'boolean previousWasPrefix = outerSuffix < 0 && outerPrefix >= 0;', :564-571 cross-product branch, :566 'if (previousWasPrefix) return true;', :567-570 the per-rule check that inner suffixes still get, 'dictionary.hasFlag(append, prevFlag)'), :271 (processStemCandidate checks the outer prefix flag on the root only when innerPrefix < 0), :619-650 (applyAffix; :626 the second-prefix stage gated by 'dictionary.complexPrefixes && dictionary.isSecondStagePrefix(flag)', :640 LFV-375's 'doPrefix = true')lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:138-142 (at a9779ef3c193) (javadoc of secondStagePrefixFlags: 'If an outer affix's flag isn't here, there's no need to do 2-level affix stripping with it', a short-cut), :368-370 (COMPLEXPREFIXES), :482 (secondStagePrefixFlags = continuation flags of PFX rules), :1563-1565 (isSecondStagePrefix); HunspellStemFilter.java:39 (@lucene.experimental)git diff ea57360912ed a9779ef3c193 -- lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/ (empty: the GPT reviews on ea57360912ed exercised identical code)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java:424, (at a9779ef3c193) 537-574 (isAffixCompatible; :541, :564-571, :566), 262-277 (processStemCandidate; :271), 617-650 (applyAffix; :626, :640)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:138-142, (at a9779ef3c193) 336, 363-364, 482, 738-740, 1563-1565hunspell(4) man page installed with Hunspell 1.3.2, lines 119-121 (COMPLEXPREFIXES) and 790-800 (Twofold suffix stripping)
- Why it looks unintended
lucene/CHANGES.txt:12545-12549; (at a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:35-44, (at a9779ef3c193) 336; Stemmer.java:28-30, 564-571; Dictionary.java:138-141; lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/complexprefix.aff, TestComplexPrefix.java
- TestComplexPrefixesSecondPrefix.java (JUnit test):
repro/LFV-642/src/org/apache/lucene/analysis/hunspell/TestComplexPrefixesSecondPrefix.java(46 lines)
Made in parallel with this doc from a probe run on main a9779ef3c193 (stock, -ea and -da, 10.5.2, 9.4.2 and 9.5.0, and with the fix shadowed), using the repro's dictionary.
assets/LFV-642/bug.png(496 KB)